

Update comparison and inference roadmap
Browse files- .gitattributes +1 -0
- README.md +19 -1
- assets/jevvision-comparison-table.png +3 -0
- assets/jevvision-comparison-table.svg +111 -0
.gitattributes
CHANGED
|
@@ -40,3 +40,4 @@ assets/svgviewer-png-output.png filter=lfs diff=lfs merge=lfs -text
|
|
| 40 |
assets/JevBench[[:space:]]Results.png filter=lfs diff=lfs merge=lfs -text
|
| 41 |
assets/JevBench-results.png filter=lfs diff=lfs merge=lfs -text
|
| 42 |
assets/capability-comparison.png filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 40 |
assets/JevBench[[:space:]]Results.png filter=lfs diff=lfs merge=lfs -text
|
| 41 |
assets/JevBench-results.png filter=lfs diff=lfs merge=lfs -text
|
| 42 |
assets/capability-comparison.png filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
assets/jevvision-comparison-table.png filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -98,6 +98,12 @@ The release combines a trained text adapter, a separately trained visual sidecar
|
|
| 98 |
|
| 99 |
The capability graphic summarizes the separate input routes and shared response format. Its 80,000-token value is a configured request limit, not a measure of answer quality.
|
| 100 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 101 |
The serving route processed 76,999 text tokens and 76,998 image-plus-text tokens in recorded acceptance checks. The text check used the included KEV-0.8B option; the image check used the visual sidecar. These checks establish request handling near 77K, while long-context answer quality remains to be evaluated.
|
| 102 |
|
| 103 |
## See the visual route
|
|
@@ -224,6 +230,18 @@ The JevBench result for JEVision is 183/231 (79.3%). The grouped test is the sep
|
|
| 224 |
|
| 225 |
The [manifest](jevvision_manifest.json) identifies the components, their source revisions, hashes, and serving limit. Users should assess the model on their own images and decision tasks before relying on its outputs.
|
| 226 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 227 |
## License
|
| 228 |
|
| 229 |
-
The adapter bundle and runtime are published under Apache-2.0. The Qwen3.5 base model is also Apache-2.0; follow the base model's terms and the terms of any datasets you use.
|
|
|
|
| 98 |
|
| 99 |
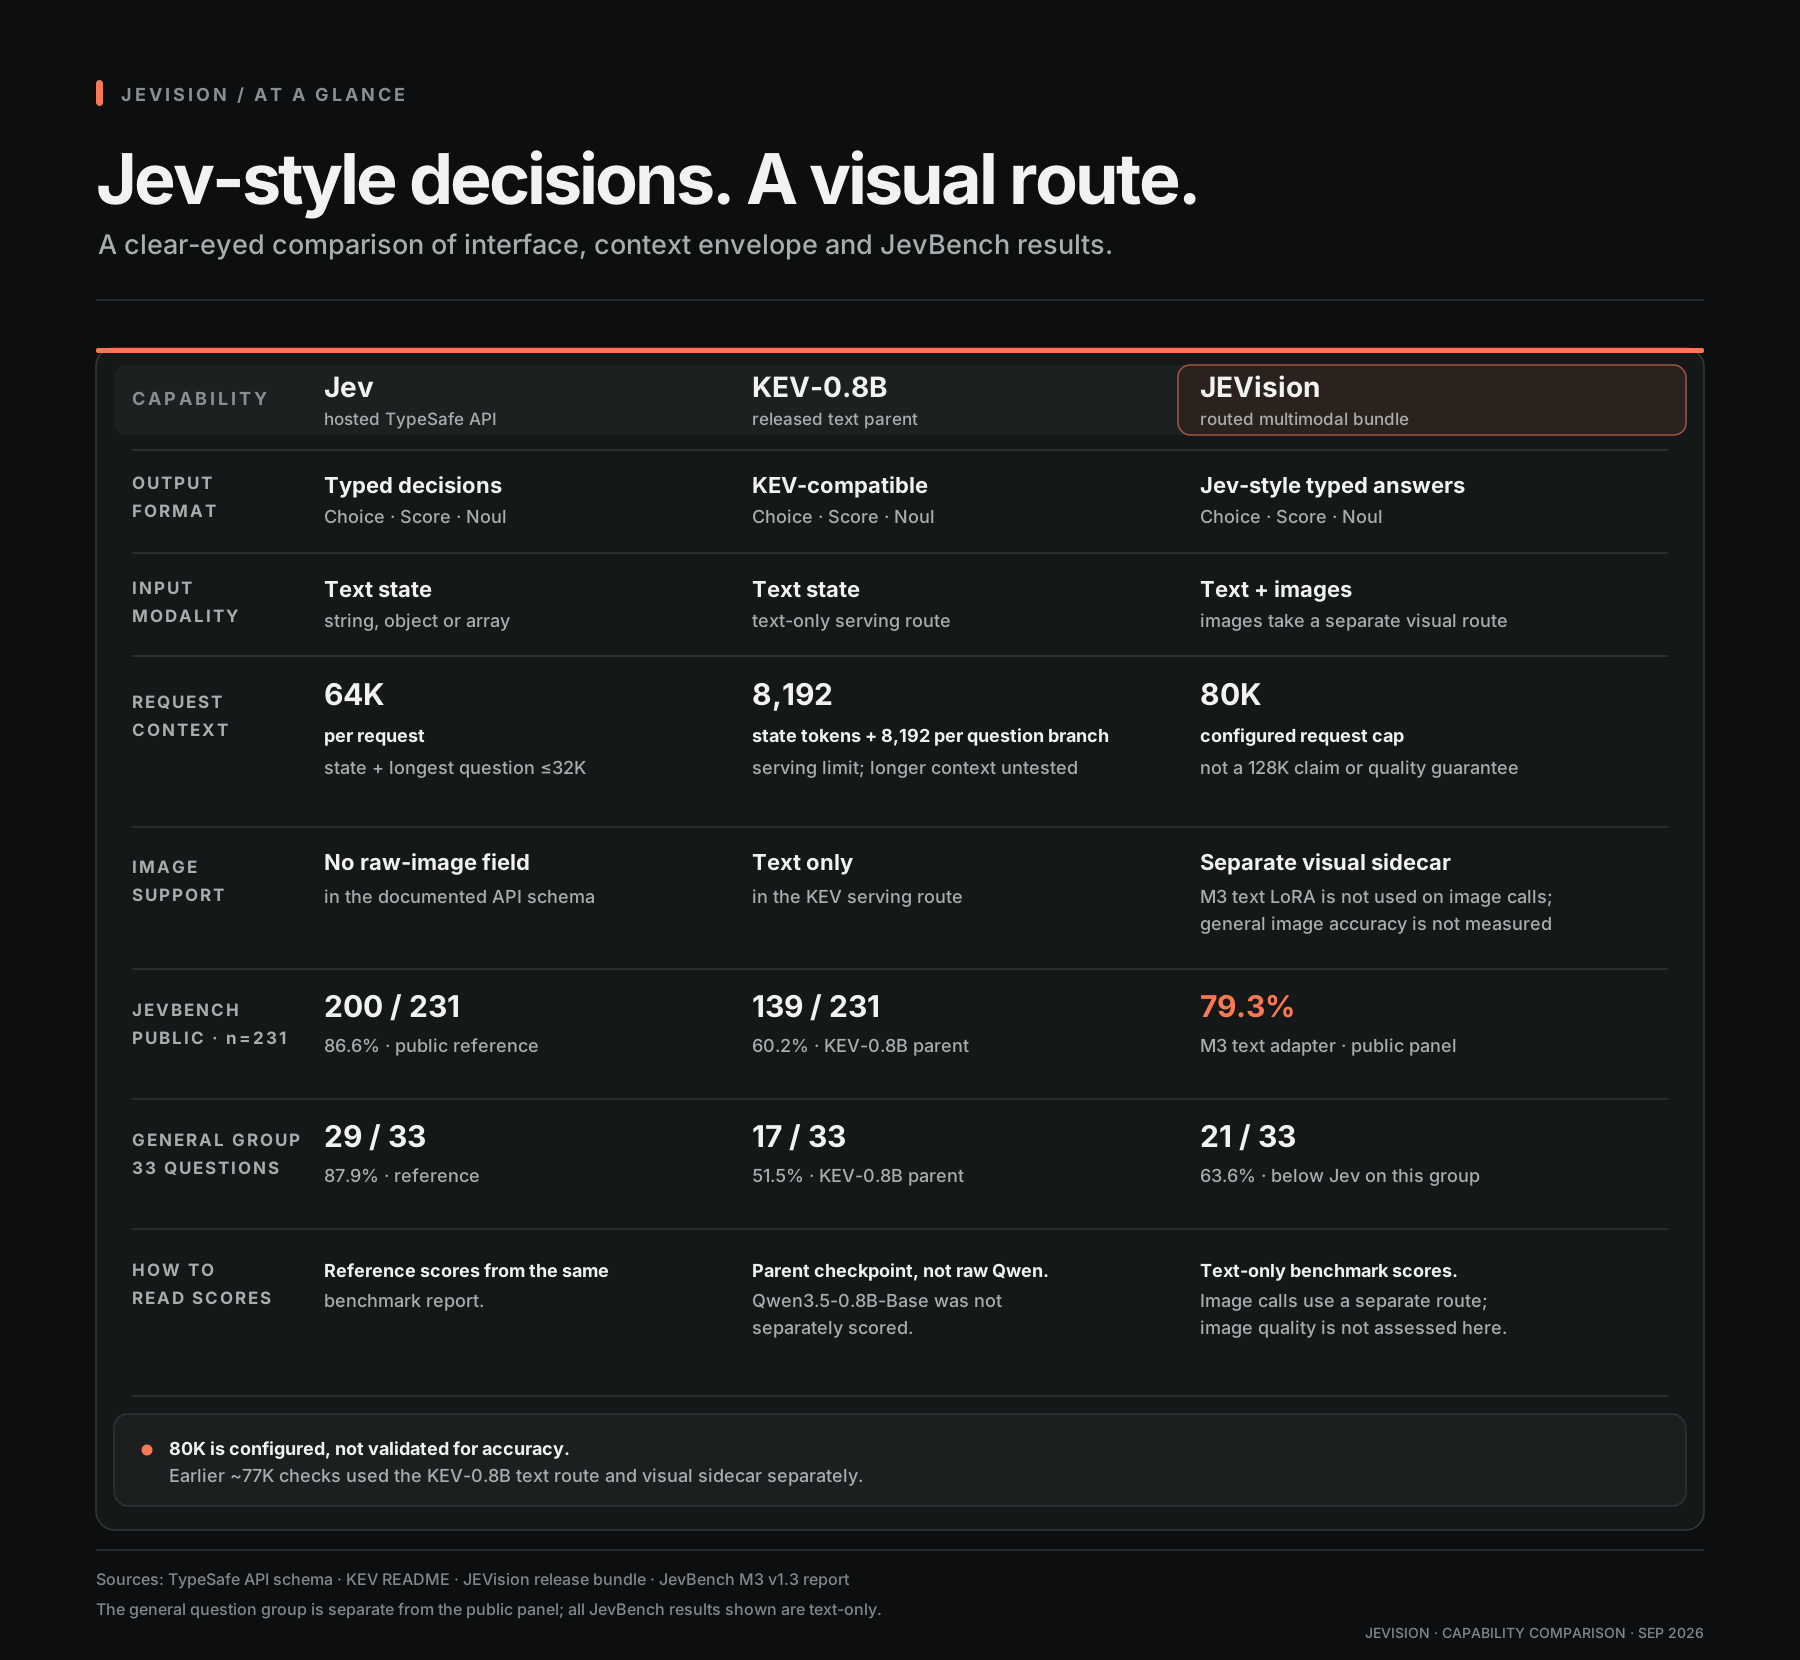
The capability graphic summarizes the separate input routes and shared response format. Its 80,000-token value is a configured request limit, not a measure of answer quality.
|
| 100 |
|
| 101 |
+
### Compared with Jev and KEV-0.8B
|
| 102 |
+
|
| 103 |
+

|
| 104 |
+
|
| 105 |
+
This view compares output format, input modality, configured context, image support, and text-only JevBench results. JEVision’s public-panel figure is 79.3%, and its 33-question general group result is 21/33 (63.6%). The [editable SVG](assets/jevvision-comparison-table.svg) is also included.
|
| 106 |
+
|
| 107 |
The serving route processed 76,999 text tokens and 76,998 image-plus-text tokens in recorded acceptance checks. The text check used the included KEV-0.8B option; the image check used the visual sidecar. These checks establish request handling near 77K, while long-context answer quality remains to be evaluated.
|
| 108 |
|
| 109 |
## See the visual route
|
|
|
|
| 230 |
|
| 231 |
The [manifest](jevvision_manifest.json) identifies the components, their source revisions, hashes, and serving limit. Users should assess the model on their own images and decision tasks before relying on its outputs.
|
| 232 |
|
| 233 |
+
## What's next
|
| 234 |
+
|
| 235 |
+
JEVision's next phase targets a purpose-built decision architecture and a faster production inference path. The work below is planned for future releases; the measurements above describe the current one.
|
| 236 |
+
|
| 237 |
+
### JEV-style parallel decision architecture
|
| 238 |
+
|
| 239 |
+
The architectural direction is to move from sequential, decoder-style question handling toward a shared-state decision engine. A common context representation would feed multiple question branches concurrently, with typed heads for **Choice**, **Noul**, and **Score** outputs. This makes multi-question calls a first-class model workload: shared context computation can be reused, independent questions can run in parallel, and the system can spend less compute repeatedly generating answer scaffolding. The goal is higher question throughput and more predictable latency as a request grows.
|
| 240 |
+
|
| 241 |
+
### Inference engineered for low latency
|
| 242 |
+
|
| 243 |
+
The serving roadmap focuses on the full request path: context prefill, question scheduling, batching, adapter dispatch, and typed-answer readout. For the current Qwen-based backbone, we plan to profile and optimize reusable context work and cache behavior; for the evolving decision architecture, we plan to schedule question branches and text/visual routes with less synchronization and data movement. The target is a responsive decision API with lower end-to-end and tail latency under multi-question load. We will report p50/p95 latency, throughput, and output-quality checks when these changes are implemented.
|
| 244 |
+
|
| 245 |
## License
|
| 246 |
|
| 247 |
+
The adapter bundle and runtime are published under Apache-2.0. The Qwen3.5 base model is also Apache-2.0; follow the base model's terms and the terms of any datasets you use.
|
assets/jevvision-comparison-table.png
ADDED

|
Git LFS Details
|
assets/jevvision-comparison-table.svg
ADDED
|