

Clarify JEVision evaluation claims and update graphics
Browse files
README.md
CHANGED
|
@@ -33,9 +33,9 @@ The release combines a trained text adapter, a separately trained visual sidecar
|
|
| 33 |
| Request envelope | Configured for up to 80,000 processed input tokens |
|
| 34 |
| Packaging | Adapters, heads, and a runnable local server; base weights download separately |
|
| 35 |
|
| 36 |
-
![
|
| 37 |
|
| 38 |
-
|
| 39 |
|
| 40 |
The serving route processed 76,999 text tokens and 76,998 image-plus-text tokens in recorded acceptance checks. The text check used the included KEV-0.8B option; the image check used the visual sidecar. These checks establish request handling near 77K, while long-context answer quality remains to be evaluated.
|
| 41 |
|
|
@@ -142,11 +142,11 @@ The default text adapter was fitted to public JevBench decision examples, starti
|
|
| 142 |
|
| 143 |
## Evaluation scope
|
| 144 |
|
| 145 |
-
JEVision currently has functional checks for typed responses, image routing, and long request acceptance, plus the recorded real-photo example above.
|
| 146 |
|
| 147 |
-
 identifies the components, their source revisions, hashes, and serving limit. Users should assess the model on their own images and decision tasks before relying on its outputs.
|
| 152 |
|
|
|
|
| 33 |
| Request envelope | Configured for up to 80,000 processed input tokens |
|
| 34 |
| Packaging | Adapters, heads, and a runnable local server; base weights download separately |
|
| 35 |
|
| 36 |
+

|
| 37 |
|
| 38 |
+
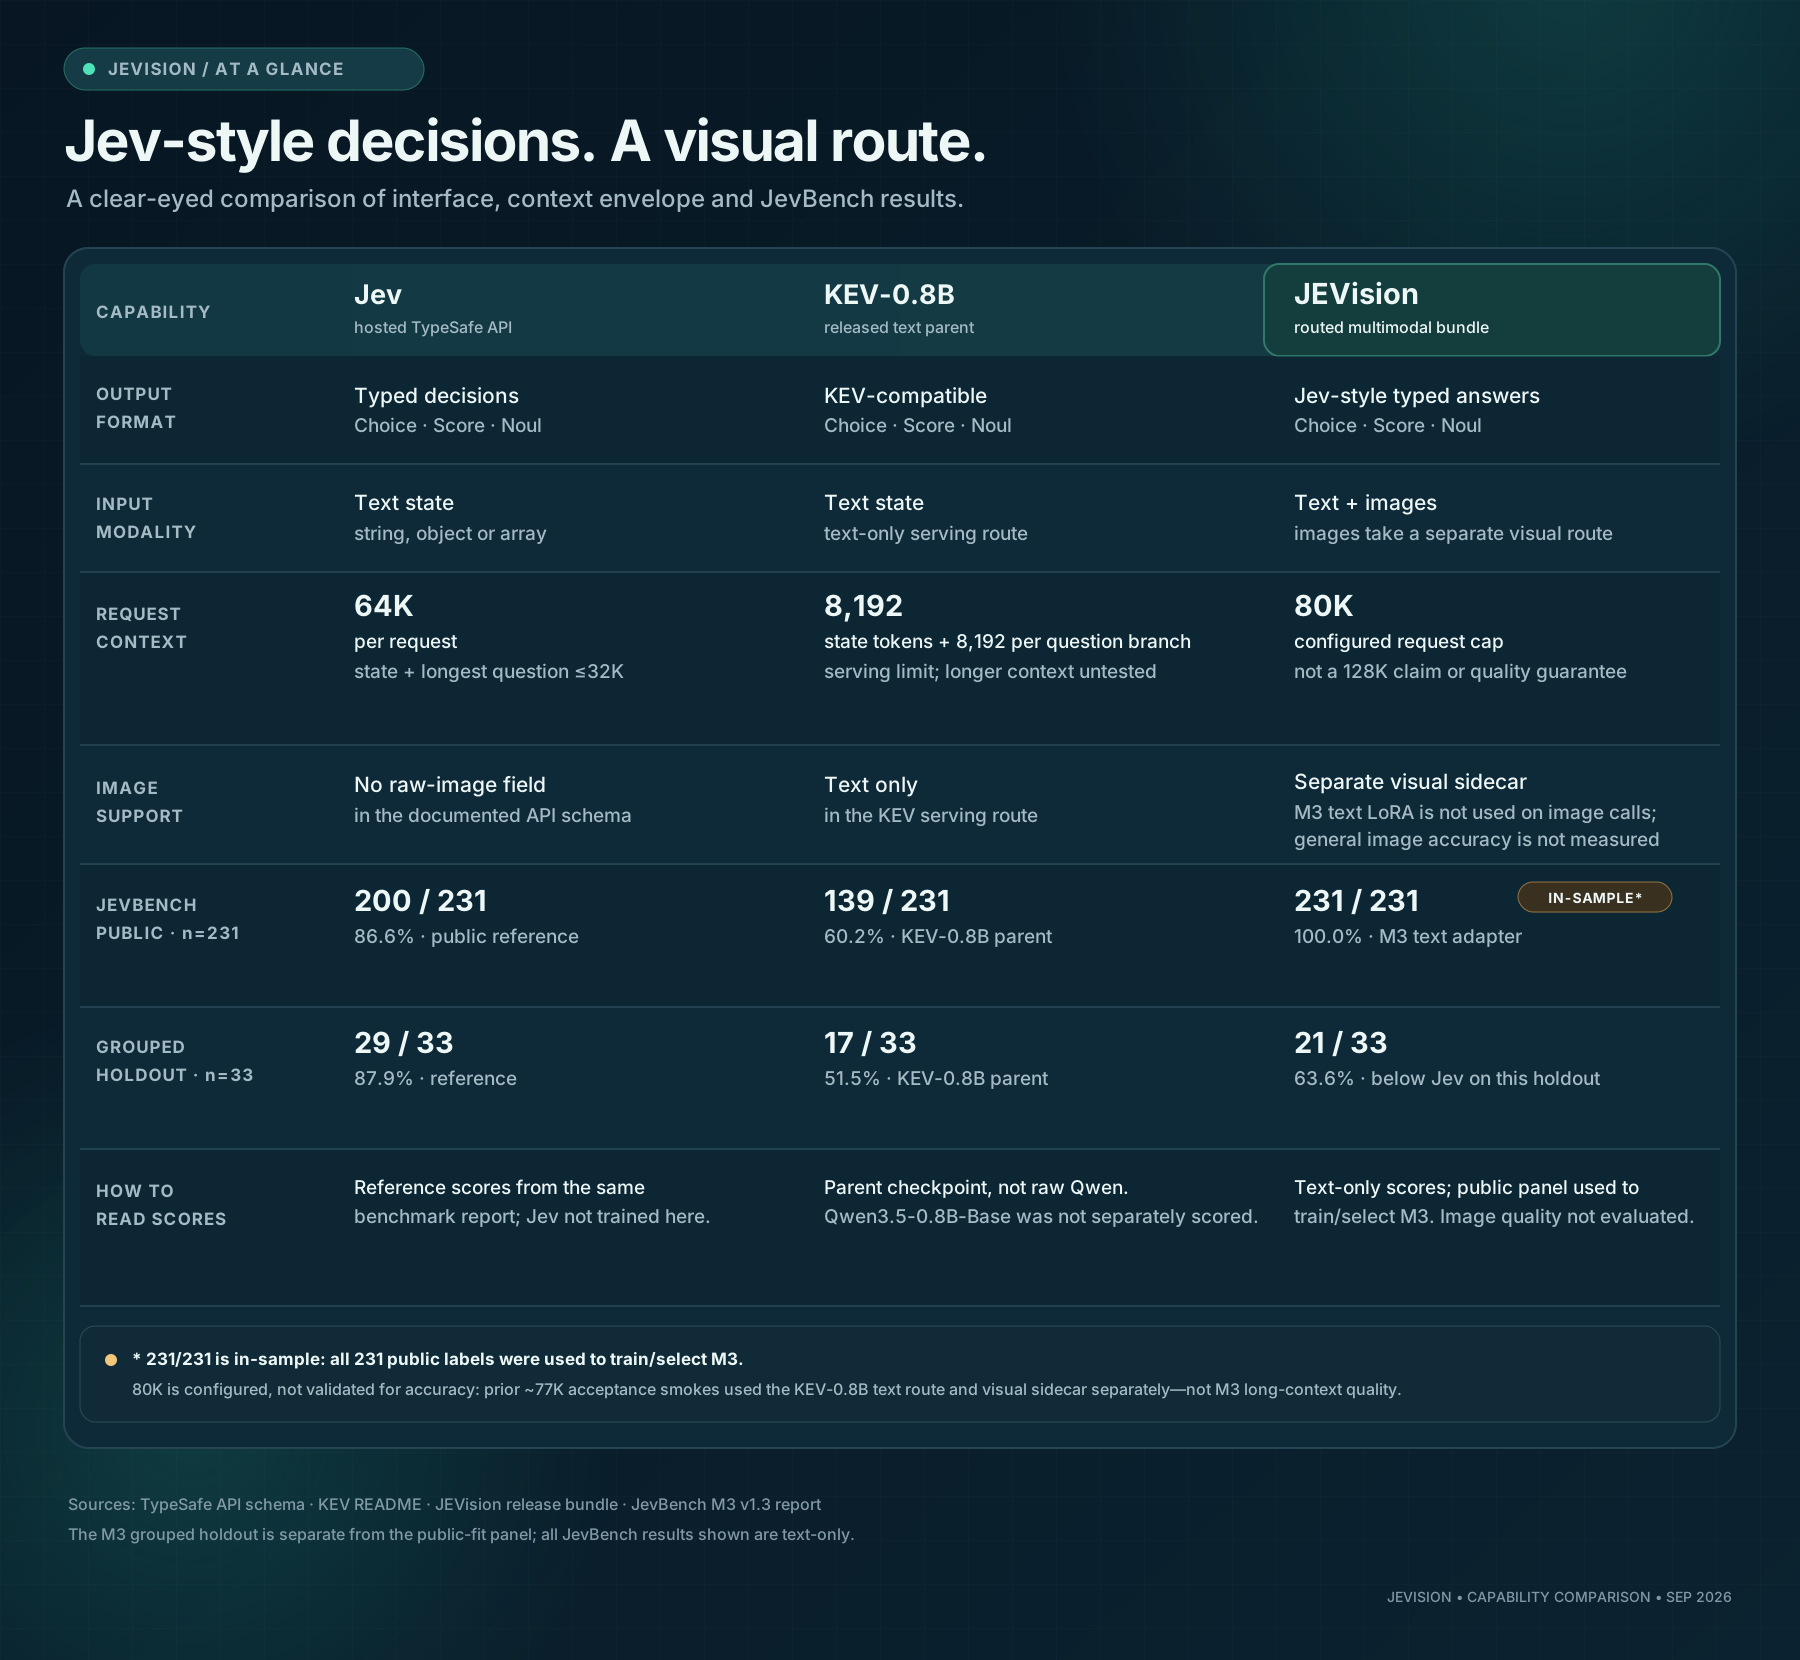
The capability graphic summarizes the separate input routes and shared response format. Its 80,000-token value is a configured request limit, not a measure of answer quality.
|
| 39 |
|
| 40 |
The serving route processed 76,999 text tokens and 76,998 image-plus-text tokens in recorded acceptance checks. The text check used the included KEV-0.8B option; the image check used the visual sidecar. These checks establish request handling near 77K, while long-context answer quality remains to be evaluated.
|
| 41 |
|
|
|
|
| 142 |
|
| 143 |
## Evaluation scope
|
| 144 |
|
| 145 |
+
JEVision currently has functional checks for typed responses, image routing, and long request acceptance, plus the recorded real-photo example above. The public JevBench examples were used to fit and select the text adapter, so accuracy on those examples is not an independent benchmark result. A separate 33-question grouped text test recorded 21 correct (63.6%) with a 4,096-token cap. This small test does not measure the visual route or long-context answer quality. The 80,000-token value is a service limit, and requests beyond it are rejected instead of silently truncated. No comparative accuracy, latency, or cost claim is made here.
|
| 146 |
|
| 147 |
+

|
| 148 |
|
| 149 |
+
This results graphic records the small grouped text test and distinguishes it from the public examples used during training and selection. It does not evaluate the visual route.
|
| 150 |
|
| 151 |
The [manifest](jevvision_manifest.json) identifies the components, their source revisions, hashes, and serving limit. Users should assess the model on their own images and decision tasks before relying on its outputs.
|
| 152 |
|
assets/jevbench-m3-results.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
assets/jevbench-m3-results.svg
CHANGED

|

|
assets/jevvision-capability-comparison.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
assets/jevvision-capability-comparison.svg
CHANGED
|

|