
Kubanychbek Emil commited on
Commit ·
2e58279
1
Parent(s): 684790e
Create README.md
Browse files
README.md
ADDED
|
@@ -0,0 +1,97 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
language:
|
| 3 |
+
- en
|
| 4 |
+
license: creativeml-openrail-m
|
| 5 |
+
tags:
|
| 6 |
+
- stable-diffusion
|
| 7 |
+
- stable-diffusion-diffusers
|
| 8 |
+
- text-to-image
|
| 9 |
+
- diffusers
|
| 10 |
+
inference: true
|
| 11 |
+
---
|
| 12 |
+
|
| 13 |
+
AnyLORA is the diffusion checkpoint that is highly compatible with **Civitai's** LORA instances.
|
| 14 |
+
|
| 15 |
+
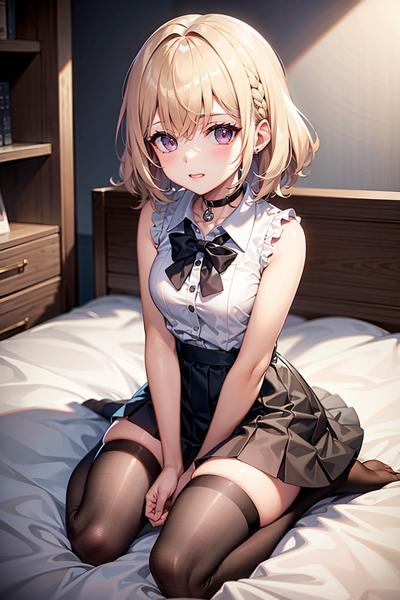
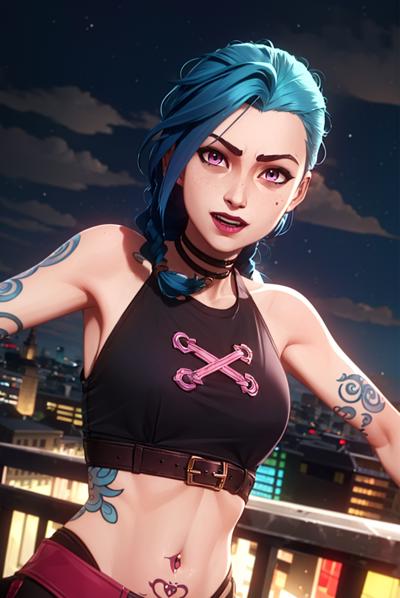
Examples:
|
| 16 |
+
|
| 17 |
+

|
| 18 |
+

|
| 19 |
+

|
| 20 |
+
|
| 21 |
+
-------
|
| 22 |
+
|
| 23 |
+
<font color="grey">Thanks to [Linaqruf](https://huggingface.co/Linaqruf) for letting me borrow his model card for reference.
|
| 24 |
+
|
| 25 |
+
# Anything V4
|
| 26 |
+
|
| 27 |
+
Welcome to Anything V4 - a latent diffusion model for weebs. The newest version of Anything. This model is intended to produce high-quality, highly detailed anime style with just a few prompts. Like other anime-style Stable Diffusion models, it also supports danbooru tags to generate images.
|
| 28 |
+
|
| 29 |
+
e.g. **_1girl, white hair, golden eyes, beautiful eyes, detail, flower meadow, cumulonimbus clouds, lighting, detailed sky, garden_**
|
| 30 |
+
|
| 31 |
+
I think the V4.5 version better though, it's in this repo. feel free 2 try it.
|
| 32 |
+
|
| 33 |
+
## Yes, this model has [AbyssOrangeMix2](https://huggingface.co/WarriorMama777/OrangeMixs) in it. coz its a very good model. check it out luls ;)
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
# Gradio
|
| 37 |
+
|
| 38 |
+
We support a [Gradio](https://github.com/gradio-app/gradio) Web UI to run anything-v4.0:
|
| 39 |
+
[](https://huggingface.co/spaces/akhaliq/anything-v4.0)
|
| 40 |
+
|
| 41 |
+
## 🧨 Diffusers
|
| 42 |
+
|
| 43 |
+
This model can be used just like any other Stable Diffusion model. For more information,
|
| 44 |
+
please have a look at the [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion).
|
| 45 |
+
|
| 46 |
+
You can also export the model to [ONNX](https://huggingface.co/docs/diffusers/optimization/onnx), [MPS](https://huggingface.co/docs/diffusers/optimization/mps) and/or [FLAX/JAX]().
|
| 47 |
+
|
| 48 |
+
```python
|
| 49 |
+
from diffusers import StableDiffusionPipeline
|
| 50 |
+
import torch
|
| 51 |
+
|
| 52 |
+
model_id = "andite/anything-v4.0"
|
| 53 |
+
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
|
| 54 |
+
pipe = pipe.to("cuda")
|
| 55 |
+
|
| 56 |
+
prompt = "hatsune_miku"
|
| 57 |
+
image = pipe(prompt).images[0]
|
| 58 |
+
|
| 59 |
+
image.save("./hatsune_miku.png")
|
| 60 |
+
```
|
| 61 |
+
|
| 62 |
+
## Examples
|
| 63 |
+
|
| 64 |
+
Below are some examples of images generated using this model:
|
| 65 |
+
|
| 66 |
+
**Anime Girl:**
|
| 67 |
+

|
| 68 |
+
```
|
| 69 |
+
masterpiece, best quality, 1girl, white hair, medium hair, cat ears, closed eyes, looking at viewer, :3, cute, scarf, jacket, outdoors, streets
|
| 70 |
+
Steps: 20, Sampler: DPM++ 2M Karras, CFG scale: 7
|
| 71 |
+
```
|
| 72 |
+
**Anime Boy:**
|
| 73 |
+

|
| 74 |
+
```
|
| 75 |
+
1boy, bishounen, casual, indoors, sitting, coffee shop, bokeh
|
| 76 |
+
Steps: 20, Sampler: DPM++ 2M Karras, CFG scale: 7
|
| 77 |
+
```
|
| 78 |
+
**Scenery:**
|
| 79 |
+

|
| 80 |
+
```
|
| 81 |
+
scenery, village, outdoors, sky, clouds
|
| 82 |
+
Steps: 50, Sampler: DPM++ 2S a Karras, CFG scale: 7
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
## License
|
| 86 |
+
|
| 87 |
+
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage.
|
| 88 |
+
The CreativeML OpenRAIL License specifies:
|
| 89 |
+
[Please read the full license here](https://huggingface.co/spaces/CompVis/stable-diffusion-license)
|
| 90 |
+
|
| 91 |
+
## Big Thanks to
|
| 92 |
+
|
| 93 |
+
- [Linaqruf](https://huggingface.co/Linaqruf). [NoCrypt](https://huggingface.co/NoCrypt), and Fannovel16#9022 for helping me out alot regarding my inquiries and concern about models and other stuff.
|
| 94 |
+
|
| 95 |
+

|
| 96 |
+
|
| 97 |
+
|