---
license: other
license_name: qwen-research
license_link: LICENSE
base_model:
- Qwen/Qwen-Image-2.1
base_model_relation: quantized
pipeline_tag: text-to-image
library_name: mnn
tags:
- mnn
- android
- opencl
- int4
- qwen-image
---
# Qwen-Image-2.1 · MNN (int4) for Android
[Qwen/Qwen-Image-2.1](https://huggingface.co/Qwen/Qwen-Image-2.1) converted to [MNN](https://github.com/alibaba/MNN)
for on-device **text-to-image and image editing** on Android, with the OpenCL GPU running the DiT. Any size with sides
a multiple of 32 works, from 256×256 up; the app offers 7 aspect ratios at three pixel budgets (~512², ~384², ~320²),
e.g. 512×512, 576×448, 672×384, 480×320, 384×288. An optional **Turbo** LoRA (`dit_turbo.mnn`) cuts a run from
20–40 steps to a fixed 6.
Runtime, Android library and demo app: **[github.com/scsonic/libQwenImage21](https://github.com/scsonic/libQwenImage21)**
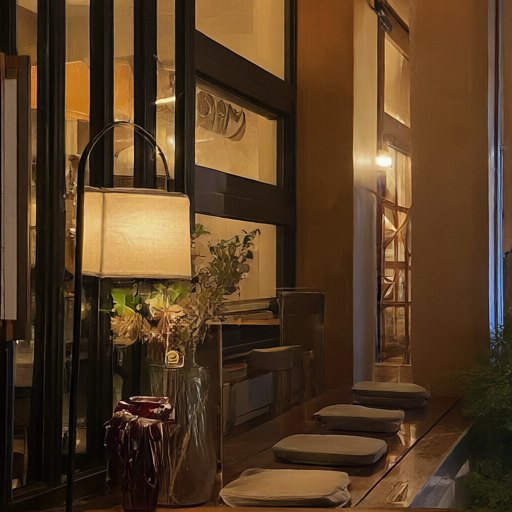
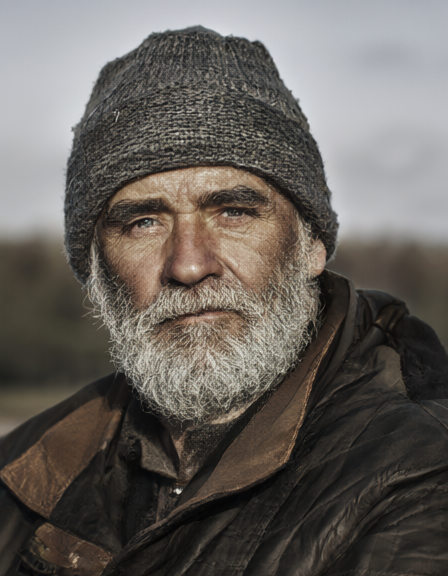
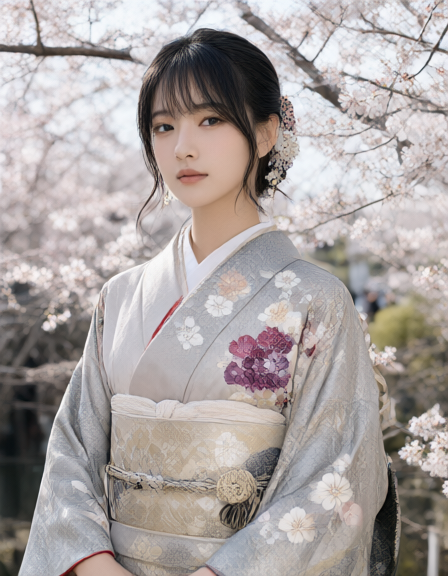
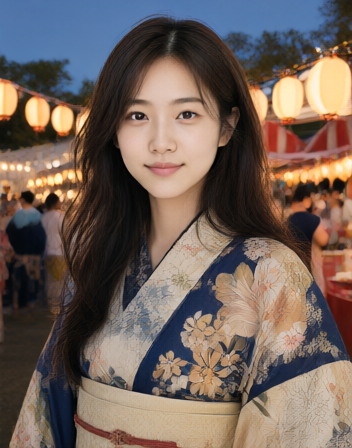
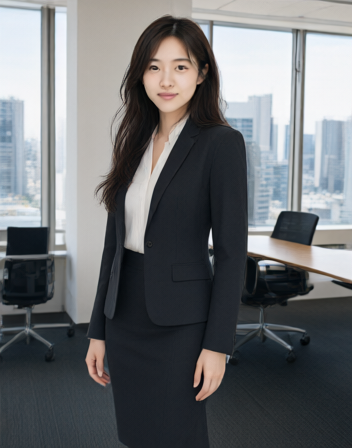
*Left two: base model, 20 steps. Right three: Turbo, 6 steps — a text-to-image portrait, then two edits of it (same
face, new outfit and background). All generated on a phone; see [Turbo (6-step)](#turbo-6-step) below for the rest
of the set and per-run timings.*
| Tested on | Snapdragon 8 Gen 2 (Adreno 740), 16 GB RAM, Android 13 |
|---|---|
| Text to image, 448×576, 20 steps | 451 s total (DiT 19.1 s/step on OpenCL fp16) |
| Image edit, 352×448, 20 steps | 348 s total (DiT 12.6 s/step) |
| Text to image, 512×512, **Turbo 6 steps** | ~216–235 s total (DiT ~22 s/step) |
| Image edit, 352×448, **Turbo 6 steps** | ~196–200 s total |
## Files
| Path | What | Size |
|---|---|---|
| `dit.mnn` + `.weight` | 7B single-stream DiT (32 blocks + norm_out/proj_out). Block linears int4 (block 32), small layers int8 | 4.5 GB |
| `dit_turbo.mnn` + `.weight` | Same DiT with the [Viggle-turbo](https://huggingface.co/Viggle/Qwen-Image-2.1-viggle-turbo) LoRA applied unmerged (a small extra fp16 branch per targeted layer); fixed 6-step schedule. Optional — see [below](#turbo-6-step) | 5.2 GB |
| `txt_in.mnn`, `img_in.mnn` | text (int8) / latent (fp16) input projections | 36 MB |
| `vae_decoder.mnn` | VAE decoder, 64-ch latent → RGBA, fp16 weights, dynamic size | 0.5 GB |
| `vae_encoder.mnn` | VAE encoder for image editing, RGBA → normalized 64-ch latent, fp16 | 0.16 GB |
| `text_encoder/` | Qwen3-VL-8B-Instruct, MNN int4 (from [taobao-mnn/Qwen3-VL-8B-Instruct-MNN](https://huggingface.co/taobao-mnn/Qwen3-VL-8B-Instruct-MNN)). `te_config.json` runs it text-only; `te_vl_config.json` adds the vision tower (`visual.mnn`) for image editing. Both return the last decoder layer before the final norm | 5.4 GB |
Download everything (~15.5 GB with Turbo) or skip `dit_turbo.mnn*` to save 5.2 GB:
```bash
hf download evankuo/Qwen-Image-2.1-MNN --local-dir qwen_image21 # + Turbo
hf download evankuo/Qwen-Image-2.1-MNN --local-dir qwen_image21 --exclude "dit_turbo.mnn*" # base model only
```
## Turbo (6-step)
[Viggle-turbo](https://huggingface.co/Viggle/Qwen-Image-2.1-viggle-turbo) distills Qwen-Image-2.1 to a fixed
6-step schedule with no CFG. `dit_turbo.mnn` applies it **unmerged**, the way diffusers and the LoRA's own
ComfyUI node do: the int4 base weights are untouched (identical to `dit.mnn`'s), and the LoRA's rank-128
correction is added as a small extra fp16 branch per targeted layer, exported as its own MNN model file that
happens to carry a second copy of the base weights (MNN has no format for patching an already-compiled graph).
Merging the correction into the weights instead — especially into int4 — is what the LoRA's own README
specifically measures as lossy; unmerged is the accurate path. `txt_in.mnn`, `img_in.mnn`, both VAE models and
the text encoder are unaffected and shared with the base pipeline.
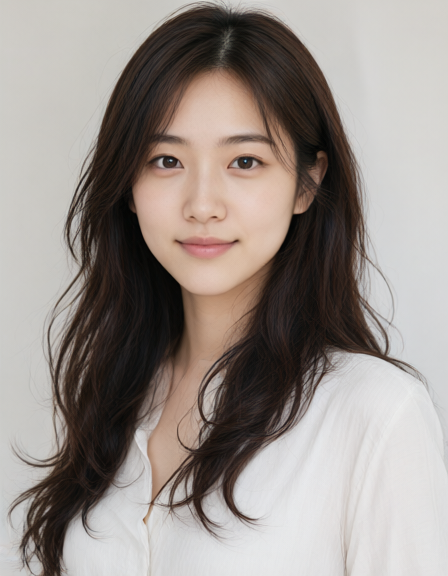
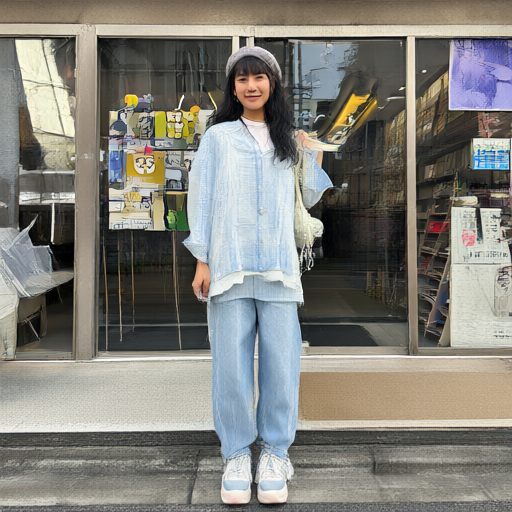
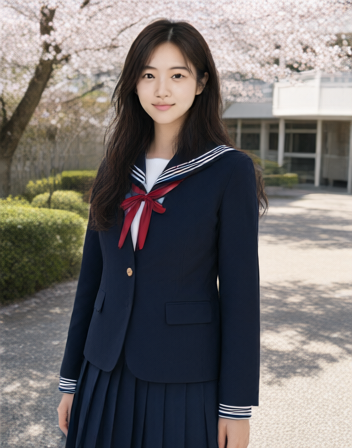
*Text-to-image (studio portrait, kimono, Harajuku street fashion) and two edits of the studio portrait — same
face, new outfit and setting. All on a Snapdragon 8 Gen 2, OpenCL, 6 steps.*
| | text encoder (+ prefix) | DiT (6 steps) | VAE | total |
|---|---|---|---|---|
| Text to image, 448×576–512×512 | ~15 s | 6 × ~22 s ≈ 134 s | ~18 s | **216–235 s** |
| Image edit → 352×448 | ~20–80 s (with vision; P≈680) | 6 × ~18 s ≈ 108 s | ~13 s | **196–200 s** |
A Turbo DiT step (~22 s at ~512²) is slower than a base-model step at the same size (~19 s) — the extra fp16
branch costs roughly the 10–25% diffusers/ComfyUI themselves measure — but 6 steps instead of 20 still roughly
halves the total time for both modes. Base model at 6 steps *without* the LoRA is visibly worse (soft, muddy) —
the schedule alone isn't what's doing the work.
Load it like the base model, just with `dit_turbo.mnn` instead of `dit.mnn`; the demo app has a **Turbo LoRA**
checkbox that fixes the step count to 6. See the [runtime repo](https://github.com/scsonic/libQwenImage21/blob/main/docs/TURBO.md)
for the CLI/library API.
## How it was made
- **DiT**: taken from the GGUF **Q4_K** build ([leejet/Qwen-Image-2.1-GGUF](https://huggingface.co/leejet/Qwen-Image-2.1-GGUF)).
Every Q4_K sub-block of 32 weights (`w = d·sc·q − dmin·m`) maps exactly onto MNN's asymmetric int4 with block 32,
so the weights are copied without re-quantization (scales stored as fp16).
- **Text encoder**: Qwen-Image-2.1's `text_encoder` is byte-identical to Qwen3-VL-8B-Instruct, so the existing MNN
export is reused unchanged.
- **VAE**: the residual stream is divided by 256 (exact, power of two) and RMSNorm pre-divides by max|x| so the decoder
fits fp16 (it peaks at ~3.5e5 otherwise). The decoded image is unchanged.
- The pipeline caches the text K/V once per prompt (Qwen-Image-2.1's block-causal attention), so each denoising step
only runs the image tokens. The cache is one tensor per layer (`past_kv_0`…`past_kv_31`): a single
`[32, 2, P, 32, 128]` tensor is exactly 1 MiB per prefix token, and an image-edit prefix (P > 1000) would exceed
OpenCL's 1 GiB maximum buffer size on an Adreno 740.
> **2026-09-23:** `dit.mnn` / `dit.mnn.weight` were re-exported for that per-layer K/V cache. Older copies do not load
> with the current runtime — re-download both files.
> **2026-09-25:** added `dit_turbo.mnn` / `.weight` (optional, see [Turbo](#turbo-6-step) above).
Conversion scripts: `export/` in the GitHub repo.
## License
Derived from Qwen-Image-2.1 and released under the **Qwen Research License Agreement** (see `LICENSE`), i.e. for
research / non-commercial use under its terms. The text encoder weights come from Qwen3-VL-8B-Instruct (Apache-2.0).
The Turbo LoRA is a derivative of the same base model, released by Viggle under the same Qwen Research License
Agreement.