Sentence Similarity
sentence-transformers
Safetensors
Transformers
Japanese
llama
feature-extraction
mirei
llm2vec
text-embedding
embeddings
retrieval
custom_code
text-embeddings-inference
Instructions to use iamtatsuki05/Sentence-Sarashina-Bi-0.5B with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- sentence-transformers
How to use iamtatsuki05/Sentence-Sarashina-Bi-0.5B with sentence-transformers:
from sentence_transformers import SentenceTransformer model = SentenceTransformer("iamtatsuki05/Sentence-Sarashina-Bi-0.5B", trust_remote_code=True) sentences = [ "The weather is lovely today.", "It's so sunny outside!", "He drove to the stadium." ] embeddings = model.encode(sentences) similarities = model.similarity(embeddings, embeddings) print(similarities.shape) # [3, 3] - Transformers
How to use iamtatsuki05/Sentence-Sarashina-Bi-0.5B with Transformers:
# Load model directly from transformers import AutoTokenizer, AutoModel tokenizer = AutoTokenizer.from_pretrained("iamtatsuki05/Sentence-Sarashina-Bi-0.5B", trust_remote_code=True) model = AutoModel.from_pretrained("iamtatsuki05/Sentence-Sarashina-Bi-0.5B", trust_remote_code=True, device_map="auto") - Notebooks
- Google Colab
- Kaggle
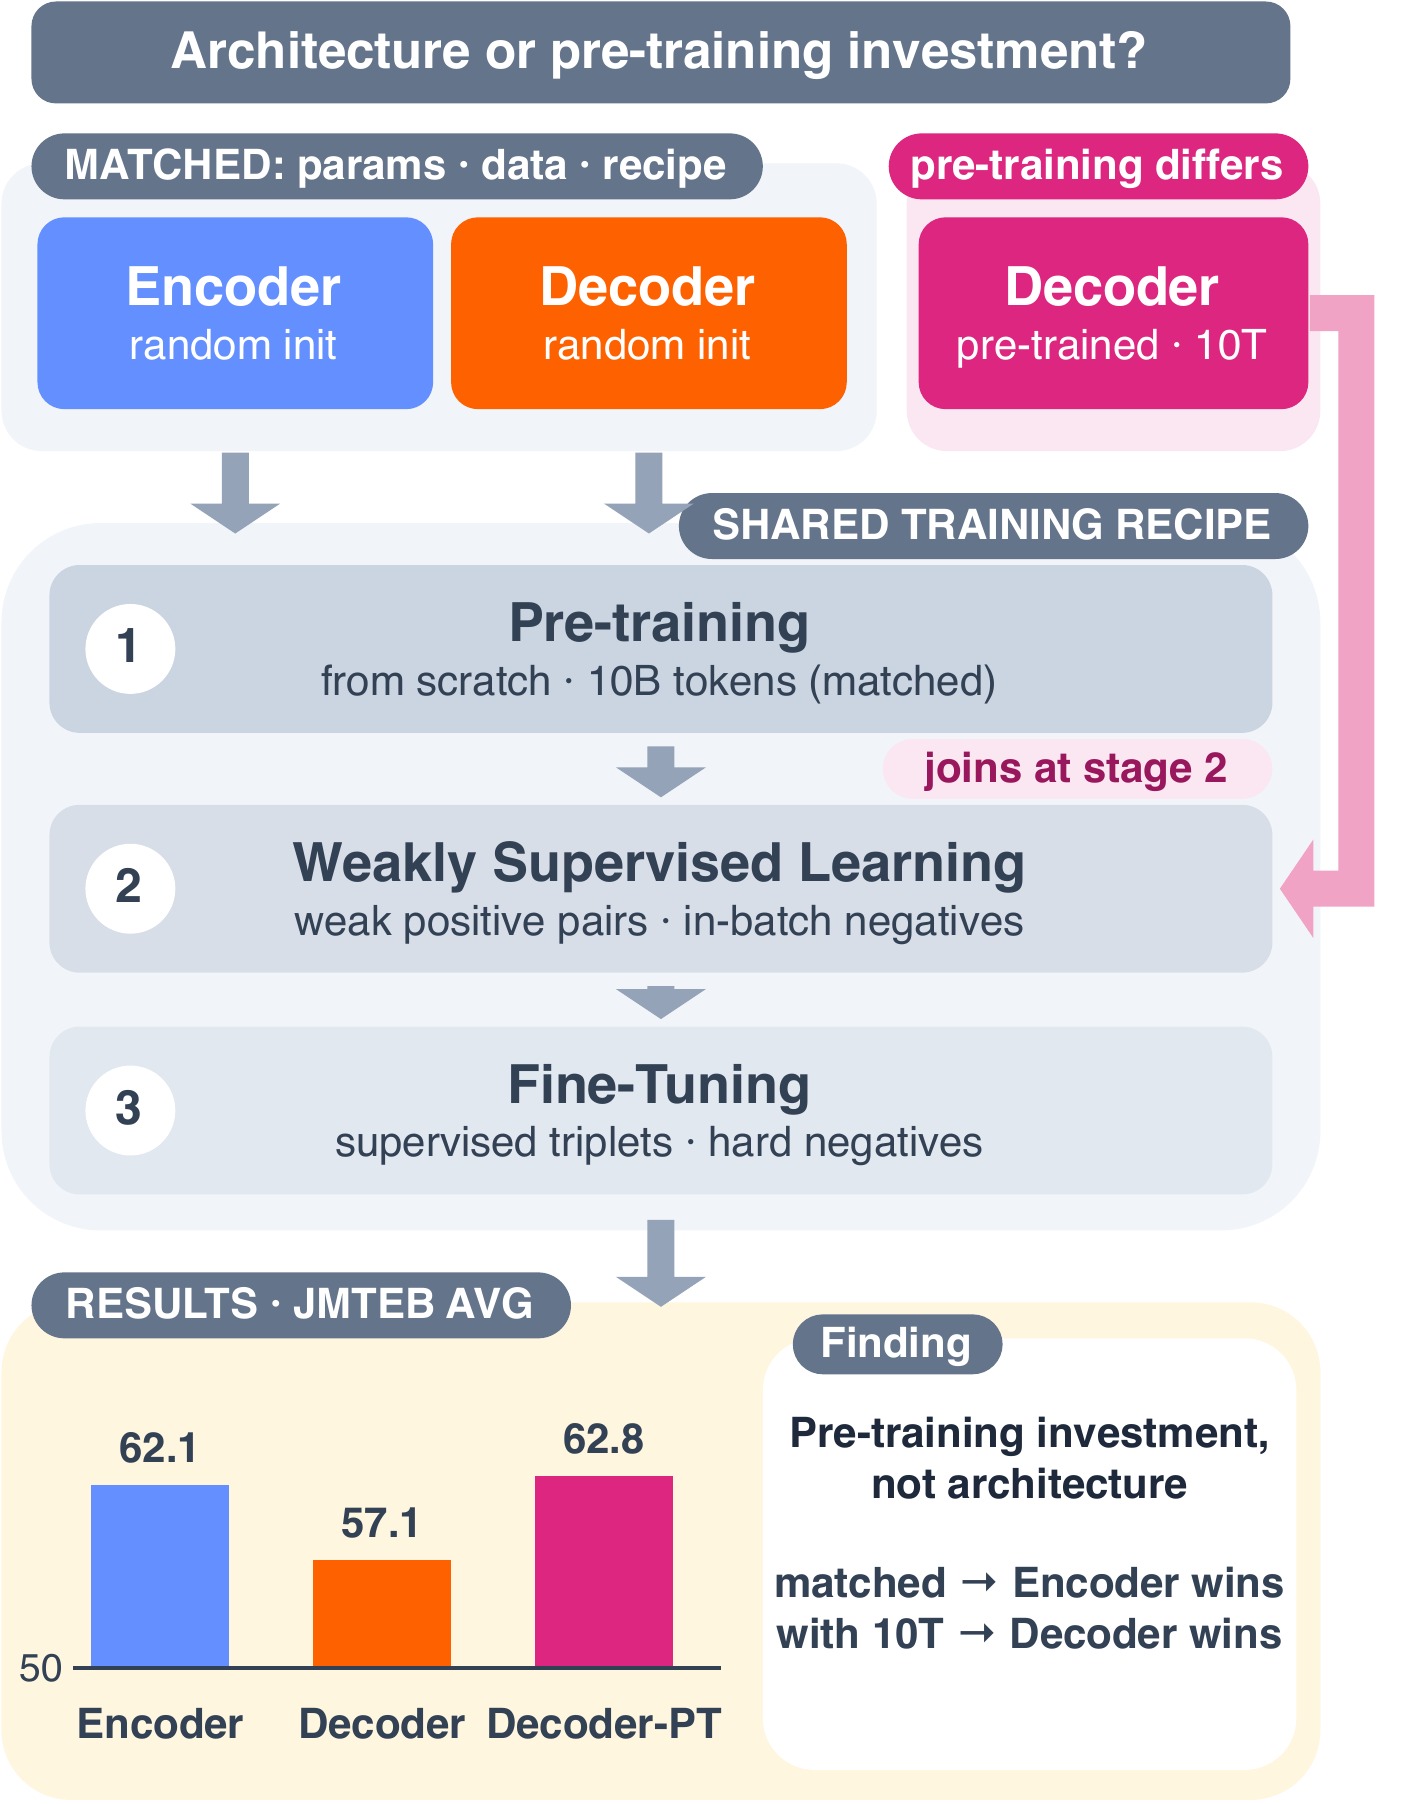
Update concept overview figure to the latest version (color-blind-safe palette aligned with result plots)
4ed46d3 verified 
- Xet hash:
- 347f8225fb9edb1805bfd012f2a5fdf5ef7d5aadc66085562cba34115a25fec2
- Size of remote file:
- 328 kB
- SHA256:
- 864229e9c3d402238537ed86edec125d1e0d41594b65a6ac7f573b27932e5b77
·
Xet efficiently stores Large Files inside Git, intelligently splitting files into unique chunks and accelerating uploads and downloads. More info.