LLaDA-Image
Welcome to the official repository for LLaDA-Image, a unified model for high-quality image generation and editing.
## Introduction
LLaDA-Image is a competitive 6B-parameter open-source unified image generation and editing model family. It includes **LLaDA-Image**, a 50-step Base model for high-quality text-to-image generation and instruction-guided editing, and **LLaDA-Image-Turbo**, a 4-step distilled model for fast generation and editing. Both variants support practical text-to-image generation, VQ-conditioned generation, reference-image editing, and Chinese--English text rendering.
This repository provides the checkpoints and Diffusers-based inference code for the LLaDA-Image model family.
## News
- **TODO:** We released the LLaDA-Image Base and Turbo checkpoints together with the inference code.
## Highlights
- **Unified generation and editing.** A single checkpoint supports text-to-image generation and reference-preserving, instruction-guided editing without a separate editing backbone.
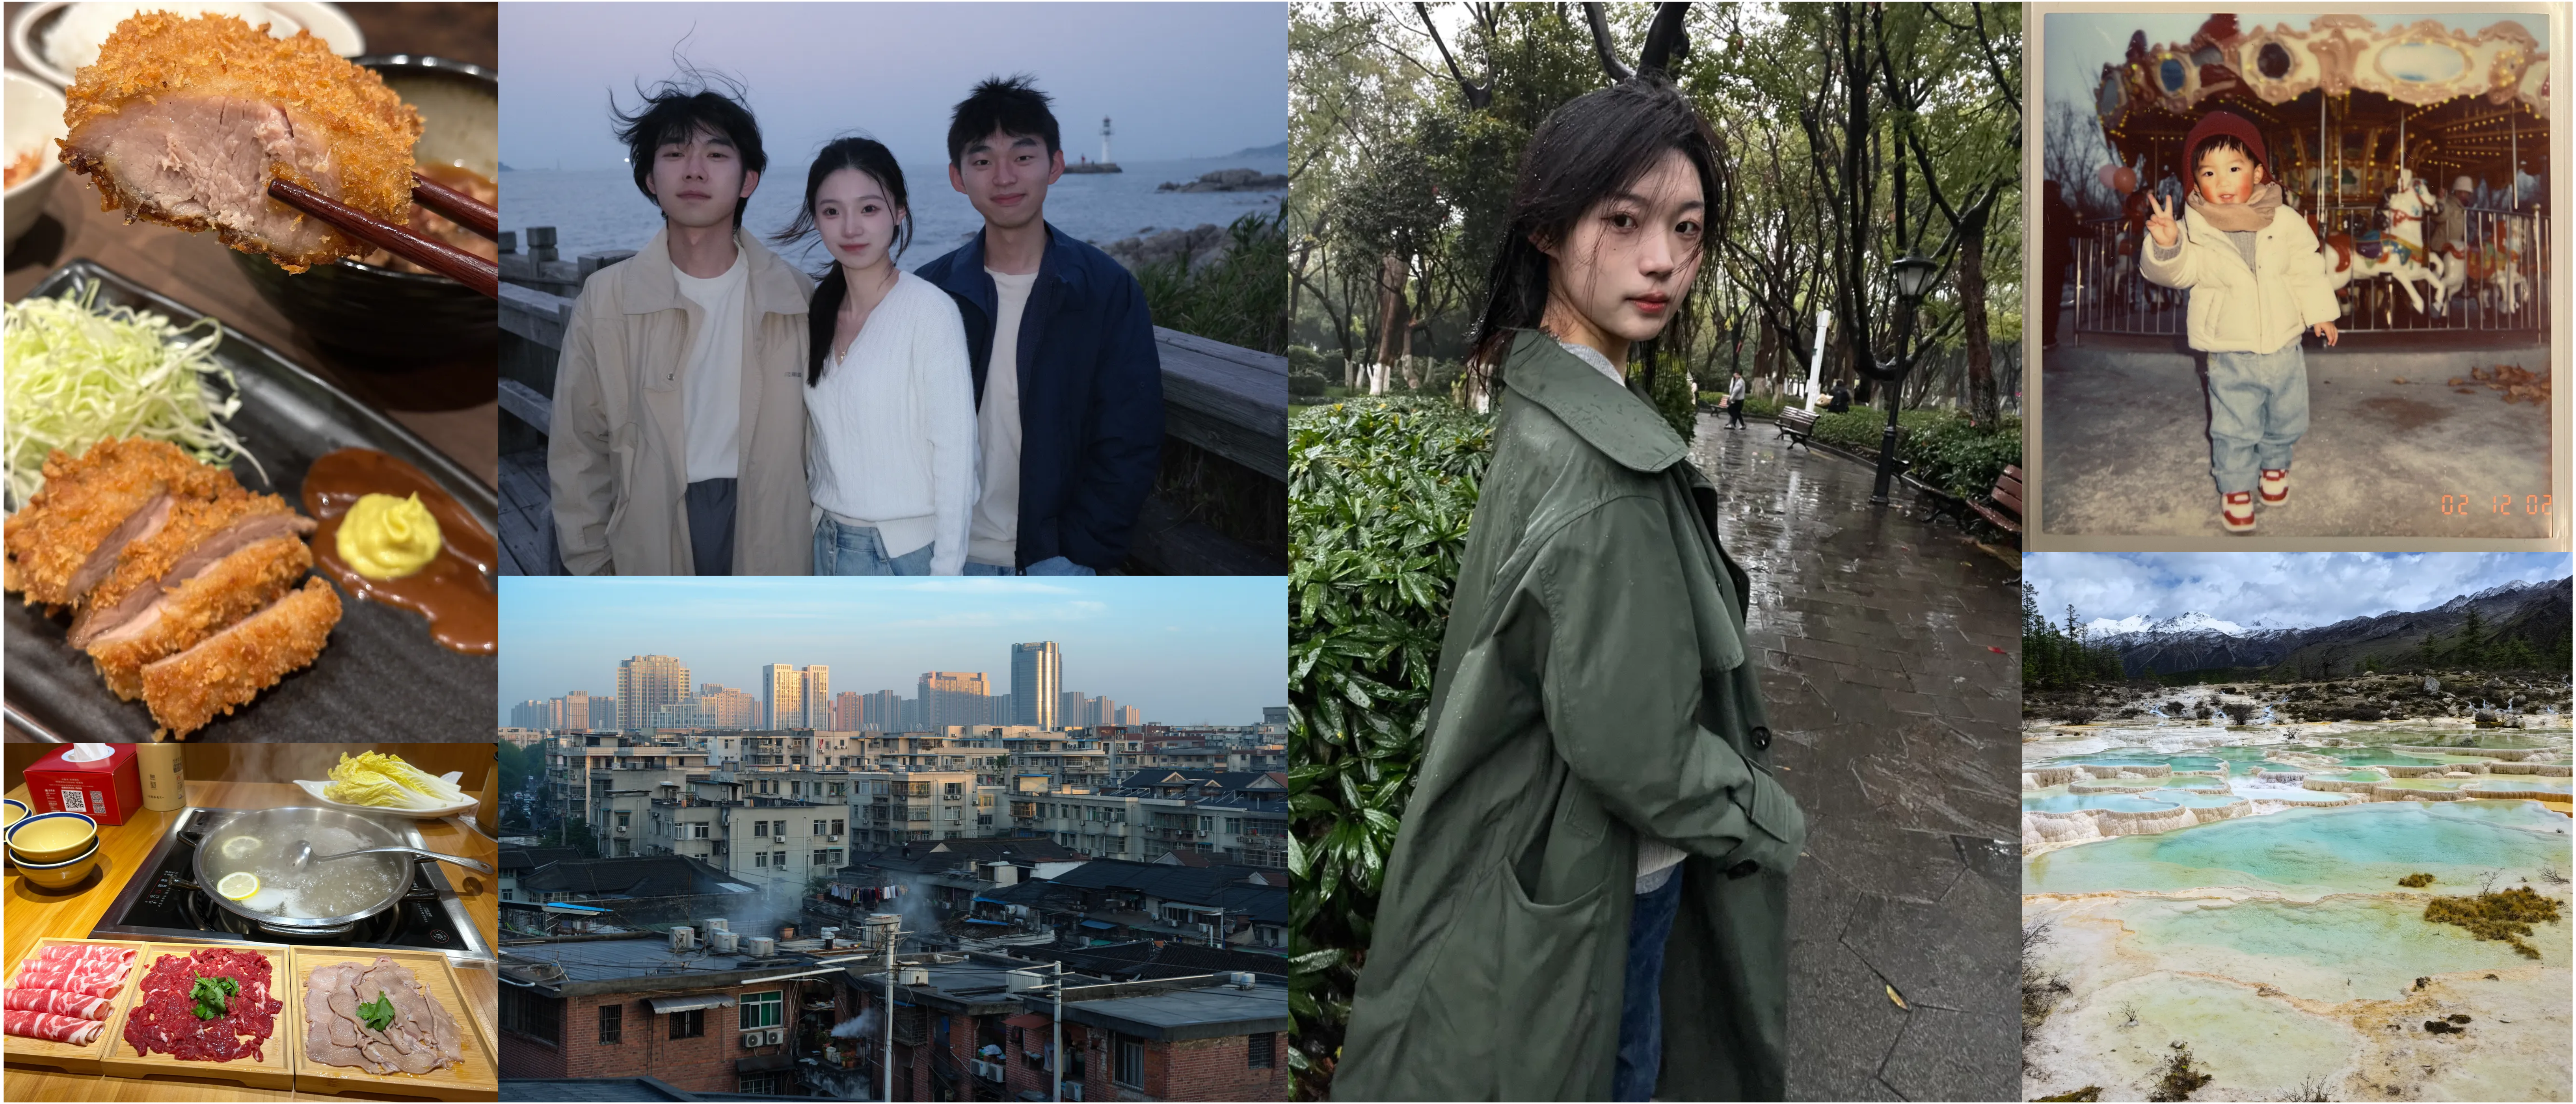
- **Realistic image generation.** LLaDA-Image produces high-quality images with rich visual details, natural lighting, and coherent compositions.
- **Image-only pre-training for visual-prior learning.** The report establishes the visual prior through image-only pre-training and mid-training before introducing paired language supervision and joint generation--editing training.
- **Efficient inference with distilled model.** LLaDA-Image-Turbo uses Twin-DMD distillation to deliver fast image generation and editing in only 2--4 sampling steps.
- **SOTA on Qwen-Image-Bench.** LLaDA-Image achieves state-of-the-art overall scores of 53.53 in English and 53.38 in Chinese.
## Model Zoo
| Model | Description | Sampling steps | Hugging Face |
| --- | --- | ---: | --- |
| **LLaDA-Image** | Base model for high-fidelity text-to-image generation and instruction-guided editing. | 50 | [inclusionAI/LLaDA-Image](https://huggingface.co/inclusionAI/LLaDA-Image) |
| **LLaDA-Image-Turbo** | Distilled model for fast generation and editing. | 4 | [inclusionAI/LLaDA-Image-Turbo](https://huggingface.co/inclusionAI/LLaDA-Image-Turbo) |
## Quick Start
### 1. Create an environment
The implementation has been used with Python 3.11, PyTorch 2.8, Transformers 4.57.6, and Diffusers 0.39.0.
```bash
git clone https://github.com/inclusionAI/LLaDA-Image.git
cd LLaDA-Image
pip install -r requirements.txt
```
The published LLaDA2 text encoder uses `veomni.ops.fused_moe_forward`. Install a compatible LLaDA2 / VeOmni runtime before running inference.
### 2. Run inference
The pipeline accepts a prompt and, for editing, an optional reference image.
#### LLaDA-Image (Base)
Use the Base checkpoint for high-fidelity generation and editing. Its recommended sampling configuration is **50 steps**.
```python
import torch
from src import LLaDAImagePipeline
# Load the pipeline. The model is downloaded from Hugging Face on first use.
pipe = LLaDAImagePipeline.from_pretrained(
"inclusionAI/LLaDA-Image",
torch_dtype=torch.bfloat16,
device="cuda",
)
# Generate an image.
prompt = (
"A cinematic photograph of a red fox standing in fresh snow, "
"soft winter light, detailed fur, shallow depth of field"
)
negative_prompt = ""
image = pipe(
prompt=prompt,
negative_prompt=negative_prompt,
generation_mode="text",
height=1024,
width=1024,
num_inference_steps=50,
guidance_scale=5.0,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("llada-image-base.png")
```
#### LLaDA-Image-Turbo
Use the Turbo checkpoint for fast generation and editing. Its recommended sampling configuration is **4 steps**.
```python
import torch
from src import LLaDAImagePipeline
# Load the distilled Turbo checkpoint.
pipe = LLaDAImagePipeline.from_pretrained(
"inclusionAI/LLaDA-Image-Turbo",
torch_dtype=torch.bfloat16,
device="cuda",
)
prompt = "A quiet observatory above a sea of clouds at sunrise, golden light, wide-angle photograph"
image = pipe(
prompt=prompt,
generation_mode="text",
height=1024,
width=1024,
num_inference_steps=4,
guidance_scale=1.0,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("llada-image-turbo.png")
```
#### Generation modes
Both checkpoints support the following modes. Text and VQ-conditioned generation require height and width divisible by 16; image editing requires dimensions divisible by 32.
**VQ-conditioned generation** uses the LLaDA2 model to produce image VQ tokens from the prompt, which SigVQ embeds before diffusion. Do not provide an input image in VQ mode.
```python
image = pipe(
prompt="A quiet observatory above a sea of clouds at sunrise",
generation_mode="vq",
height=1024,
width=1024,
num_inference_steps=50, # Use 4 for LLaDA-Image-Turbo.
guidance_scale=5.0, # Use 1.0 for few-step inference.
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
```
**Image editing** requires a reference image:
```python
from diffusers.utils import load_image
reference_image = load_image("/path/to/input.png")
image = pipe(
prompt="Turn it into a watercolor painting",
image=reference_image,
generation_mode="editing",
height=1024,
width=1024,
num_inference_steps=50, # Use 4 for LLaDA-Image-Turbo.
guidance_scale=5.0, # Use 1.0 for few-step inference.
generator=torch.Generator("cuda").manual_seed(43),
).images[0]
```
## Citation
If you find LLaDA-Image useful for your research or applications, please consider citing our work.
TODO