

Spatial-Interactor
Collection
Models and data for Spatial-Interactor: Learning Spatial Reasoning through Interaction with the Observable Physical World. • 6 items • Updated • 4
docker model run hf.co/kagakouko/Spatial-Interactor-Qwen2.5-VL-3B
Learning Spatial Reasoning through Interaction with the Observable Physical World


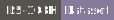
This is the full-parameter BF16 Spatial-Interactor checkpoint based on Qwen/Qwen2.5-VL-3B-Instruct. It learns local world-state and ego-motion transitions through supervised fine-tuning, then uses On-Policy Distillation (OPD) to integrate successive transitions over long trajectories.
The privileged transition trace is used only during training. At inference, this checkpoint takes the same image/video and question inputs as its base model, with no extra trace, reward model, or teacher branch.
import torch
from transformers import AutoModelForImageTextToText, AutoProcessor
model_id = "kagakouko/Spatial-Interactor-Qwen2.5-VL-3B"
processor = AutoProcessor.from_pretrained(model_id)
model = AutoModelForImageTextToText.from_pretrained(
model_id, torch_dtype=torch.bfloat16, device_map="auto",
)
Use the base model's image/video input format. No privileged trace or additional teacher is needed for inference. Weights, tokenizer, processor, and chat template are included. See the training guide for SFT and OPD.
For citation, use the project BibTeX.
This checkpoint follows the Qwen Research License of the base model. Users must also comply with licenses and terms governing input datasets and media.
Install from pip and serve model
# Install vLLM from pip: pip install vllm# Start the vLLM server: vllm serve "kagakouko/Spatial-Interactor-Qwen2.5-VL-3B"# Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "kagakouko/Spatial-Interactor-Qwen2.5-VL-3B", "messages": [ { "role": "user", "content": [ { "type": "text", "text": "Describe this image in one sentence." }, { "type": "image_url", "image_url": { "url": "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg" } } ] } ] }'