


Publish hopper_tensor_core_fp16 kernel and performance card
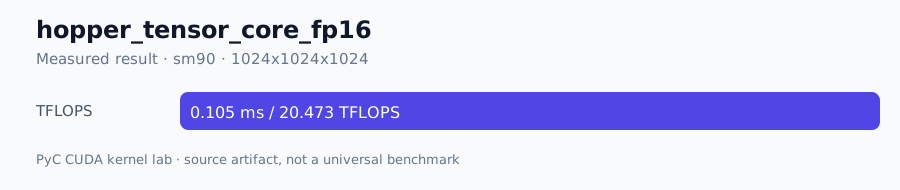
Browse filesCUDA source, short description, performance table, and plot.
- README.md +40 -0
- kernel.cu +450 -0
- performance.svg +8 -0
README.md
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
tags:
|
| 4 |
+
- cuda
|
| 5 |
+
- kernel
|
| 6 |
+
- gpu-optimization
|
| 7 |
+
- hpc
|
| 8 |
+
---
|
| 9 |
+
|
| 10 |
+
# hopper_tensor_core_fp16
|
| 11 |
+
|
| 12 |
+
Hopper Tensor Core FP16 GEMM prototype with a 64x64x16 WMMA tile and larger per-block warpgroup-style work.
|
| 13 |
+
|
| 14 |
+
This repository contains the standalone CUDA source for the `hopper_tensor_core_fp16` lane from
|
| 15 |
+
the PyC kernel lab. It is a source artifact for inspection and benchmarking;
|
| 16 |
+
it is not a precompiled binary and the result below is not a universal ranking.
|
| 17 |
+
|
| 18 |
+
## Performance
|
| 19 |
+
|
| 20 |
+
| Kernel | GPU / architecture | Shape | Best recorded result | Evidence |
|
| 21 |
+
|---|---|---|---|---|
|
| 22 |
+
| `hopper_tensor_core_fp16` | sm90 | 1024x1024x1024 | 0.105 ms / 20.473 TFLOPS | Measured on sm90, shape 1024x1024x1024; evidence `hopper-tensorcore-bringup-20260421T191817Z.json`. |
|
| 23 |
+
|
| 24 |
+

|
| 25 |
+
|
| 26 |
+
The result is reported with the original campaign's timing and correctness
|
| 27 |
+
context. Compare kernels only when GPU, CUDA version, matrix shape, warmup,
|
| 28 |
+
repeats, and reference/correctness mode match.
|
| 29 |
+
|
| 30 |
+
## Source
|
| 31 |
+
|
| 32 |
+
- `kernel.cu` — copied from `kernels/prototypes/hopper/tensor_core/kernel.cu`.
|
| 33 |
+
- Original lane tags: `cuda, matmul, hopper, sm90, prototype, tensor-core, fp16`.
|
| 34 |
+
|
| 35 |
+
## Build/run contract
|
| 36 |
+
|
| 37 |
+
```text
|
| 38 |
+
{nvcc} -O3 -std=c++17 -lineinfo -DPYC_HOPPER_TENSOR_CORE_USE_BF16=0 -gencode arch=compute_90,code=sm_90 -gencode arch=compute_90,code=compute_90 {source} -o {build_dir}/{name}
|
| 39 |
+
{build_dir}/{name} 1024 1024 1024 5 20
|
| 40 |
+
```
|
kernel.cu
ADDED
|
@@ -0,0 +1,450 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#include <cuda_runtime.h>
|
| 2 |
+
#include <mma.h>
|
| 3 |
+
|
| 4 |
+
#include <math.h>
|
| 5 |
+
#include <stdint.h>
|
| 6 |
+
#include <stdio.h>
|
| 7 |
+
#include <stdlib.h>
|
| 8 |
+
#include <string.h>
|
| 9 |
+
|
| 10 |
+
#if defined(PYC_HOPPER_TENSOR_CORE_USE_BF16) && PYC_HOPPER_TENSOR_CORE_USE_BF16
|
| 11 |
+
#include <cuda_bf16.h>
|
| 12 |
+
typedef __nv_bfloat16 pyc_hopper_tc_scalar_t;
|
| 13 |
+
#define PYC_HOPPER_TC_LANE_NAME "bf16"
|
| 14 |
+
static __host__ __device__ inline pyc_hopper_tc_scalar_t pyc_hopper_tc_make_scalar(float value) {
|
| 15 |
+
return __float2bfloat16(value);
|
| 16 |
+
}
|
| 17 |
+
static __host__ __device__ inline float pyc_hopper_tc_scalar_to_float(pyc_hopper_tc_scalar_t value) {
|
| 18 |
+
return __bfloat162float(value);
|
| 19 |
+
}
|
| 20 |
+
#else
|
| 21 |
+
#include <cuda_fp16.h>
|
| 22 |
+
typedef half pyc_hopper_tc_scalar_t;
|
| 23 |
+
#define PYC_HOPPER_TC_LANE_NAME "fp16"
|
| 24 |
+
static __host__ __device__ inline pyc_hopper_tc_scalar_t pyc_hopper_tc_make_scalar(float value) {
|
| 25 |
+
return __float2half(value);
|
| 26 |
+
}
|
| 27 |
+
static __host__ __device__ inline float pyc_hopper_tc_scalar_to_float(pyc_hopper_tc_scalar_t value) {
|
| 28 |
+
return __half2float(value);
|
| 29 |
+
}
|
| 30 |
+
#endif
|
| 31 |
+
|
| 32 |
+
namespace wmma = nvcuda::wmma;
|
| 33 |
+
|
| 34 |
+
#ifndef PYC_HOPPER_TC_MMA_TILE_M
|
| 35 |
+
#define PYC_HOPPER_TC_MMA_TILE_M 16
|
| 36 |
+
#endif
|
| 37 |
+
|
| 38 |
+
#ifndef PYC_HOPPER_TC_MMA_TILE_N
|
| 39 |
+
#define PYC_HOPPER_TC_MMA_TILE_N 16
|
| 40 |
+
#endif
|
| 41 |
+
|
| 42 |
+
#ifndef PYC_HOPPER_TC_MMA_TILE_K
|
| 43 |
+
#define PYC_HOPPER_TC_MMA_TILE_K 16
|
| 44 |
+
#endif
|
| 45 |
+
|
| 46 |
+
#ifndef PYC_HOPPER_TC_WARP_ROW_TILES
|
| 47 |
+
#define PYC_HOPPER_TC_WARP_ROW_TILES 1
|
| 48 |
+
#endif
|
| 49 |
+
|
| 50 |
+
#ifndef PYC_HOPPER_TC_WARP_COL_TILES
|
| 51 |
+
#define PYC_HOPPER_TC_WARP_COL_TILES 1
|
| 52 |
+
#endif
|
| 53 |
+
|
| 54 |
+
#ifndef PYC_HOPPER_TC_WARP_ROW_GROUPS
|
| 55 |
+
#define PYC_HOPPER_TC_WARP_ROW_GROUPS 4
|
| 56 |
+
#endif
|
| 57 |
+
|
| 58 |
+
#ifndef PYC_HOPPER_TC_WARP_COL_GROUPS
|
| 59 |
+
#define PYC_HOPPER_TC_WARP_COL_GROUPS 4
|
| 60 |
+
#endif
|
| 61 |
+
|
| 62 |
+
#ifndef PYC_HOPPER_TC_TILE_K
|
| 63 |
+
#define PYC_HOPPER_TC_TILE_K 16
|
| 64 |
+
#endif
|
| 65 |
+
|
| 66 |
+
#ifndef PYC_HOPPER_TC_SHARED_PAD_A
|
| 67 |
+
#define PYC_HOPPER_TC_SHARED_PAD_A 0
|
| 68 |
+
#endif
|
| 69 |
+
|
| 70 |
+
#ifndef PYC_HOPPER_TC_SHARED_PAD_B
|
| 71 |
+
#define PYC_HOPPER_TC_SHARED_PAD_B 0
|
| 72 |
+
#endif
|
| 73 |
+
|
| 74 |
+
#define PYC_HOPPER_TC_WARP_TILE_M (PYC_HOPPER_TC_MMA_TILE_M * PYC_HOPPER_TC_WARP_ROW_TILES)
|
| 75 |
+
#define PYC_HOPPER_TC_WARP_TILE_N (PYC_HOPPER_TC_MMA_TILE_N * PYC_HOPPER_TC_WARP_COL_TILES)
|
| 76 |
+
#define PYC_HOPPER_TC_TILE_M (PYC_HOPPER_TC_WARP_TILE_M * PYC_HOPPER_TC_WARP_ROW_GROUPS)
|
| 77 |
+
#define PYC_HOPPER_TC_TILE_N (PYC_HOPPER_TC_WARP_TILE_N * PYC_HOPPER_TC_WARP_COL_GROUPS)
|
| 78 |
+
#define PYC_HOPPER_TC_WARPS_PER_BLOCK (PYC_HOPPER_TC_WARP_ROW_GROUPS * PYC_HOPPER_TC_WARP_COL_GROUPS)
|
| 79 |
+
#define PYC_HOPPER_TC_THREADS_PER_BLOCK (PYC_HOPPER_TC_WARPS_PER_BLOCK * 32)
|
| 80 |
+
#define PYC_HOPPER_TC_SHARED_STRIDE_A (PYC_HOPPER_TC_TILE_K + PYC_HOPPER_TC_SHARED_PAD_A)
|
| 81 |
+
#define PYC_HOPPER_TC_SHARED_STRIDE_B (PYC_HOPPER_TC_TILE_K + PYC_HOPPER_TC_SHARED_PAD_B)
|
| 82 |
+
|
| 83 |
+
typedef struct {
|
| 84 |
+
int m;
|
| 85 |
+
int n;
|
| 86 |
+
int k;
|
| 87 |
+
int warmup;
|
| 88 |
+
int iters;
|
| 89 |
+
int skip_reference;
|
| 90 |
+
} pyc_hopper_tc_config;
|
| 91 |
+
|
| 92 |
+
static int check_cuda(cudaError_t status, const char* what) {
|
| 93 |
+
if (status != cudaSuccess) {
|
| 94 |
+
fprintf(stderr, "%s failed: %s\n", what, cudaGetErrorString(status));
|
| 95 |
+
return -1;
|
| 96 |
+
}
|
| 97 |
+
return 0;
|
| 98 |
+
}
|
| 99 |
+
|
| 100 |
+
static int parse_int_arg(const char* text, int* out_value) {
|
| 101 |
+
char* end = NULL;
|
| 102 |
+
long parsed;
|
| 103 |
+
if (!text || !out_value) {
|
| 104 |
+
return -1;
|
| 105 |
+
}
|
| 106 |
+
parsed = strtol(text, &end, 10);
|
| 107 |
+
if (end == text || *end != '\0' || parsed < 0 || parsed > INT32_MAX) {
|
| 108 |
+
return -1;
|
| 109 |
+
}
|
| 110 |
+
*out_value = (int)parsed;
|
| 111 |
+
return 0;
|
| 112 |
+
}
|
| 113 |
+
|
| 114 |
+
static int env_flag(const char* name, int default_value) {
|
| 115 |
+
const char* raw = getenv(name);
|
| 116 |
+
if (!raw || raw[0] == '\0') {
|
| 117 |
+
return default_value;
|
| 118 |
+
}
|
| 119 |
+
if (
|
| 120 |
+
strcmp(raw, "1") == 0 || strcmp(raw, "true") == 0 || strcmp(raw, "TRUE") == 0
|
| 121 |
+
|| strcmp(raw, "yes") == 0 || strcmp(raw, "on") == 0) {
|
| 122 |
+
return 1;
|
| 123 |
+
}
|
| 124 |
+
if (
|
| 125 |
+
strcmp(raw, "0") == 0 || strcmp(raw, "false") == 0 || strcmp(raw, "FALSE") == 0
|
| 126 |
+
|| strcmp(raw, "no") == 0 || strcmp(raw, "off") == 0) {
|
| 127 |
+
return 0;
|
| 128 |
+
}
|
| 129 |
+
return default_value;
|
| 130 |
+
}
|
| 131 |
+
|
| 132 |
+
static void fill_matrix(pyc_hopper_tc_scalar_t* data, int rows, int cols, float scale) {
|
| 133 |
+
int i;
|
| 134 |
+
for (i = 0; i < rows * cols; ++i) {
|
| 135 |
+
int pattern = (i * 23 + rows * 13 + cols * 5) % 31;
|
| 136 |
+
data[i] = pyc_hopper_tc_make_scalar(((float)pattern - 15.0f) * scale);
|
| 137 |
+
}
|
| 138 |
+
}
|
| 139 |
+
|
| 140 |
+
static void reference_gemm(
|
| 141 |
+
const pyc_hopper_tc_scalar_t* a,
|
| 142 |
+
const pyc_hopper_tc_scalar_t* b,
|
| 143 |
+
float* c,
|
| 144 |
+
int m,
|
| 145 |
+
int n,
|
| 146 |
+
int k) {
|
| 147 |
+
int row;
|
| 148 |
+
for (row = 0; row < m; ++row) {
|
| 149 |
+
int col;
|
| 150 |
+
for (col = 0; col < n; ++col) {
|
| 151 |
+
float acc = 0.0f;
|
| 152 |
+
int kk;
|
| 153 |
+
for (kk = 0; kk < k; ++kk) {
|
| 154 |
+
acc += pyc_hopper_tc_scalar_to_float(a[row * k + kk]) * pyc_hopper_tc_scalar_to_float(b[kk * n + col]);
|
| 155 |
+
}
|
| 156 |
+
c[row * n + col] = acc;
|
| 157 |
+
}
|
| 158 |
+
}
|
| 159 |
+
}
|
| 160 |
+
|
| 161 |
+
__launch_bounds__(PYC_HOPPER_TC_THREADS_PER_BLOCK, 1)
|
| 162 |
+
__global__ void pyc_hopper_tc_gemm_kernel(
|
| 163 |
+
const pyc_hopper_tc_scalar_t* __restrict__ a,
|
| 164 |
+
const pyc_hopper_tc_scalar_t* __restrict__ b,
|
| 165 |
+
float* __restrict__ c,
|
| 166 |
+
int m,
|
| 167 |
+
int n,
|
| 168 |
+
int k) {
|
| 169 |
+
__shared__ __align__(16) pyc_hopper_tc_scalar_t shared_a[PYC_HOPPER_TC_TILE_M][PYC_HOPPER_TC_SHARED_STRIDE_A];
|
| 170 |
+
__shared__ __align__(16) pyc_hopper_tc_scalar_t shared_b[PYC_HOPPER_TC_TILE_N][PYC_HOPPER_TC_SHARED_STRIDE_B];
|
| 171 |
+
|
| 172 |
+
const int warp_id = threadIdx.x / 32;
|
| 173 |
+
const int block_row = blockIdx.y * PYC_HOPPER_TC_TILE_M;
|
| 174 |
+
const int block_col = blockIdx.x * PYC_HOPPER_TC_TILE_N;
|
| 175 |
+
const int warp_row_group = warp_id / PYC_HOPPER_TC_WARP_COL_GROUPS;
|
| 176 |
+
const int warp_col_group = warp_id % PYC_HOPPER_TC_WARP_COL_GROUPS;
|
| 177 |
+
const int warp_row = warp_row_group * PYC_HOPPER_TC_WARP_TILE_M;
|
| 178 |
+
const int warp_col = warp_col_group * PYC_HOPPER_TC_WARP_TILE_N;
|
| 179 |
+
|
| 180 |
+
wmma::fragment<wmma::accumulator, 16, 16, 16, float> acc[PYC_HOPPER_TC_WARP_ROW_TILES][PYC_HOPPER_TC_WARP_COL_TILES];
|
| 181 |
+
|
| 182 |
+
if (warp_id >= PYC_HOPPER_TC_WARPS_PER_BLOCK) {
|
| 183 |
+
return;
|
| 184 |
+
}
|
| 185 |
+
|
| 186 |
+
for (int row_tile = 0; row_tile < PYC_HOPPER_TC_WARP_ROW_TILES; ++row_tile) {
|
| 187 |
+
for (int col_tile = 0; col_tile < PYC_HOPPER_TC_WARP_COL_TILES; ++col_tile) {
|
| 188 |
+
wmma::fill_fragment(acc[row_tile][col_tile], 0.0f);
|
| 189 |
+
}
|
| 190 |
+
}
|
| 191 |
+
|
| 192 |
+
for (int kk = 0; kk < k; kk += PYC_HOPPER_TC_TILE_K) {
|
| 193 |
+
int idx;
|
| 194 |
+
|
| 195 |
+
for (idx = threadIdx.x; idx < PYC_HOPPER_TC_TILE_M * PYC_HOPPER_TC_TILE_K; idx += blockDim.x) {
|
| 196 |
+
const int row = idx / PYC_HOPPER_TC_TILE_K;
|
| 197 |
+
const int col = idx % PYC_HOPPER_TC_TILE_K;
|
| 198 |
+
const int g_row = block_row + row;
|
| 199 |
+
const int g_col = kk + col;
|
| 200 |
+
if (g_row < m && g_col < k) {
|
| 201 |
+
shared_a[row][col] = a[g_row * k + g_col];
|
| 202 |
+
} else {
|
| 203 |
+
shared_a[row][col] = pyc_hopper_tc_make_scalar(0.0f);
|
| 204 |
+
}
|
| 205 |
+
}
|
| 206 |
+
|
| 207 |
+
for (idx = threadIdx.x; idx < PYC_HOPPER_TC_TILE_N * PYC_HOPPER_TC_TILE_K; idx += blockDim.x) {
|
| 208 |
+
const int row = idx / PYC_HOPPER_TC_TILE_K;
|
| 209 |
+
const int col = idx % PYC_HOPPER_TC_TILE_K;
|
| 210 |
+
const int g_row = kk + col;
|
| 211 |
+
const int g_col = block_col + row;
|
| 212 |
+
if (g_row < k && g_col < n) {
|
| 213 |
+
shared_b[row][col] = b[g_row * n + g_col];
|
| 214 |
+
} else {
|
| 215 |
+
shared_b[row][col] = pyc_hopper_tc_make_scalar(0.0f);
|
| 216 |
+
}
|
| 217 |
+
}
|
| 218 |
+
|
| 219 |
+
__syncthreads();
|
| 220 |
+
|
| 221 |
+
for (int k_frag = 0; k_frag < PYC_HOPPER_TC_TILE_K; k_frag += PYC_HOPPER_TC_MMA_TILE_K) {
|
| 222 |
+
wmma::fragment<wmma::matrix_a, 16, 16, 16, pyc_hopper_tc_scalar_t, wmma::row_major> a_frag[PYC_HOPPER_TC_WARP_ROW_TILES];
|
| 223 |
+
wmma::fragment<wmma::matrix_b, 16, 16, 16, pyc_hopper_tc_scalar_t, wmma::col_major> b_frag[PYC_HOPPER_TC_WARP_COL_TILES];
|
| 224 |
+
|
| 225 |
+
for (int row_tile = 0; row_tile < PYC_HOPPER_TC_WARP_ROW_TILES; ++row_tile) {
|
| 226 |
+
const int a_row = warp_row + row_tile * PYC_HOPPER_TC_MMA_TILE_M;
|
| 227 |
+
wmma::load_matrix_sync(a_frag[row_tile], &shared_a[a_row][k_frag], PYC_HOPPER_TC_SHARED_STRIDE_A);
|
| 228 |
+
}
|
| 229 |
+
|
| 230 |
+
for (int col_tile = 0; col_tile < PYC_HOPPER_TC_WARP_COL_TILES; ++col_tile) {
|
| 231 |
+
const int b_row = warp_col + col_tile * PYC_HOPPER_TC_MMA_TILE_N;
|
| 232 |
+
wmma::load_matrix_sync(b_frag[col_tile], &shared_b[b_row][k_frag], PYC_HOPPER_TC_SHARED_STRIDE_B);
|
| 233 |
+
}
|
| 234 |
+
|
| 235 |
+
for (int row_tile = 0; row_tile < PYC_HOPPER_TC_WARP_ROW_TILES; ++row_tile) {
|
| 236 |
+
for (int col_tile = 0; col_tile < PYC_HOPPER_TC_WARP_COL_TILES; ++col_tile) {
|
| 237 |
+
wmma::mma_sync(acc[row_tile][col_tile], a_frag[row_tile], b_frag[col_tile], acc[row_tile][col_tile]);
|
| 238 |
+
}
|
| 239 |
+
}
|
| 240 |
+
}
|
| 241 |
+
|
| 242 |
+
__syncthreads();
|
| 243 |
+
}
|
| 244 |
+
|
| 245 |
+
for (int row_tile = 0; row_tile < PYC_HOPPER_TC_WARP_ROW_TILES; ++row_tile) {
|
| 246 |
+
const int c_row = block_row + warp_row + row_tile * PYC_HOPPER_TC_MMA_TILE_M;
|
| 247 |
+
for (int col_tile = 0; col_tile < PYC_HOPPER_TC_WARP_COL_TILES; ++col_tile) {
|
| 248 |
+
const int c_col = block_col + warp_col + col_tile * PYC_HOPPER_TC_MMA_TILE_N;
|
| 249 |
+
if (c_row < m && c_col < n) {
|
| 250 |
+
wmma::store_matrix_sync(&c[c_row * n + c_col], acc[row_tile][col_tile], n, wmma::mem_row_major);
|
| 251 |
+
}
|
| 252 |
+
}
|
| 253 |
+
}
|
| 254 |
+
}
|
| 255 |
+
|
| 256 |
+
static int set_kernel_attributes(void) {
|
| 257 |
+
cudaError_t status;
|
| 258 |
+
|
| 259 |
+
status = cudaFuncSetAttribute(
|
| 260 |
+
pyc_hopper_tc_gemm_kernel,
|
| 261 |
+
cudaFuncAttributePreferredSharedMemoryCarveout,
|
| 262 |
+
100);
|
| 263 |
+
if (status != cudaSuccess && status != cudaErrorNotSupported) {
|
| 264 |
+
fprintf(stderr, "cudaFuncSetAttribute failed: %s\n", cudaGetErrorString(status));
|
| 265 |
+
return -1;
|
| 266 |
+
}
|
| 267 |
+
|
| 268 |
+
return 0;
|
| 269 |
+
}
|
| 270 |
+
|
| 271 |
+
static int parse_config(int argc, char** argv, pyc_hopper_tc_config* cfg) {
|
| 272 |
+
if (!cfg) {
|
| 273 |
+
return -1;
|
| 274 |
+
}
|
| 275 |
+
|
| 276 |
+
cfg->m = 1024;
|
| 277 |
+
cfg->n = 1024;
|
| 278 |
+
cfg->k = 1024;
|
| 279 |
+
cfg->warmup = 5;
|
| 280 |
+
cfg->iters = 20;
|
| 281 |
+
cfg->skip_reference = env_flag("PYC_HOPPER_TC_SKIP_REFERENCE", 0);
|
| 282 |
+
|
| 283 |
+
if (argc > 1 && parse_int_arg(argv[1], &cfg->m) != 0) return -1;
|
| 284 |
+
if (argc > 2 && parse_int_arg(argv[2], &cfg->n) != 0) return -1;
|
| 285 |
+
if (argc > 3 && parse_int_arg(argv[3], &cfg->k) != 0) return -1;
|
| 286 |
+
if (argc > 4 && parse_int_arg(argv[4], &cfg->warmup) != 0) return -1;
|
| 287 |
+
if (argc > 5 && parse_int_arg(argv[5], &cfg->iters) != 0) return -1;
|
| 288 |
+
if (argc > 6 && parse_int_arg(argv[6], &cfg->skip_reference) != 0) return -1;
|
| 289 |
+
|
| 290 |
+
return 0;
|
| 291 |
+
}
|
| 292 |
+
|
| 293 |
+
int main(int argc, char** argv) {
|
| 294 |
+
pyc_hopper_tc_config cfg;
|
| 295 |
+
struct cudaDeviceProp props;
|
| 296 |
+
pyc_hopper_tc_scalar_t* host_a = NULL;
|
| 297 |
+
pyc_hopper_tc_scalar_t* host_b = NULL;
|
| 298 |
+
float* host_c = NULL;
|
| 299 |
+
float* ref_c = NULL;
|
| 300 |
+
pyc_hopper_tc_scalar_t* dev_a = NULL;
|
| 301 |
+
pyc_hopper_tc_scalar_t* dev_b = NULL;
|
| 302 |
+
float* dev_c = NULL;
|
| 303 |
+
cudaEvent_t start = NULL;
|
| 304 |
+
cudaEvent_t stop = NULL;
|
| 305 |
+
size_t a_bytes;
|
| 306 |
+
size_t b_bytes;
|
| 307 |
+
size_t c_bytes;
|
| 308 |
+
dim3 block;
|
| 309 |
+
dim3 grid;
|
| 310 |
+
float elapsed_ms = 0.0f;
|
| 311 |
+
double best_ms = 0.0;
|
| 312 |
+
double max_abs_diff = 0.0;
|
| 313 |
+
int iter;
|
| 314 |
+
|
| 315 |
+
if (parse_config(argc, argv, &cfg) != 0) {
|
| 316 |
+
fprintf(stderr, "usage: %s [m] [n] [k] [warmup] [iters] [skip_reference]\n", argv[0]);
|
| 317 |
+
return 2;
|
| 318 |
+
}
|
| 319 |
+
|
| 320 |
+
if (
|
| 321 |
+
(cfg.m % PYC_HOPPER_TC_TILE_M) != 0 || (cfg.n % PYC_HOPPER_TC_TILE_N) != 0
|
| 322 |
+
|| (cfg.k % PYC_HOPPER_TC_TILE_K) != 0) {
|
| 323 |
+
fprintf(
|
| 324 |
+
stderr,
|
| 325 |
+
"Hopper Tensor Core lane requires %dx%dx%d-aligned shapes\n",
|
| 326 |
+
PYC_HOPPER_TC_TILE_M,
|
| 327 |
+
PYC_HOPPER_TC_TILE_N,
|
| 328 |
+
PYC_HOPPER_TC_TILE_K);
|
| 329 |
+
return 2;
|
| 330 |
+
}
|
| 331 |
+
|
| 332 |
+
if (check_cuda(cudaGetDeviceProperties(&props, 0), "cudaGetDeviceProperties") != 0) {
|
| 333 |
+
return 1;
|
| 334 |
+
}
|
| 335 |
+
if (props.major < 9) {
|
| 336 |
+
fprintf(stderr, "Hopper Tensor Core prototype requires sm_90-class hardware\n");
|
| 337 |
+
return 1;
|
| 338 |
+
}
|
| 339 |
+
|
| 340 |
+
a_bytes = (size_t)cfg.m * (size_t)cfg.k * sizeof(pyc_hopper_tc_scalar_t);
|
| 341 |
+
b_bytes = (size_t)cfg.k * (size_t)cfg.n * sizeof(pyc_hopper_tc_scalar_t);
|
| 342 |
+
c_bytes = (size_t)cfg.m * (size_t)cfg.n * sizeof(float);
|
| 343 |
+
|
| 344 |
+
host_a = (pyc_hopper_tc_scalar_t*)malloc(a_bytes);
|
| 345 |
+
host_b = (pyc_hopper_tc_scalar_t*)malloc(b_bytes);
|
| 346 |
+
if (!host_a || !host_b) {
|
| 347 |
+
fprintf(stderr, "host allocation failed\n");
|
| 348 |
+
return 1;
|
| 349 |
+
}
|
| 350 |
+
if (!cfg.skip_reference) {
|
| 351 |
+
host_c = (float*)malloc(c_bytes);
|
| 352 |
+
ref_c = (float*)malloc(c_bytes);
|
| 353 |
+
if (!host_c || !ref_c) {
|
| 354 |
+
fprintf(stderr, "host validation allocation failed\n");
|
| 355 |
+
return 1;
|
| 356 |
+
}
|
| 357 |
+
}
|
| 358 |
+
|
| 359 |
+
fill_matrix(host_a, cfg.m, cfg.k, 0.03125f);
|
| 360 |
+
fill_matrix(host_b, cfg.k, cfg.n, 0.0625f);
|
| 361 |
+
if (!cfg.skip_reference) {
|
| 362 |
+
reference_gemm(host_a, host_b, ref_c, cfg.m, cfg.n, cfg.k);
|
| 363 |
+
}
|
| 364 |
+
|
| 365 |
+
if (check_cuda(cudaMalloc((void**)&dev_a, a_bytes), "cudaMalloc(a)") != 0) return 1;
|
| 366 |
+
if (check_cuda(cudaMalloc((void**)&dev_b, b_bytes), "cudaMalloc(b)") != 0) return 1;
|
| 367 |
+
if (check_cuda(cudaMalloc((void**)&dev_c, c_bytes), "cudaMalloc(c)") != 0) return 1;
|
| 368 |
+
|
| 369 |
+
if (check_cuda(cudaMemcpy(dev_a, host_a, a_bytes, cudaMemcpyHostToDevice), "cudaMemcpy(a)") != 0) return 1;
|
| 370 |
+
if (check_cuda(cudaMemcpy(dev_b, host_b, b_bytes, cudaMemcpyHostToDevice), "cudaMemcpy(b)") != 0) return 1;
|
| 371 |
+
|
| 372 |
+
if (set_kernel_attributes() != 0) return 1;
|
| 373 |
+
|
| 374 |
+
block = dim3(PYC_HOPPER_TC_THREADS_PER_BLOCK, 1, 1);
|
| 375 |
+
grid = dim3(
|
| 376 |
+
(unsigned int)((cfg.n + PYC_HOPPER_TC_TILE_N - 1) / PYC_HOPPER_TC_TILE_N),
|
| 377 |
+
(unsigned int)((cfg.m + PYC_HOPPER_TC_TILE_M - 1) / PYC_HOPPER_TC_TILE_M),
|
| 378 |
+
1);
|
| 379 |
+
|
| 380 |
+
if (check_cuda(cudaEventCreate(&start), "cudaEventCreate(start)") != 0) return 1;
|
| 381 |
+
if (check_cuda(cudaEventCreate(&stop), "cudaEventCreate(stop)") != 0) return 1;
|
| 382 |
+
|
| 383 |
+
for (iter = 0; iter < cfg.warmup; ++iter) {
|
| 384 |
+
pyc_hopper_tc_gemm_kernel<<<grid, block>>>(dev_a, dev_b, dev_c, cfg.m, cfg.n, cfg.k);
|
| 385 |
+
}
|
| 386 |
+
if (check_cuda(cudaGetLastError(), "kernel launch warmup") != 0) return 1;
|
| 387 |
+
if (check_cuda(cudaDeviceSynchronize(), "cudaDeviceSynchronize warmup") != 0) return 1;
|
| 388 |
+
|
| 389 |
+
best_ms = 0.0;
|
| 390 |
+
for (iter = 0; iter < cfg.iters; ++iter) {
|
| 391 |
+
if (check_cuda(cudaEventRecord(start), "cudaEventRecord(start)") != 0) return 1;
|
| 392 |
+
pyc_hopper_tc_gemm_kernel<<<grid, block>>>(dev_a, dev_b, dev_c, cfg.m, cfg.n, cfg.k);
|
| 393 |
+
if (check_cuda(cudaEventRecord(stop), "cudaEventRecord(stop)") != 0) return 1;
|
| 394 |
+
if (check_cuda(cudaEventSynchronize(stop), "cudaEventSynchronize(stop)") != 0) return 1;
|
| 395 |
+
if (check_cuda(cudaEventElapsedTime(&elapsed_ms, start, stop), "cudaEventElapsedTime") != 0) return 1;
|
| 396 |
+
if (iter == 0 || elapsed_ms < (float)best_ms) {
|
| 397 |
+
best_ms = elapsed_ms;
|
| 398 |
+
}
|
| 399 |
+
}
|
| 400 |
+
|
| 401 |
+
if (!cfg.skip_reference) {
|
| 402 |
+
if (check_cuda(cudaMemcpy(host_c, dev_c, c_bytes, cudaMemcpyDeviceToHost), "cudaMemcpy(c)") != 0) return 1;
|
| 403 |
+
for (iter = 0; iter < cfg.m * cfg.n; ++iter) {
|
| 404 |
+
double diff = fabs((double)host_c[iter] - (double)ref_c[iter]);
|
| 405 |
+
if (diff > max_abs_diff) {
|
| 406 |
+
max_abs_diff = diff;
|
| 407 |
+
}
|
| 408 |
+
}
|
| 409 |
+
}
|
| 410 |
+
|
| 411 |
+
printf("kernel=hopper_tensor_core\n");
|
| 412 |
+
printf("lane=%s\n", PYC_HOPPER_TC_LANE_NAME);
|
| 413 |
+
printf("arch=sm%d%d\n", props.major, props.minor);
|
| 414 |
+
printf("shape=%dx%dx%d\n", cfg.m, cfg.n, cfg.k);
|
| 415 |
+
printf(
|
| 416 |
+
"tile=%dx%dx%d warp_tile=%dx%d warp_groups=%dx%d pads=%dx%d warps=%d threads=%d\n",
|
| 417 |
+
PYC_HOPPER_TC_TILE_M,
|
| 418 |
+
PYC_HOPPER_TC_TILE_N,
|
| 419 |
+
PYC_HOPPER_TC_TILE_K,
|
| 420 |
+
PYC_HOPPER_TC_WARP_TILE_M,
|
| 421 |
+
PYC_HOPPER_TC_WARP_TILE_N,
|
| 422 |
+
PYC_HOPPER_TC_WARP_ROW_GROUPS,
|
| 423 |
+
PYC_HOPPER_TC_WARP_COL_GROUPS,
|
| 424 |
+
PYC_HOPPER_TC_SHARED_PAD_A,
|
| 425 |
+
PYC_HOPPER_TC_SHARED_PAD_B,
|
| 426 |
+
PYC_HOPPER_TC_WARPS_PER_BLOCK,
|
| 427 |
+
PYC_HOPPER_TC_THREADS_PER_BLOCK);
|
| 428 |
+
printf("skip_reference=%d\n", cfg.skip_reference);
|
| 429 |
+
printf("best_ms=%.3f\n", best_ms);
|
| 430 |
+
if (!cfg.skip_reference) {
|
| 431 |
+
printf("max_abs_diff=%.6f\n", max_abs_diff);
|
| 432 |
+
}
|
| 433 |
+
if (best_ms > 0.0) {
|
| 434 |
+
double flops = 2.0 * (double)cfg.m * (double)cfg.n * (double)cfg.k;
|
| 435 |
+
double gflops = flops / (best_ms * 1.0e6);
|
| 436 |
+
printf("gflops=%.3f\n", gflops);
|
| 437 |
+
printf("tflops=%.3f\n", gflops / 1000.0);
|
| 438 |
+
}
|
| 439 |
+
|
| 440 |
+
cudaEventDestroy(start);
|
| 441 |
+
cudaEventDestroy(stop);
|
| 442 |
+
cudaFree(dev_a);
|
| 443 |
+
cudaFree(dev_b);
|
| 444 |
+
cudaFree(dev_c);
|
| 445 |
+
free(host_a);
|
| 446 |
+
free(host_b);
|
| 447 |
+
free(host_c);
|
| 448 |
+
free(ref_c);
|
| 449 |
+
return (cfg.skip_reference || max_abs_diff <= 0.2) ? 0 : 1;
|
| 450 |
+
}
|
performance.svg
ADDED
|