

Add files using upload-large-folder tool
Browse files- .gitattributes +8 -0
- code/assets/layer_decompose_5layers.txt +8 -0
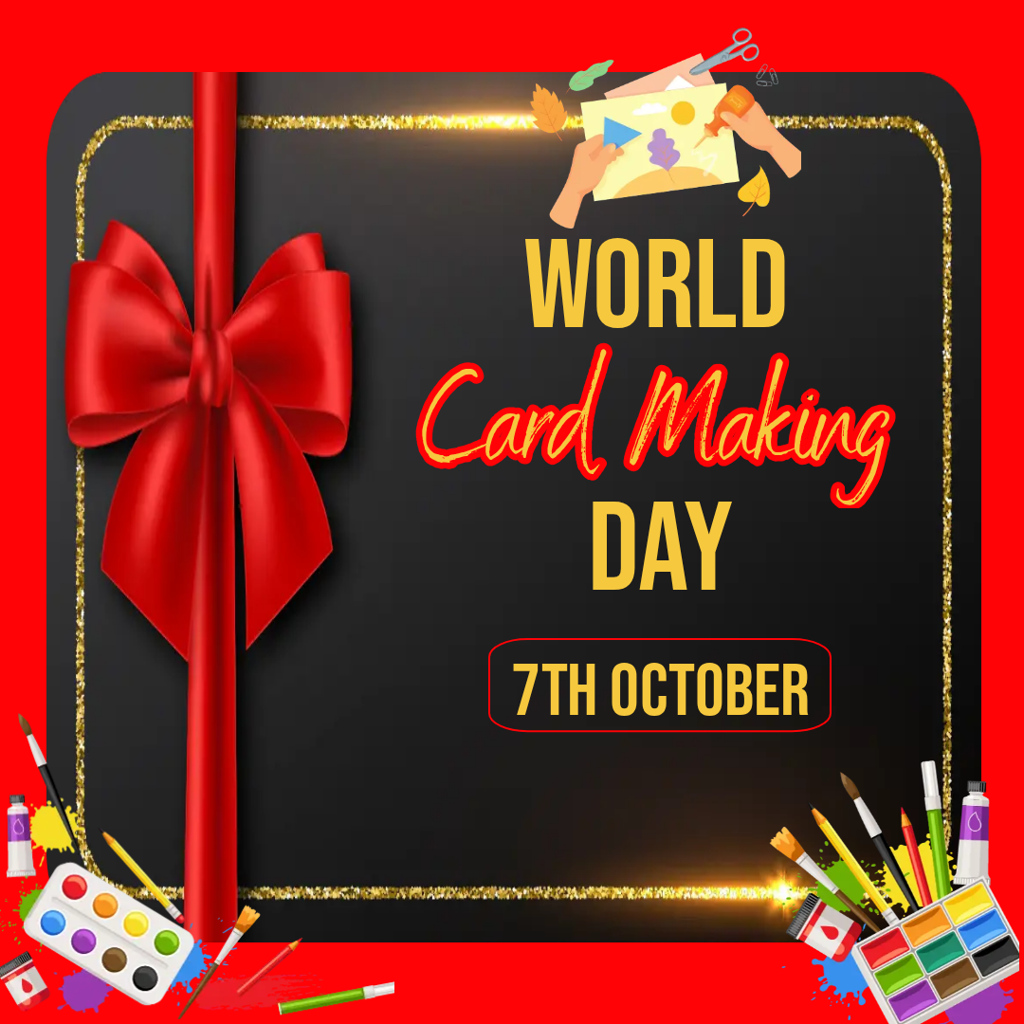
- code/assets/layer_samples/card_making_decomposition.png +3 -0
- code/assets/layer_samples/card_making_input.png +3 -0
- code/assets/layer_samples/card_making_prompt.txt +9 -0
- code/assets/t2i_four_seasons_cabin_prompt.json +33 -0
- code/assets/t2i_rewriter_system_prompt.txt +15 -0
- code/diffusion/__init__.py +0 -0
- code/diffusion/autoencoder_kl_qwenimage.py +1057 -0
- code/diffusion/generator.py +298 -0
- code/diffusion/padding.py +45 -0
- code/diffusion/pipeline.py +716 -0
- code/diffusion/transformer.py +768 -0
- code/quant/load_int8.py +172 -0
- code/quant/test_int8.py +665 -0
- code/tests/__init__.py +0 -0
- code/tests/test_infer_cli.py +226 -0
- code/tests/test_inference_profile.py +257 -0
- code/tests/test_inference_smoke.py +206 -0
- code/tests/test_mllm_device_map.py +82 -0
- code/tests/test_padding.py +41 -0
- code/tests/test_runtime_precision.py +208 -0
- code/tools/convert_connector.py +72 -0
- code/tools/fidelity_compare.py +104 -0
- code/tools/ming_bench.py +127 -0
- code/tools/sdpa_layout.py +49 -0
- code/tools/step_probe.py +99 -0
- code/tools/verify_package.py +110 -0
- connector/model.safetensors +3 -0
- mllm/model-00001-of-00004.safetensors +3 -0
- mllm/model-00002-of-00004.safetensors +3 -0
- mllm/model-00003-of-00004.safetensors +3 -0
- mllm/model-00004-of-00004.safetensors +3 -0
- mllm/tokenizer.json +3 -0
- mlp/model.safetensors +3 -0
- samples/cabin_upstream.png +3 -0
- samples/e2e_daily_grind.png +3 -0
- samples/info_water.png +3 -0
- samples/poster_jazz.png +3 -0
- samples/ui_banking.png +3 -0
- transformer/diffusion_pytorch_model-00001-of-00005.safetensors +3 -0
- transformer/diffusion_pytorch_model-00002-of-00005.safetensors +3 -0
- transformer/diffusion_pytorch_model-00003-of-00005.safetensors +3 -0
- transformer/diffusion_pytorch_model-00004-of-00005.safetensors +3 -0
- transformer/diffusion_pytorch_model-00005-of-00005.safetensors +3 -0
- vae/diffusion_pytorch_model.safetensors +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,11 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
samples/cabin_upstream.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
samples/ui_banking.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
samples/poster_jazz.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
samples/info_water.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
samples/e2e_daily_grind.png filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
mllm/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
code/assets/layer_samples/card_making_decomposition.png filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
code/assets/layer_samples/card_making_input.png filter=lfs diff=lfs merge=lfs -text
|
code/assets/layer_decompose_5layers.txt
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Decompose this image into 5 layers with the following specifications:
|
| 2 |
+
|
| 3 |
+
Number of layers: 5
|
| 4 |
+
Layer 1: A large solid crimson-red circle in the upper-left quadrant, with a subtly uneven printed-like texture and no outline.
|
| 5 |
+
Layer 2: A tall solid dark-green rectangular panel centered in the canvas, evenly filled with faint mottling and no border or visible text.
|
| 6 |
+
Layer 3: A broad solid royal-blue isosceles triangle on the right, its sharp apex near the upper-middle area and flat base aligned close to the large green panel's bottom edge.
|
| 7 |
+
Layer 4: A small solid golden-yellow square in the lower-left quadrant, with soft uneven fill texture, squared edges, and no text.
|
| 8 |
+
Layer 5: Pale cool-gray canvas background spanning the whole composition, with a continuous dark charcoal-gray horizontal baseline running along the bottom edge behind the floating geometric shapes.
|
code/assets/layer_samples/card_making_decomposition.png
ADDED

|
Git LFS Details
|
code/assets/layer_samples/card_making_input.png
ADDED
|
Git LFS Details
|
code/assets/layer_samples/card_making_prompt.txt
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Decompose this image into 6 layers with the following specifications:
|
| 2 |
+
|
| 3 |
+
Number of layers: 6
|
| 4 |
+
Layer 1: Central text stack reading "WORLD", "Card Making", "DAY" in mixed gold and red fonts, plus "7TH OCTOBER" within a red outline box.
|
| 5 |
+
Layer 2: Illustration at the top right showing hands crafting with paper, scissors, glue, and leaves.
|
| 6 |
+
Layer 3: Illustrations at the bottom left and right corners featuring watercolor palettes, brushes, paint tubes, and splatters.
|
| 7 |
+
Layer 4: Realistic red satin ribbon and bow tied vertically along the left side.
|
| 8 |
+
Layer 5: Dark grey rounded rectangle serving as the main card surface, framed by a textured gold glitter border.
|
| 9 |
+
Layer 6: Solid bright red background.
|
code/assets/t2i_four_seasons_cabin_prompt.json
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"canvas_settings": {
|
| 3 |
+
"aspect_ratio": "1:1, 2048 × 2048 px",
|
| 4 |
+
"ambient_lighting": "Four season-specific lighting conditions unified by one fixed eye-level sun direction, consistent horizon at 48% canvas height, matching atmospheric depth, and natural cinematic exposure.",
|
| 5 |
+
"image_style": "High-resolution cinematic photorealistic environmental concept sheet; four equal edge-to-edge vertical panels with crisp shared boundaries and no gutters, frames, extra title, or decorative inter-panel objects. Fixed 35 mm lens, eye-level three-quarter front-right camera angle, identical perspective and cabin registration in every panel. Each panel uses restrained bold uppercase condensed sans-serif labeling at the bottom."
|
| 6 |
+
},
|
| 7 |
+
"layers": [
|
| 8 |
+
{
|
| 9 |
+
"description": "Leftmost spring panel. The same small one-story rectangular log cabin appears at a fixed local position and scale: horizontal dark-brown logs, pale stone foundation, centered vertical-plank front door, two square four-pane front windows, one matching right-side window, and a charcoal standing-seam gabled roof with identical ridge height and overhang. Fresh pale-green grass, budding branches, white and pink blossoms, rain-darkened soil, shallow puddles, wet roof highlights, fine recent-rain droplets, and soft mist fill the landscape beneath an overcast clearing sky. Render the exact label \"SPRING\" centered near the bottom in bold condensed uppercase white sans-serif with a subtle dark shadow.",
|
| 10 |
+
"coordinates": "cx: 0.125, cy: 0.500, w: 0.250, h: 1",
|
| 11 |
+
"hierarchy_and_relation": "Complete first panel; aligned to the shared horizon and fixed cabin registration, flush with the canvas left edge and directly abutting the second panel without a gutter.",
|
| 12 |
+
"color_specs": ["#A9C7D2", "#D8E4DE", "#7FAF69", "#B7D58B", "#F2D7DE", "#F4F1E8", "#5A3B28", "#2C3032", "#7B7468", "#FFFFFF"]
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"description": "Second summer panel. Repeat the cabin with exactly the same architecture, camera angle, local placement, dimensions, centered plank door, front and side windows, stone foundation, roof pitch, ridge height, and overhang. Surround it with lush meadow grass, dense layered deciduous foliage, full tree canopies, small sunlit shrubs, and dry natural ground; use a bright clear sky, strong warm sunlight from the same direction, crisp leaf highlights, controlled shadows, and mild atmospheric haze. Render the exact label \"SUMMER\" centered near the bottom in bold condensed uppercase white sans-serif with a subtle dark shadow.",
|
| 16 |
+
"coordinates": "cx: 0.375, cy: 0.500, w: 0.250, h: 1",
|
| 17 |
+
"hierarchy_and_relation": "Complete second panel; aligned to the shared horizon and fixed cabin registration, directly abutting the first and third panels without gutters.",
|
| 18 |
+
"color_specs": ["#4FA9D8", "#BDE8F2", "#26733E", "#4F9A45", "#79B84A", "#D8C66A", "#5A3B28", "#2C3032", "#7B7468", "#FFFFFF"]
|
| 19 |
+
},
|
| 20 |
+
{
|
| 21 |
+
"description": "Third autumn panel. Repeat the cabin with exactly the same architecture, camera angle, local placement, dimensions, centered plank door, front and side windows, stone foundation, roof pitch, ridge height, and overhang. Cover the landscape with amber grass, rust-orange and golden deciduous foliage, scattered fallen leaves, and a few leaves drifting naturally in the air. Use warm late-afternoon sunlight from the same direction, long soft shadows, copper rim light on logs and roof, a pale warm sky, and subtle atmospheric depth. Render the exact label \"AUTUMN\" centered near the bottom in bold condensed uppercase white sans-serif with a subtle dark shadow.",
|
| 22 |
+
"coordinates": "cx: 0.625, cy: 0.500, w: 0.250, h: 1",
|
| 23 |
+
"hierarchy_and_relation": "Complete third panel; aligned to the shared horizon and fixed cabin registration, directly abutting the second and fourth panels without gutters.",
|
| 24 |
+
"color_specs": ["#E6B06A", "#F0D6A2", "#D66A2C", "#A84324", "#E2A62B", "#80613B", "#5A3B28", "#2C3032", "#7B7468", "#FFFFFF"]
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"description": "Rightmost winter panel. Repeat the cabin with exactly the same architecture, camera angle, local placement, dimensions, centered plank door, front and side windows, stone foundation, roof pitch, ridge height, and overhang. Blanket the ground and roof with natural snow accumulation while keeping doors and windows readable; add bare deciduous branches, snow-laden low shrubs, faint footprints away from the cabin, and sparse fine snowfall. Use cool blue ambient light, a pale clouded sky, soft low-contrast shadows from the same direction, icy edge highlights, and slight winter haze. Render the exact label \"WINTER\" centered near the bottom in bold condensed uppercase white sans-serif with a subtle dark shadow.",
|
| 28 |
+
"coordinates": "cx: 0.875, cy: 0.500, w: 0.250, h: 1",
|
| 29 |
+
"hierarchy_and_relation": "Complete fourth panel; aligned to the shared horizon and fixed cabin registration, directly abutting the third panel without a gutter and flush with the canvas right edge.",
|
| 30 |
+
"color_specs": ["#AFC8DE", "#DCE8F1", "#F4F7F8", "#C6D8E5", "#8198AA", "#6D5949", "#5A3B28", "#2C3032", "#7B7468", "#FFFFFF"]
|
| 31 |
+
}
|
| 32 |
+
]
|
| 33 |
+
}
|
code/assets/t2i_rewriter_system_prompt.txt
ADDED
|
@@ -0,0 +1,15 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
You are a senior visual designer and image-prompt engineer. Expand the user's request into one precise, high-resolution Figma-style caption. Return only one JSON object.
|
| 2 |
+
|
| 3 |
+
Use exactly two top-level keys. `canvas_settings` contains exactly `aspect_ratio`, `ambient_lighting`, and `image_style`. `layers` lists visible groups from background to topmost overlay. Every layer contains exactly `description`, `coordinates`, `hierarchy_and_relation`, and `color_specs`; `color_specs` is an array of hex colors.
|
| 4 |
+
|
| 5 |
+
`coordinates` MUST be one string, never an object or array, in exactly this form: `"cx: 0.500, cy: 0.500, w: 1.000, h: 1.000"`. Values are normalized; each bbox encloses its complete owned object and stays inside the canvas.
|
| 6 |
+
|
| 7 |
+
A layer is one selectable visible semantic group: background, full person, coherent object, panel, card, row, or text block. Prefer the fewest groups that preserve the layout. Keep people and objects intact. Never create invisible parents, guides, placeholders, empty layers, duplicate summaries, or multiple owners for one element.
|
| 8 |
+
|
| 9 |
+
Preserve every user-supplied rendered string character-for-character and as one contiguous string. Unless multiple visible copies are requested, it must occur exactly once across all `description` fields and zero times in `hierarchy_and_relation`. Quote it only where describing its visible rendering; refer to the related subject elsewhere with unquoted semantic wording. Enumerate intended copy, invent extra copy sparingly, and never hide content behind "other text", "remaining labels", or "etc."
|
| 10 |
+
|
| 11 |
+
Describe concrete composition, typography, materials, texture, lighting, pose, and camera treatment without literary filler. Use `hierarchy_and_relation` only for ownership, alignment, containment, stacking, and occlusion.
|
| 12 |
+
|
| 13 |
+
Infer structured layouts first. Use one complete layer per card and state its row and column. A compact secondary table may be one layer only if every header and cell is listed; otherwise use a visible shared frame when present, one complete header, and one complete layer per body row, binding values to columns and stating blanks. Enumerate sequences, schedules, spans, gaps, and vacant tracks in visual order. Do not mistake ordinary alignment for a table.
|
| 14 |
+
|
| 15 |
+
Silently verify schema, string coordinates, Z-order, exact-text counts, geometry, bbox validity, and completeness.
|
code/diffusion/__init__.py
ADDED
|
File without changes
|
code/diffusion/autoencoder_kl_qwenimage.py
ADDED
|
@@ -0,0 +1,1057 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/python
|
| 2 |
+
# Copyright 2025 The Qwen-Image Team, Wan Team and The HuggingFace Team. All rights reserved.
|
| 3 |
+
#
|
| 4 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
+
# you may not use this file except in compliance with the License.
|
| 6 |
+
# You may obtain a copy of the License at
|
| 7 |
+
#
|
| 8 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
+
#
|
| 10 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 11 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
+
# See the License for the specific language governing permissions and
|
| 14 |
+
# limitations under the License.
|
| 15 |
+
#
|
| 16 |
+
# We gratefully acknowledge the Wan Team for their outstanding contributions.
|
| 17 |
+
# QwenImageVAE is further fine-tuned from the Wan Video VAE to achieve improved performance.
|
| 18 |
+
# For more information about the Wan VAE, please refer to:
|
| 19 |
+
# - GitHub: https://github.com/Wan-Video/Wan2.1
|
| 20 |
+
# - Paper: https://huggingface.co/papers/2503.20314
|
| 21 |
+
|
| 22 |
+
import torch
|
| 23 |
+
import torch.nn as nn
|
| 24 |
+
import torch.nn.functional as F
|
| 25 |
+
|
| 26 |
+
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
| 27 |
+
from diffusers.loaders import FromOriginalModelMixin
|
| 28 |
+
from diffusers.utils import logging
|
| 29 |
+
from diffusers.utils.accelerate_utils import apply_forward_hook
|
| 30 |
+
from diffusers.models.activations import get_activation
|
| 31 |
+
from diffusers.models.modeling_outputs import AutoencoderKLOutput
|
| 32 |
+
from diffusers.models.modeling_utils import ModelMixin
|
| 33 |
+
from diffusers.models.autoencoders.vae import AutoencoderMixin, DecoderOutput, DiagonalGaussianDistribution
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
| 37 |
+
|
| 38 |
+
CACHE_T = 2
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
class QwenImageCausalConv3d(nn.Conv3d):
|
| 42 |
+
r"""
|
| 43 |
+
A custom 3D causal convolution layer with feature caching support.
|
| 44 |
+
|
| 45 |
+
This layer extends the standard Conv3D layer by ensuring causality in the time dimension and handling feature
|
| 46 |
+
caching for efficient inference.
|
| 47 |
+
|
| 48 |
+
Args:
|
| 49 |
+
in_channels (int): Number of channels in the input image
|
| 50 |
+
out_channels (int): Number of channels produced by the convolution
|
| 51 |
+
kernel_size (int or tuple): Size of the convolving kernel
|
| 52 |
+
stride (int or tuple, optional): Stride of the convolution. Default: 1
|
| 53 |
+
padding (int or tuple, optional): Zero-padding added to all three sides of the input. Default: 0
|
| 54 |
+
"""
|
| 55 |
+
|
| 56 |
+
def __init__(
|
| 57 |
+
self,
|
| 58 |
+
in_channels: int,
|
| 59 |
+
out_channels: int,
|
| 60 |
+
kernel_size: int | tuple[int, int, int],
|
| 61 |
+
stride: int | tuple[int, int, int] = 1,
|
| 62 |
+
padding: int | tuple[int, int, int] = 0,
|
| 63 |
+
) -> None:
|
| 64 |
+
super().__init__(
|
| 65 |
+
in_channels=in_channels,
|
| 66 |
+
out_channels=out_channels,
|
| 67 |
+
kernel_size=kernel_size,
|
| 68 |
+
stride=stride,
|
| 69 |
+
padding=padding,
|
| 70 |
+
)
|
| 71 |
+
|
| 72 |
+
# Set up causal padding
|
| 73 |
+
self._padding = (self.padding[2], self.padding[2], self.padding[1], self.padding[1], 2 * self.padding[0], 0)
|
| 74 |
+
self.padding = (0, 0, 0)
|
| 75 |
+
|
| 76 |
+
def forward(self, x, cache_x=None):
|
| 77 |
+
padding = list(self._padding)
|
| 78 |
+
if cache_x is not None and self._padding[4] > 0:
|
| 79 |
+
cache_x = cache_x.to(x.device)
|
| 80 |
+
x = torch.cat([cache_x, x], dim=2)
|
| 81 |
+
padding[4] -= cache_x.shape[2]
|
| 82 |
+
x = F.pad(x, padding)
|
| 83 |
+
return super().forward(x)
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
class QwenImageRMS_norm(nn.Module):
|
| 87 |
+
r"""
|
| 88 |
+
A custom RMS normalization layer.
|
| 89 |
+
|
| 90 |
+
Args:
|
| 91 |
+
dim (int): The number of dimensions to normalize over.
|
| 92 |
+
channel_first (bool, optional): Whether the input tensor has channels as the first dimension.
|
| 93 |
+
Default is True.
|
| 94 |
+
images (bool, optional): Whether the input represents image data. Default is True.
|
| 95 |
+
bias (bool, optional): Whether to include a learnable bias term. Default is False.
|
| 96 |
+
"""
|
| 97 |
+
|
| 98 |
+
def __init__(self, dim: int, channel_first: bool = True, images: bool = True, bias: bool = False) -> None:
|
| 99 |
+
super().__init__()
|
| 100 |
+
broadcastable_dims = (1, 1, 1) if not images else (1, 1)
|
| 101 |
+
shape = (dim, *broadcastable_dims) if channel_first else (dim,)
|
| 102 |
+
|
| 103 |
+
self.channel_first = channel_first
|
| 104 |
+
self.scale = dim**0.5
|
| 105 |
+
self.gamma = nn.Parameter(torch.ones(shape))
|
| 106 |
+
self.bias = nn.Parameter(torch.zeros(shape)) if bias else 0.0
|
| 107 |
+
|
| 108 |
+
def forward(self, x):
|
| 109 |
+
needs_fp32_normalize = x.dtype in (torch.float16, torch.bfloat16) or any(
|
| 110 |
+
t in str(x.dtype) for t in ("float4_", "float8_")
|
| 111 |
+
)
|
| 112 |
+
normalized = F.normalize(x.float() if needs_fp32_normalize else x, dim=(1 if self.channel_first else -1)).to(
|
| 113 |
+
x.dtype
|
| 114 |
+
)
|
| 115 |
+
|
| 116 |
+
return normalized * self.scale * self.gamma + self.bias
|
| 117 |
+
|
| 118 |
+
|
| 119 |
+
class QwenImageUpsample(nn.Upsample):
|
| 120 |
+
r"""
|
| 121 |
+
Perform upsampling while ensuring the output tensor has the same data type as the input.
|
| 122 |
+
|
| 123 |
+
Args:
|
| 124 |
+
x (torch.Tensor): Input tensor to be upsampled.
|
| 125 |
+
|
| 126 |
+
Returns:
|
| 127 |
+
torch.Tensor: Upsampled tensor with the same data type as the input.
|
| 128 |
+
"""
|
| 129 |
+
|
| 130 |
+
def forward(self, x):
|
| 131 |
+
return super().forward(x.float()).type_as(x)
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
class QwenImageResample(nn.Module):
|
| 135 |
+
r"""
|
| 136 |
+
A custom resampling module for 2D and 3D data.
|
| 137 |
+
|
| 138 |
+
Args:
|
| 139 |
+
dim (int): The number of input/output channels.
|
| 140 |
+
mode (str): The resampling mode. Must be one of:
|
| 141 |
+
- 'none': No resampling (identity operation).
|
| 142 |
+
- 'upsample2d': 2D upsampling with nearest-exact interpolation and convolution.
|
| 143 |
+
- 'upsample3d': 3D upsampling with nearest-exact interpolation, convolution, and causal 3D convolution.
|
| 144 |
+
- 'downsample2d': 2D downsampling with zero-padding and convolution.
|
| 145 |
+
- 'downsample3d': 3D downsampling with zero-padding, convolution, and causal 3D convolution.
|
| 146 |
+
"""
|
| 147 |
+
|
| 148 |
+
def __init__(self, dim: int, mode: str) -> None:
|
| 149 |
+
super().__init__()
|
| 150 |
+
self.dim = dim
|
| 151 |
+
self.mode = mode
|
| 152 |
+
|
| 153 |
+
# layers
|
| 154 |
+
if mode == "upsample2d":
|
| 155 |
+
self.resample = nn.Sequential(
|
| 156 |
+
QwenImageUpsample(scale_factor=(2.0, 2.0), mode="nearest-exact"),
|
| 157 |
+
nn.Conv2d(dim, dim // 2, 3, padding=1),
|
| 158 |
+
)
|
| 159 |
+
elif mode == "upsample3d":
|
| 160 |
+
self.resample = nn.Sequential(
|
| 161 |
+
QwenImageUpsample(scale_factor=(2.0, 2.0), mode="nearest-exact"),
|
| 162 |
+
nn.Conv2d(dim, dim // 2, 3, padding=1),
|
| 163 |
+
)
|
| 164 |
+
self.time_conv = QwenImageCausalConv3d(dim, dim * 2, (3, 1, 1), padding=(1, 0, 0))
|
| 165 |
+
|
| 166 |
+
elif mode == "downsample2d":
|
| 167 |
+
self.resample = nn.Sequential(nn.ZeroPad2d((0, 1, 0, 1)), nn.Conv2d(dim, dim, 3, stride=(2, 2)))
|
| 168 |
+
elif mode == "downsample3d":
|
| 169 |
+
self.resample = nn.Sequential(nn.ZeroPad2d((0, 1, 0, 1)), nn.Conv2d(dim, dim, 3, stride=(2, 2)))
|
| 170 |
+
self.time_conv = QwenImageCausalConv3d(dim, dim, (3, 1, 1), stride=(2, 1, 1), padding=(0, 0, 0))
|
| 171 |
+
|
| 172 |
+
else:
|
| 173 |
+
self.resample = nn.Identity()
|
| 174 |
+
|
| 175 |
+
def forward(self, x, feat_cache=None, feat_idx=[0]):
|
| 176 |
+
b, c, t, h, w = x.size()
|
| 177 |
+
if self.mode == "upsample3d":
|
| 178 |
+
if feat_cache is not None:
|
| 179 |
+
idx = feat_idx[0]
|
| 180 |
+
if feat_cache[idx] is None:
|
| 181 |
+
feat_cache[idx] = "Rep"
|
| 182 |
+
feat_idx[0] += 1
|
| 183 |
+
else:
|
| 184 |
+
cache_x = x[:, :, -CACHE_T:, :, :].clone()
|
| 185 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None and feat_cache[idx] != "Rep":
|
| 186 |
+
# cache last frame of last two chunk
|
| 187 |
+
cache_x = torch.cat(
|
| 188 |
+
[feat_cache[idx][:, :, -1, :, :].unsqueeze(2).to(cache_x.device), cache_x], dim=2
|
| 189 |
+
)
|
| 190 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None and feat_cache[idx] == "Rep":
|
| 191 |
+
cache_x = torch.cat([torch.zeros_like(cache_x).to(cache_x.device), cache_x], dim=2)
|
| 192 |
+
if feat_cache[idx] == "Rep":
|
| 193 |
+
x = self.time_conv(x)
|
| 194 |
+
else:
|
| 195 |
+
x = self.time_conv(x, feat_cache[idx])
|
| 196 |
+
feat_cache[idx] = cache_x
|
| 197 |
+
feat_idx[0] += 1
|
| 198 |
+
|
| 199 |
+
x = x.reshape(b, 2, c, t, h, w)
|
| 200 |
+
x = torch.stack((x[:, 0, :, :, :, :], x[:, 1, :, :, :, :]), 3)
|
| 201 |
+
x = x.reshape(b, c, t * 2, h, w)
|
| 202 |
+
t = x.shape[2]
|
| 203 |
+
x = x.permute(0, 2, 1, 3, 4).reshape(b * t, c, h, w)
|
| 204 |
+
x = self.resample(x)
|
| 205 |
+
x = x.view(b, t, x.size(1), x.size(2), x.size(3)).permute(0, 2, 1, 3, 4)
|
| 206 |
+
|
| 207 |
+
if self.mode == "downsample3d":
|
| 208 |
+
if feat_cache is not None:
|
| 209 |
+
idx = feat_idx[0]
|
| 210 |
+
if feat_cache[idx] is None:
|
| 211 |
+
feat_cache[idx] = x.clone()
|
| 212 |
+
feat_idx[0] += 1
|
| 213 |
+
else:
|
| 214 |
+
cache_x = x[:, :, -1:, :, :].clone()
|
| 215 |
+
x = self.time_conv(torch.cat([feat_cache[idx][:, :, -1:, :, :], x], 2))
|
| 216 |
+
feat_cache[idx] = cache_x
|
| 217 |
+
feat_idx[0] += 1
|
| 218 |
+
return x
|
| 219 |
+
|
| 220 |
+
|
| 221 |
+
class QwenImageResidualBlock(nn.Module):
|
| 222 |
+
r"""
|
| 223 |
+
A custom residual block module.
|
| 224 |
+
|
| 225 |
+
Args:
|
| 226 |
+
in_dim (int): Number of input channels.
|
| 227 |
+
out_dim (int): Number of output channels.
|
| 228 |
+
dropout (float, optional): Dropout rate for the dropout layer. Default is 0.0.
|
| 229 |
+
non_linearity (str, optional): Type of non-linearity to use. Default is "silu".
|
| 230 |
+
"""
|
| 231 |
+
|
| 232 |
+
def __init__(
|
| 233 |
+
self,
|
| 234 |
+
in_dim: int,
|
| 235 |
+
out_dim: int,
|
| 236 |
+
dropout: float = 0.0,
|
| 237 |
+
non_linearity: str = "silu",
|
| 238 |
+
) -> None:
|
| 239 |
+
super().__init__()
|
| 240 |
+
self.in_dim = in_dim
|
| 241 |
+
self.out_dim = out_dim
|
| 242 |
+
self.nonlinearity = get_activation(non_linearity)
|
| 243 |
+
|
| 244 |
+
# layers
|
| 245 |
+
self.norm1 = QwenImageRMS_norm(in_dim, images=False)
|
| 246 |
+
self.conv1 = QwenImageCausalConv3d(in_dim, out_dim, 3, padding=1)
|
| 247 |
+
self.norm2 = QwenImageRMS_norm(out_dim, images=False)
|
| 248 |
+
self.dropout = nn.Dropout(dropout)
|
| 249 |
+
self.conv2 = QwenImageCausalConv3d(out_dim, out_dim, 3, padding=1)
|
| 250 |
+
self.conv_shortcut = QwenImageCausalConv3d(in_dim, out_dim, 1) if in_dim != out_dim else nn.Identity()
|
| 251 |
+
|
| 252 |
+
def forward(self, x, feat_cache=None, feat_idx=[0]):
|
| 253 |
+
# Apply shortcut connection
|
| 254 |
+
h = self.conv_shortcut(x)
|
| 255 |
+
|
| 256 |
+
# First normalization and activation
|
| 257 |
+
x = self.norm1(x)
|
| 258 |
+
x = self.nonlinearity(x)
|
| 259 |
+
|
| 260 |
+
if feat_cache is not None:
|
| 261 |
+
idx = feat_idx[0]
|
| 262 |
+
cache_x = x[:, :, -CACHE_T:, :, :].clone()
|
| 263 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None:
|
| 264 |
+
cache_x = torch.cat([feat_cache[idx][:, :, -1, :, :].unsqueeze(2).to(cache_x.device), cache_x], dim=2)
|
| 265 |
+
|
| 266 |
+
x = self.conv1(x, feat_cache[idx])
|
| 267 |
+
feat_cache[idx] = cache_x
|
| 268 |
+
feat_idx[0] += 1
|
| 269 |
+
else:
|
| 270 |
+
x = self.conv1(x)
|
| 271 |
+
|
| 272 |
+
# Second normalization and activation
|
| 273 |
+
x = self.norm2(x)
|
| 274 |
+
x = self.nonlinearity(x)
|
| 275 |
+
|
| 276 |
+
# Dropout
|
| 277 |
+
x = self.dropout(x)
|
| 278 |
+
|
| 279 |
+
if feat_cache is not None:
|
| 280 |
+
idx = feat_idx[0]
|
| 281 |
+
cache_x = x[:, :, -CACHE_T:, :, :].clone()
|
| 282 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None:
|
| 283 |
+
cache_x = torch.cat([feat_cache[idx][:, :, -1, :, :].unsqueeze(2).to(cache_x.device), cache_x], dim=2)
|
| 284 |
+
|
| 285 |
+
x = self.conv2(x, feat_cache[idx])
|
| 286 |
+
feat_cache[idx] = cache_x
|
| 287 |
+
feat_idx[0] += 1
|
| 288 |
+
else:
|
| 289 |
+
x = self.conv2(x)
|
| 290 |
+
|
| 291 |
+
# Add residual connection
|
| 292 |
+
return x + h
|
| 293 |
+
|
| 294 |
+
|
| 295 |
+
class QwenImageAttentionBlock(nn.Module):
|
| 296 |
+
r"""
|
| 297 |
+
Causal self-attention with a single head.
|
| 298 |
+
|
| 299 |
+
Args:
|
| 300 |
+
dim (int): The number of channels in the input tensor.
|
| 301 |
+
"""
|
| 302 |
+
|
| 303 |
+
def __init__(self, dim):
|
| 304 |
+
super().__init__()
|
| 305 |
+
self.dim = dim
|
| 306 |
+
|
| 307 |
+
# layers
|
| 308 |
+
self.norm = QwenImageRMS_norm(dim)
|
| 309 |
+
self.to_qkv = nn.Conv2d(dim, dim * 3, 1)
|
| 310 |
+
self.proj = nn.Conv2d(dim, dim, 1)
|
| 311 |
+
|
| 312 |
+
def forward(self, x):
|
| 313 |
+
identity = x
|
| 314 |
+
batch_size, channels, time, height, width = x.size()
|
| 315 |
+
|
| 316 |
+
x = x.permute(0, 2, 1, 3, 4).reshape(batch_size * time, channels, height, width)
|
| 317 |
+
x = self.norm(x)
|
| 318 |
+
|
| 319 |
+
# compute query, key, value
|
| 320 |
+
qkv = self.to_qkv(x)
|
| 321 |
+
qkv = qkv.reshape(batch_size * time, 1, channels * 3, -1)
|
| 322 |
+
qkv = qkv.permute(0, 1, 3, 2).contiguous()
|
| 323 |
+
q, k, v = qkv.chunk(3, dim=-1)
|
| 324 |
+
|
| 325 |
+
# apply attention
|
| 326 |
+
x = F.scaled_dot_product_attention(q, k, v)
|
| 327 |
+
|
| 328 |
+
x = x.squeeze(1).permute(0, 2, 1).reshape(batch_size * time, channels, height, width)
|
| 329 |
+
|
| 330 |
+
# output projection
|
| 331 |
+
x = self.proj(x)
|
| 332 |
+
|
| 333 |
+
# Reshape back: [(b*t), c, h, w] -> [b, c, t, h, w]
|
| 334 |
+
x = x.view(batch_size, time, channels, height, width)
|
| 335 |
+
x = x.permute(0, 2, 1, 3, 4)
|
| 336 |
+
|
| 337 |
+
return x + identity
|
| 338 |
+
|
| 339 |
+
|
| 340 |
+
class QwenImageMidBlock(nn.Module):
|
| 341 |
+
"""
|
| 342 |
+
Middle block for QwenImageVAE encoder and decoder.
|
| 343 |
+
|
| 344 |
+
Args:
|
| 345 |
+
dim (int): Number of input/output channels.
|
| 346 |
+
dropout (float): Dropout rate.
|
| 347 |
+
non_linearity (str): Type of non-linearity to use.
|
| 348 |
+
"""
|
| 349 |
+
|
| 350 |
+
def __init__(self, dim: int, dropout: float = 0.0, non_linearity: str = "silu", num_layers: int = 1):
|
| 351 |
+
super().__init__()
|
| 352 |
+
self.dim = dim
|
| 353 |
+
|
| 354 |
+
# Create the components
|
| 355 |
+
resnets = [QwenImageResidualBlock(dim, dim, dropout, non_linearity)]
|
| 356 |
+
attentions = []
|
| 357 |
+
for _ in range(num_layers):
|
| 358 |
+
attentions.append(QwenImageAttentionBlock(dim))
|
| 359 |
+
resnets.append(QwenImageResidualBlock(dim, dim, dropout, non_linearity))
|
| 360 |
+
self.attentions = nn.ModuleList(attentions)
|
| 361 |
+
self.resnets = nn.ModuleList(resnets)
|
| 362 |
+
|
| 363 |
+
self.gradient_checkpointing = False
|
| 364 |
+
|
| 365 |
+
def forward(self, x, feat_cache=None, feat_idx=[0]):
|
| 366 |
+
# First residual block
|
| 367 |
+
x = self.resnets[0](x, feat_cache, feat_idx)
|
| 368 |
+
|
| 369 |
+
# Process through attention and residual blocks
|
| 370 |
+
for attn, resnet in zip(self.attentions, self.resnets[1:]):
|
| 371 |
+
if attn is not None:
|
| 372 |
+
x = attn(x)
|
| 373 |
+
|
| 374 |
+
x = resnet(x, feat_cache, feat_idx)
|
| 375 |
+
|
| 376 |
+
return x
|
| 377 |
+
|
| 378 |
+
|
| 379 |
+
class QwenImageEncoder3d(nn.Module):
|
| 380 |
+
r"""
|
| 381 |
+
A 3D encoder module.
|
| 382 |
+
|
| 383 |
+
Args:
|
| 384 |
+
dim (int): The base number of channels in the first layer.
|
| 385 |
+
z_dim (int): The dimensionality of the latent space.
|
| 386 |
+
dim_mult (list of int): Multipliers for the number of channels in each block.
|
| 387 |
+
num_res_blocks (int): Number of residual blocks in each block.
|
| 388 |
+
attn_scales (list of float): Scales at which to apply attention mechanisms.
|
| 389 |
+
temperal_downsample (list of bool): Whether to downsample temporally in each block.
|
| 390 |
+
dropout (float): Dropout rate for the dropout layers.
|
| 391 |
+
non_linearity (str): Type of non-linearity to use.
|
| 392 |
+
"""
|
| 393 |
+
|
| 394 |
+
def __init__(
|
| 395 |
+
self,
|
| 396 |
+
dim=128,
|
| 397 |
+
z_dim=4,
|
| 398 |
+
dim_mult=[1, 2, 4, 4],
|
| 399 |
+
num_res_blocks=2,
|
| 400 |
+
attn_scales=[],
|
| 401 |
+
temperal_downsample=[True, True, False],
|
| 402 |
+
dropout=0.0,
|
| 403 |
+
input_channels=3,
|
| 404 |
+
non_linearity: str = "silu",
|
| 405 |
+
):
|
| 406 |
+
super().__init__()
|
| 407 |
+
self.dim = dim
|
| 408 |
+
self.z_dim = z_dim
|
| 409 |
+
self.dim_mult = dim_mult
|
| 410 |
+
self.num_res_blocks = num_res_blocks
|
| 411 |
+
self.attn_scales = attn_scales
|
| 412 |
+
self.temperal_downsample = temperal_downsample
|
| 413 |
+
self.nonlinearity = get_activation(non_linearity)
|
| 414 |
+
|
| 415 |
+
# dimensions
|
| 416 |
+
dims = [dim * u for u in [1] + dim_mult]
|
| 417 |
+
scale = 1.0
|
| 418 |
+
|
| 419 |
+
# init block
|
| 420 |
+
self.conv_in = QwenImageCausalConv3d(input_channels, dims[0], 3, padding=1)
|
| 421 |
+
|
| 422 |
+
# downsample blocks
|
| 423 |
+
self.down_blocks = nn.ModuleList([])
|
| 424 |
+
for i, (in_dim, out_dim) in enumerate(zip(dims[:-1], dims[1:])):
|
| 425 |
+
# residual (+attention) blocks
|
| 426 |
+
for _ in range(num_res_blocks):
|
| 427 |
+
self.down_blocks.append(QwenImageResidualBlock(in_dim, out_dim, dropout))
|
| 428 |
+
if scale in attn_scales:
|
| 429 |
+
self.down_blocks.append(QwenImageAttentionBlock(out_dim))
|
| 430 |
+
in_dim = out_dim
|
| 431 |
+
|
| 432 |
+
# downsample block
|
| 433 |
+
if i != len(dim_mult) - 1:
|
| 434 |
+
mode = "downsample3d" if temperal_downsample[i] else "downsample2d"
|
| 435 |
+
self.down_blocks.append(QwenImageResample(out_dim, mode=mode))
|
| 436 |
+
scale /= 2.0
|
| 437 |
+
|
| 438 |
+
# middle blocks
|
| 439 |
+
self.mid_block = QwenImageMidBlock(out_dim, dropout, non_linearity, num_layers=1)
|
| 440 |
+
|
| 441 |
+
# output blocks
|
| 442 |
+
self.norm_out = QwenImageRMS_norm(out_dim, images=False)
|
| 443 |
+
self.conv_out = QwenImageCausalConv3d(out_dim, z_dim, 3, padding=1)
|
| 444 |
+
|
| 445 |
+
self.gradient_checkpointing = False
|
| 446 |
+
|
| 447 |
+
def forward(self, x, feat_cache=None, feat_idx=[0]):
|
| 448 |
+
if feat_cache is not None:
|
| 449 |
+
idx = feat_idx[0]
|
| 450 |
+
cache_x = x[:, :, -CACHE_T:, :, :].clone()
|
| 451 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None:
|
| 452 |
+
# cache last frame of last two chunk
|
| 453 |
+
cache_x = torch.cat([feat_cache[idx][:, :, -1, :, :].unsqueeze(2).to(cache_x.device), cache_x], dim=2)
|
| 454 |
+
x = self.conv_in(x, feat_cache[idx])
|
| 455 |
+
feat_cache[idx] = cache_x
|
| 456 |
+
feat_idx[0] += 1
|
| 457 |
+
else:
|
| 458 |
+
x = self.conv_in(x)
|
| 459 |
+
|
| 460 |
+
## downsamples
|
| 461 |
+
for layer in self.down_blocks:
|
| 462 |
+
if feat_cache is not None:
|
| 463 |
+
x = layer(x, feat_cache, feat_idx)
|
| 464 |
+
else:
|
| 465 |
+
x = layer(x)
|
| 466 |
+
|
| 467 |
+
## middle
|
| 468 |
+
x = self.mid_block(x, feat_cache, feat_idx)
|
| 469 |
+
|
| 470 |
+
## head
|
| 471 |
+
x = self.norm_out(x)
|
| 472 |
+
x = self.nonlinearity(x)
|
| 473 |
+
if feat_cache is not None:
|
| 474 |
+
idx = feat_idx[0]
|
| 475 |
+
cache_x = x[:, :, -CACHE_T:, :, :].clone()
|
| 476 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None:
|
| 477 |
+
# cache last frame of last two chunk
|
| 478 |
+
cache_x = torch.cat([feat_cache[idx][:, :, -1, :, :].unsqueeze(2).to(cache_x.device), cache_x], dim=2)
|
| 479 |
+
x = self.conv_out(x, feat_cache[idx])
|
| 480 |
+
feat_cache[idx] = cache_x
|
| 481 |
+
feat_idx[0] += 1
|
| 482 |
+
else:
|
| 483 |
+
x = self.conv_out(x)
|
| 484 |
+
return x
|
| 485 |
+
|
| 486 |
+
|
| 487 |
+
class QwenImageUpBlock(nn.Module):
|
| 488 |
+
"""
|
| 489 |
+
A block that handles upsampling for the QwenImageVAE decoder.
|
| 490 |
+
|
| 491 |
+
Args:
|
| 492 |
+
in_dim (int): Input dimension
|
| 493 |
+
out_dim (int): Output dimension
|
| 494 |
+
num_res_blocks (int): Number of residual blocks
|
| 495 |
+
dropout (float): Dropout rate
|
| 496 |
+
upsample_mode (str, optional): Mode for upsampling ('upsample2d' or 'upsample3d')
|
| 497 |
+
non_linearity (str): Type of non-linearity to use
|
| 498 |
+
"""
|
| 499 |
+
|
| 500 |
+
def __init__(
|
| 501 |
+
self,
|
| 502 |
+
in_dim: int,
|
| 503 |
+
out_dim: int,
|
| 504 |
+
num_res_blocks: int,
|
| 505 |
+
dropout: float = 0.0,
|
| 506 |
+
upsample_mode: str | None = None,
|
| 507 |
+
non_linearity: str = "silu",
|
| 508 |
+
):
|
| 509 |
+
super().__init__()
|
| 510 |
+
self.in_dim = in_dim
|
| 511 |
+
self.out_dim = out_dim
|
| 512 |
+
|
| 513 |
+
# Create layers list
|
| 514 |
+
resnets = []
|
| 515 |
+
# Add residual blocks and attention if needed
|
| 516 |
+
current_dim = in_dim
|
| 517 |
+
for _ in range(num_res_blocks + 1):
|
| 518 |
+
resnets.append(QwenImageResidualBlock(current_dim, out_dim, dropout, non_linearity))
|
| 519 |
+
current_dim = out_dim
|
| 520 |
+
|
| 521 |
+
self.resnets = nn.ModuleList(resnets)
|
| 522 |
+
|
| 523 |
+
# Add upsampling layer if needed
|
| 524 |
+
self.upsamplers = None
|
| 525 |
+
if upsample_mode is not None:
|
| 526 |
+
self.upsamplers = nn.ModuleList([QwenImageResample(out_dim, mode=upsample_mode)])
|
| 527 |
+
|
| 528 |
+
self.gradient_checkpointing = False
|
| 529 |
+
|
| 530 |
+
def forward(self, x, feat_cache=None, feat_idx=[0]):
|
| 531 |
+
"""
|
| 532 |
+
Forward pass through the upsampling block.
|
| 533 |
+
|
| 534 |
+
Args:
|
| 535 |
+
x (torch.Tensor): Input tensor
|
| 536 |
+
feat_cache (list, optional): Feature cache for causal convolutions
|
| 537 |
+
feat_idx (list, optional): Feature index for cache management
|
| 538 |
+
|
| 539 |
+
Returns:
|
| 540 |
+
torch.Tensor: Output tensor
|
| 541 |
+
"""
|
| 542 |
+
for resnet in self.resnets:
|
| 543 |
+
if feat_cache is not None:
|
| 544 |
+
x = resnet(x, feat_cache, feat_idx)
|
| 545 |
+
else:
|
| 546 |
+
x = resnet(x)
|
| 547 |
+
|
| 548 |
+
if self.upsamplers is not None:
|
| 549 |
+
if feat_cache is not None:
|
| 550 |
+
x = self.upsamplers[0](x, feat_cache, feat_idx)
|
| 551 |
+
else:
|
| 552 |
+
x = self.upsamplers[0](x)
|
| 553 |
+
return x
|
| 554 |
+
|
| 555 |
+
|
| 556 |
+
class QwenImageDecoder3d(nn.Module):
|
| 557 |
+
r"""
|
| 558 |
+
A 3D decoder module.
|
| 559 |
+
|
| 560 |
+
Args:
|
| 561 |
+
dim (int): The base number of channels in the first layer.
|
| 562 |
+
z_dim (int): The dimensionality of the latent space.
|
| 563 |
+
dim_mult (list of int): Multipliers for the number of channels in each block.
|
| 564 |
+
num_res_blocks (int): Number of residual blocks in each block.
|
| 565 |
+
attn_scales (list of float): Scales at which to apply attention mechanisms.
|
| 566 |
+
temperal_upsample (list of bool): Whether to upsample temporally in each block.
|
| 567 |
+
dropout (float): Dropout rate for the dropout layers.
|
| 568 |
+
non_linearity (str): Type of non-linearity to use.
|
| 569 |
+
"""
|
| 570 |
+
|
| 571 |
+
def __init__(
|
| 572 |
+
self,
|
| 573 |
+
dim=128,
|
| 574 |
+
z_dim=4,
|
| 575 |
+
dim_mult=[1, 2, 4, 4],
|
| 576 |
+
num_res_blocks=2,
|
| 577 |
+
attn_scales=[],
|
| 578 |
+
temperal_upsample=[False, True, True],
|
| 579 |
+
dropout=0.0,
|
| 580 |
+
input_channels=3,
|
| 581 |
+
non_linearity: str = "silu",
|
| 582 |
+
):
|
| 583 |
+
super().__init__()
|
| 584 |
+
self.dim = dim
|
| 585 |
+
self.z_dim = z_dim
|
| 586 |
+
self.dim_mult = dim_mult
|
| 587 |
+
self.num_res_blocks = num_res_blocks
|
| 588 |
+
self.attn_scales = attn_scales
|
| 589 |
+
self.temperal_upsample = temperal_upsample
|
| 590 |
+
|
| 591 |
+
self.nonlinearity = get_activation(non_linearity)
|
| 592 |
+
|
| 593 |
+
# dimensions
|
| 594 |
+
dims = [dim * u for u in [dim_mult[-1]] + dim_mult[::-1]]
|
| 595 |
+
scale = 1.0 / 2 ** (len(dim_mult) - 2)
|
| 596 |
+
|
| 597 |
+
# init block
|
| 598 |
+
self.conv_in = QwenImageCausalConv3d(z_dim, dims[0], 3, padding=1)
|
| 599 |
+
|
| 600 |
+
# middle blocks
|
| 601 |
+
self.mid_block = QwenImageMidBlock(dims[0], dropout, non_linearity, num_layers=1)
|
| 602 |
+
|
| 603 |
+
# upsample blocks
|
| 604 |
+
self.up_blocks = nn.ModuleList([])
|
| 605 |
+
for i, (in_dim, out_dim) in enumerate(zip(dims[:-1], dims[1:])):
|
| 606 |
+
# residual (+attention) blocks
|
| 607 |
+
if i > 0:
|
| 608 |
+
in_dim = in_dim // 2
|
| 609 |
+
|
| 610 |
+
# Determine if we need upsampling
|
| 611 |
+
upsample_mode = None
|
| 612 |
+
if i != len(dim_mult) - 1:
|
| 613 |
+
upsample_mode = "upsample3d" if temperal_upsample[i] else "upsample2d"
|
| 614 |
+
|
| 615 |
+
# Create and add the upsampling block
|
| 616 |
+
up_block = QwenImageUpBlock(
|
| 617 |
+
in_dim=in_dim,
|
| 618 |
+
out_dim=out_dim,
|
| 619 |
+
num_res_blocks=num_res_blocks,
|
| 620 |
+
dropout=dropout,
|
| 621 |
+
upsample_mode=upsample_mode,
|
| 622 |
+
non_linearity=non_linearity,
|
| 623 |
+
)
|
| 624 |
+
self.up_blocks.append(up_block)
|
| 625 |
+
|
| 626 |
+
# Update scale for next iteration
|
| 627 |
+
if upsample_mode is not None:
|
| 628 |
+
scale *= 2.0
|
| 629 |
+
|
| 630 |
+
# output blocks
|
| 631 |
+
self.norm_out = QwenImageRMS_norm(out_dim, images=False)
|
| 632 |
+
self.conv_out = QwenImageCausalConv3d(out_dim, input_channels, 3, padding=1)
|
| 633 |
+
|
| 634 |
+
self.gradient_checkpointing = False
|
| 635 |
+
|
| 636 |
+
def forward(self, x, feat_cache=None, feat_idx=[0]):
|
| 637 |
+
## conv1
|
| 638 |
+
if feat_cache is not None:
|
| 639 |
+
idx = feat_idx[0]
|
| 640 |
+
cache_x = x[:, :, -CACHE_T:, :, :].clone()
|
| 641 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None:
|
| 642 |
+
# cache last frame of last two chunk
|
| 643 |
+
cache_x = torch.cat([feat_cache[idx][:, :, -1, :, :].unsqueeze(2).to(cache_x.device), cache_x], dim=2)
|
| 644 |
+
x = self.conv_in(x, feat_cache[idx])
|
| 645 |
+
feat_cache[idx] = cache_x
|
| 646 |
+
feat_idx[0] += 1
|
| 647 |
+
else:
|
| 648 |
+
x = self.conv_in(x)
|
| 649 |
+
|
| 650 |
+
## middle
|
| 651 |
+
x = self.mid_block(x, feat_cache, feat_idx)
|
| 652 |
+
|
| 653 |
+
## upsamples
|
| 654 |
+
for up_block in self.up_blocks:
|
| 655 |
+
x = up_block(x, feat_cache, feat_idx)
|
| 656 |
+
|
| 657 |
+
## head
|
| 658 |
+
x = self.norm_out(x)
|
| 659 |
+
x = self.nonlinearity(x)
|
| 660 |
+
if feat_cache is not None:
|
| 661 |
+
idx = feat_idx[0]
|
| 662 |
+
cache_x = x[:, :, -CACHE_T:, :, :].clone()
|
| 663 |
+
if cache_x.shape[2] < 2 and feat_cache[idx] is not None:
|
| 664 |
+
# cache last frame of last two chunk
|
| 665 |
+
cache_x = torch.cat([feat_cache[idx][:, :, -1, :, :].unsqueeze(2).to(cache_x.device), cache_x], dim=2)
|
| 666 |
+
x = self.conv_out(x, feat_cache[idx])
|
| 667 |
+
feat_cache[idx] = cache_x
|
| 668 |
+
feat_idx[0] += 1
|
| 669 |
+
else:
|
| 670 |
+
x = self.conv_out(x)
|
| 671 |
+
return x
|
| 672 |
+
|
| 673 |
+
|
| 674 |
+
class AutoencoderKLQwenImage(ModelMixin, AutoencoderMixin, ConfigMixin, FromOriginalModelMixin):
|
| 675 |
+
r"""
|
| 676 |
+
A VAE model with KL loss for encoding videos into latents and decoding latent representations into videos.
|
| 677 |
+
|
| 678 |
+
This model inherits from [`ModelMixin`]. Check the superclass documentation for it's generic methods implemented
|
| 679 |
+
for all models (such as downloading or saving).
|
| 680 |
+
"""
|
| 681 |
+
|
| 682 |
+
_supports_gradient_checkpointing = False
|
| 683 |
+
|
| 684 |
+
# fmt: off
|
| 685 |
+
@register_to_config
|
| 686 |
+
def __init__(
|
| 687 |
+
self,
|
| 688 |
+
base_dim: int = 96,
|
| 689 |
+
z_dim: int = 16,
|
| 690 |
+
dim_mult: list[int] = [1, 2, 4, 4],
|
| 691 |
+
num_res_blocks: int = 2,
|
| 692 |
+
attn_scales: list[float] = [],
|
| 693 |
+
temperal_downsample: list[bool] = [False, True, True],
|
| 694 |
+
dropout: float = 0.0,
|
| 695 |
+
input_channels: int = 3,
|
| 696 |
+
latents_mean: list[float] = [-0.7571, -0.7089, -0.9113, 0.1075, -0.1745, 0.9653, -0.1517, 1.5508, 0.4134, -0.0715, 0.5517, -0.3632, -0.1922, -0.9497, 0.2503, -0.2921],
|
| 697 |
+
latents_std: list[float] = [2.8184, 1.4541, 2.3275, 2.6558, 1.2196, 1.7708, 2.6052, 2.0743, 3.2687, 2.1526, 2.8652, 1.5579, 1.6382, 1.1253, 2.8251, 1.9160],
|
| 698 |
+
) -> None:
|
| 699 |
+
# fmt: on
|
| 700 |
+
super().__init__()
|
| 701 |
+
|
| 702 |
+
self.z_dim = z_dim
|
| 703 |
+
self.temperal_downsample = temperal_downsample
|
| 704 |
+
self.temperal_upsample = temperal_downsample[::-1]
|
| 705 |
+
|
| 706 |
+
self.encoder = QwenImageEncoder3d(
|
| 707 |
+
base_dim, z_dim * 2, dim_mult, num_res_blocks, attn_scales, self.temperal_downsample, dropout, input_channels
|
| 708 |
+
)
|
| 709 |
+
self.quant_conv = QwenImageCausalConv3d(z_dim * 2, z_dim * 2, 1)
|
| 710 |
+
self.post_quant_conv = QwenImageCausalConv3d(z_dim, z_dim, 1)
|
| 711 |
+
|
| 712 |
+
self.decoder = QwenImageDecoder3d(
|
| 713 |
+
base_dim, z_dim, dim_mult, num_res_blocks, attn_scales, self.temperal_upsample, dropout, input_channels
|
| 714 |
+
)
|
| 715 |
+
|
| 716 |
+
self.spatial_compression_ratio = 2 ** len(self.temperal_downsample)
|
| 717 |
+
|
| 718 |
+
# When decoding a batch of video latents at a time, one can save memory by slicing across the batch dimension
|
| 719 |
+
# to perform decoding of a single video latent at a time.
|
| 720 |
+
self.use_slicing = False
|
| 721 |
+
|
| 722 |
+
# When decoding spatially large video latents, the memory requirement is very high. By breaking the video latent
|
| 723 |
+
# frames spatially into smaller tiles and performing multiple forward passes for decoding, and then blending the
|
| 724 |
+
# intermediate tiles together, the memory requirement can be lowered.
|
| 725 |
+
self.use_tiling = False
|
| 726 |
+
|
| 727 |
+
# The minimal tile height and width for spatial tiling to be used
|
| 728 |
+
self.tile_sample_min_height = 256
|
| 729 |
+
self.tile_sample_min_width = 256
|
| 730 |
+
|
| 731 |
+
# The minimal distance between two spatial tiles
|
| 732 |
+
self.tile_sample_stride_height = 192
|
| 733 |
+
self.tile_sample_stride_width = 192
|
| 734 |
+
|
| 735 |
+
# Precompute and cache conv counts for encoder and decoder for clear_cache speedup
|
| 736 |
+
self._cached_conv_counts = {
|
| 737 |
+
"decoder": sum(isinstance(m, QwenImageCausalConv3d) for m in self.decoder.modules())
|
| 738 |
+
if self.decoder is not None
|
| 739 |
+
else 0,
|
| 740 |
+
"encoder": sum(isinstance(m, QwenImageCausalConv3d) for m in self.encoder.modules())
|
| 741 |
+
if self.encoder is not None
|
| 742 |
+
else 0,
|
| 743 |
+
}
|
| 744 |
+
|
| 745 |
+
def enable_tiling(
|
| 746 |
+
self,
|
| 747 |
+
tile_sample_min_height: int | None = None,
|
| 748 |
+
tile_sample_min_width: int | None = None,
|
| 749 |
+
tile_sample_stride_height: float | None = None,
|
| 750 |
+
tile_sample_stride_width: float | None = None,
|
| 751 |
+
) -> None:
|
| 752 |
+
r"""
|
| 753 |
+
Enable tiled VAE decoding. When this option is enabled, the VAE will split the input tensor into tiles to
|
| 754 |
+
compute decoding and encoding in several steps. This is useful for saving a large amount of memory and to allow
|
| 755 |
+
processing larger images.
|
| 756 |
+
|
| 757 |
+
Args:
|
| 758 |
+
tile_sample_min_height (`int`, *optional*):
|
| 759 |
+
The minimum height required for a sample to be separated into tiles across the height dimension.
|
| 760 |
+
tile_sample_min_width (`int`, *optional*):
|
| 761 |
+
The minimum width required for a sample to be separated into tiles across the width dimension.
|
| 762 |
+
tile_sample_stride_height (`int`, *optional*):
|
| 763 |
+
The minimum amount of overlap between two consecutive vertical tiles. This is to ensure that there are
|
| 764 |
+
no tiling artifacts produced across the height dimension.
|
| 765 |
+
tile_sample_stride_width (`int`, *optional*):
|
| 766 |
+
The stride between two consecutive horizontal tiles. This is to ensure that there are no tiling
|
| 767 |
+
artifacts produced across the width dimension.
|
| 768 |
+
"""
|
| 769 |
+
self.use_tiling = True
|
| 770 |
+
self.tile_sample_min_height = tile_sample_min_height or self.tile_sample_min_height
|
| 771 |
+
self.tile_sample_min_width = tile_sample_min_width or self.tile_sample_min_width
|
| 772 |
+
self.tile_sample_stride_height = tile_sample_stride_height or self.tile_sample_stride_height
|
| 773 |
+
self.tile_sample_stride_width = tile_sample_stride_width or self.tile_sample_stride_width
|
| 774 |
+
|
| 775 |
+
def clear_cache(self):
|
| 776 |
+
def _count_conv3d(model):
|
| 777 |
+
count = 0
|
| 778 |
+
for m in model.modules():
|
| 779 |
+
if isinstance(m, QwenImageCausalConv3d):
|
| 780 |
+
count += 1
|
| 781 |
+
return count
|
| 782 |
+
|
| 783 |
+
self._conv_num = _count_conv3d(self.decoder)
|
| 784 |
+
self._conv_idx = [0]
|
| 785 |
+
self._feat_map = [None] * self._conv_num
|
| 786 |
+
# cache encode
|
| 787 |
+
self._enc_conv_num = _count_conv3d(self.encoder)
|
| 788 |
+
self._enc_conv_idx = [0]
|
| 789 |
+
self._enc_feat_map = [None] * self._enc_conv_num
|
| 790 |
+
|
| 791 |
+
def _encode(self, x: torch.Tensor):
|
| 792 |
+
_, _, num_frame, height, width = x.shape
|
| 793 |
+
|
| 794 |
+
if self.use_tiling and (width > self.tile_sample_min_width or height > self.tile_sample_min_height):
|
| 795 |
+
return self.tiled_encode(x)
|
| 796 |
+
|
| 797 |
+
self.clear_cache()
|
| 798 |
+
iter_ = 1 + (num_frame - 1) // 4
|
| 799 |
+
for i in range(iter_):
|
| 800 |
+
self._enc_conv_idx = [0]
|
| 801 |
+
if i == 0:
|
| 802 |
+
out = self.encoder(x[:, :, :1, :, :], feat_cache=self._enc_feat_map, feat_idx=self._enc_conv_idx)
|
| 803 |
+
else:
|
| 804 |
+
out_ = self.encoder(
|
| 805 |
+
x[:, :, 1 + 4 * (i - 1) : 1 + 4 * i, :, :],
|
| 806 |
+
feat_cache=self._enc_feat_map,
|
| 807 |
+
feat_idx=self._enc_conv_idx,
|
| 808 |
+
)
|
| 809 |
+
out = torch.cat([out, out_], 2)
|
| 810 |
+
|
| 811 |
+
enc = self.quant_conv(out)
|
| 812 |
+
self.clear_cache()
|
| 813 |
+
return enc
|
| 814 |
+
|
| 815 |
+
@apply_forward_hook
|
| 816 |
+
def encode(
|
| 817 |
+
self, x: torch.Tensor, return_dict: bool = True
|
| 818 |
+
) -> AutoencoderKLOutput | tuple[DiagonalGaussianDistribution]:
|
| 819 |
+
r"""
|
| 820 |
+
Encode a batch of images into latents.
|
| 821 |
+
|
| 822 |
+
Args:
|
| 823 |
+
x (`torch.Tensor`): Input batch of images.
|
| 824 |
+
return_dict (`bool`, *optional*, defaults to `True`):
|
| 825 |
+
Whether to return a [`~models.autoencoder_kl.AutoencoderKLOutput`] instead of a plain tuple.
|
| 826 |
+
|
| 827 |
+
Returns:
|
| 828 |
+
The latent representations of the encoded videos. If `return_dict` is True, a
|
| 829 |
+
[`~models.autoencoder_kl.AutoencoderKLOutput`] is returned, otherwise a plain `tuple` is returned.
|
| 830 |
+
"""
|
| 831 |
+
if self.use_slicing and x.shape[0] > 1:
|
| 832 |
+
encoded_slices = [self._encode(x_slice) for x_slice in x.split(1)]
|
| 833 |
+
h = torch.cat(encoded_slices)
|
| 834 |
+
else:
|
| 835 |
+
h = self._encode(x)
|
| 836 |
+
posterior = DiagonalGaussianDistribution(h)
|
| 837 |
+
|
| 838 |
+
if not return_dict:
|
| 839 |
+
return (posterior,)
|
| 840 |
+
return AutoencoderKLOutput(latent_dist=posterior)
|
| 841 |
+
|
| 842 |
+
def _decode(self, z: torch.Tensor, return_dict: bool = True):
|
| 843 |
+
_, _, num_frame, height, width = z.shape
|
| 844 |
+
tile_latent_min_height = self.tile_sample_min_height // self.spatial_compression_ratio
|
| 845 |
+
tile_latent_min_width = self.tile_sample_min_width // self.spatial_compression_ratio
|
| 846 |
+
|
| 847 |
+
if self.use_tiling and (width > tile_latent_min_width or height > tile_latent_min_height):
|
| 848 |
+
return self.tiled_decode(z, return_dict=return_dict)
|
| 849 |
+
|
| 850 |
+
self.clear_cache()
|
| 851 |
+
x = self.post_quant_conv(z)
|
| 852 |
+
for i in range(num_frame):
|
| 853 |
+
self._conv_idx = [0]
|
| 854 |
+
if i == 0:
|
| 855 |
+
out = self.decoder(x[:, :, i : i + 1, :, :], feat_cache=self._feat_map, feat_idx=self._conv_idx)
|
| 856 |
+
else:
|
| 857 |
+
out_ = self.decoder(x[:, :, i : i + 1, :, :], feat_cache=self._feat_map, feat_idx=self._conv_idx)
|
| 858 |
+
out = torch.cat([out, out_], 2)
|
| 859 |
+
|
| 860 |
+
out = torch.clamp(out, min=-1.0, max=1.0)
|
| 861 |
+
self.clear_cache()
|
| 862 |
+
if not return_dict:
|
| 863 |
+
return (out,)
|
| 864 |
+
|
| 865 |
+
return DecoderOutput(sample=out)
|
| 866 |
+
|
| 867 |
+
@apply_forward_hook
|
| 868 |
+
def decode(self, z: torch.Tensor, return_dict: bool = True) -> DecoderOutput | torch.Tensor:
|
| 869 |
+
r"""
|
| 870 |
+
Decode a batch of images.
|
| 871 |
+
|
| 872 |
+
Args:
|
| 873 |
+
z (`torch.Tensor`): Input batch of latent vectors.
|
| 874 |
+
return_dict (`bool`, *optional*, defaults to `True`):
|
| 875 |
+
Whether to return a [`~models.vae.DecoderOutput`] instead of a plain tuple.
|
| 876 |
+
|
| 877 |
+
Returns:
|
| 878 |
+
[`~models.vae.DecoderOutput`] or `tuple`:
|
| 879 |
+
If return_dict is True, a [`~models.vae.DecoderOutput`] is returned, otherwise a plain `tuple` is
|
| 880 |
+
returned.
|
| 881 |
+
"""
|
| 882 |
+
if self.use_slicing and z.shape[0] > 1:
|
| 883 |
+
decoded_slices = [self._decode(z_slice).sample for z_slice in z.split(1)]
|
| 884 |
+
decoded = torch.cat(decoded_slices)
|
| 885 |
+
else:
|
| 886 |
+
decoded = self._decode(z).sample
|
| 887 |
+
|
| 888 |
+
if not return_dict:
|
| 889 |
+
return (decoded,)
|
| 890 |
+
return DecoderOutput(sample=decoded)
|
| 891 |
+
|
| 892 |
+
def blend_v(self, a: torch.Tensor, b: torch.Tensor, blend_extent: int) -> torch.Tensor:
|
| 893 |
+
blend_extent = min(a.shape[-2], b.shape[-2], blend_extent)
|
| 894 |
+
for y in range(blend_extent):
|
| 895 |
+
b[:, :, :, y, :] = a[:, :, :, -blend_extent + y, :] * (1 - y / blend_extent) + b[:, :, :, y, :] * (
|
| 896 |
+
y / blend_extent
|
| 897 |
+
)
|
| 898 |
+
return b
|
| 899 |
+
|
| 900 |
+
def blend_h(self, a: torch.Tensor, b: torch.Tensor, blend_extent: int) -> torch.Tensor:
|
| 901 |
+
blend_extent = min(a.shape[-1], b.shape[-1], blend_extent)
|
| 902 |
+
for x in range(blend_extent):
|
| 903 |
+
b[:, :, :, :, x] = a[:, :, :, :, -blend_extent + x] * (1 - x / blend_extent) + b[:, :, :, :, x] * (
|
| 904 |
+
x / blend_extent
|
| 905 |
+
)
|
| 906 |
+
return b
|
| 907 |
+
|
| 908 |
+
def tiled_encode(self, x: torch.Tensor) -> AutoencoderKLOutput:
|
| 909 |
+
r"""Encode a batch of images using a tiled encoder.
|
| 910 |
+
|
| 911 |
+
Args:
|
| 912 |
+
x (`torch.Tensor`): Input batch of videos.
|
| 913 |
+
|
| 914 |
+
Returns:
|
| 915 |
+
`torch.Tensor`:
|
| 916 |
+
The latent representation of the encoded videos.
|
| 917 |
+
"""
|
| 918 |
+
_, _, num_frames, height, width = x.shape
|
| 919 |
+
latent_height = height // self.spatial_compression_ratio
|
| 920 |
+
latent_width = width // self.spatial_compression_ratio
|
| 921 |
+
|
| 922 |
+
tile_latent_min_height = self.tile_sample_min_height // self.spatial_compression_ratio
|
| 923 |
+
tile_latent_min_width = self.tile_sample_min_width // self.spatial_compression_ratio
|
| 924 |
+
tile_latent_stride_height = self.tile_sample_stride_height // self.spatial_compression_ratio
|
| 925 |
+
tile_latent_stride_width = self.tile_sample_stride_width // self.spatial_compression_ratio
|
| 926 |
+
|
| 927 |
+
blend_height = tile_latent_min_height - tile_latent_stride_height
|
| 928 |
+
blend_width = tile_latent_min_width - tile_latent_stride_width
|
| 929 |
+
|
| 930 |
+
# Split x into overlapping tiles and encode them separately.
|
| 931 |
+
# The tiles have an overlap to avoid seams between tiles.
|
| 932 |
+
rows = []
|
| 933 |
+
for i in range(0, height, self.tile_sample_stride_height):
|
| 934 |
+
row = []
|
| 935 |
+
for j in range(0, width, self.tile_sample_stride_width):
|
| 936 |
+
self.clear_cache()
|
| 937 |
+
time = []
|
| 938 |
+
frame_range = 1 + (num_frames - 1) // 4
|
| 939 |
+
for k in range(frame_range):
|
| 940 |
+
self._enc_conv_idx = [0]
|
| 941 |
+
if k == 0:
|
| 942 |
+
tile = x[:, :, :1, i : i + self.tile_sample_min_height, j : j + self.tile_sample_min_width]
|
| 943 |
+
else:
|
| 944 |
+
tile = x[
|
| 945 |
+
:,
|
| 946 |
+
:,
|
| 947 |
+
1 + 4 * (k - 1) : 1 + 4 * k,
|
| 948 |
+
i : i + self.tile_sample_min_height,
|
| 949 |
+
j : j + self.tile_sample_min_width,
|
| 950 |
+
]
|
| 951 |
+
tile = self.encoder(tile, feat_cache=self._enc_feat_map, feat_idx=self._enc_conv_idx)
|
| 952 |
+
tile = self.quant_conv(tile)
|
| 953 |
+
time.append(tile)
|
| 954 |
+
row.append(torch.cat(time, dim=2))
|
| 955 |
+
rows.append(row)
|
| 956 |
+
self.clear_cache()
|
| 957 |
+
|
| 958 |
+
result_rows = []
|
| 959 |
+
for i, row in enumerate(rows):
|
| 960 |
+
result_row = []
|
| 961 |
+
for j, tile in enumerate(row):
|
| 962 |
+
# blend the above tile and the left tile
|
| 963 |
+
# to the current tile and add the current tile to the result row
|
| 964 |
+
if i > 0:
|
| 965 |
+
tile = self.blend_v(rows[i - 1][j], tile, blend_height)
|
| 966 |
+
if j > 0:
|
| 967 |
+
tile = self.blend_h(row[j - 1], tile, blend_width)
|
| 968 |
+
result_row.append(tile[:, :, :, :tile_latent_stride_height, :tile_latent_stride_width])
|
| 969 |
+
result_rows.append(torch.cat(result_row, dim=-1))
|
| 970 |
+
|
| 971 |
+
enc = torch.cat(result_rows, dim=3)[:, :, :, :latent_height, :latent_width]
|
| 972 |
+
return enc
|
| 973 |
+
|
| 974 |
+
def tiled_decode(self, z: torch.Tensor, return_dict: bool = True) -> DecoderOutput | torch.Tensor:
|
| 975 |
+
r"""
|
| 976 |
+
Decode a batch of images using a tiled decoder.
|
| 977 |
+
|
| 978 |
+
Args:
|
| 979 |
+
z (`torch.Tensor`): Input batch of latent vectors.
|
| 980 |
+
return_dict (`bool`, *optional*, defaults to `True`):
|
| 981 |
+
Whether or not to return a [`~models.vae.DecoderOutput`] instead of a plain tuple.
|
| 982 |
+
|
| 983 |
+
Returns:
|
| 984 |
+
[`~models.vae.DecoderOutput`] or `tuple`:
|
| 985 |
+
If return_dict is True, a [`~models.vae.DecoderOutput`] is returned, otherwise a plain `tuple` is
|
| 986 |
+
returned.
|
| 987 |
+
"""
|
| 988 |
+
_, _, num_frames, height, width = z.shape
|
| 989 |
+
sample_height = height * self.spatial_compression_ratio
|
| 990 |
+
sample_width = width * self.spatial_compression_ratio
|
| 991 |
+
|
| 992 |
+
tile_latent_min_height = self.tile_sample_min_height // self.spatial_compression_ratio
|
| 993 |
+
tile_latent_min_width = self.tile_sample_min_width // self.spatial_compression_ratio
|
| 994 |
+
tile_latent_stride_height = self.tile_sample_stride_height // self.spatial_compression_ratio
|
| 995 |
+
tile_latent_stride_width = self.tile_sample_stride_width // self.spatial_compression_ratio
|
| 996 |
+
|
| 997 |
+
blend_height = self.tile_sample_min_height - self.tile_sample_stride_height
|
| 998 |
+
blend_width = self.tile_sample_min_width - self.tile_sample_stride_width
|
| 999 |
+
|
| 1000 |
+
# Split z into overlapping tiles and decode them separately.
|
| 1001 |
+
# The tiles have an overlap to avoid seams between tiles.
|
| 1002 |
+
rows = []
|
| 1003 |
+
for i in range(0, height, tile_latent_stride_height):
|
| 1004 |
+
row = []
|
| 1005 |
+
for j in range(0, width, tile_latent_stride_width):
|
| 1006 |
+
self.clear_cache()
|
| 1007 |
+
time = []
|
| 1008 |
+
for k in range(num_frames):
|
| 1009 |
+
self._conv_idx = [0]
|
| 1010 |
+
tile = z[:, :, k : k + 1, i : i + tile_latent_min_height, j : j + tile_latent_min_width]
|
| 1011 |
+
tile = self.post_quant_conv(tile)
|
| 1012 |
+
decoded = self.decoder(tile, feat_cache=self._feat_map, feat_idx=self._conv_idx)
|
| 1013 |
+
time.append(decoded)
|
| 1014 |
+
row.append(torch.cat(time, dim=2))
|
| 1015 |
+
rows.append(row)
|
| 1016 |
+
self.clear_cache()
|
| 1017 |
+
|
| 1018 |
+
result_rows = []
|
| 1019 |
+
for i, row in enumerate(rows):
|
| 1020 |
+
result_row = []
|
| 1021 |
+
for j, tile in enumerate(row):
|
| 1022 |
+
# blend the above tile and the left tile
|
| 1023 |
+
# to the current tile and add the current tile to the result row
|
| 1024 |
+
if i > 0:
|
| 1025 |
+
tile = self.blend_v(rows[i - 1][j], tile, blend_height)
|
| 1026 |
+
if j > 0:
|
| 1027 |
+
tile = self.blend_h(row[j - 1], tile, blend_width)
|
| 1028 |
+
result_row.append(tile[:, :, :, : self.tile_sample_stride_height, : self.tile_sample_stride_width])
|
| 1029 |
+
result_rows.append(torch.cat(result_row, dim=-1))
|
| 1030 |
+
|
| 1031 |
+
dec = torch.cat(result_rows, dim=3)[:, :, :, :sample_height, :sample_width]
|
| 1032 |
+
|
| 1033 |
+
if not return_dict:
|
| 1034 |
+
return (dec,)
|
| 1035 |
+
return DecoderOutput(sample=dec)
|
| 1036 |
+
|
| 1037 |
+
def forward(
|
| 1038 |
+
self,
|
| 1039 |
+
sample: torch.Tensor,
|
| 1040 |
+
sample_posterior: bool = False,
|
| 1041 |
+
return_dict: bool = True,
|
| 1042 |
+
generator: torch.Generator | None = None,
|
| 1043 |
+
) -> DecoderOutput | torch.Tensor:
|
| 1044 |
+
"""
|
| 1045 |
+
Args:
|
| 1046 |
+
sample (`torch.Tensor`): Input sample.
|
| 1047 |
+
return_dict (`bool`, *optional*, defaults to `True`):
|
| 1048 |
+
Whether or not to return a [`DecoderOutput`] instead of a plain tuple.
|
| 1049 |
+
"""
|
| 1050 |
+
x = sample
|
| 1051 |
+
posterior = self.encode(x).latent_dist
|
| 1052 |
+
if sample_posterior:
|
| 1053 |
+
z = posterior.sample(generator=generator)
|
| 1054 |
+
else:
|
| 1055 |
+
z = posterior.mode()
|
| 1056 |
+
dec = self.decode(z, return_dict=return_dict)
|
| 1057 |
+
return dec
|
code/diffusion/generator.py
ADDED
|
@@ -0,0 +1,298 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import torch
|
| 2 |
+
from diffusers import AutoencoderKL
|
| 3 |
+
import json
|
| 4 |
+
import os
|
| 5 |
+
from diffusers import FlowMatchEulerDiscreteScheduler
|
| 6 |
+
from .transformer import DiffusionTransformer
|
| 7 |
+
from .pipeline import ImageGenerationPipeline
|
| 8 |
+
import torch.nn as nn
|
| 9 |
+
import torch.nn.functional as F
|
| 10 |
+
from .autoencoder_kl_qwenimage import AutoencoderKLQwenImage
|
| 11 |
+
from inference_profile import InferenceProfile
|
| 12 |
+
|
| 13 |
+
import logging
|
| 14 |
+
logging.basicConfig(level=logging.INFO)
|
| 15 |
+
logger = logging.getLogger(__name__)
|
| 16 |
+
|
| 17 |
+
class ToClipMLP(nn.Module):
|
| 18 |
+
def __init__(self, input_dim, output_dim):
|
| 19 |
+
super().__init__()
|
| 20 |
+
#self.activation_fn = ACT2FN[config.hidden_act]
|
| 21 |
+
self.fc1 = nn.Linear(input_dim, 2048)
|
| 22 |
+
self.layer_norm1 = nn.LayerNorm(2048)
|
| 23 |
+
self.relu = nn.ReLU()
|
| 24 |
+
self.fc2 = nn.Linear(2048, output_dim)
|
| 25 |
+
self.layer_norm2 = nn.LayerNorm(output_dim)
|
| 26 |
+
|
| 27 |
+
def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
|
| 28 |
+
hidden_states = self.fc1(hidden_states)
|
| 29 |
+
hidden_states = self.layer_norm1(hidden_states)
|
| 30 |
+
hidden_states = self.relu(hidden_states)
|
| 31 |
+
hidden_states = self.fc2(hidden_states)
|
| 32 |
+
hidden_states = self.layer_norm2(hidden_states)
|
| 33 |
+
return hidden_states
|
| 34 |
+
|
| 35 |
+
class ConditionedTransformer(nn.Module):
|
| 36 |
+
def __init__(self, transformer, vision_dim=1152, use_identity_mlp=False, text_encoder_norm=False):
|
| 37 |
+
super().__init__()
|
| 38 |
+
self.transformer = transformer
|
| 39 |
+
self.mlp = ToClipMLP(vision_dim, 2560) if not use_identity_mlp else nn.Identity()
|
| 40 |
+
self.mlp.to(dtype=self.dtype)
|
| 41 |
+
# self.mlp_pool = ToClipMLP(vision_dim, 768)
|
| 42 |
+
self.config = self.transformer.config
|
| 43 |
+
self.in_channels = self.transformer.in_channels
|
| 44 |
+
self.text_encoder_norm = text_encoder_norm
|
| 45 |
+
|
| 46 |
+
# must be used together
|
| 47 |
+
#if text_encoder_norm or use_identity_mlp:
|
| 48 |
+
# assert use_identity_mlp and text_encoder_norm
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
@property
|
| 52 |
+
def dtype(self):
|
| 53 |
+
return next(self.transformer.parameters()).dtype
|
| 54 |
+
|
| 55 |
+
def forward(self, hidden_states,
|
| 56 |
+
timestep,
|
| 57 |
+
encoder_hidden_states,
|
| 58 |
+
return_dict,
|
| 59 |
+
encoder_attention_mask=None,
|
| 60 |
+
extra_vit_input=None,
|
| 61 |
+
ref_hidden_states=None,
|
| 62 |
+
encoder_hidden_states_2=None,
|
| 63 |
+
**kargs):
|
| 64 |
+
|
| 65 |
+
if encoder_hidden_states is not None:
|
| 66 |
+
if isinstance(encoder_hidden_states, list):
|
| 67 |
+
encoder_hidden_states = torch.stack(encoder_hidden_states, dim=0)
|
| 68 |
+
|
| 69 |
+
if self.text_encoder_norm:
|
| 70 |
+
encoder_hidden_states = F.normalize(encoder_hidden_states, dim=-1) * 1000.0 # 1000 matches the original text encoder norm
|
| 71 |
+
|
| 72 |
+
encoder_hidden_states = self.mlp(encoder_hidden_states)
|
| 73 |
+
|
| 74 |
+
if extra_vit_input is not None:
|
| 75 |
+
encoder_hidden_states = torch.cat((encoder_hidden_states, extra_vit_input), dim=1)
|
| 76 |
+
|
| 77 |
+
encoder_hidden_states = list(encoder_hidden_states.unbind(dim=0))
|
| 78 |
+
|
| 79 |
+
hidden_states = self.transformer(
|
| 80 |
+
x=hidden_states,
|
| 81 |
+
cap_feats=encoder_hidden_states,
|
| 82 |
+
t=timestep,
|
| 83 |
+
return_dict=False,
|
| 84 |
+
ref_x=ref_hidden_states,
|
| 85 |
+
cap_feats_2=encoder_hidden_states_2,
|
| 86 |
+
**kargs
|
| 87 |
+
)
|
| 88 |
+
return hidden_states
|
| 89 |
+
|
| 90 |
+
def enable_gradient_checkpointing(self):
|
| 91 |
+
self.transformer.enable_gradient_checkpointing()
|
| 92 |
+
|
| 93 |
+
def latent_mean_variance(latents: torch.Tensor, per_channel: bool = True, unbiased_var: bool = False):
|
| 94 |
+
"""Compute the mean and variance of latents (shape follows the diffusion
|
| 95 |
+
training ``latents``, usually ``[B, C, H, W]``).
|
| 96 |
+
|
| 97 |
+
Args:
|
| 98 |
+
latents: ``[B, C, H, W]``; a ``[B, C, T, H, W]`` tensor with
|
| 99 |
+
``T==1`` is ``squeeze(2)`` first.
|
| 100 |
+
per_channel: when True aggregate over ``(B, H, W)``, one scalar per
|
| 101 |
+
channel, shape ``[C]``; when False use one global mean/variance.
|
| 102 |
+
unbiased_var: use the unbiased estimator (Bessel).
|
| 103 |
+
|
| 104 |
+
Returns:
|
| 105 |
+
``(mean, variance)``; the std is ``variance.sqrt()`` (use
|
| 106 |
+
``torch.sqrt(variance.clamp_min(0))`` for numerical stability).
|
| 107 |
+
"""
|
| 108 |
+
z = latents
|
| 109 |
+
if z.dim() == 5 and z.shape[2] == 1:
|
| 110 |
+
z = z.squeeze(2)
|
| 111 |
+
if z.dim() != 4:
|
| 112 |
+
raise ValueError(f"Expected 4D latents [B,C,H,W] (or 5D with T=1), got {tuple(z.shape)}")
|
| 113 |
+
if per_channel:
|
| 114 |
+
dims = (0, 2, 3)
|
| 115 |
+
mean_v = z.mean(dim=dims)
|
| 116 |
+
var_v = z.var(dim=dims, unbiased=unbiased_var)
|
| 117 |
+
else:
|
| 118 |
+
mean_v = z.mean()
|
| 119 |
+
var_v = z.var(unbiased=unbiased_var)
|
| 120 |
+
return mean_v, var_v
|
| 121 |
+
|
| 122 |
+
class ImageGenerator(torch.nn.Module):
|
| 123 |
+
def __init__(self,
|
| 124 |
+
model_path,
|
| 125 |
+
vision_dim=2560,
|
| 126 |
+
scheduler_path=None,
|
| 127 |
+
mlp_state_dict=None,
|
| 128 |
+
torch_dtype=torch.float32,
|
| 129 |
+
device='cpu',
|
| 130 |
+
use_identity_mlp=False,
|
| 131 |
+
text_encoder_norm=False,
|
| 132 |
+
inference_profile=None,
|
| 133 |
+
):
|
| 134 |
+
super(ImageGenerator, self).__init__()
|
| 135 |
+
|
| 136 |
+
if not isinstance(inference_profile, InferenceProfile):
|
| 137 |
+
raise ValueError(
|
| 138 |
+
"inference_profile must be derived from the checkpoint "
|
| 139 |
+
"capability contract (load_checkpoint_capabilities)"
|
| 140 |
+
)
|
| 141 |
+
self.inference_profile = inference_profile
|
| 142 |
+
|
| 143 |
+
if device is not None:
|
| 144 |
+
device = torch.device(device)
|
| 145 |
+
else:
|
| 146 |
+
device = torch.device(torch.cuda.current_device())
|
| 147 |
+
|
| 148 |
+
self.scheduler_path = scheduler_path
|
| 149 |
+
|
| 150 |
+
vae_config_path = os.path.join(model_path, "vae", "config.json")
|
| 151 |
+
assert os.path.exists(vae_config_path)
|
| 152 |
+
|
| 153 |
+
with open(vae_config_path, "r") as f:
|
| 154 |
+
vae_config = json.load(f)
|
| 155 |
+
if "_class_name" in vae_config and vae_config["_class_name"] == "AutoencoderKLQwenImage":
|
| 156 |
+
self.vae = AutoencoderKLQwenImage.from_pretrained(
|
| 157 |
+
model_path,
|
| 158 |
+
subfolder="vae",
|
| 159 |
+
torch_dtype=torch_dtype,
|
| 160 |
+
)
|
| 161 |
+
self.vae_sample_mode = "argmax"
|
| 162 |
+
else:
|
| 163 |
+
self.vae = AutoencoderKL.from_pretrained(
|
| 164 |
+
model_path,
|
| 165 |
+
subfolder="vae",
|
| 166 |
+
torch_dtype=torch_dtype,
|
| 167 |
+
)
|
| 168 |
+
self.vae_sample_mode = "sample"
|
| 169 |
+
|
| 170 |
+
self.vae.input_channels = 4 if ('input_channels' in self.vae.config and self.vae.config.input_channels == 4) or ('in_channels' in self.vae.config and self.vae.config.in_channels == 4) else 3
|
| 171 |
+
if self.vae.input_channels != self.inference_profile.vae_input_channels:
|
| 172 |
+
raise ValueError(
|
| 173 |
+
"VAE input channels do not match the checkpoint capability "
|
| 174 |
+
f"contract: checkpoint={self.vae.input_channels}, "
|
| 175 |
+
f"capability={self.inference_profile.vae_input_channels}"
|
| 176 |
+
)
|
| 177 |
+
if self.vae_sample_mode != self.inference_profile.vae_sample_mode:
|
| 178 |
+
raise ValueError(
|
| 179 |
+
"VAE sample mode does not match the checkpoint capability "
|
| 180 |
+
f"contract: checkpoint={self.vae_sample_mode}, "
|
| 181 |
+
f"capability={self.inference_profile.vae_sample_mode}"
|
| 182 |
+
)
|
| 183 |
+
|
| 184 |
+
# self.vae.to(self.torch_type).to(self.device)
|
| 185 |
+
self.vae.requires_grad_(False)
|
| 186 |
+
|
| 187 |
+
self.train_model = DiffusionTransformer.from_pretrained(
|
| 188 |
+
model_path, subfolder="transformer",
|
| 189 |
+
torch_dtype=torch_dtype,
|
| 190 |
+
alignment_padding_mode=self.inference_profile.alignment_padding_mode,
|
| 191 |
+
multi_frame_output=self.inference_profile.multi_frame_output,
|
| 192 |
+
)
|
| 193 |
+
if (
|
| 194 |
+
self.train_model.alignment_padding_mode
|
| 195 |
+
!= self.inference_profile.alignment_padding_mode
|
| 196 |
+
or self.train_model.multi_frame_output
|
| 197 |
+
!= self.inference_profile.multi_frame_output
|
| 198 |
+
):
|
| 199 |
+
raise ValueError(
|
| 200 |
+
"instantiated Transformer capability does not match the "
|
| 201 |
+
"checkpoint capability contract: "
|
| 202 |
+
f"transformer=({self.train_model.alignment_padding_mode!r}, "
|
| 203 |
+
f"{self.train_model.multi_frame_output!r}), "
|
| 204 |
+
f"capability=({self.inference_profile.alignment_padding_mode!r}, "
|
| 205 |
+
f"{self.inference_profile.multi_frame_output!r})"
|
| 206 |
+
)
|
| 207 |
+
|
| 208 |
+
self.train_model = ConditionedTransformer(self.train_model, vision_dim=vision_dim, use_identity_mlp=use_identity_mlp, text_encoder_norm=text_encoder_norm)
|
| 209 |
+
|
| 210 |
+
assert mlp_state_dict is not None
|
| 211 |
+
self.train_model.mlp.load_state_dict(mlp_state_dict, strict=True)
|
| 212 |
+
|
| 213 |
+
self.noise_scheduler = FlowMatchEulerDiscreteScheduler.from_pretrained(self.scheduler_path, subfolder="scheduler")
|
| 214 |
+
self.noise_scheduler.config['use_dynamic_shifting'] = True
|
| 215 |
+
|
| 216 |
+
self.pipelines = ImageGenerationPipeline(
|
| 217 |
+
vae=self.vae,
|
| 218 |
+
transformer=self.train_model,
|
| 219 |
+
text_encoder=None,
|
| 220 |
+
tokenizer=None,
|
| 221 |
+
scheduler=self.noise_scheduler,
|
| 222 |
+
).to(device)
|
| 223 |
+
|
| 224 |
+
@property
|
| 225 |
+
def device(self):
|
| 226 |
+
return next(self.train_model.parameters()).device
|
| 227 |
+
|
| 228 |
+
def set_trainable_params(self, trainable_params):
|
| 229 |
+
|
| 230 |
+
self.vae.requires_grad_(False)
|
| 231 |
+
|
| 232 |
+
if trainable_params == 'all':
|
| 233 |
+
self.train_model.requires_grad_(True)
|
| 234 |
+
else:
|
| 235 |
+
self.train_model.requires_grad_(False)
|
| 236 |
+
for name, module in self.train_model.named_modules():
|
| 237 |
+
for trainable_param in trainable_params:
|
| 238 |
+
if trainable_param in name:
|
| 239 |
+
for params in module.parameters():
|
| 240 |
+
params.requires_grad = True
|
| 241 |
+
|
| 242 |
+
num_parameters_trainable = 0
|
| 243 |
+
num_parameters = 0
|
| 244 |
+
name_parameters_trainable = []
|
| 245 |
+
for n, p in self.train_model.named_parameters():
|
| 246 |
+
num_parameters += p.data.nelement()
|
| 247 |
+
if not p.requires_grad:
|
| 248 |
+
continue # frozen weights
|
| 249 |
+
name_parameters_trainable.append(n)
|
| 250 |
+
num_parameters_trainable += p.data.nelement()
|
| 251 |
+
logger.info(f"number of all Diffusion parameters: {num_parameters}, trainable: {num_parameters_trainable}")
|
| 252 |
+
|
| 253 |
+
|
| 254 |
+
def sample(self, encoder_hidden_states, steps=None, cfg=None, cfg_mode=1, seed=42, height=512, width=512, use_dynamic_shifting=False, extra_vit_input=None, ref_x=None, directvlm_hidden_states=None, num_frames_per_prompt=1):
|
| 255 |
+
sampling = self.inference_profile.resolve_sampling_parameters(
|
| 256 |
+
steps=steps,
|
| 257 |
+
cfg=cfg,
|
| 258 |
+
)
|
| 259 |
+
steps = sampling.steps
|
| 260 |
+
cfg = sampling.cfg
|
| 261 |
+
negative_prompt_embeds = None
|
| 262 |
+
if encoder_hidden_states is not None:
|
| 263 |
+
encoder_hidden_states = encoder_hidden_states.to(
|
| 264 |
+
device=self.device, dtype=self.train_model.dtype
|
| 265 |
+
)
|
| 266 |
+
encoder_hidden_states = list(encoder_hidden_states.unbind(dim=0))
|
| 267 |
+
negative_prompt_embeds= [en * 0 for en in encoder_hidden_states]
|
| 268 |
+
|
| 269 |
+
encoder_hidden_states_2 = directvlm_hidden_states
|
| 270 |
+
negative_prompt_embeds_2 = None
|
| 271 |
+
if encoder_hidden_states_2 is not None:
|
| 272 |
+
encoder_hidden_states_2 = encoder_hidden_states_2.to(
|
| 273 |
+
device=self.device, dtype=self.train_model.dtype
|
| 274 |
+
)
|
| 275 |
+
encoder_hidden_states_2 = list(encoder_hidden_states_2.unbind(dim=0))
|
| 276 |
+
negative_prompt_embeds_2= [en * 0 for en in encoder_hidden_states_2]
|
| 277 |
+
|
| 278 |
+
image = self.pipelines(
|
| 279 |
+
prompt_embeds=encoder_hidden_states,
|
| 280 |
+
negative_prompt_embeds=negative_prompt_embeds,
|
| 281 |
+
prompt_embeds_2=encoder_hidden_states_2,
|
| 282 |
+
negative_prompt_embeds_2=negative_prompt_embeds_2,
|
| 283 |
+
guidance_scale=cfg,
|
| 284 |
+
#guidance_scale_mode=cfg_mode,
|
| 285 |
+
generator=torch.manual_seed(seed),
|
| 286 |
+
num_inference_steps=steps,
|
| 287 |
+
height=height,
|
| 288 |
+
width=width,
|
| 289 |
+
max_sequence_length=512,
|
| 290 |
+
device=self.device,
|
| 291 |
+
#extra_vit_input=extra_vit_input,
|
| 292 |
+
ref_hidden_states=ref_x,
|
| 293 |
+
#use_dynamic_shifting=use_dynamic_shifting,
|
| 294 |
+
sample_mode=self.vae_sample_mode,
|
| 295 |
+
num_frames_per_prompt=num_frames_per_prompt,
|
| 296 |
+
).images
|
| 297 |
+
|
| 298 |
+
return image
|
code/diffusion/padding.py
ADDED
|
@@ -0,0 +1,45 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Alignment-padding helpers for the standard diffusion transformer."""
|
| 2 |
+
|
| 3 |
+
from typing import Optional, Sequence
|
| 4 |
+
|
| 5 |
+
import torch
|
| 6 |
+
|
| 7 |
+
|
| 8 |
+
def mask_out_alignment_padding(
|
| 9 |
+
attention_mask: torch.Tensor,
|
| 10 |
+
pad_masks: Sequence[Optional[torch.Tensor]],
|
| 11 |
+
offsets: Sequence[int],
|
| 12 |
+
) -> torch.Tensor:
|
| 13 |
+
"""Exclude per-item alignment padding from a 2D boolean attention mask."""
|
| 14 |
+
|
| 15 |
+
if attention_mask.ndim != 2 or attention_mask.dtype != torch.bool:
|
| 16 |
+
raise ValueError(
|
| 17 |
+
"attention_mask must be a 2D boolean tensor, got "
|
| 18 |
+
f"shape={attention_mask.shape}, dtype={attention_mask.dtype}"
|
| 19 |
+
)
|
| 20 |
+
batch_size = attention_mask.shape[0]
|
| 21 |
+
if len(pad_masks) != batch_size or len(offsets) != batch_size:
|
| 22 |
+
raise ValueError(
|
| 23 |
+
"pad mask metadata must match the attention-mask batch size: "
|
| 24 |
+
f"batch={batch_size}, pad_masks={len(pad_masks)}, offsets={len(offsets)}"
|
| 25 |
+
)
|
| 26 |
+
|
| 27 |
+
for item_index, (pad_mask, offset) in enumerate(zip(pad_masks, offsets)):
|
| 28 |
+
if pad_mask is None or pad_mask.numel() == 0:
|
| 29 |
+
continue
|
| 30 |
+
if pad_mask.ndim != 1 or pad_mask.dtype != torch.bool:
|
| 31 |
+
raise ValueError(
|
| 32 |
+
"each alignment-pad mask must be a 1D boolean tensor: "
|
| 33 |
+
f"item={item_index}, shape={pad_mask.shape}, dtype={pad_mask.dtype}"
|
| 34 |
+
)
|
| 35 |
+
offset = int(offset)
|
| 36 |
+
end = offset + pad_mask.shape[0]
|
| 37 |
+
if offset < 0 or end > attention_mask.shape[1]:
|
| 38 |
+
raise ValueError(
|
| 39 |
+
"alignment-pad mask falls outside the attention sequence: "
|
| 40 |
+
f"item={item_index}, offset={offset}, length={pad_mask.shape[0]}, "
|
| 41 |
+
f"sequence={attention_mask.shape[1]}"
|
| 42 |
+
)
|
| 43 |
+
attention_mask[item_index, offset:end].masked_fill_(pad_mask, False)
|
| 44 |
+
|
| 45 |
+
return attention_mask
|
code/diffusion/pipeline.py
ADDED
|
@@ -0,0 +1,716 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright (c) Ant Group. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
# All rights and credit for the original implementation remain with the original authors and contributors, and this project complies with the applicable open-source license terms of the referenced repository.
|
| 16 |
+
|
| 17 |
+
import inspect
|
| 18 |
+
from typing import Any, Callable, Dict, List, Optional, Union
|
| 19 |
+
|
| 20 |
+
import torch
|
| 21 |
+
from transformers import AutoTokenizer, PreTrainedModel
|
| 22 |
+
|
| 23 |
+
from diffusers.image_processor import VaeImageProcessor
|
| 24 |
+
from diffusers.models.autoencoders import AutoencoderKL
|
| 25 |
+
from diffusers.pipelines.pipeline_utils import DiffusionPipeline
|
| 26 |
+
from diffusers.schedulers import FlowMatchEulerDiscreteScheduler
|
| 27 |
+
from diffusers.utils import logging, replace_example_docstring
|
| 28 |
+
from diffusers.utils.torch_utils import randn_tensor
|
| 29 |
+
|
| 30 |
+
from .transformer import DiffusionTransformer
|
| 31 |
+
|
| 32 |
+
from dataclasses import dataclass
|
| 33 |
+
from typing import List, Union
|
| 34 |
+
|
| 35 |
+
import numpy as np
|
| 36 |
+
import PIL.Image
|
| 37 |
+
|
| 38 |
+
from diffusers.utils import BaseOutput
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
@dataclass
|
| 42 |
+
class ImageGenerationOutput(BaseOutput):
|
| 43 |
+
"""
|
| 44 |
+
Output class for image generation pipelines.
|
| 45 |
+
|
| 46 |
+
Args:
|
| 47 |
+
images (`List[PIL.Image.Image]` or `np.ndarray`)
|
| 48 |
+
List of denoised PIL images of length `batch_size` or numpy array of shape `(batch_size, height, width,
|
| 49 |
+
num_channels)`. PIL images or numpy array present the denoised images of the diffusion pipeline.
|
| 50 |
+
"""
|
| 51 |
+
|
| 52 |
+
images: Union[List[PIL.Image.Image], np.ndarray]
|
| 53 |
+
|
| 54 |
+
|
| 55 |
+
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
| 56 |
+
|
| 57 |
+
EXAMPLE_DOC_STRING = """
|
| 58 |
+
Examples:
|
| 59 |
+
This pipeline is assembled by the Ming image checkpoint loader; the
|
| 60 |
+
supported entry point is the repository CLI:
|
| 61 |
+
|
| 62 |
+
```bash
|
| 63 |
+
python infer.py \
|
| 64 |
+
--model /path/to/checkpoint-package \
|
| 65 |
+
--task text-to-image \
|
| 66 |
+
--prompt "A small red cube on a white table" \
|
| 67 |
+
--output-dir outputs/t2i
|
| 68 |
+
```
|
| 69 |
+
"""
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
# Copied from diffusers.pipelines.flux.pipeline_flux.calculate_shift
|
| 73 |
+
def calculate_shift(
|
| 74 |
+
image_seq_len,
|
| 75 |
+
base_seq_len: int = 256,
|
| 76 |
+
max_seq_len: int = 4096,
|
| 77 |
+
base_shift: float = 0.5,
|
| 78 |
+
max_shift: float = 1.15,
|
| 79 |
+
):
|
| 80 |
+
m = (max_shift - base_shift) / (max_seq_len - base_seq_len)
|
| 81 |
+
b = base_shift - m * base_seq_len
|
| 82 |
+
mu = image_seq_len * m + b
|
| 83 |
+
return mu
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.retrieve_timesteps
|
| 87 |
+
def retrieve_timesteps(
|
| 88 |
+
scheduler,
|
| 89 |
+
num_inference_steps: Optional[int] = None,
|
| 90 |
+
device: Optional[Union[str, torch.device]] = None,
|
| 91 |
+
timesteps: Optional[List[int]] = None,
|
| 92 |
+
sigmas: Optional[List[float]] = None,
|
| 93 |
+
**kwargs,
|
| 94 |
+
):
|
| 95 |
+
r"""
|
| 96 |
+
Calls the scheduler's `set_timesteps` method and retrieves timesteps from the scheduler after the call. Handles
|
| 97 |
+
custom timesteps. Any kwargs will be supplied to `scheduler.set_timesteps`.
|
| 98 |
+
|
| 99 |
+
Args:
|
| 100 |
+
scheduler (`SchedulerMixin`):
|
| 101 |
+
The scheduler to get timesteps from.
|
| 102 |
+
num_inference_steps (`int`):
|
| 103 |
+
The number of diffusion steps used when generating samples with a pre-trained model. If used, `timesteps`
|
| 104 |
+
must be `None`.
|
| 105 |
+
device (`str` or `torch.device`, *optional*):
|
| 106 |
+
The device to which the timesteps should be moved to. If `None`, the timesteps are not moved.
|
| 107 |
+
timesteps (`List[int]`, *optional*):
|
| 108 |
+
Custom timesteps used to override the timestep spacing strategy of the scheduler. If `timesteps` is passed,
|
| 109 |
+
`num_inference_steps` and `sigmas` must be `None`.
|
| 110 |
+
sigmas (`List[float]`, *optional*):
|
| 111 |
+
Custom sigmas used to override the timestep spacing strategy of the scheduler. If `sigmas` is passed,
|
| 112 |
+
`num_inference_steps` and `timesteps` must be `None`.
|
| 113 |
+
|
| 114 |
+
Returns:
|
| 115 |
+
`Tuple[torch.Tensor, int]`: A tuple where the first element is the timestep schedule from the scheduler and the
|
| 116 |
+
second element is the number of inference steps.
|
| 117 |
+
"""
|
| 118 |
+
if timesteps is not None and sigmas is not None:
|
| 119 |
+
raise ValueError("Only one of `timesteps` or `sigmas` can be passed. Please choose one to set custom values")
|
| 120 |
+
if timesteps is not None:
|
| 121 |
+
accepts_timesteps = "timesteps" in set(inspect.signature(scheduler.set_timesteps).parameters.keys())
|
| 122 |
+
if not accepts_timesteps:
|
| 123 |
+
raise ValueError(
|
| 124 |
+
f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
|
| 125 |
+
f" timestep schedules. Please check whether you are using the correct scheduler."
|
| 126 |
+
)
|
| 127 |
+
scheduler.set_timesteps(timesteps=timesteps, device=device, **kwargs)
|
| 128 |
+
timesteps = scheduler.timesteps
|
| 129 |
+
num_inference_steps = len(timesteps)
|
| 130 |
+
elif sigmas is not None:
|
| 131 |
+
accept_sigmas = "sigmas" in set(inspect.signature(scheduler.set_timesteps).parameters.keys())
|
| 132 |
+
if not accept_sigmas:
|
| 133 |
+
raise ValueError(
|
| 134 |
+
f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
|
| 135 |
+
f" sigmas schedules. Please check whether you are using the correct scheduler."
|
| 136 |
+
)
|
| 137 |
+
scheduler.set_timesteps(sigmas=sigmas, device=device, **kwargs)
|
| 138 |
+
timesteps = scheduler.timesteps
|
| 139 |
+
num_inference_steps = len(timesteps)
|
| 140 |
+
else:
|
| 141 |
+
scheduler.set_timesteps(num_inference_steps, device=device, **kwargs)
|
| 142 |
+
timesteps = scheduler.timesteps
|
| 143 |
+
return timesteps, num_inference_steps
|
| 144 |
+
|
| 145 |
+
|
| 146 |
+
class ImageGenerationPipeline(DiffusionPipeline):
|
| 147 |
+
model_cpu_offload_seq = "text_encoder->transformer->vae"
|
| 148 |
+
_optional_components = []
|
| 149 |
+
_callback_tensor_inputs = ["latents", "prompt_embeds"]
|
| 150 |
+
|
| 151 |
+
def __init__(
|
| 152 |
+
self,
|
| 153 |
+
scheduler: FlowMatchEulerDiscreteScheduler,
|
| 154 |
+
vae: AutoencoderKL,
|
| 155 |
+
text_encoder: PreTrainedModel,
|
| 156 |
+
tokenizer: AutoTokenizer,
|
| 157 |
+
transformer: DiffusionTransformer,
|
| 158 |
+
):
|
| 159 |
+
super().__init__()
|
| 160 |
+
|
| 161 |
+
self.register_modules(
|
| 162 |
+
vae=vae,
|
| 163 |
+
text_encoder=text_encoder,
|
| 164 |
+
tokenizer=tokenizer,
|
| 165 |
+
scheduler=scheduler,
|
| 166 |
+
transformer=transformer,
|
| 167 |
+
)
|
| 168 |
+
|
| 169 |
+
if hasattr(self, "vae") and self.vae is not None and 'temperal_downsample' in self.vae.config:
|
| 170 |
+
self.vae_scale_factor = 2 ** len(self.vae.config.temperal_downsample)
|
| 171 |
+
else:
|
| 172 |
+
self.vae_scale_factor = (
|
| 173 |
+
2 ** (len(self.vae.config.block_out_channels) - 1) if hasattr(self, "vae") and self.vae is not None else 8
|
| 174 |
+
)
|
| 175 |
+
|
| 176 |
+
self.image_processor = VaeImageProcessor(vae_scale_factor=self.vae_scale_factor * 2)
|
| 177 |
+
|
| 178 |
+
def encode_prompt(
|
| 179 |
+
self,
|
| 180 |
+
prompt: Union[str, List[str]],
|
| 181 |
+
device: Optional[torch.device] = None,
|
| 182 |
+
do_classifier_free_guidance: bool = True,
|
| 183 |
+
negative_prompt: Optional[Union[str, List[str]]] = None,
|
| 184 |
+
prompt_embeds: Optional[List[torch.FloatTensor]] = None,
|
| 185 |
+
negative_prompt_embeds: Optional[torch.FloatTensor] = None,
|
| 186 |
+
max_sequence_length: int = 512,
|
| 187 |
+
):
|
| 188 |
+
prompt = [prompt] if isinstance(prompt, str) else prompt
|
| 189 |
+
prompt_embeds = self._encode_prompt(
|
| 190 |
+
prompt=prompt,
|
| 191 |
+
device=device,
|
| 192 |
+
prompt_embeds=prompt_embeds,
|
| 193 |
+
max_sequence_length=max_sequence_length,
|
| 194 |
+
)
|
| 195 |
+
|
| 196 |
+
if do_classifier_free_guidance:
|
| 197 |
+
if negative_prompt is None:
|
| 198 |
+
negative_prompt = ["" for _ in prompt]
|
| 199 |
+
else:
|
| 200 |
+
negative_prompt = [negative_prompt] if isinstance(negative_prompt, str) else negative_prompt
|
| 201 |
+
assert len(prompt) == len(negative_prompt)
|
| 202 |
+
negative_prompt_embeds = self._encode_prompt(
|
| 203 |
+
prompt=negative_prompt,
|
| 204 |
+
device=device,
|
| 205 |
+
prompt_embeds=negative_prompt_embeds,
|
| 206 |
+
max_sequence_length=max_sequence_length,
|
| 207 |
+
)
|
| 208 |
+
else:
|
| 209 |
+
negative_prompt_embeds = []
|
| 210 |
+
return prompt_embeds, negative_prompt_embeds
|
| 211 |
+
|
| 212 |
+
def _encode_prompt(
|
| 213 |
+
self,
|
| 214 |
+
prompt: Union[str, List[str]],
|
| 215 |
+
device: Optional[torch.device] = None,
|
| 216 |
+
prompt_embeds: Optional[List[torch.FloatTensor]] = None,
|
| 217 |
+
max_sequence_length: int = 512,
|
| 218 |
+
) -> List[torch.FloatTensor]:
|
| 219 |
+
device = device or self._execution_device
|
| 220 |
+
|
| 221 |
+
if prompt_embeds is not None:
|
| 222 |
+
return prompt_embeds
|
| 223 |
+
|
| 224 |
+
if isinstance(prompt, str):
|
| 225 |
+
prompt = [prompt]
|
| 226 |
+
|
| 227 |
+
for i, prompt_item in enumerate(prompt):
|
| 228 |
+
messages = [
|
| 229 |
+
{"role": "user", "content": prompt_item},
|
| 230 |
+
]
|
| 231 |
+
prompt_item = self.tokenizer.apply_chat_template(
|
| 232 |
+
messages,
|
| 233 |
+
tokenize=False,
|
| 234 |
+
add_generation_prompt=True,
|
| 235 |
+
enable_thinking=True,
|
| 236 |
+
)
|
| 237 |
+
prompt[i] = prompt_item
|
| 238 |
+
|
| 239 |
+
text_inputs = self.tokenizer(
|
| 240 |
+
prompt,
|
| 241 |
+
padding="max_length",
|
| 242 |
+
max_length=max_sequence_length,
|
| 243 |
+
truncation=True,
|
| 244 |
+
return_tensors="pt",
|
| 245 |
+
)
|
| 246 |
+
|
| 247 |
+
text_input_ids = text_inputs.input_ids.to(device)
|
| 248 |
+
prompt_masks = text_inputs.attention_mask.to(device).bool()
|
| 249 |
+
|
| 250 |
+
prompt_embeds = self.text_encoder(
|
| 251 |
+
input_ids=text_input_ids,
|
| 252 |
+
attention_mask=prompt_masks,
|
| 253 |
+
output_hidden_states=True,
|
| 254 |
+
).hidden_states[-2]
|
| 255 |
+
|
| 256 |
+
embeddings_list = []
|
| 257 |
+
|
| 258 |
+
for i in range(len(prompt_embeds)):
|
| 259 |
+
embeddings_list.append(prompt_embeds[i][prompt_masks[i]])
|
| 260 |
+
|
| 261 |
+
return embeddings_list
|
| 262 |
+
|
| 263 |
+
def prepare_latents(
|
| 264 |
+
self,
|
| 265 |
+
batch_size,
|
| 266 |
+
num_channels_latents,
|
| 267 |
+
height,
|
| 268 |
+
width,
|
| 269 |
+
dtype,
|
| 270 |
+
device,
|
| 271 |
+
generator,
|
| 272 |
+
latents=None,
|
| 273 |
+
):
|
| 274 |
+
height = 2 * (int(height) // (self.vae_scale_factor * 2))
|
| 275 |
+
width = 2 * (int(width) // (self.vae_scale_factor * 2))
|
| 276 |
+
|
| 277 |
+
shape = (batch_size, num_channels_latents, height, width)
|
| 278 |
+
|
| 279 |
+
if latents is None:
|
| 280 |
+
latents = randn_tensor(shape, generator=generator, device=device, dtype=dtype)
|
| 281 |
+
else:
|
| 282 |
+
if latents.shape != shape:
|
| 283 |
+
raise ValueError(f"Unexpected latents shape, got {latents.shape}, expected {shape}")
|
| 284 |
+
latents = latents.to(device)
|
| 285 |
+
return latents
|
| 286 |
+
|
| 287 |
+
@property
|
| 288 |
+
def guidance_scale(self):
|
| 289 |
+
return self._guidance_scale
|
| 290 |
+
|
| 291 |
+
@property
|
| 292 |
+
def do_classifier_free_guidance(self):
|
| 293 |
+
return self._guidance_scale > 1
|
| 294 |
+
|
| 295 |
+
@property
|
| 296 |
+
def joint_attention_kwargs(self):
|
| 297 |
+
return self._joint_attention_kwargs
|
| 298 |
+
|
| 299 |
+
@property
|
| 300 |
+
def num_timesteps(self):
|
| 301 |
+
return self._num_timesteps
|
| 302 |
+
|
| 303 |
+
@property
|
| 304 |
+
def interrupt(self):
|
| 305 |
+
return self._interrupt
|
| 306 |
+
|
| 307 |
+
@torch.no_grad()
|
| 308 |
+
@replace_example_docstring(EXAMPLE_DOC_STRING)
|
| 309 |
+
def __call__(
|
| 310 |
+
self,
|
| 311 |
+
prompt: Union[str, List[str]] = None,
|
| 312 |
+
height: Optional[int] = None,
|
| 313 |
+
width: Optional[int] = None,
|
| 314 |
+
num_inference_steps: int = 50,
|
| 315 |
+
sigmas: Optional[List[float]] = None,
|
| 316 |
+
guidance_scale: float = 5.0,
|
| 317 |
+
cfg_normalization: bool = False,
|
| 318 |
+
cfg_truncation: float = 1.0,
|
| 319 |
+
negative_prompt: Optional[Union[str, List[str]]] = None,
|
| 320 |
+
num_images_per_prompt: Optional[int] = 1,
|
| 321 |
+
num_frames_per_prompt: Optional[int] = 1,
|
| 322 |
+
generator: Optional[Union[torch.Generator, List[torch.Generator]]] = None,
|
| 323 |
+
latents: Optional[torch.FloatTensor] = None,
|
| 324 |
+
prompt_embeds: Optional[List[torch.FloatTensor]] = None,
|
| 325 |
+
negative_prompt_embeds: Optional[List[torch.FloatTensor]] = None,
|
| 326 |
+
output_type: Optional[str] = "pil",
|
| 327 |
+
return_dict: bool = True,
|
| 328 |
+
joint_attention_kwargs: Optional[Dict[str, Any]] = None,
|
| 329 |
+
callback_on_step_end: Optional[Callable[[int, int, Dict], None]] = None,
|
| 330 |
+
callback_on_step_end_tensor_inputs: List[str] = ["latents"],
|
| 331 |
+
max_sequence_length: int = 512,
|
| 332 |
+
device: Optional[Union[str, torch.device]] = None,
|
| 333 |
+
ref_hidden_states: Optional[torch.FloatTensor] = None,
|
| 334 |
+
prompt_embeds_2: Optional[List[torch.FloatTensor]] = None,
|
| 335 |
+
negative_prompt_embeds_2: Optional[List[torch.FloatTensor]] = None,
|
| 336 |
+
sample_mode: Optional[str] = "sample",
|
| 337 |
+
):
|
| 338 |
+
r"""
|
| 339 |
+
Function invoked when calling the pipeline for generation.
|
| 340 |
+
|
| 341 |
+
Args:
|
| 342 |
+
prompt (`str` or `List[str]`, *optional*):
|
| 343 |
+
The prompt or prompts to guide the image generation. If not defined, one has to pass `prompt_embeds`.
|
| 344 |
+
instead.
|
| 345 |
+
height (`int`, *optional*, defaults to 1024):
|
| 346 |
+
The height in pixels of the generated image.
|
| 347 |
+
width (`int`, *optional*, defaults to 1024):
|
| 348 |
+
The width in pixels of the generated image.
|
| 349 |
+
num_inference_steps (`int`, *optional*, defaults to 50):
|
| 350 |
+
The number of denoising steps. More denoising steps usually lead to a higher quality image at the
|
| 351 |
+
expense of slower inference.
|
| 352 |
+
sigmas (`List[float]`, *optional*):
|
| 353 |
+
Custom sigmas to use for the denoising process with schedulers which support a `sigmas` argument in
|
| 354 |
+
their `set_timesteps` method. If not defined, the default behavior when `num_inference_steps` is passed
|
| 355 |
+
will be used.
|
| 356 |
+
guidance_scale (`float`, *optional*, defaults to 5.0):
|
| 357 |
+
Guidance scale as defined in [Classifier-Free Diffusion Guidance](https://arxiv.org/abs/2207.12598).
|
| 358 |
+
`guidance_scale` is defined as `w` of equation 2. of [Imagen
|
| 359 |
+
Paper](https://arxiv.org/pdf/2205.11487.pdf). Guidance scale is enabled by setting `guidance_scale >
|
| 360 |
+
1`. Higher guidance scale encourages to generate images that are closely linked to the text `prompt`,
|
| 361 |
+
usually at the expense of lower image quality.
|
| 362 |
+
cfg_normalization (`bool`, *optional*, defaults to False):
|
| 363 |
+
Whether to apply configuration normalization.
|
| 364 |
+
cfg_truncation (`float`, *optional*, defaults to 1.0):
|
| 365 |
+
The truncation value for configuration.
|
| 366 |
+
negative_prompt (`str` or `List[str]`, *optional*):
|
| 367 |
+
The prompt or prompts not to guide the image generation. If not defined, one has to pass
|
| 368 |
+
`negative_prompt_embeds` instead. Ignored when not using guidance (i.e., ignored if `guidance_scale` is
|
| 369 |
+
less than `1`).
|
| 370 |
+
num_images_per_prompt (`int`, *optional*, defaults to 1):
|
| 371 |
+
The number of images to generate per prompt.
|
| 372 |
+
generator (`torch.Generator` or `List[torch.Generator]`, *optional*):
|
| 373 |
+
One or a list of [torch generator(s)](https://pytorch.org/docs/stable/generated/torch.Generator.html)
|
| 374 |
+
to make generation deterministic.
|
| 375 |
+
latents (`torch.FloatTensor`, *optional*):
|
| 376 |
+
Pre-generated noisy latents, sampled from a Gaussian distribution, to be used as inputs for image
|
| 377 |
+
generation. Can be used to tweak the same generation with different prompts. If not provided, a latents
|
| 378 |
+
tensor will be generated by sampling using the supplied random `generator`.
|
| 379 |
+
prompt_embeds (`List[torch.FloatTensor]`, *optional*):
|
| 380 |
+
Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not
|
| 381 |
+
provided, text embeddings will be generated from `prompt` input argument.
|
| 382 |
+
negative_prompt_embeds (`List[torch.FloatTensor]`, *optional*):
|
| 383 |
+
Pre-generated negative text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt
|
| 384 |
+
weighting. If not provided, negative_prompt_embeds will be generated from `negative_prompt` input
|
| 385 |
+
argument.
|
| 386 |
+
output_type (`str`, *optional*, defaults to `"pil"`):
|
| 387 |
+
The output format of the generate image. Choose between
|
| 388 |
+
[PIL](https://pillow.readthedocs.io/en/stable/): `PIL.Image.Image` or `np.array`.
|
| 389 |
+
return_dict (`bool`, *optional*, defaults to `True`):
|
| 390 |
+
Whether or not to return a [`~pipelines.stable_diffusion.ImageGenerationOutput`] instead of a plain
|
| 391 |
+
tuple.
|
| 392 |
+
joint_attention_kwargs (`dict`, *optional*):
|
| 393 |
+
A kwargs dictionary that if specified is passed along to the `AttentionProcessor` as defined under
|
| 394 |
+
`self.processor` in
|
| 395 |
+
[diffusers.models.attention_processor](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py).
|
| 396 |
+
callback_on_step_end (`Callable`, *optional*):
|
| 397 |
+
A function that calls at the end of each denoising steps during the inference. The function is called
|
| 398 |
+
with the following arguments: `callback_on_step_end(self: DiffusionPipeline, step: int, timestep: int,
|
| 399 |
+
callback_kwargs: Dict)`. `callback_kwargs` will include a list of all tensors as specified by
|
| 400 |
+
`callback_on_step_end_tensor_inputs`.
|
| 401 |
+
callback_on_step_end_tensor_inputs (`List`, *optional*):
|
| 402 |
+
The list of tensor inputs for the `callback_on_step_end` function. The tensors specified in the list
|
| 403 |
+
will be passed as `callback_kwargs` argument. You will only be able to include variables listed in the
|
| 404 |
+
`._callback_tensor_inputs` attribute of your pipeline class.
|
| 405 |
+
max_sequence_length (`int`, *optional*, defaults to 512):
|
| 406 |
+
Maximum sequence length to use with the `prompt`.
|
| 407 |
+
|
| 408 |
+
Examples:
|
| 409 |
+
|
| 410 |
+
Returns:
|
| 411 |
+
[`ImageGenerationOutput`] or `tuple`: [`ImageGenerationOutput`] if
|
| 412 |
+
`return_dict` is True, otherwise a `tuple`. When returning a tuple, the first element is a list with the
|
| 413 |
+
generated images.
|
| 414 |
+
"""
|
| 415 |
+
height = height or 1024
|
| 416 |
+
width = width or 1024
|
| 417 |
+
if type(num_frames_per_prompt) is not int or num_frames_per_prompt < 1:
|
| 418 |
+
raise ValueError("num_frames_per_prompt must be an integer >= 1")
|
| 419 |
+
supports_multi_frame = bool(
|
| 420 |
+
getattr(self.transformer.config, "multi_frame_output", False)
|
| 421 |
+
)
|
| 422 |
+
if num_frames_per_prompt > 1 and not supports_multi_frame:
|
| 423 |
+
raise ValueError(
|
| 424 |
+
"the loaded checkpoint profile does not support multi-frame output"
|
| 425 |
+
)
|
| 426 |
+
|
| 427 |
+
vae_scale = self.vae_scale_factor * 2
|
| 428 |
+
if height % vae_scale != 0:
|
| 429 |
+
raise ValueError(
|
| 430 |
+
f"Height must be divisible by {vae_scale} (got {height}). "
|
| 431 |
+
f"Please adjust the height to a multiple of {vae_scale}."
|
| 432 |
+
)
|
| 433 |
+
if width % vae_scale != 0:
|
| 434 |
+
raise ValueError(
|
| 435 |
+
f"Width must be divisible by {vae_scale} (got {width}). "
|
| 436 |
+
f"Please adjust the width to a multiple of {vae_scale}."
|
| 437 |
+
)
|
| 438 |
+
|
| 439 |
+
device = device or self._execution_device
|
| 440 |
+
|
| 441 |
+
self._guidance_scale = guidance_scale
|
| 442 |
+
self._joint_attention_kwargs = joint_attention_kwargs
|
| 443 |
+
self._interrupt = False
|
| 444 |
+
self._cfg_normalization = cfg_normalization
|
| 445 |
+
self._cfg_truncation = cfg_truncation
|
| 446 |
+
# 2. Define call parameters
|
| 447 |
+
|
| 448 |
+
self.vae.config.shift_factor = self.vae.config.shift_factor.to(device=device, dtype=self.vae.dtype) if isinstance(self.vae.config.shift_factor, torch.Tensor) else self.vae.config.shift_factor
|
| 449 |
+
self.vae.config.scaling_factor = self.vae.config.scaling_factor.to(device=device, dtype=self.vae.dtype) if isinstance(self.vae.config.scaling_factor, torch.Tensor) else self.vae.config.scaling_factor
|
| 450 |
+
|
| 451 |
+
assert prompt is None
|
| 452 |
+
assert prompt_embeds is not None or prompt_embeds_2 is not None
|
| 453 |
+
if prompt_embeds is not None:
|
| 454 |
+
batch_size = len(prompt_embeds)
|
| 455 |
+
if prompt_embeds_2 is not None:
|
| 456 |
+
assert len(prompt_embeds_2) == len(prompt_embeds)
|
| 457 |
+
|
| 458 |
+
assert negative_prompt_embeds is not None
|
| 459 |
+
assert len(negative_prompt_embeds) == len(prompt_embeds)
|
| 460 |
+
else:
|
| 461 |
+
assert prompt_embeds_2 is not None
|
| 462 |
+
batch_size = len(prompt_embeds_2)
|
| 463 |
+
assert negative_prompt_embeds_2 is not None
|
| 464 |
+
assert len(negative_prompt_embeds_2) == len(prompt_embeds_2)
|
| 465 |
+
|
| 466 |
+
|
| 467 |
+
|
| 468 |
+
# 4. Prepare latent variables
|
| 469 |
+
num_channels_latents = self.transformer.in_channels
|
| 470 |
+
|
| 471 |
+
latents = self.prepare_latents(
|
| 472 |
+
batch_size * num_images_per_prompt * num_frames_per_prompt,
|
| 473 |
+
num_channels_latents,
|
| 474 |
+
height,
|
| 475 |
+
width,
|
| 476 |
+
torch.float32,
|
| 477 |
+
device,
|
| 478 |
+
generator,
|
| 479 |
+
latents,
|
| 480 |
+
)
|
| 481 |
+
|
| 482 |
+
if ref_hidden_states is not None:
|
| 483 |
+
assert ref_hidden_states.ndim == 4 # and ref_hidden_states.shape[0] == 1
|
| 484 |
+
ref_hidden_states = ref_hidden_states.to(self.vae.dtype).to(device)
|
| 485 |
+
C = ref_hidden_states.shape[1]
|
| 486 |
+
input_channels = self.vae.input_channels
|
| 487 |
+
if C % input_channels != 0:
|
| 488 |
+
raise ValueError(f"ref_hidden_states.shape[1] must be a multiple of {input_channels}, got C={C}")
|
| 489 |
+
num_images = C // input_channels
|
| 490 |
+
ref_latents = []
|
| 491 |
+
for i in range(num_images):
|
| 492 |
+
x = ref_hidden_states[:, i * input_channels:(i + 1) * input_channels, :, :] # RGB block of image i
|
| 493 |
+
if 'temperal_downsample' in self.vae.config:
|
| 494 |
+
x = x.unsqueeze(2)
|
| 495 |
+
if sample_mode == "argmax":
|
| 496 |
+
z = self.vae.encode(x).latent_dist.mode()
|
| 497 |
+
elif sample_mode == "sample":
|
| 498 |
+
z = self.vae.encode(x).latent_dist.sample()
|
| 499 |
+
z = (z - self.vae.config.shift_factor) * self.vae.config.scaling_factor
|
| 500 |
+
ref_latents.append(z)
|
| 501 |
+
|
| 502 |
+
ref_hidden_states = torch.cat(ref_latents, dim=1)
|
| 503 |
+
|
| 504 |
+
if ref_hidden_states.dim() == 5:
|
| 505 |
+
ref_hidden_states = ref_hidden_states.squeeze(2)
|
| 506 |
+
|
| 507 |
+
|
| 508 |
+
|
| 509 |
+
# Repeat prompt_embeds for num_images_per_prompt
|
| 510 |
+
if num_images_per_prompt > 1:
|
| 511 |
+
if prompt_embeds is not None:
|
| 512 |
+
prompt_embeds = [pe for pe in prompt_embeds for _ in range(num_images_per_prompt)]
|
| 513 |
+
if self.do_classifier_free_guidance and negative_prompt_embeds:
|
| 514 |
+
negative_prompt_embeds = [npe for npe in negative_prompt_embeds for _ in range(num_images_per_prompt)]
|
| 515 |
+
|
| 516 |
+
if prompt_embeds_2 is not None:
|
| 517 |
+
prompt_embeds_2 = [pe for pe in prompt_embeds_2 for _ in range(num_images_per_prompt)]
|
| 518 |
+
if self.do_classifier_free_guidance and negative_prompt_embeds_2:
|
| 519 |
+
negative_prompt_embeds_2 = [npe for npe in negative_prompt_embeds_2 for _ in range(num_images_per_prompt)]
|
| 520 |
+
|
| 521 |
+
actual_batch_size = batch_size * num_images_per_prompt
|
| 522 |
+
image_seq_len = (latents.shape[2] // 2) * (latents.shape[3] // 2)
|
| 523 |
+
|
| 524 |
+
# 5. Prepare timesteps
|
| 525 |
+
if image_seq_len >= 4096:
|
| 526 |
+
self.scheduler.config["max_image_seq_len"] = image_seq_len
|
| 527 |
+
self.scheduler.config["max_shift"] = 1.35
|
| 528 |
+
else:
|
| 529 |
+
self.scheduler.config["max_image_seq_len"] = 4096
|
| 530 |
+
self.scheduler.config["max_shift"] = 1.15
|
| 531 |
+
mu = calculate_shift(
|
| 532 |
+
image_seq_len,
|
| 533 |
+
self.scheduler.config.get("base_image_seq_len", 256),
|
| 534 |
+
self.scheduler.config.get("max_image_seq_len", 4096),
|
| 535 |
+
self.scheduler.config.get("base_shift", 0.5),
|
| 536 |
+
self.scheduler.config.get("max_shift", 1.15),
|
| 537 |
+
)
|
| 538 |
+
self.scheduler.sigma_min = 0.0
|
| 539 |
+
scheduler_kwargs = {"mu": mu}
|
| 540 |
+
timesteps, num_inference_steps = retrieve_timesteps(
|
| 541 |
+
self.scheduler,
|
| 542 |
+
num_inference_steps,
|
| 543 |
+
device,
|
| 544 |
+
sigmas=sigmas,
|
| 545 |
+
**scheduler_kwargs,
|
| 546 |
+
)
|
| 547 |
+
num_warmup_steps = max(len(timesteps) - num_inference_steps * self.scheduler.order, 0)
|
| 548 |
+
self._num_timesteps = len(timesteps)
|
| 549 |
+
|
| 550 |
+
if num_frames_per_prompt > 1:
|
| 551 |
+
latents = torch.stack(
|
| 552 |
+
latents.chunk(num_frames_per_prompt, dim=0), dim=2
|
| 553 |
+
)
|
| 554 |
+
|
| 555 |
+
# 6. Denoising loop
|
| 556 |
+
with self.progress_bar(total=num_inference_steps) as progress_bar:
|
| 557 |
+
for i, t in enumerate(timesteps):
|
| 558 |
+
if self.interrupt:
|
| 559 |
+
continue
|
| 560 |
+
|
| 561 |
+
# broadcast to batch dimension in a way that's compatible with ONNX/Core ML
|
| 562 |
+
timestep = t.expand(latents.shape[0])
|
| 563 |
+
timestep = (1000 - timestep) / 1000
|
| 564 |
+
# Normalized time for time-aware config (0 at start, 1 at end)
|
| 565 |
+
t_norm = timestep[0].item()
|
| 566 |
+
|
| 567 |
+
# Handle cfg truncation
|
| 568 |
+
current_guidance_scale = self.guidance_scale
|
| 569 |
+
if (
|
| 570 |
+
self.do_classifier_free_guidance
|
| 571 |
+
and self._cfg_truncation is not None
|
| 572 |
+
and float(self._cfg_truncation) <= 1
|
| 573 |
+
):
|
| 574 |
+
if t_norm > self._cfg_truncation:
|
| 575 |
+
current_guidance_scale = 0.0
|
| 576 |
+
|
| 577 |
+
# Run CFG only if configured AND scale is non-zero
|
| 578 |
+
apply_cfg = self.do_classifier_free_guidance and current_guidance_scale > 0
|
| 579 |
+
|
| 580 |
+
if apply_cfg:
|
| 581 |
+
latents_typed = latents.to(self.transformer.dtype)
|
| 582 |
+
repeat_dims = (2, 1, 1, 1, 1) if latents_typed.ndim == 5 else (2, 1, 1, 1)
|
| 583 |
+
latent_model_input = latents_typed.repeat(*repeat_dims)
|
| 584 |
+
prompt_embeds_model_input = prompt_embeds + negative_prompt_embeds if prompt_embeds is not None else None
|
| 585 |
+
prompt_embeds_model_input_2 = prompt_embeds_2 + negative_prompt_embeds_2 if prompt_embeds_2 is not None else None
|
| 586 |
+
timestep_model_input = timestep.repeat(2)
|
| 587 |
+
ref_hidden_states_input = ref_hidden_states.repeat(2, 1, 1, 1) if ref_hidden_states is not None else None
|
| 588 |
+
if ref_hidden_states_input is not None:
|
| 589 |
+
ref_hidden_states_input = ref_hidden_states_input.to(latent_model_input.dtype)
|
| 590 |
+
else:
|
| 591 |
+
latent_model_input = latents.to(self.transformer.dtype)
|
| 592 |
+
prompt_embeds_model_input = prompt_embeds
|
| 593 |
+
prompt_embeds_model_input_2 = prompt_embeds_2
|
| 594 |
+
timestep_model_input = timestep
|
| 595 |
+
ref_hidden_states_input = ref_hidden_states*1.0 if ref_hidden_states is not None else None
|
| 596 |
+
if ref_hidden_states_input is not None:
|
| 597 |
+
ref_hidden_states_input = ref_hidden_states_input.to(latent_model_input.dtype)
|
| 598 |
+
|
| 599 |
+
if latent_model_input.ndim == 4:
|
| 600 |
+
latent_model_input = latent_model_input.unsqueeze(2)
|
| 601 |
+
latent_model_input_list = list(latent_model_input.unbind(dim=0))
|
| 602 |
+
|
| 603 |
+
if ref_hidden_states_input is not None:
|
| 604 |
+
C = self.vae.config.latent_channels if 'latent_channels' in self.vae.config else self.vae.config.z_dim
|
| 605 |
+
|
| 606 |
+
# single-image input: [B, C, H, W] -> list of B elems, each [C, 1, H, W]
|
| 607 |
+
if ref_hidden_states_input.shape[1] == C:
|
| 608 |
+
ref_hidden_states_input = ref_hidden_states_input.unsqueeze(2) # [B, C, 1, H, W]
|
| 609 |
+
ref_hidden_states_input = list(ref_hidden_states_input.unbind(dim=0)) # B * [C, 1, H, W]
|
| 610 |
+
|
| 611 |
+
# multi-image input: [B, N*C, H, W] -> list of B elems, each [C, N, H, W]
|
| 612 |
+
else:
|
| 613 |
+
B, total_C, H, W = ref_hidden_states_input.shape
|
| 614 |
+
if total_C % C != 0:
|
| 615 |
+
raise ValueError(
|
| 616 |
+
f"ref_hidden_states_input channel ({total_C}) must be divisible by latent_channels ({C})."
|
| 617 |
+
)
|
| 618 |
+
N = total_C // C
|
| 619 |
+
|
| 620 |
+
# order-preserving: input assumes [img0(C), img1(C), ..., imgN-1(C)] stacked along channels
|
| 621 |
+
ref_hidden_states_input = (
|
| 622 |
+
ref_hidden_states_input.reshape(B, N, C, H, W) # [B, N, C, H, W], N in stacking order
|
| 623 |
+
.permute(0, 2, 1, 3, 4) # [B, C, N, H, W]
|
| 624 |
+
.contiguous()
|
| 625 |
+
)
|
| 626 |
+
ref_hidden_states_input = list(ref_hidden_states_input.unbind(dim=0)) # B * [C, N, H, W]
|
| 627 |
+
|
| 628 |
+
model_out_list = self.transformer(
|
| 629 |
+
latent_model_input_list,
|
| 630 |
+
timestep_model_input,
|
| 631 |
+
prompt_embeds_model_input,
|
| 632 |
+
ref_hidden_states=ref_hidden_states_input,
|
| 633 |
+
return_dict=False,
|
| 634 |
+
encoder_hidden_states_2=prompt_embeds_model_input_2,
|
| 635 |
+
)[0]
|
| 636 |
+
model_out_list = [
|
| 637 |
+
output[:, :num_frames_per_prompt, :, :].float()
|
| 638 |
+
for output in model_out_list
|
| 639 |
+
]
|
| 640 |
+
|
| 641 |
+
if apply_cfg:
|
| 642 |
+
# Perform CFG
|
| 643 |
+
pos_out = model_out_list[:actual_batch_size]
|
| 644 |
+
neg_out = model_out_list[actual_batch_size:]
|
| 645 |
+
|
| 646 |
+
noise_pred = []
|
| 647 |
+
for j in range(actual_batch_size):
|
| 648 |
+
pos = pos_out[j].float()
|
| 649 |
+
neg = neg_out[j].float()
|
| 650 |
+
|
| 651 |
+
pred = pos + current_guidance_scale * (pos - neg)
|
| 652 |
+
|
| 653 |
+
# Renormalization
|
| 654 |
+
if self._cfg_normalization and float(self._cfg_normalization) > 0.0:
|
| 655 |
+
ori_pos_norm = torch.linalg.vector_norm(pos)
|
| 656 |
+
new_pos_norm = torch.linalg.vector_norm(pred)
|
| 657 |
+
max_new_norm = ori_pos_norm * float(self._cfg_normalization)
|
| 658 |
+
if new_pos_norm > max_new_norm:
|
| 659 |
+
pred = pred * (max_new_norm / new_pos_norm)
|
| 660 |
+
|
| 661 |
+
noise_pred.append(pred)
|
| 662 |
+
|
| 663 |
+
noise_pred = torch.stack(noise_pred, dim=0)
|
| 664 |
+
else:
|
| 665 |
+
noise_pred = torch.stack([t.float() for t in model_out_list], dim=0)
|
| 666 |
+
|
| 667 |
+
if num_frames_per_prompt == 1:
|
| 668 |
+
noise_pred = noise_pred.squeeze(2)
|
| 669 |
+
noise_pred = -noise_pred
|
| 670 |
+
|
| 671 |
+
# compute the previous noisy sample x_t -> x_t-1
|
| 672 |
+
latents = self.scheduler.step(noise_pred.to(torch.float32), t, latents, return_dict=False)[0]
|
| 673 |
+
assert latents.dtype == torch.float32
|
| 674 |
+
|
| 675 |
+
if callback_on_step_end is not None:
|
| 676 |
+
callback_kwargs = {}
|
| 677 |
+
for k in callback_on_step_end_tensor_inputs:
|
| 678 |
+
callback_kwargs[k] = locals()[k]
|
| 679 |
+
callback_outputs = callback_on_step_end(self, i, t, callback_kwargs)
|
| 680 |
+
|
| 681 |
+
latents = callback_outputs.pop("latents", latents)
|
| 682 |
+
prompt_embeds = callback_outputs.pop("prompt_embeds", prompt_embeds)
|
| 683 |
+
negative_prompt_embeds = callback_outputs.pop("negative_prompt_embeds", negative_prompt_embeds)
|
| 684 |
+
|
| 685 |
+
# call the callback, if provided
|
| 686 |
+
if i == len(timesteps) - 1 or ((i + 1) > num_warmup_steps and (i + 1) % self.scheduler.order == 0):
|
| 687 |
+
progress_bar.update()
|
| 688 |
+
|
| 689 |
+
if num_frames_per_prompt > 1:
|
| 690 |
+
latents = torch.cat(
|
| 691 |
+
latents.chunk(num_frames_per_prompt, dim=2), dim=0
|
| 692 |
+
).squeeze(2)
|
| 693 |
+
|
| 694 |
+
if output_type == "latent":
|
| 695 |
+
image = latents
|
| 696 |
+
|
| 697 |
+
else:
|
| 698 |
+
latents = latents.to(self.vae.dtype)
|
| 699 |
+
if 'temperal_downsample' in self.vae.config:
|
| 700 |
+
latents = latents.unsqueeze(2)
|
| 701 |
+
|
| 702 |
+
latents = (latents / self.vae.config.scaling_factor) + self.vae.config.shift_factor
|
| 703 |
+
|
| 704 |
+
image = self.vae.decode(latents, return_dict=False)[0]
|
| 705 |
+
if image.dim() == 5:
|
| 706 |
+
image = image.squeeze(2)
|
| 707 |
+
|
| 708 |
+
image = self.image_processor.postprocess(image, output_type=output_type)
|
| 709 |
+
|
| 710 |
+
# Offload all models
|
| 711 |
+
self.maybe_free_model_hooks()
|
| 712 |
+
|
| 713 |
+
if not return_dict:
|
| 714 |
+
return (image,)
|
| 715 |
+
|
| 716 |
+
return ImageGenerationOutput(images=image)
|
code/diffusion/transformer.py
ADDED
|
@@ -0,0 +1,768 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright (c) Ant Group. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
import math
|
| 16 |
+
from typing import List, Optional, Tuple
|
| 17 |
+
|
| 18 |
+
import torch
|
| 19 |
+
import torch.nn as nn
|
| 20 |
+
import torch.nn.functional as F
|
| 21 |
+
from torch.nn.utils.rnn import pad_sequence
|
| 22 |
+
|
| 23 |
+
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
| 24 |
+
from diffusers.loaders import FromOriginalModelMixin, PeftAdapterMixin
|
| 25 |
+
from diffusers.models.attention_processor import Attention
|
| 26 |
+
from diffusers.models.modeling_utils import ModelMixin
|
| 27 |
+
from diffusers.models.normalization import RMSNorm
|
| 28 |
+
from diffusers.utils.torch_utils import maybe_allow_in_graph
|
| 29 |
+
from diffusers.models.attention_dispatch import dispatch_attention_fn
|
| 30 |
+
from diffusers.models.modeling_outputs import Transformer2DModelOutput
|
| 31 |
+
|
| 32 |
+
from inference_profile import LEARNED_PADDING, VALID_PADDING_MODES, ZERO_MASKED_PADDING
|
| 33 |
+
from .padding import mask_out_alignment_padding
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
ADALN_EMBED_DIM = 256
|
| 37 |
+
SEQ_MULTI_OF = 32
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
def _native_sdpa_is_active(processor) -> bool:
|
| 41 |
+
"""True when attention would go to diffusers' default native SDPA backend (no per-model backend,
|
| 42 |
+
no context parallelism, and the active global backend is NATIVE)."""
|
| 43 |
+
if processor._attention_backend is not None or processor._parallel_config is not None:
|
| 44 |
+
return False
|
| 45 |
+
try:
|
| 46 |
+
from diffusers.models.attention_dispatch import AttentionBackendName, _AttentionBackendRegistry
|
| 47 |
+
|
| 48 |
+
name, _ = _AttentionBackendRegistry.get_active_backend()
|
| 49 |
+
return name == AttentionBackendName.NATIVE
|
| 50 |
+
except Exception:
|
| 51 |
+
return False
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
class TimestepEmbedder(nn.Module):
|
| 55 |
+
def __init__(self, out_size, mid_size=None, frequency_embedding_size=256):
|
| 56 |
+
super().__init__()
|
| 57 |
+
if mid_size is None:
|
| 58 |
+
mid_size = out_size
|
| 59 |
+
self.mlp = nn.Sequential(
|
| 60 |
+
nn.Linear(frequency_embedding_size, mid_size, bias=True),
|
| 61 |
+
nn.SiLU(),
|
| 62 |
+
nn.Linear(mid_size, out_size, bias=True),
|
| 63 |
+
)
|
| 64 |
+
|
| 65 |
+
self.frequency_embedding_size = frequency_embedding_size
|
| 66 |
+
|
| 67 |
+
@staticmethod
|
| 68 |
+
def timestep_embedding(t, dim, max_period=10000):
|
| 69 |
+
with torch.amp.autocast("cuda", enabled=False):
|
| 70 |
+
half = dim // 2
|
| 71 |
+
freqs = torch.exp(
|
| 72 |
+
-math.log(max_period) * torch.arange(start=0, end=half, dtype=torch.float32, device=t.device) / half
|
| 73 |
+
)
|
| 74 |
+
args = t[:, None].float() * freqs[None]
|
| 75 |
+
embedding = torch.cat([torch.cos(args), torch.sin(args)], dim=-1)
|
| 76 |
+
if dim % 2:
|
| 77 |
+
embedding = torch.cat([embedding, torch.zeros_like(embedding[:, :1])], dim=-1)
|
| 78 |
+
return embedding
|
| 79 |
+
|
| 80 |
+
def forward(self, t):
|
| 81 |
+
t_freq = self.timestep_embedding(t, self.frequency_embedding_size)
|
| 82 |
+
weight_dtype = self.mlp[0].weight.dtype
|
| 83 |
+
if weight_dtype.is_floating_point:
|
| 84 |
+
t_freq = t_freq.to(weight_dtype)
|
| 85 |
+
t_emb = self.mlp(t_freq)
|
| 86 |
+
return t_emb
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
class SingleStreamAttentionProcessor:
|
| 90 |
+
"""
|
| 91 |
+
Processor for single-stream (joint text-image) attention; adapts the
|
| 92 |
+
existing Attention class to the single-stream behavior.
|
| 93 |
+
"""
|
| 94 |
+
|
| 95 |
+
_attention_backend = None
|
| 96 |
+
_parallel_config = None
|
| 97 |
+
|
| 98 |
+
def __init__(self):
|
| 99 |
+
if not hasattr(F, "scaled_dot_product_attention"):
|
| 100 |
+
raise ImportError(
|
| 101 |
+
"SingleStreamAttentionProcessor requires PyTorch 2.0. To use it, please upgrade PyTorch to version 2.0 or higher."
|
| 102 |
+
)
|
| 103 |
+
|
| 104 |
+
def __call__(
|
| 105 |
+
self,
|
| 106 |
+
attn: Attention,
|
| 107 |
+
hidden_states: torch.Tensor,
|
| 108 |
+
encoder_hidden_states: Optional[torch.Tensor] = None,
|
| 109 |
+
attention_mask: Optional[torch.Tensor] = None,
|
| 110 |
+
freqs_cis: Optional[torch.Tensor] = None,
|
| 111 |
+
) -> torch.Tensor:
|
| 112 |
+
query = attn.to_q(hidden_states)
|
| 113 |
+
key = attn.to_k(hidden_states)
|
| 114 |
+
value = attn.to_v(hidden_states)
|
| 115 |
+
|
| 116 |
+
query = query.unflatten(-1, (attn.heads, -1))
|
| 117 |
+
key = key.unflatten(-1, (attn.heads, -1))
|
| 118 |
+
value = value.unflatten(-1, (attn.heads, -1))
|
| 119 |
+
|
| 120 |
+
# Apply Norms
|
| 121 |
+
if attn.norm_q is not None:
|
| 122 |
+
query = attn.norm_q(query)
|
| 123 |
+
if attn.norm_k is not None:
|
| 124 |
+
key = attn.norm_k(key)
|
| 125 |
+
|
| 126 |
+
# Apply RoPE
|
| 127 |
+
def apply_rotary_emb(x_in: torch.Tensor, freqs_cis: torch.Tensor) -> torch.Tensor:
|
| 128 |
+
with torch.amp.autocast("cuda", enabled=False):
|
| 129 |
+
x = torch.view_as_complex(x_in.float().reshape(*x_in.shape[:-1], -1, 2))
|
| 130 |
+
freqs_cis = freqs_cis.unsqueeze(2)
|
| 131 |
+
x_out = torch.view_as_real(x * freqs_cis).flatten(3)
|
| 132 |
+
return x_out.type_as(x_in) # todo
|
| 133 |
+
|
| 134 |
+
if freqs_cis is not None:
|
| 135 |
+
query = apply_rotary_emb(query, freqs_cis)
|
| 136 |
+
key = apply_rotary_emb(key, freqs_cis)
|
| 137 |
+
|
| 138 |
+
# Cast to correct dtype
|
| 139 |
+
dtype = query.dtype
|
| 140 |
+
query, key = query.to(dtype), key.to(dtype)
|
| 141 |
+
|
| 142 |
+
# From [batch, seq_len] to [batch, 1, 1, seq_len] -> broadcast to [batch, heads, seq_len, seq_len]
|
| 143 |
+
if attention_mask is not None and attention_mask.ndim == 2:
|
| 144 |
+
attention_mask = attention_mask[:, None, None, :]
|
| 145 |
+
|
| 146 |
+
# Compute joint attention
|
| 147 |
+
if _native_sdpa_is_active(self):
|
| 148 |
+
# What diffusers' default "native" backend computes, but SDPA receives contiguous
|
| 149 |
+
# [B, H, L, D] tensors instead of permuted views. PyTorch's math SDPA (the only SDPA
|
| 150 |
+
# kernel that runs on ROCm gfx1151) is ~2x faster on contiguous inputs, with
|
| 151 |
+
# bit-identical output.
|
| 152 |
+
q, k, v = (x.transpose(1, 2).contiguous() for x in (query, key, value))
|
| 153 |
+
hidden_states = F.scaled_dot_product_attention(
|
| 154 |
+
q, k, v, attn_mask=attention_mask, dropout_p=0.0, is_causal=False
|
| 155 |
+
).transpose(1, 2)
|
| 156 |
+
else:
|
| 157 |
+
hidden_states = dispatch_attention_fn(
|
| 158 |
+
query,
|
| 159 |
+
key,
|
| 160 |
+
value,
|
| 161 |
+
attn_mask=attention_mask,
|
| 162 |
+
dropout_p=0.0,
|
| 163 |
+
is_causal=False,
|
| 164 |
+
backend=self._attention_backend,
|
| 165 |
+
parallel_config=self._parallel_config,
|
| 166 |
+
)
|
| 167 |
+
|
| 168 |
+
# Reshape back
|
| 169 |
+
hidden_states = hidden_states.flatten(2, 3)
|
| 170 |
+
hidden_states = hidden_states.to(dtype)
|
| 171 |
+
|
| 172 |
+
output = attn.to_out[0](hidden_states)
|
| 173 |
+
if len(attn.to_out) > 1: # dropout
|
| 174 |
+
output = attn.to_out[1](output)
|
| 175 |
+
|
| 176 |
+
return output
|
| 177 |
+
|
| 178 |
+
|
| 179 |
+
class FeedForward(nn.Module):
|
| 180 |
+
def __init__(self, dim: int, hidden_dim: int):
|
| 181 |
+
super().__init__()
|
| 182 |
+
self.w1 = nn.Linear(dim, hidden_dim, bias=False)
|
| 183 |
+
self.w2 = nn.Linear(hidden_dim, dim, bias=False)
|
| 184 |
+
self.w3 = nn.Linear(dim, hidden_dim, bias=False)
|
| 185 |
+
|
| 186 |
+
def _forward_silu_gating(self, x1, x3):
|
| 187 |
+
return F.silu(x1) * x3
|
| 188 |
+
|
| 189 |
+
def forward(self, x):
|
| 190 |
+
return self.w2(self._forward_silu_gating(self.w1(x), self.w3(x)))
|
| 191 |
+
|
| 192 |
+
|
| 193 |
+
@maybe_allow_in_graph
|
| 194 |
+
class TransformerBlock(nn.Module):
|
| 195 |
+
def __init__(
|
| 196 |
+
self,
|
| 197 |
+
layer_id: int,
|
| 198 |
+
dim: int,
|
| 199 |
+
n_heads: int,
|
| 200 |
+
n_kv_heads: int,
|
| 201 |
+
norm_eps: float,
|
| 202 |
+
qk_norm: bool,
|
| 203 |
+
modulation=True,
|
| 204 |
+
):
|
| 205 |
+
super().__init__()
|
| 206 |
+
self.dim = dim
|
| 207 |
+
self.head_dim = dim // n_heads
|
| 208 |
+
|
| 209 |
+
# Refactored to use diffusers Attention with custom processor
|
| 210 |
+
# Upstream parameter order: dim, n_heads, n_kv_heads, qk_norm
|
| 211 |
+
self.attention = Attention(
|
| 212 |
+
query_dim=dim,
|
| 213 |
+
cross_attention_dim=None,
|
| 214 |
+
dim_head=dim // n_heads,
|
| 215 |
+
heads=n_heads,
|
| 216 |
+
qk_norm="rms_norm" if qk_norm else None,
|
| 217 |
+
eps=1e-5,
|
| 218 |
+
bias=False,
|
| 219 |
+
out_bias=False,
|
| 220 |
+
processor=SingleStreamAttentionProcessor(),
|
| 221 |
+
)
|
| 222 |
+
|
| 223 |
+
self.feed_forward = FeedForward(dim=dim, hidden_dim=int(dim / 3 * 8))
|
| 224 |
+
self.layer_id = layer_id
|
| 225 |
+
|
| 226 |
+
self.attention_norm1 = RMSNorm(dim, eps=norm_eps)
|
| 227 |
+
self.ffn_norm1 = RMSNorm(dim, eps=norm_eps)
|
| 228 |
+
|
| 229 |
+
self.attention_norm2 = RMSNorm(dim, eps=norm_eps)
|
| 230 |
+
self.ffn_norm2 = RMSNorm(dim, eps=norm_eps)
|
| 231 |
+
|
| 232 |
+
self.modulation = modulation
|
| 233 |
+
if modulation:
|
| 234 |
+
self.adaLN_modulation = nn.Sequential(nn.Linear(min(dim, ADALN_EMBED_DIM), 4 * dim, bias=True))
|
| 235 |
+
|
| 236 |
+
def forward(
|
| 237 |
+
self,
|
| 238 |
+
x: torch.Tensor,
|
| 239 |
+
attn_mask: torch.Tensor,
|
| 240 |
+
freqs_cis: torch.Tensor,
|
| 241 |
+
adaln_input: Optional[torch.Tensor] = None,
|
| 242 |
+
):
|
| 243 |
+
if self.modulation:
|
| 244 |
+
assert adaln_input is not None
|
| 245 |
+
scale_msa, gate_msa, scale_mlp, gate_mlp = self.adaLN_modulation(adaln_input).unsqueeze(1).chunk(4, dim=2)
|
| 246 |
+
gate_msa, gate_mlp = gate_msa.tanh(), gate_mlp.tanh()
|
| 247 |
+
scale_msa, scale_mlp = 1.0 + scale_msa, 1.0 + scale_mlp
|
| 248 |
+
|
| 249 |
+
# Attention block
|
| 250 |
+
attn_out = self.attention(
|
| 251 |
+
self.attention_norm1(x) * scale_msa, attention_mask=attn_mask, freqs_cis=freqs_cis
|
| 252 |
+
)
|
| 253 |
+
x = x + gate_msa * self.attention_norm2(attn_out)
|
| 254 |
+
|
| 255 |
+
# FFN block
|
| 256 |
+
x = x + gate_mlp * self.ffn_norm2(self.feed_forward(self.ffn_norm1(x) * scale_mlp))
|
| 257 |
+
else:
|
| 258 |
+
# Attention block
|
| 259 |
+
attn_out = self.attention(self.attention_norm1(x), attention_mask=attn_mask, freqs_cis=freqs_cis)
|
| 260 |
+
x = x + self.attention_norm2(attn_out)
|
| 261 |
+
|
| 262 |
+
# FFN block
|
| 263 |
+
x = x + self.ffn_norm2(self.feed_forward(self.ffn_norm1(x)))
|
| 264 |
+
|
| 265 |
+
return x
|
| 266 |
+
|
| 267 |
+
|
| 268 |
+
class FinalLayer(nn.Module):
|
| 269 |
+
def __init__(self, hidden_size, out_channels):
|
| 270 |
+
super().__init__()
|
| 271 |
+
self.norm_final = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
| 272 |
+
self.linear = nn.Linear(hidden_size, out_channels, bias=True)
|
| 273 |
+
|
| 274 |
+
self.adaLN_modulation = nn.Sequential(
|
| 275 |
+
nn.SiLU(),
|
| 276 |
+
nn.Linear(min(hidden_size, ADALN_EMBED_DIM), hidden_size, bias=True),
|
| 277 |
+
)
|
| 278 |
+
|
| 279 |
+
def forward(self, x, c):
|
| 280 |
+
scale = 1.0 + self.adaLN_modulation(c)
|
| 281 |
+
x = self.norm_final(x) * scale.unsqueeze(1)
|
| 282 |
+
x = self.linear(x)
|
| 283 |
+
return x
|
| 284 |
+
|
| 285 |
+
|
| 286 |
+
class RopeEmbedder:
|
| 287 |
+
def __init__(
|
| 288 |
+
self,
|
| 289 |
+
theta: float = 256.0,
|
| 290 |
+
axes_dims: List[int] = (16, 56, 56),
|
| 291 |
+
axes_lens: List[int] = (64, 128, 128),
|
| 292 |
+
):
|
| 293 |
+
self.theta = theta
|
| 294 |
+
self.axes_dims = axes_dims
|
| 295 |
+
self.axes_lens = axes_lens
|
| 296 |
+
assert len(axes_dims) == len(axes_lens), "axes_dims and axes_lens must have the same length"
|
| 297 |
+
self.freqs_cis = None
|
| 298 |
+
|
| 299 |
+
@staticmethod
|
| 300 |
+
def precompute_freqs_cis(dim: List[int], end: List[int], theta: float = 256.0):
|
| 301 |
+
with torch.device("cpu"):
|
| 302 |
+
freqs_cis = []
|
| 303 |
+
for i, (d, e) in enumerate(zip(dim, end)):
|
| 304 |
+
freqs = 1.0 / (theta ** (torch.arange(0, d, 2, dtype=torch.float64, device="cpu") / d))
|
| 305 |
+
timestep = torch.arange(e, device=freqs.device, dtype=torch.float64)
|
| 306 |
+
freqs = torch.outer(timestep, freqs).float()
|
| 307 |
+
freqs_cis_i = torch.polar(torch.ones_like(freqs), freqs).to(torch.complex64) # complex64
|
| 308 |
+
freqs_cis.append(freqs_cis_i)
|
| 309 |
+
|
| 310 |
+
return freqs_cis
|
| 311 |
+
|
| 312 |
+
def __call__(self, ids: torch.Tensor):
|
| 313 |
+
assert ids.ndim == 2
|
| 314 |
+
assert ids.shape[-1] == len(self.axes_dims)
|
| 315 |
+
device = ids.device
|
| 316 |
+
|
| 317 |
+
if self.freqs_cis is None:
|
| 318 |
+
self.freqs_cis = self.precompute_freqs_cis(self.axes_dims, self.axes_lens, theta=self.theta)
|
| 319 |
+
self.freqs_cis = [freqs_cis.to(device) for freqs_cis in self.freqs_cis]
|
| 320 |
+
else:
|
| 321 |
+
# Ensure freqs_cis are on the same device as ids
|
| 322 |
+
if self.freqs_cis[0].device != device:
|
| 323 |
+
self.freqs_cis = [freqs_cis.to(device) for freqs_cis in self.freqs_cis]
|
| 324 |
+
|
| 325 |
+
result = []
|
| 326 |
+
for i in range(len(self.axes_dims)):
|
| 327 |
+
index = ids[:, i]
|
| 328 |
+
result.append(self.freqs_cis[i][index])
|
| 329 |
+
return torch.cat(result, dim=-1)
|
| 330 |
+
|
| 331 |
+
|
| 332 |
+
class DiffusionTransformer(ModelMixin, ConfigMixin, PeftAdapterMixin, FromOriginalModelMixin):
|
| 333 |
+
_supports_gradient_checkpointing = True
|
| 334 |
+
_no_split_modules = ["TransformerBlock"]
|
| 335 |
+
_repeated_blocks = ["TransformerBlock"]
|
| 336 |
+
_skip_layerwise_casting_patterns = ["t_embedder", "cap_embedder"] # precision sensitive layers
|
| 337 |
+
|
| 338 |
+
@register_to_config
|
| 339 |
+
def __init__(
|
| 340 |
+
self,
|
| 341 |
+
all_patch_size=(2,),
|
| 342 |
+
all_f_patch_size=(1,),
|
| 343 |
+
in_channels=16,
|
| 344 |
+
dim=3840,
|
| 345 |
+
n_layers=30,
|
| 346 |
+
n_refiner_layers=2,
|
| 347 |
+
n_heads=30,
|
| 348 |
+
n_kv_heads=30,
|
| 349 |
+
norm_eps=1e-5,
|
| 350 |
+
qk_norm=True,
|
| 351 |
+
cap_feat_dim=2560,
|
| 352 |
+
rope_theta=256.0,
|
| 353 |
+
t_scale=1000.0,
|
| 354 |
+
axes_dims=[32, 48, 48],
|
| 355 |
+
axes_lens=[20480, 512, 512],
|
| 356 |
+
alignment_padding_mode=None,
|
| 357 |
+
multi_frame_output=None,
|
| 358 |
+
) -> None:
|
| 359 |
+
super().__init__()
|
| 360 |
+
if alignment_padding_mode not in VALID_PADDING_MODES:
|
| 361 |
+
raise ValueError(
|
| 362 |
+
"alignment_padding_mode must come from the checkpoint capability "
|
| 363 |
+
"contract (transformer/config.json, or the legacy "
|
| 364 |
+
f"inference_profile.json) and be one of "
|
| 365 |
+
f"{sorted(VALID_PADDING_MODES)}, got {alignment_padding_mode!r}"
|
| 366 |
+
)
|
| 367 |
+
if type(multi_frame_output) is not bool:
|
| 368 |
+
raise ValueError(
|
| 369 |
+
"multi_frame_output must come from the checkpoint capability "
|
| 370 |
+
"contract (transformer/config.json, or the legacy "
|
| 371 |
+
"inference_profile.json) as a boolean"
|
| 372 |
+
)
|
| 373 |
+
self.in_channels = in_channels
|
| 374 |
+
self.out_channels = in_channels
|
| 375 |
+
self.all_patch_size = all_patch_size
|
| 376 |
+
self.all_f_patch_size = all_f_patch_size
|
| 377 |
+
self.dim = dim
|
| 378 |
+
self.n_heads = n_heads
|
| 379 |
+
self.alignment_padding_mode = alignment_padding_mode
|
| 380 |
+
self.multi_frame_output = multi_frame_output
|
| 381 |
+
|
| 382 |
+
self.rope_theta = rope_theta
|
| 383 |
+
self.t_scale = t_scale
|
| 384 |
+
self.gradient_checkpointing = False
|
| 385 |
+
|
| 386 |
+
assert len(all_patch_size) == len(all_f_patch_size)
|
| 387 |
+
|
| 388 |
+
all_x_embedder = {}
|
| 389 |
+
all_final_layer = {}
|
| 390 |
+
for patch_idx, (patch_size, f_patch_size) in enumerate(zip(all_patch_size, all_f_patch_size)):
|
| 391 |
+
x_embedder = nn.Linear(f_patch_size * patch_size * patch_size * in_channels, dim, bias=True)
|
| 392 |
+
all_x_embedder[f"{patch_size}-{f_patch_size}"] = x_embedder
|
| 393 |
+
|
| 394 |
+
final_layer = FinalLayer(dim, patch_size * patch_size * f_patch_size * self.out_channels)
|
| 395 |
+
all_final_layer[f"{patch_size}-{f_patch_size}"] = final_layer
|
| 396 |
+
|
| 397 |
+
self.all_x_embedder = nn.ModuleDict(all_x_embedder)
|
| 398 |
+
self.all_final_layer = nn.ModuleDict(all_final_layer)
|
| 399 |
+
self.noise_refiner = nn.ModuleList(
|
| 400 |
+
[
|
| 401 |
+
TransformerBlock(
|
| 402 |
+
1000 + layer_id,
|
| 403 |
+
dim,
|
| 404 |
+
n_heads,
|
| 405 |
+
n_kv_heads,
|
| 406 |
+
norm_eps,
|
| 407 |
+
qk_norm,
|
| 408 |
+
modulation=True,
|
| 409 |
+
)
|
| 410 |
+
for layer_id in range(n_refiner_layers)
|
| 411 |
+
]
|
| 412 |
+
)
|
| 413 |
+
self.context_refiner = nn.ModuleList(
|
| 414 |
+
[
|
| 415 |
+
TransformerBlock(
|
| 416 |
+
layer_id,
|
| 417 |
+
dim,
|
| 418 |
+
n_heads,
|
| 419 |
+
n_kv_heads,
|
| 420 |
+
norm_eps,
|
| 421 |
+
qk_norm,
|
| 422 |
+
modulation=False,
|
| 423 |
+
)
|
| 424 |
+
for layer_id in range(n_refiner_layers)
|
| 425 |
+
]
|
| 426 |
+
)
|
| 427 |
+
self.t_embedder = TimestepEmbedder(min(dim, ADALN_EMBED_DIM), mid_size=1024)
|
| 428 |
+
self.cap_embedder = nn.Sequential(RMSNorm(cap_feat_dim, eps=norm_eps), nn.Linear(cap_feat_dim, dim, bias=True))
|
| 429 |
+
|
| 430 |
+
if self.alignment_padding_mode == LEARNED_PADDING:
|
| 431 |
+
self.x_pad_token = nn.Parameter(torch.empty((1, dim)))
|
| 432 |
+
self.cap_pad_token = nn.Parameter(torch.empty((1, dim)))
|
| 433 |
+
else:
|
| 434 |
+
self.register_parameter("x_pad_token", None)
|
| 435 |
+
self.register_parameter("cap_pad_token", None)
|
| 436 |
+
|
| 437 |
+
self.layers = nn.ModuleList(
|
| 438 |
+
[
|
| 439 |
+
TransformerBlock(layer_id, dim, n_heads, n_kv_heads, norm_eps, qk_norm)
|
| 440 |
+
for layer_id in range(n_layers)
|
| 441 |
+
]
|
| 442 |
+
)
|
| 443 |
+
head_dim = dim // n_heads
|
| 444 |
+
assert head_dim == sum(axes_dims)
|
| 445 |
+
self.axes_dims = axes_dims
|
| 446 |
+
self.axes_lens = axes_lens
|
| 447 |
+
|
| 448 |
+
self.rope_embedder = RopeEmbedder(theta=rope_theta, axes_dims=axes_dims, axes_lens=axes_lens)
|
| 449 |
+
|
| 450 |
+
def unpatchify(self, x: List[torch.Tensor], size: List[Tuple], patch_size, f_patch_size) -> List[torch.Tensor]:
|
| 451 |
+
pH = pW = patch_size
|
| 452 |
+
pF = f_patch_size
|
| 453 |
+
bsz = len(x)
|
| 454 |
+
assert len(size) == bsz
|
| 455 |
+
for i in range(bsz):
|
| 456 |
+
F, H, W = size[i]
|
| 457 |
+
ori_len = (F // pF) * (H // pH) * (W // pW)
|
| 458 |
+
# "f h w pf ph pw c -> c (f pf) (h ph) (w pw)"
|
| 459 |
+
x[i] = (
|
| 460 |
+
x[i][:ori_len]
|
| 461 |
+
.view(F // pF, H // pH, W // pW, pF, pH, pW, self.out_channels)
|
| 462 |
+
.permute(6, 0, 3, 1, 4, 2, 5)
|
| 463 |
+
.reshape(self.out_channels, F, H, W)
|
| 464 |
+
)
|
| 465 |
+
if not self.multi_frame_output:
|
| 466 |
+
x[i] = x[i][:, :1, :, :]
|
| 467 |
+
return x
|
| 468 |
+
|
| 469 |
+
@staticmethod
|
| 470 |
+
def create_coordinate_grid(size, start=None, device=None):
|
| 471 |
+
if start is None:
|
| 472 |
+
start = (0 for _ in size)
|
| 473 |
+
|
| 474 |
+
axes = [torch.arange(x0, x0 + span, dtype=torch.int32, device=device) for x0, span in zip(start, size)]
|
| 475 |
+
grids = torch.meshgrid(axes, indexing="ij")
|
| 476 |
+
return torch.stack(grids, dim=-1)
|
| 477 |
+
|
| 478 |
+
def patchify_and_embed(
|
| 479 |
+
self,
|
| 480 |
+
all_image: List[torch.Tensor],
|
| 481 |
+
all_cap_feats: List[torch.Tensor],
|
| 482 |
+
patch_size: int,
|
| 483 |
+
f_patch_size: int,
|
| 484 |
+
all_image_ref: List[torch.Tensor] = None,
|
| 485 |
+
all_cap_feats_2: List[torch.Tensor] = None,
|
| 486 |
+
):
|
| 487 |
+
pH = pW = patch_size
|
| 488 |
+
pF = f_patch_size
|
| 489 |
+
device = all_image[0].device
|
| 490 |
+
|
| 491 |
+
all_image_out = []
|
| 492 |
+
all_image_size = []
|
| 493 |
+
all_image_pos_ids = []
|
| 494 |
+
all_image_pad_mask = []
|
| 495 |
+
all_cap_pos_ids = []
|
| 496 |
+
all_cap_pad_mask = []
|
| 497 |
+
all_cap_feats_out = []
|
| 498 |
+
all_cap_feats_2_out = []
|
| 499 |
+
|
| 500 |
+
if all_image_ref is None:
|
| 501 |
+
all_image_ref = [None]*len(all_image)
|
| 502 |
+
|
| 503 |
+
assert all_cap_feats is not None or all_cap_feats_2 is not None
|
| 504 |
+
|
| 505 |
+
if all_cap_feats is None:
|
| 506 |
+
all_cap_feats = [None for _ in range(len(all_image))]
|
| 507 |
+
else:
|
| 508 |
+
assert not any([i is None for i in all_cap_feats])
|
| 509 |
+
|
| 510 |
+
if all_cap_feats_2 is None:
|
| 511 |
+
all_cap_feats_2 = [None for _ in range(len(all_image))]
|
| 512 |
+
else:
|
| 513 |
+
assert not any([i is None for i in all_cap_feats_2])
|
| 514 |
+
|
| 515 |
+
for i, (image, cap_feat, cap_feat_2, image_ref) in enumerate(zip(all_image, all_cap_feats, all_cap_feats_2, all_image_ref)):
|
| 516 |
+
### Process Caption
|
| 517 |
+
cap_ori_len = 0
|
| 518 |
+
if cap_feat is not None:
|
| 519 |
+
cap_ori_len += len(cap_feat)
|
| 520 |
+
|
| 521 |
+
if cap_feat_2 is not None:
|
| 522 |
+
cap_ori_len += len(cap_feat_2)
|
| 523 |
+
|
| 524 |
+
cap_padding_len = (-cap_ori_len) % SEQ_MULTI_OF
|
| 525 |
+
# padded position ids
|
| 526 |
+
cap_padded_pos_ids = self.create_coordinate_grid(
|
| 527 |
+
size=(cap_ori_len + cap_padding_len, 1, 1),
|
| 528 |
+
start=(1, 0, 0),
|
| 529 |
+
device=device,
|
| 530 |
+
).flatten(0, 2)
|
| 531 |
+
all_cap_pos_ids.append(cap_padded_pos_ids)
|
| 532 |
+
# pad mask
|
| 533 |
+
cap_pad_mask = torch.cat(
|
| 534 |
+
[
|
| 535 |
+
torch.zeros((cap_ori_len,), dtype=torch.bool, device=device),
|
| 536 |
+
torch.ones((cap_padding_len,), dtype=torch.bool, device=device),
|
| 537 |
+
],
|
| 538 |
+
dim=0,
|
| 539 |
+
)
|
| 540 |
+
all_cap_pad_mask.append(
|
| 541 |
+
cap_pad_mask if cap_padding_len > 0 else torch.zeros((cap_ori_len,), dtype=torch.bool, device=device)
|
| 542 |
+
)
|
| 543 |
+
|
| 544 |
+
if cap_feat_2 is not None:
|
| 545 |
+
if cap_feat is not None:
|
| 546 |
+
all_cap_feats_out.append(cap_feat)
|
| 547 |
+
cap_padded_feat = torch.cat([cap_feat_2, (cap_feat_2[-1:] * 0).repeat(cap_padding_len, 1)], dim=0)
|
| 548 |
+
all_cap_feats_2_out.append(cap_padded_feat)
|
| 549 |
+
else:
|
| 550 |
+
cap_padded_feat = torch.cat([cap_feat, cap_feat[-1:].repeat(cap_padding_len, 1)], dim=0)
|
| 551 |
+
all_cap_feats_out.append(cap_padded_feat)
|
| 552 |
+
|
| 553 |
+
### Process Image
|
| 554 |
+
if image_ref is not None:
|
| 555 |
+
image = torch.cat([image, image_ref], dim=1)
|
| 556 |
+
|
| 557 |
+
C, F, H, W = image.size()
|
| 558 |
+
all_image_size.append((F, H, W))
|
| 559 |
+
F_tokens, H_tokens, W_tokens = F // pF, H // pH, W // pW
|
| 560 |
+
|
| 561 |
+
image = image.view(C, F_tokens, pF, H_tokens, pH, W_tokens, pW)
|
| 562 |
+
# "c f pf h ph w pw -> (f h w) (pf ph pw c)"
|
| 563 |
+
image = image.permute(1, 3, 5, 2, 4, 6, 0).reshape(F_tokens * H_tokens * W_tokens, pF * pH * pW * C)
|
| 564 |
+
|
| 565 |
+
image_ori_len = len(image)
|
| 566 |
+
image_padding_len = (-image_ori_len) % SEQ_MULTI_OF
|
| 567 |
+
|
| 568 |
+
image_ori_pos_ids = self.create_coordinate_grid(
|
| 569 |
+
size=(F_tokens, H_tokens, W_tokens),
|
| 570 |
+
start=(cap_ori_len + cap_padding_len + 1, 0, 0),
|
| 571 |
+
device=device,
|
| 572 |
+
).flatten(0, 2)
|
| 573 |
+
image_padded_pos_ids = torch.cat(
|
| 574 |
+
[
|
| 575 |
+
image_ori_pos_ids,
|
| 576 |
+
self.create_coordinate_grid(size=(1, 1, 1), start=(0, 0, 0), device=device)
|
| 577 |
+
.flatten(0, 2)
|
| 578 |
+
.repeat(image_padding_len, 1),
|
| 579 |
+
],
|
| 580 |
+
dim=0,
|
| 581 |
+
)
|
| 582 |
+
all_image_pos_ids.append(image_padded_pos_ids if image_padding_len > 0 else image_ori_pos_ids)
|
| 583 |
+
# pad mask
|
| 584 |
+
image_pad_mask = torch.cat(
|
| 585 |
+
[
|
| 586 |
+
torch.zeros((image_ori_len,), dtype=torch.bool, device=device),
|
| 587 |
+
torch.ones((image_padding_len,), dtype=torch.bool, device=device),
|
| 588 |
+
],
|
| 589 |
+
dim=0,
|
| 590 |
+
)
|
| 591 |
+
all_image_pad_mask.append(
|
| 592 |
+
image_pad_mask
|
| 593 |
+
if image_padding_len > 0
|
| 594 |
+
else torch.zeros((image_ori_len,), dtype=torch.bool, device=device)
|
| 595 |
+
)
|
| 596 |
+
# padded feature
|
| 597 |
+
image_padded_feat = torch.cat(
|
| 598 |
+
[image, image[-1:].repeat(image_padding_len, 1)],
|
| 599 |
+
dim=0,
|
| 600 |
+
)
|
| 601 |
+
all_image_out.append(image_padded_feat if image_padding_len > 0 else image)
|
| 602 |
+
|
| 603 |
+
return (
|
| 604 |
+
all_image_out,
|
| 605 |
+
all_cap_feats_out,
|
| 606 |
+
all_image_size,
|
| 607 |
+
all_image_pos_ids,
|
| 608 |
+
all_cap_pos_ids,
|
| 609 |
+
all_image_pad_mask,
|
| 610 |
+
all_cap_pad_mask,
|
| 611 |
+
all_cap_feats_2_out,
|
| 612 |
+
)
|
| 613 |
+
|
| 614 |
+
def forward(
|
| 615 |
+
self,
|
| 616 |
+
x: List[torch.Tensor],
|
| 617 |
+
t,
|
| 618 |
+
cap_feats: List[torch.Tensor],
|
| 619 |
+
patch_size=2,
|
| 620 |
+
f_patch_size=1,
|
| 621 |
+
ref_x=None,
|
| 622 |
+
cap_feats_2=None,
|
| 623 |
+
return_dict: bool = True,
|
| 624 |
+
):
|
| 625 |
+
assert patch_size in self.all_patch_size
|
| 626 |
+
assert f_patch_size in self.all_f_patch_size
|
| 627 |
+
|
| 628 |
+
bsz = len(x)
|
| 629 |
+
device = x[0].device
|
| 630 |
+
t = t * self.t_scale
|
| 631 |
+
t = self.t_embedder(t)
|
| 632 |
+
|
| 633 |
+
(
|
| 634 |
+
x,
|
| 635 |
+
cap_feats,
|
| 636 |
+
x_size,
|
| 637 |
+
x_pos_ids,
|
| 638 |
+
cap_pos_ids,
|
| 639 |
+
x_inner_pad_mask,
|
| 640 |
+
cap_inner_pad_mask,
|
| 641 |
+
cap_feats_2,
|
| 642 |
+
) = self.patchify_and_embed(x, cap_feats, patch_size, f_patch_size, ref_x, cap_feats_2)
|
| 643 |
+
|
| 644 |
+
# x embed & refine
|
| 645 |
+
x_item_seqlens = [len(_) for _ in x]
|
| 646 |
+
assert all(_ % SEQ_MULTI_OF == 0 for _ in x_item_seqlens)
|
| 647 |
+
x_max_item_seqlen = max(x_item_seqlens)
|
| 648 |
+
|
| 649 |
+
x = torch.cat(x, dim=0)
|
| 650 |
+
x = self.all_x_embedder[f"{patch_size}-{f_patch_size}"](x)
|
| 651 |
+
|
| 652 |
+
# Match t_embedder output dtype to x for layerwise casting compatibility
|
| 653 |
+
adaln_input = t.type_as(x)
|
| 654 |
+
if self.alignment_padding_mode == LEARNED_PADDING:
|
| 655 |
+
x[torch.cat(x_inner_pad_mask)] = self.x_pad_token
|
| 656 |
+
else:
|
| 657 |
+
x[torch.cat(x_inner_pad_mask)] = 0.0
|
| 658 |
+
x = list(x.split(x_item_seqlens, dim=0))
|
| 659 |
+
x_freqs_cis = list(self.rope_embedder(torch.cat(x_pos_ids, dim=0)).split([len(_) for _ in x_pos_ids], dim=0))
|
| 660 |
+
|
| 661 |
+
x = pad_sequence(x, batch_first=True, padding_value=0.0)
|
| 662 |
+
x_freqs_cis = pad_sequence(x_freqs_cis, batch_first=True, padding_value=0.0)
|
| 663 |
+
# Clarify the length matches to satisfy Dynamo due to "Symbolic Shape Inference" to avoid compilation errors
|
| 664 |
+
x_freqs_cis = x_freqs_cis[:, : x.shape[1]]
|
| 665 |
+
|
| 666 |
+
x_attn_mask = torch.zeros((bsz, x_max_item_seqlen), dtype=torch.bool, device=device)
|
| 667 |
+
for i, seq_len in enumerate(x_item_seqlens):
|
| 668 |
+
x_attn_mask[i, :seq_len] = 1
|
| 669 |
+
if self.alignment_padding_mode == ZERO_MASKED_PADDING:
|
| 670 |
+
mask_out_alignment_padding(x_attn_mask, x_inner_pad_mask, [0] * bsz)
|
| 671 |
+
|
| 672 |
+
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
| 673 |
+
for layer in self.noise_refiner:
|
| 674 |
+
x = self._gradient_checkpointing_func(layer, x, x_attn_mask, x_freqs_cis, adaln_input)
|
| 675 |
+
else:
|
| 676 |
+
for layer in self.noise_refiner:
|
| 677 |
+
x = layer(x, x_attn_mask, x_freqs_cis, adaln_input)
|
| 678 |
+
|
| 679 |
+
|
| 680 |
+
if len(cap_feats) > 0:
|
| 681 |
+
# cap embed & refine
|
| 682 |
+
cap_item_seqlens = [len(_) for _ in cap_feats]
|
| 683 |
+
cap_feats = torch.cat(cap_feats, dim=0)
|
| 684 |
+
cap_feats = self.cap_embedder(cap_feats)
|
| 685 |
+
|
| 686 |
+
if len(cap_feats_2) > 0:
|
| 687 |
+
cap_feats = list(cap_feats.split(cap_item_seqlens, dim=0))
|
| 688 |
+
assert len(cap_feats) == len(cap_feats_2)
|
| 689 |
+
assert cap_feats[0].ndim == 2
|
| 690 |
+
assert cap_feats_2[0].ndim == 2
|
| 691 |
+
cap_feats = [torch.cat([i, j], dim=0) for i, j in zip(cap_feats, cap_feats_2)]
|
| 692 |
+
cap_item_seqlens = [len(_) for _ in cap_feats]
|
| 693 |
+
cap_feats = torch.cat(cap_feats, dim=0)
|
| 694 |
+
else:
|
| 695 |
+
assert len(cap_feats_2) > 0
|
| 696 |
+
cap_item_seqlens = [len(_) for _ in cap_feats_2]
|
| 697 |
+
cap_feats = torch.cat(cap_feats_2, dim=0)
|
| 698 |
+
|
| 699 |
+
cap_max_item_seqlen = max(cap_item_seqlens)
|
| 700 |
+
if self.alignment_padding_mode == LEARNED_PADDING:
|
| 701 |
+
cap_feats[torch.cat(cap_inner_pad_mask)] = self.cap_pad_token
|
| 702 |
+
else:
|
| 703 |
+
cap_feats[torch.cat(cap_inner_pad_mask)] = 0.0
|
| 704 |
+
|
| 705 |
+
cap_feats = list(cap_feats.split(cap_item_seqlens, dim=0))
|
| 706 |
+
cap_freqs_cis = list(
|
| 707 |
+
self.rope_embedder(torch.cat(cap_pos_ids, dim=0)).split([len(_) for _ in cap_pos_ids], dim=0)
|
| 708 |
+
)
|
| 709 |
+
|
| 710 |
+
cap_feats = pad_sequence(cap_feats, batch_first=True, padding_value=0.0)
|
| 711 |
+
cap_freqs_cis = pad_sequence(cap_freqs_cis, batch_first=True, padding_value=0.0)
|
| 712 |
+
# Clarify the length matches to satisfy Dynamo due to "Symbolic Shape Inference" to avoid compilation errors
|
| 713 |
+
cap_freqs_cis = cap_freqs_cis[:, : cap_feats.shape[1]]
|
| 714 |
+
|
| 715 |
+
cap_attn_mask = torch.zeros((bsz, cap_max_item_seqlen), dtype=torch.bool, device=device)
|
| 716 |
+
for i, seq_len in enumerate(cap_item_seqlens):
|
| 717 |
+
cap_attn_mask[i, :seq_len] = 1
|
| 718 |
+
if self.alignment_padding_mode == ZERO_MASKED_PADDING:
|
| 719 |
+
mask_out_alignment_padding(cap_attn_mask, cap_inner_pad_mask, [0] * bsz)
|
| 720 |
+
|
| 721 |
+
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
| 722 |
+
for layer in self.context_refiner:
|
| 723 |
+
cap_feats = self._gradient_checkpointing_func(layer, cap_feats, cap_attn_mask, cap_freqs_cis)
|
| 724 |
+
else:
|
| 725 |
+
for layer in self.context_refiner:
|
| 726 |
+
cap_feats = layer(cap_feats, cap_attn_mask, cap_freqs_cis)
|
| 727 |
+
|
| 728 |
+
# unified
|
| 729 |
+
unified = []
|
| 730 |
+
unified_freqs_cis = []
|
| 731 |
+
for i in range(bsz):
|
| 732 |
+
x_len = x_item_seqlens[i]
|
| 733 |
+
cap_len = cap_item_seqlens[i]
|
| 734 |
+
unified.append(torch.cat([x[i][:x_len], cap_feats[i][:cap_len]]))
|
| 735 |
+
unified_freqs_cis.append(torch.cat([x_freqs_cis[i][:x_len], cap_freqs_cis[i][:cap_len]]))
|
| 736 |
+
unified_item_seqlens = [a + b for a, b in zip(cap_item_seqlens, x_item_seqlens)]
|
| 737 |
+
assert unified_item_seqlens == [len(_) for _ in unified]
|
| 738 |
+
unified_max_item_seqlen = max(unified_item_seqlens)
|
| 739 |
+
|
| 740 |
+
unified = pad_sequence(unified, batch_first=True, padding_value=0.0)
|
| 741 |
+
unified_freqs_cis = pad_sequence(unified_freqs_cis, batch_first=True, padding_value=0.0)
|
| 742 |
+
unified_attn_mask = torch.zeros((bsz, unified_max_item_seqlen), dtype=torch.bool, device=device)
|
| 743 |
+
for i, seq_len in enumerate(unified_item_seqlens):
|
| 744 |
+
unified_attn_mask[i, :seq_len] = 1
|
| 745 |
+
if self.alignment_padding_mode == ZERO_MASKED_PADDING:
|
| 746 |
+
# Unified layout is [image, caption] for every batch item.
|
| 747 |
+
mask_out_alignment_padding(unified_attn_mask, x_inner_pad_mask, [0] * bsz)
|
| 748 |
+
mask_out_alignment_padding(
|
| 749 |
+
unified_attn_mask, cap_inner_pad_mask, x_item_seqlens
|
| 750 |
+
)
|
| 751 |
+
|
| 752 |
+
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
| 753 |
+
for layer in self.layers:
|
| 754 |
+
unified = self._gradient_checkpointing_func(
|
| 755 |
+
layer, unified, unified_attn_mask, unified_freqs_cis, adaln_input
|
| 756 |
+
)
|
| 757 |
+
else:
|
| 758 |
+
for layer in self.layers:
|
| 759 |
+
unified = layer(unified, unified_attn_mask, unified_freqs_cis, adaln_input)
|
| 760 |
+
|
| 761 |
+
unified = self.all_final_layer[f"{patch_size}-{f_patch_size}"](unified, adaln_input)
|
| 762 |
+
unified = list(unified.unbind(dim=0))
|
| 763 |
+
x = self.unpatchify(unified, x_size, patch_size, f_patch_size)
|
| 764 |
+
|
| 765 |
+
if not return_dict:
|
| 766 |
+
return (x,)
|
| 767 |
+
|
| 768 |
+
return Transformer2DModelOutput(sample=x)
|
code/quant/load_int8.py
ADDED
|
@@ -0,0 +1,172 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Load a streamed INT8 Ming MLLM checkpoint onto a meta-initialized model.
|
| 2 |
+
|
| 3 |
+
``model`` must already exist with parameters on ``meta`` (for example under
|
| 4 |
+
``accelerate.init_empty_weights()``). Quantized modules listed in
|
| 5 |
+
``int8_manifest.json`` are swapped from ``nn.Linear`` to ``Int8Linear.shell``
|
| 6 |
+
before the shards are assigned in.
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
from __future__ import annotations
|
| 10 |
+
|
| 11 |
+
import json
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
|
| 14 |
+
import torch
|
| 15 |
+
from safetensors.torch import load_file
|
| 16 |
+
from torch import nn
|
| 17 |
+
|
| 18 |
+
try: # imported as the `quant` package (modeling_bailingmm2.py)
|
| 19 |
+
from .int8_linear import Int8Linear
|
| 20 |
+
except ImportError: # run from inside quant/ (CLI, tests)
|
| 21 |
+
from int8_linear import Int8Linear
|
| 22 |
+
|
| 23 |
+
MANIFEST_NAME = "int8_manifest.json"
|
| 24 |
+
INDEX_NAME = "model.safetensors.index.json"
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
def load_int8_mllm_(model: nn.Module, int8_dir, device) -> dict:
|
| 28 |
+
"""Swap quantize-rule linears for INT8 shells and assign shard tensors.
|
| 29 |
+
|
| 30 |
+
Returns ``{"modules_swapped", "tensors_loaded", "bytes_loaded"}``.
|
| 31 |
+
Raises ``RuntimeError`` on a bad manifest, a module that is not an
|
| 32 |
+
``nn.Linear``, an unexpected checkpoint key, or any parameter / persistent
|
| 33 |
+
buffer still on ``meta``. Non-persistent buffers (rotary ``inv_freq``) may
|
| 34 |
+
stay on CPU; the caller moves the model afterwards.
|
| 35 |
+
"""
|
| 36 |
+
int8_dir = Path(int8_dir)
|
| 37 |
+
dev = torch.device(device) if not isinstance(device, torch.device) else device
|
| 38 |
+
manifest_path = int8_dir / MANIFEST_NAME
|
| 39 |
+
if not manifest_path.is_file():
|
| 40 |
+
raise RuntimeError(f"missing int8 manifest: {manifest_path}")
|
| 41 |
+
manifest = json.loads(manifest_path.read_text(encoding="utf-8"))
|
| 42 |
+
if manifest.get("format") != "ming-int8-wo-v1":
|
| 43 |
+
raise RuntimeError(
|
| 44 |
+
f"unsupported int8 manifest format: {manifest.get('format')!r} ({manifest_path})"
|
| 45 |
+
)
|
| 46 |
+
module_names = manifest.get("quantized_modules")
|
| 47 |
+
if not isinstance(module_names, list) or not all(isinstance(n, str) for n in module_names):
|
| 48 |
+
raise RuntimeError(f"{manifest_path} quantized_modules is not a list of strings")
|
| 49 |
+
|
| 50 |
+
swapped = _swap_linears(model, module_names)
|
| 51 |
+
|
| 52 |
+
index_path = int8_dir / INDEX_NAME
|
| 53 |
+
if not index_path.is_file():
|
| 54 |
+
raise RuntimeError(f"missing index: {index_path}")
|
| 55 |
+
index = json.loads(index_path.read_text(encoding="utf-8"))
|
| 56 |
+
weight_map = index.get("weight_map")
|
| 57 |
+
if not isinstance(weight_map, dict) or not weight_map:
|
| 58 |
+
raise RuntimeError(f"{index_path} has no weight_map")
|
| 59 |
+
|
| 60 |
+
shard_names: list[str] = []
|
| 61 |
+
seen: set[str] = set()
|
| 62 |
+
for shard in weight_map.values():
|
| 63 |
+
if shard not in seen:
|
| 64 |
+
seen.add(shard)
|
| 65 |
+
shard_names.append(shard)
|
| 66 |
+
|
| 67 |
+
tensors_loaded = 0
|
| 68 |
+
bytes_loaded = 0
|
| 69 |
+
unexpected: list[str] = []
|
| 70 |
+
for shard in shard_names:
|
| 71 |
+
rel = Path(shard)
|
| 72 |
+
if rel.is_absolute() or ".." in rel.parts:
|
| 73 |
+
raise RuntimeError(f"unsafe shard path in index: {shard}")
|
| 74 |
+
path = int8_dir / rel
|
| 75 |
+
if not path.is_file():
|
| 76 |
+
raise RuntimeError(f"missing shard: {path}")
|
| 77 |
+
sd = load_file(str(path), device=str(dev))
|
| 78 |
+
for tensor in sd.values():
|
| 79 |
+
tensors_loaded += 1
|
| 80 |
+
bytes_loaded += tensor.numel() * tensor.element_size()
|
| 81 |
+
incompatible = model.load_state_dict(sd, strict=False, assign=True)
|
| 82 |
+
unexpected.extend(incompatible.unexpected_keys)
|
| 83 |
+
del sd
|
| 84 |
+
|
| 85 |
+
if unexpected:
|
| 86 |
+
listed = "\n".join(f" {key}" for key in unexpected)
|
| 87 |
+
raise RuntimeError(
|
| 88 |
+
f"unexpected keys in checkpoint (not present on the model):\n{listed}"
|
| 89 |
+
)
|
| 90 |
+
|
| 91 |
+
_assert_loaded(model, module_names, dev)
|
| 92 |
+
return {
|
| 93 |
+
"modules_swapped": swapped,
|
| 94 |
+
"tensors_loaded": tensors_loaded,
|
| 95 |
+
"bytes_loaded": bytes_loaded,
|
| 96 |
+
}
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
def _swap_linears(model: nn.Module, module_names: list[str]) -> int:
|
| 100 |
+
for name in module_names:
|
| 101 |
+
try:
|
| 102 |
+
linear = model.get_submodule(name)
|
| 103 |
+
except AttributeError as exc:
|
| 104 |
+
raise RuntimeError(f"manifest module not found on model: {name}") from exc
|
| 105 |
+
if not isinstance(linear, nn.Linear):
|
| 106 |
+
raise RuntimeError(
|
| 107 |
+
f"{name} is {type(linear).__name__}, expected nn.Linear "
|
| 108 |
+
"(refusing to swap a router or other non-linear)"
|
| 109 |
+
)
|
| 110 |
+
parent_name, _, leaf = name.rpartition(".")
|
| 111 |
+
if not leaf:
|
| 112 |
+
raise RuntimeError(f"cannot place shell for {name}")
|
| 113 |
+
parent = model.get_submodule(parent_name) if parent_name else model
|
| 114 |
+
has_bias = linear.bias is not None
|
| 115 |
+
bias_dtype = linear.bias.dtype if has_bias else torch.float32
|
| 116 |
+
shell = Int8Linear.shell(
|
| 117 |
+
in_features=linear.in_features,
|
| 118 |
+
out_features=linear.out_features,
|
| 119 |
+
bias=has_bias,
|
| 120 |
+
bias_dtype=bias_dtype,
|
| 121 |
+
device="meta",
|
| 122 |
+
)
|
| 123 |
+
setattr(parent, leaf, shell)
|
| 124 |
+
return len(module_names)
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
def _assert_loaded(model: nn.Module, module_names: list[str], dev: torch.device) -> None:
|
| 128 |
+
offenders: list[str] = []
|
| 129 |
+
for name, param in model.named_parameters(remove_duplicate=False):
|
| 130 |
+
if param is not None and param.device.type == "meta":
|
| 131 |
+
offenders.append(f"parameter {name} dtype={param.dtype} device={param.device}")
|
| 132 |
+
for mod_name, mod in model.named_modules():
|
| 133 |
+
nonpersist = getattr(mod, "_non_persistent_buffers_set", set())
|
| 134 |
+
for buf_name, buf in mod._buffers.items():
|
| 135 |
+
if buf is None:
|
| 136 |
+
continue
|
| 137 |
+
full = f"{mod_name}.{buf_name}" if mod_name else buf_name
|
| 138 |
+
if buf.device.type != "meta":
|
| 139 |
+
# Non-persistent buffers (rotary inv_freq) are not in the
|
| 140 |
+
# checkpoint. accelerate leaves them on CPU; that is not an error.
|
| 141 |
+
continue
|
| 142 |
+
if buf_name in nonpersist:
|
| 143 |
+
offenders.append(
|
| 144 |
+
f"non-persistent buffer {full} dtype={buf.dtype} device={buf.device}"
|
| 145 |
+
)
|
| 146 |
+
else:
|
| 147 |
+
offenders.append(f"buffer {full} dtype={buf.dtype} device={buf.device}")
|
| 148 |
+
if offenders:
|
| 149 |
+
listed = "\n".join(f" {line}" for line in offenders)
|
| 150 |
+
raise RuntimeError(f"tensors still on meta after load:\n{listed}")
|
| 151 |
+
|
| 152 |
+
for name in module_names:
|
| 153 |
+
mod = model.get_submodule(name)
|
| 154 |
+
if not isinstance(mod, Int8Linear):
|
| 155 |
+
raise RuntimeError(f"{name} was not swapped to Int8Linear")
|
| 156 |
+
if mod.weight is None or mod.weight.dtype != torch.int8:
|
| 157 |
+
raise RuntimeError(f"{name}.weight is not int8 after load")
|
| 158 |
+
if mod.scale is None or mod.scale.dtype != torch.float32:
|
| 159 |
+
raise RuntimeError(f"{name}.scale is not float32 after load")
|
| 160 |
+
if mod.weight.device.type == "meta" or mod.scale.device.type == "meta":
|
| 161 |
+
raise RuntimeError(f"{name} still has meta tensors after load")
|
| 162 |
+
if mod.weight.device != dev or mod.scale.device != dev:
|
| 163 |
+
raise RuntimeError(
|
| 164 |
+
f"{name} loaded on weight={mod.weight.device} scale={mod.scale.device}, "
|
| 165 |
+
f"expected {dev}"
|
| 166 |
+
)
|
| 167 |
+
if tuple(mod.scale.shape) != (mod.out_features,):
|
| 168 |
+
raise RuntimeError(
|
| 169 |
+
f"{name}.scale shape {tuple(mod.scale.shape)} != ({mod.out_features},)"
|
| 170 |
+
)
|
| 171 |
+
if mod.bias is not None and mod.bias.device != dev:
|
| 172 |
+
raise RuntimeError(f"{name}.bias is on {mod.bias.device}, expected {dev}")
|
code/quant/test_int8.py
ADDED
|
@@ -0,0 +1,665 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""CPU tests for weight-only INT8 Ming MLLM quantize + load.
|
| 2 |
+
|
| 3 |
+
Run: HIP_VISIBLE_DEVICES=-1 python test_int8.py
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
from __future__ import annotations
|
| 7 |
+
|
| 8 |
+
import json
|
| 9 |
+
import sys
|
| 10 |
+
import tempfile
|
| 11 |
+
import traceback
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
|
| 14 |
+
import torch
|
| 15 |
+
import torch.nn.functional as F
|
| 16 |
+
from safetensors.torch import load_file, save_file
|
| 17 |
+
from torch import nn
|
| 18 |
+
|
| 19 |
+
import quantize_stream
|
| 20 |
+
from int8_linear import Int8Linear, is_quantizable, quantize_weight
|
| 21 |
+
from load_int8 import load_int8_mllm_
|
| 22 |
+
|
| 23 |
+
# Tiny stand-in for Ming's MLLM names. Not the real model.
|
| 24 |
+
HIDDEN = 32
|
| 25 |
+
INTER = 48
|
| 26 |
+
VOCAB = 64
|
| 27 |
+
N_EXPERTS = 2
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
class RMSNorm(nn.Module):
|
| 31 |
+
def __init__(self, dim: int, eps: float = 1e-6):
|
| 32 |
+
super().__init__()
|
| 33 |
+
self.weight = nn.Parameter(torch.ones(dim))
|
| 34 |
+
self.eps = eps
|
| 35 |
+
|
| 36 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 37 |
+
var = x.float().pow(2).mean(dim=-1, keepdim=True)
|
| 38 |
+
y = x * torch.rsqrt(var + self.eps)
|
| 39 |
+
return (y * self.weight).to(dtype=x.dtype)
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
class Attention(nn.Module):
|
| 43 |
+
def __init__(self, hidden: int):
|
| 44 |
+
super().__init__()
|
| 45 |
+
self.hidden = hidden
|
| 46 |
+
self.query_key_value = nn.Linear(hidden, hidden * 3, bias=True)
|
| 47 |
+
self.dense = nn.Linear(hidden, hidden, bias=False)
|
| 48 |
+
self.q_norm = RMSNorm(hidden)
|
| 49 |
+
self.k_norm = RMSNorm(hidden)
|
| 50 |
+
# Non-persistent, like BailingMoeV2RotaryEmbedding.inv_freq.
|
| 51 |
+
self.register_buffer(
|
| 52 |
+
"inv_freq", torch.arange(hidden // 2, dtype=torch.float32), persistent=False
|
| 53 |
+
)
|
| 54 |
+
|
| 55 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 56 |
+
qkv = self.query_key_value(x)
|
| 57 |
+
h = self.hidden
|
| 58 |
+
q = self.q_norm(qkv[..., :h])
|
| 59 |
+
k = self.k_norm(qkv[..., h : 2 * h])
|
| 60 |
+
v = qkv[..., 2 * h :]
|
| 61 |
+
return self.dense(q + k + v)
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
class DenseMLP(nn.Module):
|
| 65 |
+
def __init__(self, hidden: int, inter: int):
|
| 66 |
+
super().__init__()
|
| 67 |
+
self.gate_proj = nn.Linear(hidden, inter, bias=False)
|
| 68 |
+
self.up_proj = nn.Linear(hidden, inter, bias=True)
|
| 69 |
+
self.down_proj = nn.Linear(inter, hidden, bias=False)
|
| 70 |
+
|
| 71 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 72 |
+
return self.down_proj(F.silu(self.gate_proj(x)) * self.up_proj(x))
|
| 73 |
+
|
| 74 |
+
|
| 75 |
+
class Expert(nn.Module):
|
| 76 |
+
def __init__(self, hidden: int, inter: int):
|
| 77 |
+
super().__init__()
|
| 78 |
+
self.gate_proj = nn.Linear(hidden, inter, bias=False)
|
| 79 |
+
self.up_proj = nn.Linear(hidden, inter, bias=True)
|
| 80 |
+
self.down_proj = nn.Linear(inter, hidden, bias=False)
|
| 81 |
+
|
| 82 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 83 |
+
return self.down_proj(F.silu(self.gate_proj(x)) * self.up_proj(x))
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
class Router(nn.Module):
|
| 87 |
+
"""Not an nn.Linear. Leaf name is gate / image_gate / audio_gate."""
|
| 88 |
+
|
| 89 |
+
def __init__(self, hidden: int, n_experts: int):
|
| 90 |
+
super().__init__()
|
| 91 |
+
self.weight = nn.Parameter(torch.empty(n_experts, hidden))
|
| 92 |
+
self.expert_bias = nn.Parameter(torch.zeros(n_experts), requires_grad=False)
|
| 93 |
+
nn.init.kaiming_uniform_(self.weight, a=5**0.5)
|
| 94 |
+
|
| 95 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 96 |
+
return F.linear(x, self.weight, self.expert_bias)
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
class MoeMLP(nn.Module):
|
| 100 |
+
def __init__(self, hidden: int, inter: int, n_experts: int):
|
| 101 |
+
super().__init__()
|
| 102 |
+
self.gate = Router(hidden, n_experts)
|
| 103 |
+
self.image_gate = Router(hidden, n_experts)
|
| 104 |
+
self.audio_gate = Router(hidden, n_experts)
|
| 105 |
+
self.experts = nn.ModuleList(Expert(hidden, inter) for _ in range(n_experts))
|
| 106 |
+
self.shared_experts = Expert(hidden, inter)
|
| 107 |
+
|
| 108 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 109 |
+
scores = self.gate(x) + self.image_gate(x) + self.audio_gate(x)
|
| 110 |
+
weights = torch.softmax(scores, dim=-1)
|
| 111 |
+
mixed = self.shared_experts(x)
|
| 112 |
+
for i, expert in enumerate(self.experts):
|
| 113 |
+
mixed = mixed + expert(x) * weights[..., i : i + 1]
|
| 114 |
+
return mixed
|
| 115 |
+
|
| 116 |
+
|
| 117 |
+
class DecoderLayer(nn.Module):
|
| 118 |
+
def __init__(self, hidden: int, mlp: nn.Module):
|
| 119 |
+
super().__init__()
|
| 120 |
+
self.input_layernorm = RMSNorm(hidden)
|
| 121 |
+
self.post_attention_layernorm = RMSNorm(hidden)
|
| 122 |
+
self.attention = Attention(hidden)
|
| 123 |
+
self.mlp = mlp
|
| 124 |
+
|
| 125 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 126 |
+
x = x + self.attention(self.input_layernorm(x))
|
| 127 |
+
x = x + self.mlp(self.post_attention_layernorm(x))
|
| 128 |
+
return x
|
| 129 |
+
|
| 130 |
+
|
| 131 |
+
class TinyMing(nn.Module):
|
| 132 |
+
"""Names match the real checkpoint: model.model.layers.*, model.lm_head, vision.*."""
|
| 133 |
+
|
| 134 |
+
def __init__(self):
|
| 135 |
+
super().__init__()
|
| 136 |
+
self.model = nn.Module()
|
| 137 |
+
self.model.model = nn.Module()
|
| 138 |
+
self.model.model.word_embeddings = nn.Embedding(VOCAB, HIDDEN)
|
| 139 |
+
self.model.model.layers = nn.ModuleList(
|
| 140 |
+
[
|
| 141 |
+
DecoderLayer(HIDDEN, DenseMLP(HIDDEN, INTER)),
|
| 142 |
+
DecoderLayer(HIDDEN, MoeMLP(HIDDEN, INTER, N_EXPERTS)),
|
| 143 |
+
]
|
| 144 |
+
)
|
| 145 |
+
self.model.model.norm = RMSNorm(HIDDEN)
|
| 146 |
+
self.model.lm_head = nn.Linear(HIDDEN, VOCAB, bias=False)
|
| 147 |
+
block = nn.Module()
|
| 148 |
+
block.attn = nn.Module()
|
| 149 |
+
block.attn.qkv = nn.Linear(HIDDEN, HIDDEN, bias=False)
|
| 150 |
+
self.vision = nn.Module()
|
| 151 |
+
self.vision.blocks = nn.ModuleList([block])
|
| 152 |
+
self.linear_proj = nn.ModuleList([nn.Linear(HIDDEN, HIDDEN, bias=True)])
|
| 153 |
+
|
| 154 |
+
def forward(self, input_ids: torch.Tensor) -> torch.Tensor:
|
| 155 |
+
h = self.model.model.word_embeddings(input_ids)
|
| 156 |
+
for layer in self.model.model.layers:
|
| 157 |
+
h = layer(h)
|
| 158 |
+
h = self.model.model.norm(h)
|
| 159 |
+
return self.model.lm_head(h)
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
# Modules the rule must select for TinyMing. Hardcoded — not derived from is_quantizable.
|
| 163 |
+
EXPECTED_QUANT_MODULES = [
|
| 164 |
+
"model.model.layers.0.attention.dense",
|
| 165 |
+
"model.model.layers.0.attention.query_key_value",
|
| 166 |
+
"model.model.layers.0.mlp.down_proj",
|
| 167 |
+
"model.model.layers.0.mlp.gate_proj",
|
| 168 |
+
"model.model.layers.0.mlp.up_proj",
|
| 169 |
+
"model.model.layers.1.attention.dense",
|
| 170 |
+
"model.model.layers.1.attention.query_key_value",
|
| 171 |
+
"model.model.layers.1.mlp.experts.0.down_proj",
|
| 172 |
+
"model.model.layers.1.mlp.experts.0.gate_proj",
|
| 173 |
+
"model.model.layers.1.mlp.experts.0.up_proj",
|
| 174 |
+
"model.model.layers.1.mlp.experts.1.down_proj",
|
| 175 |
+
"model.model.layers.1.mlp.experts.1.gate_proj",
|
| 176 |
+
"model.model.layers.1.mlp.experts.1.up_proj",
|
| 177 |
+
"model.model.layers.1.mlp.shared_experts.down_proj",
|
| 178 |
+
"model.model.layers.1.mlp.shared_experts.gate_proj",
|
| 179 |
+
"model.model.layers.1.mlp.shared_experts.up_proj",
|
| 180 |
+
]
|
| 181 |
+
|
| 182 |
+
MUST_NOT_QUANTIZE = [
|
| 183 |
+
"model.model.layers.1.mlp.gate",
|
| 184 |
+
"model.model.layers.1.mlp.image_gate",
|
| 185 |
+
"model.model.layers.1.mlp.audio_gate",
|
| 186 |
+
"model.model.word_embeddings",
|
| 187 |
+
"model.model.norm",
|
| 188 |
+
"model.lm_head",
|
| 189 |
+
"vision.blocks.0.attn.qkv",
|
| 190 |
+
"linear_proj.0",
|
| 191 |
+
"model.model.layers.0.attention.q_norm",
|
| 192 |
+
"model.model.layers.0.input_layernorm",
|
| 193 |
+
]
|
| 194 |
+
|
| 195 |
+
|
| 196 |
+
def _move_parameters_to_meta(model: nn.Module) -> nn.Module:
|
| 197 |
+
"""Parameters → meta, buffers stay where they are (CPU). Matches accelerate include_buffers=False."""
|
| 198 |
+
for mod in model.modules():
|
| 199 |
+
for name, param in list(mod._parameters.items()):
|
| 200 |
+
if param is None:
|
| 201 |
+
continue
|
| 202 |
+
mod._parameters[name] = nn.Parameter(
|
| 203 |
+
param.detach().to(device="meta"),
|
| 204 |
+
requires_grad=param.requires_grad,
|
| 205 |
+
)
|
| 206 |
+
return model
|
| 207 |
+
|
| 208 |
+
|
| 209 |
+
def _save_bf16_checkpoint(model: nn.Module, src: Path) -> None:
|
| 210 |
+
src.mkdir(parents=True, exist_ok=True)
|
| 211 |
+
sd = {k: v.detach().contiguous() for k, v in model.state_dict().items()}
|
| 212 |
+
if not sd:
|
| 213 |
+
raise AssertionError("empty state_dict")
|
| 214 |
+
for tensor in sd.values():
|
| 215 |
+
if tensor.is_floating_point():
|
| 216 |
+
assert tensor.dtype == torch.bfloat16, tensor.dtype
|
| 217 |
+
keys = list(sd)
|
| 218 |
+
mid = max(1, len(keys) // 2)
|
| 219 |
+
shards = {
|
| 220 |
+
"bf16-00001.safetensors": {k: sd[k] for k in keys[:mid]},
|
| 221 |
+
"bf16-00002.safetensors": {k: sd[k] for k in keys[mid:]},
|
| 222 |
+
}
|
| 223 |
+
weight_map = {}
|
| 224 |
+
total = 0
|
| 225 |
+
for filename, tensors in shards.items():
|
| 226 |
+
save_file(tensors, str(src / filename))
|
| 227 |
+
for name, tensor in tensors.items():
|
| 228 |
+
weight_map[name] = filename
|
| 229 |
+
total += tensor.numel() * tensor.element_size()
|
| 230 |
+
index = {"metadata": {"total_size": total}, "weight_map": weight_map}
|
| 231 |
+
(src / "model.safetensors.index.json").write_text(
|
| 232 |
+
json.dumps(index, indent=2) + "\n", encoding="utf-8"
|
| 233 |
+
)
|
| 234 |
+
(src / "config.json").write_bytes(b'{"model_type":"tiny-ming","hidden":32}\n')
|
| 235 |
+
extra = src / "extra"
|
| 236 |
+
extra.mkdir()
|
| 237 |
+
(extra / "chat_template.jinja").write_text("{{ messages }}\n", encoding="utf-8")
|
| 238 |
+
|
| 239 |
+
|
| 240 |
+
def _load_all(folder: Path) -> dict[str, torch.Tensor]:
|
| 241 |
+
index = json.loads((folder / "model.safetensors.index.json").read_text(encoding="utf-8"))
|
| 242 |
+
order: list[str] = []
|
| 243 |
+
seen: set[str] = set()
|
| 244 |
+
for shard in index["weight_map"].values():
|
| 245 |
+
if shard not in seen:
|
| 246 |
+
seen.add(shard)
|
| 247 |
+
order.append(shard)
|
| 248 |
+
sd: dict[str, torch.Tensor] = {}
|
| 249 |
+
for shard in order:
|
| 250 |
+
sd.update(load_file(str(folder / shard)))
|
| 251 |
+
return sd
|
| 252 |
+
|
| 253 |
+
|
| 254 |
+
def _apply_int8_(model: nn.Module) -> None:
|
| 255 |
+
names = []
|
| 256 |
+
for name, mod in model.named_modules():
|
| 257 |
+
if isinstance(mod, nn.Linear) and is_quantizable(
|
| 258 |
+
f"{name}.weight", tuple(mod.weight.shape)
|
| 259 |
+
):
|
| 260 |
+
names.append(name)
|
| 261 |
+
for name in names:
|
| 262 |
+
parent_name, _, leaf = name.rpartition(".")
|
| 263 |
+
parent = model.get_submodule(parent_name) if parent_name else model
|
| 264 |
+
setattr(parent, leaf, Int8Linear.from_linear(getattr(parent, leaf)))
|
| 265 |
+
|
| 266 |
+
|
| 267 |
+
def _assert_no_meta(model: nn.Module) -> None:
|
| 268 |
+
for name, param in model.named_parameters():
|
| 269 |
+
assert param.device.type != "meta", name
|
| 270 |
+
for mod_name, mod in model.named_modules():
|
| 271 |
+
for buf_name, buf in mod._buffers.items():
|
| 272 |
+
if buf is None:
|
| 273 |
+
continue
|
| 274 |
+
full = f"{mod_name}.{buf_name}" if mod_name else buf_name
|
| 275 |
+
assert buf.device.type != "meta", full
|
| 276 |
+
|
| 277 |
+
|
| 278 |
+
def test_from_linear_roundtrip() -> None:
|
| 279 |
+
torch.manual_seed(0)
|
| 280 |
+
out_f, in_f = 5, 7
|
| 281 |
+
lin = nn.Linear(in_f, out_f, bias=True)
|
| 282 |
+
scales = torch.tensor([0.5, 0.25, 0.125, 2.0, 4.0], dtype=torch.float32)
|
| 283 |
+
q = torch.randint(-127, 128, (out_f, in_f), dtype=torch.int8)
|
| 284 |
+
q[:, 0] = 127
|
| 285 |
+
q[2, :] = 0 # all-zero row; must not NaN
|
| 286 |
+
weight = q.float() * scales[:, None]
|
| 287 |
+
with torch.no_grad():
|
| 288 |
+
lin.weight.copy_(weight)
|
| 289 |
+
lin.bias.copy_(torch.tensor([0.1, -0.2, 0.3, -0.4, 0.5]))
|
| 290 |
+
mod = Int8Linear.from_linear(lin)
|
| 291 |
+
deq = mod.weight.float() * mod.scale[:, None]
|
| 292 |
+
for row in range(out_f):
|
| 293 |
+
if row == 2:
|
| 294 |
+
assert torch.equal(mod.weight[row], torch.zeros(in_f, dtype=torch.int8))
|
| 295 |
+
assert float(mod.scale[row]) == 1.0
|
| 296 |
+
assert torch.equal(deq[row], torch.zeros(in_f))
|
| 297 |
+
else:
|
| 298 |
+
assert torch.equal(deq[row], weight[row]), (deq[row] - weight[row]).abs().max().item()
|
| 299 |
+
assert mod.bias is not None and torch.equal(mod.bias, lin.bias)
|
| 300 |
+
assert mod.bias.dtype == lin.bias.dtype
|
| 301 |
+
assert torch.isfinite(mod.scale).all()
|
| 302 |
+
|
| 303 |
+
# Random weights: per-element error stays within half a bin (+ float slack).
|
| 304 |
+
lin_r = nn.Linear(13, 9, bias=False)
|
| 305 |
+
mod_r = Int8Linear.from_linear(lin_r)
|
| 306 |
+
w = lin_r.weight.detach().float()
|
| 307 |
+
deq_r = (mod_r.weight.double() * mod_r.scale.double()[:, None]).float()
|
| 308 |
+
err = (w.double() - deq_r.double()).abs()
|
| 309 |
+
half = mod_r.scale.double()[:, None] * 0.5
|
| 310 |
+
slip = (err - half).max().item()
|
| 311 |
+
assert slip <= 1e-4, slip
|
| 312 |
+
assert torch.isfinite(mod_r.scale).all()
|
| 313 |
+
|
| 314 |
+
# Entirely zero weight: finite forward, zero codes, scale 1.
|
| 315 |
+
lin_z = nn.Linear(4, 3, bias=True)
|
| 316 |
+
with torch.no_grad():
|
| 317 |
+
lin_z.weight.zero_()
|
| 318 |
+
mod_z = Int8Linear.from_linear(lin_z)
|
| 319 |
+
assert torch.equal(mod_z.weight, torch.zeros_like(mod_z.weight))
|
| 320 |
+
assert torch.equal(mod_z.scale, torch.ones(3))
|
| 321 |
+
y = mod_z(torch.randn(8, 4))
|
| 322 |
+
assert torch.isfinite(y).all()
|
| 323 |
+
assert torch.allclose(y, mod_z.bias.expand_as(y))
|
| 324 |
+
|
| 325 |
+
# Zero row contributes only its bias.
|
| 326 |
+
x = torch.randn(6, in_f)
|
| 327 |
+
y_mix = mod(x)
|
| 328 |
+
assert torch.isfinite(y_mix).all()
|
| 329 |
+
assert torch.allclose(y_mix[:, 2], mod.bias[2].expand(6))
|
| 330 |
+
|
| 331 |
+
# bf16 source linear: codes int8, scale fp32, bias stays bf16.
|
| 332 |
+
lin_b = nn.Linear(8, 4, bias=True).to(dtype=torch.bfloat16)
|
| 333 |
+
mod_b = Int8Linear.from_linear(lin_b)
|
| 334 |
+
assert mod_b.weight.dtype == torch.int8
|
| 335 |
+
assert mod_b.scale.dtype == torch.float32
|
| 336 |
+
assert mod_b.bias is not None and mod_b.bias.dtype == torch.bfloat16
|
| 337 |
+
w_b = lin_b.weight.detach().float()
|
| 338 |
+
deq_b = mod_b.weight.float() * mod_b.scale[:, None]
|
| 339 |
+
err_b = (w_b.double() - deq_b.double()).abs()
|
| 340 |
+
half_b = mod_b.scale.double()[:, None] * 0.5
|
| 341 |
+
assert (err_b - half_b).max().item() <= 1e-2, (err_b - half_b).max().item()
|
| 342 |
+
|
| 343 |
+
|
| 344 |
+
def _assert_quant_dtypes(mod: Int8Linear, scale: torch.Tensor, weight: torch.Tensor, bias_dtype: torch.dtype) -> None:
|
| 345 |
+
assert mod.weight.dtype == torch.int8
|
| 346 |
+
assert mod.scale.dtype == torch.float32
|
| 347 |
+
assert torch.equal(mod.weight, weight)
|
| 348 |
+
assert torch.equal(mod.scale, scale)
|
| 349 |
+
assert mod.bias is not None and mod.bias.dtype == bias_dtype
|
| 350 |
+
|
| 351 |
+
|
| 352 |
+
def test_dtype_cast_keeps_scale_fp32() -> None:
|
| 353 |
+
torch.manual_seed(1)
|
| 354 |
+
lin = nn.Linear(5, 3, bias=True)
|
| 355 |
+
fresh = Int8Linear.from_linear(lin)
|
| 356 |
+
scale = fresh.scale.detach().clone()
|
| 357 |
+
weight = fresh.weight.detach().clone()
|
| 358 |
+
bias = fresh.bias.detach().clone()
|
| 359 |
+
assert scale.dtype == torch.float32 and weight.dtype == torch.int8 and bias.dtype == torch.float32
|
| 360 |
+
|
| 361 |
+
# Each cast starts from fp32 so "bias follows the cast" is the single cast of the source bias.
|
| 362 |
+
mod = Int8Linear.from_linear(lin)
|
| 363 |
+
mod.bfloat16()
|
| 364 |
+
_assert_quant_dtypes(mod, scale, weight, torch.bfloat16)
|
| 365 |
+
assert torch.equal(mod.bias, bias.to(dtype=torch.bfloat16))
|
| 366 |
+
|
| 367 |
+
mod = Int8Linear.from_linear(lin)
|
| 368 |
+
mod.half()
|
| 369 |
+
_assert_quant_dtypes(mod, scale, weight, torch.float16)
|
| 370 |
+
assert torch.equal(mod.bias, bias.to(dtype=torch.float16))
|
| 371 |
+
|
| 372 |
+
mod = Int8Linear.from_linear(lin)
|
| 373 |
+
mod.to(torch.bfloat16)
|
| 374 |
+
_assert_quant_dtypes(mod, scale, weight, torch.bfloat16)
|
| 375 |
+
assert torch.equal(mod.bias, bias.to(dtype=torch.bfloat16))
|
| 376 |
+
|
| 377 |
+
mod = Int8Linear.from_linear(lin)
|
| 378 |
+
mod.to(dtype=torch.float16)
|
| 379 |
+
_assert_quant_dtypes(mod, scale, weight, torch.float16)
|
| 380 |
+
assert torch.equal(mod.bias, bias.to(dtype=torch.float16))
|
| 381 |
+
|
| 382 |
+
# A second cast applies to the bias's current dtype, not the original fp32 value.
|
| 383 |
+
mod = Int8Linear.from_linear(lin)
|
| 384 |
+
mod.to(torch.bfloat16)
|
| 385 |
+
mod.to(dtype=torch.float16)
|
| 386 |
+
_assert_quant_dtypes(mod, scale, weight, torch.float16)
|
| 387 |
+
assert torch.equal(mod.bias, bias.to(dtype=torch.bfloat16).to(dtype=torch.float16))
|
| 388 |
+
|
| 389 |
+
# What the caller actually does: parent.to(device=..., dtype=bf16).
|
| 390 |
+
parent = nn.Sequential(Int8Linear.from_linear(lin))
|
| 391 |
+
parent.to(device="cpu", dtype=torch.bfloat16)
|
| 392 |
+
_assert_quant_dtypes(parent[0], scale, weight, torch.bfloat16)
|
| 393 |
+
assert torch.equal(parent[0].bias, bias.to(dtype=torch.bfloat16))
|
| 394 |
+
|
| 395 |
+
shell = Int8Linear.shell(4, 3, bias=True, bias_dtype=torch.bfloat16, device="meta")
|
| 396 |
+
assert shell.weight.dtype == torch.int8 and shell.weight.device.type == "meta"
|
| 397 |
+
assert shell.scale.dtype == torch.float32 and shell.scale.device.type == "meta"
|
| 398 |
+
assert shell.bias is not None
|
| 399 |
+
assert shell.bias.dtype == torch.bfloat16 and shell.bias.device.type == "meta"
|
| 400 |
+
shell_nb = Int8Linear.shell(4, 3, bias=False, bias_dtype=torch.float32, device="meta")
|
| 401 |
+
assert shell_nb.bias is None
|
| 402 |
+
|
| 403 |
+
|
| 404 |
+
def test_forward_matches_reference() -> None:
|
| 405 |
+
torch.manual_seed(2)
|
| 406 |
+
for bias in (True, False):
|
| 407 |
+
lin = nn.Linear(6, 4, bias=bias)
|
| 408 |
+
# Bias is passed through unchanged, so it has to already match x's dtype
|
| 409 |
+
# (the caller does model.to(dtype=...) before the prefill).
|
| 410 |
+
modules = [
|
| 411 |
+
(Int8Linear.from_linear(lin), torch.float32),
|
| 412 |
+
(Int8Linear.from_linear(lin).to(torch.bfloat16), torch.bfloat16),
|
| 413 |
+
(Int8Linear.from_linear(lin).to(dtype=torch.float16), torch.float16),
|
| 414 |
+
]
|
| 415 |
+
for mod, dtype in modules:
|
| 416 |
+
if mod.bias is not None:
|
| 417 |
+
assert mod.bias.dtype == dtype
|
| 418 |
+
x = torch.randn(3, 5, 6, dtype=dtype)
|
| 419 |
+
ref_w = (mod.weight.float() * mod.scale[:, None]).to(dtype=x.dtype)
|
| 420 |
+
y = mod(x)
|
| 421 |
+
y_ref = F.linear(x, ref_w, mod.bias)
|
| 422 |
+
assert torch.equal(y, y_ref), (bias, dtype)
|
| 423 |
+
|
| 424 |
+
|
| 425 |
+
def test_is_quantizable_rule() -> None:
|
| 426 |
+
false_cases = [
|
| 427 |
+
("model.model.layers.1.mlp.gate.weight", (256, 2048)),
|
| 428 |
+
("model.model.layers.1.mlp.image_gate.weight", (256, 2048)),
|
| 429 |
+
("model.model.layers.1.mlp.audio_gate.weight", (256, 2048)),
|
| 430 |
+
("model.model.layers.1.mlp.gate.expert_bias", (256,)),
|
| 431 |
+
("model.lm_head.weight", (151936, 2048)),
|
| 432 |
+
("model.model.word_embeddings.weight", (151936, 2048)),
|
| 433 |
+
("vision.blocks.0.attn.qkv.weight", (3072, 1280)),
|
| 434 |
+
("model.model.layers.0.input_layernorm.weight", (2048,)),
|
| 435 |
+
("model.model.layers.0.post_attention_layernorm.weight", (2048,)),
|
| 436 |
+
("model.model.layers.0.attention.q_norm.weight", (128,)),
|
| 437 |
+
("model.model.layers.0.attention.k_norm.weight", (128,)),
|
| 438 |
+
("model.model.norm.weight", (2048,)),
|
| 439 |
+
("linear_proj.0.weight", (2048, 2048)),
|
| 440 |
+
("model.model.layers.0.attention.query_key_value.bias", (3072,)),
|
| 441 |
+
("model.model.layers.0.mlp.experts.0.gate_proj.bias", (512,)),
|
| 442 |
+
# Right leaf, wrong rank: not quantizable (the stream must reject it).
|
| 443 |
+
("model.model.layers.0.attention.query_key_value.weight", (3072,)),
|
| 444 |
+
("model.model.layers.0.mlp.gate_proj.weight", (1024, 2048, 1)),
|
| 445 |
+
]
|
| 446 |
+
true_cases = [
|
| 447 |
+
("model.model.layers.3.mlp.experts.3.gate_proj.weight", (512, 2048)),
|
| 448 |
+
("model.model.layers.3.mlp.shared_experts.down_proj.weight", (2048, 512)),
|
| 449 |
+
("model.model.layers.0.mlp.up_proj.weight", (512, 2048)),
|
| 450 |
+
("layers.0.mlp.up_proj.weight", (512, 2048)),
|
| 451 |
+
("model.model.layers.0.attention.query_key_value.weight", (3072, 2048)),
|
| 452 |
+
("model.model.layers.0.attention.dense.weight", (2048, 2048)),
|
| 453 |
+
("model.model.layers.0.mlp.gate_proj.weight", (512, 2048)),
|
| 454 |
+
("model.model.layers.0.mlp.down_proj.weight", (2048, 512)),
|
| 455 |
+
("model.model.layers.19.mlp.experts.255.up_proj.weight", (512, 2048)),
|
| 456 |
+
]
|
| 457 |
+
for name, shape in false_cases:
|
| 458 |
+
assert is_quantizable(name, shape) is False, name
|
| 459 |
+
for name, shape in true_cases:
|
| 460 |
+
assert is_quantizable(name, shape) is True, name
|
| 461 |
+
|
| 462 |
+
|
| 463 |
+
def _shard_groups(sd: dict[str, torch.Tensor]) -> set[str]:
|
| 464 |
+
"""One copy-tensor, or one weight+scale pair, is one unsplittable group."""
|
| 465 |
+
names = set(sd)
|
| 466 |
+
groups: set[str] = set()
|
| 467 |
+
for name in names:
|
| 468 |
+
if name.endswith(".scale") and name[: -len(".scale")] + ".weight" in names:
|
| 469 |
+
groups.add(name[: -len(".scale")])
|
| 470 |
+
elif name.endswith(".weight") and name[: -len(".weight")] + ".scale" in names:
|
| 471 |
+
groups.add(name[: -len(".weight")])
|
| 472 |
+
else:
|
| 473 |
+
groups.add(name)
|
| 474 |
+
return groups
|
| 475 |
+
|
| 476 |
+
|
| 477 |
+
def test_end_to_end_stream_and_load() -> None:
|
| 478 |
+
assert quantize_stream.MAX_SHARD_BYTES == 5 * 10**9
|
| 479 |
+
torch.manual_seed(3)
|
| 480 |
+
src_model = TinyMing().to(dtype=torch.bfloat16)
|
| 481 |
+
# Non-persistent rotary buffer is not part of the checkpoint.
|
| 482 |
+
assert "model.model.layers.0.attention.inv_freq" not in src_model.state_dict()
|
| 483 |
+
|
| 484 |
+
with tempfile.TemporaryDirectory(prefix="ming-int8-") as tmp:
|
| 485 |
+
root = Path(tmp)
|
| 486 |
+
src = root / "src"
|
| 487 |
+
dst = root / "dst"
|
| 488 |
+
_save_bf16_checkpoint(src_model, src)
|
| 489 |
+
limit = 2048
|
| 490 |
+
old = quantize_stream.MAX_SHARD_BYTES
|
| 491 |
+
quantize_stream.MAX_SHARD_BYTES = limit
|
| 492 |
+
try:
|
| 493 |
+
rc = quantize_stream.main([str(src), str(dst)])
|
| 494 |
+
finally:
|
| 495 |
+
quantize_stream.MAX_SHARD_BYTES = old
|
| 496 |
+
assert rc == 0, rc
|
| 497 |
+
assert quantize_stream.MAX_SHARD_BYTES == 5 * 10**9
|
| 498 |
+
|
| 499 |
+
# Sidecars copied verbatim; original index replaced.
|
| 500 |
+
assert (dst / "config.json").read_bytes() == (src / "config.json").read_bytes()
|
| 501 |
+
assert (dst / "extra" / "chat_template.jinja").read_bytes() == (
|
| 502 |
+
src / "extra" / "chat_template.jinja"
|
| 503 |
+
).read_bytes()
|
| 504 |
+
assert not (dst / "bf16-00001.safetensors").exists()
|
| 505 |
+
|
| 506 |
+
manifest = json.loads((dst / "int8_manifest.json").read_text(encoding="utf-8"))
|
| 507 |
+
assert manifest["format"] == "ming-int8-wo-v1"
|
| 508 |
+
assert manifest["scheme"] == (
|
| 509 |
+
"weight-only int8, per-output-channel symmetric, fp32 scales"
|
| 510 |
+
)
|
| 511 |
+
assert manifest["quantized_modules"] == sorted(EXPECTED_QUANT_MODULES)
|
| 512 |
+
for banned in MUST_NOT_QUANTIZE:
|
| 513 |
+
assert banned not in manifest["quantized_modules"], banned
|
| 514 |
+
|
| 515 |
+
index = json.loads((dst / "model.safetensors.index.json").read_text(encoding="utf-8"))
|
| 516 |
+
assert index["metadata"]["total_size"] == manifest["total_size"]
|
| 517 |
+
measured = manifest["measured"]
|
| 518 |
+
assert measured["tensors_quantized"] == len(EXPECTED_QUANT_MODULES)
|
| 519 |
+
assert measured["bytes_in"] == manifest["source_total_size"]
|
| 520 |
+
assert measured["bytes_out"] == manifest["total_size"]
|
| 521 |
+
assert measured["bytes_out"] < measured["bytes_in"]
|
| 522 |
+
n_out_keys = measured["tensors_copied"] + 2 * measured["tensors_quantized"]
|
| 523 |
+
assert len(index["weight_map"]) == n_out_keys
|
| 524 |
+
|
| 525 |
+
src_sd = _load_all(src)
|
| 526 |
+
dst_sd = _load_all(dst)
|
| 527 |
+
assert manifest["source_total_size"] == sum(
|
| 528 |
+
t.numel() * t.element_size() for t in src_sd.values()
|
| 529 |
+
)
|
| 530 |
+
assert manifest["total_size"] == sum(t.numel() * t.element_size() for t in dst_sd.values())
|
| 531 |
+
|
| 532 |
+
shard_names = sorted({*index["weight_map"].values()})
|
| 533 |
+
assert len(shard_names) >= 2, shard_names
|
| 534 |
+
for shard in shard_names:
|
| 535 |
+
shard_sd = load_file(str(dst / shard))
|
| 536 |
+
total = sum(t.numel() * t.element_size() for t in shard_sd.values())
|
| 537 |
+
if total > limit:
|
| 538 |
+
assert len(_shard_groups(shard_sd)) == 1, (shard, total, list(shard_sd))
|
| 539 |
+
|
| 540 |
+
errors = []
|
| 541 |
+
for name, src_t in src_sd.items():
|
| 542 |
+
if is_quantizable(name, tuple(src_t.shape)):
|
| 543 |
+
q = dst_sd[name]
|
| 544 |
+
scale_key = name[: -len("weight")] + "scale"
|
| 545 |
+
scale = dst_sd[scale_key]
|
| 546 |
+
assert q.dtype == torch.int8, name
|
| 547 |
+
assert scale.dtype == torch.float32, scale_key
|
| 548 |
+
q_ref, scale_ref = quantize_weight(src_t)
|
| 549 |
+
assert torch.equal(q, q_ref), name
|
| 550 |
+
assert torch.equal(scale, scale_ref), scale_key
|
| 551 |
+
errors.append((name, quantize_stream._relative_frobenius(src_t, q, scale)))
|
| 552 |
+
else:
|
| 553 |
+
assert name in dst_sd, name
|
| 554 |
+
assert dst_sd[name].dtype == src_t.dtype, (name, dst_sd[name].dtype, src_t.dtype)
|
| 555 |
+
assert torch.equal(dst_sd[name], src_t), name
|
| 556 |
+
# Router weights stayed BF16 and byte-identical (the gate vs gate_proj trap).
|
| 557 |
+
router = "model.model.layers.1.mlp.gate.weight"
|
| 558 |
+
assert dst_sd[router].dtype == torch.bfloat16
|
| 559 |
+
assert torch.equal(dst_sd[router], src_sd[router])
|
| 560 |
+
for suffix in ("image_gate.weight", "audio_gate.weight", "gate.expert_bias"):
|
| 561 |
+
key = f"model.model.layers.1.mlp.{suffix}"
|
| 562 |
+
assert torch.equal(dst_sd[key], src_sd[key]), key
|
| 563 |
+
|
| 564 |
+
vals = [e for _, e in errors]
|
| 565 |
+
assert measured["max_relative_error"] == max(vals)
|
| 566 |
+
assert measured["mean_relative_error"] == sum(vals) / len(vals)
|
| 567 |
+
assert measured["worst_tensor"] in dict(errors)
|
| 568 |
+
assert measured["max_relative_error"] == dict(errors)[measured["worst_tensor"]]
|
| 569 |
+
assert 0.0 <= measured["mean_relative_error"] <= measured["p99_relative_error"]
|
| 570 |
+
assert measured["p99_relative_error"] <= measured["max_relative_error"]
|
| 571 |
+
assert measured["max_relative_error"] < 0.05, measured
|
| 572 |
+
|
| 573 |
+
# Eager quant of the same BF16 bytes.
|
| 574 |
+
eager = TinyMing().to(dtype=torch.bfloat16)
|
| 575 |
+
incompatible = eager.load_state_dict(src_sd, strict=True)
|
| 576 |
+
assert not incompatible.missing_keys and not incompatible.unexpected_keys
|
| 577 |
+
_apply_int8_(eager)
|
| 578 |
+
|
| 579 |
+
loaded = _move_parameters_to_meta(TinyMing())
|
| 580 |
+
for layer in loaded.model.model.layers:
|
| 581 |
+
assert layer.attention.inv_freq.device.type == "cpu"
|
| 582 |
+
assert layer.attention.query_key_value.weight.device.type == "meta"
|
| 583 |
+
report = load_int8_mllm_(loaded, dst, "cpu")
|
| 584 |
+
assert report["modules_swapped"] == len(EXPECTED_QUANT_MODULES)
|
| 585 |
+
assert report["tensors_loaded"] == len(dst_sd)
|
| 586 |
+
assert report["bytes_loaded"] == manifest["total_size"]
|
| 587 |
+
_assert_no_meta(loaded)
|
| 588 |
+
for layer in loaded.model.model.layers:
|
| 589 |
+
assert layer.attention.inv_freq.device.type == "cpu"
|
| 590 |
+
assert layer.attention.inv_freq.dtype == torch.float32
|
| 591 |
+
for name in EXPECTED_QUANT_MODULES:
|
| 592 |
+
mod = loaded.get_submodule(name)
|
| 593 |
+
assert isinstance(mod, Int8Linear), name
|
| 594 |
+
assert mod.weight.dtype == torch.int8
|
| 595 |
+
assert mod.scale.dtype == torch.float32
|
| 596 |
+
|
| 597 |
+
eager.eval()
|
| 598 |
+
loaded.eval()
|
| 599 |
+
ids = torch.randint(0, VOCAB, (2, 6))
|
| 600 |
+
with torch.no_grad():
|
| 601 |
+
y_eager = eager(ids)
|
| 602 |
+
y_loaded = loaded(ids)
|
| 603 |
+
assert y_eager.dtype == y_loaded.dtype
|
| 604 |
+
assert torch.equal(y_eager, y_loaded), (y_eager - y_loaded).abs().max().item()
|
| 605 |
+
|
| 606 |
+
# A second run into a non-empty safetensors dir must fail loudly.
|
| 607 |
+
print(" re-running into a non-empty dst (expect error on stderr)", flush=True)
|
| 608 |
+
rc_again = quantize_stream.main([str(src), str(dst)])
|
| 609 |
+
assert rc_again == 1
|
| 610 |
+
|
| 611 |
+
|
| 612 |
+
def test_unknown_key_fails_loudly() -> None:
|
| 613 |
+
torch.manual_seed(4)
|
| 614 |
+
model = TinyMing().to(dtype=torch.bfloat16)
|
| 615 |
+
with tempfile.TemporaryDirectory(prefix="ming-int8-bad-") as tmp:
|
| 616 |
+
root = Path(tmp)
|
| 617 |
+
src = root / "src"
|
| 618 |
+
dst = root / "dst"
|
| 619 |
+
_save_bf16_checkpoint(model, src)
|
| 620 |
+
rc = quantize_stream.main([str(src), str(dst)])
|
| 621 |
+
assert rc == 0, rc
|
| 622 |
+
shard = next(dst.glob("*.safetensors"))
|
| 623 |
+
sd = load_file(str(shard))
|
| 624 |
+
sd["not.a.real.key"] = torch.zeros(4, dtype=torch.float32)
|
| 625 |
+
save_file(sd, str(shard))
|
| 626 |
+
loaded = _move_parameters_to_meta(TinyMing())
|
| 627 |
+
try:
|
| 628 |
+
load_int8_mllm_(loaded, dst, "cpu")
|
| 629 |
+
except RuntimeError as exc:
|
| 630 |
+
text = str(exc)
|
| 631 |
+
assert "unexpected" in text.lower(), text
|
| 632 |
+
assert "not.a.real.key" in text, text
|
| 633 |
+
print(f" caught RuntimeError: {text.splitlines()[0]}")
|
| 634 |
+
else:
|
| 635 |
+
raise AssertionError("load_int8_mllm_ returned instead of failing on an unknown key")
|
| 636 |
+
|
| 637 |
+
|
| 638 |
+
def main() -> int:
|
| 639 |
+
import safetensors
|
| 640 |
+
|
| 641 |
+
print(f"torch={torch.__version__} safetensors={safetensors.__version__}", flush=True)
|
| 642 |
+
tests = [
|
| 643 |
+
test_from_linear_roundtrip,
|
| 644 |
+
test_dtype_cast_keeps_scale_fp32,
|
| 645 |
+
test_forward_matches_reference,
|
| 646 |
+
test_is_quantizable_rule,
|
| 647 |
+
test_end_to_end_stream_and_load,
|
| 648 |
+
test_unknown_key_fails_loudly,
|
| 649 |
+
]
|
| 650 |
+
failed = 0
|
| 651 |
+
for fn in tests:
|
| 652 |
+
try:
|
| 653 |
+
fn()
|
| 654 |
+
except Exception:
|
| 655 |
+
failed += 1
|
| 656 |
+
print(f"FAIL {fn.__name__}", flush=True)
|
| 657 |
+
traceback.print_exc()
|
| 658 |
+
else:
|
| 659 |
+
print(f"PASS {fn.__name__}", flush=True)
|
| 660 |
+
print(f"{len(tests) - failed} passed, {failed} failed", flush=True)
|
| 661 |
+
return 1 if failed else 0
|
| 662 |
+
|
| 663 |
+
|
| 664 |
+
if __name__ == "__main__":
|
| 665 |
+
sys.exit(main())
|
code/tests/__init__.py
ADDED
|
File without changes
|
code/tests/test_infer_cli.py
ADDED
|
@@ -0,0 +1,226 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import json
|
| 2 |
+
from pathlib import Path
|
| 3 |
+
import subprocess
|
| 4 |
+
import sys
|
| 5 |
+
import tempfile
|
| 6 |
+
import unittest
|
| 7 |
+
from unittest.mock import patch
|
| 8 |
+
|
| 9 |
+
from infer import parse_args, resolve_task_resolution
|
| 10 |
+
|
| 11 |
+
|
| 12 |
+
REPOSITORY = Path(__file__).resolve().parents[1]
|
| 13 |
+
INFER = REPOSITORY / "infer.py"
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
class InferenceCliTest(unittest.TestCase):
|
| 17 |
+
def _model_directory(self, profile):
|
| 18 |
+
temporary = tempfile.TemporaryDirectory()
|
| 19 |
+
model_directory = Path(temporary.name)
|
| 20 |
+
(model_directory / "inference_profile.json").write_text(
|
| 21 |
+
json.dumps(profile), encoding="utf-8"
|
| 22 |
+
)
|
| 23 |
+
return temporary, model_directory
|
| 24 |
+
|
| 25 |
+
def test_cli_defaults_to_one_gpu(self):
|
| 26 |
+
with patch.object(
|
| 27 |
+
sys,
|
| 28 |
+
"argv",
|
| 29 |
+
["infer.py", "--model", "checkpoint", "--task", "text-to-image"],
|
| 30 |
+
):
|
| 31 |
+
args = parse_args()
|
| 32 |
+
self.assertEqual(args.device, "cuda:0")
|
| 33 |
+
self.assertEqual(args.device_map, "balanced")
|
| 34 |
+
self.assertEqual(args.num_gpus, 1)
|
| 35 |
+
self.assertIsNone(args.resolution)
|
| 36 |
+
|
| 37 |
+
def test_task_resolution_defaults_and_snapping(self):
|
| 38 |
+
self.assertEqual(resolve_task_resolution("text-to-image", None), 2048)
|
| 39 |
+
self.assertEqual(resolve_task_resolution("text-to-image", 1200), 1024)
|
| 40 |
+
self.assertEqual(resolve_task_resolution("text-to-image", 1800), 2048)
|
| 41 |
+
self.assertEqual(resolve_task_resolution("text-to-image", 1536), 1024)
|
| 42 |
+
|
| 43 |
+
self.assertEqual(resolve_task_resolution("image-edit", None), 1024)
|
| 44 |
+
self.assertEqual(resolve_task_resolution("image-edit", 512), 1024)
|
| 45 |
+
self.assertEqual(resolve_task_resolution("image-edit", 2048), 1024)
|
| 46 |
+
|
| 47 |
+
self.assertEqual(resolve_task_resolution("layer-decompose", None), 1024)
|
| 48 |
+
self.assertEqual(resolve_task_resolution("layer-decompose", 600), 512)
|
| 49 |
+
self.assertEqual(resolve_task_resolution("layer-decompose", 900), 1024)
|
| 50 |
+
self.assertEqual(resolve_task_resolution("layer-decompose", 768), 512)
|
| 51 |
+
|
| 52 |
+
def test_task_resolution_rejects_non_positive_values(self):
|
| 53 |
+
for value in (0, -1):
|
| 54 |
+
with self.subTest(value=value):
|
| 55 |
+
with self.assertRaisesRegex(ValueError, "positive integer"):
|
| 56 |
+
resolve_task_resolution("text-to-image", value)
|
| 57 |
+
|
| 58 |
+
def test_validate_only_accepts_local_generation_checkpoint(self):
|
| 59 |
+
temporary, model_directory = self._model_directory(
|
| 60 |
+
{
|
| 61 |
+
"schema_version": 1,
|
| 62 |
+
"inference_profile": "generation_edit",
|
| 63 |
+
"alignment_padding_mode": "zero_masked",
|
| 64 |
+
"multi_frame_output": False,
|
| 65 |
+
"vae_input_channels": 4,
|
| 66 |
+
"vae_sample_mode": "argmax",
|
| 67 |
+
}
|
| 68 |
+
)
|
| 69 |
+
self.addCleanup(temporary.cleanup)
|
| 70 |
+
result = subprocess.run(
|
| 71 |
+
[
|
| 72 |
+
sys.executable,
|
| 73 |
+
str(INFER),
|
| 74 |
+
"--model",
|
| 75 |
+
str(model_directory),
|
| 76 |
+
"--task",
|
| 77 |
+
"text-to-image",
|
| 78 |
+
"--prompt",
|
| 79 |
+
"test",
|
| 80 |
+
"--validate-only",
|
| 81 |
+
],
|
| 82 |
+
check=True,
|
| 83 |
+
capture_output=True,
|
| 84 |
+
text=True,
|
| 85 |
+
)
|
| 86 |
+
payload = json.loads(result.stdout)
|
| 87 |
+
self.assertEqual(payload["task"], "text-to-image")
|
| 88 |
+
self.assertEqual(payload["sampling"], {"steps": 12, "cfg": 1.0})
|
| 89 |
+
self.assertEqual(
|
| 90 |
+
payload["resolution"], {"requested": None, "effective": 2048}
|
| 91 |
+
)
|
| 92 |
+
|
| 93 |
+
def test_validate_only_accepts_long_literal_prompt(self):
|
| 94 |
+
temporary, model_directory = self._model_directory(
|
| 95 |
+
{
|
| 96 |
+
"schema_version": 1,
|
| 97 |
+
"inference_profile": "generation_edit",
|
| 98 |
+
"alignment_padding_mode": "zero_masked",
|
| 99 |
+
"multi_frame_output": False,
|
| 100 |
+
"vae_input_channels": 4,
|
| 101 |
+
"vae_sample_mode": "argmax",
|
| 102 |
+
}
|
| 103 |
+
)
|
| 104 |
+
self.addCleanup(temporary.cleanup)
|
| 105 |
+
long_prompt = "Create a detailed ocean research poster. " * 40
|
| 106 |
+
result = subprocess.run(
|
| 107 |
+
[
|
| 108 |
+
sys.executable,
|
| 109 |
+
str(INFER),
|
| 110 |
+
"--model",
|
| 111 |
+
str(model_directory),
|
| 112 |
+
"--task",
|
| 113 |
+
"text-to-image",
|
| 114 |
+
"--prompt",
|
| 115 |
+
long_prompt,
|
| 116 |
+
"--validate-only",
|
| 117 |
+
],
|
| 118 |
+
check=True,
|
| 119 |
+
capture_output=True,
|
| 120 |
+
text=True,
|
| 121 |
+
)
|
| 122 |
+
payload = json.loads(result.stdout)
|
| 123 |
+
self.assertEqual(payload["task"], "text-to-image")
|
| 124 |
+
self.assertEqual(payload["sampling"], {"steps": 12, "cfg": 1.0})
|
| 125 |
+
|
| 126 |
+
def test_validate_only_uses_layer_defaults_and_accepts_overrides(self):
|
| 127 |
+
temporary, model_directory = self._model_directory(
|
| 128 |
+
{
|
| 129 |
+
"schema_version": 1,
|
| 130 |
+
"inference_profile": "layer_decompose",
|
| 131 |
+
"alignment_padding_mode": "learned",
|
| 132 |
+
"multi_frame_output": True,
|
| 133 |
+
"vae_input_channels": 4,
|
| 134 |
+
"vae_sample_mode": "argmax",
|
| 135 |
+
}
|
| 136 |
+
)
|
| 137 |
+
self.addCleanup(temporary.cleanup)
|
| 138 |
+
input_image = model_directory / "input.png"
|
| 139 |
+
input_image.write_bytes(b"validation-only")
|
| 140 |
+
|
| 141 |
+
default_result = subprocess.run(
|
| 142 |
+
[
|
| 143 |
+
sys.executable,
|
| 144 |
+
str(INFER),
|
| 145 |
+
"--model",
|
| 146 |
+
str(model_directory),
|
| 147 |
+
"--task",
|
| 148 |
+
"layer-decompose",
|
| 149 |
+
"--input-image",
|
| 150 |
+
str(input_image),
|
| 151 |
+
"--num-layers",
|
| 152 |
+
"4",
|
| 153 |
+
"--validate-only",
|
| 154 |
+
],
|
| 155 |
+
check=True,
|
| 156 |
+
capture_output=True,
|
| 157 |
+
text=True,
|
| 158 |
+
)
|
| 159 |
+
self.assertEqual(
|
| 160 |
+
json.loads(default_result.stdout)["sampling"],
|
| 161 |
+
{"steps": 12, "cfg": 2.0},
|
| 162 |
+
)
|
| 163 |
+
self.assertEqual(
|
| 164 |
+
json.loads(default_result.stdout)["resolution"],
|
| 165 |
+
{"requested": None, "effective": 1024},
|
| 166 |
+
)
|
| 167 |
+
|
| 168 |
+
override_result = subprocess.run(
|
| 169 |
+
[
|
| 170 |
+
sys.executable,
|
| 171 |
+
str(INFER),
|
| 172 |
+
"--model",
|
| 173 |
+
str(model_directory),
|
| 174 |
+
"--task",
|
| 175 |
+
"layer-decompose",
|
| 176 |
+
"--input-image",
|
| 177 |
+
str(input_image),
|
| 178 |
+
"--steps",
|
| 179 |
+
"16",
|
| 180 |
+
"--cfg",
|
| 181 |
+
"1.25",
|
| 182 |
+
"--validate-only",
|
| 183 |
+
],
|
| 184 |
+
check=True,
|
| 185 |
+
capture_output=True,
|
| 186 |
+
text=True,
|
| 187 |
+
)
|
| 188 |
+
self.assertEqual(
|
| 189 |
+
json.loads(override_result.stdout)["sampling"],
|
| 190 |
+
{"steps": 16, "cfg": 1.25},
|
| 191 |
+
)
|
| 192 |
+
|
| 193 |
+
def test_validate_only_rejects_wrong_checkpoint_family(self):
|
| 194 |
+
temporary, model_directory = self._model_directory(
|
| 195 |
+
{
|
| 196 |
+
"schema_version": 1,
|
| 197 |
+
"inference_profile": "layer_decompose",
|
| 198 |
+
"alignment_padding_mode": "learned",
|
| 199 |
+
"multi_frame_output": True,
|
| 200 |
+
"vae_input_channels": 4,
|
| 201 |
+
"vae_sample_mode": "argmax",
|
| 202 |
+
}
|
| 203 |
+
)
|
| 204 |
+
self.addCleanup(temporary.cleanup)
|
| 205 |
+
result = subprocess.run(
|
| 206 |
+
[
|
| 207 |
+
sys.executable,
|
| 208 |
+
str(INFER),
|
| 209 |
+
"--model",
|
| 210 |
+
str(model_directory),
|
| 211 |
+
"--task",
|
| 212 |
+
"text-to-image",
|
| 213 |
+
"--prompt",
|
| 214 |
+
"test",
|
| 215 |
+
"--validate-only",
|
| 216 |
+
],
|
| 217 |
+
check=False,
|
| 218 |
+
capture_output=True,
|
| 219 |
+
text=True,
|
| 220 |
+
)
|
| 221 |
+
self.assertNotEqual(result.returncode, 0)
|
| 222 |
+
self.assertIn("generation_edit checkpoint", result.stderr)
|
| 223 |
+
|
| 224 |
+
|
| 225 |
+
if __name__ == "__main__":
|
| 226 |
+
unittest.main()
|
code/tests/test_inference_profile.py
ADDED
|
@@ -0,0 +1,257 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import json
|
| 2 |
+
import tempfile
|
| 3 |
+
from pathlib import Path
|
| 4 |
+
import unittest
|
| 5 |
+
|
| 6 |
+
from inference_profile import (
|
| 7 |
+
InferenceProfile,
|
| 8 |
+
InferenceProfileError,
|
| 9 |
+
load_checkpoint_capabilities,
|
| 10 |
+
load_inference_profile,
|
| 11 |
+
resolve_model_directory,
|
| 12 |
+
)
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
GENERATION = {
|
| 16 |
+
"schema_version": 1,
|
| 17 |
+
"inference_profile": "generation_edit",
|
| 18 |
+
"alignment_padding_mode": "zero_masked",
|
| 19 |
+
"multi_frame_output": False,
|
| 20 |
+
"vae_input_channels": 4,
|
| 21 |
+
"vae_sample_mode": "argmax",
|
| 22 |
+
}
|
| 23 |
+
|
| 24 |
+
LAYER = {
|
| 25 |
+
"schema_version": 1,
|
| 26 |
+
"inference_profile": "layer_decompose",
|
| 27 |
+
"alignment_padding_mode": "learned",
|
| 28 |
+
"multi_frame_output": True,
|
| 29 |
+
"vae_input_channels": 4,
|
| 30 |
+
"vae_sample_mode": "argmax",
|
| 31 |
+
}
|
| 32 |
+
|
| 33 |
+
|
| 34 |
+
class InferenceProfileTest(unittest.TestCase):
|
| 35 |
+
def test_all_profile_fields_are_required(self):
|
| 36 |
+
for field in GENERATION:
|
| 37 |
+
raw = dict(GENERATION)
|
| 38 |
+
raw.pop(field)
|
| 39 |
+
with self.assertRaisesRegex(InferenceProfileError, "missing required fields"):
|
| 40 |
+
InferenceProfile.from_dict(raw)
|
| 41 |
+
|
| 42 |
+
def test_profile_rejects_unknown_fields(self):
|
| 43 |
+
raw = dict(GENERATION, inferred_from_directory_name=True)
|
| 44 |
+
with self.assertRaisesRegex(InferenceProfileError, "unsupported fields"):
|
| 45 |
+
InferenceProfile.from_dict(raw)
|
| 46 |
+
|
| 47 |
+
def test_generation_profile_task_matrix(self):
|
| 48 |
+
profile = InferenceProfile.from_dict(GENERATION)
|
| 49 |
+
self.assertEqual(profile.resolve_sampling_parameters().steps, 12)
|
| 50 |
+
self.assertEqual(profile.resolve_sampling_parameters().cfg, 1.0)
|
| 51 |
+
profile.validate_task("text-to-image", has_reference_image=False)
|
| 52 |
+
profile.validate_task("image-edit", has_reference_image=True)
|
| 53 |
+
with self.assertRaisesRegex(InferenceProfileError, "layer_decompose checkpoint"):
|
| 54 |
+
profile.validate_task("layer-decompose", has_reference_image=True, num_layers=4)
|
| 55 |
+
|
| 56 |
+
def test_layer_profile_task_matrix(self):
|
| 57 |
+
profile = InferenceProfile.from_dict(LAYER)
|
| 58 |
+
self.assertEqual(profile.resolve_sampling_parameters().steps, 12)
|
| 59 |
+
self.assertEqual(profile.resolve_sampling_parameters().cfg, 2.0)
|
| 60 |
+
profile.validate_task("layer-decompose", has_reference_image=True, num_layers=4)
|
| 61 |
+
with self.assertRaisesRegex(InferenceProfileError, "generation_edit checkpoint"):
|
| 62 |
+
profile.validate_task("image-edit", has_reference_image=True)
|
| 63 |
+
|
| 64 |
+
def test_generation_profile_requires_qwen_vae_contract(self):
|
| 65 |
+
with self.assertRaisesRegex(InferenceProfileError, "vae_input_channels=4"):
|
| 66 |
+
InferenceProfile.from_dict(dict(GENERATION, vae_input_channels=3))
|
| 67 |
+
with self.assertRaisesRegex(InferenceProfileError, "vae_sample_mode='argmax'"):
|
| 68 |
+
InferenceProfile.from_dict(dict(GENERATION, vae_sample_mode="sample"))
|
| 69 |
+
|
| 70 |
+
def test_layer_profile_requires_qwen_vae_contract(self):
|
| 71 |
+
with self.assertRaisesRegex(InferenceProfileError, "vae_sample_mode='argmax'"):
|
| 72 |
+
InferenceProfile.from_dict(dict(LAYER, vae_sample_mode="sample"))
|
| 73 |
+
|
| 74 |
+
def test_sampling_overrides_are_validated(self):
|
| 75 |
+
profile = InferenceProfile.from_dict(GENERATION)
|
| 76 |
+
resolved = profile.resolve_sampling_parameters(steps=18, cfg=1.5)
|
| 77 |
+
self.assertEqual((resolved.steps, resolved.cfg), (18, 1.5))
|
| 78 |
+
with self.assertRaisesRegex(InferenceProfileError, "steps"):
|
| 79 |
+
profile.resolve_sampling_parameters(steps=0)
|
| 80 |
+
with self.assertRaisesRegex(InferenceProfileError, "CFG"):
|
| 81 |
+
profile.resolve_sampling_parameters(cfg=float("inf"))
|
| 82 |
+
|
| 83 |
+
def test_profile_is_loaded_from_local_model_directory(self):
|
| 84 |
+
with self.subTest("local profile"):
|
| 85 |
+
import tempfile
|
| 86 |
+
from pathlib import Path
|
| 87 |
+
|
| 88 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 89 |
+
model_directory = Path(directory)
|
| 90 |
+
(model_directory / "inference_profile.json").write_text(
|
| 91 |
+
json.dumps(LAYER), encoding="utf-8"
|
| 92 |
+
)
|
| 93 |
+
self.assertEqual(
|
| 94 |
+
load_inference_profile(model_directory).inference_profile,
|
| 95 |
+
"layer_decompose",
|
| 96 |
+
)
|
| 97 |
+
self.assertEqual(
|
| 98 |
+
resolve_model_directory(model_directory), model_directory.resolve()
|
| 99 |
+
)
|
| 100 |
+
|
| 101 |
+
def test_missing_profile_is_an_error(self):
|
| 102 |
+
import tempfile
|
| 103 |
+
|
| 104 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 105 |
+
with self.assertRaisesRegex(InferenceProfileError, "must contain"):
|
| 106 |
+
load_inference_profile(directory)
|
| 107 |
+
|
| 108 |
+
def test_missing_absolute_local_path_is_not_treated_as_hub_id(self):
|
| 109 |
+
import tempfile
|
| 110 |
+
from pathlib import Path
|
| 111 |
+
|
| 112 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 113 |
+
with self.assertRaises(FileNotFoundError):
|
| 114 |
+
resolve_model_directory(Path(directory) / "missing")
|
| 115 |
+
|
| 116 |
+
|
| 117 |
+
VAE_QWEN_4CH = {"_class_name": "AutoencoderKLQwenImage", "input_channels": 4}
|
| 118 |
+
|
| 119 |
+
|
| 120 |
+
def build_component_package(
|
| 121 |
+
root: Path,
|
| 122 |
+
transformer_extra=None,
|
| 123 |
+
vae=None,
|
| 124 |
+
profile=None,
|
| 125 |
+
) -> None:
|
| 126 |
+
(root / "transformer").mkdir(parents=True, exist_ok=True)
|
| 127 |
+
(root / "vae").mkdir(parents=True, exist_ok=True)
|
| 128 |
+
transformer = {"_class_name": "DiffusionTransformer", "dim": 4}
|
| 129 |
+
transformer.update(transformer_extra or {})
|
| 130 |
+
(root / "transformer" / "config.json").write_text(json.dumps(transformer))
|
| 131 |
+
(root / "vae" / "config.json").write_text(json.dumps(vae or VAE_QWEN_4CH))
|
| 132 |
+
if profile is not None:
|
| 133 |
+
(root / "inference_profile.json").write_text(json.dumps(profile))
|
| 134 |
+
|
| 135 |
+
|
| 136 |
+
class ComponentCapabilityTest(unittest.TestCase):
|
| 137 |
+
def capabilities(self, **kwargs):
|
| 138 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 139 |
+
root = Path(directory)
|
| 140 |
+
build_component_package(root, **kwargs)
|
| 141 |
+
return load_checkpoint_capabilities(root)
|
| 142 |
+
|
| 143 |
+
def test_generation_pair_without_profile(self):
|
| 144 |
+
profile = self.capabilities(
|
| 145 |
+
transformer_extra={
|
| 146 |
+
"alignment_padding_mode": "zero_masked",
|
| 147 |
+
"multi_frame_output": False,
|
| 148 |
+
}
|
| 149 |
+
)
|
| 150 |
+
self.assertEqual(profile.inference_profile, "generation_edit")
|
| 151 |
+
self.assertEqual(profile.vae_input_channels, 4)
|
| 152 |
+
self.assertEqual(profile.vae_sample_mode, "argmax")
|
| 153 |
+
self.assertEqual(profile.resolve_sampling_parameters().steps, 12)
|
| 154 |
+
self.assertEqual(profile.resolve_sampling_parameters().cfg, 1.0)
|
| 155 |
+
|
| 156 |
+
def test_layer_pair_without_profile(self):
|
| 157 |
+
profile = self.capabilities(
|
| 158 |
+
transformer_extra={
|
| 159 |
+
"alignment_padding_mode": "learned",
|
| 160 |
+
"multi_frame_output": True,
|
| 161 |
+
}
|
| 162 |
+
)
|
| 163 |
+
self.assertEqual(profile.inference_profile, "layer_decompose")
|
| 164 |
+
self.assertEqual(profile.resolve_sampling_parameters().cfg, 2.0)
|
| 165 |
+
|
| 166 |
+
def test_partial_pair_is_rejected(self):
|
| 167 |
+
for field in ("alignment_padding_mode", "multi_frame_output"):
|
| 168 |
+
with self.subTest(only=field):
|
| 169 |
+
pair = {
|
| 170 |
+
"alignment_padding_mode": "zero_masked",
|
| 171 |
+
"multi_frame_output": False,
|
| 172 |
+
}
|
| 173 |
+
with self.assertRaisesRegex(InferenceProfileError, "declared together"):
|
| 174 |
+
self.capabilities(transformer_extra={field: pair[field]})
|
| 175 |
+
|
| 176 |
+
def test_every_invalid_pair_is_rejected(self):
|
| 177 |
+
invalid = [
|
| 178 |
+
{"alignment_padding_mode": "zero_masked", "multi_frame_output": True},
|
| 179 |
+
{"alignment_padding_mode": "learned", "multi_frame_output": False},
|
| 180 |
+
{"alignment_padding_mode": "zero", "multi_frame_output": False},
|
| 181 |
+
{"alignment_padding_mode": "learned", "multi_frame_output": 1},
|
| 182 |
+
{"alignment_padding_mode": None, "multi_frame_output": False},
|
| 183 |
+
]
|
| 184 |
+
for pair in invalid:
|
| 185 |
+
with self.subTest(pair=pair):
|
| 186 |
+
with self.assertRaises(InferenceProfileError):
|
| 187 |
+
self.capabilities(transformer_extra=pair)
|
| 188 |
+
|
| 189 |
+
def test_vae_class_must_be_qwen(self):
|
| 190 |
+
with self.assertRaisesRegex(InferenceProfileError, "AutoencoderKLQwenImage"):
|
| 191 |
+
self.capabilities(
|
| 192 |
+
transformer_extra={
|
| 193 |
+
"alignment_padding_mode": "zero_masked",
|
| 194 |
+
"multi_frame_output": False,
|
| 195 |
+
},
|
| 196 |
+
vae={"_class_name": "AutoencoderKL", "in_channels": 4},
|
| 197 |
+
)
|
| 198 |
+
|
| 199 |
+
def test_vae_channel_fields_must_agree_and_be_four(self):
|
| 200 |
+
base = {"alignment_padding_mode": "zero_masked", "multi_frame_output": False}
|
| 201 |
+
with self.assertRaisesRegex(InferenceProfileError, "disagree"):
|
| 202 |
+
self.capabilities(
|
| 203 |
+
transformer_extra=base,
|
| 204 |
+
vae=dict(VAE_QWEN_4CH, in_channels=16),
|
| 205 |
+
)
|
| 206 |
+
with self.assertRaisesRegex(InferenceProfileError, "4-channel"):
|
| 207 |
+
self.capabilities(
|
| 208 |
+
transformer_extra=base,
|
| 209 |
+
vae={"_class_name": "AutoencoderKLQwenImage", "input_channels": 3},
|
| 210 |
+
)
|
| 211 |
+
with self.assertRaisesRegex(InferenceProfileError, "must declare"):
|
| 212 |
+
self.capabilities(
|
| 213 |
+
transformer_extra=base,
|
| 214 |
+
vae={"_class_name": "AutoencoderKLQwenImage"},
|
| 215 |
+
)
|
| 216 |
+
# in_channels alone is accepted when it agrees by itself.
|
| 217 |
+
profile = self.capabilities(
|
| 218 |
+
transformer_extra=base,
|
| 219 |
+
vae={"_class_name": "AutoencoderKLQwenImage", "in_channels": 4},
|
| 220 |
+
)
|
| 221 |
+
self.assertEqual(profile.vae_input_channels, 4)
|
| 222 |
+
|
| 223 |
+
def test_legacy_profile_fallback(self):
|
| 224 |
+
profile = self.capabilities(profile=LAYER)
|
| 225 |
+
self.assertEqual(profile.inference_profile, "layer_decompose")
|
| 226 |
+
self.assertEqual(profile.alignment_padding_mode, "learned")
|
| 227 |
+
|
| 228 |
+
def test_legacy_fallback_requires_profile_file(self):
|
| 229 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 230 |
+
root = Path(directory)
|
| 231 |
+
build_component_package(root)
|
| 232 |
+
with self.assertRaisesRegex(InferenceProfileError, "must contain"):
|
| 233 |
+
load_checkpoint_capabilities(root)
|
| 234 |
+
|
| 235 |
+
def test_component_fields_and_agreeing_legacy_profile(self):
|
| 236 |
+
profile = self.capabilities(
|
| 237 |
+
transformer_extra={
|
| 238 |
+
"alignment_padding_mode": "zero_masked",
|
| 239 |
+
"multi_frame_output": False,
|
| 240 |
+
},
|
| 241 |
+
profile=GENERATION,
|
| 242 |
+
)
|
| 243 |
+
self.assertEqual(profile.inference_profile, "generation_edit")
|
| 244 |
+
|
| 245 |
+
def test_component_fields_disagreeing_with_legacy_profile(self):
|
| 246 |
+
with self.assertRaisesRegex(InferenceProfileError, "disagree"):
|
| 247 |
+
self.capabilities(
|
| 248 |
+
transformer_extra={
|
| 249 |
+
"alignment_padding_mode": "learned",
|
| 250 |
+
"multi_frame_output": True,
|
| 251 |
+
},
|
| 252 |
+
profile=GENERATION,
|
| 253 |
+
)
|
| 254 |
+
|
| 255 |
+
|
| 256 |
+
if __name__ == "__main__":
|
| 257 |
+
unittest.main()
|
code/tests/test_inference_smoke.py
ADDED
|
@@ -0,0 +1,206 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Optional end-to-end GPU smoke tests for the maintained demo cases.
|
| 2 |
+
|
| 3 |
+
Required environment variables:
|
| 4 |
+
|
| 5 |
+
- MING_GENERATION_MODEL
|
| 6 |
+
- MING_LAYER_MODEL
|
| 7 |
+
|
| 8 |
+
The model variables may be local directories or Hugging Face Hub IDs.
|
| 9 |
+
|
| 10 |
+
Optional environment variables:
|
| 11 |
+
|
| 12 |
+
- MING_SMOKE_OUTPUT_DIR: keep outputs under this directory (created when
|
| 13 |
+
missing) instead of a temporary directory.
|
| 14 |
+
- MING_SMOKE_MODE: "short" (default) runs the two-step probes only;
|
| 15 |
+
"full" additionally runs the default-parameter acceptance cases.
|
| 16 |
+
- MING_SMOKE_DEVICE, MING_SMOKE_DEVICE_MAP, MING_SMOKE_NUM_GPUS,
|
| 17 |
+
MING_SMOKE_DTYPE and MING_SMOKE_ATTN_IMPLEMENTATION are forwarded to
|
| 18 |
+
infer.py. The smoke defaults to the validated single-GPU layout in BF16
|
| 19 |
+
and FlashAttention 2; set MING_SMOKE_NUM_GPUS (e.g. 8) for a multi-GPU
|
| 20 |
+
run.
|
| 21 |
+
|
| 22 |
+
Text-to-image and layer decomposition use the same assets displayed in the
|
| 23 |
+
public README. The image-edit compatibility probe keeps its established input
|
| 24 |
+
and prompt.
|
| 25 |
+
"""
|
| 26 |
+
|
| 27 |
+
import json
|
| 28 |
+
import os
|
| 29 |
+
from pathlib import Path
|
| 30 |
+
import subprocess
|
| 31 |
+
import sys
|
| 32 |
+
import tempfile
|
| 33 |
+
import unittest
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
REPOSITORY = Path(__file__).resolve().parents[1]
|
| 37 |
+
INFER = REPOSITORY / "infer.py"
|
| 38 |
+
T2I_PROMPT = REPOSITORY / "assets" / "t2i_four_seasons_cabin_prompt.json"
|
| 39 |
+
IMAGE_EDIT_INPUT = REPOSITORY / "tests" / "assets" / "smoke_input.png"
|
| 40 |
+
IMAGE_EDIT_PROMPT = "Change the background to blue"
|
| 41 |
+
LAYER_INPUT = REPOSITORY / "assets" / "layer_samples" / "card_making_input.png"
|
| 42 |
+
LAYER_PROMPT = REPOSITORY / "assets" / "layer_samples" / "card_making_prompt.txt"
|
| 43 |
+
LAYER_COUNT = 6
|
| 44 |
+
|
| 45 |
+
|
| 46 |
+
class SmokeAssetContractTest(unittest.TestCase):
|
| 47 |
+
def test_smoke_assets_are_present_and_well_formed(self):
|
| 48 |
+
for path in (T2I_PROMPT, IMAGE_EDIT_INPUT, LAYER_INPUT, LAYER_PROMPT):
|
| 49 |
+
self.assertTrue(path.is_file(), path)
|
| 50 |
+
|
| 51 |
+
with T2I_PROMPT.open(encoding="utf-8") as handle:
|
| 52 |
+
structured_prompt = json.load(handle)
|
| 53 |
+
self.assertEqual(set(structured_prompt), {"canvas_settings", "layers"})
|
| 54 |
+
|
| 55 |
+
layer_prompt = LAYER_PROMPT.read_text(encoding="utf-8")
|
| 56 |
+
self.assertIn(f"Number of layers: {LAYER_COUNT}", layer_prompt)
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
def _smoke_output_root():
|
| 60 |
+
value = os.environ.get("MING_SMOKE_OUTPUT_DIR")
|
| 61 |
+
return Path(value).expanduser().resolve() if value else None
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
@unittest.skipUnless(
|
| 65 |
+
os.environ.get("MING_GENERATION_MODEL")
|
| 66 |
+
and os.environ.get("MING_LAYER_MODEL"),
|
| 67 |
+
"set MING_GENERATION_MODEL and MING_LAYER_MODEL",
|
| 68 |
+
)
|
| 69 |
+
class InferenceSmokeTest(unittest.TestCase):
|
| 70 |
+
def _run(self, *arguments, steps=2, resolution=None):
|
| 71 |
+
command = [
|
| 72 |
+
sys.executable,
|
| 73 |
+
str(INFER),
|
| 74 |
+
*map(str, arguments),
|
| 75 |
+
"--seed",
|
| 76 |
+
"42",
|
| 77 |
+
"--device",
|
| 78 |
+
os.environ.get("MING_SMOKE_DEVICE", "cuda:0"),
|
| 79 |
+
"--device-map",
|
| 80 |
+
os.environ.get("MING_SMOKE_DEVICE_MAP", "balanced"),
|
| 81 |
+
"--num-gpus",
|
| 82 |
+
os.environ.get("MING_SMOKE_NUM_GPUS", "1"),
|
| 83 |
+
"--dtype",
|
| 84 |
+
os.environ.get("MING_SMOKE_DTYPE", "bfloat16"),
|
| 85 |
+
"--attn-implementation",
|
| 86 |
+
os.environ.get("MING_SMOKE_ATTN_IMPLEMENTATION", "flash_attention_2"),
|
| 87 |
+
]
|
| 88 |
+
if resolution is not None:
|
| 89 |
+
command += ["--resolution", str(resolution)]
|
| 90 |
+
if steps is not None:
|
| 91 |
+
command += ["--steps", str(steps)]
|
| 92 |
+
subprocess.run(command, cwd=REPOSITORY, check=True)
|
| 93 |
+
|
| 94 |
+
def _output_root(self, test_case_dir):
|
| 95 |
+
configured = _smoke_output_root()
|
| 96 |
+
if configured is not None:
|
| 97 |
+
return configured / test_case_dir
|
| 98 |
+
return Path(self._temporary_directory.name) / test_case_dir
|
| 99 |
+
|
| 100 |
+
def setUp(self):
|
| 101 |
+
self._temporary_directory = (
|
| 102 |
+
tempfile.TemporaryDirectory() if _smoke_output_root() is None else None
|
| 103 |
+
)
|
| 104 |
+
self.generation_model = os.environ["MING_GENERATION_MODEL"]
|
| 105 |
+
self.layer_model = os.environ["MING_LAYER_MODEL"]
|
| 106 |
+
for path in (T2I_PROMPT, IMAGE_EDIT_INPUT, LAYER_INPUT, LAYER_PROMPT):
|
| 107 |
+
self.assertTrue(path.is_file(), path)
|
| 108 |
+
|
| 109 |
+
def tearDown(self):
|
| 110 |
+
if self._temporary_directory is not None:
|
| 111 |
+
self._temporary_directory.cleanup()
|
| 112 |
+
|
| 113 |
+
def _assert_png_set(self, directory, count, mode=None):
|
| 114 |
+
from PIL import Image
|
| 115 |
+
|
| 116 |
+
paths = sorted(Path(directory).glob("*.png"))
|
| 117 |
+
self.assertEqual(len(paths), count, f"{directory}: {paths}")
|
| 118 |
+
pixels = []
|
| 119 |
+
for path in paths:
|
| 120 |
+
with Image.open(path) as image:
|
| 121 |
+
if mode is not None:
|
| 122 |
+
self.assertEqual(image.mode, mode, path)
|
| 123 |
+
sample = image.convert("RGBA")
|
| 124 |
+
pixels.append(sample.tobytes())
|
| 125 |
+
extrema = sample.getextrema()
|
| 126 |
+
for channel, (low, high) in enumerate(extrema):
|
| 127 |
+
self.assertGreater(
|
| 128 |
+
high, low, f"{path} channel {channel} is constant"
|
| 129 |
+
)
|
| 130 |
+
return paths, pixels
|
| 131 |
+
|
| 132 |
+
def _assert_showcase_layers(self, directory):
|
| 133 |
+
from PIL import Image
|
| 134 |
+
|
| 135 |
+
paths, pixels = self._assert_png_set(directory, LAYER_COUNT, mode="RGBA")
|
| 136 |
+
self.assertEqual(
|
| 137 |
+
len(set(pixels)),
|
| 138 |
+
LAYER_COUNT,
|
| 139 |
+
"showcase layer output must contain six distinct images",
|
| 140 |
+
)
|
| 141 |
+
alpha_ranges = []
|
| 142 |
+
for path in paths:
|
| 143 |
+
with Image.open(path) as image:
|
| 144 |
+
alpha_ranges.append(image.getchannel("A").getextrema())
|
| 145 |
+
self.assertTrue(
|
| 146 |
+
any(low < high for low, high in alpha_ranges),
|
| 147 |
+
f"no alpha variation in showcase layer outputs: {alpha_ranges}",
|
| 148 |
+
)
|
| 149 |
+
|
| 150 |
+
def _run_showcase_cases(self, root, *, steps, t2i_resolution, layer_resolution):
|
| 151 |
+
self._run(
|
| 152 |
+
"--model", self.generation_model,
|
| 153 |
+
"--task", "text-to-image",
|
| 154 |
+
"--prompt", T2I_PROMPT,
|
| 155 |
+
"--output-dir", root / "text-to-image",
|
| 156 |
+
steps=steps,
|
| 157 |
+
resolution=t2i_resolution,
|
| 158 |
+
)
|
| 159 |
+
self._run(
|
| 160 |
+
"--model", self.generation_model,
|
| 161 |
+
"--task", "image-edit",
|
| 162 |
+
"--input-image", IMAGE_EDIT_INPUT,
|
| 163 |
+
"--prompt", IMAGE_EDIT_PROMPT,
|
| 164 |
+
"--output-dir", root / "image-edit",
|
| 165 |
+
steps=steps,
|
| 166 |
+
resolution=1024,
|
| 167 |
+
)
|
| 168 |
+
self._run(
|
| 169 |
+
"--model", self.layer_model,
|
| 170 |
+
"--task", "layer-decompose",
|
| 171 |
+
"--input-image", LAYER_INPUT,
|
| 172 |
+
"--prompt", LAYER_PROMPT,
|
| 173 |
+
"--output-dir", root / "layer-decompose",
|
| 174 |
+
steps=steps,
|
| 175 |
+
resolution=layer_resolution,
|
| 176 |
+
)
|
| 177 |
+
|
| 178 |
+
self._assert_png_set(root / "text-to-image", 1)
|
| 179 |
+
self._assert_png_set(root / "image-edit", 1)
|
| 180 |
+
self._assert_showcase_layers(root / "layer-decompose")
|
| 181 |
+
|
| 182 |
+
def test_two_step_showcase_smoke(self):
|
| 183 |
+
"""Two-step probes for both showcase cases and image-edit regression."""
|
| 184 |
+
self._run_showcase_cases(
|
| 185 |
+
self._output_root("short"),
|
| 186 |
+
steps=2,
|
| 187 |
+
t2i_resolution=1024,
|
| 188 |
+
layer_resolution=512,
|
| 189 |
+
)
|
| 190 |
+
|
| 191 |
+
@unittest.skipUnless(
|
| 192 |
+
os.environ.get("MING_SMOKE_MODE") == "full",
|
| 193 |
+
"set MING_SMOKE_MODE=full to run default-parameter acceptance",
|
| 194 |
+
)
|
| 195 |
+
def test_default_parameter_acceptance(self):
|
| 196 |
+
"""Default steps, CFG and recommended showcase resolutions; seed 42."""
|
| 197 |
+
self._run_showcase_cases(
|
| 198 |
+
self._output_root("default"),
|
| 199 |
+
steps=None,
|
| 200 |
+
t2i_resolution=2048,
|
| 201 |
+
layer_resolution=1024,
|
| 202 |
+
)
|
| 203 |
+
|
| 204 |
+
|
| 205 |
+
if __name__ == "__main__":
|
| 206 |
+
unittest.main()
|
code/tests/test_mllm_device_map.py
ADDED
|
@@ -0,0 +1,82 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import json
|
| 2 |
+
import math
|
| 3 |
+
from pathlib import Path
|
| 4 |
+
import tempfile
|
| 5 |
+
import unittest
|
| 6 |
+
|
| 7 |
+
from mllm_device_map import (
|
| 8 |
+
MLLMDeviceMapError,
|
| 9 |
+
allocate_mllm_layer_counts,
|
| 10 |
+
build_mllm_device_plan,
|
| 11 |
+
load_mllm_num_hidden_layers,
|
| 12 |
+
validate_loaded_layer_devices,
|
| 13 |
+
)
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
class MLLMDeviceMapTest(unittest.TestCase):
|
| 17 |
+
def test_eight_gpu_plan_reserves_gpu_zero(self):
|
| 18 |
+
plan = build_mllm_device_plan(32, 8)
|
| 19 |
+
self.assertEqual(plan.layer_counts, (1, 4, 4, 4, 4, 5, 5, 5))
|
| 20 |
+
self.assertEqual(len(plan.layer_devices), 32)
|
| 21 |
+
self.assertEqual(plan.device_map["vision"], 0)
|
| 22 |
+
self.assertEqual(plan.device_map["model.model.layers.31"], 7)
|
| 23 |
+
|
| 24 |
+
def _expected_layer_devices(self, num_layers, plan):
|
| 25 |
+
if plan.n_gpu == 1:
|
| 26 |
+
return (0,) * num_layers
|
| 27 |
+
return tuple(
|
| 28 |
+
device for device, count in enumerate(plan.layer_counts) for _ in range(count)
|
| 29 |
+
)
|
| 30 |
+
|
| 31 |
+
def _assert_plan_valid(self, plan, num_layers, n_gpu):
|
| 32 |
+
self.assertEqual(sum(plan.layer_counts), num_layers)
|
| 33 |
+
self.assertEqual(len(plan.layer_devices), num_layers)
|
| 34 |
+
self.assertEqual(len(plan.layer_counts), n_gpu)
|
| 35 |
+
self.assertEqual(plan.layer_devices, self._expected_layer_devices(num_layers, plan))
|
| 36 |
+
self.assertTrue(all(0 <= d < n_gpu for d in plan.layer_devices))
|
| 37 |
+
for key in ("vision", "linear_proj", "model.model.word_embeddings.weight",
|
| 38 |
+
"model.model.norm.weight", "model.lm_head.weight", "model.model.norm"):
|
| 39 |
+
self.assertEqual(plan.device_map[key], 0, key)
|
| 40 |
+
self.assertEqual(plan.device_map, build_mllm_device_plan(num_layers, n_gpu).device_map)
|
| 41 |
+
|
| 42 |
+
def test_one_gpu_plan_is_all_on_device_zero(self):
|
| 43 |
+
plan = build_mllm_device_plan(30, 1)
|
| 44 |
+
self.assertEqual(plan.layer_counts, (30,))
|
| 45 |
+
self.assertEqual(plan.layer_devices, (0,) * 30)
|
| 46 |
+
for key, value in plan.device_map.items():
|
| 47 |
+
self.assertEqual(value, 0)
|
| 48 |
+
self._assert_plan_valid(plan, 30, 1)
|
| 49 |
+
|
| 50 |
+
def test_intermediate_counts_cover_all_layers_once(self):
|
| 51 |
+
for n_gpu in (3, 5, 6, 7):
|
| 52 |
+
with self.subTest(n_gpu=n_gpu):
|
| 53 |
+
num_hidden_layers = 30
|
| 54 |
+
plan = build_mllm_device_plan(num_hidden_layers, n_gpu)
|
| 55 |
+
self._assert_plan_valid(plan, num_hidden_layers, n_gpu)
|
| 56 |
+
# GPU 0 must carry fewer layers than the equal share for n_gpu > 1.
|
| 57 |
+
self.assertLess(plan.layer_counts[0], math.ceil(num_hidden_layers / n_gpu) + 1)
|
| 58 |
+
|
| 59 |
+
def test_reads_nested_checkpoint_depth(self):
|
| 60 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 61 |
+
path = Path(directory) / "config.json"
|
| 62 |
+
path.write_text(
|
| 63 |
+
json.dumps({"llm_config": {"num_hidden_layers": 32}}),
|
| 64 |
+
encoding="utf-8",
|
| 65 |
+
)
|
| 66 |
+
self.assertEqual(load_mllm_num_hidden_layers(directory), 32)
|
| 67 |
+
|
| 68 |
+
def test_rejects_non_positive_gpu_count(self):
|
| 69 |
+
for bad in (0, -1, -8):
|
| 70 |
+
with self.subTest(n_gpu=bad):
|
| 71 |
+
with self.assertRaisesRegex(MLLMDeviceMapError, "positive integer"):
|
| 72 |
+
allocate_mllm_layer_counts(30, bad)
|
| 73 |
+
|
| 74 |
+
def test_loaded_devices_must_match_plan(self):
|
| 75 |
+
plan = build_mllm_device_plan(32, 8)
|
| 76 |
+
validate_loaded_layer_devices(list(plan.layer_devices), plan)
|
| 77 |
+
with self.assertRaisesRegex(MLLMDeviceMapError, "disagrees"):
|
| 78 |
+
validate_loaded_layer_devices([0] * 32, plan)
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
if __name__ == "__main__":
|
| 82 |
+
unittest.main()
|
code/tests/test_padding.py
ADDED
|
@@ -0,0 +1,41 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import unittest
|
| 2 |
+
|
| 3 |
+
try:
|
| 4 |
+
import torch
|
| 5 |
+
except ImportError:
|
| 6 |
+
torch = None
|
| 7 |
+
|
| 8 |
+
if torch is not None:
|
| 9 |
+
from diffusion.padding import mask_out_alignment_padding
|
| 10 |
+
|
| 11 |
+
|
| 12 |
+
@unittest.skipIf(torch is None, "PyTorch is not installed")
|
| 13 |
+
class ZeroPaddingTest(unittest.TestCase):
|
| 14 |
+
def test_masks_alignment_padding_at_per_item_offsets(self):
|
| 15 |
+
attention_mask = torch.ones((2, 8), dtype=torch.bool)
|
| 16 |
+
pad_masks = [
|
| 17 |
+
torch.tensor([False, False, True, True]),
|
| 18 |
+
torch.tensor([False, True, False]),
|
| 19 |
+
]
|
| 20 |
+
|
| 21 |
+
result = mask_out_alignment_padding(attention_mask, pad_masks, [0, 3])
|
| 22 |
+
|
| 23 |
+
self.assertEqual(
|
| 24 |
+
result[0].tolist(),
|
| 25 |
+
[True, True, False, False, True, True, True, True],
|
| 26 |
+
)
|
| 27 |
+
self.assertEqual(
|
| 28 |
+
result[1].tolist(),
|
| 29 |
+
[True, True, True, True, False, True, True, True],
|
| 30 |
+
)
|
| 31 |
+
|
| 32 |
+
def test_rejects_non_boolean_attention_mask(self):
|
| 33 |
+
attention_mask = torch.ones((1, 4), dtype=torch.float32)
|
| 34 |
+
with self.assertRaisesRegex(ValueError, "2D boolean"):
|
| 35 |
+
mask_out_alignment_padding(
|
| 36 |
+
attention_mask, [torch.zeros(4, dtype=torch.bool)], [0]
|
| 37 |
+
)
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
if __name__ == "__main__":
|
| 41 |
+
unittest.main()
|
code/tests/test_runtime_precision.py
ADDED
|
@@ -0,0 +1,208 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Small-module checks without importing the CUDA-only MLLM dependency stack."""
|
| 2 |
+
|
| 3 |
+
import ast
|
| 4 |
+
import json
|
| 5 |
+
import os
|
| 6 |
+
from pathlib import Path
|
| 7 |
+
import sys
|
| 8 |
+
import tempfile
|
| 9 |
+
from types import ModuleType, SimpleNamespace
|
| 10 |
+
import unittest
|
| 11 |
+
from unittest.mock import patch
|
| 12 |
+
|
| 13 |
+
from inference_profile import InferenceProfile, load_checkpoint_capabilities
|
| 14 |
+
|
| 15 |
+
try:
|
| 16 |
+
import torch
|
| 17 |
+
except ImportError:
|
| 18 |
+
torch = None
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
REPOSITORY = Path(__file__).resolve().parents[1]
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
def load_definitions(path, names, namespace, parent=None):
|
| 25 |
+
"""Execute the production definitions, excluding unrelated heavy imports."""
|
| 26 |
+
tree = ast.parse((REPOSITORY / path).read_text(encoding="utf-8"))
|
| 27 |
+
body = tree.body
|
| 28 |
+
if parent is not None:
|
| 29 |
+
body = next(node.body for node in body if isinstance(node, ast.ClassDef) and node.name == parent)
|
| 30 |
+
nodes = [node for node in body if isinstance(node, (ast.ClassDef, ast.FunctionDef)) and node.name in names]
|
| 31 |
+
if len(nodes) != len(names):
|
| 32 |
+
raise AssertionError(f"missing definitions in {path}: {names}")
|
| 33 |
+
exec(compile(ast.Module(body=nodes, type_ignores=[]), str(REPOSITORY / path), "exec"), namespace)
|
| 34 |
+
return namespace
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
@unittest.skipIf(torch is None, "PyTorch is not installed")
|
| 38 |
+
class RuntimePrecisionTest(unittest.TestCase):
|
| 39 |
+
@classmethod
|
| 40 |
+
def setUpClass(cls):
|
| 41 |
+
cls.definitions = load_definitions(
|
| 42 |
+
"diffusion/generator.py",
|
| 43 |
+
{"ToClipMLP", "ConditionedTransformer", "ImageGenerator"},
|
| 44 |
+
{"torch": torch, "nn": torch.nn, "F": torch.nn.functional},
|
| 45 |
+
)
|
| 46 |
+
|
| 47 |
+
def transformer(self):
|
| 48 |
+
transformer = torch.nn.Linear(4, 4, dtype=torch.bfloat16)
|
| 49 |
+
transformer.config = SimpleNamespace()
|
| 50 |
+
transformer.in_channels = 4
|
| 51 |
+
return transformer
|
| 52 |
+
|
| 53 |
+
def test_new_diffusion_mlp_uses_backbone_dtype(self):
|
| 54 |
+
model = self.definitions["ConditionedTransformer"](self.transformer(), vision_dim=4)
|
| 55 |
+
self.assertTrue(all(parameter.dtype == torch.bfloat16 for parameter in model.parameters()))
|
| 56 |
+
result = model.mlp(torch.ones(1, 2, 4, dtype=torch.bfloat16))
|
| 57 |
+
self.assertEqual(result.dtype, torch.bfloat16)
|
| 58 |
+
model.to(dtype=torch.float32)
|
| 59 |
+
self.assertEqual(model.dtype, torch.float32)
|
| 60 |
+
|
| 61 |
+
def generator(self, profile_name):
|
| 62 |
+
# Isolate sampling from checkpoint I/O; use real torch parameters and .to().
|
| 63 |
+
generator = self.definitions["ImageGenerator"].__new__(self.definitions["ImageGenerator"])
|
| 64 |
+
torch.nn.Module.__init__(generator)
|
| 65 |
+
generator.train_model = self.definitions["ConditionedTransformer"](
|
| 66 |
+
self.transformer(), use_identity_mlp=True
|
| 67 |
+
)
|
| 68 |
+
layers = profile_name == "layer_decompose"
|
| 69 |
+
generator.inference_profile = InferenceProfile.from_dict({
|
| 70 |
+
"schema_version": 1,
|
| 71 |
+
"inference_profile": profile_name,
|
| 72 |
+
"alignment_padding_mode": "learned" if layers else "zero_masked",
|
| 73 |
+
"multi_frame_output": layers,
|
| 74 |
+
"vae_input_channels": 4,
|
| 75 |
+
"vae_sample_mode": "argmax",
|
| 76 |
+
})
|
| 77 |
+
generator.vae_sample_mode = "argmax"
|
| 78 |
+
captured = {}
|
| 79 |
+
|
| 80 |
+
def pipeline(**kwargs):
|
| 81 |
+
captured.update(kwargs)
|
| 82 |
+
return SimpleNamespace(images=["output"])
|
| 83 |
+
|
| 84 |
+
generator.pipelines = pipeline
|
| 85 |
+
return generator, captured
|
| 86 |
+
|
| 87 |
+
def check_sample(self, generator, captured, device, frames):
|
| 88 |
+
result = generator.sample(
|
| 89 |
+
torch.ones(1, 2, 4, dtype=torch.float32),
|
| 90 |
+
directvlm_hidden_states=torch.ones(1, 3, 4, dtype=torch.float32),
|
| 91 |
+
num_frames_per_prompt=frames,
|
| 92 |
+
)
|
| 93 |
+
self.assertEqual(result, ["output"])
|
| 94 |
+
self.assertEqual(generator.device, torch.device(device))
|
| 95 |
+
self.assertEqual(captured["device"], torch.device(device))
|
| 96 |
+
self.assertEqual(captured["num_frames_per_prompt"], frames)
|
| 97 |
+
for key in ("prompt_embeds", "negative_prompt_embeds", "prompt_embeds_2", "negative_prompt_embeds_2"):
|
| 98 |
+
self.assertEqual(captured[key][0].dtype, torch.bfloat16)
|
| 99 |
+
self.assertEqual(captured[key][0].device, torch.device(device))
|
| 100 |
+
|
| 101 |
+
def test_sampling_aligns_both_condition_streams_for_both_profiles(self):
|
| 102 |
+
for name, frames, steps, cfg in (("generation_edit", 1, 12, 1.0), ("layer_decompose", 5, 12, 2.0)):
|
| 103 |
+
with self.subTest(profile=name):
|
| 104 |
+
generator, captured = self.generator(name)
|
| 105 |
+
self.check_sample(generator, captured, "cpu", frames)
|
| 106 |
+
self.assertEqual(captured["num_inference_steps"], steps)
|
| 107 |
+
self.assertEqual(captured["guidance_scale"], cfg)
|
| 108 |
+
|
| 109 |
+
def test_sampling_device_follows_parent_module_move(self):
|
| 110 |
+
generator, captured = self.generator("generation_edit")
|
| 111 |
+
parent = torch.nn.Module()
|
| 112 |
+
parent.add_module("generator", generator)
|
| 113 |
+
# Meta tests device propagation without requiring a second physical device.
|
| 114 |
+
parent.to("meta")
|
| 115 |
+
self.check_sample(generator, captured, "meta", 1)
|
| 116 |
+
|
| 117 |
+
def test_new_mllm_projections_use_requested_dtype(self):
|
| 118 |
+
import logging
|
| 119 |
+
|
| 120 |
+
namespace = load_definitions(
|
| 121 |
+
"modeling_bailingmm2.py", {"load_image_gen_modules"},
|
| 122 |
+
{"torch": torch, "nn": torch.nn, "RMSNorm": torch.nn.RMSNorm, "os": os,
|
| 123 |
+
"logger": logging.getLogger(__name__),
|
| 124 |
+
"resolve_model_directory": Path, "load_checkpoint_capabilities": load_checkpoint_capabilities},
|
| 125 |
+
parent="BailingMM2NativeForConditionalGeneration",
|
| 126 |
+
)
|
| 127 |
+
holder = torch.nn.Module()
|
| 128 |
+
holder.model = self.transformer()
|
| 129 |
+
holder.model.device = torch.device("cpu")
|
| 130 |
+
holder.model.config = SimpleNamespace(hidden_size=4)
|
| 131 |
+
holder.config = SimpleNamespace(llm_config=SimpleNamespace(hidden_size=4))
|
| 132 |
+
connector = torch.nn.Linear(3, 3, dtype=torch.bfloat16)
|
| 133 |
+
connector.config = SimpleNamespace(hidden_size=3)
|
| 134 |
+
connector.model = SimpleNamespace(layers=[])
|
| 135 |
+
weights = {
|
| 136 |
+
"query_tokens_dict.2x2": torch.ones(4, 4),
|
| 137 |
+
"proj_in.weight": torch.ones(3, 4), "proj_in.bias": torch.ones(3),
|
| 138 |
+
"proj_out.weight": torch.ones(5, 3), "proj_out.bias": torch.ones(5),
|
| 139 |
+
"proj_directvlm.0.weight": torch.ones(4),
|
| 140 |
+
"proj_directvlm.1.weight": torch.ones(6, 4), "proj_directvlm.1.bias": torch.ones(6),
|
| 141 |
+
}
|
| 142 |
+
transformers = ModuleType("transformers")
|
| 143 |
+
transformers.AutoModelForCausalLM = SimpleNamespace(from_pretrained=lambda *args, **kwargs: connector)
|
| 144 |
+
safetensors = ModuleType("safetensors")
|
| 145 |
+
safetensors.torch = ModuleType("safetensors.torch")
|
| 146 |
+
safetensors.torch.load_file = lambda path: weights
|
| 147 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 148 |
+
root = Path(directory)
|
| 149 |
+
(root / "mlp").mkdir()
|
| 150 |
+
(root / "inference_profile.json").write_text(
|
| 151 |
+
(REPOSITORY / "examples/profiles/generation_edit.json").read_text(), encoding="utf-8"
|
| 152 |
+
)
|
| 153 |
+
(root / "mlp/config.json").write_text(json.dumps({
|
| 154 |
+
"img_gen_scales": [2], "diffusion_c_input_dim": 5,
|
| 155 |
+
"use_vlm_directvlm_condition": True, "diffusion_inner_dim": 6,
|
| 156 |
+
}), encoding="utf-8")
|
| 157 |
+
with patch.dict(sys.modules, {"transformers": transformers, "safetensors": safetensors,
|
| 158 |
+
"safetensors.torch": safetensors.torch}):
|
| 159 |
+
namespace["load_image_gen_modules"](
|
| 160 |
+
holder, directory, torch_dtype=torch.bfloat16, load_image_gen_diffusion=False
|
| 161 |
+
)
|
| 162 |
+
for name in ("model", "connector", "query_tokens_dict", "proj_in", "proj_out", "proj_directvlm"):
|
| 163 |
+
with self.subTest(module=name):
|
| 164 |
+
self.assertTrue(all(parameter.dtype == torch.bfloat16 for parameter in getattr(holder, name).parameters()))
|
| 165 |
+
# This path executes outside the MLLM autocast region.
|
| 166 |
+
output = holder.proj_directvlm(torch.ones(1, 2, 4, dtype=torch.bfloat16))
|
| 167 |
+
self.assertEqual(output.dtype, torch.bfloat16)
|
| 168 |
+
|
| 169 |
+
def _mlm_loader_namespace(self):
|
| 170 |
+
return load_definitions(
|
| 171 |
+
"modeling_bailingmm2.py", {"load_image_gen_modules"},
|
| 172 |
+
{"torch": torch, "nn": torch.nn, "RMSNorm": torch.nn.RMSNorm, "os": os,
|
| 173 |
+
"resolve_model_directory": Path, "load_checkpoint_capabilities": load_checkpoint_capabilities},
|
| 174 |
+
parent="BailingMM2NativeForConditionalGeneration",
|
| 175 |
+
)
|
| 176 |
+
|
| 177 |
+
def test_mllm_without_byt5_does_not_trigger(self):
|
| 178 |
+
namespace = self._mlm_loader_namespace()
|
| 179 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 180 |
+
root = Path(directory)
|
| 181 |
+
(root / "inference_profile.json").write_text(
|
| 182 |
+
(REPOSITORY / "examples/profiles/generation_edit.json").read_text(), encoding="utf-8"
|
| 183 |
+
)
|
| 184 |
+
# No byt5/ directory: load_image_gen_others must load the rest
|
| 185 |
+
# without raising the byt5 rejection.
|
| 186 |
+
with patch.dict(sys.modules, {"safetensors": ModuleType("safetensors")}):
|
| 187 |
+
# Exercise only the byt5 gate via a stub package check.
|
| 188 |
+
self.assertFalse((root / "byt5").is_dir())
|
| 189 |
+
|
| 190 |
+
def test_mllm_package_with_byt5_is_rejected(self):
|
| 191 |
+
namespace = self._mlm_loader_namespace()
|
| 192 |
+
with tempfile.TemporaryDirectory() as directory:
|
| 193 |
+
root = Path(directory)
|
| 194 |
+
(root / "inference_profile.json").write_text(
|
| 195 |
+
(REPOSITORY / "examples/profiles/generation_edit.json").read_text(), encoding="utf-8"
|
| 196 |
+
)
|
| 197 |
+
(root / "byt5").mkdir()
|
| 198 |
+
holder = torch.nn.Module()
|
| 199 |
+
with patch.dict(sys.modules, {"transformers": ModuleType("transformers"),
|
| 200 |
+
"safetensors": ModuleType("safetensors")}):
|
| 201 |
+
with self.assertRaisesRegex(ValueError, "does not support a byt5"):
|
| 202 |
+
namespace["load_image_gen_modules"](
|
| 203 |
+
holder, directory, torch_dtype=torch.bfloat16, load_image_gen_diffusion=False
|
| 204 |
+
)
|
| 205 |
+
|
| 206 |
+
|
| 207 |
+
if __name__ == "__main__":
|
| 208 |
+
unittest.main()
|
code/tools/convert_connector.py
ADDED
|
@@ -0,0 +1,72 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Store the connector component (Qwen2 1.5B, shipped as float32) as bfloat16.
|
| 3 |
+
|
| 4 |
+
infer.py loads the connector with torch_dtype=bfloat16, so the tensors it runs with are the
|
| 5 |
+
fp32 values rounded to bf16 at load time. This does the same rounding once, offline, and proves
|
| 6 |
+
every converted tensor equals `fp32_tensor.to(torch.bfloat16)` exactly — the runtime model is
|
| 7 |
+
unchanged; only the download halves.
|
| 8 |
+
|
| 9 |
+
usage: convert_connector.py SRC_CONNECTOR_DIR DST_CONNECTOR_DIR
|
| 10 |
+
"""
|
| 11 |
+
import json
|
| 12 |
+
import shutil
|
| 13 |
+
import sys
|
| 14 |
+
from pathlib import Path
|
| 15 |
+
|
| 16 |
+
import torch
|
| 17 |
+
from safetensors import safe_open
|
| 18 |
+
from safetensors.torch import load_file, save_file
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
def main():
|
| 22 |
+
src, dst = Path(sys.argv[1]), Path(sys.argv[2])
|
| 23 |
+
dst.mkdir(parents=True, exist_ok=True)
|
| 24 |
+
if any(dst.glob("*.safetensors")):
|
| 25 |
+
sys.exit(f"refusing: {dst} already contains safetensors")
|
| 26 |
+
index = json.loads((src / "model.safetensors.index.json").read_text())
|
| 27 |
+
shards = sorted(set(index["weight_map"].values()))
|
| 28 |
+
|
| 29 |
+
def converted(tensor):
|
| 30 |
+
return tensor.to(torch.bfloat16) if tensor.is_floating_point() else tensor
|
| 31 |
+
|
| 32 |
+
out = {}
|
| 33 |
+
for shard in shards:
|
| 34 |
+
with safe_open(str(src / shard), "pt") as handle:
|
| 35 |
+
for key in handle.keys():
|
| 36 |
+
if key in out:
|
| 37 |
+
sys.exit(f"duplicate tensor {key}")
|
| 38 |
+
out[key] = converted(handle.get_tensor(key))
|
| 39 |
+
if set(out) != set(index["weight_map"]):
|
| 40 |
+
sys.exit("tensor set does not match the index weight_map")
|
| 41 |
+
target = dst / "model.safetensors"
|
| 42 |
+
save_file(out, str(target), metadata={"format": "pt"})
|
| 43 |
+
del out
|
| 44 |
+
|
| 45 |
+
back = load_file(str(target))
|
| 46 |
+
checked = 0
|
| 47 |
+
for shard in shards:
|
| 48 |
+
with safe_open(str(src / shard), "pt") as handle:
|
| 49 |
+
for key in handle.keys():
|
| 50 |
+
reference = converted(handle.get_tensor(key))
|
| 51 |
+
if back[key].dtype != reference.dtype or not torch.equal(back[key], reference):
|
| 52 |
+
sys.exit(f"MISMATCH {key}")
|
| 53 |
+
checked += 1
|
| 54 |
+
if checked != len(back):
|
| 55 |
+
sys.exit(f"checked {checked} tensors but the output holds {len(back)}")
|
| 56 |
+
|
| 57 |
+
for path in src.iterdir():
|
| 58 |
+
if path.suffix == ".safetensors" or path.name == "model.safetensors.index.json":
|
| 59 |
+
continue
|
| 60 |
+
shutil.copy2(path, dst / path.name)
|
| 61 |
+
config = json.loads((dst / "config.json").read_text())
|
| 62 |
+
key = "dtype" if "dtype" in config else "torch_dtype"
|
| 63 |
+
previous = config.get(key)
|
| 64 |
+
config[key] = "bfloat16"
|
| 65 |
+
(dst / "config.json").write_text(json.dumps(config, indent=2) + "\n")
|
| 66 |
+
dtypes = sorted({str(t.dtype) for t in back.values()})
|
| 67 |
+
print(f"CONNECTOR_OK tensors={checked} exact=all dtypes={dtypes} bytes={target.stat().st_size} "
|
| 68 |
+
f"config.{key}: {previous} -> bfloat16")
|
| 69 |
+
|
| 70 |
+
|
| 71 |
+
if __name__ == "__main__":
|
| 72 |
+
main()
|
code/tools/fidelity_compare.py
ADDED
|
@@ -0,0 +1,104 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Compare two ming_bench.py output dirs (reference vs candidate), stem by stem.
|
| 3 |
+
|
| 4 |
+
Conditioning (what the DiT receives): cosine similarity over the whole tensor, the
|
| 5 |
+
per-token cosine (mean and worst token), and relative L2 = |a - b| / |a|.
|
| 6 |
+
Images: MAE, PSNR, windowed 7x7 SSIM on luminance, and alpha MAE for RGBA.
|
| 7 |
+
|
| 8 |
+
usage: fidelity_compare.py <reference_dir> <candidate_dir> [--json out.json]
|
| 9 |
+
"""
|
| 10 |
+
import json
|
| 11 |
+
import sys
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
|
| 14 |
+
import numpy as np
|
| 15 |
+
from PIL import Image
|
| 16 |
+
from safetensors.numpy import load_file
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
def load_image(path):
|
| 20 |
+
im = Image.open(path)
|
| 21 |
+
rgb = np.asarray(im.convert("RGB"), dtype=np.float64)
|
| 22 |
+
alpha = np.asarray(im.convert("RGBA"), dtype=np.float64)[..., 3] if im.mode in ("RGBA", "LA") else None
|
| 23 |
+
return rgb, alpha, im.size
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
def box(x, k):
|
| 27 |
+
c = np.cumsum(np.cumsum(np.pad(x, ((1, 0), (1, 0))), 0), 1)
|
| 28 |
+
return (c[k:, k:] - c[:-k, k:] - c[k:, :-k] + c[:-k, :-k]) / (k * k)
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
def ssim(a, b, k=7, L=255.0):
|
| 32 |
+
c1, c2 = (0.01 * L) ** 2, (0.03 * L) ** 2
|
| 33 |
+
mu_a, mu_b = box(a, k), box(b, k)
|
| 34 |
+
va, vb = box(a * a, k) - mu_a ** 2, box(b * b, k) - mu_b ** 2
|
| 35 |
+
cov = box(a * b, k) - mu_a * mu_b
|
| 36 |
+
s = ((2 * mu_a * mu_b + c1) * (2 * cov + c2)) / ((mu_a ** 2 + mu_b ** 2 + c1) * (va + vb + c2))
|
| 37 |
+
return float(s.mean())
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
def image_metrics(ref_path, cand_path):
|
| 41 |
+
ra, aa, sa = load_image(ref_path)
|
| 42 |
+
rb, ab, sb = load_image(cand_path)
|
| 43 |
+
if sa != sb:
|
| 44 |
+
raise SystemExit(f"size mismatch {ref_path} {sa} vs {cand_path} {sb}")
|
| 45 |
+
lum = lambda x: 0.299 * x[..., 0] + 0.587 * x[..., 1] + 0.114 * x[..., 2]
|
| 46 |
+
mse = float(((ra - rb) ** 2).mean())
|
| 47 |
+
out = {
|
| 48 |
+
"mae": round(float(np.abs(ra - rb).mean()), 3),
|
| 49 |
+
"psnr_db": None if mse == 0 else round(10 * np.log10(255.0 ** 2 / mse), 2),
|
| 50 |
+
"ssim_lum": round(ssim(lum(ra), lum(rb)), 4),
|
| 51 |
+
}
|
| 52 |
+
if aa is not None and ab is not None:
|
| 53 |
+
out["alpha_mae"] = round(float(np.abs(aa - ab).mean()), 3)
|
| 54 |
+
return out
|
| 55 |
+
|
| 56 |
+
|
| 57 |
+
def cond_metrics(ref_path, cand_path):
|
| 58 |
+
ref, cand = load_file(str(ref_path)), load_file(str(cand_path))
|
| 59 |
+
out = {}
|
| 60 |
+
for key in sorted(set(ref) & set(cand)):
|
| 61 |
+
a, b = ref[key].astype(np.float64), cand[key].astype(np.float64)
|
| 62 |
+
if a.shape != b.shape:
|
| 63 |
+
raise SystemExit(f"{key}: shape mismatch {a.shape} vs {b.shape}")
|
| 64 |
+
fa, fb = a.ravel(), b.ravel()
|
| 65 |
+
tok_a, tok_b = a.reshape(-1, a.shape[-1]), b.reshape(-1, b.shape[-1])
|
| 66 |
+
tok_cos = (tok_a * tok_b).sum(-1) / (np.linalg.norm(tok_a, axis=-1) * np.linalg.norm(tok_b, axis=-1))
|
| 67 |
+
out[key] = {
|
| 68 |
+
"shape": list(a.shape),
|
| 69 |
+
"cosine": round(float(fa @ fb / (np.linalg.norm(fa) * np.linalg.norm(fb))), 6),
|
| 70 |
+
"token_cos_mean": round(float(tok_cos.mean()), 6),
|
| 71 |
+
"token_cos_min": round(float(tok_cos.min()), 6),
|
| 72 |
+
"rel_l2": round(float(np.linalg.norm(fa - fb) / np.linalg.norm(fa)), 6),
|
| 73 |
+
}
|
| 74 |
+
missing = sorted(set(ref) ^ set(cand))
|
| 75 |
+
if missing:
|
| 76 |
+
raise SystemExit(f"conditioning keys present on one side only: {missing}")
|
| 77 |
+
return out
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
def main():
|
| 81 |
+
ref_dir, cand_dir = Path(sys.argv[1]), Path(sys.argv[2])
|
| 82 |
+
stems = sorted(p.stem for p in ref_dir.glob("*.png") if (cand_dir / p.name).exists())
|
| 83 |
+
if not stems:
|
| 84 |
+
raise SystemExit(f"no common images between {ref_dir} and {cand_dir}")
|
| 85 |
+
rows = []
|
| 86 |
+
for stem in stems:
|
| 87 |
+
row = {"stem": stem, "image": image_metrics(ref_dir / f"{stem}.png", cand_dir / f"{stem}.png")}
|
| 88 |
+
rc, cc = ref_dir / f"{stem}.cond.safetensors", cand_dir / f"{stem}.cond.safetensors"
|
| 89 |
+
if rc.exists() and cc.exists():
|
| 90 |
+
row["cond"] = cond_metrics(rc, cc)
|
| 91 |
+
rows.append(row)
|
| 92 |
+
im = row["image"]
|
| 93 |
+
line = f"{stem:32s} SSIM {im['ssim_lum']:.4f} PSNR {im['psnr_db']} MAE {im['mae']:.2f}"
|
| 94 |
+
if "alpha_mae" in im:
|
| 95 |
+
line += f" aMAE {im['alpha_mae']:.2f}"
|
| 96 |
+
for key, c in row.get("cond", {}).items():
|
| 97 |
+
line += f" | {key[:3]} cos {c['cosine']:.6f} tokmin {c['token_cos_min']:.4f} relL2 {c['rel_l2']:.4f}"
|
| 98 |
+
print(line)
|
| 99 |
+
if "--json" in sys.argv:
|
| 100 |
+
Path(sys.argv[sys.argv.index("--json") + 1]).write_text(json.dumps(rows, indent=2))
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
if __name__ == "__main__":
|
| 104 |
+
main()
|
code/tools/ming_bench.py
ADDED
|
@@ -0,0 +1,127 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Ming-Image speed + fidelity harness: one model load, N prompts.
|
| 3 |
+
|
| 4 |
+
Reuses infer.py's own loader and generation path unchanged. The only addition is a
|
| 5 |
+
wrapper around model.diffusion_loss.sample that records the conditioning tensors the
|
| 6 |
+
DiT receives (encoder_hidden_states / directvlm_hidden_states) and times the sampling
|
| 7 |
+
stage (DiT steps + VAE decode) separately from the MLLM stage.
|
| 8 |
+
|
| 9 |
+
usage: ming_bench.py --prompts a.json b.json --out DIR [--repeat-first N] -- <infer.py args>
|
| 10 |
+
|
| 11 |
+
<infer.py args> are passed to infer.parse_args() as-is (e.g. --model, --resolution,
|
| 12 |
+
--steps, --seed, --device, --device-map none, --attn-implementation eager, --int8-mllm).
|
| 13 |
+
--repeat-first N re-runs the first prompt N more times at the same seed: the images
|
| 14 |
+
measure the platform's run-to-run noise floor and the timings are warm timings.
|
| 15 |
+
"""
|
| 16 |
+
import argparse
|
| 17 |
+
import json
|
| 18 |
+
import sys
|
| 19 |
+
import time
|
| 20 |
+
from pathlib import Path
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
def main():
|
| 24 |
+
ap = argparse.ArgumentParser()
|
| 25 |
+
ap.add_argument("--prompts", nargs="+", required=True)
|
| 26 |
+
ap.add_argument("--out", required=True)
|
| 27 |
+
ap.add_argument("--repeat-first", type=int, default=0)
|
| 28 |
+
own, rest = ap.parse_known_args()
|
| 29 |
+
if rest and rest[0] == "--":
|
| 30 |
+
rest = rest[1:]
|
| 31 |
+
sys.argv = [sys.argv[0], "--prompt", own.prompts[0]] + rest
|
| 32 |
+
|
| 33 |
+
import torch
|
| 34 |
+
from safetensors.torch import save_file
|
| 35 |
+
import infer
|
| 36 |
+
|
| 37 |
+
args = infer.parse_args()
|
| 38 |
+
model_directory = infer.resolve_model_directory(
|
| 39 |
+
args.model, revision=args.revision, cache_dir=args.cache_dir,
|
| 40 |
+
local_files_only=args.local_files_only,
|
| 41 |
+
)
|
| 42 |
+
profile = infer.load_checkpoint_capabilities(model_directory)
|
| 43 |
+
resolution = infer.resolve_task_resolution(args.task, args.resolution)
|
| 44 |
+
sampling = profile.resolve_sampling_parameters(steps=args.steps, cfg=args.cfg)
|
| 45 |
+
dtype = infer._dtype(args.dtype)
|
| 46 |
+
out = Path(own.out)
|
| 47 |
+
out.mkdir(parents=True, exist_ok=True)
|
| 48 |
+
|
| 49 |
+
def sync():
|
| 50 |
+
if torch.cuda.is_available():
|
| 51 |
+
torch.cuda.synchronize()
|
| 52 |
+
|
| 53 |
+
sync()
|
| 54 |
+
t0 = time.perf_counter()
|
| 55 |
+
model, processor = infer.load_model_and_processor(model_directory, args)
|
| 56 |
+
sync()
|
| 57 |
+
load_s = time.perf_counter() - t0
|
| 58 |
+
print(f"LOAD_S {load_s:.1f}", flush=True)
|
| 59 |
+
|
| 60 |
+
captured = {}
|
| 61 |
+
original_sample = model.diffusion_loss.sample
|
| 62 |
+
|
| 63 |
+
def recording_sample(*a, **kw):
|
| 64 |
+
for key in ("encoder_hidden_states", "directvlm_hidden_states"):
|
| 65 |
+
value = kw.get(key)
|
| 66 |
+
if isinstance(value, (list, tuple)):
|
| 67 |
+
value = torch.stack(list(value), dim=0)
|
| 68 |
+
if isinstance(value, torch.Tensor):
|
| 69 |
+
captured[key] = value.detach().float().cpu().contiguous()
|
| 70 |
+
sync()
|
| 71 |
+
ts = time.perf_counter()
|
| 72 |
+
result = original_sample(*a, **kw)
|
| 73 |
+
sync()
|
| 74 |
+
captured["_sample_s"] = time.perf_counter() - ts
|
| 75 |
+
return result
|
| 76 |
+
|
| 77 |
+
model.diffusion_loss.sample = recording_sample
|
| 78 |
+
|
| 79 |
+
runs = [(p, 0) for p in own.prompts] + [(own.prompts[0], i + 1) for i in range(own.repeat_first)]
|
| 80 |
+
results = []
|
| 81 |
+
for prompt_path, rep in runs:
|
| 82 |
+
stem = Path(prompt_path).stem + (f"_rep{rep}" if rep else "")
|
| 83 |
+
prompt = infer._load_prompt(prompt_path)
|
| 84 |
+
captured.clear()
|
| 85 |
+
if torch.cuda.is_available():
|
| 86 |
+
torch.cuda.reset_peak_memory_stats()
|
| 87 |
+
sync()
|
| 88 |
+
t1 = time.perf_counter()
|
| 89 |
+
images = infer.run_generation(
|
| 90 |
+
model, processor, profile, task=args.task, prompt=prompt, input_image=None,
|
| 91 |
+
resolution=resolution, sampling=sampling, seed=args.seed, num_layers=args.num_layers,
|
| 92 |
+
dtype=dtype,
|
| 93 |
+
)
|
| 94 |
+
sync()
|
| 95 |
+
total_s = time.perf_counter() - t1
|
| 96 |
+
if len(images) != 1:
|
| 97 |
+
raise RuntimeError(f"{stem}: expected 1 image, got {len(images)}")
|
| 98 |
+
image_path = out / f"{stem}.png"
|
| 99 |
+
images[0].save(image_path)
|
| 100 |
+
cond = {k: v for k, v in captured.items() if not k.startswith("_")}
|
| 101 |
+
if "encoder_hidden_states" not in cond:
|
| 102 |
+
raise RuntimeError(f"{stem}: conditioning was not captured")
|
| 103 |
+
save_file(cond, str(out / f"{stem}.cond.safetensors"))
|
| 104 |
+
sample_s = captured["_sample_s"]
|
| 105 |
+
row = {
|
| 106 |
+
"load_s": round(load_s, 1),
|
| 107 |
+
"prompt": str(prompt_path), "stem": stem, "seed": args.seed, "resolution": resolution,
|
| 108 |
+
"steps": sampling.steps, "cfg": sampling.cfg, "mode": images[0].mode,
|
| 109 |
+
"size": list(images[0].size), "total_s": round(total_s, 2),
|
| 110 |
+
"sample_s": round(sample_s, 2), "mllm_s": round(total_s - sample_s, 2),
|
| 111 |
+
"peak_alloc_gib": round(torch.cuda.max_memory_allocated() / 2**30, 2)
|
| 112 |
+
if torch.cuda.is_available() else None,
|
| 113 |
+
"cond_shapes": {k: list(v.shape) for k, v in cond.items()},
|
| 114 |
+
}
|
| 115 |
+
results.append(row)
|
| 116 |
+
print("RUN " + json.dumps(row), flush=True)
|
| 117 |
+
with open(out / "runs.jsonl", "a") as fh: # accumulates across one-prompt-per-process runs
|
| 118 |
+
fh.write(json.dumps(row) + "\n")
|
| 119 |
+
|
| 120 |
+
manifest = {"load_s": round(load_s, 1), "args": {k: str(v) for k, v in vars(args).items()},
|
| 121 |
+
"runs": results}
|
| 122 |
+
(out / "manifest.json").write_text(json.dumps(manifest, indent=2))
|
| 123 |
+
print("BENCH_DONE", out, flush=True)
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
if __name__ == "__main__":
|
| 127 |
+
main()
|
code/tools/sdpa_layout.py
ADDED
|
@@ -0,0 +1,49 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Math SDPA with the DiT's real input layout: [B, L, H, D] permuted to [B, H, L, D] (non-contiguous,
|
| 3 |
+
exactly what diffusers' native attention backend passes) vs the same tensors made contiguous.
|
| 4 |
+
Speed and error vs an fp32 reference, masked, at the cabin prompt's real length.
|
| 5 |
+
|
| 6 |
+
usage: sdpa_layout.py [L]
|
| 7 |
+
"""
|
| 8 |
+
import sys
|
| 9 |
+
import time
|
| 10 |
+
|
| 11 |
+
import torch
|
| 12 |
+
import torch.nn.functional as F
|
| 13 |
+
from torch.nn.attention import SDPBackend, sdpa_kernel
|
| 14 |
+
|
| 15 |
+
L = int(sys.argv[1]) if len(sys.argv) > 1 else 5759
|
| 16 |
+
H, D, dev = 30, 128, "cuda"
|
| 17 |
+
g = torch.Generator(device=dev).manual_seed(0)
|
| 18 |
+
blhd = [torch.randn(1, L, H, D, device=dev, dtype=torch.bfloat16, generator=g) for _ in range(3)]
|
| 19 |
+
q, k, v = (x.permute(0, 2, 1, 3) for x in blhd) # views, as diffusers passes them
|
| 20 |
+
qc, kc, vc = (x.contiguous() for x in (q, k, v))
|
| 21 |
+
mask = torch.ones(1, 1, 1, L, dtype=torch.bool, device=dev)
|
| 22 |
+
mask[..., L - 64:] = False
|
| 23 |
+
with sdpa_kernel(SDPBackend.MATH):
|
| 24 |
+
ref = F.scaled_dot_product_attention(qc.float(), kc.float(), vc.float(), attn_mask=mask)
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
def run(tag, a, b, c, bf16_reduction):
|
| 28 |
+
torch.backends.cuda.allow_fp16_bf16_reduction_math_sdp(bf16_reduction)
|
| 29 |
+
with sdpa_kernel(SDPBackend.MATH):
|
| 30 |
+
out = F.scaled_dot_product_attention(a, b, c, attn_mask=mask)
|
| 31 |
+
torch.cuda.synchronize()
|
| 32 |
+
t0 = time.perf_counter()
|
| 33 |
+
for _ in range(3):
|
| 34 |
+
out = F.scaled_dot_product_attention(a, b, c, attn_mask=mask)
|
| 35 |
+
torch.cuda.synchronize()
|
| 36 |
+
ms = (time.perf_counter() - t0) / 3 * 1000
|
| 37 |
+
rel = ((out.float() - ref).norm() / ref.norm()).item()
|
| 38 |
+
exact = torch.equal(out, base) if base is not None else None
|
| 39 |
+
print(f" {tag:34s} {ms:8.2f} ms rel_l2 {rel:.3e} identical_to_default: {exact}")
|
| 40 |
+
return out
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
base = None
|
| 44 |
+
print(f"torch {torch.__version__} | L={L} | q strides {tuple(q.stride())} contiguous={q.is_contiguous()}")
|
| 45 |
+
base = run("permuted views (DiT today), fp32", q, k, v, False)
|
| 46 |
+
run("contiguous, fp32 (math unchanged)", qc, kc, vc, False)
|
| 47 |
+
run("permuted views, bf16 reduction", q, k, v, True)
|
| 48 |
+
run("contiguous, bf16 reduction", qc, kc, vc, True)
|
| 49 |
+
torch.backends.cuda.allow_fp16_bf16_reduction_math_sdp(False)
|
code/tools/step_probe.py
ADDED
|
@@ -0,0 +1,99 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Per-step timing of Ming-Image's DiT with allocator stats and a GPU clock/power sampler.
|
| 3 |
+
|
| 4 |
+
Diagnoses step time that grows within one generation. For every DiT call it records the
|
| 5 |
+
synchronized wall time, the caching allocator's reserved/allocated bytes, how many device
|
| 6 |
+
mallocs and malloc retries (fragmentation) have happened so far; a sampler thread reads the
|
| 7 |
+
GPU sclk, power and temperature twice a second.
|
| 8 |
+
|
| 9 |
+
usage: PYTHONPATH=<code_dir> step_probe.py --prompt P.json [--runs N] -- <infer.py args>
|
| 10 |
+
"""
|
| 11 |
+
import argparse
|
| 12 |
+
import glob
|
| 13 |
+
import json
|
| 14 |
+
import sys
|
| 15 |
+
import threading
|
| 16 |
+
import time
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
def read_gpu():
|
| 20 |
+
base = "/sys/class/drm/card0/device"
|
| 21 |
+
sclk = next((l.split(":")[1].strip().rstrip("*").strip() for l in open(f"{base}/pp_dpm_sclk") if "*" in l), "?")
|
| 22 |
+
hw = sorted(glob.glob(f"{base}/hwmon/hwmon*"))[0]
|
| 23 |
+
power = int(open(f"{hw}/power1_average").read()) / 1e6
|
| 24 |
+
temp = int(open(f"{hw}/temp1_input").read()) / 1e3
|
| 25 |
+
busy = int(open(f"{base}/gpu_busy_percent").read())
|
| 26 |
+
return sclk, power, temp, busy
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
def main():
|
| 30 |
+
ap = argparse.ArgumentParser()
|
| 31 |
+
ap.add_argument("--prompt", required=True)
|
| 32 |
+
ap.add_argument("--runs", type=int, default=1)
|
| 33 |
+
own, rest = ap.parse_known_args()
|
| 34 |
+
if rest and rest[0] == "--":
|
| 35 |
+
rest = rest[1:]
|
| 36 |
+
sys.argv = [sys.argv[0], "--prompt", own.prompt] + rest
|
| 37 |
+
|
| 38 |
+
import torch
|
| 39 |
+
import infer
|
| 40 |
+
|
| 41 |
+
args = infer.parse_args()
|
| 42 |
+
model_directory = infer.resolve_model_directory(args.model, local_files_only=True)
|
| 43 |
+
caps = infer.load_checkpoint_capabilities(model_directory)
|
| 44 |
+
resolution = infer.resolve_task_resolution(args.task, args.resolution)
|
| 45 |
+
sampling = caps.resolve_sampling_parameters(steps=args.steps, cfg=args.cfg)
|
| 46 |
+
dtype = infer._dtype(args.dtype)
|
| 47 |
+
model, processor = infer.load_model_and_processor(model_directory, args)
|
| 48 |
+
prompt = infer._load_prompt(own.prompt)
|
| 49 |
+
|
| 50 |
+
samples, stop = [], threading.Event()
|
| 51 |
+
|
| 52 |
+
def sampler():
|
| 53 |
+
t0 = time.perf_counter()
|
| 54 |
+
while not stop.is_set():
|
| 55 |
+
samples.append((round(time.perf_counter() - t0, 1),) + read_gpu())
|
| 56 |
+
time.sleep(0.5)
|
| 57 |
+
|
| 58 |
+
dit = model.diffusion_loss.train_model
|
| 59 |
+
marks = {}
|
| 60 |
+
|
| 61 |
+
def pre(_module, _args, _kwargs):
|
| 62 |
+
torch.cuda.synchronize()
|
| 63 |
+
marks["t"] = time.perf_counter()
|
| 64 |
+
|
| 65 |
+
def post(_module, _args, _kwargs, _out):
|
| 66 |
+
torch.cuda.synchronize()
|
| 67 |
+
st = torch.cuda.memory_stats()
|
| 68 |
+
step_log.append({
|
| 69 |
+
"step_s": round(time.perf_counter() - marks["t"], 2),
|
| 70 |
+
"reserved_gib": round(torch.cuda.memory_reserved() / 2**30, 2),
|
| 71 |
+
"allocated_gib": round(torch.cuda.memory_allocated() / 2**30, 2),
|
| 72 |
+
"device_mallocs": st.get("num_device_alloc", 0),
|
| 73 |
+
"device_frees": st.get("num_device_free", 0),
|
| 74 |
+
"alloc_retries": st.get("num_alloc_retries", 0),
|
| 75 |
+
})
|
| 76 |
+
|
| 77 |
+
dit.register_forward_pre_hook(pre, with_kwargs=True)
|
| 78 |
+
dit.register_forward_hook(post, with_kwargs=True)
|
| 79 |
+
thread = threading.Thread(target=sampler, daemon=True)
|
| 80 |
+
thread.start()
|
| 81 |
+
for run in range(own.runs):
|
| 82 |
+
step_log = []
|
| 83 |
+
torch.cuda.synchronize()
|
| 84 |
+
t0 = time.perf_counter()
|
| 85 |
+
infer.run_generation(model, processor, caps, task=args.task, prompt=prompt, input_image=None,
|
| 86 |
+
resolution=resolution, sampling=sampling, seed=args.seed,
|
| 87 |
+
num_layers=args.num_layers, dtype=dtype)
|
| 88 |
+
torch.cuda.synchronize()
|
| 89 |
+
print(f"RUN {run} total_s {time.perf_counter() - t0:.1f}", flush=True)
|
| 90 |
+
for i, row in enumerate(step_log):
|
| 91 |
+
print("STEP " + json.dumps({"run": run, "i": i, **row}), flush=True)
|
| 92 |
+
stop.set()
|
| 93 |
+
thread.join()
|
| 94 |
+
for s in samples[:: max(1, len(samples) // 60)]:
|
| 95 |
+
print("GPU t=%6.1fs sclk=%s power=%.0fW temp=%.0fC busy=%d%%" % s)
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
if __name__ == "__main__":
|
| 99 |
+
main()
|
code/tools/verify_package.py
ADDED
|
@@ -0,0 +1,110 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Pre-upload verification of the INT8 package against the upstream download. Read-only on both trees
|
| 3 |
+
except for writing SHA256SUMS into the package. Exits non-zero on the first failed check.
|
| 4 |
+
|
| 5 |
+
usage: verify_package.py UPSTREAM_DIR PACKAGE_DIR
|
| 6 |
+
"""
|
| 7 |
+
import hashlib
|
| 8 |
+
import json
|
| 9 |
+
import os
|
| 10 |
+
import sys
|
| 11 |
+
from pathlib import Path
|
| 12 |
+
|
| 13 |
+
import torch
|
| 14 |
+
from safetensors import safe_open
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
def fail(msg):
|
| 18 |
+
sys.exit(f"VERIFY_FAIL {msg}")
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
def shard_map(d):
|
| 22 |
+
index = json.loads((d / "model.safetensors.index.json").read_text())
|
| 23 |
+
return index["weight_map"]
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
def main():
|
| 27 |
+
up, pkg = Path(sys.argv[1]), Path(sys.argv[2])
|
| 28 |
+
|
| 29 |
+
# 1. connector: bf16 file == upstream fp32 cast to bf16, tensor by tensor
|
| 30 |
+
up_map = shard_map(up / "connector")
|
| 31 |
+
with safe_open(str(pkg / "connector/model.safetensors"), "pt") as new:
|
| 32 |
+
if set(new.keys()) != set(up_map):
|
| 33 |
+
fail("connector tensor set differs from upstream")
|
| 34 |
+
n = 0
|
| 35 |
+
for shard in sorted(set(up_map.values())):
|
| 36 |
+
with safe_open(str(up / "connector" / shard), "pt") as old:
|
| 37 |
+
for key in old.keys():
|
| 38 |
+
ref = old.get_tensor(key)
|
| 39 |
+
ref = ref.to(torch.bfloat16) if ref.is_floating_point() else ref
|
| 40 |
+
got = new.get_tensor(key)
|
| 41 |
+
if got.dtype != ref.dtype or not torch.equal(got, ref):
|
| 42 |
+
fail(f"connector {key} != fp32->bf16")
|
| 43 |
+
n += 1
|
| 44 |
+
print(f"OK connector: {n} tensors equal upstream fp32 -> bf16", flush=True)
|
| 45 |
+
|
| 46 |
+
# 2. unchanged components: hardlink (same inode) or identical bytes
|
| 47 |
+
same = 0
|
| 48 |
+
for comp in ("transformer", "vae", "mlp", "scheduler"):
|
| 49 |
+
for f in sorted((up / comp).rglob("*")):
|
| 50 |
+
if f.is_dir():
|
| 51 |
+
continue
|
| 52 |
+
g = pkg / f.relative_to(up)
|
| 53 |
+
if not g.is_file():
|
| 54 |
+
fail(f"missing {g}")
|
| 55 |
+
if os.stat(f).st_ino != os.stat(g).st_ino and f.read_bytes() != g.read_bytes():
|
| 56 |
+
fail(f"{g} differs from upstream")
|
| 57 |
+
same += 1
|
| 58 |
+
if (up / "LICENSE").read_bytes() != (pkg / "LICENSE").read_bytes():
|
| 59 |
+
fail("LICENSE differs from upstream")
|
| 60 |
+
print(f"OK unchanged components: {same} files identical to upstream (+ LICENSE)", flush=True)
|
| 61 |
+
|
| 62 |
+
# 3. mllm: copied tensors byte-identical, quantized ones present as int8 + fp32 scale
|
| 63 |
+
manifest = json.loads((pkg / "mllm/int8_manifest.json").read_text())
|
| 64 |
+
quant = set(manifest["quantized_modules"])
|
| 65 |
+
old_map, new_map = shard_map(up / "mllm"), shard_map(pkg / "mllm")
|
| 66 |
+
expect_new = {k for k in old_map if k[: -len(".weight")] not in quant or not k.endswith(".weight")}
|
| 67 |
+
expect_new |= {m + ".weight" for m in quant} | {m + ".scale" for m in quant}
|
| 68 |
+
if set(new_map) != expect_new:
|
| 69 |
+
fail(f"mllm index: {len(set(new_map) ^ expect_new)} names differ from the expected set")
|
| 70 |
+
handles = {}
|
| 71 |
+
|
| 72 |
+
def tensor(tree, mapping, key):
|
| 73 |
+
path = str(tree / mapping[key])
|
| 74 |
+
if path not in handles:
|
| 75 |
+
handles[path] = safe_open(path, "pt")
|
| 76 |
+
return handles[path].get_tensor(key)
|
| 77 |
+
|
| 78 |
+
copied = quantized = 0
|
| 79 |
+
for key in sorted(old_map):
|
| 80 |
+
module = key[: -len(".weight")] if key.endswith(".weight") else None
|
| 81 |
+
ref = tensor(up / "mllm", old_map, key)
|
| 82 |
+
if module in quant:
|
| 83 |
+
w, s = tensor(pkg / "mllm", new_map, key), tensor(pkg / "mllm", new_map, module + ".scale")
|
| 84 |
+
if w.dtype != torch.int8 or s.dtype != torch.float32 or w.shape != ref.shape or s.shape != (ref.shape[0],):
|
| 85 |
+
fail(f"{key}: int8/scale dtype or shape wrong")
|
| 86 |
+
quantized += 1
|
| 87 |
+
else:
|
| 88 |
+
got = tensor(pkg / "mllm", new_map, key)
|
| 89 |
+
if got.dtype != ref.dtype or not torch.equal(got, ref):
|
| 90 |
+
fail(f"{key}: copied tensor differs from upstream")
|
| 91 |
+
copied += 1
|
| 92 |
+
if len(handles) > 4:
|
| 93 |
+
handles.clear()
|
| 94 |
+
print(f"OK mllm: {copied} tensors byte-identical to upstream, {quantized} quantized (int8 + fp32 scale)", flush=True)
|
| 95 |
+
|
| 96 |
+
# 4. sha256 of every file in the package
|
| 97 |
+
lines = []
|
| 98 |
+
for f in sorted(p for p in pkg.rglob("*") if p.is_file() and p.name != "SHA256SUMS" and ".cache" not in p.parts):
|
| 99 |
+
h = hashlib.sha256()
|
| 100 |
+
with open(f, "rb") as fh:
|
| 101 |
+
for chunk in iter(lambda: fh.read(1 << 24), b""):
|
| 102 |
+
h.update(chunk)
|
| 103 |
+
lines.append(f"{h.hexdigest()} {f.relative_to(pkg).as_posix()}")
|
| 104 |
+
(pkg / "SHA256SUMS").write_text("\n".join(lines) + "\n")
|
| 105 |
+
print(f"OK sha256: {len(lines)} files -> SHA256SUMS", flush=True)
|
| 106 |
+
print("VERIFY_OK", flush=True)
|
| 107 |
+
|
| 108 |
+
|
| 109 |
+
if __name__ == "__main__":
|
| 110 |
+
main()
|
connector/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1522edb909db45f90d3628aa5cb03805fba81aca1950dfe9385b057c6b636a47
|
| 3 |
+
size 3087467144
|
mllm/model-00001-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fd19afe5acf56675a154a2ea5f79a7844514d7500dd4efe6b7e771524fdf9c52
|
| 3 |
+
size 4999024272
|
mllm/model-00002-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a1f3472a28da6607565cd2e31324c25b17499b61620666d090d3f6a434ebdfa7
|
| 3 |
+
size 5000397680
|
mllm/model-00003-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d9be6de14c1f0fabaab1941b895bee49e97a015a469f7da31e622f6f10ba368e
|
| 3 |
+
size 5000680224
|
mllm/model-00004-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c770d343ff03238ec3f3a6c2cb594c7efe286eca5a790612bbe72c4e5155783c
|
| 3 |
+
size 3764771128
|
mllm/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e7ff01708d504f7bf4dbf7f5815adde57bab9a40e7f563ab6ad1acace4464917
|
| 3 |
+
size 12210709
|
mlp/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:53e47c1ec942749f07025a41be148f5e8364d8587aa2d954969716abe521b77b
|
| 3 |
+
size 124837576
|
samples/cabin_upstream.png
ADDED
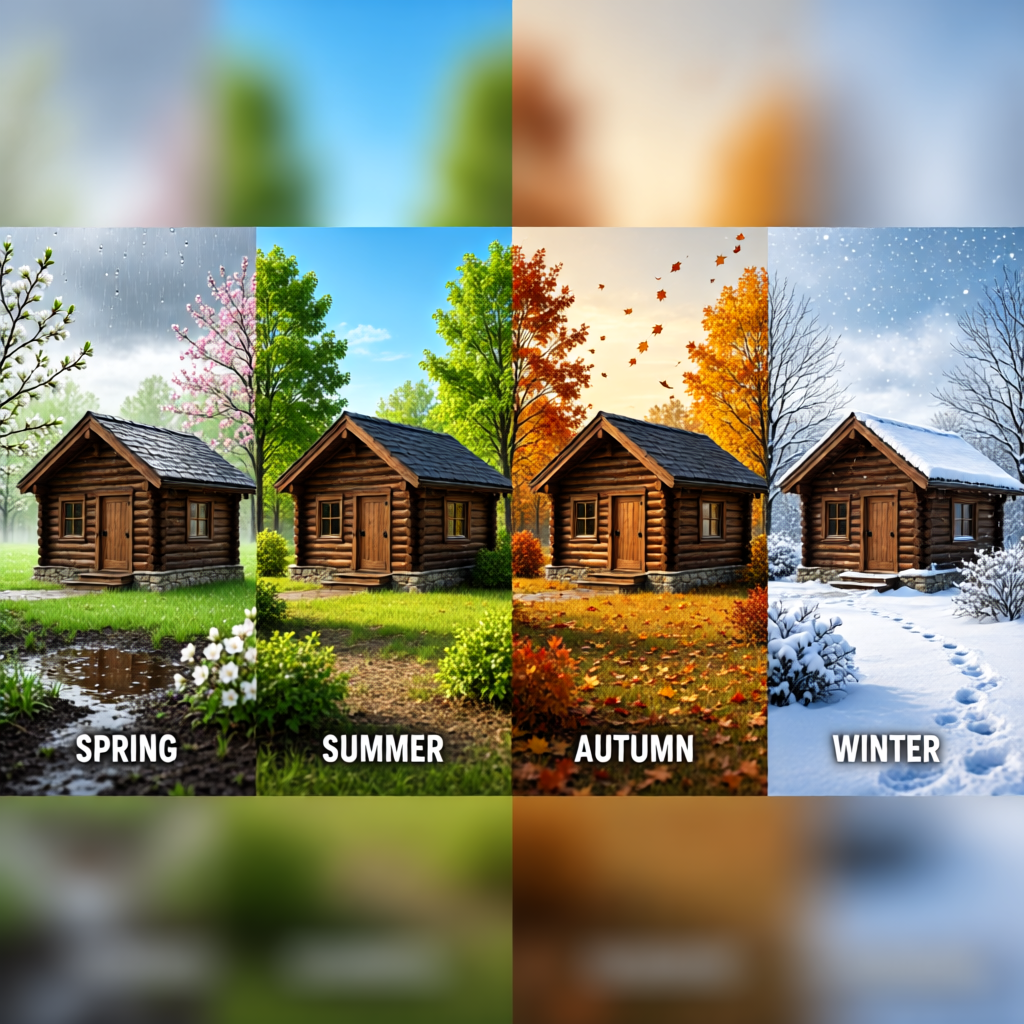
|
Git LFS Details
|
samples/e2e_daily_grind.png
ADDED
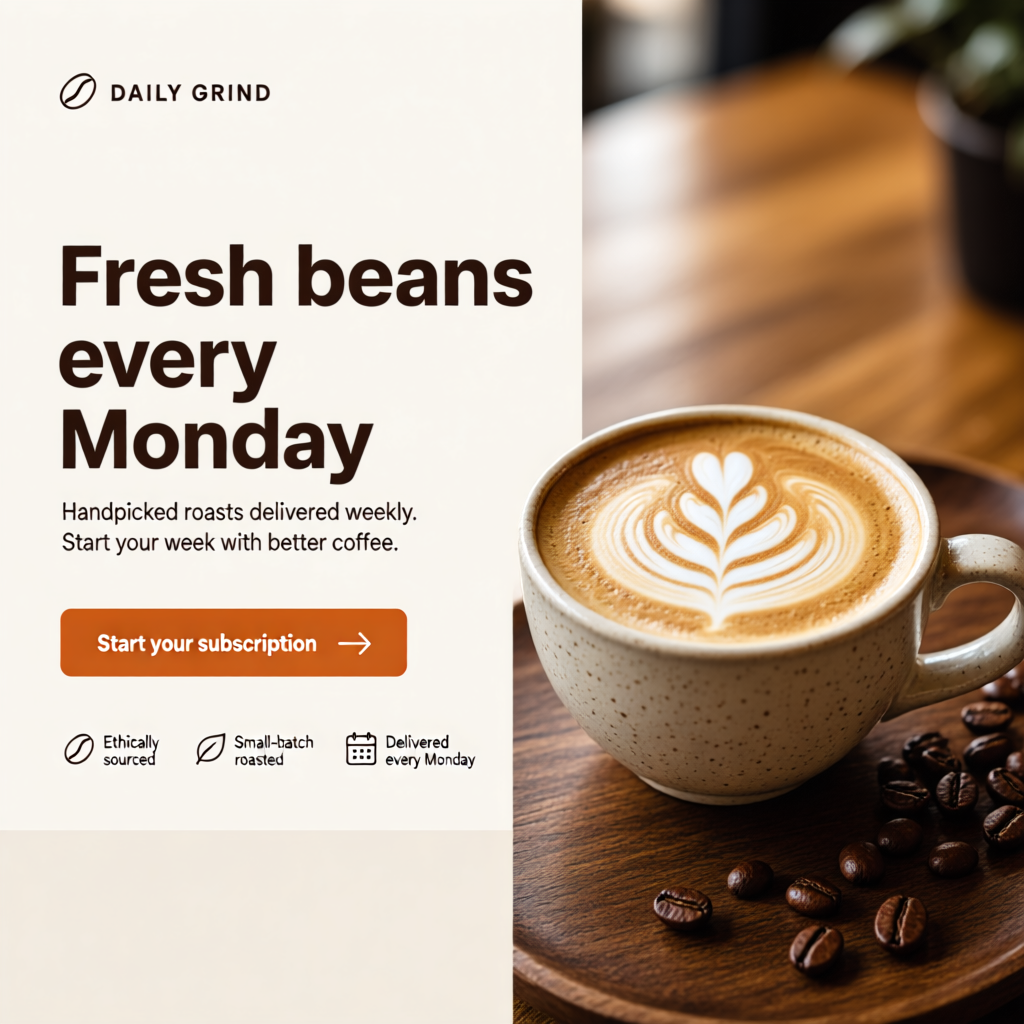
|
Git LFS Details
|
samples/info_water.png
ADDED
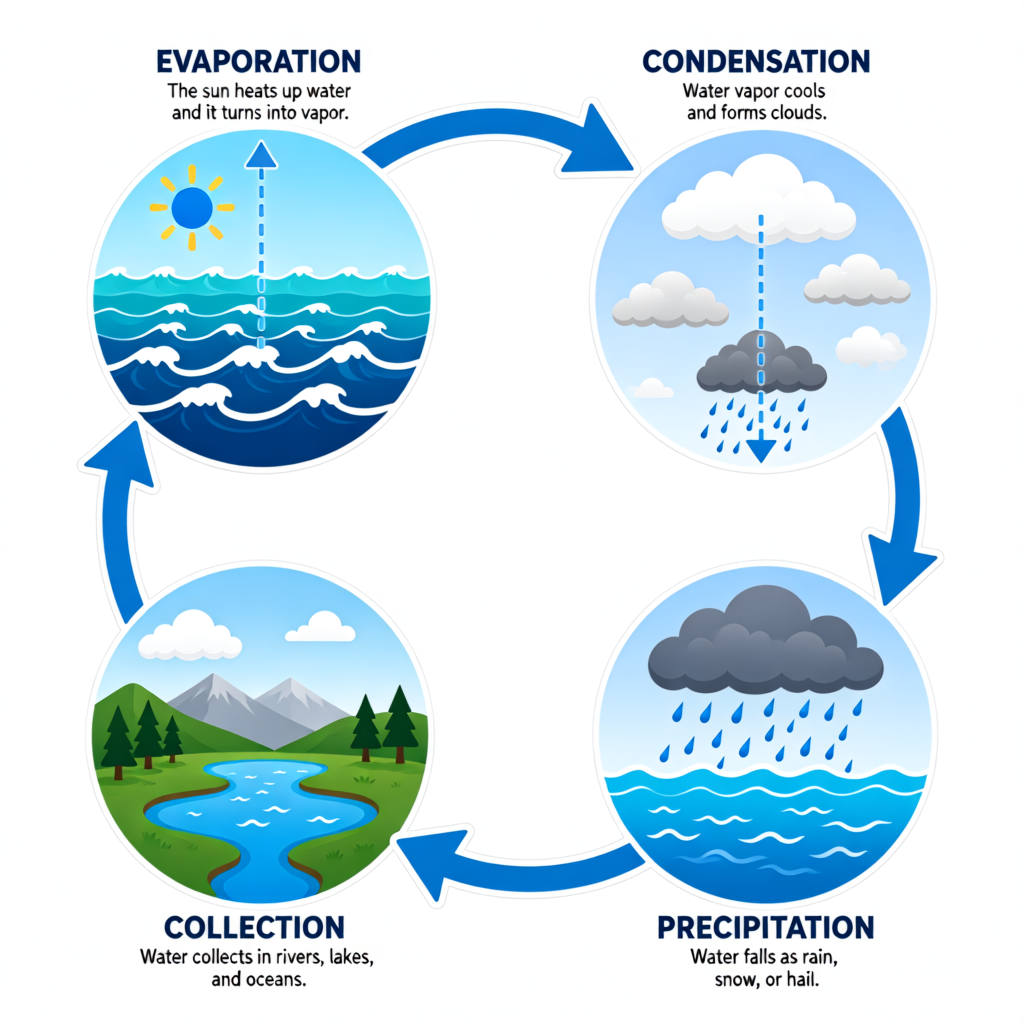
|
Git LFS Details
|
samples/poster_jazz.png
ADDED

|
Git LFS Details
|
samples/ui_banking.png
ADDED
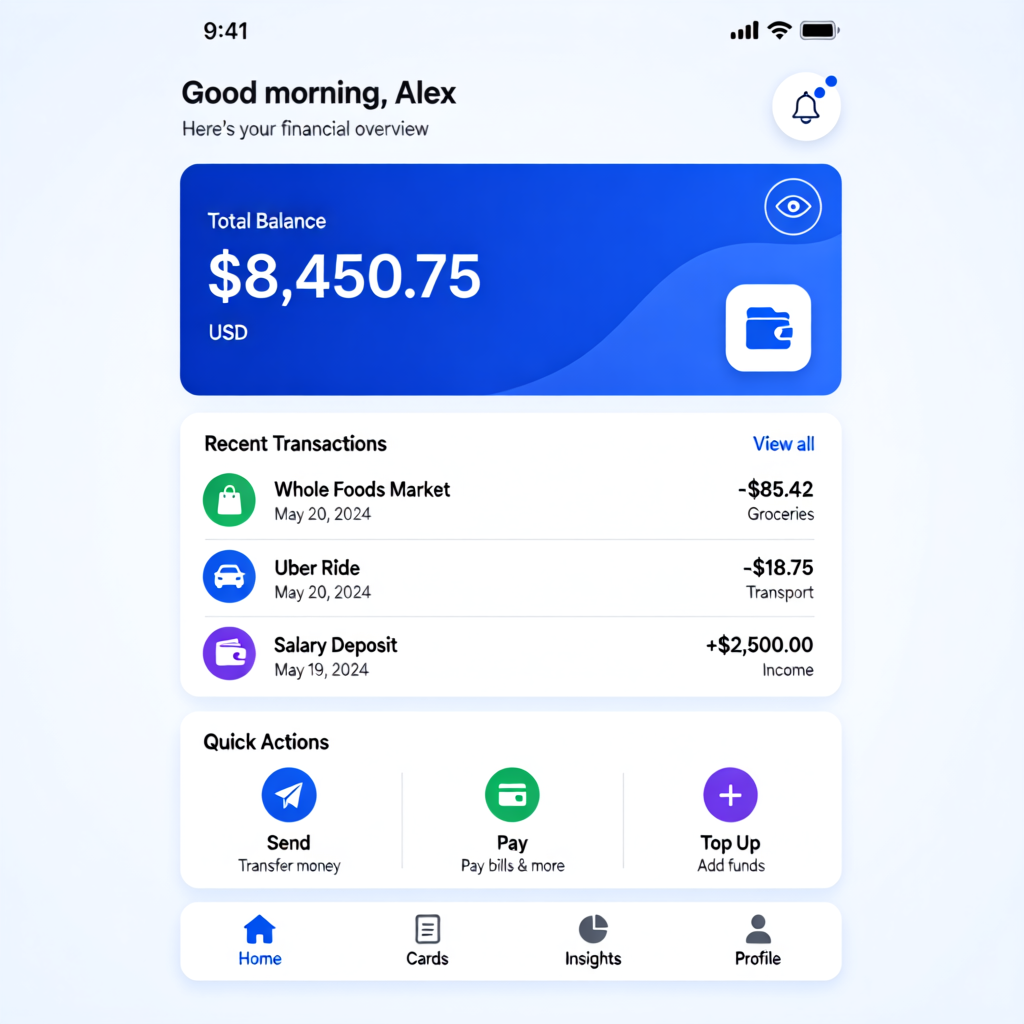
|
Git LFS Details
|
transformer/diffusion_pytorch_model-00001-of-00005.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1488ae867d45a4c184fa0df9fde68d8f7bd9c2dea52b611b77fc6bbd685d9d70
|
| 3 |
+
size 2990953408
|
transformer/diffusion_pytorch_model-00002-of-00005.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6f9441923d41408c74bd3761a34eb4db2c583fc08d5785a2c7f2260c8e17089e
|
| 3 |
+
size 2924069536
|
transformer/diffusion_pytorch_model-00003-of-00005.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:45cbd9a557c20c7ae5d676049b301f4856046be2f802f3e9e7de477c77a35b8c
|
| 3 |
+
size 2973221624
|
transformer/diffusion_pytorch_model-00004-of-00005.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:73c70763356a57d5d3cd04e91e714cb0b86081a3e922b594659b58f2ab49bc90
|
| 3 |
+
size 2973221616
|
transformer/diffusion_pytorch_model-00005-of-00005.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0c178789512c7f5d45a7b0c1c561f868704cd0fa77d4cb32f8d7ea06b2707781
|
| 3 |
+
size 448391960
|
vae/diffusion_pytorch_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06520463778e64dca1039c7447890065ee220bc408d15412182e5c3e06f304f1
|
| 3 |
+
size 253817336
|