Text Generation
Transformers
GGUF
English
mistral
Not-For-All-Audiences
8-bit precision
bitsandbytes
Instructions to use lemonilia/Limamono-Mistral-7B-v0.50 with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- Transformers
How to use lemonilia/Limamono-Mistral-7B-v0.50 with Transformers:
# Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation", model="lemonilia/Limamono-Mistral-7B-v0.50")# Load model directly from transformers import AutoTokenizer, AutoModelForCausalLM tokenizer = AutoTokenizer.from_pretrained("lemonilia/Limamono-Mistral-7B-v0.50") model = AutoModelForCausalLM.from_pretrained("lemonilia/Limamono-Mistral-7B-v0.50", device_map="auto") - Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- llama.cpp
How to use lemonilia/Limamono-Mistral-7B-v0.50 with llama.cpp:
Install (macOS, Linux)
curl -LsSf https://llama.app/install.sh | sh # Start a local OpenAI-compatible server with a web UI: llama serve -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K # Run inference directly in the terminal: llama cli -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
Install from WinGet (Windows)
winget install llama.cpp # Start a local OpenAI-compatible server with a web UI: llama serve -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K # Run inference directly in the terminal: llama cli -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
Use pre-built binary
# Download pre-built binary from: # https://github.com/ggerganov/llama.cpp/releases # Start a local OpenAI-compatible server with a web UI: ./llama-server -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K # Run inference directly in the terminal: ./llama-cli -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
Build from source code
git clone https://github.com/ggerganov/llama.cpp.git cd llama.cpp cmake -B build cmake --build build -j --target llama-server llama-cli # Start a local OpenAI-compatible server with a web UI: ./build/bin/llama-server -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K # Run inference directly in the terminal: ./build/bin/llama-cli -hf lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
Use Docker
docker model run hf.co/lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
- LM Studio
- Jan
- vLLM
How to use lemonilia/Limamono-Mistral-7B-v0.50 with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "lemonilia/Limamono-Mistral-7B-v0.50" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "lemonilia/Limamono-Mistral-7B-v0.50", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'Use Docker
docker model run hf.co/lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
- SGLang
How to use lemonilia/Limamono-Mistral-7B-v0.50 with SGLang:
Install from pip and serve model
# Install SGLang from pip: pip install sglang # Start the SGLang server: python3 -m sglang.launch_server \ --model-path "lemonilia/Limamono-Mistral-7B-v0.50" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "lemonilia/Limamono-Mistral-7B-v0.50", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'Use Docker images
docker run --gpus all \ --shm-size 32g \ -p 30000:30000 \ -v ~/.cache/huggingface:/root/.cache/huggingface \ --env "HF_TOKEN=<secret>" \ --ipc=host \ lmsysorg/sglang:latest \ python3 -m sglang.launch_server \ --model-path "lemonilia/Limamono-Mistral-7B-v0.50" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "lemonilia/Limamono-Mistral-7B-v0.50", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }' - Ollama
How to use lemonilia/Limamono-Mistral-7B-v0.50 with Ollama:
ollama run hf.co/lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
- Unsloth Desktop
- Docker Model Runner
How to use lemonilia/Limamono-Mistral-7B-v0.50 with Docker Model Runner:
docker model run hf.co/lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
- Lemonade
How to use lemonilia/Limamono-Mistral-7B-v0.50 with Lemonade:
Pull the model
# Download Lemonade from https://lemonade-server.ai/ lemonade pull lemonilia/Limamono-Mistral-7B-v0.50:Q2_K
Run and chat with the model
lemonade run user.Limamono-Mistral-7B-v0.50-Q2_K
List all available models
lemonade list
- Atomic Chat
Update README.md
Browse files
README.md
CHANGED
|
@@ -7,8 +7,8 @@ tags:
|
|
| 7 |
- not-for-all-audiences
|
| 8 |
---
|
| 9 |
|
| 10 |
-
# Limamono-7B (Mistral) v0.
|
| 11 |
-
This is an **early version** (
|
| 12 |
_extremely limited_ amounts of almost entirely synthetic data of hopefully higher quality than typical
|
| 13 |
human conversations. The intended target audience is straight men and lesbians.
|
| 14 |
|
|
@@ -154,7 +154,7 @@ in the repository.
|
|
| 154 |
## Text generation settings
|
| 155 |
For testing I use these settings:
|
| 156 |
- Temperature: 1.0
|
| 157 |
-
- Tail-Free Sampling: 0.85
|
| 158 |
- Repetition Penalty: 1.11
|
| 159 |
- Repetition Penalty range: 2048
|
| 160 |
- Top-p: 1 (disabled), Top-k: 0 (disabled)
|
|
@@ -163,7 +163,7 @@ For testing I use these settings:
|
|
| 163 |
[Axolotl](https://github.com/OpenAccess-AI-Collective/axolotl) was used for training
|
| 164 |
on one NVidia RTX3090.
|
| 165 |
|
| 166 |
-
The training data consisted of **
|
| 167 |
of roughly 4k tokens length. The learning rate is the one that about minimizes the
|
| 168 |
eval loss on one epoch with a constant learning schedule. For the following two epochs
|
| 169 |
what would be normally considered overfitting occurs, but at the same time output
|
|
@@ -182,7 +182,7 @@ quality also improves.
|
|
| 182 |
- micro_batch_size: 1
|
| 183 |
- num_epochs: 3
|
| 184 |
- optimizer: adamw_torch
|
| 185 |
-
- lr_scheduler:
|
| 186 |
- learning_rate: 0.0002
|
| 187 |
- weight_decay: 0.1
|
| 188 |
- train_on_inputs: false
|
|
@@ -192,8 +192,4 @@ quality also improves.
|
|
| 192 |
- tf32: true
|
| 193 |
|
| 194 |
### Train loss graph
|
| 195 |
-
|
| 196 |
-
with similar end results but a smoother graph without sudden jumps compared to finetuning
|
| 197 |
-
unique data for 3 epochs.
|
| 198 |
-
|
| 199 |
-
|
|
|
|
| 7 |
- not-for-all-audiences
|
| 8 |
---
|
| 9 |
|
| 10 |
+
# Limamono-7B (Mistral) v0.50
|
| 11 |
+
This is an **early version** (50% completed) of a strongly NSFW roleplaying model trained with
|
| 12 |
_extremely limited_ amounts of almost entirely synthetic data of hopefully higher quality than typical
|
| 13 |
human conversations. The intended target audience is straight men and lesbians.
|
| 14 |
|
|
|
|
| 154 |
## Text generation settings
|
| 155 |
For testing I use these settings:
|
| 156 |
- Temperature: 1.0
|
| 157 |
+
- Tail-Free Sampling: 0.85
|
| 158 |
- Repetition Penalty: 1.11
|
| 159 |
- Repetition Penalty range: 2048
|
| 160 |
- Top-p: 1 (disabled), Top-k: 0 (disabled)
|
|
|
|
| 163 |
[Axolotl](https://github.com/OpenAccess-AI-Collective/axolotl) was used for training
|
| 164 |
on one NVidia RTX3090.
|
| 165 |
|
| 166 |
+
The training data consisted of **50** conversations (199k tokens / 1117 messages)
|
| 167 |
of roughly 4k tokens length. The learning rate is the one that about minimizes the
|
| 168 |
eval loss on one epoch with a constant learning schedule. For the following two epochs
|
| 169 |
what would be normally considered overfitting occurs, but at the same time output
|
|
|
|
| 182 |
- micro_batch_size: 1
|
| 183 |
- num_epochs: 3
|
| 184 |
- optimizer: adamw_torch
|
| 185 |
+
- lr_scheduler: cosine
|
| 186 |
- learning_rate: 0.0002
|
| 187 |
- weight_decay: 0.1
|
| 188 |
- train_on_inputs: false
|
|
|
|
| 192 |
- tf32: true
|
| 193 |
|
| 194 |
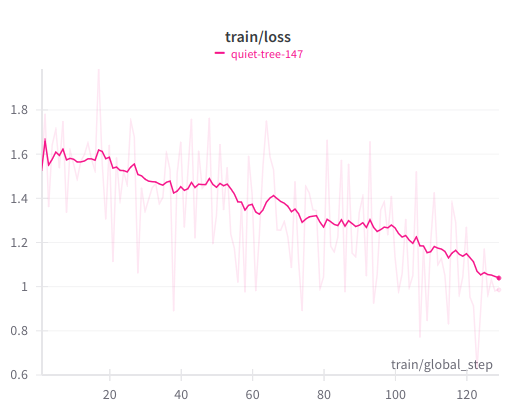
### Train loss graph
|
| 195 |
+

|
|
|
|
|
|
|
|
|
|
|
|