


Copy of mlboydaisuke/Depth-Anything-3-Small-LiteRT at 15344dc67dca
Browse files- .gitattributes +3 -0
- README.md +86 -0
- da3_small_gpu_fp16.tflite +3 -0
- samples/alley.png +3 -0
- samples/avenue.png +3 -0
- samples/sydney_official_vs_litert.png +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,6 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
samples/avenue.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
samples/alley.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
samples/sydney_official_vs_litert.png filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,86 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
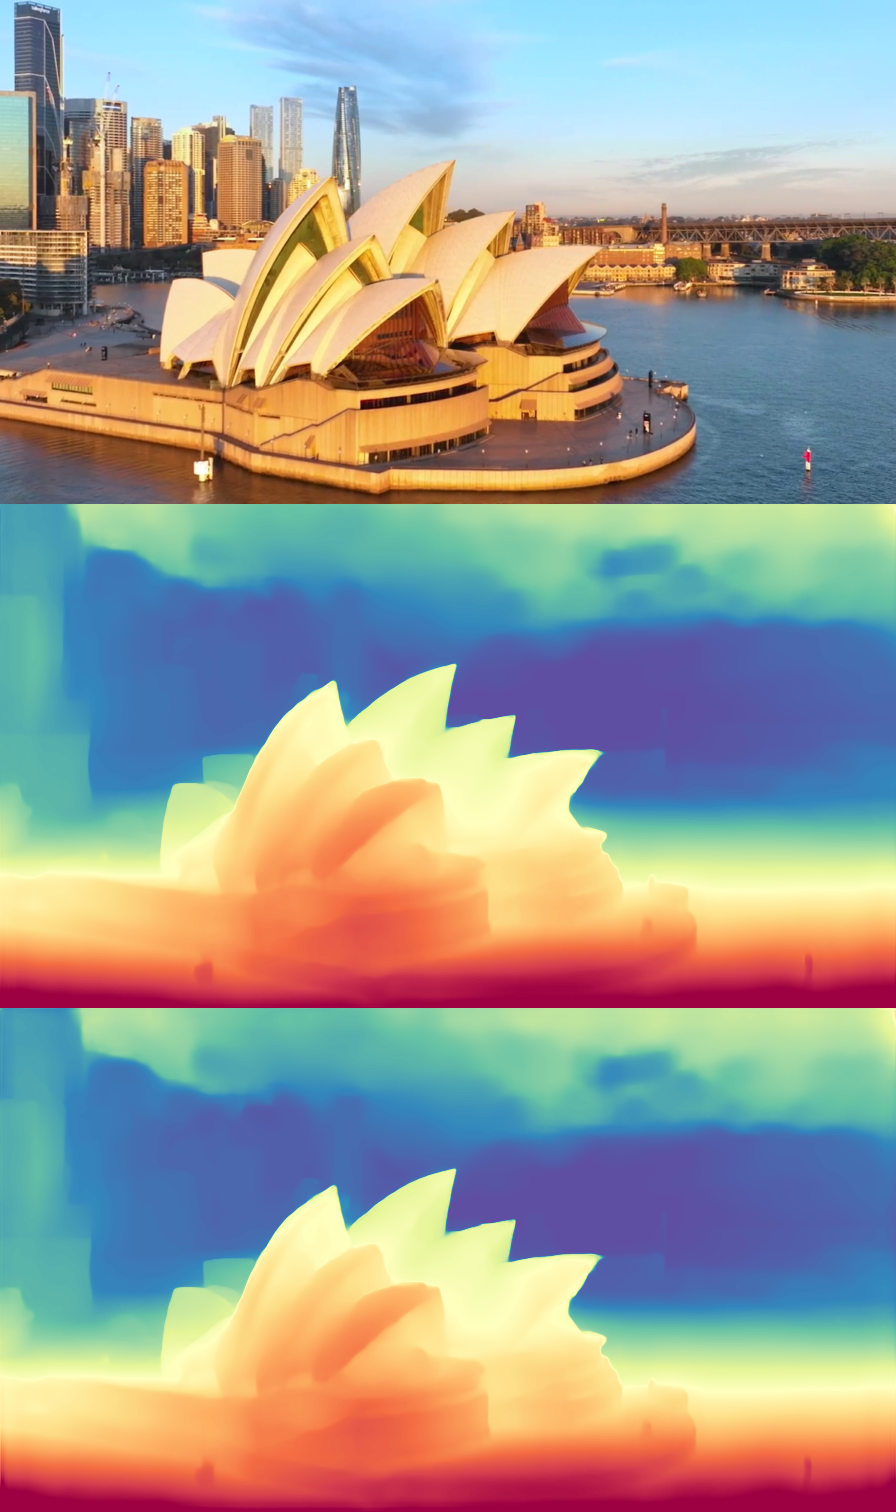
|
|
|
|
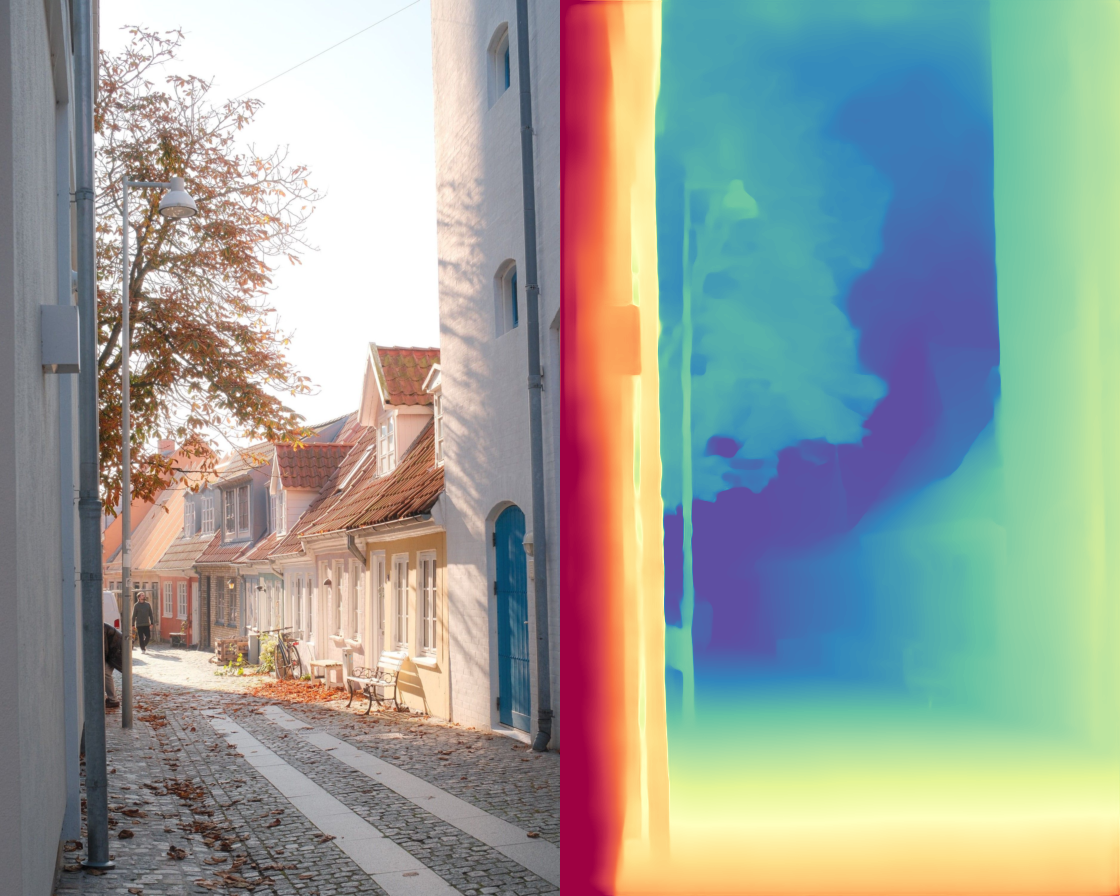
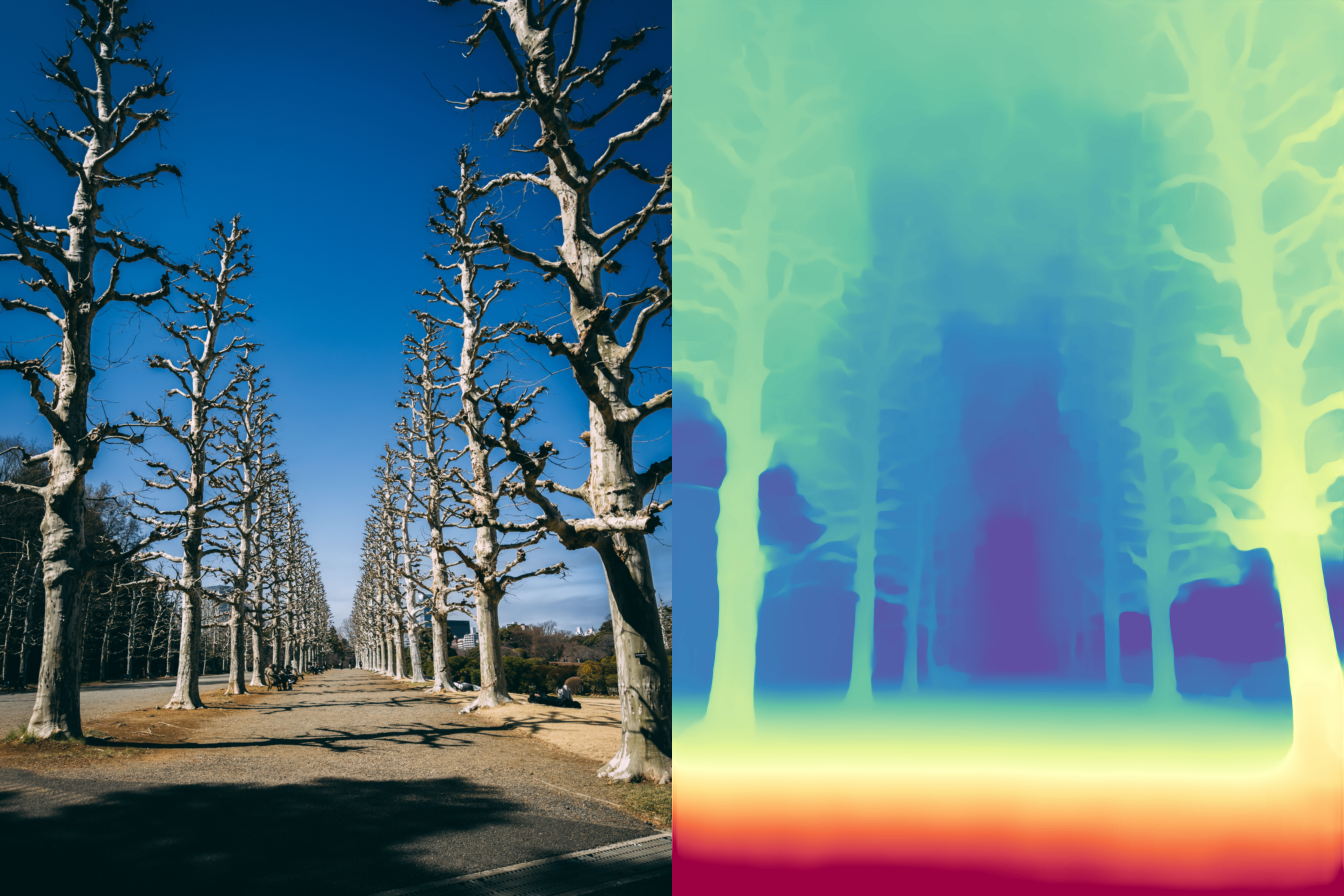
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
library_name: litert
|
| 4 |
+
pipeline_tag: depth-estimation
|
| 5 |
+
tags:
|
| 6 |
+
- litert
|
| 7 |
+
- tflite
|
| 8 |
+
- depth-estimation
|
| 9 |
+
- monocular-depth
|
| 10 |
+
- on-device
|
| 11 |
+
- gpu
|
| 12 |
+
- depth-anything
|
| 13 |
+
base_model: depth-anything/DA3-SMALL
|
| 14 |
+
base_model_relation: quantized
|
| 15 |
+
---
|
| 16 |
+
|
| 17 |
+
# Depth Anything 3 (Small) — LiteRT GPU, monocular depth
|
| 18 |
+
|
| 19 |
+
On-device **LiteRT / TFLite** conversion of [**Depth Anything 3 — Small**](https://huggingface.co/depth-anything/DA3-SMALL)
|
| 20 |
+
(ByteDance-Seed, Apache-2.0) for **monocular depth**, running fully on the mobile **GPU** via the LiteRT
|
| 21 |
+
`CompiledModel` API (ML Drift delegate). No CPU fallback ops — the whole graph is GPU-compatible.
|
| 22 |
+
|
| 23 |
+
| | |
|
| 24 |
+
|---|---|
|
| 25 |
+
| Task | Monocular depth (single RGB → depth) |
|
| 26 |
+
| Backbone | DINOv2 ViT-S + RoPE, DPT/DualDPT depth head |
|
| 27 |
+
| Input | `[1, 3, 896, 504]` NCHW float32, ImageNet-normalized, **native portrait aspect** |
|
| 28 |
+
| Output | `[1, 1, 896, 504]` depth |
|
| 29 |
+
| Precision / size | FP16, **55 MB** |
|
| 30 |
+
| Device | Pixel 8a, LiteRT GPU (`Accelerator.GPU`), **~1.8 s / image** |
|
| 31 |
+
| Fidelity | **Pearson corr 0.99948** vs the official PyTorch DA3-Small pipeline |
|
| 32 |
+
|
| 33 |
+
## Why a fixed 896×504 (native aspect, not square)
|
| 34 |
+
|
| 35 |
+
DA3 processes images at their **native aspect ratio** (`upper_bound_resize`, longer side → 896, multiple of 14).
|
| 36 |
+
Forcing a square `896×896` and letterbox-padding drops the match to corr **0.977** (the black padding leaks into
|
| 37 |
+
the content through global attention). Converting at the native rectangle restores **corr 0.9994** and is also
|
| 38 |
+
faster (fewer tokens). This checkpoint is built for **portrait ~9:16**. For another aspect, re-convert at that
|
| 39 |
+
shape (or your camera's fixed aspect) with the script below.
|
| 40 |
+
|
| 41 |
+
## Preprocessing (must match)
|
| 42 |
+
|
| 43 |
+
```
|
| 44 |
+
resize to 504×896 (W×H) → x/255 → (x - mean) / std
|
| 45 |
+
mean = [0.485, 0.456, 0.406], std = [0.229, 0.224, 0.225] # ImageNet, RGB, NCHW
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
## GPU-clean conversion (what was patched)
|
| 49 |
+
|
| 50 |
+
Converted with `litert-torch`. DA3 is not GPU-clean out of the box; the following exact, GPU-clean rewrites
|
| 51 |
+
were applied (all numerically faithful unless noted):
|
| 52 |
+
|
| 53 |
+
1. checkpoint `model.` key-prefix strip (load fix)
|
| 54 |
+
2. RoPE `max_position = int(positions.max())+1` → constant (torch.export data-dependent)
|
| 55 |
+
3. fused-QKV attention → 3 separate Linears + 4D attention (avoids 5D RESHAPE; exact, 1e-6)
|
| 56 |
+
4. **LayerScale** `gamma` folded into `attn.proj` / `mlp.fc2` (the LayerScale MUL otherwise mis-lays-out the
|
| 57 |
+
token dim on the GPU delegate: `fully_connected {1,1,N,C} vs {N,1,1,C}`)
|
| 58 |
+
5. `pos_embed` bicubic interpolation **baked** to a constant (the interpolate of a constant emits `GATHER_ND`
|
| 59 |
+
on desktop and `RESIZE_BILINEAR` with 0 runtime inputs on device)
|
| 60 |
+
6. **ConvTranspose2d(k=s,stride=s)** → zero-stuff (nearest-upsample × top-left mask) + `Conv2d` (flipped
|
| 61 |
+
weight) — exact equivalent (~1e-7), because the Pixel-8a GPU rejects `TRANSPOSE_CONV` and the conv+
|
| 62 |
+
depth-to-space alternative needs >4D
|
| 63 |
+
7. DPT-head `custom_interpolate` `align_corners=True → False` (GPU bans `align_corners=True` resize) — **the
|
| 64 |
+
only non-exact rewrite**; source of the residual ~0.05 % vs the official model
|
| 65 |
+
8. head UV pos-embed-again disabled (its `make_sincos` broadcast emits `BROADCAST_TO`; ratio-0.1 refinement)
|
| 66 |
+
9. camera-token insertion `x[:, :, 0] = cam_token` → `torch.cat` (in-place index-assign → `SELECT_V2`)
|
| 67 |
+
|
| 68 |
+
Net result: `GATHER_ND = 0`, no `>4D` tensors, no `TRANSPOSE_CONV` / `BROADCAST_TO` / banned ops.
|
| 69 |
+
|
| 70 |
+
## Fidelity note (honest)
|
| 71 |
+
|
| 72 |
+
corr **0.99948** vs the official FP32 PyTorch pipeline. FP16 is **not** a factor (FP32≡FP16, corr 1.0). The
|
| 73 |
+
residual ~0.05 % is the `align_corners=True→False` change in (7), which the mobile GPU forces — an irreducible
|
| 74 |
+
hardware constraint, not a conversion error. Structure and edge sharpness are visually identical.
|
| 75 |
+
|
| 76 |
+
## Usage (Android / LiteRT CompiledModel)
|
| 77 |
+
|
| 78 |
+
```kotlin
|
| 79 |
+
val model = CompiledModel.create(context.assets, "da3_small_gpu_fp16.tflite",
|
| 80 |
+
CompiledModel.Options(Accelerator.GPU), null)
|
| 81 |
+
// input: [1,3,896,504] NCHW, ImageNet-normalized; output: [1,1,896,504] depth
|
| 82 |
+
```
|
| 83 |
+
|
| 84 |
+
## License
|
| 85 |
+
|
| 86 |
+
Apache-2.0, inherited from the upstream [Depth Anything 3](https://github.com/ByteDance-Seed/depth-anything-3).
|
da3_small_gpu_fp16.tflite
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e170369a72ba1bba7486a4d2de555639fccd0595a9bb5b5349f7733ed4aebd1f
|
| 3 |
+
size 55035456
|
samples/alley.png
ADDED
|
Git LFS Details
|
samples/avenue.png
ADDED
|
Git LFS Details
|
samples/sydney_official_vs_litert.png
ADDED
|
Git LFS Details
|