


Release measured v1.2 update
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +9 -0
- ATTRIBUTIONS.md +10 -0
- EVALUATION.md +92 -93
- NORMALIZATION_RUNTIME.md +5 -0
- QUESTION-SCALING.md +64 -55
- README.md +26 -55
- RUNTIME.md +1 -1
- RUNTIME_BINDING.json +76 -0
- SOURCE_BUNDLE_MANIFEST.json +173 -0
- assets/decision-capabilities.svg +0 -0
- assets/{architecture-atlas.pdf → decision-expanded-old_core-600px.png} +2 -2
- assets/decision-expanded-old_core.pdf +0 -0
- assets/{architecture.pdf → decision-expanded-old_core.png} +2 -2
- assets/decision-expanded-old_core.svg +1434 -0
- assets/decision-expanded-overview-600px.png +0 -0
- assets/decision-expanded-overview.pdf +0 -0
- assets/{decision-capabilities.pdf → decision-expanded-overview.png} +2 -2
- assets/decision-expanded-overview.svg +714 -0
- assets/decision-expanded-ranking-600px.png +0 -0
- assets/{decision-quality.pdf → decision-expanded-ranking.pdf} +0 -0
- assets/{decision-capabilities.png → decision-expanded-ranking.png} +2 -2
- assets/{decision-quality.svg → decision-expanded-ranking.svg} +227 -264
- assets/decision-expanded-v3_core-600px.png +3 -0
- assets/decision-expanded-v3_core.pdf +0 -0
- assets/decision-expanded-v3_core.png +3 -0
- assets/decision-expanded-v3_core.svg +1434 -0
- assets/decision-expanded-v4-600px.png +0 -0
- assets/decision-expanded-v4.pdf +0 -0
- assets/decision-expanded-v4.png +3 -0
- assets/decision-expanded-v4.svg +594 -0
- assets/decision-expanded-v5-600px.png +0 -0
- assets/decision-expanded-v5.pdf +0 -0
- assets/decision-expanded-v5.png +3 -0
- assets/decision-expanded-v5.svg +714 -0
- assets/decision-mark.png +0 -3
- assets/decision-quality.png +0 -3
- assets/decision-question-scaling-600px.png +0 -0
- assets/decision-question-scaling.pdf +0 -0
- assets/decision-question-scaling.png +0 -0
- assets/decision-question-scaling.svg +122 -203
- assets/readout.pdf +0 -3
- assets/readout.svg +0 -92
- backbone/model-00001-of-00003.safetensors +1 -1
- backbone/model-00002-of-00003.safetensors +1 -1
- backbone/model-00003-of-00003.safetensors +1 -1
- bundle-manifest.json +84 -26
- code/decision_api.py +27 -0
- code/profile_guard.py +82 -0
- code/runtime_profile.py +36 -0
- decision_head.safetensors +1 -1
.gitattributes
CHANGED
|
@@ -44,3 +44,12 @@ assets/decision-quality.png filter=lfs diff=lfs merge=lfs -text
|
|
| 44 |
assets/readout.pdf filter=lfs diff=lfs merge=lfs -text
|
| 45 |
assets/readout.png filter=lfs diff=lfs merge=lfs -text
|
| 46 |
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 44 |
assets/readout.pdf filter=lfs diff=lfs merge=lfs -text
|
| 45 |
assets/readout.png filter=lfs diff=lfs merge=lfs -text
|
| 46 |
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 47 |
+
assets/decision-expanded-old_core-600px.png filter=lfs diff=lfs merge=lfs -text
|
| 48 |
+
assets/decision-expanded-old_core.png filter=lfs diff=lfs merge=lfs -text
|
| 49 |
+
assets/decision-expanded-overview.png filter=lfs diff=lfs merge=lfs -text
|
| 50 |
+
assets/decision-expanded-ranking.png filter=lfs diff=lfs merge=lfs -text
|
| 51 |
+
assets/decision-expanded-v3_core-600px.png filter=lfs diff=lfs merge=lfs -text
|
| 52 |
+
assets/decision-expanded-v3_core.png filter=lfs diff=lfs merge=lfs -text
|
| 53 |
+
assets/decision-expanded-v4.png filter=lfs diff=lfs merge=lfs -text
|
| 54 |
+
assets/decision-expanded-v5.png filter=lfs diff=lfs merge=lfs -text
|
| 55 |
+
assets/decision-question-scaling.png filter=lfs diff=lfs merge=lfs -text
|
ATTRIBUTIONS.md
CHANGED
|
@@ -23,3 +23,13 @@ MultiNLI is by Adina Williams, Nikita Nangia and Samuel R. Bowman, *A Broad-Cove
|
|
| 23 |
- [MultiNLI paper](https://aclanthology.org/N18-1101/).
|
| 24 |
|
| 25 |
MASSIVE and SLURP remain excluded from custom training, checkpoint selection and calibration. MASSIVE is used only for evaluation. Official Jev outputs are never used as training labels. The initial-release training histories above remain historical; the subsequent selected model and evaluation provenance identify the actual update.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 23 |
- [MultiNLI paper](https://aclanthology.org/N18-1101/).
|
| 24 |
|
| 25 |
MASSIVE and SLURP remain excluded from custom training, checkpoint selection and calibration. MASSIVE is used only for evaluation. Official Jev outputs are never used as training labels. The initial-release training histories above remain historical; the subsequent selected model and evaluation provenance identify the actual update.
|
| 26 |
+
|
| 27 |
+
## Natural-language decision adaptation
|
| 28 |
+
|
| 29 |
+
This update adds 8,000 human-annotated training examples to 16,000 retained decision examples: 4,000 Cosmos QA reading questions, 2,000 SQuAD 2.0 answerability judgments, and 2,000 SNLI inference pairs. The selected natural-data checkpoints complete one pass of this 24,000-example mixture. Human source labels are preserved; SQuAD answerability uses its supplied impossible/answerable annotation, and each source is converted to the model's decision interface. Source-parent groups and near duplicates are separated between custom training, selection and calibration. No official Jev output supplies a training label.
|
| 30 |
+
|
| 31 |
+
- **Cosmos QA**, by Lifu Huang, Ronan Le Bras, Chandra Bhagavatula and Yejin Choi. Data from the [author repository at the pinned revision](https://github.com/wilburOne/cosmosqa/tree/b6eb99cca4e2a51dd28a9a6f562534872d851639). The [official AllenAI dataset card](https://huggingface.co/datasets/allenai/cosmos_qa/blob/28d9d5e2aae025e73e11177891a88dba51190013/README.md) records the author-confirmed [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/) license.
|
| 32 |
+
- **SQuAD 2.0**, by Pranav Rajpurkar, Robin Jia and Percy Liang. The official [SQuAD project](https://rajpurkar.github.io/SQuAD-explorer/) distributes the dataset under [CC BY-SA 4.0](https://creativecommons.org/licenses/by-sa/4.0/). The adaptation here is answerability classification, not the official span-extraction benchmark.
|
| 33 |
+
- **SNLI 1.0**, by Samuel R. Bowman, Gabor Angeli, Christopher Potts and Christopher D. Manning. The official [Stanford Natural Language Inference project](https://nlp.stanford.edu/projects/snli/) and release README identify [CC BY-SA 4.0](https://creativecommons.org/licenses/by-sa/4.0/) for the corpus. Original entailment, neutral and contradiction labels supply the three decision alternatives.
|
| 34 |
+
|
| 35 |
+
These dataset licenses govern their respective source material; they are not replaced by the model package's Apache 2.0 license. Source corpus text, transformed training records and individual evaluation predictions are not redistributed in this model package. New evaluation panels, including supplied-fact QASC questions, are described separately in EVALUATION.md; evaluation data are not used for checkpoint selection or temperature fitting. As with other public datasets, exclusion from this custom training does not establish absence from upstream pretraining.
|
EVALUATION.md
CHANGED
|
@@ -1,93 +1,92 @@
|
|
| 1 |
-
#
|
| 2 |
-
|
| 3 |
-
|
| 4 |
-
|
| 5 |
-
| Model |
|
| 6 |
-
|
|
| 7 |
-
| Jev
|
| 8 |
-
| Nox
|
| 9 |
-
|
|
| 10 |
-
|
|
| 11 |
-
|
|
| 12 |
-
| Qwen3.5
|
| 13 |
-
| Laya
|
| 14 |
-
|
| 15 |
-
|
| 16 |
-
|
| 17 |
-
|
| 18 |
-
|
| 19 |
-
|
| 20 |
-
|
|
| 21 |
-
|
|
| 22 |
-
|
|
| 23 |
-
|
|
| 24 |
-
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
|
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
| Jev · 1.13.0 |
|
| 36 |
-
|
|
| 37 |
-
|
|
| 38 |
-
|
|
| 39 |
-
|
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
|
|
| 46 |
-
|
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
|
| 50 |
-
|
|
| 51 |
-
|
|
| 52 |
-
|
|
| 53 |
-
|
|
| 54 |
-
|
| 55 |
-
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
|
| 67 |
-
|
| 68 |
-
|
| 69 |
-
|
| 70 |
-
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
|
|
| 74 |
-
|
|
| 75 |
-
|
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
|
| 90 |
-
|
| 91 |
-
|
| 92 |
-
|
| 93 |
-
[Reading benchmark aggregate measurements](metrics/natural-confirmation.json).
|
|
|
|
| 1 |
+
# Evaluation
|
| 2 |
+
|
| 3 |
+
Four complete panels, shared requests and recorded native decisions. Failures and rejections remain in the requested denominator. The four-panel mean uses 25% each for general decisions, compositional tasks, natural reading, and reading/inference. Within-panel source/family weights are retained. Intervals use the frozen paired source-cluster procedure; they are reported without introducing another release gate.
|
| 4 |
+
|
| 5 |
+
| Model | Version | General decisions | Compositional tasks | Natural reading | Reading and inference | Mean |
|
| 6 |
+
|---|---|---:|---:|---:|---:|---:|
|
| 7 |
+
| Jev | 1.13.0 | 79.10 | **66.38** | **94.53** | **89.79** | **82.45** |
|
| 8 |
+
| Nox | v1.2 · this release | **83.21** | 51.08 | 78.12 | 84.38 | 74.20 |
|
| 9 |
+
| Nox | v1.1 · previous | 82.85 | 51.25 | 78.44 | 79.17 | 72.93 |
|
| 10 |
+
| Decider | 2B | 64.01 | 46.58 | 92.03 | 84.38 | 71.75 |
|
| 11 |
+
| Qwen3.5 | 4B · untuned | 69.89 | 43.33 | 87.97 | 79.79 | 70.25 |
|
| 12 |
+
| Qwen3.5 | 2B · untuned | 57.12 | 39.00 | 73.75 | 72.29 | 60.54 |
|
| 13 |
+
| Laya | Upstream default | 57.01 | 37.75 | 51.25 | 63.75 | 52.44 |
|
| 14 |
+
|
| 15 |
+
Accuracy (%). Mean weights each panel equally; each panel retains its frozen family/source weights.
|
| 16 |
+
Bold marks the exact highest score in a column, including exact ties. Rounded visual ties can differ.
|
| 17 |
+
|
| 18 |
+
### General decisions
|
| 19 |
+
|
| 20 |
+
| Task | Jev · 1.13.0 | Nox · v1.2 · this release | Nox · v1.1 · previous | Decider · 2B | Qwen3.5 · 4B · untuned | Qwen3.5 · 2B · untuned | Laya · Upstream default |
|
| 21 |
+
|---|---:|---:|---:|---:|---:|---:|---:|
|
| 22 |
+
| ag news | 85.16 | 85.16 | 83.59 | 86.72 | 84.38 | 80.47 | **91.41** |
|
| 23 |
+
| boolean constraints | **100.00** | 93.75 | 93.75 | 71.88 | 62.50 | 37.50 | 43.75 |
|
| 24 |
+
| dbpedia 14 | 96.43 | 96.43 | 96.43 | **98.21** | 97.32 | 92.86 | 83.93 |
|
| 25 |
+
| natural intents | **100.00** | **100.00** | **100.00** | **100.00** | **100.00** | 96.88 | 85.94 |
|
| 26 |
+
| option carrier | 30.21 | **100.00** | **100.00** | 8.33 | 72.92 | 9.38 | 95.83 |
|
| 27 |
+
| ordinal rubric | **100.00** | 89.06 | 89.06 | 84.38 | 90.62 | 81.25 | 18.75 |
|
| 28 |
+
| relational composition | **56.25** | 54.17 | 55.21 | 54.17 | 51.04 | 48.96 | 25.00 |
|
| 29 |
+
| scoped evidence | **89.58** | 78.12 | 75.00 | 47.92 | 51.04 | 36.46 | 37.50 |
|
| 30 |
+
| state tracking | 33.33 | **35.42** | **35.42** | 29.17 | 28.12 | 25.00 | 23.96 |
|
| 31 |
+
| unknown rejection | **100.00** | **100.00** | **100.00** | 59.38 | 60.94 | 62.50 | 64.06 |
|
| 32 |
+
|
| 33 |
+
### Compositional tasks
|
| 34 |
+
|
| 35 |
+
| Task | Jev · 1.13.0 | Nox · v1.2 · this release | Nox · v1.1 · previous | Decider · 2B | Qwen3.5 · 4B · untuned | Qwen3.5 · 2B · untuned | Laya · Upstream default |
|
| 36 |
+
|---|---:|---:|---:|---:|---:|---:|---:|
|
| 37 |
+
| canonical record identity | **76.25** | 50.00 | 50.00 | 56.25 | 50.00 | 46.25 | 47.50 |
|
| 38 |
+
| capacitated assignment | **68.75** | 41.25 | 43.75 | 51.25 | 50.00 | 50.00 | 63.75 |
|
| 39 |
+
| constraint assignment | **55.00** | 41.25 | 42.50 | 23.75 | 23.75 | 21.25 | 22.50 |
|
| 40 |
+
| massive en | **91.67** | 90.83 | **91.67** | 90.00 | **91.67** | 70.83 | 74.17 |
|
| 41 |
+
| massive zh | **88.33** | 87.50 | **88.33** | **88.33** | 86.67 | 74.17 | 73.33 |
|
| 42 |
+
| multiset reconciliation | **58.75** | 28.75 | 31.25 | 23.75 | 27.50 | 27.50 | 26.25 |
|
| 43 |
+
| ordinal service loss | **42.50** | 31.25 | 28.75 | 22.50 | 21.25 | 20.00 | 20.00 |
|
| 44 |
+
| paraconsistent rule closure | **66.25** | 33.75 | 35.00 | 26.25 | 25.00 | 27.50 | 18.75 |
|
| 45 |
+
| temporal exclusion | 41.25 | **45.00** | 41.25 | 42.50 | 31.25 | 28.75 | 12.50 |
|
| 46 |
+
| transaction recovery | **75.00** | 61.25 | 60.00 | 41.25 | 26.25 | 23.75 | 18.75 |
|
| 47 |
+
|
| 48 |
+
### Natural reading
|
| 49 |
+
|
| 50 |
+
| Task | Jev · 1.13.0 | Nox · v1.2 · this release | Nox · v1.1 · previous | Decider · 2B | Qwen3.5 · 4B · untuned | Qwen3.5 · 2B · untuned | Laya · Upstream default |
|
| 51 |
+
|---|---:|---:|---:|---:|---:|---:|---:|
|
| 52 |
+
| boolq | **92.50** | 85.62 | 87.50 | 91.88 | 83.75 | 65.00 | 69.38 |
|
| 53 |
+
| belebele en | **96.88** | 71.88 | 71.25 | 93.12 | 93.12 | 83.75 | 38.12 |
|
| 54 |
+
| belebele zh | **96.25** | 69.38 | 67.50 | 91.25 | 91.25 | 81.25 | 28.12 |
|
| 55 |
+
|
| 56 |
+
### Reading and inference
|
| 57 |
+
|
| 58 |
+
| Task | Jev · 1.13.0 | Nox · v1.2 · this release | Nox · v1.1 · previous | Decider · 2B | Qwen3.5 · 4B · untuned | Qwen3.5 · 2B · untuned | Laya · Upstream default |
|
| 59 |
+
|---|---:|---:|---:|---:|---:|---:|---:|
|
| 60 |
+
| cosmos qa | **86.67** | 68.33 | 57.50 | 66.67 | 60.83 | 56.67 | 30.00 |
|
| 61 |
+
| squad2 answerability | **90.83** | 85.00 | 75.83 | 84.17 | 81.67 | 82.50 | 57.50 |
|
| 62 |
+
| snli | 82.50 | 86.67 | 85.83 | **90.83** | 80.00 | 64.17 | 72.50 |
|
| 63 |
+
| qasc | **99.17** | 97.50 | 97.50 | 95.83 | 96.67 | 85.83 | 95.00 |
|
| 64 |
+
|
| 65 |
+
### Probability quality
|
| 66 |
+
|
| 67 |
+
| Model | Version | Weighted Brier ↓ | Valid probability rows |
|
| 68 |
+
|---|---|---:|---:|
|
| 69 |
+
| Jev | 1.13.0 | **0.2287** | 2,720 / 2,720 |
|
| 70 |
+
| Nox | v1.2 · this release | 0.3416 | 2,720 / 2,720 |
|
| 71 |
+
| Nox | v1.1 · previous | 0.3630 | 2,720 / 2,720 |
|
| 72 |
+
| Decider | 2B | 0.3535 | 2,720 / 2,720 |
|
| 73 |
+
| Qwen3.5 | 4B · untuned | 0.3996 | 2,720 / 2,720 |
|
| 74 |
+
| Qwen3.5 | 2B · untuned | 0.5130 | 2,720 / 2,720 |
|
| 75 |
+
| Laya | Upstream default | 0.5903 | 2,720 / 2,720 |
|
| 76 |
+
|
| 77 |
+
Missing Brier means probability coverage was incomplete; no supported-only average is substituted.
|
| 78 |
+
The two native contract supplements are reported separately and are outside this quality mean.
|
| 79 |
+
|
| 80 |
+

|
| 81 |
+
|
| 82 |
+

|
| 83 |
+
|
| 84 |
+

|
| 85 |
+
|
| 86 |
+

|
| 87 |
+
|
| 88 |
+
## Scope
|
| 89 |
+
|
| 90 |
+
These panels include previously observed regression sets. They are not all pristine holdouts. The untuned Qwen models use their frozen chat/LM-head adapters. Laya uses its unmodified upstream default language router (no explicit language override); Decider retains its native adapter. Documented native truncation is retained. Jev is a closed service snapshot, not a reproducible weight release. Full native-interface supplements are outside the quality mean.
|
| 91 |
+
|
| 92 |
+
[Exact aggregate statistics](metrics/expanded-quality.json) · [Probability and adapter coverage](metrics/comparator-coverage.json) · [Measured latency](QUESTION-SCALING.md) · [Material provenance](metrics/materials-provenance.json)
|
|
|
NORMALIZATION_RUNTIME.md
ADDED
|
@@ -0,0 +1,5 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Validated normalization runtime
|
| 2 |
+
|
| 3 |
+
This Nox bundle installs its recorded FLA normalization profile through the default public entrypoint. It requires the pinned ROCm runtime on gfx942 and a fresh process. The profile covers dimension 128, BF16 input/output, FP32 reciprocal norms, and buckets 1–64 for the actual 32 normalized value heads, batch size at most 8 and complete inputs at most 16,384 tokens. Unknown keys fail closed. Weights, tokenizer, prompt, readout and temperature remain unchanged from the source export.
|
| 4 |
+
|
| 5 |
+
No private compilation cache is required. Other FLA kernels retain normal runtime behavior. Numerical validation of this newly bound bundle is still required. Earlier latency measurements do not measure this runtime or candidate.
|
QUESTION-SCALING.md
CHANGED
|
@@ -1,55 +1,64 @@
|
|
| 1 |
-
#
|
| 2 |
-
|
| 3 |
-
|
| 4 |
-
|
| 5 |
-
|
| 6 |
-
|
| 7 |
-
|
| 8 |
-
|
| 9 |
-
|
| 10 |
-
|
| 11 |
-
|
| 12 |
-
|
| 13 |
-
|
| 14 |
-
|
| 15 |
-
|
| 16 |
-
|
| 17 |
-
|
|
| 18 |
-
|
|
| 19 |
-
|
|
| 20 |
-
|
|
| 21 |
-
|
|
| 22 |
-
|
|
| 23 |
-
|
|
| 24 |
-
|
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
|
|
| 29 |
-
|
|
| 30 |
-
| Nox
|
| 31 |
-
|
|
| 32 |
-
|
|
| 33 |
-
|
|
| 34 |
-
|
|
| 35 |
-
|
|
| 36 |
-
|
|
| 37 |
-
|
|
| 38 |
-
|
|
| 39 |
-
|
|
| 40 |
-
|
|
| 41 |
-
|
|
| 42 |
-
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
|
| 46 |
-
|
| 47 |
-
|
| 48 |
-
|
|
| 49 |
-
|
|
| 50 |
-
|
|
| 51 |
-
| Nox
|
| 52 |
-
|
|
| 53 |
-
|
|
| 54 |
-
|
| 55 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Request latency
|
| 2 |
+
|
| 3 |
+
Fresh matched measurements of this candidate and its own published predecessor.
|
| 4 |
+
|
| 5 |
+
The same physical AMD gfx942 GPU runs three independently loaded blocks per model in a counterbalanced order. Each of 18 fixed Choice/Noul/Score cases has three warmups and ten measurements per block. The tables pool all 30 measurements per point. Loading and network time are excluded; tokenization and inference are included. No cross-request prefix cache is enabled. These are sequential requests, not concurrent-service throughput.
|
| 6 |
+
|
| 7 |
+

|
| 8 |
+
|
| 9 |
+
## Choice
|
| 10 |
+
|
| 11 |
+
| Model | Q | p50 ms ↓ | p95 ms ↓ | Input tokens |
|
| 12 |
+
|---|---:|---:|---:|---:|
|
| 13 |
+
| Nox · v1.2 · this release | 1 | 32.108 | 33.047 | 309 |
|
| 14 |
+
| Nox · v1.1 · previous | 1 | **28.976** | **30.240** | 309 |
|
| 15 |
+
| Nox · v1.2 · this release | 2 | 33.025 | 34.047 | 618 |
|
| 16 |
+
| Nox · v1.1 · previous | 2 | **29.337** | **29.953** | 618 |
|
| 17 |
+
| Nox · v1.2 · this release | 4 | **41.706** | **42.005** | 1236 |
|
| 18 |
+
| Nox · v1.1 · previous | 4 | 42.041 | 42.413 | 1236 |
|
| 19 |
+
| Nox · v1.2 · this release | 8 | **69.483** | **70.719** | 2472 |
|
| 20 |
+
| Nox · v1.1 · previous | 8 | 70.106 | 70.850 | 2472 |
|
| 21 |
+
| Nox · v1.2 · this release | 16 | **141.299** | **141.921** | 4944 |
|
| 22 |
+
| Nox · v1.1 · previous | 16 | 141.369 | 142.338 | 4944 |
|
| 23 |
+
| Nox · v1.2 · this release | 32 | **282.326** | **284.856** | 9888 |
|
| 24 |
+
| Nox · v1.1 · previous | 32 | 283.681 | 286.013 | 9888 |
|
| 25 |
+
|
| 26 |
+
## Noul
|
| 27 |
+
|
| 28 |
+
| Model | Q | p50 ms ↓ | p95 ms ↓ | Input tokens |
|
| 29 |
+
|---|---:|---:|---:|---:|
|
| 30 |
+
| Nox · v1.2 · this release | 1 | 32.282 | 32.977 | 262 |
|
| 31 |
+
| Nox · v1.1 · previous | 1 | **28.993** | **29.371** | 262 |
|
| 32 |
+
| Nox · v1.2 · this release | 2 | 32.573 | 33.978 | 524 |
|
| 33 |
+
| Nox · v1.1 · previous | 2 | **29.196** | **30.459** | 524 |
|
| 34 |
+
| Nox · v1.2 · this release | 4 | **38.967** | **39.277** | 1048 |
|
| 35 |
+
| Nox · v1.1 · previous | 4 | 39.373 | 39.573 | 1048 |
|
| 36 |
+
| Nox · v1.2 · this release | 8 | 64.497 | **65.068** | 2096 |
|
| 37 |
+
| Nox · v1.1 · previous | 8 | **64.382** | 65.297 | 2096 |
|
| 38 |
+
| Nox · v1.2 · this release | 16 | **129.421** | **130.165** | 4192 |
|
| 39 |
+
| Nox · v1.1 · previous | 16 | 129.926 | 130.926 | 4192 |
|
| 40 |
+
| Nox · v1.2 · this release | 32 | 260.115 | **261.017** | 8384 |
|
| 41 |
+
| Nox · v1.1 · previous | 32 | **259.700** | 262.418 | 8384 |
|
| 42 |
+
|
| 43 |
+
## Score
|
| 44 |
+
|
| 45 |
+
| Model | Q | p50 ms ↓ | p95 ms ↓ | Input tokens |
|
| 46 |
+
|---|---:|---:|---:|---:|
|
| 47 |
+
| Nox · v1.2 · this release | 1 | 32.601 | 33.154 | 307 |
|
| 48 |
+
| Nox · v1.1 · previous | 1 | **28.816** | **29.119** | 307 |
|
| 49 |
+
| Nox · v1.2 · this release | 2 | 33.221 | 33.625 | 614 |
|
| 50 |
+
| Nox · v1.1 · previous | 2 | **29.339** | **29.777** | 614 |
|
| 51 |
+
| Nox · v1.2 · this release | 4 | **41.776** | 42.379 | 1228 |
|
| 52 |
+
| Nox · v1.1 · previous | 4 | 41.965 | **42.220** | 1228 |
|
| 53 |
+
| Nox · v1.2 · this release | 8 | **69.535** | **70.140** | 2456 |
|
| 54 |
+
| Nox · v1.1 · previous | 8 | 69.583 | 70.672 | 2456 |
|
| 55 |
+
| Nox · v1.2 · this release | 16 | **140.447** | **141.969** | 4912 |
|
| 56 |
+
| Nox · v1.1 · previous | 16 | 141.124 | 142.791 | 4912 |
|
| 57 |
+
| Nox · v1.2 · this release | 32 | **281.576** | **284.902** | 9824 |
|
| 58 |
+
| Nox · v1.1 · previous | 32 | 283.684 | 286.097 | 9824 |
|
| 59 |
+
|
| 60 |
+
Choice six-point geometric-mean latency ratio (candidate / predecessor): **1.0337**.
|
| 61 |
+
|
| 62 |
+
The candidate has 3.37% higher measured latency by this summary. This is a descriptive result for these six request sizes, not a claim of universal speedup.
|
| 63 |
+
|
| 64 |
+
The runtime/profile and temperature belong to these exact measured bundles. Older release timing is not reused.
|
README.md
CHANGED
|
@@ -12,13 +12,6 @@ tags:
|
|
| 12 |
- custom-code
|
| 13 |
- pytorch
|
| 14 |
- rocm
|
| 15 |
-
- choice
|
| 16 |
-
- noul
|
| 17 |
-
- scoring
|
| 18 |
-
datasets:
|
| 19 |
-
- PolyAI/banking77
|
| 20 |
-
- clinc/clinc_oos
|
| 21 |
-
- nyu-mll/multi_nli
|
| 22 |
---
|
| 23 |
|
| 24 |

|
|
@@ -27,69 +20,47 @@ datasets:
|
|
| 27 |
|
| 28 |
*Nox, Latin for night.*
|
| 29 |
|
| 30 |
-
**Your move.**
|
| 31 |
-
|
| 32 |
-
A capable decoder for decisions defined by you. Give Nox a state, questions and possible answers. It returns choices, yes/no judgments and rubric scores with probability distributions—one forward pass per question.
|
| 33 |
|
| 34 |
**4.208B parameters · 16K complete-question budget · English / Chinese evaluated · Apache 2.0**
|
| 35 |
|
| 36 |
-
[Decision family](https://huggingface.co/collections/llm-semantic-router/decision-10-6ab12177bd0002394d8409f9)
|
| 37 |
-
|
| 38 |
-
## Three ways to decide
|
| 39 |
|
| 40 |
| Type | Use it for | Output |
|
| 41 |
-
|
|
| 42 |
-
| **Choice** | Route a request
|
| 43 |
-
| **Noul** | Check a condition against
|
| 44 |
| **Score** | Apply 2–10 ordered rubric descriptions. | Expected index + distribution |
|
| 45 |
|
| 46 |
-
Your question names and candidate IDs are preserved. Labels are defined at runtime.
|
| 47 |
-
|
| 48 |
## Measured capability
|
| 49 |
|
| 50 |
-
**
|
| 51 |
-
|
| 52 |
-
| Model | Overall accuracy ↑ | Choice ↑ | Noul ↑ | Score ↑ |
|
| 53 |
-
| --- | ---: | ---: | ---: | ---: |
|
| 54 |
-
| Jev · 1.13.0 | **72.74** | **71.77** | **80.36** | **68.06** |
|
| 55 |
-
| Nox · 4B · v1.1 | 67.05 | 70.55 | 60.27 | 55.56 |
|
| 56 |
-
| Qwen3.5 · 4B · untuned | 56.61 | 60.06 | 53.57 | 52.08 |
|
| 57 |
-
| Sol · 2B · v1.0 | 55.58 | 61.93 | 50.89 | 32.64 |
|
| 58 |
-
| Decider · 2B | 55.30 | 57.26 | 58.93 | 50.00 |
|
| 59 |
-
| Qwen3.5 · 2B · untuned | 48.06 | 50.36 | 45.09 | 47.22 |
|
| 60 |
-
| Laya · EN/ML | 47.38 | 53.02 | 52.23 | 19.44 |
|
| 61 |
-
|
| 62 |
-
Accuracy (%). Overall is the equal-weight mean of **20 task families**, covering **1,760 questions**; type columns pool their questions. Same requests for every model. Laya's native interface reported 152 truncated inputs. [Methods, coverage and uncertainty](EVALUATION.md).
|
| 63 |
-
|
| 64 |
-

|
| 65 |
-
|
| 66 |
-

|
| 67 |
|
| 68 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 69 |
|
| 70 |
-
|
| 71 |
|
| 72 |
-
|
| 73 |
-
| --- | ---: |
|
| 74 |
-
| Jev 1.13.0 | **94.53** |
|
| 75 |
-
| Decider 2B | 92.03 |
|
| 76 |
-
| Qwen3.5 4B + LM-head adapter | 87.97 |
|
| 77 |
-
| Nox · 4B · v1.1 | 78.44 |
|
| 78 |
-
| Qwen3.5 2B + LM-head adapter | 73.75 |
|
| 79 |
-
| Sol · 2B · v1.0 | 69.38 |
|
| 80 |
-
| Laya EN/ML routed | 51.25 |
|
| 81 |
|
| 82 |
-
|
| 83 |
|
| 84 |
## More questions, measured
|
| 85 |
|
| 86 |
-
![
|
| 87 |
|
| 88 |
-
|
| 89 |
|
| 90 |
## Try it
|
| 91 |
|
| 92 |
-
Download
|
| 93 |
|
| 94 |
```python
|
| 95 |
from decision import DecisionModel
|
|
@@ -99,16 +70,16 @@ model = DecisionModel.from_pretrained("/model", local_files_only=True)
|
|
| 99 |
print(model.decide(**REQUEST)["answers"])
|
| 100 |
```
|
| 101 |
|
| 102 |
-
[
|
| 103 |
|
| 104 |
-
The complete state, question and candidates must fit 16,384 tokens
|
| 105 |
|
| 106 |
## Architecture
|
| 107 |
|
| 108 |

|
| 109 |
|
| 110 |
-
A causal Qwen3.5 text backbone combines gated linear
|
| 111 |
|
| 112 |
-
[Candidate head](assets/readout.png) · [
|
| 113 |
|
| 114 |
-
Adapted from [Qwen3.5-4B](https://huggingface.co/Qwen/Qwen3.5-4B). It evaluates supplied evidence
|
|
|
|
| 12 |
- custom-code
|
| 13 |
- pytorch
|
| 14 |
- rocm
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 15 |
---
|
| 16 |
|
| 17 |

|
|
|
|
| 20 |
|
| 21 |
*Nox, Latin for night.*
|
| 22 |
|
| 23 |
+
**Your move.** Give Nox a state, questions and possible answers. It returns decisions and probabilities with labels defined at runtime.
|
|
|
|
|
|
|
| 24 |
|
| 25 |
**4.208B parameters · 16K complete-question budget · English / Chinese evaluated · Apache 2.0**
|
| 26 |
|
| 27 |
+
[Decision family](https://huggingface.co/collections/llm-semantic-router/decision-10-6ab12177bd0002394d8409f9)
|
|
|
|
|
|
|
| 28 |
|
| 29 |
| Type | Use it for | Output |
|
| 30 |
+
|---|---|---|
|
| 31 |
+
| **Choice** | Route a request or choose among 2–255 actions. | Selected ID + distribution |
|
| 32 |
+
| **Noul** | Check a condition against supplied evidence. | P(true) |
|
| 33 |
| **Score** | Apply 2–10 ordered rubric descriptions. | Expected index + distribution |
|
| 34 |
|
|
|
|
|
|
|
| 35 |
## Measured capability
|
| 36 |
|
| 37 |
+
**74.20% four-panel mean**, +1.27 points versus its published predecessor.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 38 |
|
| 39 |
+
| Model | Mean accuracy ↑ | Decisions | Composition | Reading | Inference |
|
| 40 |
+
|---|---:|---:|---:|---:|---:|
|
| 41 |
+
| Jev · 1.13.0 | **82.45** | 79.10 | **66.38** | **94.53** | **89.79** |
|
| 42 |
+
| Nox · v1.2 · this release | 74.20 | **83.21** | 51.08 | 78.12 | 84.38 |
|
| 43 |
+
| Nox · v1.1 · previous | 72.93 | 82.85 | 51.25 | 78.44 | 79.17 |
|
| 44 |
+
| Decider · 2B | 71.75 | 64.01 | 46.58 | 92.03 | 84.38 |
|
| 45 |
+
| Qwen3.5 · 4B · untuned | 70.25 | 69.89 | 43.33 | 87.97 | 79.79 |
|
| 46 |
+
| Qwen3.5 · 2B · untuned | 60.54 | 57.12 | 39.00 | 73.75 | 72.29 |
|
| 47 |
+
| Laya · Upstream default | 52.44 | 57.01 | 37.75 | 51.25 | 63.75 |
|
| 48 |
|
| 49 |
+
Accuracy (%), **2,720 decisions**. Each panel contributes one quarter; its original family/source weights are retained. Bold marks each column's exact highest score. [Methods, uncertainty and all task results](EVALUATION.md).
|
| 50 |
|
| 51 |
+

|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 52 |
|
| 53 |
+

|
| 54 |
|
| 55 |
## More questions, measured
|
| 56 |
|
| 57 |
+

|
| 58 |
|
| 59 |
+
Same inputs and physical AMD gfx942 GPU; 30 measured requests per point across three blocks. Python request latency includes tokenization and inference, excluding loading and network. [p95 and all three native types](QUESTION-SCALING.md).
|
| 60 |
|
| 61 |
## Try it
|
| 62 |
|
| 63 |
+
Download `hf download llm-semantic-router/Decision-1.0-Nox --revision v1.2 --local-dir decision-model`, then follow [ROCm setup](RUNTIME.md). In that container, with the model mounted at `/model`:
|
| 64 |
|
| 65 |
```python
|
| 66 |
from decision import DecisionModel
|
|
|
|
| 70 |
print(model.decide(**REQUEST)["answers"])
|
| 71 |
```
|
| 72 |
|
| 73 |
+
[Tested request and output](model-card-example.json) · [Install and API guide](USAGE.md)
|
| 74 |
|
| 75 |
+
The complete state, question and candidates must fit 16,384 tokens; overflow is rejected. The bundled normalization profile loads automatically. AMD gfx942 is validated; CPU/MPS are unsupported and NVIDIA is unqualified. Use a fresh Python process when switching profiles.
|
| 76 |
|
| 77 |
## Architecture
|
| 78 |
|
| 79 |

|
| 80 |
|
| 81 |
+
A causal Qwen3.5 text backbone combines gated linear and full attention. A shared candidate head reads candidate endpoints and the final query vector. Each question uses one forward pass; questions run independently in batches of eight.
|
| 82 |
|
| 83 |
+
[Candidate head](assets/readout.png) · [Vector architecture](assets/architecture.svg) · [Inference code](code/decision_model.py)
|
| 84 |
|
| 85 |
+
Adapted from [Qwen3.5-4B](https://huggingface.co/Qwen/Qwen3.5-4B). It evaluates supplied evidence without live retrieval; confidence does not guarantee correctness. [License](LICENSE) · [Attributions](ATTRIBUTIONS.md).
|
RUNTIME.md
CHANGED
|
@@ -2,7 +2,7 @@
|
|
| 2 |
|
| 3 |
The package has a public, digest-pinned installation path. `Dockerfile.runtime` starts from `vllm/vllm-openai-rocm@sha256:1fd21abe66455b4df5a2e83629e97cdcc9d58913b16052d8118b92b239792339`, adds two hash-checked FLA wheels, and installs this repository's loading wrapper. It keeps the base image's ROCm PyTorch and Triton builds. The vLLM server is not used by Decision inference.
|
| 4 |
|
| 5 |
-
**Validation boundary:** the public registry manifest, base-image ancestry, package metadata and critical PyTorch binary hashes have been checked. The recipe built successfully and passed CPU imports and real AMD ROCm gfx942 GPU inference for both
|
| 6 |
|
| 7 |
## Build and run
|
| 8 |
|
|
|
|
| 2 |
|
| 3 |
The package has a public, digest-pinned installation path. `Dockerfile.runtime` starts from `vllm/vllm-openai-rocm@sha256:1fd21abe66455b4df5a2e83629e97cdcc9d58913b16052d8118b92b239792339`, adds two hash-checked FLA wheels, and installs this repository's loading wrapper. It keeps the base image's ROCm PyTorch and Triton builds. The vLLM server is not used by Decision inference.
|
| 4 |
|
| 5 |
+
**Validation boundary:** the public registry manifest, base-image ancestry, package metadata and critical PyTorch binary hashes have been checked. The recipe built successfully and passed CPU imports and real AMD ROCm gfx942 GPU GPU inference for both released bundles. On the packaged three-question Choice/Noul/Score example, its complete responses matched the qualified research runtime exactly; the wrapper matched the direct engine and rejected an oversized complete input. Evidence is in `runtime-build-provenance.json`. This example establishes a working public installation path; it is not a full rerun of the quality or timing benchmark. Published benchmark results use the qualified runtime in each bundle's `runtime.json`.
|
| 6 |
|
| 7 |
## Build and run
|
| 8 |
|
RUNTIME_BINDING.json
ADDED
|
@@ -0,0 +1,76 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"source_bundle_manifest_sha256": "6d402d6d55e734851cb0d6417d6f3b416b25ae807c3a0d6dcf12e40acb6ac546",
|
| 3 |
+
"profile_sha256": "be32858d15233e0a3fbee0e4257fb02be0b3439deee4eb9c3f61151df7b73850",
|
| 4 |
+
"profile_validation_receipt_sha256": "7a66474325b5575fdd15a33e5e0340c19e809bdcc22adf4cbb45baa0e1b32693",
|
| 5 |
+
"unchanged_files": [
|
| 6 |
+
{
|
| 7 |
+
"file": "backbone/config.json",
|
| 8 |
+
"bytes": 1978,
|
| 9 |
+
"sha256": "ae3a463b32e95b6cc207a7af4f1defb4195f388eb6f9ff19d2690b73d4966953"
|
| 10 |
+
},
|
| 11 |
+
{
|
| 12 |
+
"file": "backbone/model-00001-of-00003.safetensors",
|
| 13 |
+
"bytes": 3991295368,
|
| 14 |
+
"sha256": "5f9c4bc396605b551b5983a1699de8e96755fafdb6afdb228a5cc4d9b438a5da"
|
| 15 |
+
},
|
| 16 |
+
{
|
| 17 |
+
"file": "backbone/model-00002-of-00003.safetensors",
|
| 18 |
+
"bytes": 3979828128,
|
| 19 |
+
"sha256": "656cc757ba03f87cedc0e4c88237db1ae8215686f9b6477334a34dc0a32136db"
|
| 20 |
+
},
|
| 21 |
+
{
|
| 22 |
+
"file": "backbone/model-00003-of-00003.safetensors",
|
| 23 |
+
"bytes": 440425856,
|
| 24 |
+
"sha256": "0a30a07b6efbaa37d016008848c1fa6dadcb46ae451a0e5e4b927ac9b5771804"
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"file": "backbone/model.safetensors.index.json",
|
| 28 |
+
"bytes": 33047,
|
| 29 |
+
"sha256": "1602d52e38d81586af85bc4ce29ce082c5fc5877c763b1ebcab7545320016599"
|
| 30 |
+
},
|
| 31 |
+
{
|
| 32 |
+
"file": "chat_template.jinja",
|
| 33 |
+
"bytes": 7756,
|
| 34 |
+
"sha256": "a4aee8afcf2e0711942cf848899be66016f8d14a889ff9ede07bca099c28f715"
|
| 35 |
+
},
|
| 36 |
+
{
|
| 37 |
+
"file": "code/decision_model.py",
|
| 38 |
+
"bytes": 10114,
|
| 39 |
+
"sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646"
|
| 40 |
+
},
|
| 41 |
+
{
|
| 42 |
+
"file": "code/predict.py",
|
| 43 |
+
"bytes": 3164,
|
| 44 |
+
"sha256": "02352e8385ab47157b6459910da54d962e5da4bb4940d571faedc86bc5da9aee"
|
| 45 |
+
},
|
| 46 |
+
{
|
| 47 |
+
"file": "decision_config.json",
|
| 48 |
+
"bytes": 753,
|
| 49 |
+
"sha256": "443a9b3f191a8387915c606de8303700fc1a069fe7c8ad46a0eba5528a2549a8"
|
| 50 |
+
},
|
| 51 |
+
{
|
| 52 |
+
"file": "decision_head.safetensors",
|
| 53 |
+
"bytes": 10529624,
|
| 54 |
+
"sha256": "8b8e342445035e503b4963e16c5f7a4fef95c08368e27eace312145fc3660772"
|
| 55 |
+
},
|
| 56 |
+
{
|
| 57 |
+
"file": "temperature.json",
|
| 58 |
+
"bytes": 6095,
|
| 59 |
+
"sha256": "1d652e75f49b5c232d1e742b189c1c826ad52ced1a931a124e29e65e7d7fb569"
|
| 60 |
+
},
|
| 61 |
+
{
|
| 62 |
+
"file": "tokenizer.json",
|
| 63 |
+
"bytes": 19989325,
|
| 64 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523"
|
| 65 |
+
},
|
| 66 |
+
{
|
| 67 |
+
"file": "tokenizer_config.json",
|
| 68 |
+
"bytes": 1123,
|
| 69 |
+
"sha256": "bee8eba30f0eb4af73c0fe2cd06d0f89b657d7819941c438157ec42f7c80ea87"
|
| 70 |
+
}
|
| 71 |
+
],
|
| 72 |
+
"training_selection_calibration_unchanged": true,
|
| 73 |
+
"recomputed_or_recalibrated": false,
|
| 74 |
+
"private_compiled_cache_required": false,
|
| 75 |
+
"new_bundle_offline_proof_required": true
|
| 76 |
+
}
|
SOURCE_BUNDLE_MANIFEST.json
ADDED
|
@@ -0,0 +1,173 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "research-pointer-bundle-v1",
|
| 3 |
+
"status": "candidate-export-awaiting-independent-reload-and-quality-gates",
|
| 4 |
+
"files": [
|
| 5 |
+
{
|
| 6 |
+
"file": "backbone/config.json",
|
| 7 |
+
"bytes": 1978,
|
| 8 |
+
"sha256": "ae3a463b32e95b6cc207a7af4f1defb4195f388eb6f9ff19d2690b73d4966953"
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"file": "backbone/model-00001-of-00003.safetensors",
|
| 12 |
+
"bytes": 3991295368,
|
| 13 |
+
"sha256": "5f9c4bc396605b551b5983a1699de8e96755fafdb6afdb228a5cc4d9b438a5da"
|
| 14 |
+
},
|
| 15 |
+
{
|
| 16 |
+
"file": "backbone/model-00002-of-00003.safetensors",
|
| 17 |
+
"bytes": 3979828128,
|
| 18 |
+
"sha256": "656cc757ba03f87cedc0e4c88237db1ae8215686f9b6477334a34dc0a32136db"
|
| 19 |
+
},
|
| 20 |
+
{
|
| 21 |
+
"file": "backbone/model-00003-of-00003.safetensors",
|
| 22 |
+
"bytes": 440425856,
|
| 23 |
+
"sha256": "0a30a07b6efbaa37d016008848c1fa6dadcb46ae451a0e5e4b927ac9b5771804"
|
| 24 |
+
},
|
| 25 |
+
{
|
| 26 |
+
"file": "backbone/model.safetensors.index.json",
|
| 27 |
+
"bytes": 33047,
|
| 28 |
+
"sha256": "1602d52e38d81586af85bc4ce29ce082c5fc5877c763b1ebcab7545320016599"
|
| 29 |
+
},
|
| 30 |
+
{
|
| 31 |
+
"file": "chat_template.jinja",
|
| 32 |
+
"bytes": 7756,
|
| 33 |
+
"sha256": "a4aee8afcf2e0711942cf848899be66016f8d14a889ff9ede07bca099c28f715"
|
| 34 |
+
},
|
| 35 |
+
{
|
| 36 |
+
"file": "code/decision_api.py",
|
| 37 |
+
"bytes": 6724,
|
| 38 |
+
"sha256": "147b2fec32cbbbbb1b92cf2a19bb887f9d945e4974e141ca7ea93b8c542f5b21"
|
| 39 |
+
},
|
| 40 |
+
{
|
| 41 |
+
"file": "code/decision_model.py",
|
| 42 |
+
"bytes": 10114,
|
| 43 |
+
"sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646"
|
| 44 |
+
},
|
| 45 |
+
{
|
| 46 |
+
"file": "code/predict.py",
|
| 47 |
+
"bytes": 3164,
|
| 48 |
+
"sha256": "02352e8385ab47157b6459910da54d962e5da4bb4940d571faedc86bc5da9aee"
|
| 49 |
+
},
|
| 50 |
+
{
|
| 51 |
+
"file": "decision_config.json",
|
| 52 |
+
"bytes": 753,
|
| 53 |
+
"sha256": "443a9b3f191a8387915c606de8303700fc1a069fe7c8ad46a0eba5528a2549a8"
|
| 54 |
+
},
|
| 55 |
+
{
|
| 56 |
+
"file": "decision_head.safetensors",
|
| 57 |
+
"bytes": 10529624,
|
| 58 |
+
"sha256": "8b8e342445035e503b4963e16c5f7a4fef95c08368e27eace312145fc3660772"
|
| 59 |
+
},
|
| 60 |
+
{
|
| 61 |
+
"file": "runtime.json",
|
| 62 |
+
"bytes": 378,
|
| 63 |
+
"sha256": "c5d3521358b2817f4e56ea8150c5c612139b4e2b2c5bb09f512d9a7c0b5298b9"
|
| 64 |
+
},
|
| 65 |
+
{
|
| 66 |
+
"file": "temperature.json",
|
| 67 |
+
"bytes": 6095,
|
| 68 |
+
"sha256": "1d652e75f49b5c232d1e742b189c1c826ad52ced1a931a124e29e65e7d7fb569"
|
| 69 |
+
},
|
| 70 |
+
{
|
| 71 |
+
"file": "tokenizer.json",
|
| 72 |
+
"bytes": 19989325,
|
| 73 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523"
|
| 74 |
+
},
|
| 75 |
+
{
|
| 76 |
+
"file": "tokenizer_config.json",
|
| 77 |
+
"bytes": 1123,
|
| 78 |
+
"sha256": "bee8eba30f0eb4af73c0fe2cd06d0f89b657d7819941c438157ec42f7c80ea87"
|
| 79 |
+
}
|
| 80 |
+
],
|
| 81 |
+
"tensors": [
|
| 82 |
+
{
|
| 83 |
+
"file": "backbone/model-00001-of-00003.safetensors",
|
| 84 |
+
"elements": 1995638528,
|
| 85 |
+
"elements_by_dtype": {
|
| 86 |
+
"BF16": 1995638528
|
| 87 |
+
}
|
| 88 |
+
},
|
| 89 |
+
{
|
| 90 |
+
"file": "backbone/model-00002-of-00003.safetensors",
|
| 91 |
+
"elements": 1989900928,
|
| 92 |
+
"elements_by_dtype": {
|
| 93 |
+
"BF16": 1989900928
|
| 94 |
+
}
|
| 95 |
+
},
|
| 96 |
+
{
|
| 97 |
+
"file": "backbone/model-00003-of-00003.safetensors",
|
| 98 |
+
"elements": 220211840,
|
| 99 |
+
"elements_by_dtype": {
|
| 100 |
+
"BF16": 220211840
|
| 101 |
+
}
|
| 102 |
+
},
|
| 103 |
+
{
|
| 104 |
+
"file": "decision_head.safetensors",
|
| 105 |
+
"elements": 2632192,
|
| 106 |
+
"elements_by_dtype": {
|
| 107 |
+
"F32": 2632192
|
| 108 |
+
}
|
| 109 |
+
}
|
| 110 |
+
],
|
| 111 |
+
"source_checkpoint_files": [
|
| 112 |
+
{
|
| 113 |
+
"file": "backbone/config.json",
|
| 114 |
+
"bytes": 1977,
|
| 115 |
+
"sha256": "a5ed4156fda05f0f9149c66964d6165916754e7355488a8a07d9b0398acdbdb9"
|
| 116 |
+
},
|
| 117 |
+
{
|
| 118 |
+
"file": "backbone/model-00001-of-00005.safetensors",
|
| 119 |
+
"bytes": 3992269864,
|
| 120 |
+
"sha256": "8adb3dbf9db30b3ecd1f29ce6a853bc6d7e3f465857471cfe579c570537250f8"
|
| 121 |
+
},
|
| 122 |
+
{
|
| 123 |
+
"file": "backbone/model-00002-of-00005.safetensors",
|
| 124 |
+
"bytes": 3990302320,
|
| 125 |
+
"sha256": "8aa80bed34a466a7208ad177d5e5742773e4140c55cba69911fcc805633afa5e"
|
| 126 |
+
},
|
| 127 |
+
{
|
| 128 |
+
"file": "backbone/model-00003-of-00005.safetensors",
|
| 129 |
+
"bytes": 3937871784,
|
| 130 |
+
"sha256": "9af681e845c99e0d933dc3fa643271ee9f5bb382f98454ceb41eb1faf0979f87"
|
| 131 |
+
},
|
| 132 |
+
{
|
| 133 |
+
"file": "backbone/model-00004-of-00005.safetensors",
|
| 134 |
+
"bytes": 3926578128,
|
| 135 |
+
"sha256": "34de5c39c2338e1c7110beaf2834c856f3830411002893f7946045c0a083cc92"
|
| 136 |
+
},
|
| 137 |
+
{
|
| 138 |
+
"file": "backbone/model-00005-of-00005.safetensors",
|
| 139 |
+
"bytes": 976029360,
|
| 140 |
+
"sha256": "ce20083dd8deb786b14fe1126a12cdbf678a8a3c25367a6676c0ca55d9ae7980"
|
| 141 |
+
},
|
| 142 |
+
{
|
| 143 |
+
"file": "decision_config.json",
|
| 144 |
+
"bytes": 1110,
|
| 145 |
+
"sha256": "a12bd49b459771f22d22f29c59fe3cb6779c52a5d39b40cdbe5e247c5181b3fc"
|
| 146 |
+
},
|
| 147 |
+
{
|
| 148 |
+
"file": "decision_head.safetensors",
|
| 149 |
+
"bytes": 10529624,
|
| 150 |
+
"sha256": "8b8e342445035e503b4963e16c5f7a4fef95c08368e27eace312145fc3660772"
|
| 151 |
+
},
|
| 152 |
+
{
|
| 153 |
+
"file": "tokenizer.json",
|
| 154 |
+
"bytes": 19989325,
|
| 155 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523"
|
| 156 |
+
},
|
| 157 |
+
{
|
| 158 |
+
"file": "tokenizer_config.json",
|
| 159 |
+
"bytes": 1123,
|
| 160 |
+
"sha256": "bee8eba30f0eb4af73c0fe2cd06d0f89b657d7819941c438157ec42f7c80ea87"
|
| 161 |
+
}
|
| 162 |
+
],
|
| 163 |
+
"source_model_code_sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646",
|
| 164 |
+
"source_api_code_sha256": "147b2fec32cbbbbb1b92cf2a19bb887f9d945e4974e141ca7ea93b8c542f5b21",
|
| 165 |
+
"dev_sha256": "45b4cd46acc4be53b95c7ed8f333b3533972296a4d0557c7b8c48c9cab6ced61",
|
| 166 |
+
"production_predictions_sha256": "cf0b1a17008bddc2e3e18289866993770c41d4a5af5f6f4219508bb34fcabefa",
|
| 167 |
+
"temperature_sha256": "1d652e75f49b5c232d1e742b189c1c826ad52ced1a931a124e29e65e7d7fb569",
|
| 168 |
+
"runtime_sha256": "c5d3521358b2817f4e56ea8150c5c612139b4e2b2c5bb09f512d9a7c0b5298b9",
|
| 169 |
+
"production_batch_size": 8,
|
| 170 |
+
"input_length_limit": 16384,
|
| 171 |
+
"original_checkpoint_name": "winner",
|
| 172 |
+
"no_publication_performed": true
|
| 173 |
+
}
|
assets/decision-capabilities.svg
DELETED
assets/{architecture-atlas.pdf → decision-expanded-old_core-600px.png}
RENAMED
|
File without changes
|
assets/decision-expanded-old_core.pdf
ADDED
|
Binary file (44 kB). View file
|
|
|
assets/{architecture.pdf → decision-expanded-old_core.png}
RENAMED
|
File without changes
|
assets/decision-expanded-old_core.svg
ADDED

|
assets/decision-expanded-overview-600px.png
ADDED

|
assets/decision-expanded-overview.pdf
ADDED
|
Binary file (40.6 kB). View file
|
|
|
assets/{decision-capabilities.pdf → decision-expanded-overview.png}
RENAMED
|
File without changes
|
assets/decision-expanded-overview.svg
ADDED

|
assets/decision-expanded-ranking-600px.png
ADDED

|
assets/{decision-quality.pdf → decision-expanded-ranking.pdf}
RENAMED
|
Binary files a/assets/decision-quality.pdf and b/assets/decision-expanded-ranking.pdf differ
|
|
|
assets/{decision-capabilities.png → decision-expanded-ranking.png}
RENAMED
|
File without changes
|
assets/{decision-quality.svg → decision-expanded-ranking.svg}
RENAMED
|
File without changes
|
assets/decision-expanded-v3_core-600px.png
ADDED

|
Git LFS Details
|
assets/decision-expanded-v3_core.pdf
ADDED
|
Binary file (44.1 kB). View file
|
|
|
assets/decision-expanded-v3_core.png
ADDED

|
Git LFS Details
|
assets/decision-expanded-v3_core.svg
ADDED

|
assets/decision-expanded-v4-600px.png
ADDED

|
assets/decision-expanded-v4.pdf
ADDED
|
Binary file (38.1 kB). View file
|
|
|
assets/decision-expanded-v4.png
ADDED

|
Git LFS Details
|
assets/decision-expanded-v4.svg
ADDED

|
assets/decision-expanded-v5-600px.png
ADDED

|
assets/decision-expanded-v5.pdf
ADDED
|
Binary file (40.1 kB). View file
|
|
|
assets/decision-expanded-v5.png
ADDED

|
Git LFS Details
|
assets/decision-expanded-v5.svg
ADDED

|
assets/decision-mark.png
DELETED
Git LFS Details
|
assets/decision-quality.png
DELETED
Git LFS Details
|
assets/decision-question-scaling-600px.png
ADDED

|
assets/decision-question-scaling.pdf
CHANGED
|
Binary files a/assets/decision-question-scaling.pdf and b/assets/decision-question-scaling.pdf differ
|
|
|
assets/decision-question-scaling.png
CHANGED

|

|
Git LFS Details
|
assets/decision-question-scaling.svg
CHANGED
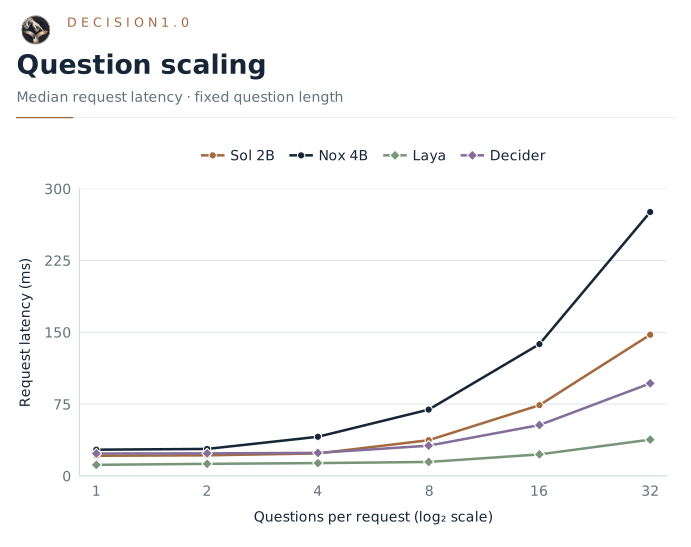
|

|
assets/readout.pdf
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:d489b0d1814e37495a8612c12fabd3bf4a6e73d11c7e356bf1ce0cedded8a745
|
| 3 |
-
size 123008
|
|
|
|
|
|
|
|
|
|
|
|
assets/readout.svg
DELETED
backbone/model-00001-of-00003.safetensors
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
size 3991295368
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5f9c4bc396605b551b5983a1699de8e96755fafdb6afdb228a5cc4d9b438a5da
|
| 3 |
size 3991295368
|
backbone/model-00002-of-00003.safetensors
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
size 3979828128
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:656cc757ba03f87cedc0e4c88237db1ae8215686f9b6477334a34dc0a32136db
|
| 3 |
size 3979828128
|
backbone/model-00003-of-00003.safetensors
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
size 440425856
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0a30a07b6efbaa37d016008848c1fa6dadcb46ae451a0e5e4b927ac9b5771804
|
| 3 |
size 440425856
|
bundle-manifest.json
CHANGED
|
@@ -1,7 +1,22 @@
|
|
| 1 |
{
|
| 2 |
"format": "research-pointer-bundle-v1",
|
| 3 |
-
"status": "
|
| 4 |
"files": [
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 5 |
{
|
| 6 |
"file": "backbone/config.json",
|
| 7 |
"bytes": 1978,
|
|
@@ -10,17 +25,17 @@
|
|
| 10 |
{
|
| 11 |
"file": "backbone/model-00001-of-00003.safetensors",
|
| 12 |
"bytes": 3991295368,
|
| 13 |
-
"sha256": "
|
| 14 |
},
|
| 15 |
{
|
| 16 |
"file": "backbone/model-00002-of-00003.safetensors",
|
| 17 |
"bytes": 3979828128,
|
| 18 |
-
"sha256": "
|
| 19 |
},
|
| 20 |
{
|
| 21 |
"file": "backbone/model-00003-of-00003.safetensors",
|
| 22 |
"bytes": 440425856,
|
| 23 |
-
"sha256": "
|
| 24 |
},
|
| 25 |
{
|
| 26 |
"file": "backbone/model.safetensors.index.json",
|
|
@@ -34,8 +49,8 @@
|
|
| 34 |
},
|
| 35 |
{
|
| 36 |
"file": "code/decision_api.py",
|
| 37 |
-
"bytes":
|
| 38 |
-
"sha256": "
|
| 39 |
},
|
| 40 |
{
|
| 41 |
"file": "code/decision_model.py",
|
|
@@ -47,6 +62,16 @@
|
|
| 47 |
"bytes": 3164,
|
| 48 |
"sha256": "02352e8385ab47157b6459910da54d962e5da4bb4940d571faedc86bc5da9aee"
|
| 49 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 50 |
{
|
| 51 |
"file": "decision_config.json",
|
| 52 |
"bytes": 753,
|
|
@@ -55,17 +80,47 @@
|
|
| 55 |
{
|
| 56 |
"file": "decision_head.safetensors",
|
| 57 |
"bytes": 10529624,
|
| 58 |
-
"sha256": "
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 59 |
},
|
| 60 |
{
|
| 61 |
"file": "runtime.json",
|
| 62 |
-
"bytes":
|
| 63 |
-
"sha256": "
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 64 |
},
|
| 65 |
{
|
| 66 |
"file": "temperature.json",
|
| 67 |
-
"bytes":
|
| 68 |
-
"sha256": "
|
| 69 |
},
|
| 70 |
{
|
| 71 |
"file": "tokenizer.json",
|
|
@@ -117,37 +172,37 @@
|
|
| 117 |
{
|
| 118 |
"file": "backbone/model-00001-of-00005.safetensors",
|
| 119 |
"bytes": 3992269864,
|
| 120 |
-
"sha256": "
|
| 121 |
},
|
| 122 |
{
|
| 123 |
"file": "backbone/model-00002-of-00005.safetensors",
|
| 124 |
"bytes": 3990302320,
|
| 125 |
-
"sha256": "
|
| 126 |
},
|
| 127 |
{
|
| 128 |
"file": "backbone/model-00003-of-00005.safetensors",
|
| 129 |
"bytes": 3937871784,
|
| 130 |
-
"sha256": "
|
| 131 |
},
|
| 132 |
{
|
| 133 |
"file": "backbone/model-00004-of-00005.safetensors",
|
| 134 |
"bytes": 3926578128,
|
| 135 |
-
"sha256": "
|
| 136 |
},
|
| 137 |
{
|
| 138 |
"file": "backbone/model-00005-of-00005.safetensors",
|
| 139 |
"bytes": 976029360,
|
| 140 |
-
"sha256": "
|
| 141 |
},
|
| 142 |
{
|
| 143 |
"file": "decision_config.json",
|
| 144 |
-
"bytes":
|
| 145 |
-
"sha256": "
|
| 146 |
},
|
| 147 |
{
|
| 148 |
"file": "decision_head.safetensors",
|
| 149 |
"bytes": 10529624,
|
| 150 |
-
"sha256": "
|
| 151 |
},
|
| 152 |
{
|
| 153 |
"file": "tokenizer.json",
|
|
@@ -161,13 +216,16 @@
|
|
| 161 |
}
|
| 162 |
],
|
| 163 |
"source_model_code_sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646",
|
| 164 |
-
"source_api_code_sha256": "
|
| 165 |
-
"dev_sha256": "
|
| 166 |
-
"production_predictions_sha256": "
|
| 167 |
-
"temperature_sha256": "
|
| 168 |
-
"runtime_sha256": "
|
| 169 |
"production_batch_size": 8,
|
| 170 |
"input_length_limit": 16384,
|
| 171 |
-
"original_checkpoint_name": "
|
| 172 |
-
"no_publication_performed": true
|
|
|
|
|
|
|
|
|
|
| 173 |
}
|
|
|
|
| 1 |
{
|
| 2 |
"format": "research-pointer-bundle-v1",
|
| 3 |
+
"status": "profile-bound-candidate-awaiting-default-public-entrypoint-offline-proof",
|
| 4 |
"files": [
|
| 5 |
+
{
|
| 6 |
+
"file": "NORMALIZATION_RUNTIME.md",
|
| 7 |
+
"bytes": 756,
|
| 8 |
+
"sha256": "cf8e6ce1f07687a68b6adeb98e6704b8f292cb6adc7b10e4b84e8e70aa5472e5"
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"file": "RUNTIME_BINDING.json",
|
| 12 |
+
"bytes": 2621,
|
| 13 |
+
"sha256": "65a7772ed57e811faefe6b3b3868e174c5e4a3d7f3aa0138a3838464bb2612fe"
|
| 14 |
+
},
|
| 15 |
+
{
|
| 16 |
+
"file": "SOURCE_BUNDLE_MANIFEST.json",
|
| 17 |
+
"bytes": 5637,
|
| 18 |
+
"sha256": "6d402d6d55e734851cb0d6417d6f3b416b25ae807c3a0d6dcf12e40acb6ac546"
|
| 19 |
+
},
|
| 20 |
{
|
| 21 |
"file": "backbone/config.json",
|
| 22 |
"bytes": 1978,
|
|
|
|
| 25 |
{
|
| 26 |
"file": "backbone/model-00001-of-00003.safetensors",
|
| 27 |
"bytes": 3991295368,
|
| 28 |
+
"sha256": "5f9c4bc396605b551b5983a1699de8e96755fafdb6afdb228a5cc4d9b438a5da"
|
| 29 |
},
|
| 30 |
{
|
| 31 |
"file": "backbone/model-00002-of-00003.safetensors",
|
| 32 |
"bytes": 3979828128,
|
| 33 |
+
"sha256": "656cc757ba03f87cedc0e4c88237db1ae8215686f9b6477334a34dc0a32136db"
|
| 34 |
},
|
| 35 |
{
|
| 36 |
"file": "backbone/model-00003-of-00003.safetensors",
|
| 37 |
"bytes": 440425856,
|
| 38 |
+
"sha256": "0a30a07b6efbaa37d016008848c1fa6dadcb46ae451a0e5e4b927ac9b5771804"
|
| 39 |
},
|
| 40 |
{
|
| 41 |
"file": "backbone/model.safetensors.index.json",
|
|
|
|
| 49 |
},
|
| 50 |
{
|
| 51 |
"file": "code/decision_api.py",
|
| 52 |
+
"bytes": 8251,
|
| 53 |
+
"sha256": "1b068eccdffd3c3b67bfa52f8f526e6b482d92551c927668ad28a794767f8a40"
|
| 54 |
},
|
| 55 |
{
|
| 56 |
"file": "code/decision_model.py",
|
|
|
|
| 62 |
"bytes": 3164,
|
| 63 |
"sha256": "02352e8385ab47157b6459910da54d962e5da4bb4940d571faedc86bc5da9aee"
|
| 64 |
},
|
| 65 |
+
{
|
| 66 |
+
"file": "code/profile_guard.py",
|
| 67 |
+
"bytes": 6184,
|
| 68 |
+
"sha256": "061d6ba3edf032038b074b061879a1ff81cfd2928fc0131c66b15563f7822509"
|
| 69 |
+
},
|
| 70 |
+
{
|
| 71 |
+
"file": "code/runtime_profile.py",
|
| 72 |
+
"bytes": 2857,
|
| 73 |
+
"sha256": "3e26ed65f2cd706def209761421cb8fc825281e5c1ed8f168350365ad803dc96"
|
| 74 |
+
},
|
| 75 |
{
|
| 76 |
"file": "decision_config.json",
|
| 77 |
"bytes": 753,
|
|
|
|
| 80 |
{
|
| 81 |
"file": "decision_head.safetensors",
|
| 82 |
"bytes": 10529624,
|
| 83 |
+
"sha256": "8b8e342445035e503b4963e16c5f7a4fef95c08368e27eace312145fc3660772"
|
| 84 |
+
},
|
| 85 |
+
{
|
| 86 |
+
"file": "pyproject.toml",
|
| 87 |
+
"bytes": 436,
|
| 88 |
+
"sha256": "135a9516e87ca2fb41ef54a974e29132256b6c2d528a1cbdea1001e28f306946"
|
| 89 |
+
},
|
| 90 |
+
{
|
| 91 |
+
"file": "runtime-profile/l2norm_fwd_kernel.json",
|
| 92 |
+
"bytes": 26330,
|
| 93 |
+
"sha256": "d7ed7c9962a48efdfa76ed695c8bdc0f56afe1397c202c936eb78315e87a26df"
|
| 94 |
+
},
|
| 95 |
+
{
|
| 96 |
+
"file": "runtime-profile/profile.json",
|
| 97 |
+
"bytes": 35040,
|
| 98 |
+
"sha256": "be32858d15233e0a3fbee0e4257fb02be0b3439deee4eb9c3f61151df7b73850"
|
| 99 |
},
|
| 100 |
{
|
| 101 |
"file": "runtime.json",
|
| 102 |
+
"bytes": 1112,
|
| 103 |
+
"sha256": "78a2c21f8138beeffb3e6b1c11e03cb48972a78ca5ef3d1f58c50651031c34b6"
|
| 104 |
+
},
|
| 105 |
+
{
|
| 106 |
+
"file": "src/decision/__init__.py",
|
| 107 |
+
"bytes": 167,
|
| 108 |
+
"sha256": "70de37df98b6fc8e3b9f9d43935ba31a32350496214c11adf8c5fba72c433313"
|
| 109 |
+
},
|
| 110 |
+
{
|
| 111 |
+
"file": "src/decision/example.py",
|
| 112 |
+
"bytes": 3581,
|
| 113 |
+
"sha256": "a54dec885f92c2d38d07ef2333dff51965be52bc119f772cc74200ed314e69b6"
|
| 114 |
+
},
|
| 115 |
+
{
|
| 116 |
+
"file": "src/decision/model.py",
|
| 117 |
+
"bytes": 9415,
|
| 118 |
+
"sha256": "ba240d7493fc29203fe036966f0ab911200cd4a9252b50b05423409977639ee0"
|
| 119 |
},
|
| 120 |
{
|
| 121 |
"file": "temperature.json",
|
| 122 |
+
"bytes": 6095,
|
| 123 |
+
"sha256": "1d652e75f49b5c232d1e742b189c1c826ad52ced1a931a124e29e65e7d7fb569"
|
| 124 |
},
|
| 125 |
{
|
| 126 |
"file": "tokenizer.json",
|
|
|
|
| 172 |
{
|
| 173 |
"file": "backbone/model-00001-of-00005.safetensors",
|
| 174 |
"bytes": 3992269864,
|
| 175 |
+
"sha256": "8adb3dbf9db30b3ecd1f29ce6a853bc6d7e3f465857471cfe579c570537250f8"
|
| 176 |
},
|
| 177 |
{
|
| 178 |
"file": "backbone/model-00002-of-00005.safetensors",
|
| 179 |
"bytes": 3990302320,
|
| 180 |
+
"sha256": "8aa80bed34a466a7208ad177d5e5742773e4140c55cba69911fcc805633afa5e"
|
| 181 |
},
|
| 182 |
{
|
| 183 |
"file": "backbone/model-00003-of-00005.safetensors",
|
| 184 |
"bytes": 3937871784,
|
| 185 |
+
"sha256": "9af681e845c99e0d933dc3fa643271ee9f5bb382f98454ceb41eb1faf0979f87"
|
| 186 |
},
|
| 187 |
{
|
| 188 |
"file": "backbone/model-00004-of-00005.safetensors",
|
| 189 |
"bytes": 3926578128,
|
| 190 |
+
"sha256": "34de5c39c2338e1c7110beaf2834c856f3830411002893f7946045c0a083cc92"
|
| 191 |
},
|
| 192 |
{
|
| 193 |
"file": "backbone/model-00005-of-00005.safetensors",
|
| 194 |
"bytes": 976029360,
|
| 195 |
+
"sha256": "ce20083dd8deb786b14fe1126a12cdbf678a8a3c25367a6676c0ca55d9ae7980"
|
| 196 |
},
|
| 197 |
{
|
| 198 |
"file": "decision_config.json",
|
| 199 |
+
"bytes": 1110,
|
| 200 |
+
"sha256": "a12bd49b459771f22d22f29c59fe3cb6779c52a5d39b40cdbe5e247c5181b3fc"
|
| 201 |
},
|
| 202 |
{
|
| 203 |
"file": "decision_head.safetensors",
|
| 204 |
"bytes": 10529624,
|
| 205 |
+
"sha256": "8b8e342445035e503b4963e16c5f7a4fef95c08368e27eace312145fc3660772"
|
| 206 |
},
|
| 207 |
{
|
| 208 |
"file": "tokenizer.json",
|
|
|
|
| 216 |
}
|
| 217 |
],
|
| 218 |
"source_model_code_sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646",
|
| 219 |
+
"source_api_code_sha256": "1b068eccdffd3c3b67bfa52f8f526e6b482d92551c927668ad28a794767f8a40",
|
| 220 |
+
"dev_sha256": "45b4cd46acc4be53b95c7ed8f333b3533972296a4d0557c7b8c48c9cab6ced61",
|
| 221 |
+
"production_predictions_sha256": "cf0b1a17008bddc2e3e18289866993770c41d4a5af5f6f4219508bb34fcabefa",
|
| 222 |
+
"temperature_sha256": "1d652e75f49b5c232d1e742b189c1c826ad52ced1a931a124e29e65e7d7fb569",
|
| 223 |
+
"runtime_sha256": "78a2c21f8138beeffb3e6b1c11e03cb48972a78ca5ef3d1f58c50651031c34b6",
|
| 224 |
"production_batch_size": 8,
|
| 225 |
"input_length_limit": 16384,
|
| 226 |
+
"original_checkpoint_name": "winner",
|
| 227 |
+
"no_publication_performed": true,
|
| 228 |
+
"source_bundle_manifest_sha256": "6d402d6d55e734851cb0d6417d6f3b416b25ae807c3a0d6dcf12e40acb6ac546",
|
| 229 |
+
"normalization_profile_sha256": "be32858d15233e0a3fbee0e4257fb02be0b3439deee4eb9c3f61151df7b73850",
|
| 230 |
+
"public_wrapper_included": true
|
| 231 |
}
|
code/decision_api.py
CHANGED
|
@@ -10,6 +10,32 @@ import math
|
|
| 10 |
from pathlib import Path
|
| 11 |
|
| 12 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 13 |
def question_row(state, name, question):
|
| 14 |
kind=question.get('type')
|
| 15 |
if kind not in {'choice','noul','score'}:raise ValueError('Unknown question type')
|
|
@@ -61,6 +87,7 @@ def typed_answer(row, probabilities):
|
|
| 61 |
class DecisionEngine:
|
| 62 |
def __init__(self, checkpoint, model_code, *, device='cuda:0', max_length=16384,
|
| 63 |
batch_size=8, temperatures=None, model_name='local-decision-research'):
|
|
|
|
| 64 |
import torch
|
| 65 |
path=Path(model_code)/'decision_model.py'
|
| 66 |
spec=importlib.util.spec_from_file_location('research_decision_runtime',path)
|
|
|
|
| 10 |
from pathlib import Path
|
| 11 |
|
| 12 |
|
| 13 |
+
def prepare_runtime_profile(checkpoint, device='cuda:0'):
|
| 14 |
+
# This profile is verified before any dependency import can choose kernels.
|
| 15 |
+
import hashlib, json, sys
|
| 16 |
+
root=Path(checkpoint);runtime=json.loads((root/'runtime.json').read_text())
|
| 17 |
+
spec=runtime.get('normalization_profile')
|
| 18 |
+
if spec is None:
|
| 19 |
+
if '_decision_process_normalization_profile_v1' in sys.modules:
|
| 20 |
+
raise RuntimeError('Use separate processes for profiled and unprofiled models')
|
| 21 |
+
return None
|
| 22 |
+
import torch
|
| 23 |
+
target=torch.device(device)
|
| 24 |
+
if target.type!='cuda' or not torch.cuda.is_available():
|
| 25 |
+
raise RuntimeError('The bound profile requires a ROCm CUDA device')
|
| 26 |
+
arch=getattr(torch.cuda.get_device_properties(target),'gcnArchName','').split(':')[0]
|
| 27 |
+
if arch!=spec['validated_arch']:
|
| 28 |
+
raise RuntimeError('Target GPU architecture does not match the bound profile: '+arch)
|
| 29 |
+
relative=Path(spec['loader_file'])
|
| 30 |
+
if relative.is_absolute() or '..' in relative.parts:raise ValueError('Unsafe profile loader path')
|
| 31 |
+
path=root/relative
|
| 32 |
+
if hashlib.sha256(path.read_bytes()).hexdigest()!=spec['loader_sha256']:
|
| 33 |
+
raise ValueError('Bound runtime profile loader changed')
|
| 34 |
+
definition=importlib.util.spec_from_file_location('decision_bundle_runtime_profile',path)
|
| 35 |
+
module=importlib.util.module_from_spec(definition);definition.loader.exec_module(module)
|
| 36 |
+
return module.ensure_profile(root)
|
| 37 |
+
|
| 38 |
+
|
| 39 |
def question_row(state, name, question):
|
| 40 |
kind=question.get('type')
|
| 41 |
if kind not in {'choice','noul','score'}:raise ValueError('Unknown question type')
|
|
|
|
| 87 |
class DecisionEngine:
|
| 88 |
def __init__(self, checkpoint, model_code, *, device='cuda:0', max_length=16384,
|
| 89 |
batch_size=8, temperatures=None, model_name='local-decision-research'):
|
| 90 |
+
self.normalization_profile=prepare_runtime_profile(checkpoint, device=device)
|
| 91 |
import torch
|
| 92 |
path=Path(model_code)/'decision_model.py'
|
| 93 |
spec=importlib.util.spec_from_file_location('research_decision_runtime',path)
|
code/profile_guard.py
ADDED
|
@@ -0,0 +1,82 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Fail-closed official FLA strict-config setup for one isolated process.
|
| 2 |
+
|
| 3 |
+
No model/prompt/head changes. The guard prevents FLA STRICT's ordinary missing
|
| 4 |
+
key fallback and records actual configured calls. This is a diagnostic module,
|
| 5 |
+
not an installed change to the published wrapper or dependency environment.
|
| 6 |
+
"""
|
| 7 |
+
import hashlib,importlib,json,os,sys
|
| 8 |
+
from pathlib import Path
|
| 9 |
+
|
| 10 |
+
def sha(p):return hashlib.sha256(Path(p).read_bytes()).hexdigest()
|
| 11 |
+
def serialized(key):return json.dumps(key,separators=(',',':'),sort_keys=True)
|
| 12 |
+
def config_fields(config):
|
| 13 |
+
if isinstance(config,dict):return {k:config.get(k) for k in ['kwargs','num_warps','num_stages','num_ctas','maxnreg','ir_override']}
|
| 14 |
+
return {k:getattr(config,k,None) for k in ['kwargs','num_warps','num_stages','num_ctas','maxnreg','ir_override']}
|
| 15 |
+
def validate_profile(path,expected_sha):
|
| 16 |
+
path=Path(path).resolve()
|
| 17 |
+
if sha(path)!=expected_sha:raise ValueError('Profile hash changed')
|
| 18 |
+
profile=json.loads(path.read_text())
|
| 19 |
+
if profile['format']!='decision-fla-l2norm-profile-v1' or profile.get('model_family')!='Qwen/Qwen3.5-4B' or profile['cache_mode']!='strict':raise ValueError('Profile format/mode unsupported')
|
| 20 |
+
if len(profile['files'])!=1 or profile['files'][0]['file']!='l2norm_fwd_kernel.json':raise ValueError('Unexpected profile file set')
|
| 21 |
+
f=path.parent/'l2norm_fwd_kernel.json'
|
| 22 |
+
if sha(f)!=profile['files'][0]['sha256']:raise ValueError('Explicit kernel config changed')
|
| 23 |
+
data=json.loads(f.read_text());entries={}
|
| 24 |
+
if data.get('default_config') is not None:raise ValueError('Implicit fallback defaults forbidden')
|
| 25 |
+
for h,item in data['autotune_entries'].items():
|
| 26 |
+
key=item['autotune_key'];encoded=serialized(key)
|
| 27 |
+
if hashlib.md5(encoded.encode()).hexdigest()!=h or encoded in entries:raise ValueError('Invalid/duplicate key')
|
| 28 |
+
if len(key)!=5 or key[0]!=128 or type(key[1]) is not int or not 1<=key[1]<=64 or key[2:]!=['torch.bfloat16','torch.bfloat16','torch.float32']:raise ValueError('Unsupported numerical key')
|
| 29 |
+
c=item['config']
|
| 30 |
+
if c['kwargs'].keys()!={'BT'} or c['kwargs']['BT'] not in [8,16,32,64] or c['num_warps'] not in [1,2,4,8,16] or c['num_stages']!=3 or c['num_ctas']!=1 or any(c.get(x) is not None for x in ['maxnreg','pre_hook','ir_override']):raise ValueError('Unexpected launch configuration')
|
| 31 |
+
entries[encoded]=c
|
| 32 |
+
if {json.loads(k)[1] for k in entries}!=set(range(1,65)):raise ValueError('Incomplete legal NB coverage')
|
| 33 |
+
return path,profile,entries
|
| 34 |
+
|
| 35 |
+
def attach_guard(kernel,cache_module,entries,telemetry):
|
| 36 |
+
original=kernel.run
|
| 37 |
+
def guarded(*args,**kwargs):
|
| 38 |
+
if cache_module.FLA_CACHE_MODE is not cache_module.FlaCacheMode.STRICT:raise RuntimeError('FLA strict mode changed')
|
| 39 |
+
key=cache_module.AutotuneKey.build(kernel.arg_names,kernel.keys,args,kwargs);encoded=serialized(list(key.autotune_key))
|
| 40 |
+
if encoded not in entries:raise RuntimeError('Uncontracted FLA l2norm key: '+encoded)
|
| 41 |
+
expected=entries[encoded];loaded=cache_module.load_cached_config(kernel.kernel_name,key)
|
| 42 |
+
if config_fields(loaded)!=config_fields(expected):raise RuntimeError('FLA exact config lookup mismatch')
|
| 43 |
+
if key.autotune_key in kernel.cache and config_fields(kernel.cache[key.autotune_key])!=config_fields(expected):raise RuntimeError('A conflicting in-process kernel cache exists')
|
| 44 |
+
# Explicit official configuration load guarantees that the following original
|
| 45 |
+
# run finds this exact cache entry and cannot perform timing-based autotune.
|
| 46 |
+
kernel.maybe_load_cached_config(key)
|
| 47 |
+
if key.autotune_key not in kernel.cache or config_fields(kernel.cache[key.autotune_key])!=config_fields(expected):raise RuntimeError('Official strict config did not load')
|
| 48 |
+
result=original(*args,**kwargs)
|
| 49 |
+
if config_fields(kernel.cache[key.autotune_key])!=config_fields(expected):raise RuntimeError('Kernel config changed during call')
|
| 50 |
+
telemetry['calls']+=1;telemetry['keys'][encoded]=telemetry['keys'].get(encoded,0)+1
|
| 51 |
+
return result
|
| 52 |
+
kernel.run=guarded
|
| 53 |
+
return original
|
| 54 |
+
|
| 55 |
+
def install(profile_path,expected_sha):
|
| 56 |
+
path,profile,entries=validate_profile(profile_path,expected_sha)
|
| 57 |
+
if any(n=='fla' or n.startswith('fla.') for n in sys.modules):raise RuntimeError('Install profile before importing FLA; use a fresh isolated process')
|
| 58 |
+
for name,wanted in {'FLA_CACHE_MODE':'strict','FLA_CONFIG_DIR':str(path.parent)}.items():
|
| 59 |
+
actual=os.environ.get(name)
|
| 60 |
+
if actual is not None and actual!=wanted:raise RuntimeError('Conflicting '+name)
|
| 61 |
+
os.environ[name]=wanted
|
| 62 |
+
import torch,triton,fla
|
| 63 |
+
actual={'torch':str(torch.__version__),'hip':torch.version.hip,'triton':triton.__version__,'fla':fla.__version__}
|
| 64 |
+
for name,value in actual.items():
|
| 65 |
+
if value!=profile['runtime'][name]:raise RuntimeError('Runtime mismatch: '+name)
|
| 66 |
+
if not torch.cuda.is_available():raise RuntimeError('Profile is only qualified for the specified ROCm GPU')
|
| 67 |
+
arch=torch.cuda.get_device_properties(0).gcnArchName.split(':')[0]
|
| 68 |
+
if arch!=profile['runtime']['gpu_arch']:raise RuntimeError('Unsupported GPU architecture '+arch)
|
| 69 |
+
module=importlib.import_module('fla.modules.l2norm');cache_module=importlib.import_module('fla.ops.utils.cache');root=Path(fla.__file__).parent
|
| 70 |
+
for name,value in profile['fla_source_sha256'].items():
|
| 71 |
+
if sha(root/name)!=value:raise RuntimeError('Pinned FLA source changed: '+name)
|
| 72 |
+
kernel=module.l2norm_fwd_kernel
|
| 73 |
+
if kernel.kernel_name!='l2norm_fwd_kernel' or kernel.keys!=['D','NB'] or kernel.cache:raise RuntimeError('Kernel identity or fresh-cache precondition failed')
|
| 74 |
+
telemetry={'profile_sha256':expected_sha,'status':'installed','calls':0,'keys':{},'strict_guard':True,'unknown_keys':'raise','autotune_fallback_permitted':False,'runtime':actual,'gpu_arch':arch,'process_scope':'one explicitly profiled Nox model; other model loading in this process is not supported'}
|
| 75 |
+
attach_guard(kernel,cache_module,entries,telemetry)
|
| 76 |
+
# The validated inference path only uses the vectorized D128 forward kernel.
|
| 77 |
+
# Other dimensions/backward must not silently enter a different autotuner.
|
| 78 |
+
for name in ['l2norm_fwd_kernel1','l2norm_bwd_kernel','l2norm_bwd_kernel1']:
|
| 79 |
+
other=getattr(module,name)
|
| 80 |
+
def reject(*args,_name=name,**kwargs):raise RuntimeError('Uncontracted normalization kernel: '+_name)
|
| 81 |
+
other.run=reject
|
| 82 |
+
return telemetry
|
code/runtime_profile.py
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Bundle-local automatic launch-profile binding, before importing FLA.
|
| 2 |
+
|
| 3 |
+
One profile is active per Python process. Repeated loading of the same verified
|
| 4 |
+
profile is allowed; mixing with an unprofiled/different-profile model is not.
|
| 5 |
+
"""
|
| 6 |
+
import hashlib,importlib.util,json,os,sys,types
|
| 7 |
+
from pathlib import Path
|
| 8 |
+
STATE='_decision_process_normalization_profile_v1'
|
| 9 |
+
def sha(p):return hashlib.sha256(Path(p).read_bytes()).hexdigest()
|
| 10 |
+
def safe(root,relative):
|
| 11 |
+
p=Path(relative)
|
| 12 |
+
if p.is_absolute() or '..' in p.parts:raise ValueError('Unsafe runtime-profile path')
|
| 13 |
+
return root/p
|
| 14 |
+
|
| 15 |
+
def ensure_profile(bundle):
|
| 16 |
+
bundle=Path(bundle).resolve();runtime=json.loads((bundle/'runtime.json').read_text());spec=runtime.get('normalization_profile');active=sys.modules.get(STATE)
|
| 17 |
+
if spec is None:
|
| 18 |
+
if active is not None:raise RuntimeError('Load unprofiled and profiled Decision models in separate processes')
|
| 19 |
+
return None
|
| 20 |
+
if spec.get('kind')!='decision-fla-l2norm-profile-v1' or spec.get('validated_arch')!='gfx942':raise ValueError('Unknown normalization profile contract')
|
| 21 |
+
profile=safe(bundle,spec['profile_file']);guard=safe(bundle,spec['guard_file'])
|
| 22 |
+
if sha(profile)!=spec['profile_sha256'] or sha(guard)!=spec['guard_sha256']:raise ValueError('Bound runtime profile bytes changed')
|
| 23 |
+
if json.loads((bundle/'decision_config.json').read_text()).get('base_model')!='Qwen/Qwen3.5-4B':raise ValueError('This bundle profile is bound to the validated Nox family only')
|
| 24 |
+
if active is not None:
|
| 25 |
+
if active.profile_sha256!=spec['profile_sha256'] or active.guard_sha256!=spec['guard_sha256']:raise RuntimeError('Different Decision normalization profile is already active; use a separate process')
|
| 26 |
+
active.guard.validate_profile(profile,spec['profile_sha256'])
|
| 27 |
+
if os.environ.get('FLA_CACHE_MODE')!='strict' or os.environ.get('FLA_CONFIG_DIR')!=active.profile_dir:raise RuntimeError('Active FLA profile environment changed')
|
| 28 |
+
return {'profile_sha256':active.profile_sha256,'guard_sha256':active.guard_sha256,'validated_arch':'gfx942','automatic_bundle_binding':True,'scope':'single profile per process'}
|
| 29 |
+
module_spec=importlib.util.spec_from_file_location('decision_profile_guard_'+spec['guard_sha256'][:16],guard);module=importlib.util.module_from_spec(module_spec);module_spec.loader.exec_module(module)
|
| 30 |
+
telemetry=module.install(profile,spec['profile_sha256'])
|
| 31 |
+
state=types.ModuleType(STATE);state.profile_sha256=spec['profile_sha256'];state.guard_sha256=spec['guard_sha256'];state.profile_dir=str(profile.parent);state.guard=module;state.telemetry=telemetry;sys.modules[STATE]=state
|
| 32 |
+
return {'profile_sha256':state.profile_sha256,'guard_sha256':state.guard_sha256,'validated_arch':'gfx942','automatic_bundle_binding':True,'scope':'single profile per process'}
|
| 33 |
+
|
| 34 |
+
def active_telemetry():
|
| 35 |
+
state=sys.modules.get(STATE)
|
| 36 |
+
return None if state is None else dict(state.telemetry)
|
decision_head.safetensors
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
size 10529624
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8b8e342445035e503b4963e16c5f7a4fef95c08368e27eace312145fc3660772
|
| 3 |
size 10529624
|