
license: mit
base_model: Qwen/Qwen2.5-VL-7B
tags:
  - vision-language
  - document-to-markdown
  - reinforcement-learning
  - grpo
  - qwen2.5
  - markdown
model_name: NuMarkdown-reasoning
library_name: transformers
pipeline_tag: text-generation
🖥️ API / Platform | 📑 Blog | 🗣️ Discord
NuMarkdown-reasoning 📄
NuMarkdown-reasoning is the first reasoning vision-language model trained specifically to convert documents into clean GitHub-flavoured Markdown. It is a fine-tune of Qwen 2.5-VL-7B using ~10 k synthetic doc-to-Reasoning-to-Markdown pairs, followed by a RL phase (GRPO) with a layout-centric reward.
(note: the number of thinking tokens can vary from 20% to 2X the number of token of the final answers)
Results
NuMarkdown-reasoning is significantly better than similar size non-reasoning models trained for markdown generation on complex documents, and achieve competitive results against top close sources alternatives.
Arena ranking (using trueskill-2 ranking system):
| Rank | Model | μ | σ | μ − 3σ | | ---- | --------------------------------------- | ----- | ---- | ------ | | 🥇 1 | **gemini-flash-reasoning** | 26.75 | 0.80 | 24.35 | | 🥈 2 | **NuMarkdown-reasoning** | 26.10 | 0.79 | 23.72 | | 🥉 3 | **NuMarkdown-reasoning-w/o\_grpo** | 25.32 | 0.80 | 22.93 | | 4 | **OCRFlux-3B** | 24.63 | 0.80 | 22.22 | | 5 | **gpt-4o** | 24.48 | 0.80 | 22.08 | | 6 | **gemini-flash-w/o\_reasoning** | 24.11 | 0.79 | 21.74 | | 7 | **RolmoOCR** | 23.53 | 0.82 | 21.07 |
we plan to realease a markdown arena, similar to llmArena, for complex document to markdown task to help evaluate different document to markdown solution
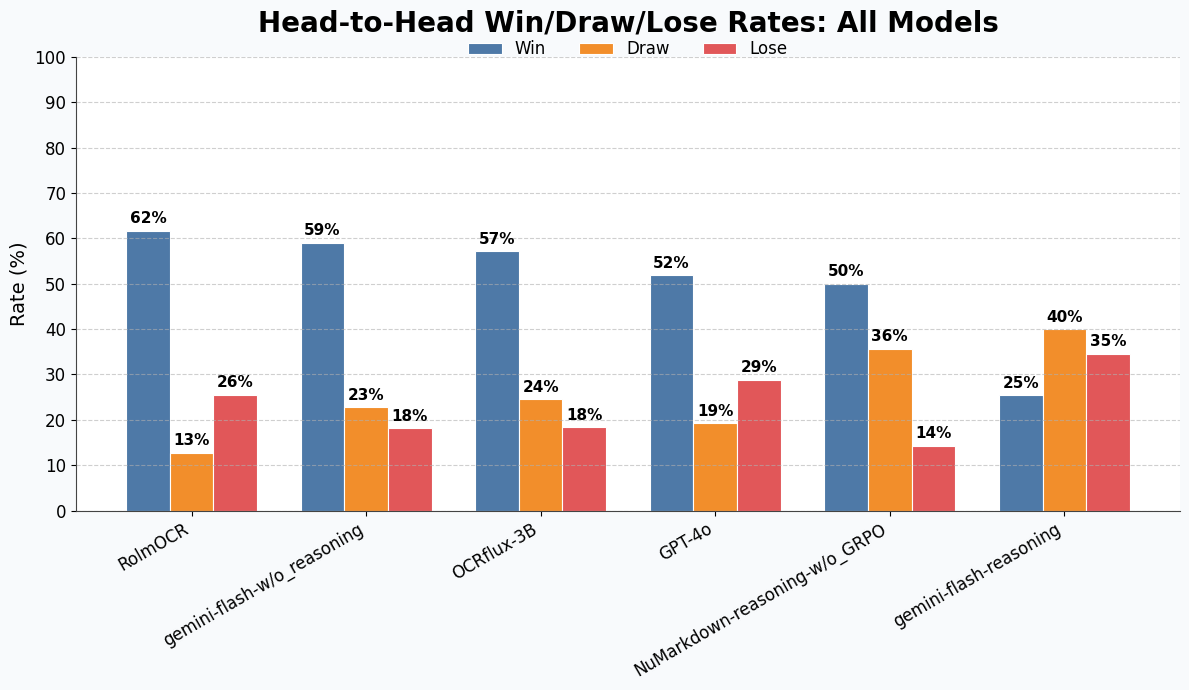
Win-rate against others models (image-only):
Training
- SFT: One-epoch supervised fine-tune on synthetic reasoning trace generated from public PDFs (10K input/output pairs).
- RL (GRPO): RL phase using a structure-aware reward (5K difficults image examples).
Model before GRPO loose 80% time vs post GRPO model (see win-rate matrix)
Quick start: 🤗 Transformers
from __future__ import annotations

import torch
from PIL import Image
from transformers import AutoProcessor, Qwen2_5_VLForConditionalGeneration

model_id = "Numind/NuMarkdown-reasoning"

processor = AutoProcessor.from_pretrained(
    model_id,
    trust_remote_code=True,
)

model = Qwen2_5_VLForConditionalGeneration.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    attn_implementation="flash_attention_2",
    device_map="auto",
    trust_remote_code=True,
)

img = Image.open("invoice.png").convert("RGB")
messages = [{
    "role": "user",
    "content": [
        {"type": "image"},
    ],
}]
prompt = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
enc = processor(text=prompt, images=[img], return_tensors="pt").to(model.device)

with torch.no_grad():
    out = model.generate(**enc, max_new_tokens=5000)

print(processor.decode(out[0].split("<answer>")[1].split("</answer>")[0], skip_special_tokens=True))
VLLM:
from PIL import Image
from vllm import LLM, SamplingParams
from transformers import AutoProcessor

model_id = "Numind/NuMarkdown-reasoning"

llm = LLM(
        model=model_id,
        tokenizer=model_id,
        dtype="bfloat16",
        gpu_memory_utilization=0.85,
        max_num_seqs=256,
        enforce_eager=True,
        trust_remote_code=True
    )

sampling_params = SamplingParams(
                temperature=0.8,
                max_tokens=5000,
)
processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)

inputs = []
messages = [{
        "role": "user",
        "content": [
            {"type": "image"},
            # {"type": "text", "text": guideline},
        ]
}]

prompt = processor.apply_chat_template(
        messages,
        tokenize=False,
        add_generation_prompt=True,
    )
image = Image.open("invoice.png").convert("RGB")

inputs.append({
        "prompt": prompt,
        "multi_modal_data": {"image": image}
})

outs = llm.generate(inputs, sampling_params)
preds = [o.outputs[0].text.strip().split("<answer>")[1].split("</answer>")[0] for o in outs]