

FoundationStereo: Zero-Shot Stereo Matching
Paper • 2501.09898 • Published • 3
FoundationStereo is a foundation model developed by NVIDIA Research for Stereo Depth Estimation. The model takes as input an RGB stereo-image pair and outputs an accurate disparity map. The model was designed to achieve strong zero-shot generalization and has been shown to generalize to various scenarios with wide zero-shot coverage.
FoundationStereo is designed for developers who intend to apply accurate zero-shot depth to 3D perception use cases in industrial, robotics, and smart space applications using stereo images as input.
This model is ready for commercial use.
License to use these models is covered by the NVIDIA Open Model License. By downloading the model, you accept the terms and conditions of these licenses.
Global
Wen, B., Trepte, M., Aribido, J., Kautz, J., Gallo, O., & Birchfield, S. (2025). FoundationStereo: Zero-Shot Stereo Matching. arXiv preprint arXiv:2501.09898.
Architecture Type: Mixed Transformer-CNN based Network Architecture
Network Architecture:
The network consists of various modules. A generic designed feature extractor based on:
The pretrained DepthAnythingV2 is a foundational monocular depth estimation network. The model is frozen in the feature extraction phase and its features are sandwiched with a pretrained CNN-based model, EdgeNeXt. The Edgenext model, though pretrained on NV-Imagenet, is not frozen during training to enable a side-tuning effect into its layer weights.
The extracted stereo features are passed into an Attentive Hybrid Cost Filtering (AHCF) cost volume. The cost volume computes rich correlated mappings between stereo features.
In addition, a disparity transformer is also used to compute feature attention. The features from the disparity transformer are combined with the cost features from the cost volume and combined to estimate an initial disparity map.
To obtain highly accurate disparity output, the initial estimated disparity maps are refined iteratively using a convolutional GRU. Lastly, the mean average error metric is used to assess the model performance.
Number of model parameters: 6.3 * 10^7
Our AI models are designed and/or optimized to run on NVIDIA GPU-accelerated systems. By leveraging NVIDIA’s hardware and software frameworks, FoundationStereo achieves faster training and inference times compared to CPU-only solutions.
Runtime:
FoundationStereo perception module supports PyTorch inference, ONNX and Tensorrt Runtimes.
Supported Hardware Microarchitecture Compatibility:
[Preferred/Supported] Operating Systems:
Deployable_foundation_stereo_small_v1.0: contains two zipped decrypted ONNX files, inferencable on TensorrtEngine and ONNX runtime.
deployable_foundation_stereo_small_dynamic_v1.0: decrypted ONNX file, inferencable on only ONNX runtime.
The network is trained using a mixture of various datasets -synthetically generated data and real-world collected datasets with pseudo-label groundtruth.
During training, the model predicts a coarse initial disparity. A GRU module uses a context network pipeline to refine the initial disparity using a specified iteration sequence. L1-loss is applied to the refined disparity and the network weights are updated accordingly. The validation dataset is carefully selected from a mix of synthetic and real data.
The synthetic dataset used consists of three variants of datasets namely: Foundation Stereo Dataset (FSD), Crestereo and Tartanair. The training datasets can be downloaded at the links below.
The model is first pretrained on FSD and Crestereo, and then finetuned on the former and Tartanair.
Link
Data Collection Method by dataset Hybrid: Synthetic, Human.
The synthetic dataset used was generated using NVIDIA Omniverse and NVIDIA native 3D assets. The real dataset collection was driven by NVIDIA using well-regulated, consent driven approaches.
Labeling Method by dataset
We used only synthetic (SDG) dataset for training, which already contains pseudo-labelled synthetic depth labels.
Properties:
All datasets below are part of the SDG (Synthetic Data Generation) mixture.
| Dataset | Size | Resolution |
|---|---|---|
| FSD | 1.6 M | 720 x 1280 x 3 |
| Crestereo | 200 K | 1080 x 1920 |
| Tartanair | 307 K | 480 x 640 |
Link
Data Collection Method by Dataset
Labeling Method by Dataset
Acceleration Engine Tensor(RT)
Test Hardware:
The inference performance of the FoundationStereo model is evaluated at FP16 precision. In this model card, we included 2 fixed input shape models with spatial resolutions: 320x736 and 576x960 in zipped file respectively. We also include one dynamic-shape model that could take arbitrary input resolutions. However, the dynamic model could not be converted to TensorrtEngine in FP16 precision. Hence, user can only run ONNX inference with the dynamic model.
Both fixed shaped models can be run on ONNX and TRT runtimes. The performance assessment was conducted using trtexec on a range of devices. In the table below, we specify various inference rates on diverse hardware platforms. In the table, "BS" stands for "batch size."
The performance data presented pertains solely to model inference. The end-to-end performance, when integrated with streaming video data, pre-processing and post-processing, might differ due to potential bottlenecks in hardware and software.
| Models (FP16) | Devices | Resolution | Latency (BS=1) | Throughput per Second (BS=1) |
|---|---|---|---|---|
| FoundationStereo | Orin AGX | 320x736 | 1039.00 | 1.00 |
| FoundationStereo | Thor AGX | 320x736 | 1460.95 | 0.67 |
| FoundationStereo | Thor AGX | 576x960 | 2750.00 | 0.36 |
| FoundationStereo | A100 | 320x736 | 199.32 | 5.00 |
| FoundationStereo | A100 | 576x960 | 437.14 | 2.24 |
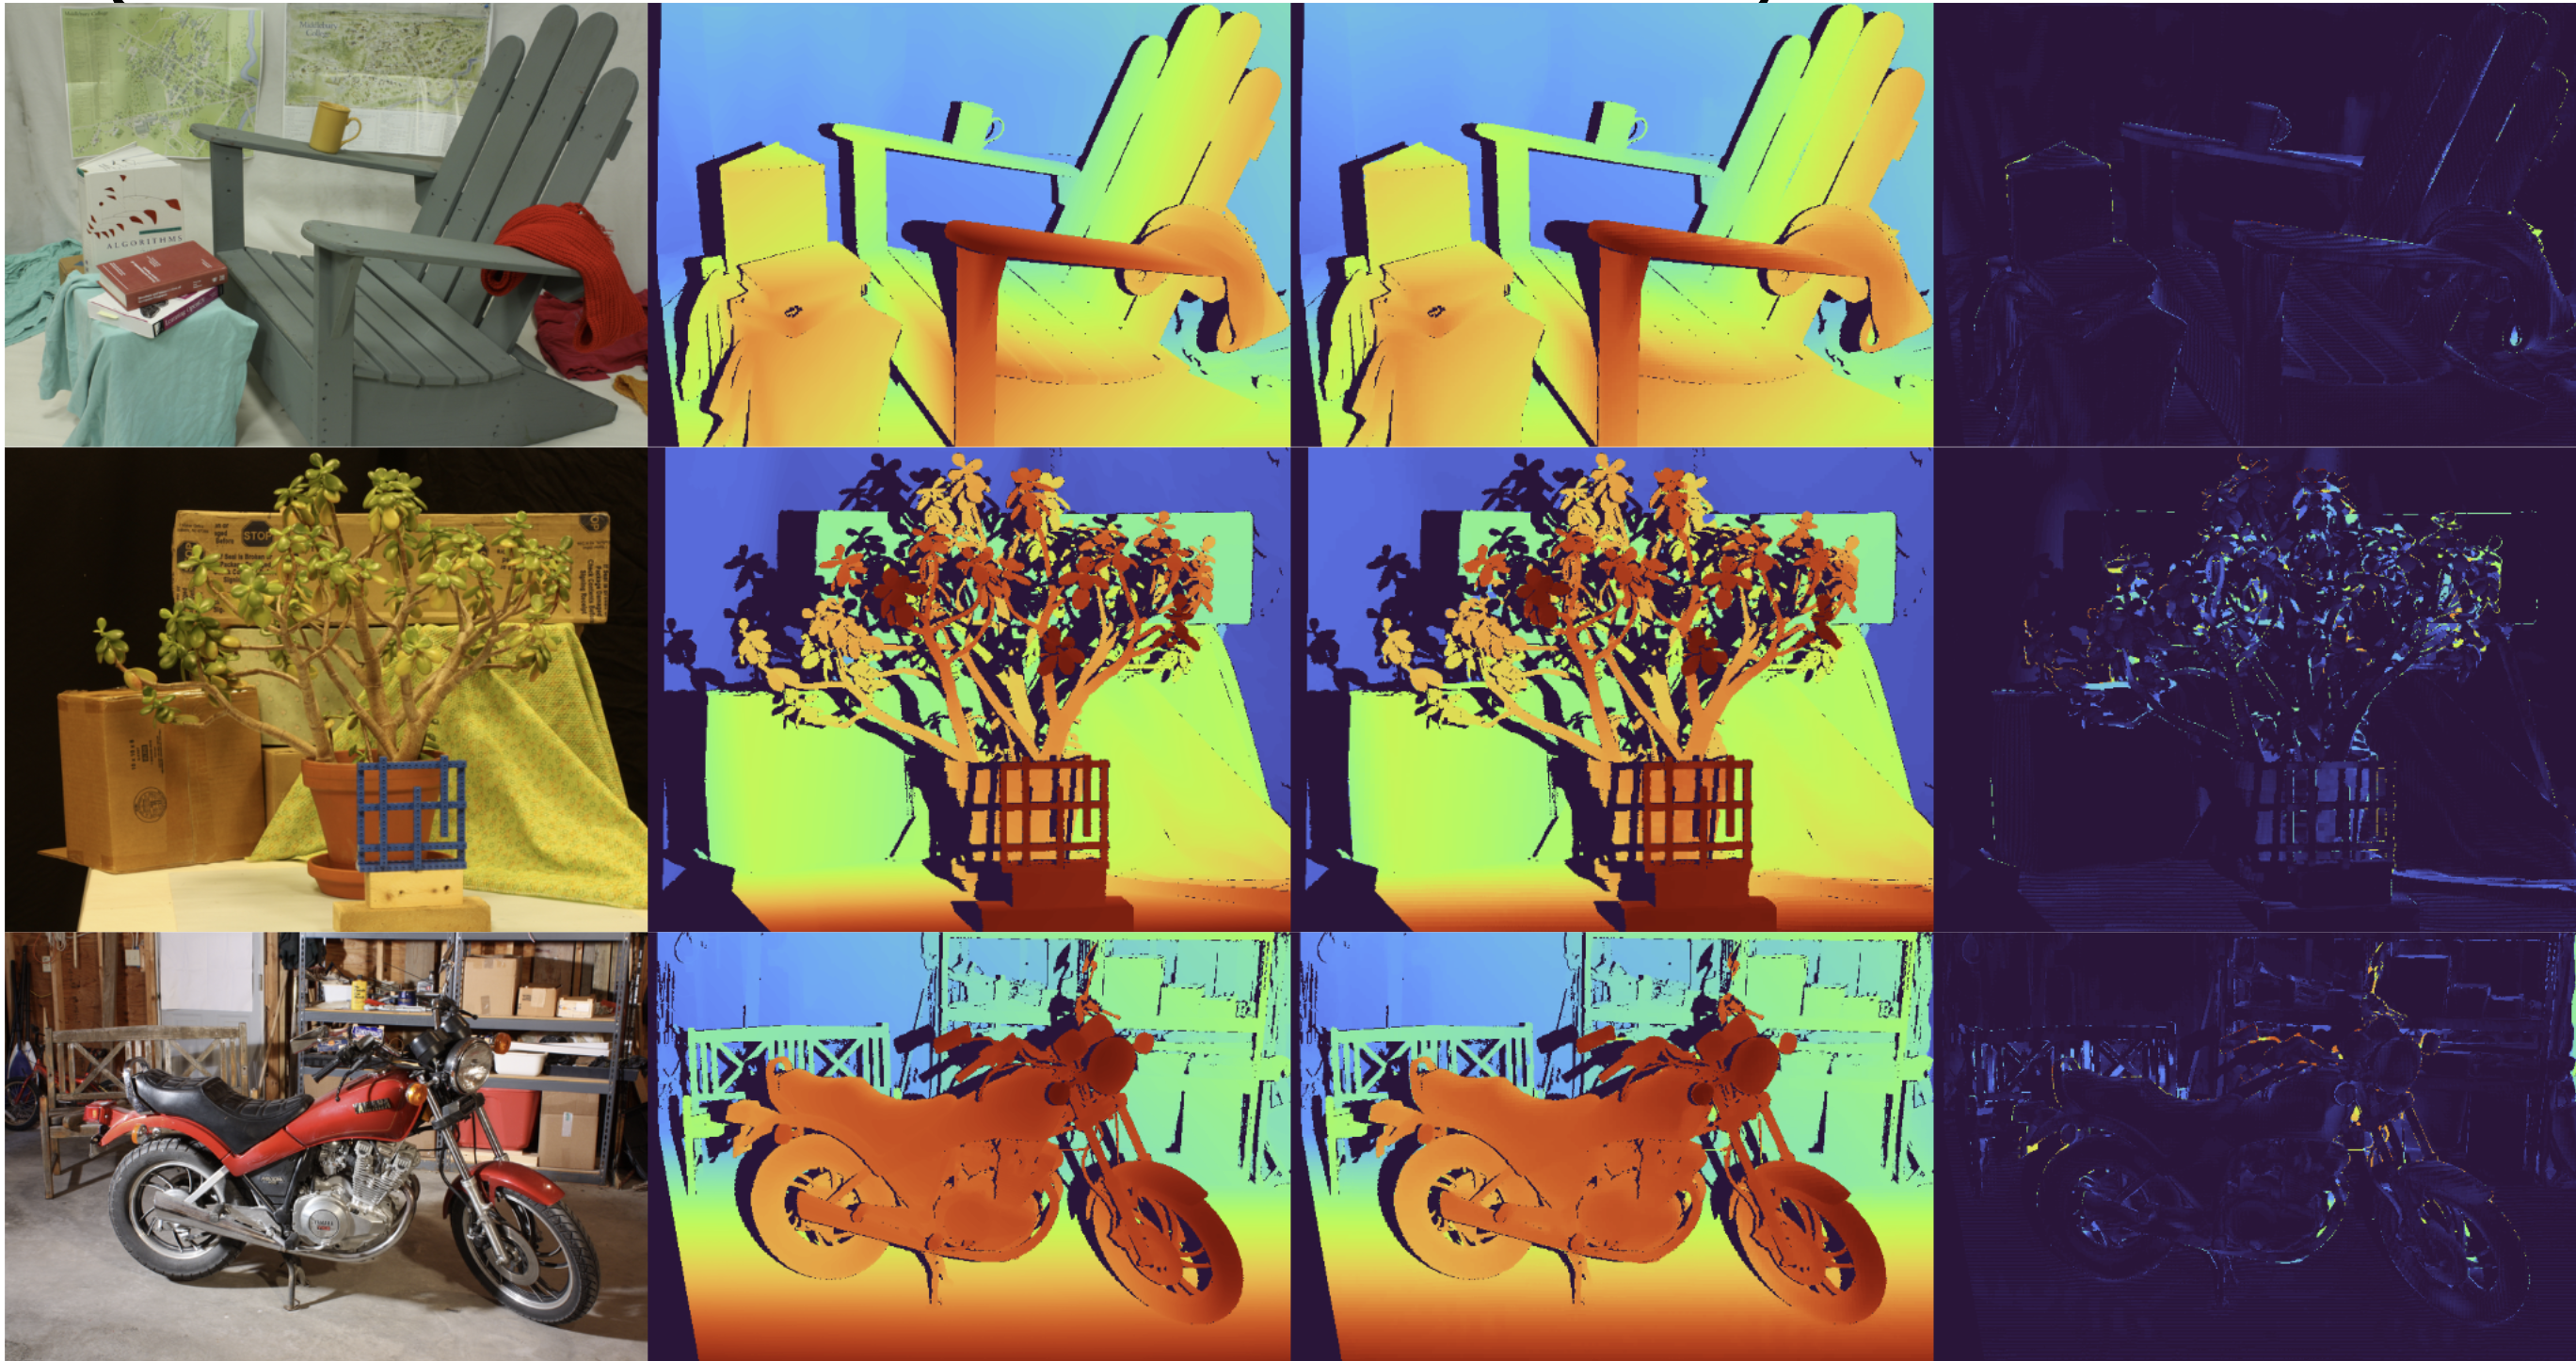
FoundationStereo may produce unreliable depth estimates of transparent objects (e.g., glass and water), high-saturation scenes, or poorly lit areas.
These models are designed for use with NVIDIA hardware and software. For hardware, the models are compatible with any NVIDIA GPU, including NVIDIA Jetson devices. For software, the models are specifically designed for the TensorRT.
The primary application of this model is to estimate an object's depth from a stereo RGB pair.
The model is designed for deployment on edge devices using TensorRT. TAO Triton apps offer capabilities to construct efficient image analytic pipelines. These pipelines can capture, decode, and process data before executing inference.
To create the entire end-to-end inference application, deploy this model with [Triton Inference Server] (https://developer.nvidia.com/nvidia-triton-inference-server). NVIDIA Triton Inference Server is an open-source inference serving software that helps standardize model deployment and execution and delivers fast and scalable AI in production. Triton supports direct integration of this model into the server and inference from a client.
To deploy this model with [Triton Inference Server] (https://developer.nvidia.com/nvidia-triton-inference-server) and end-to-end inference from images, please refer to the TAO Triton apps.
The training and evaluation dataset mostly consists of North American content. An ideal training and evaluation dataset would additionally include content from other geographies.
NVIDIA believes Trustworthy AI is a shared responsibility and we have established policies and practices to enable development for a wide array of AI applications. When downloaded or used in accordance with our terms of service, developers should work with their internal model team to ensure this model meets requirements for the relevant industry and use case and addresses unforeseen product misuse.
For more detailed information on ethical considerations for this model, please see the Model Card++ Explainability, Bias, Safety & Security, and Privacy Subcards.
Please report model quality, risk, security vulnerabilities or NVIDIA AI Concerns here.
| Field | Response |
|---|---|
| Participation considerations from adversely impacted groups (protected classes) in model design and testing: | None of the Above |
| Measures taken to mitigate against unwanted bias: | None. |
| Field | Response |
|---|---|
| Intended Application(s) & Domain(s): | Depth Perception for Robotics, Autonomous Vision Navigation and Space Mapping |
| Model Type: | Zero-shot Depth Estimation |
| Intended Users: | This model is intended for uses who need accurate 3D depth for 2D Stereo Vision |
| Output: | Disparity or Depth Map |
| Describe how the model works: | 1. Pass in two Stereo RGB images. 2. Run the model on the stereo input. 3. Save the disparity map and use camera intrinsic valus to obtain the corresponding depth map. |
| Name the adversely impacted groups this has been tested to deliver comparable outcomes regardless of | Not Applicable |
| Technical Limitations: | This model may not work well for detecting partially or fully occluded objects. |
| Verified to have met prescribed NVIDIA standards: | Yes |
| Performance Metrics: | Percentage of bad pixels, End-point Error (EPE) |
| Potential Known Risks | Poor depth perception from a failure case could lead to hallucination of objects into the depth scene or wrong depth estimation of objects in a scene |
| Licensing: | NVIDIA Open Model License |
| Field | Response |
|---|---|
| Generatable or reverse engineerable personal data? | No |
| Personal data used to create this model? | No |
| How often is dataset reviewed? | Before Release |
| Is there provenance for all datasets used in training? | Yes |
| Does data labeling (annotation, metadata) comply with privacy laws? | Yes |
| Applicable NVIDIA Privacy Policy | Applicable Privacy Policy |
| Field | Response |
|---|---|
| Model Application(s): | Depth Perception Model for Robotics and Autonomous Driving Applications |
| Describe the life-critical application (if present). | None |
| Use Case Restrictions: | Abide by NVIDIA Open Model License |
| Describe access restrictions (if any): | The Principle of least privilege (PoLP) is applied limiting access for dataset generation and model development. Restrictions enforce dataset access during training, and dataset license constraints adhered to. |