


update README
Browse files- README-cn.md +0 -4
- README.md +0 -4
README-cn.md
CHANGED
|
@@ -254,8 +254,6 @@ MiniCPM5-2B 的训练过程是 **[UltraData 分级数据管理体系](https://ar
|
|
| 254 |
|
| 255 |
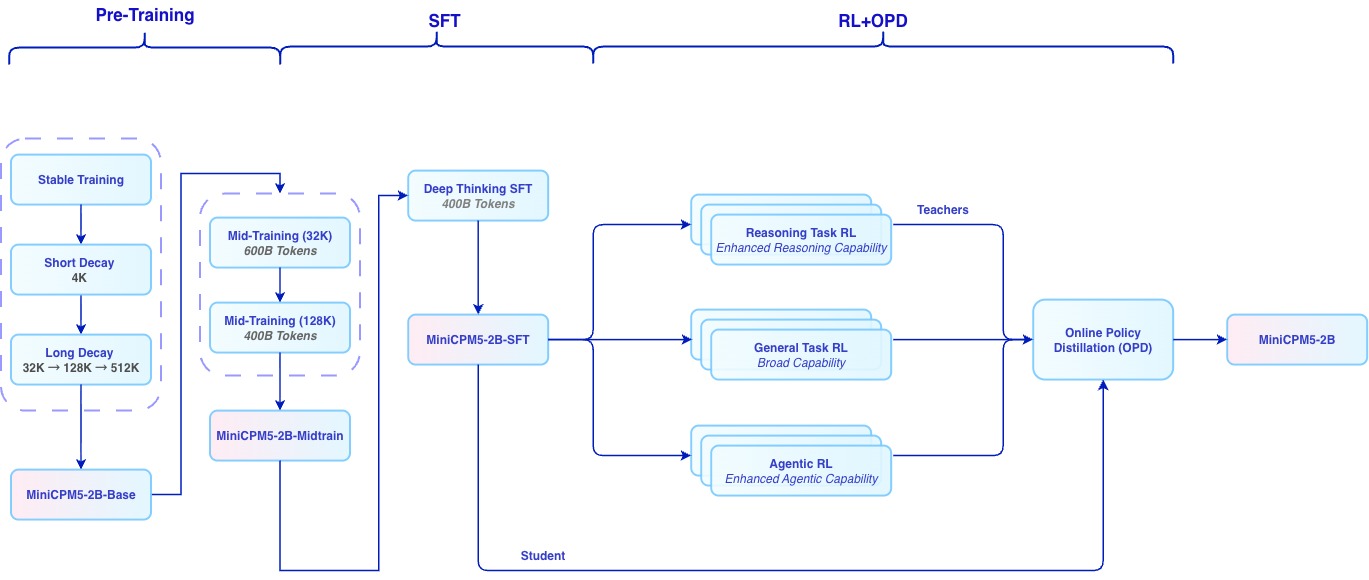
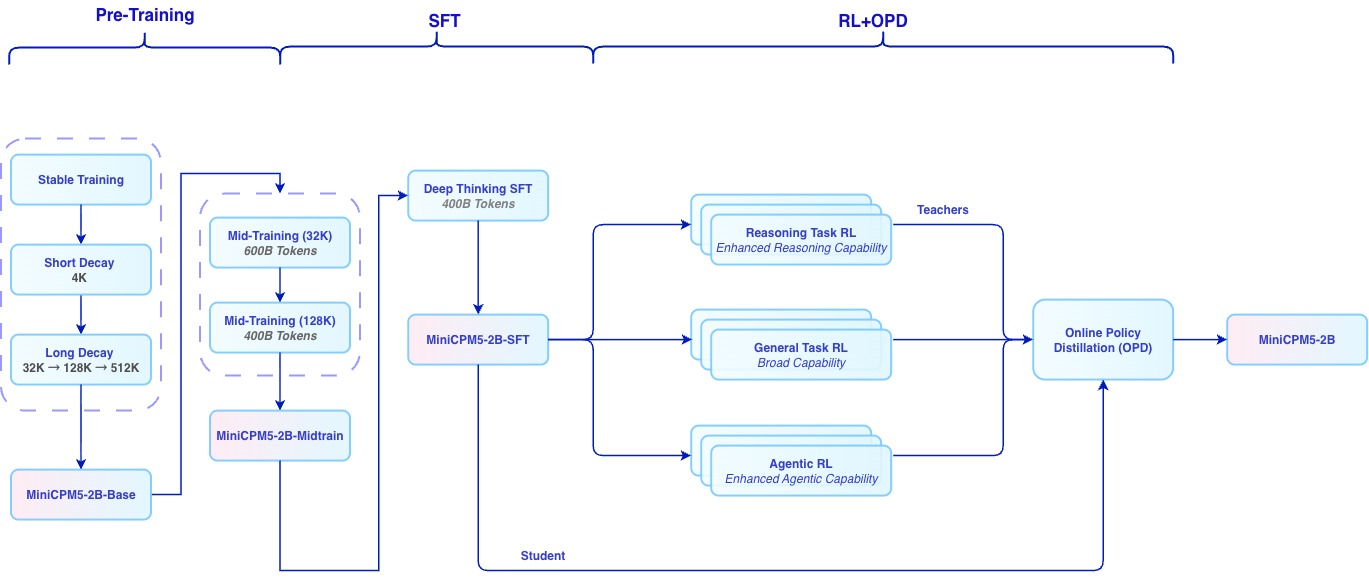
**后训练阶段**分为 **SFT**、**RL** 与 **OPD** 三步。我们先使用 **400B tokens deep-thinking SFT** 建立深度思考和通用对话能力,相关 SFT 数据已同步开源为 [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605)与[UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609)。随后针对数学、代码、Agent 和写作等方向训练专用 **RL teacher**(相关数据已同步开源为[UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)),并通过 **On-Policy Distillation (OPD)** 将这些 teacher 的能力蒸馏回同一个发布模型。
|
| 256 |
|
| 257 |
-
|
| 258 |
-
|
| 259 |
|
| 260 |
|
| 261 |
### RL + OPD 带来了什么?
|
|
@@ -264,8 +262,6 @@ MiniCPM5-2B 的训练过程是 **[UltraData 分级数据管理体系](https://ar
|
|
| 264 |
|
| 265 |
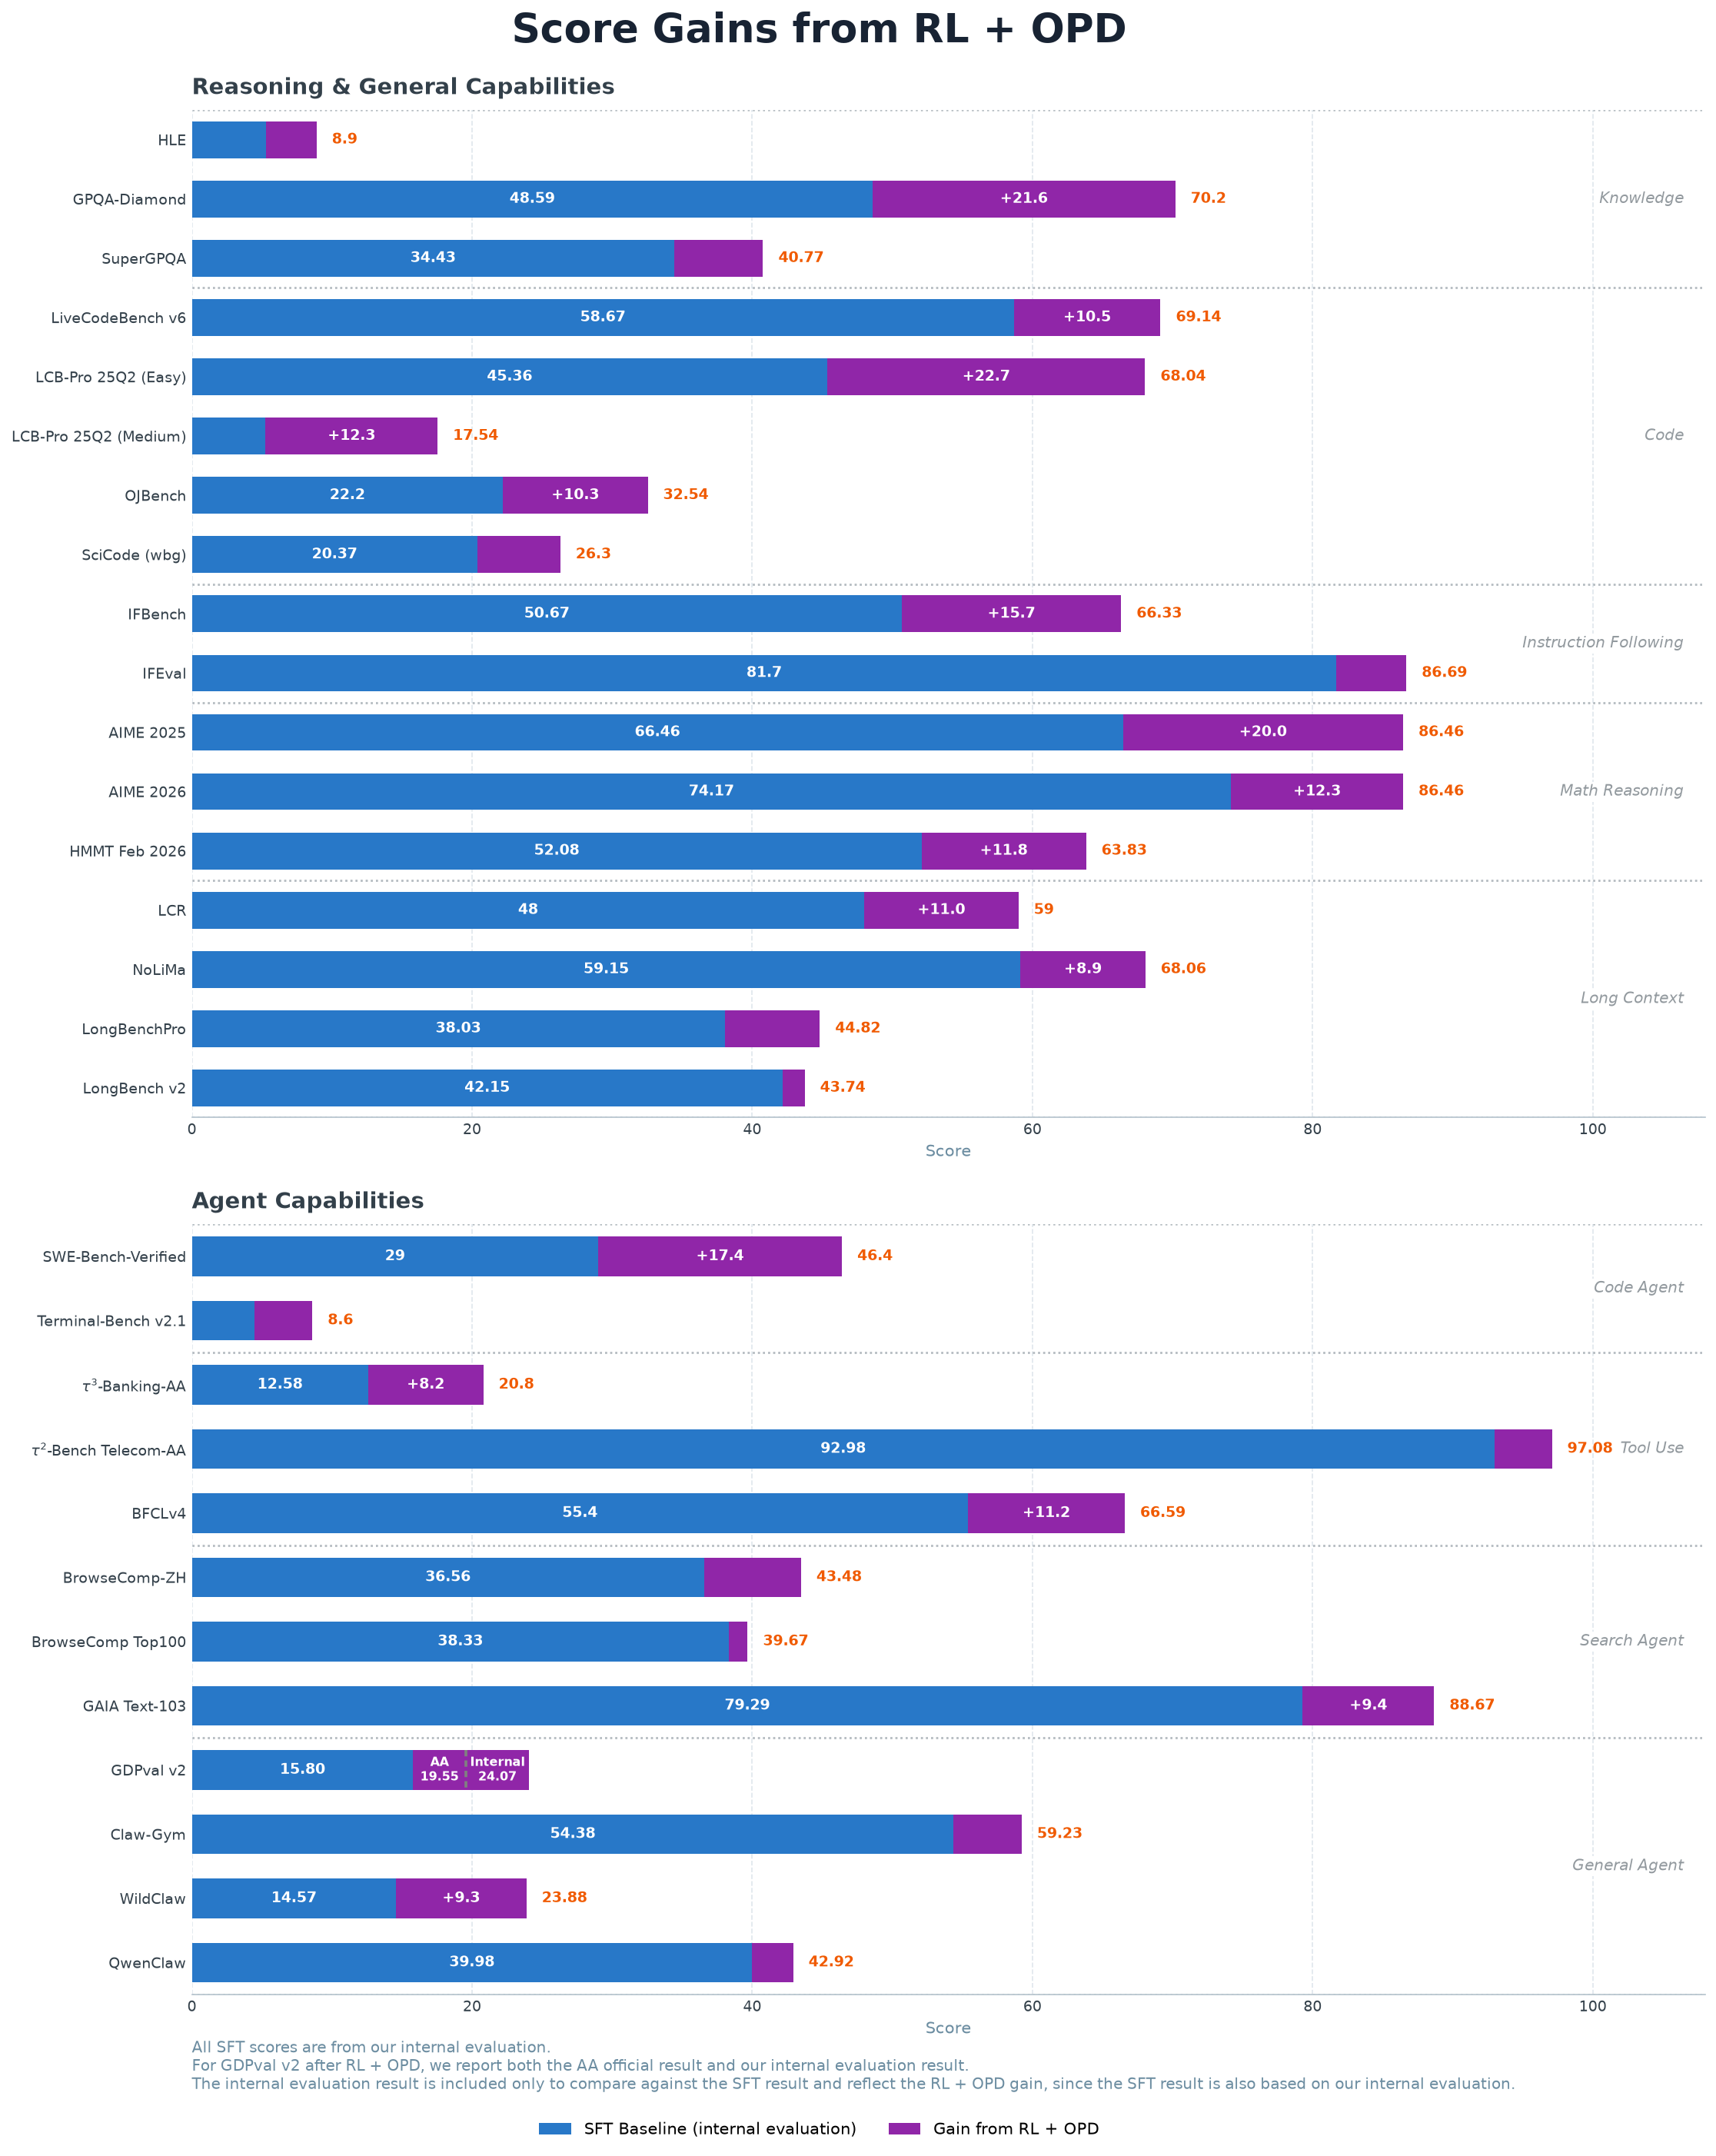
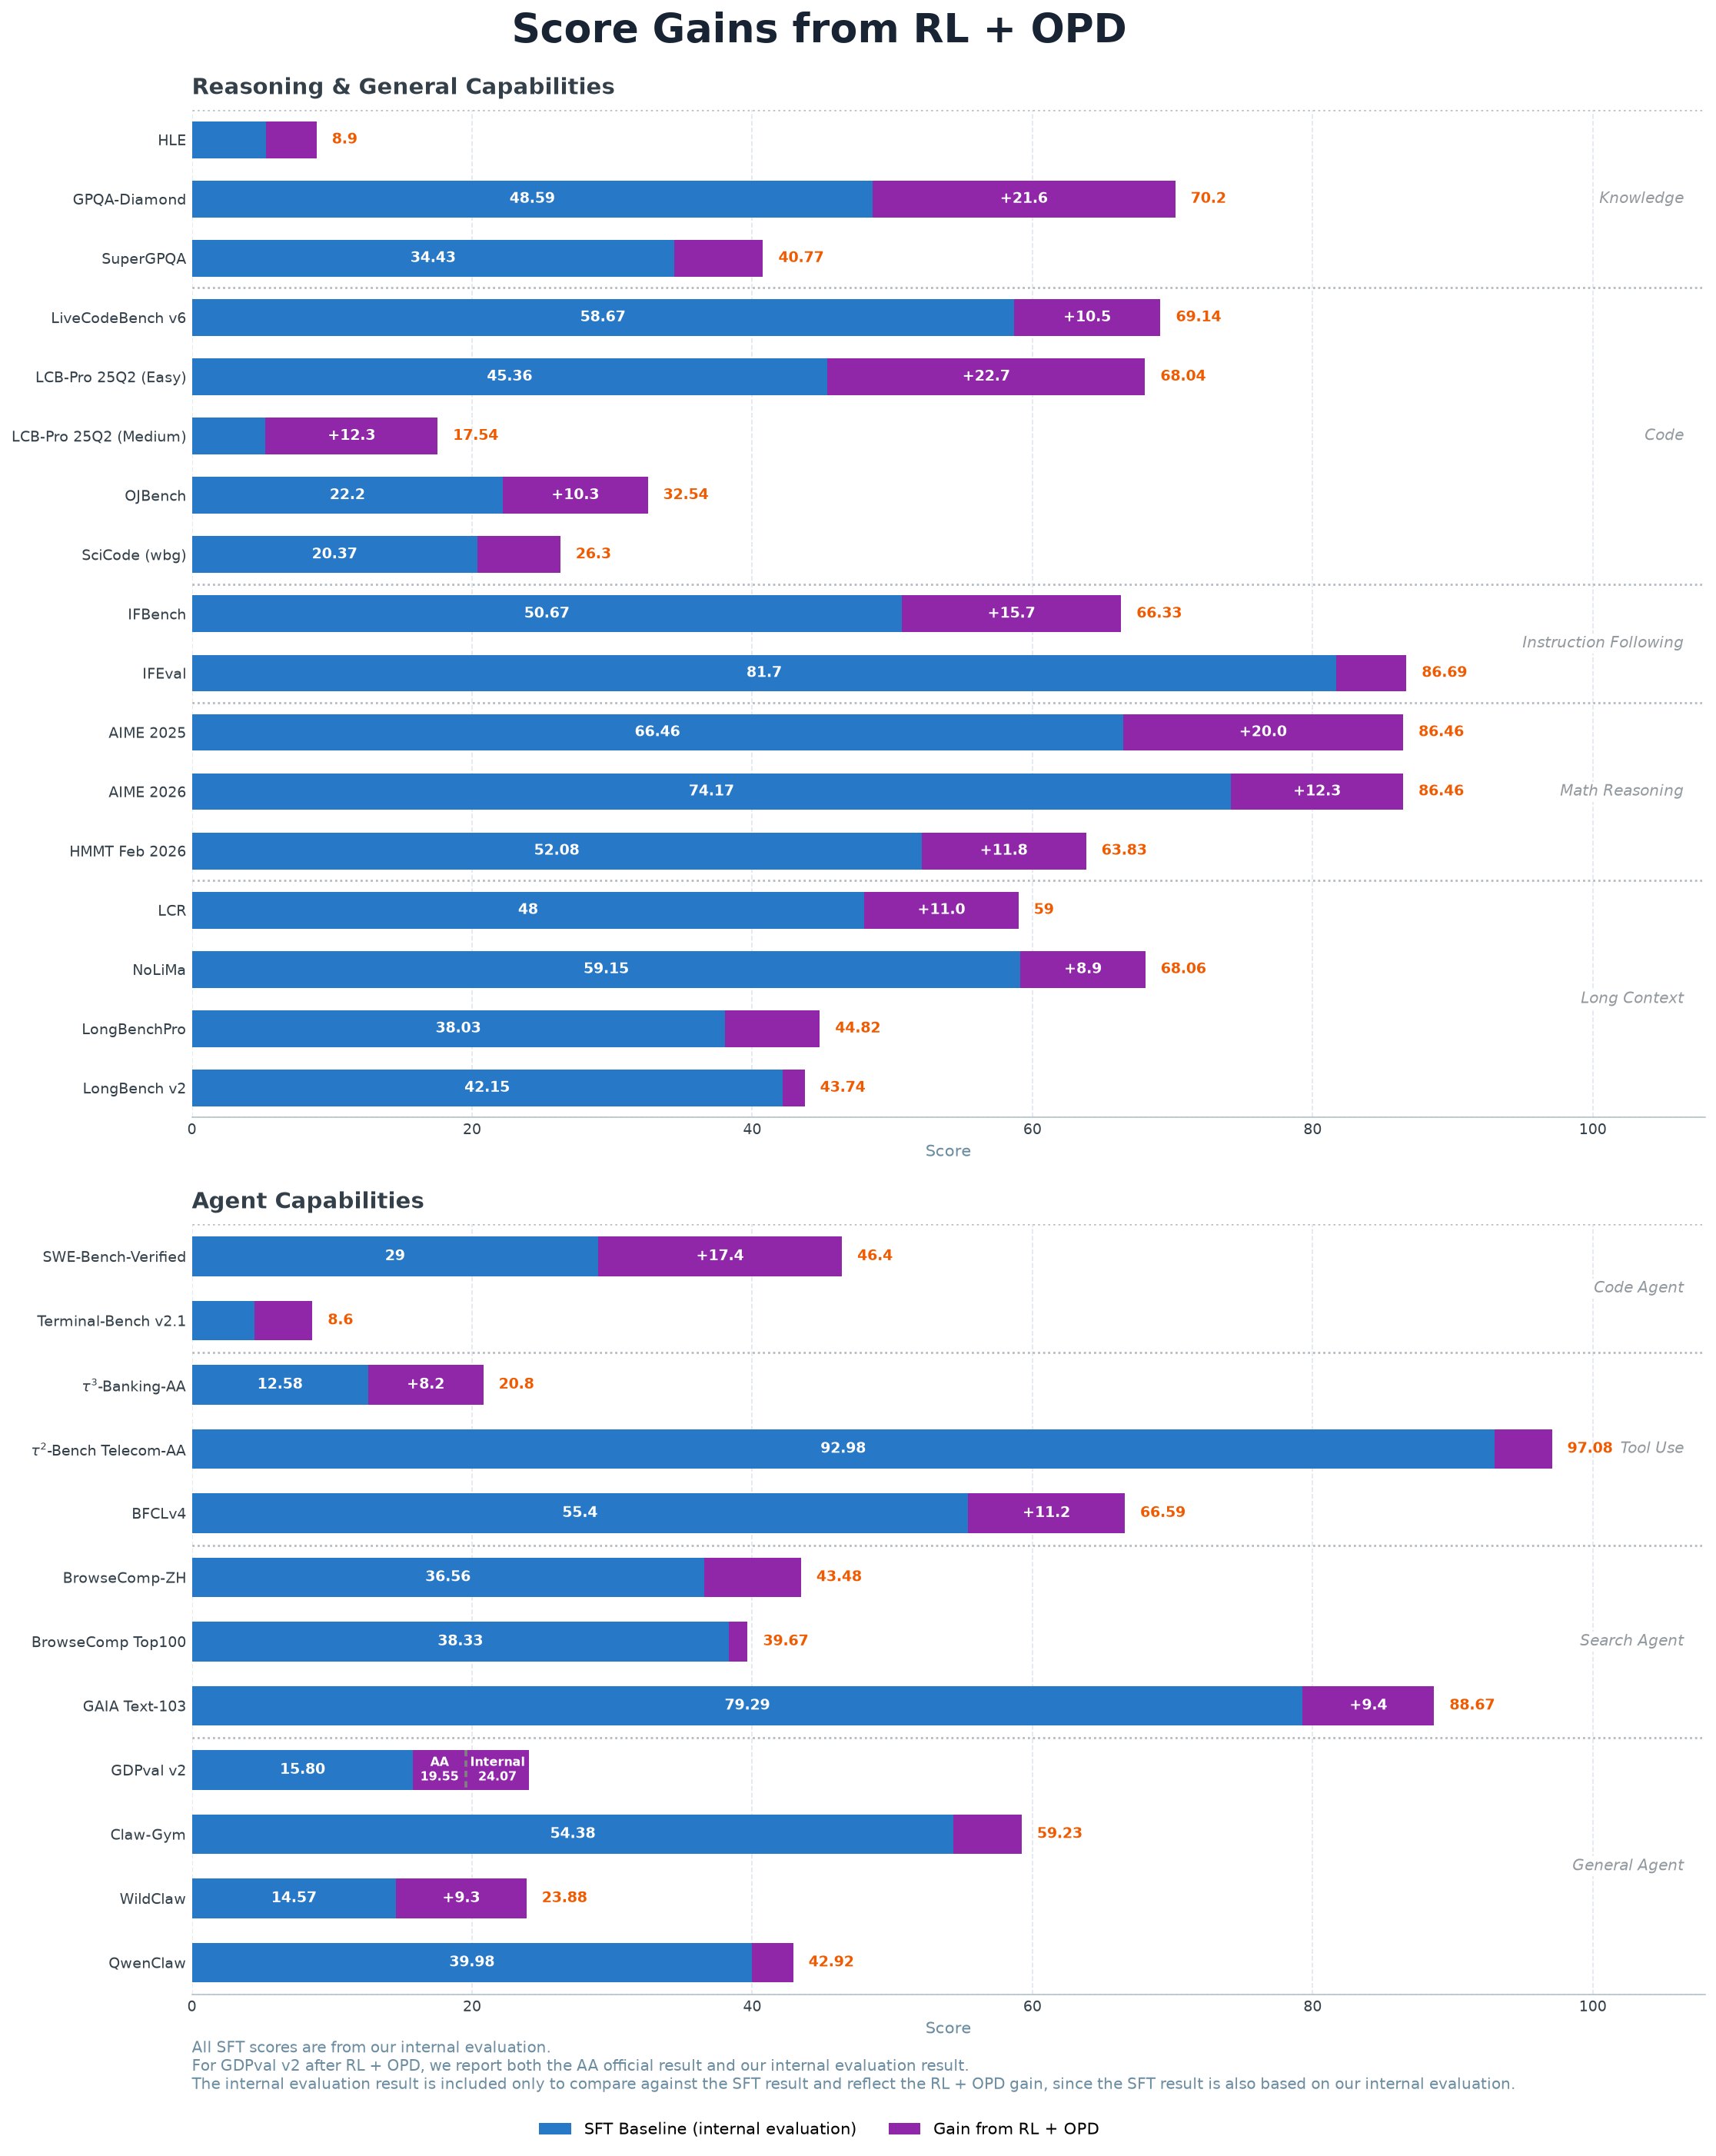
**OPD** 阶段对 16 个 RL 训练所得到的专家模型(含 5 个 agentic 专家模型)实现了能力合并。训练方式上,我们在 response 序列的每个位置分别对学生模型和教师模型 logits 计算全词表的反向 KL 散度作为优势估计值,替代原有的 verification-based advantage;训练数据上,我们的 OPD 直接复用各 RL teacher 训练时 prompt 作为蒸馏数据,无需额外构造语料。
|
| 266 |
|
| 267 |
-
|
| 268 |
-
|
| 269 |
|
| 270 |
|
| 271 |
## 快速上手
|
|
|
|
| 254 |
|
| 255 |
**后训练阶段**分为 **SFT**、**RL** 与 **OPD** 三步。我们先使用 **400B tokens deep-thinking SFT** 建立深度思考和通用对话能力,相关 SFT 数据已同步开源为 [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605)与[UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609)。随后针对数学、代码、Agent 和写作等方向训练专用 **RL teacher**(相关数据已同步开源为[UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)),并通过 **On-Policy Distillation (OPD)** 将这些 teacher 的能力蒸馏回同一个发布模型。
|
| 256 |
|
|
|
|
|
|
|
| 257 |

|
| 258 |
|
| 259 |
### RL + OPD 带来了什么?
|
|
|
|
| 262 |
|
| 263 |
**OPD** 阶段对 16 个 RL 训练所得到的专家模型(含 5 个 agentic 专家模型)实现了能力合并。训练方式上,我们在 response 序列的每个位置分别对学生模型和教师模型 logits 计算全词表的反向 KL 散度作为优势估计值,替代原有的 verification-based advantage;训练数据上,我们的 OPD 直接复用各 RL teacher 训练时 prompt 作为蒸馏数据,无需额外构造语料。
|
| 264 |
|
|
|
|
|
|
|
| 265 |

|
| 266 |
|
| 267 |
## 快速上手
|
README.md
CHANGED
|
@@ -264,8 +264,6 @@ During **base training**, the model goes through stable training and decay train
|
|
| 264 |
|
| 265 |
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605) and the Agent SFT data is released as [UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains (with the corresponding data also open-sourced as [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)), and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
| 266 |
|
| 267 |
-

|
| 268 |
-
|
| 269 |

|
| 270 |
|
| 271 |
### What does RL + OPD bring?
|
|
@@ -274,8 +272,6 @@ During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD*
|
|
| 274 |
|
| 275 |
**OPD** merges the capabilities of 16 expert models produced by RL training, including 5 agentic expert models. At each response position, we compute the full-vocabulary reverse KL divergence between student and teacher logits as the advantage estimate, replacing the original verification-based advantage. OPD directly reuses the prompts used to train each RL teacher as distillation data, so no additional corpus construction is required.
|
| 276 |
|
| 277 |
-

|
| 278 |
-
|
| 279 |

|
| 280 |
|
| 281 |
## Quickstart
|
|
|
|
| 264 |
|
| 265 |
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605) and the Agent SFT data is released as [UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains (with the corresponding data also open-sourced as [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)), and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
| 266 |
|
|
|
|
|
|
|
| 267 |

|
| 268 |
|
| 269 |
### What does RL + OPD bring?
|
|
|
|
| 272 |
|
| 273 |
**OPD** merges the capabilities of 16 expert models produced by RL training, including 5 agentic expert models. At each response position, we compute the full-vocabulary reverse KL divergence between student and teacher logits as the advantage estimate, replacing the original verification-based advantage. OPD directly reuses the prompts used to train each RL teacher as distillation data, so no additional corpus construction is required.
|
| 274 |
|
|
|
|
|
|
|
| 275 |

|
| 276 |
|
| 277 |
## Quickstart
|