

update README
Browse files
README.md
CHANGED
|
@@ -155,7 +155,7 @@ We are releasing **MiniCPM5-2B**, the second model in the **MiniCPM5** series, f
|
|
| 155 |
</svg>
|
| 156 |
</div>
|
| 157 |
|
| 158 |
-
📂 **Open High-Quality Data**: Alongside the model, we are releasing the high-quality training datasets behind it as part of the [UltraData](https://ultradata.openbmb.cn/) family: [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), a high-quality web pre-training dataset; [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code), featuring L0–L3 tiered code data
|
| 159 |
|
| 160 |
|
| 161 |
## Model List
|
|
@@ -263,7 +263,7 @@ The training of MiniCPM5-2B is a full-stack practice of **[UltraData Tiered Data
|
|
| 263 |
|
| 264 |
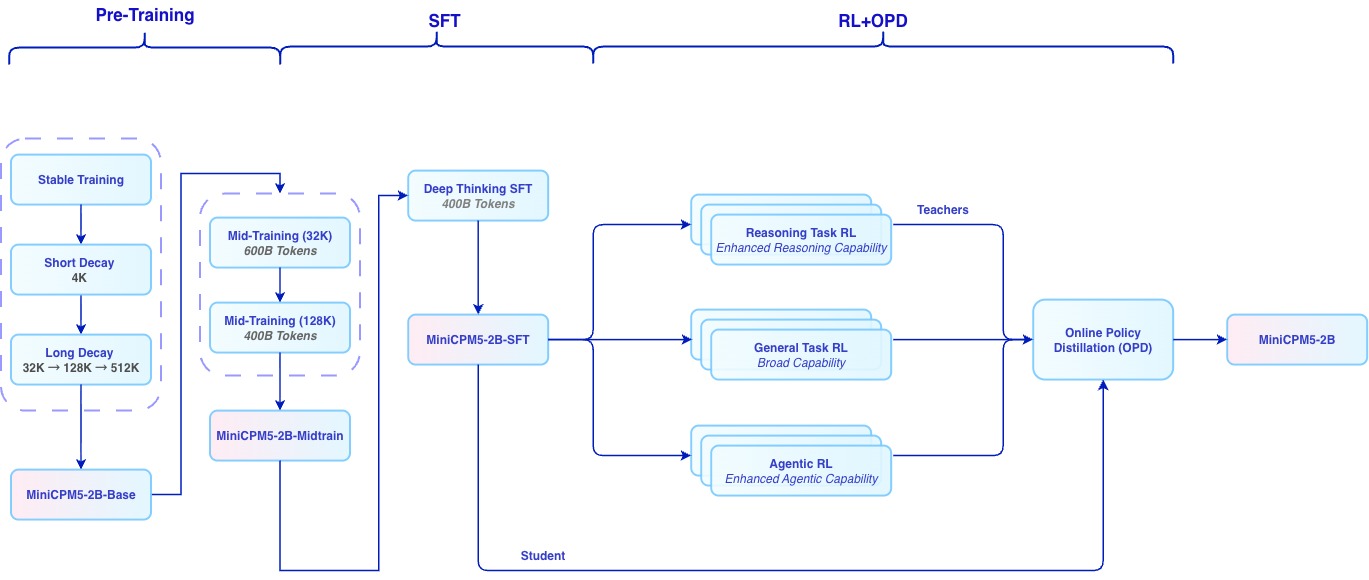
During **base training**, the model goes through stable training and decay training to build core language capability and training stability. It then enters **mid-training** to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb), [Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3), [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code) and [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math).
|
| 265 |
|
| 266 |
-
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains(with the corresponding data also open-sourced as [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)), and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
| 267 |
|
| 268 |
|
| 269 |
|
|
|
|
| 155 |
</svg>
|
| 156 |
</div>
|
| 157 |
|
| 158 |
+
📂 **Open High-Quality Data**: Alongside the model, we are releasing the high-quality training datasets behind it as part of the [UltraData](https://ultradata.openbmb.cn/) family: [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), a high-quality web pre-training dataset; [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code), featuring L0–L3 tiered code data management to drive a significant leap in coding capabilities; [UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609), comprising 500K agent training samples to enhance comprehensive on-device agent capabilities; and [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609), with 80K+ high-quality RL training samples covering mathematics, code, general knowledge, and long-context reasoning.
|
| 159 |
|
| 160 |
|
| 161 |
## Model List
|
|
|
|
| 263 |
|
| 264 |
During **base training**, the model goes through stable training and decay training to build core language capability and training stability. It then enters **mid-training** to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb), [Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3), [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code) and [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math).
|
| 265 |
|
| 266 |
+
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605) and the Agent SFT data is released as [UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains (with the corresponding data also open-sourced as [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)), and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
| 267 |
|
| 268 |

|
| 269 |
|