

zzh commited on
Commit ·
d312cb6
1
Parent(s): 85dfd5e
docs: update training data and SGLang details
Browse files- README-cn.md +2 -2
- README.md +2 -2
README-cn.md
CHANGED
|
@@ -254,9 +254,9 @@ font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,'PingFang SC',
|
|
| 254 |
|
| 255 |
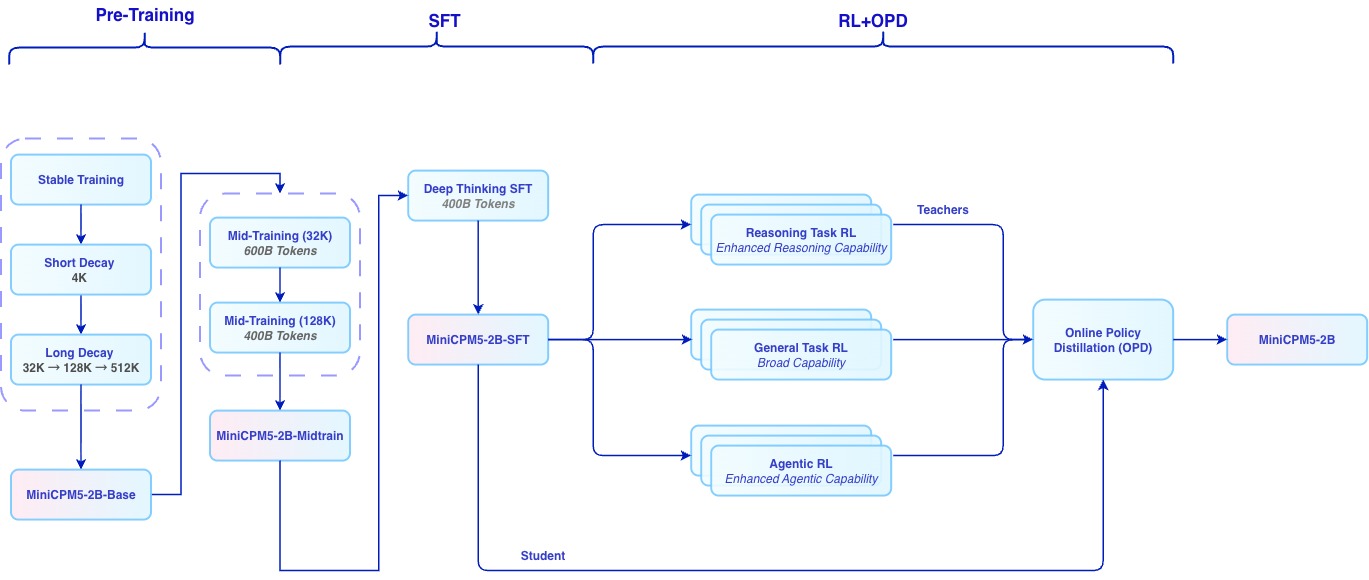
MiniCPM5-2B 的训练过程是 **[UltraData 分级数据管理体系](https://arxiv.org/pdf/2602.09003)** 的一次完整实践,覆盖 base training、mid-training 与后训练三个阶段。
|
| 256 |
|
| 257 |
-
**Base training** 采用逐级推进的训练配方,包含 stable training 与 decay training,用于建立基础语言能力与训练稳定性。随后进入 **mid-training**,进一步强化目标能力并适配数据分布。训练语料来自我们同步开源的 [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb)、[Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3) 与 [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math)。
|
| 258 |
|
| 259 |
-
**后训练阶段**分为 **SFT**、**RL** 与 **OPD** 三步。我们先使用 **400B tokens deep-thinking SFT** 建立深度思考和通用对话能力,相关 SFT 数据已同步开源为 [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605)。随后针对数学、代码、Agent 和写作等方向训练专用 **RL teacher**,并通过 **On-Policy Distillation (OPD)** 将这些 teacher 的能力蒸馏回同一个发布模型。
|
| 260 |
|
| 261 |
|
| 262 |
|
|
|
|
| 254 |
|
| 255 |
MiniCPM5-2B 的训练过程是 **[UltraData 分级数据管理体系](https://arxiv.org/pdf/2602.09003)** 的一次完整实践,覆盖 base training、mid-training 与后训练三个阶段。
|
| 256 |
|
| 257 |
+
**Base training** 采用逐级推进的训练配方,包含 stable training 与 decay training,用于建立基础语言能力与训练稳定性。随后进入 **mid-training**,进一步强化目标能力并适配数据分布。训练语料来自我们同步开源的 [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb)、[Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3)、[UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview)、[UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code) 与 [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math)。
|
| 258 |
|
| 259 |
+
**后训练阶段**分为 **SFT**、**RL** 与 **OPD** 三步。我们先使用 **400B tokens deep-thinking SFT** 建立深度思考和通用对话能力,相关 SFT 数据已同步开源为 [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605)与[UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609)。随后针对数学、代码、Agent 和写作等方向训练专用 **RL teacher**(相关数据已同步开源为[UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)),并通过 **On-Policy Distillation (OPD)** 将这些 teacher 的能力蒸馏回同一个发布模型。
|
| 260 |
|
| 261 |

|
| 262 |
|
README.md
CHANGED
|
@@ -261,9 +261,9 @@ font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,'PingFang SC',
|
|
| 261 |
|
| 262 |
The training of MiniCPM5-2B is a full-stack practice of **[UltraData Tiered Data Management](https://arxiv.org/pdf/2602.09003)**, covering three stages: base training, mid-training, and post-training.
|
| 263 |
|
| 264 |
-
During **base training**, the model goes through stable training and decay training to build core language capability and training stability. It then enters **mid-training** to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb), [Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3), and [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math).
|
| 265 |
|
| 266 |
-
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains, and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
| 267 |
|
| 268 |

|
| 269 |
|
|
|
|
| 261 |
|
| 262 |
The training of MiniCPM5-2B is a full-stack practice of **[UltraData Tiered Data Management](https://arxiv.org/pdf/2602.09003)**, covering three stages: base training, mid-training, and post-training.
|
| 263 |
|
| 264 |
+
During **base training**, the model goes through stable training and decay training to build core language capability and training stability. It then enters **mid-training** to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb), [Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3), [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code) and [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math).
|
| 265 |
|
| 266 |
+
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains(with the corresponding data also open-sourced as [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)), and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
| 267 |
|
| 268 |

|
| 269 |
|