

Songgot (송곳)
A Korean-first tiny agentic model for tool calling on the device, trained from scratch by Hanish Keloth (Palette). Apache 2.0.
- Paper: https://hanishkeloth.github.io/songgot
- Code, data generators, scorer: https://github.com/hanishkeloth/songgot
- Demo: https://huggingface.co/spaces/Hanish/songgot
Try it on the device: https://hanishkeloth.github.io/songgot/app/ (runs in the browser, works offline after the first load).
Numbers
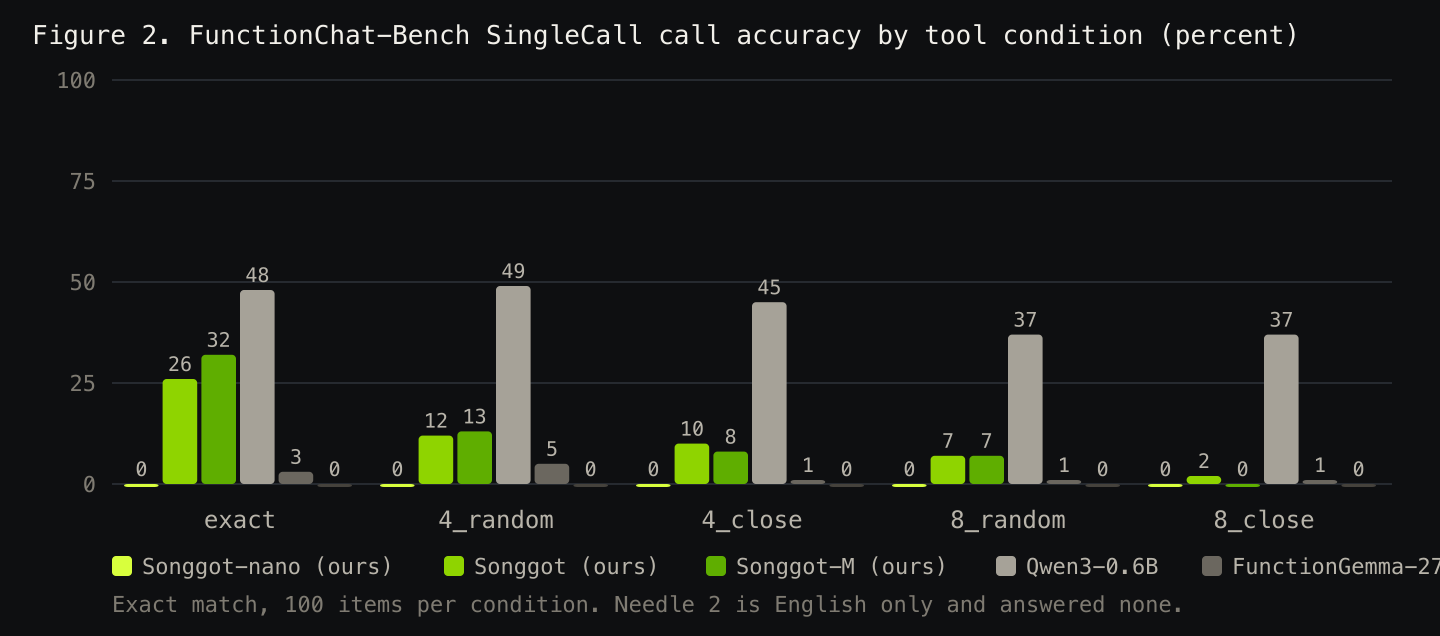
Kakao FunctionChat-Bench SingleCall (500 Korean items, 5 tool conditions), exact match on function name and arguments, scorer in the repo. Comparators run with identical tools and queries in their own documented formats.
| model | params | exact | 4_random | 4_close | 8_random | 8_close | all | name only |
|---|---|---|---|---|---|---|---|---|
| Songgot-L (12B tokens with instruction bucket, 2 epochs, v8 set) | 303M | 40.0 | 36.0 | 21.0 | 30.0 | 20.0 | 29.4 | 75.0 |
| Songgot-M (2 epochs, v8 set) | 126M | 45.0 | 43.0 | 26.0 | 34.0 | 18.0 | 33.2 | 73.8 |
| Songgot (6B tokens, 3 epochs, v8 set) | 50M | 44.0 | 39.0 | 30.0 | 35.0 | 17.0 | 33.0 | 73.6 |
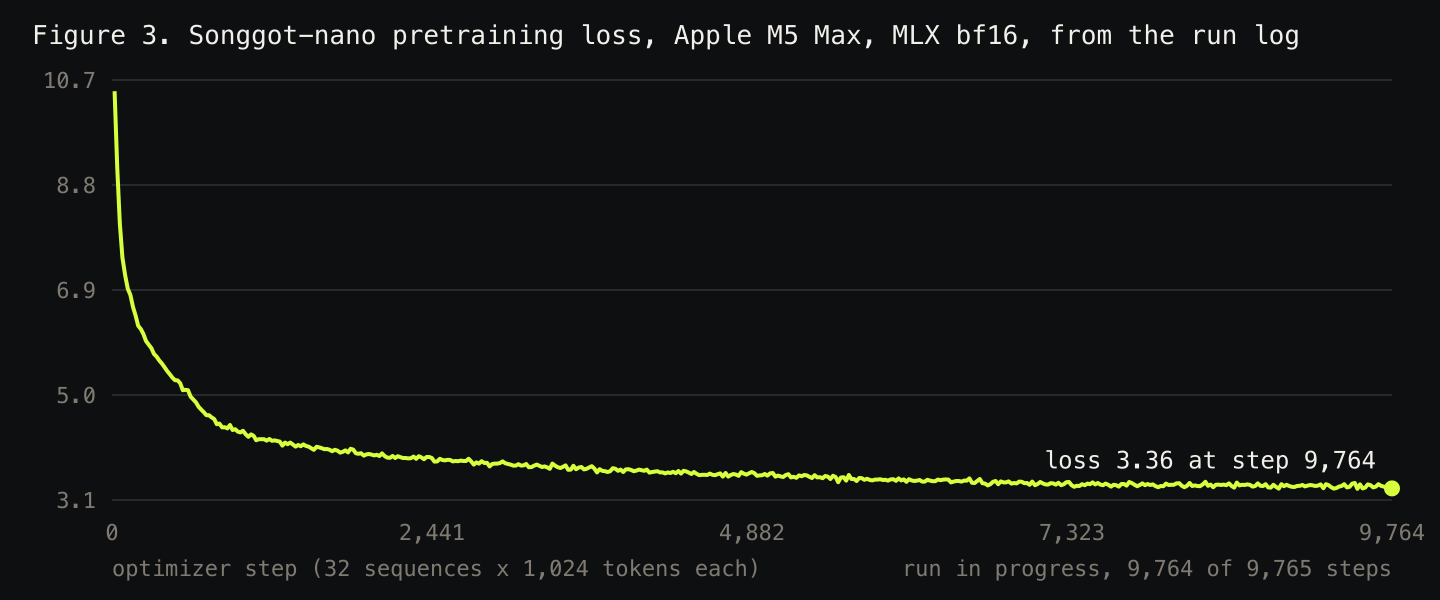
| Songgot-nano (1 epoch) | 39M | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| Needle 2 | 45M | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 |
| FunctionGemma-270M | 270M | 3.0 | 5.0 | 1.0 | 1.0 | 1.0 | 2.2 | 36.2 |
| Qwen3-0.6B | 600M | 48.0 | 49.0 | 45.0 | 37.0 | 37.0 | 43.2 | 70.8 |
| Qwen3.5-0.8B | 800M | 51.0 | 48.0 | 41.0 | 52.0 | 34.0 | 45.2 | 73.6 |
| Kanana-2-1.3B-Instruct (Kakao) | 1.3B | 76.0 | 72.0 | 70.0 | 71.0 | 63.0 | 70.4 | 93.8 |
| EXAONE-4.0-1.2B (LG) | 1.28B | 73.0 | 65.0 | 53.0 | 66.0 | 58.0 | 63.0 | 85.2 |
| DNA3.0-0.8B (Dnotitia) | 0.8B | 0.0 | 8.0 | 6.0 | 6.0 | 4.0 | 4.8 | 12.2 |
| HyperCLOVA X SEED 0.5B (Naver) | 0.57B | no tool-calling interface in its chat template |
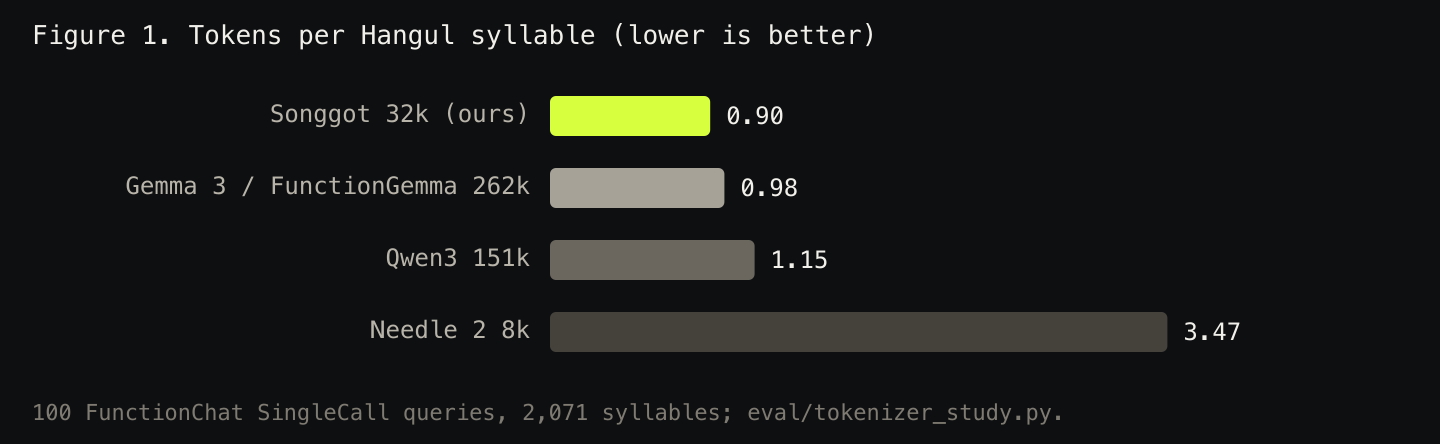
Tokens per Hangul syllable on the same 100 queries: Songgot 0.90, Gemma 3 0.98, Qwen3 1.15, Needle 2 3.47.
Status (2026-09-13 09:33)
Weights in this repo are Songgot-L, 12B tokens with instruction bucket, 2 epochs, v8 set: 24 layers, hidden 1024, about 303M parameters, trained from scratch on 8xH100 (Modal) on 12B tokens of Korean Wikipedia and fineweb-edu with 5 percent tool-calling rows in the mix, post-trained on the v8 set, post-trained on the v2 tool-calling set. Call accuracy on FunctionChat-Bench SingleCall 29.4 percent (name only 75.0). GGUF exports (f16, Q8_0, Q4_K_M) are in this repo.
Format
<|system|>
[{"name": "set_alarm", "description": "알람을 설정합니다.", "parameters": {...}}]
<|user|>
내일 아침 7시에 알람 맞춰줘
<|call|>
{"name":"set_alarm","arguments":{"time":"07:00"}}<|end|>
Tokenizer: SentencePiece BPE, 32k, byte fallback (tokenizer.model). Use sentencepiece directly; the special tokens live inside the vocabulary.
Data and provenance
fineweb-edu sample-10BT (ODC-By), Korean Wikipedia 20231101.ko (CC BY-SA 3.0; this model card carries the attribution and share-alike notice for that text), glaive-function-calling-v2 (Apache 2.0), template-generated Korean tool calls (Apache 2.0, in the repo). No closed-model outputs. FunctionChat-Bench was never used for training.
Limits
Single-call tool selection and argument extraction only. No multi-turn, no tool results, no free chat. Small models are finicky with rare tools and paraphrased values; validate every call in application code.
- Downloads last month
- 948