


weights: exact MXFP4 -> NVFP4 transcode of XiaomiMiMo/MiMo-V2.6-Flash-RL experts
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +4 -0
- MiMo_V2_6_technical_report.pdf +3 -0
- assets/architecture.png +3 -0
- audio_tokenizer/chat_template.jinja +120 -0
- audio_tokenizer/config.json +68 -0
- audio_tokenizer/generation_config.json +9 -0
- audio_tokenizer/model.safetensors +3 -0
- audio_tokenizer/tokenizer_config.json +267 -0
- chat_template.jinja +96 -0
- config.json +0 -0
- configuration_mimo_v2.py +247 -0
- dflash/config.json +56 -0
- dflash/dflash.py +379 -0
- dflash/dflash_draft_model.safetensors +3 -0
- dflash/mask_embedding.pt +3 -0
- dflash/model.safetensors.index.json +70 -0
- generation_config.json +9 -0
- merges.txt +0 -0
- model.safetensors.index.json +3 -0
- model_mtp.safetensors +3 -0
- model_pp0_ep0_shard0.safetensors +3 -0
- model_pp0_ep10_shard0.safetensors +3 -0
- model_pp0_ep11_shard0.safetensors +3 -0
- model_pp0_ep12_shard0.safetensors +3 -0
- model_pp0_ep13_shard0.safetensors +3 -0
- model_pp0_ep14_shard0.safetensors +3 -0
- model_pp0_ep15_shard0.safetensors +3 -0
- model_pp0_ep16_shard0.safetensors +3 -0
- model_pp0_ep17_shard0.safetensors +3 -0
- model_pp0_ep18_shard0.safetensors +3 -0
- model_pp0_ep19_shard0.safetensors +3 -0
- model_pp0_ep1_shard0.safetensors +3 -0
- model_pp0_ep20_shard0.safetensors +3 -0
- model_pp0_ep21_shard0.safetensors +3 -0
- model_pp0_ep22_shard0.safetensors +3 -0
- model_pp0_ep23_shard0.safetensors +3 -0
- model_pp0_ep24_shard0.safetensors +3 -0
- model_pp0_ep25_shard0.safetensors +3 -0
- model_pp0_ep26_shard0.safetensors +3 -0
- model_pp0_ep27_shard0.safetensors +3 -0
- model_pp0_ep28_shard0.safetensors +3 -0
- model_pp0_ep29_shard0.safetensors +3 -0
- model_pp0_ep2_shard0.safetensors +3 -0
- model_pp0_ep30_shard0.safetensors +3 -0
- model_pp0_ep31_shard0.safetensors +3 -0
- model_pp0_ep32_shard0.safetensors +3 -0
- model_pp0_ep33_shard0.safetensors +3 -0
- model_pp0_ep34_shard0.safetensors +3 -0
- model_pp0_ep35_shard0.safetensors +3 -0
- model_pp0_ep36_shard0.safetensors +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,7 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
MiMo_V2_6_technical_report.pdf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
assets/architecture.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
model.safetensors.index.json filter=lfs diff=lfs merge=lfs -text
|
MiMo_V2_6_technical_report.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fb81e6e083801b3358f084ed6be953dc23b0d2e434690f4541d5eae03e01e7af
|
| 3 |
+
size 3046687
|
assets/architecture.png
ADDED
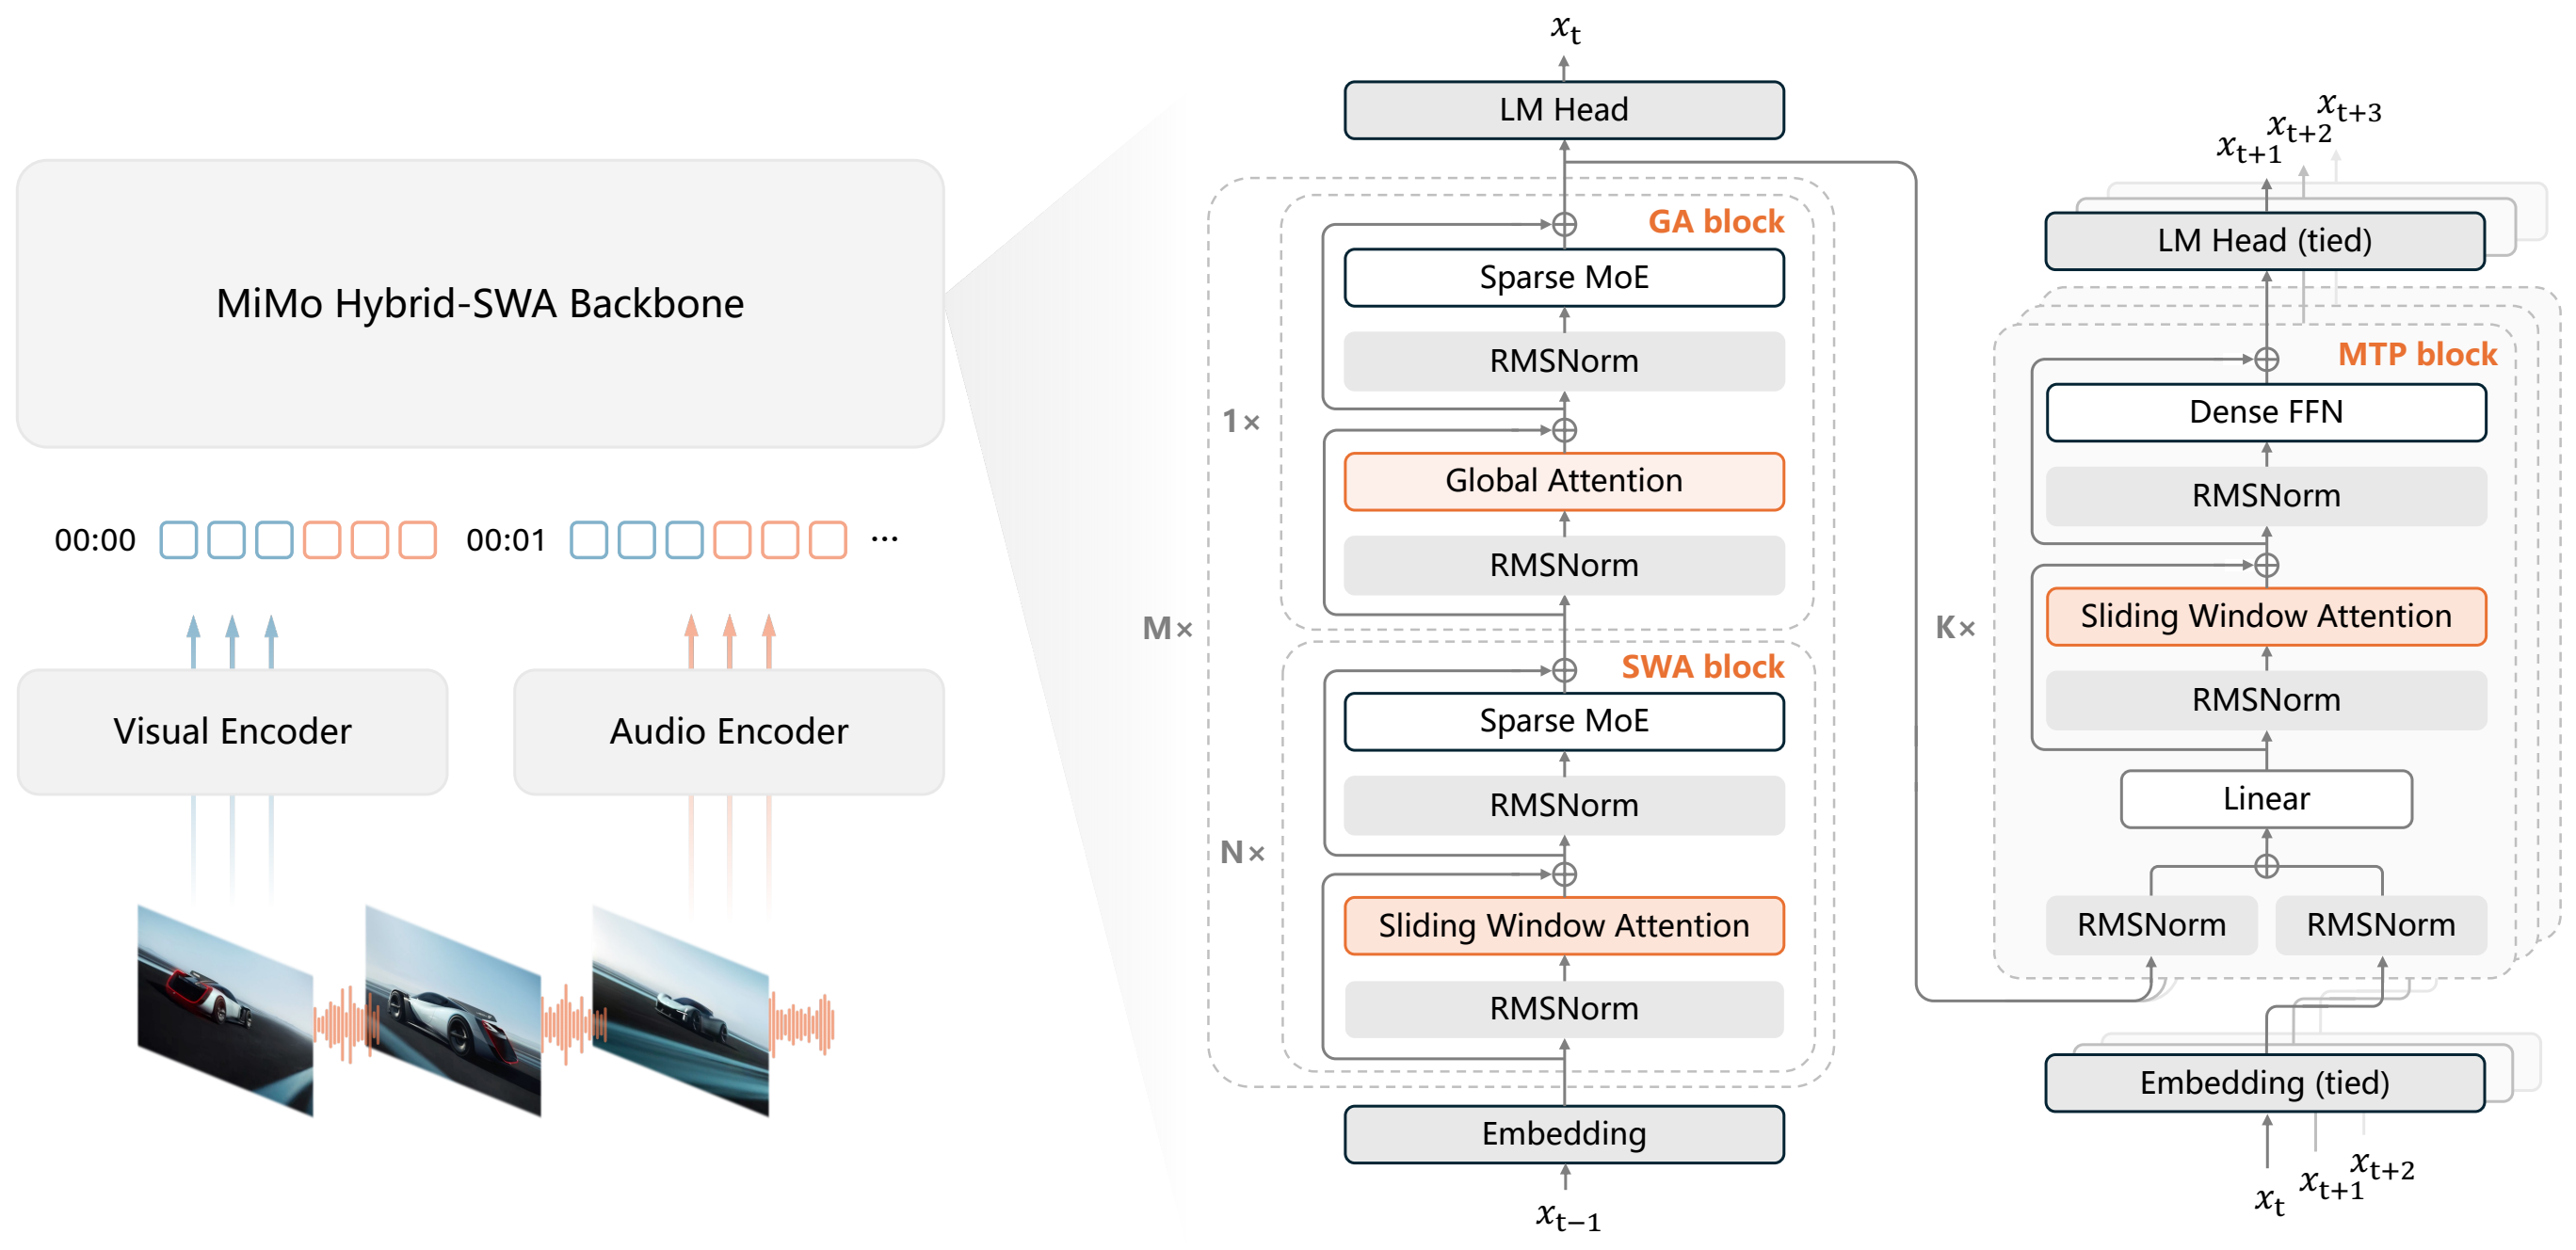
|
Git LFS Details
|
audio_tokenizer/chat_template.jinja
ADDED
|
@@ -0,0 +1,120 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- if tools %}
|
| 2 |
+
{{- '<|im_start|>system\n' }}
|
| 3 |
+
{%- if messages[0].role == 'system' %}
|
| 4 |
+
{%- if messages[0].content is string %}
|
| 5 |
+
{{- messages[0].content }}
|
| 6 |
+
{%- else %}
|
| 7 |
+
{%- for content in messages[0].content %}
|
| 8 |
+
{%- if content.type == 'audio' %}
|
| 9 |
+
{{- ("<|sosp|>" + (content.meta | tojson) + "<|eosp|>") }}
|
| 10 |
+
{%- elif content.type == 'text' %}
|
| 11 |
+
{{- content.text }}
|
| 12 |
+
{%- endif %}
|
| 13 |
+
{%- endfor %}
|
| 14 |
+
{%- endif %}
|
| 15 |
+
{%- endif %}
|
| 16 |
+
{{- '\n\n' }}
|
| 17 |
+
{{- "# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
| 18 |
+
{%- for tool in tools %}
|
| 19 |
+
{{- "\n" }}
|
| 20 |
+
{{- tool | tojson }}
|
| 21 |
+
{%- endfor %}
|
| 22 |
+
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
| 23 |
+
{%- else %}
|
| 24 |
+
{%- if messages[0].role == 'system' %}
|
| 25 |
+
{{- '<|im_start|>system\n' }}
|
| 26 |
+
{%- if messages[0].content is string %}
|
| 27 |
+
{{- messages[0].content }}
|
| 28 |
+
{%- else %}
|
| 29 |
+
{%- for content in messages[0].content %}
|
| 30 |
+
{%- if content.type == 'audio' %}
|
| 31 |
+
{{- ("<|sosp|>" + (content.meta | tojson) + "<|eosp|>") }}
|
| 32 |
+
{%- elif content.type == 'text' %}
|
| 33 |
+
{{- content.text }}
|
| 34 |
+
{%- endif %}
|
| 35 |
+
{%- endfor %}
|
| 36 |
+
{%- endif %}
|
| 37 |
+
{{- '\n<|im_end|>\n' }}
|
| 38 |
+
{%- endif %}
|
| 39 |
+
{%- endif %}
|
| 40 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1, assistant_is_last=false) %}
|
| 41 |
+
{%- for message in messages[::-1] %}
|
| 42 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 43 |
+
{%- if ns.multi_step_tool and message.role == "user" and message.content is string and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}
|
| 44 |
+
{%- set ns.multi_step_tool = false %}
|
| 45 |
+
{%- set ns.last_query_index = index %}
|
| 46 |
+
{%- endif %}
|
| 47 |
+
{%- endfor %}
|
| 48 |
+
{%- for message in messages %}
|
| 49 |
+
{%- if message.content is string %}
|
| 50 |
+
{%- set content = message.content %}
|
| 51 |
+
{%- else %}
|
| 52 |
+
{%- set content = namespace(text="") %}
|
| 53 |
+
{%- for mcontent in message.content %}
|
| 54 |
+
{%- if mcontent.type == 'audio' %}
|
| 55 |
+
{%- set content.text = content.text~("<|sosp|>" + (mcontent.meta | tojson) + "<|eosp|>") %}
|
| 56 |
+
{%- elif mcontent.type == 'text' %}
|
| 57 |
+
{%- set content.text = content.text~mcontent.text %}
|
| 58 |
+
{%- endif %}
|
| 59 |
+
{%- endfor %}
|
| 60 |
+
{%- set content = content.text %}
|
| 61 |
+
{%- endif %}
|
| 62 |
+
{%- if (message.role == "user") or (message.role == "system" and not loop.first) %}
|
| 63 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 64 |
+
{%- elif message.role == "assistant" %}
|
| 65 |
+
{%- set reasoning_content = "" %}
|
| 66 |
+
{%- if message.reasoning_content is string %}
|
| 67 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 68 |
+
{%- else %}
|
| 69 |
+
{%- if '</think>' in content %}
|
| 70 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 71 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 72 |
+
{%- endif %}
|
| 73 |
+
{%- endif %}
|
| 74 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 75 |
+
{%- if loop.last or (not loop.last and reasoning_content) %}
|
| 76 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content.strip("\n") + '\n</think>\n\n' + content.lstrip('\n') }}
|
| 77 |
+
{%- else %}
|
| 78 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 79 |
+
{%- endif %}
|
| 80 |
+
{%- else %}
|
| 81 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 82 |
+
{%- endif %}
|
| 83 |
+
{%- if message.tool_calls %}
|
| 84 |
+
{%- for tool_call in message.tool_calls %}
|
| 85 |
+
{%- if (loop.first and content) or (not loop.first) %}{{- '\n' }}{%- endif %}
|
| 86 |
+
{%- if tool_call.function %}
|
| 87 |
+
{%- set tool_call = tool_call.function %}
|
| 88 |
+
{%- endif %}
|
| 89 |
+
{{- '<tool_call>\n{"name": "' }}
|
| 90 |
+
{{- tool_call.name }}
|
| 91 |
+
{{- '", "arguments": ' }}
|
| 92 |
+
{%- if tool_call.arguments is string %}
|
| 93 |
+
{{- tool_call.arguments }}
|
| 94 |
+
{%- else %}
|
| 95 |
+
{{- tool_call.arguments | tojson }}
|
| 96 |
+
{%- endif %}
|
| 97 |
+
{{- '}\n</tool_call>' }}
|
| 98 |
+
{%- endfor %}
|
| 99 |
+
{%- endif %}
|
| 100 |
+
{%- if loop.last %}
|
| 101 |
+
{%- set ns.assistant_is_last = true %}
|
| 102 |
+
{%- else %}
|
| 103 |
+
{{- '<|im_end|>\n' }}
|
| 104 |
+
{%- endif %}
|
| 105 |
+
{%- elif message.role == "tool" %}
|
| 106 |
+
{%- if loop.first or (messages[loop.index0 - 1].role != "tool") %}{{- '<|im_start|>user' }}{%- endif %}
|
| 107 |
+
{{- '\n<tool_response>\n' }}
|
| 108 |
+
{{- content }}
|
| 109 |
+
{{- '\n</tool_response>' }}
|
| 110 |
+
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}{{- '<|im_end|>\n' }}{%- endif %}
|
| 111 |
+
{%- endif %}
|
| 112 |
+
{%- endfor %}
|
| 113 |
+
{%- if add_generation_prompt and not ns.assistant_is_last %}
|
| 114 |
+
{{- '<|im_start|>assistant\n' }}
|
| 115 |
+
{%- if audio_output %}
|
| 116 |
+
{{- '<|sostm|>'}}
|
| 117 |
+
{%- elif not enable_thinking %}
|
| 118 |
+
{{- '<think>\n\n</think>\n' }}
|
| 119 |
+
{%- endif %}
|
| 120 |
+
{%- endif %}
|
audio_tokenizer/config.json
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"max_audio_seconds": 300,
|
| 3 |
+
"stride_size": 2,
|
| 4 |
+
"avg_pooler": 2,
|
| 5 |
+
"d_model": 1024,
|
| 6 |
+
"scale_embedding": false,
|
| 7 |
+
"kernel_size": 3,
|
| 8 |
+
"activation_function": "gelu",
|
| 9 |
+
"encoder_layers": 24,
|
| 10 |
+
"encoder_skip_layer_id": 3,
|
| 11 |
+
"encoder_attention_heads": 16,
|
| 12 |
+
"encoder_ffn_dim": 4096,
|
| 13 |
+
"encoder_causal": true,
|
| 14 |
+
"encoder_attn_window_size": [
|
| 15 |
+
128,
|
| 16 |
+
0
|
| 17 |
+
],
|
| 18 |
+
"decoder_layers": 24,
|
| 19 |
+
"decoder_attention_heads": 16,
|
| 20 |
+
"decoder_ffn_dim": 4096,
|
| 21 |
+
"decoder_kernel_size": 3,
|
| 22 |
+
"decoder_stride_size": 2,
|
| 23 |
+
"decoder_causal": true,
|
| 24 |
+
"decoder_attn_window_size": [
|
| 25 |
+
128,
|
| 26 |
+
0
|
| 27 |
+
],
|
| 28 |
+
"nfft": 960,
|
| 29 |
+
"n_mels": 128,
|
| 30 |
+
"sampling_rate": 24000,
|
| 31 |
+
"hop_length": 240,
|
| 32 |
+
"window_size": 960,
|
| 33 |
+
"vocoder_padding": "same",
|
| 34 |
+
"fmin": 0,
|
| 35 |
+
"fmax": null,
|
| 36 |
+
"num_quantizers": 20,
|
| 37 |
+
"codebook_size": [
|
| 38 |
+
1024,
|
| 39 |
+
1024,
|
| 40 |
+
256,
|
| 41 |
+
128,
|
| 42 |
+
128,
|
| 43 |
+
128,
|
| 44 |
+
128,
|
| 45 |
+
128,
|
| 46 |
+
128,
|
| 47 |
+
128,
|
| 48 |
+
128,
|
| 49 |
+
128,
|
| 50 |
+
128,
|
| 51 |
+
128,
|
| 52 |
+
128,
|
| 53 |
+
128,
|
| 54 |
+
128,
|
| 55 |
+
128,
|
| 56 |
+
128,
|
| 57 |
+
128
|
| 58 |
+
],
|
| 59 |
+
"threshold_ema_dead_code": 2,
|
| 60 |
+
"position_embedding_type": "rope",
|
| 61 |
+
"rope_theta": 10000,
|
| 62 |
+
"rope_type": "default",
|
| 63 |
+
"ln_type": "LayerNorm",
|
| 64 |
+
"use_istft_only": true,
|
| 65 |
+
"hybrid_attention": true,
|
| 66 |
+
"hybrid_block_size": 8,
|
| 67 |
+
"swa_per_block": 2
|
| 68 |
+
}
|
audio_tokenizer/generation_config.json
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"do_sample": true,
|
| 3 |
+
"temperature": 0.6,
|
| 4 |
+
"top_k": -1,
|
| 5 |
+
"top_p": 0.95,
|
| 6 |
+
"audio_temperature": 0.9,
|
| 7 |
+
"audio_top_k": -1,
|
| 8 |
+
"audio_top_p": 0.95
|
| 9 |
+
}
|
audio_tokenizer/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:077033345d80eef3a315e8d394e0589667e80e4cdaba9bc5a7488410c6657265
|
| 3 |
+
size 1872618384
|
audio_tokenizer/tokenizer_config.json
ADDED
|
@@ -0,0 +1,267 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_bos_token": false,
|
| 3 |
+
"add_prefix_space": false,
|
| 4 |
+
"added_tokens_decoder": {
|
| 5 |
+
"151643": {
|
| 6 |
+
"content": "<|endoftext|>",
|
| 7 |
+
"lstrip": false,
|
| 8 |
+
"normalized": false,
|
| 9 |
+
"rstrip": false,
|
| 10 |
+
"single_word": false,
|
| 11 |
+
"special": true
|
| 12 |
+
},
|
| 13 |
+
"151644": {
|
| 14 |
+
"content": "<|im_start|>",
|
| 15 |
+
"lstrip": false,
|
| 16 |
+
"normalized": false,
|
| 17 |
+
"rstrip": false,
|
| 18 |
+
"single_word": false,
|
| 19 |
+
"special": true
|
| 20 |
+
},
|
| 21 |
+
"151645": {
|
| 22 |
+
"content": "<|im_end|>",
|
| 23 |
+
"lstrip": false,
|
| 24 |
+
"normalized": false,
|
| 25 |
+
"rstrip": false,
|
| 26 |
+
"single_word": false,
|
| 27 |
+
"special": true
|
| 28 |
+
},
|
| 29 |
+
"151646": {
|
| 30 |
+
"content": "<|object_ref_start|>",
|
| 31 |
+
"lstrip": false,
|
| 32 |
+
"normalized": false,
|
| 33 |
+
"rstrip": false,
|
| 34 |
+
"single_word": false,
|
| 35 |
+
"special": true
|
| 36 |
+
},
|
| 37 |
+
"151647": {
|
| 38 |
+
"content": "<|object_ref_end|>",
|
| 39 |
+
"lstrip": false,
|
| 40 |
+
"normalized": false,
|
| 41 |
+
"rstrip": false,
|
| 42 |
+
"single_word": false,
|
| 43 |
+
"special": true
|
| 44 |
+
},
|
| 45 |
+
"151648": {
|
| 46 |
+
"content": "<|box_start|>",
|
| 47 |
+
"lstrip": false,
|
| 48 |
+
"normalized": false,
|
| 49 |
+
"rstrip": false,
|
| 50 |
+
"single_word": false,
|
| 51 |
+
"special": true
|
| 52 |
+
},
|
| 53 |
+
"151649": {
|
| 54 |
+
"content": "<|box_end|>",
|
| 55 |
+
"lstrip": false,
|
| 56 |
+
"normalized": false,
|
| 57 |
+
"rstrip": false,
|
| 58 |
+
"single_word": false,
|
| 59 |
+
"special": true
|
| 60 |
+
},
|
| 61 |
+
"151650": {
|
| 62 |
+
"content": "<|quad_start|>",
|
| 63 |
+
"lstrip": false,
|
| 64 |
+
"normalized": false,
|
| 65 |
+
"rstrip": false,
|
| 66 |
+
"single_word": false,
|
| 67 |
+
"special": true
|
| 68 |
+
},
|
| 69 |
+
"151651": {
|
| 70 |
+
"content": "<|quad_end|>",
|
| 71 |
+
"lstrip": false,
|
| 72 |
+
"normalized": false,
|
| 73 |
+
"rstrip": false,
|
| 74 |
+
"single_word": false,
|
| 75 |
+
"special": true
|
| 76 |
+
},
|
| 77 |
+
"151652": {
|
| 78 |
+
"content": "<|vision_start|>",
|
| 79 |
+
"lstrip": false,
|
| 80 |
+
"normalized": false,
|
| 81 |
+
"rstrip": false,
|
| 82 |
+
"single_word": false,
|
| 83 |
+
"special": true
|
| 84 |
+
},
|
| 85 |
+
"151653": {
|
| 86 |
+
"content": "<|vision_end|>",
|
| 87 |
+
"lstrip": false,
|
| 88 |
+
"normalized": false,
|
| 89 |
+
"rstrip": false,
|
| 90 |
+
"single_word": false,
|
| 91 |
+
"special": true
|
| 92 |
+
},
|
| 93 |
+
"151654": {
|
| 94 |
+
"content": "<|vision_pad|>",
|
| 95 |
+
"lstrip": false,
|
| 96 |
+
"normalized": false,
|
| 97 |
+
"rstrip": false,
|
| 98 |
+
"single_word": false,
|
| 99 |
+
"special": true
|
| 100 |
+
},
|
| 101 |
+
"151655": {
|
| 102 |
+
"content": "<|image_pad|>",
|
| 103 |
+
"lstrip": false,
|
| 104 |
+
"normalized": false,
|
| 105 |
+
"rstrip": false,
|
| 106 |
+
"single_word": false,
|
| 107 |
+
"special": true
|
| 108 |
+
},
|
| 109 |
+
"151656": {
|
| 110 |
+
"content": "<|video_pad|>",
|
| 111 |
+
"lstrip": false,
|
| 112 |
+
"normalized": false,
|
| 113 |
+
"rstrip": false,
|
| 114 |
+
"single_word": false,
|
| 115 |
+
"special": true
|
| 116 |
+
},
|
| 117 |
+
"151657": {
|
| 118 |
+
"content": "<tool_call>",
|
| 119 |
+
"lstrip": false,
|
| 120 |
+
"normalized": false,
|
| 121 |
+
"rstrip": false,
|
| 122 |
+
"single_word": false,
|
| 123 |
+
"special": false
|
| 124 |
+
},
|
| 125 |
+
"151658": {
|
| 126 |
+
"content": "</tool_call>",
|
| 127 |
+
"lstrip": false,
|
| 128 |
+
"normalized": false,
|
| 129 |
+
"rstrip": false,
|
| 130 |
+
"single_word": false,
|
| 131 |
+
"special": false
|
| 132 |
+
},
|
| 133 |
+
"151659": {
|
| 134 |
+
"content": "<|fim_prefix|>",
|
| 135 |
+
"lstrip": false,
|
| 136 |
+
"normalized": false,
|
| 137 |
+
"rstrip": false,
|
| 138 |
+
"single_word": false,
|
| 139 |
+
"special": false
|
| 140 |
+
},
|
| 141 |
+
"151660": {
|
| 142 |
+
"content": "<|fim_middle|>",
|
| 143 |
+
"lstrip": false,
|
| 144 |
+
"normalized": false,
|
| 145 |
+
"rstrip": false,
|
| 146 |
+
"single_word": false,
|
| 147 |
+
"special": false
|
| 148 |
+
},
|
| 149 |
+
"151661": {
|
| 150 |
+
"content": "<|fim_suffix|>",
|
| 151 |
+
"lstrip": false,
|
| 152 |
+
"normalized": false,
|
| 153 |
+
"rstrip": false,
|
| 154 |
+
"single_word": false,
|
| 155 |
+
"special": false
|
| 156 |
+
},
|
| 157 |
+
"151662": {
|
| 158 |
+
"content": "<|fim_pad|>",
|
| 159 |
+
"lstrip": false,
|
| 160 |
+
"normalized": false,
|
| 161 |
+
"rstrip": false,
|
| 162 |
+
"single_word": false,
|
| 163 |
+
"special": false
|
| 164 |
+
},
|
| 165 |
+
"151663": {
|
| 166 |
+
"content": "<|repo_name|>",
|
| 167 |
+
"lstrip": false,
|
| 168 |
+
"normalized": false,
|
| 169 |
+
"rstrip": false,
|
| 170 |
+
"single_word": false,
|
| 171 |
+
"special": false
|
| 172 |
+
},
|
| 173 |
+
"151664": {
|
| 174 |
+
"content": "<|file_sep|>",
|
| 175 |
+
"lstrip": false,
|
| 176 |
+
"normalized": false,
|
| 177 |
+
"rstrip": false,
|
| 178 |
+
"single_word": false,
|
| 179 |
+
"special": false
|
| 180 |
+
},
|
| 181 |
+
"151665": {
|
| 182 |
+
"content": "<|mimo_audio_start|>",
|
| 183 |
+
"lstrip": false,
|
| 184 |
+
"normalized": false,
|
| 185 |
+
"rstrip": false,
|
| 186 |
+
"single_word": false,
|
| 187 |
+
"special": true
|
| 188 |
+
},
|
| 189 |
+
"151666": {
|
| 190 |
+
"content": "<|mimo_audio_end|>",
|
| 191 |
+
"lstrip": false,
|
| 192 |
+
"normalized": false,
|
| 193 |
+
"rstrip": false,
|
| 194 |
+
"single_word": false,
|
| 195 |
+
"special": true
|
| 196 |
+
},
|
| 197 |
+
"151667": {
|
| 198 |
+
"content": "<think>",
|
| 199 |
+
"lstrip": false,
|
| 200 |
+
"normalized": false,
|
| 201 |
+
"rstrip": false,
|
| 202 |
+
"single_word": false,
|
| 203 |
+
"special": false
|
| 204 |
+
},
|
| 205 |
+
"151668": {
|
| 206 |
+
"content": "</think>",
|
| 207 |
+
"lstrip": false,
|
| 208 |
+
"normalized": false,
|
| 209 |
+
"rstrip": false,
|
| 210 |
+
"single_word": false,
|
| 211 |
+
"special": false
|
| 212 |
+
},
|
| 213 |
+
"151669": {
|
| 214 |
+
"content": "<|audio_pad|>",
|
| 215 |
+
"lstrip": false,
|
| 216 |
+
"normalized": false,
|
| 217 |
+
"rstrip": false,
|
| 218 |
+
"single_word": false,
|
| 219 |
+
"special": true
|
| 220 |
+
},
|
| 221 |
+
"151670": {
|
| 222 |
+
"content": "<|mimo_video_start|>",
|
| 223 |
+
"lstrip": false,
|
| 224 |
+
"normalized": false,
|
| 225 |
+
"rstrip": false,
|
| 226 |
+
"single_word": false,
|
| 227 |
+
"special": true
|
| 228 |
+
},
|
| 229 |
+
"151671": {
|
| 230 |
+
"content": "<|mimo_video_end|>",
|
| 231 |
+
"lstrip": false,
|
| 232 |
+
"normalized": false,
|
| 233 |
+
"rstrip": false,
|
| 234 |
+
"single_word": false,
|
| 235 |
+
"special": true
|
| 236 |
+
}
|
| 237 |
+
},
|
| 238 |
+
"additional_special_tokens": [
|
| 239 |
+
"<|im_start|>",
|
| 240 |
+
"<|im_end|>",
|
| 241 |
+
"<|object_ref_start|>",
|
| 242 |
+
"<|object_ref_end|>",
|
| 243 |
+
"<|box_start|>",
|
| 244 |
+
"<|box_end|>",
|
| 245 |
+
"<|quad_start|>",
|
| 246 |
+
"<|quad_end|>",
|
| 247 |
+
"<|vision_start|>",
|
| 248 |
+
"<|vision_end|>",
|
| 249 |
+
"<|vision_pad|>",
|
| 250 |
+
"<|image_pad|>",
|
| 251 |
+
"<|video_pad|>",
|
| 252 |
+
"<|audio_pad|>",
|
| 253 |
+
"<|mimo_audio_start|>",
|
| 254 |
+
"<|mimo_audio_end|>",
|
| 255 |
+
"<|mimo_video_start|>",
|
| 256 |
+
"<|mimo_video_end|>"
|
| 257 |
+
],
|
| 258 |
+
"bos_token": null,
|
| 259 |
+
"clean_up_tokenization_spaces": false,
|
| 260 |
+
"eos_token": "<|im_end|>",
|
| 261 |
+
"errors": "replace",
|
| 262 |
+
"model_max_length": 131072,
|
| 263 |
+
"pad_token": "<|endoftext|>",
|
| 264 |
+
"split_special_tokens": false,
|
| 265 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 266 |
+
"unk_token": null
|
| 267 |
+
}
|
chat_template.jinja
ADDED
|
@@ -0,0 +1,96 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- macro render_value(value) -%}
|
| 2 |
+
{%- if value is string -%}
|
| 3 |
+
{{- value -}}
|
| 4 |
+
{%- else -%}
|
| 5 |
+
{{- value | tojson(ensure_ascii=False) -}}
|
| 6 |
+
{%- endif -%}
|
| 7 |
+
{%- endmacro -%}
|
| 8 |
+
|
| 9 |
+
{%- macro render_content(message_content) -%}
|
| 10 |
+
{%- if message_content is string -%}
|
| 11 |
+
{{- message_content -}}
|
| 12 |
+
{%- elif message_content is iterable -%}
|
| 13 |
+
{%- for part in message_content -%}
|
| 14 |
+
{%- if part is not mapping -%}
|
| 15 |
+
{{- part -}}
|
| 16 |
+
{%- elif part['type'] == 'image' or 'image' in part or 'image_url' in part -%}
|
| 17 |
+
{{- '<|vision_start|><|image_pad|><|vision_end|>' -}}
|
| 18 |
+
{%- elif part['type'] == 'audio' or part['type'] == 'input_audio' or 'audio' in part or 'audio_url' in part or 'input_audio' in part -%}
|
| 19 |
+
{{- '<|mimo_audio_start|><|audio_pad|><|mimo_audio_end|>' -}}
|
| 20 |
+
{%- elif part['type'] == 'video' or 'video' in part or 'video_url' in part -%}
|
| 21 |
+
{{- '<|vision_start|><|video_pad|><|vision_end|>' -}}
|
| 22 |
+
{%- elif 'text' in part -%}
|
| 23 |
+
{{- part['text'] -}}
|
| 24 |
+
{%- endif -%}
|
| 25 |
+
{%- endfor -%}
|
| 26 |
+
{%- endif -%}
|
| 27 |
+
{%- endmacro -%}
|
| 28 |
+
|
| 29 |
+
{%- macro render_tools(tools) -%}
|
| 30 |
+
{{- 'You are provided with the following tools:\n\n<tools>' -}}
|
| 31 |
+
{%- for tool in tools -%}
|
| 32 |
+
{{- '\n' ~ (tool | tojson(ensure_ascii=False)) -}}
|
| 33 |
+
{%- endfor -%}
|
| 34 |
+
{{- '\n</tools>' -}}
|
| 35 |
+
{%- endmacro -%}
|
| 36 |
+
|
| 37 |
+
{%- macro render_tool_calls(tool_calls) -%}
|
| 38 |
+
{%- for tool_call in tool_calls -%}
|
| 39 |
+
{%- if tool_call.function is defined -%}
|
| 40 |
+
{%- set tool_call = tool_call.function -%}
|
| 41 |
+
{%- elif tool_call.custom is defined -%}
|
| 42 |
+
{%- set tool_call = tool_call.custom -%}
|
| 43 |
+
{%- endif -%}
|
| 44 |
+
{{- '<tool_call><function=' ~ tool_call.name ~ '>' -}}
|
| 45 |
+
{%- if tool_call.input is defined and tool_call.input is string -%}
|
| 46 |
+
{{- tool_call.input -}}
|
| 47 |
+
{%- elif tool_call.arguments -%}
|
| 48 |
+
{%- if tool_call.arguments is string -%}
|
| 49 |
+
{{- tool_call.arguments -}}
|
| 50 |
+
{%- else -%}
|
| 51 |
+
{%- for args_name, args_value in tool_call.arguments | items -%}
|
| 52 |
+
{{- '<parameter=' ~ args_name ~ '>' ~ render_value(args_value) ~ '</parameter>' -}}
|
| 53 |
+
{%- endfor -%}
|
| 54 |
+
{%- endif -%}
|
| 55 |
+
{%- endif -%}
|
| 56 |
+
{{- '</function></tool_call>' -}}
|
| 57 |
+
{%- endfor -%}
|
| 58 |
+
{%- endmacro -%}
|
| 59 |
+
|
| 60 |
+
{%- macro render_assistant_message(message) -%}
|
| 61 |
+
{%- set content = render_content(message.content) -%}
|
| 62 |
+
{%- set reasoning = message.reasoning_content if message.reasoning_content is string else '' -%}
|
| 63 |
+
{{- '<|im_start|>assistant\n<think>' ~ reasoning ~ '</think>' ~ content -}}
|
| 64 |
+
{%- if message.tool_calls is defined and message.tool_calls is iterable and message.tool_calls | length > 0 -%}
|
| 65 |
+
{{- render_tool_calls(message.tool_calls) -}}
|
| 66 |
+
{%- endif -%}
|
| 67 |
+
{{- '<|im_end|>' -}}
|
| 68 |
+
{%- endmacro -%}
|
| 69 |
+
|
| 70 |
+
|
| 71 |
+
{%- if tools is defined and tools is iterable and tools | length > 0 -%}
|
| 72 |
+
{{- '<|im_start|>system\n' ~ render_tools(tools) ~ '<|im_end|>' -}}
|
| 73 |
+
{%- endif -%}
|
| 74 |
+
|
| 75 |
+
{%- for message in messages -%}
|
| 76 |
+
{%- if message.role == 'assistant' -%}
|
| 77 |
+
{{- render_assistant_message(message) -}}
|
| 78 |
+
{%- else -%}
|
| 79 |
+
{%- set body = render_content(message.content) -%}
|
| 80 |
+
{{- '<|im_start|>' ~ message.role ~ '\n' ~ body -}}
|
| 81 |
+
{%- if message.tools is defined and message.tools is iterable and message.tools | length > 0 -%}
|
| 82 |
+
{%- if body -%}
|
| 83 |
+
{{- '\n\n' -}}
|
| 84 |
+
{%- endif -%}
|
| 85 |
+
{{- render_tools(message.tools) -}}
|
| 86 |
+
{%- endif -%}
|
| 87 |
+
{{- '<|im_end|>' -}}
|
| 88 |
+
{%- endif -%}
|
| 89 |
+
{%- endfor -%}
|
| 90 |
+
|
| 91 |
+
{%- if add_generation_prompt -%}
|
| 92 |
+
{{- '<|im_start|>assistant\n' -}}
|
| 93 |
+
{%- if enable_thinking is false -%}
|
| 94 |
+
{{- '<think></think>' -}}
|
| 95 |
+
{%- endif -%}
|
| 96 |
+
{%- endif -%}
|
config.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
configuration_mimo_v2.py
ADDED
|
@@ -0,0 +1,247 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# coding=utf-8
|
| 2 |
+
#
|
| 3 |
+
# Copyright 2026 Xiaomi Corporation.
|
| 4 |
+
# Copyright 2026 The HuggingFace Inc. team.
|
| 5 |
+
#
|
| 6 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 7 |
+
# you may not use this file except in compliance with the License.
|
| 8 |
+
# You may obtain a copy of the License at
|
| 9 |
+
#
|
| 10 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 11 |
+
#
|
| 12 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 13 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 14 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 15 |
+
# See the License for the specific language governing permissions and
|
| 16 |
+
# limitations under the License.
|
| 17 |
+
|
| 18 |
+
from copy import deepcopy
|
| 19 |
+
|
| 20 |
+
from transformers.configuration_utils import PretrainedConfig
|
| 21 |
+
from transformers.modeling_rope_utils import rope_config_validation
|
| 22 |
+
from transformers.utils import logging
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
logger = logging.get_logger(__name__)
|
| 26 |
+
|
| 27 |
+
|
| 28 |
+
_MIMOV2_ATTENTION_PROJECTION_LAYOUTS = {"split", "fused_qkv"}
|
| 29 |
+
|
| 30 |
+
_MIMOV2_SPLIT_TP_PLAN = {
|
| 31 |
+
"layers.*.self_attn.q_proj": "colwise",
|
| 32 |
+
"layers.*.self_attn.k_proj": "colwise",
|
| 33 |
+
"layers.*.self_attn.v_proj": "colwise",
|
| 34 |
+
"layers.*.self_attn.o_proj": "rowwise",
|
| 35 |
+
"layers.*.mlp.gate_proj": "colwise",
|
| 36 |
+
"layers.*.mlp.up_proj": "colwise",
|
| 37 |
+
"layers.*.mlp.down_proj": "rowwise",
|
| 38 |
+
}
|
| 39 |
+
|
| 40 |
+
_MIMOV2_FUSED_QKV_TP_PLAN = {
|
| 41 |
+
"layers.*.self_attn.qkv_proj": "colwise",
|
| 42 |
+
"layers.*.self_attn.o_proj": "rowwise",
|
| 43 |
+
"layers.*.mlp.gate_proj": "colwise",
|
| 44 |
+
"layers.*.mlp.up_proj": "colwise",
|
| 45 |
+
"layers.*.mlp.down_proj": "rowwise",
|
| 46 |
+
}
|
| 47 |
+
|
| 48 |
+
_MIMOV2_PP_PLAN = {
|
| 49 |
+
"embed_tokens": (["input_ids"], ["inputs_embeds"]),
|
| 50 |
+
"layers": (["hidden_states", "attention_mask"], ["hidden_states"]),
|
| 51 |
+
"norm": (["hidden_states"], ["hidden_states"]),
|
| 52 |
+
}
|
| 53 |
+
|
| 54 |
+
|
| 55 |
+
def _to_plain_dict(value):
|
| 56 |
+
if value is None:
|
| 57 |
+
return {}
|
| 58 |
+
if isinstance(value, dict):
|
| 59 |
+
return deepcopy(value)
|
| 60 |
+
if hasattr(value, "to_dict"):
|
| 61 |
+
return deepcopy(value.to_dict())
|
| 62 |
+
if hasattr(value, "__dict__"):
|
| 63 |
+
return deepcopy(vars(value))
|
| 64 |
+
raise TypeError(f"Unsupported config value type: {type(value)!r}")
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
class MiMoV2Config(PretrainedConfig):
|
| 68 |
+
|
| 69 |
+
model_type = "mimo_v2"
|
| 70 |
+
keys_to_ignore_at_inference = ["past_key_values"]
|
| 71 |
+
|
| 72 |
+
base_model_tp_plan = _MIMOV2_SPLIT_TP_PLAN
|
| 73 |
+
base_model_pp_plan = _MIMOV2_PP_PLAN
|
| 74 |
+
|
| 75 |
+
attribute_map = {
|
| 76 |
+
"num_local_experts": "n_routed_experts",
|
| 77 |
+
}
|
| 78 |
+
|
| 79 |
+
def __init__(
|
| 80 |
+
self,
|
| 81 |
+
vocab_size=151936,
|
| 82 |
+
hidden_size=4096,
|
| 83 |
+
intermediate_size=22016,
|
| 84 |
+
num_hidden_layers=32,
|
| 85 |
+
num_attention_heads=32,
|
| 86 |
+
num_key_value_heads=32,
|
| 87 |
+
hidden_act="silu",
|
| 88 |
+
max_position_embeddings=32768,
|
| 89 |
+
initializer_range=0.02,
|
| 90 |
+
layernorm_epsilon=1e-6,
|
| 91 |
+
use_cache=True,
|
| 92 |
+
tie_word_embeddings=False,
|
| 93 |
+
rope_theta=10000.0,
|
| 94 |
+
rope_scaling=None,
|
| 95 |
+
attention_dropout=0.0,
|
| 96 |
+
attention_bias=False,
|
| 97 |
+
attention_value_scale=None,
|
| 98 |
+
head_dim=None,
|
| 99 |
+
v_head_dim=None,
|
| 100 |
+
swa_num_attention_heads=None,
|
| 101 |
+
swa_num_key_value_heads=None,
|
| 102 |
+
swa_head_dim=None,
|
| 103 |
+
swa_v_head_dim=None,
|
| 104 |
+
swa_rope_theta=None,
|
| 105 |
+
sliding_window=None,
|
| 106 |
+
sliding_window_size=None,
|
| 107 |
+
add_full_attention_sink_bias=False,
|
| 108 |
+
add_swa_attention_sink_bias=False,
|
| 109 |
+
hybrid_block_size=None,
|
| 110 |
+
hybrid_layer_pattern=None,
|
| 111 |
+
partial_rotary_factor=1.0,
|
| 112 |
+
n_routed_experts=None,
|
| 113 |
+
moe_intermediate_size=None,
|
| 114 |
+
num_experts_per_tok=None,
|
| 115 |
+
routed_scaling_factor=None,
|
| 116 |
+
scoring_func="sigmoid",
|
| 117 |
+
topk_method="noaux_tc",
|
| 118 |
+
n_group=None,
|
| 119 |
+
topk_group=None,
|
| 120 |
+
norm_topk_prob=True,
|
| 121 |
+
moe_layer_freq=None,
|
| 122 |
+
attention_projection_layout="split",
|
| 123 |
+
vision_config=None,
|
| 124 |
+
audio_config=None,
|
| 125 |
+
processor_config=None,
|
| 126 |
+
image_token_id=None,
|
| 127 |
+
video_token_id=None,
|
| 128 |
+
vision_start_token_id=None,
|
| 129 |
+
vision_end_token_id=None,
|
| 130 |
+
vision_model_type=None,
|
| 131 |
+
**kwargs,
|
| 132 |
+
):
|
| 133 |
+
rope_parameters = kwargs.pop("rope_parameters", None)
|
| 134 |
+
if rope_scaling is None and rope_parameters is not None:
|
| 135 |
+
rope_scaling = rope_parameters
|
| 136 |
+
|
| 137 |
+
if attention_projection_layout is None:
|
| 138 |
+
attention_projection_layout = "split"
|
| 139 |
+
if attention_projection_layout not in _MIMOV2_ATTENTION_PROJECTION_LAYOUTS:
|
| 140 |
+
raise ValueError(f"Unsupported MiMoV2 attention projection layout: {attention_projection_layout}")
|
| 141 |
+
|
| 142 |
+
self.attention_projection_layout = attention_projection_layout
|
| 143 |
+
self.base_model_tp_plan = (
|
| 144 |
+
_MIMOV2_FUSED_QKV_TP_PLAN.copy()
|
| 145 |
+
if attention_projection_layout == "fused_qkv"
|
| 146 |
+
else _MIMOV2_SPLIT_TP_PLAN.copy()
|
| 147 |
+
)
|
| 148 |
+
self.base_model_pp_plan = _MIMOV2_PP_PLAN.copy()
|
| 149 |
+
|
| 150 |
+
self.vocab_size = vocab_size
|
| 151 |
+
self.max_position_embeddings = max_position_embeddings
|
| 152 |
+
self.hidden_size = hidden_size
|
| 153 |
+
self.intermediate_size = intermediate_size
|
| 154 |
+
self.num_hidden_layers = num_hidden_layers
|
| 155 |
+
self.num_attention_heads = num_attention_heads
|
| 156 |
+
|
| 157 |
+
if num_key_value_heads is None:
|
| 158 |
+
num_key_value_heads = num_attention_heads
|
| 159 |
+
if num_attention_heads % num_key_value_heads != 0:
|
| 160 |
+
raise ValueError("num_attention_heads must be divisible by num_key_value_heads")
|
| 161 |
+
|
| 162 |
+
self.num_key_value_heads = num_key_value_heads
|
| 163 |
+
self.hidden_act = hidden_act
|
| 164 |
+
self.initializer_range = initializer_range
|
| 165 |
+
self.layernorm_epsilon = layernorm_epsilon
|
| 166 |
+
self.use_cache = use_cache
|
| 167 |
+
self.rope_theta = rope_theta
|
| 168 |
+
self.rope_scaling = rope_scaling
|
| 169 |
+
self.attention_dropout = attention_dropout
|
| 170 |
+
self.attention_bias = attention_bias
|
| 171 |
+
self.attention_value_scale = attention_value_scale
|
| 172 |
+
|
| 173 |
+
self.head_dim = head_dim if head_dim is not None else hidden_size // num_attention_heads
|
| 174 |
+
self.v_head_dim = v_head_dim if v_head_dim is not None else self.head_dim
|
| 175 |
+
self.swa_num_attention_heads = (
|
| 176 |
+
swa_num_attention_heads if swa_num_attention_heads is not None else num_attention_heads
|
| 177 |
+
)
|
| 178 |
+
self.swa_num_key_value_heads = (
|
| 179 |
+
swa_num_key_value_heads if swa_num_key_value_heads is not None else num_key_value_heads
|
| 180 |
+
)
|
| 181 |
+
if self.swa_num_attention_heads % self.swa_num_key_value_heads != 0:
|
| 182 |
+
raise ValueError("swa_num_attention_heads must be divisible by swa_num_key_value_heads")
|
| 183 |
+
self.swa_head_dim = swa_head_dim if swa_head_dim is not None else self.head_dim
|
| 184 |
+
self.swa_v_head_dim = swa_v_head_dim if swa_v_head_dim is not None else self.swa_head_dim
|
| 185 |
+
self.swa_rope_theta = swa_rope_theta if swa_rope_theta is not None else rope_theta
|
| 186 |
+
|
| 187 |
+
if sliding_window is None:
|
| 188 |
+
sliding_window = sliding_window_size
|
| 189 |
+
self.sliding_window = sliding_window
|
| 190 |
+
self.sliding_window_size = sliding_window_size if sliding_window_size is not None else sliding_window
|
| 191 |
+
self.add_full_attention_sink_bias = add_full_attention_sink_bias
|
| 192 |
+
self.add_swa_attention_sink_bias = add_swa_attention_sink_bias
|
| 193 |
+
|
| 194 |
+
if hybrid_block_size is not None and hybrid_layer_pattern is None:
|
| 195 |
+
hybrid_layer_pattern = [0 if ((i + 1) % hybrid_block_size == 0) else 1 for i in range(num_hidden_layers)]
|
| 196 |
+
elif hybrid_layer_pattern is None:
|
| 197 |
+
hybrid_layer_pattern = [0] * num_hidden_layers
|
| 198 |
+
if len(hybrid_layer_pattern) != num_hidden_layers:
|
| 199 |
+
raise ValueError("hybrid_layer_pattern length must match num_hidden_layers")
|
| 200 |
+
self.hybrid_block_size = hybrid_block_size
|
| 201 |
+
self.hybrid_layer_pattern = hybrid_layer_pattern
|
| 202 |
+
|
| 203 |
+
self.partial_rotary_factor = partial_rotary_factor
|
| 204 |
+
|
| 205 |
+
self.n_routed_experts = n_routed_experts
|
| 206 |
+
self.moe_intermediate_size = moe_intermediate_size if moe_intermediate_size is not None else intermediate_size
|
| 207 |
+
self.num_experts_per_tok = num_experts_per_tok
|
| 208 |
+
self.routed_scaling_factor = routed_scaling_factor
|
| 209 |
+
self.scoring_func = scoring_func
|
| 210 |
+
self.topk_method = topk_method
|
| 211 |
+
self.n_group = n_group
|
| 212 |
+
self.topk_group = topk_group
|
| 213 |
+
self.norm_topk_prob = norm_topk_prob
|
| 214 |
+
if isinstance(moe_layer_freq, int):
|
| 215 |
+
moe_layer_freq = [moe_layer_freq > 0 and i % moe_layer_freq == 0 for i in range(num_hidden_layers)]
|
| 216 |
+
elif moe_layer_freq is None:
|
| 217 |
+
moe_layer_freq = [False] * num_hidden_layers
|
| 218 |
+
if len(moe_layer_freq) != num_hidden_layers:
|
| 219 |
+
raise ValueError("moe_layer_freq length must match num_hidden_layers")
|
| 220 |
+
self.moe_layer_freq = moe_layer_freq
|
| 221 |
+
|
| 222 |
+
self.vision_config = _to_plain_dict(vision_config)
|
| 223 |
+
self.audio_config = _to_plain_dict(audio_config)
|
| 224 |
+
self.processor_config = _to_plain_dict(processor_config)
|
| 225 |
+
self.image_token_id = image_token_id
|
| 226 |
+
self.video_token_id = video_token_id
|
| 227 |
+
self.vision_start_token_id = vision_start_token_id
|
| 228 |
+
self.vision_end_token_id = vision_end_token_id
|
| 229 |
+
self.vision_model_type = vision_model_type
|
| 230 |
+
self.audio_token_id = self.processor_config.get("audio_token_id", None) if self.processor_config else None
|
| 231 |
+
self.audio_start_token_id = (
|
| 232 |
+
self.processor_config.get("audio_start_token_id", None) if self.processor_config else None
|
| 233 |
+
)
|
| 234 |
+
self.audio_end_token_id = (
|
| 235 |
+
self.processor_config.get("audio_end_token_id", None) if self.processor_config else None
|
| 236 |
+
)
|
| 237 |
+
|
| 238 |
+
if self.rope_scaling is not None and "type" in self.rope_scaling:
|
| 239 |
+
self.rope_scaling["rope_type"] = self.rope_scaling["type"]
|
| 240 |
+
rope_config_validation(self)
|
| 241 |
+
|
| 242 |
+
super().__init__(
|
| 243 |
+
tie_word_embeddings=tie_word_embeddings,
|
| 244 |
+
**kwargs,
|
| 245 |
+
)
|
| 246 |
+
|
| 247 |
+
__all__ = ["MiMoV2Config"]
|
dflash/config.json
ADDED
|
@@ -0,0 +1,56 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"DFlashDraftModel"
|
| 4 |
+
],
|
| 5 |
+
"model_type": "qwen3",
|
| 6 |
+
"auto_map": {
|
| 7 |
+
"AutoModel": "dflash.DFlashDraftModel"
|
| 8 |
+
},
|
| 9 |
+
"hidden_size": 4096,
|
| 10 |
+
"intermediate_size": 16384,
|
| 11 |
+
"num_hidden_layers": 5,
|
| 12 |
+
"num_attention_heads": 64,
|
| 13 |
+
"num_key_value_heads": 8,
|
| 14 |
+
"head_dim": 128,
|
| 15 |
+
"v_head_dim": 128,
|
| 16 |
+
"partial_rotary_factor": 0.5,
|
| 17 |
+
"block_size": 8,
|
| 18 |
+
"dflash_config": {
|
| 19 |
+
"target_layer_ids": [
|
| 20 |
+
0,
|
| 21 |
+
11,
|
| 22 |
+
23,
|
| 23 |
+
35,
|
| 24 |
+
47
|
| 25 |
+
],
|
| 26 |
+
"mask_token_id": 151675,
|
| 27 |
+
"num_anchors": 4096,
|
| 28 |
+
"block_size": 8,
|
| 29 |
+
"loss_decay_gamma": 7.0,
|
| 30 |
+
"attention_value_scale": 0.612,
|
| 31 |
+
"attention_sink_bias": true
|
| 32 |
+
},
|
| 33 |
+
"layer_types": [
|
| 34 |
+
"sliding_attention",
|
| 35 |
+
"sliding_attention",
|
| 36 |
+
"sliding_attention",
|
| 37 |
+
"sliding_attention",
|
| 38 |
+
"sliding_attention"
|
| 39 |
+
],
|
| 40 |
+
"sliding_window": 1024,
|
| 41 |
+
"use_sliding_window": true,
|
| 42 |
+
"is_causal": false,
|
| 43 |
+
"num_target_layers": 48,
|
| 44 |
+
"target_hidden_size": 4096,
|
| 45 |
+
"vocab_size": 152576,
|
| 46 |
+
"max_position_embeddings": 1048576,
|
| 47 |
+
"rope_theta": 10000.0,
|
| 48 |
+
"rms_norm_eps": 1e-06,
|
| 49 |
+
"torch_dtype": "bfloat16",
|
| 50 |
+
"hidden_act": "silu",
|
| 51 |
+
"attention_bias": false,
|
| 52 |
+
"attention_dropout": 0.0,
|
| 53 |
+
"add_swa_attention_sink_bias": true,
|
| 54 |
+
"tie_word_embeddings": false,
|
| 55 |
+
"use_cache": true
|
| 56 |
+
}
|
dflash/dflash.py
ADDED
|
@@ -0,0 +1,379 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from typing import Callable, Optional
|
| 2 |
+
|
| 3 |
+
import torch
|
| 4 |
+
from torch import nn
|
| 5 |
+
from transformers import DynamicCache
|
| 6 |
+
from transformers.cache_utils import Cache
|
| 7 |
+
from transformers.modeling_outputs import CausalLMOutputWithPast
|
| 8 |
+
from transformers.models.qwen3.modeling_qwen3 import (
|
| 9 |
+
ALL_ATTENTION_FUNCTIONS,
|
| 10 |
+
FlashAttentionKwargs,
|
| 11 |
+
GradientCheckpointingLayer,
|
| 12 |
+
Qwen3Config,
|
| 13 |
+
Qwen3MLP,
|
| 14 |
+
Qwen3PreTrainedModel,
|
| 15 |
+
Qwen3RMSNorm,
|
| 16 |
+
Qwen3RotaryEmbedding,
|
| 17 |
+
eager_attention_forward,
|
| 18 |
+
rotate_half,
|
| 19 |
+
)
|
| 20 |
+
from typing_extensions import Tuple, Unpack
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
def sample(logits: torch.Tensor, temperature: float = 0.0) -> torch.Tensor:
|
| 24 |
+
if temperature < 1e-5:
|
| 25 |
+
return torch.argmax(logits, dim=-1)
|
| 26 |
+
bsz, seq_len, vocab_size = logits.shape
|
| 27 |
+
logits = logits.view(-1, vocab_size)
|
| 28 |
+
logits = logits / temperature
|
| 29 |
+
probs = torch.softmax(logits, dim=-1)
|
| 30 |
+
return torch.multinomial(probs, num_samples=1).view(bsz, seq_len)
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
def apply_rotary_pos_emb(q, k, cos, sin, position_ids=None, unsqueeze_dim=1):
|
| 34 |
+
cos = cos.unsqueeze(unsqueeze_dim)
|
| 35 |
+
sin = sin.unsqueeze(unsqueeze_dim)
|
| 36 |
+
q_len = q.size(-2)
|
| 37 |
+
q_embed = (q * cos[..., -q_len:, :]) + (rotate_half(q) * sin[..., -q_len:, :])
|
| 38 |
+
k_embed = (k * cos) + (rotate_half(k) * sin)
|
| 39 |
+
return q_embed, k_embed
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
class Qwen3DFlashAttention(nn.Module):
|
| 43 |
+
"""Multi-headed attention from 'Attention Is All You Need' paper"""
|
| 44 |
+
|
| 45 |
+
def __init__(self, config: Qwen3Config, layer_idx: int):
|
| 46 |
+
super().__init__()
|
| 47 |
+
self.config = config
|
| 48 |
+
self.layer_idx = layer_idx
|
| 49 |
+
self.head_dim = getattr(
|
| 50 |
+
config, "head_dim", config.hidden_size // config.num_attention_heads
|
| 51 |
+
)
|
| 52 |
+
self.num_key_value_groups = (
|
| 53 |
+
config.num_attention_heads // config.num_key_value_heads
|
| 54 |
+
)
|
| 55 |
+
self.scaling = self.head_dim**-0.5
|
| 56 |
+
self.attention_dropout = config.attention_dropout
|
| 57 |
+
self.is_causal = False
|
| 58 |
+
self.q_proj = nn.Linear(
|
| 59 |
+
config.hidden_size,
|
| 60 |
+
config.num_attention_heads * self.head_dim,
|
| 61 |
+
bias=config.attention_bias,
|
| 62 |
+
)
|
| 63 |
+
self.k_proj = nn.Linear(
|
| 64 |
+
config.hidden_size,
|
| 65 |
+
config.num_key_value_heads * self.head_dim,
|
| 66 |
+
bias=config.attention_bias,
|
| 67 |
+
)
|
| 68 |
+
self.v_proj = nn.Linear(
|
| 69 |
+
config.hidden_size,
|
| 70 |
+
config.num_key_value_heads * self.head_dim,
|
| 71 |
+
bias=config.attention_bias,
|
| 72 |
+
)
|
| 73 |
+
self.o_proj = nn.Linear(
|
| 74 |
+
config.num_attention_heads * self.head_dim,
|
| 75 |
+
config.hidden_size,
|
| 76 |
+
bias=config.attention_bias,
|
| 77 |
+
)
|
| 78 |
+
self.q_norm = Qwen3RMSNorm(self.head_dim, eps=config.rms_norm_eps)
|
| 79 |
+
self.k_norm = Qwen3RMSNorm(self.head_dim, eps=config.rms_norm_eps)
|
| 80 |
+
self.sliding_window = (
|
| 81 |
+
config.sliding_window
|
| 82 |
+
if config.layer_types[layer_idx] == "sliding_attention"
|
| 83 |
+
else None
|
| 84 |
+
)
|
| 85 |
+
|
| 86 |
+
def forward(
|
| 87 |
+
self,
|
| 88 |
+
hidden_states: torch.Tensor,
|
| 89 |
+
target_hidden: torch.Tensor,
|
| 90 |
+
position_embeddings: tuple[torch.Tensor, torch.Tensor],
|
| 91 |
+
attention_mask: Optional[torch.Tensor],
|
| 92 |
+
past_key_values: Optional[Cache] = None,
|
| 93 |
+
cache_position: Optional[torch.LongTensor] = None,
|
| 94 |
+
**kwargs: Unpack[FlashAttentionKwargs],
|
| 95 |
+
) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
|
| 96 |
+
bsz, q_len = hidden_states.shape[:-1]
|
| 97 |
+
ctx_len = target_hidden.shape[1]
|
| 98 |
+
q = self.q_proj(hidden_states)
|
| 99 |
+
q = q.view(bsz, q_len, -1, self.head_dim)
|
| 100 |
+
q = self.q_norm(q).transpose(1, 2)
|
| 101 |
+
k_ctx = self.k_proj(target_hidden)
|
| 102 |
+
k_noise = self.k_proj(hidden_states)
|
| 103 |
+
v_ctx = self.v_proj(target_hidden)
|
| 104 |
+
v_noise = self.v_proj(hidden_states)
|
| 105 |
+
k = torch.cat([k_ctx, k_noise], dim=1).view(
|
| 106 |
+
bsz, ctx_len + q_len, -1, self.head_dim
|
| 107 |
+
)
|
| 108 |
+
v = torch.cat([v_ctx, v_noise], dim=1).view(
|
| 109 |
+
bsz, ctx_len + q_len, -1, self.head_dim
|
| 110 |
+
)
|
| 111 |
+
k = self.k_norm(k).transpose(1, 2)
|
| 112 |
+
v = v.transpose(1, 2)
|
| 113 |
+
cos, sin = position_embeddings
|
| 114 |
+
q, k = apply_rotary_pos_emb(q, k, cos, sin)
|
| 115 |
+
if past_key_values is not None:
|
| 116 |
+
cache_kwargs = {"sin": sin, "cos": cos, "cache_position": cache_position}
|
| 117 |
+
k, v = past_key_values.update(k, v, self.layer_idx, cache_kwargs)
|
| 118 |
+
attn_fn: Callable = eager_attention_forward
|
| 119 |
+
if self.config._attn_implementation != "eager":
|
| 120 |
+
attn_fn = ALL_ATTENTION_FUNCTIONS[self.config._attn_implementation]
|
| 121 |
+
attn_output, attn_weights = attn_fn(
|
| 122 |
+
self,
|
| 123 |
+
q,
|
| 124 |
+
k,
|
| 125 |
+
v,
|
| 126 |
+
attention_mask,
|
| 127 |
+
dropout=0.0 if not self.training else self.attention_dropout,
|
| 128 |
+
scaling=self.scaling,
|
| 129 |
+
sliding_window=self.sliding_window,
|
| 130 |
+
**kwargs,
|
| 131 |
+
)
|
| 132 |
+
attn_output = attn_output.reshape(bsz, q_len, -1)
|
| 133 |
+
attn_output = self.o_proj(attn_output)
|
| 134 |
+
return attn_output, attn_weights
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
class Qwen3DFlashDecoderLayer(GradientCheckpointingLayer):
|
| 138 |
+
def __init__(self, config: Qwen3Config, layer_idx: int):
|
| 139 |
+
super().__init__()
|
| 140 |
+
self.hidden_size = config.hidden_size
|
| 141 |
+
self.self_attn = Qwen3DFlashAttention(config=config, layer_idx=layer_idx)
|
| 142 |
+
self.mlp = Qwen3MLP(config)
|
| 143 |
+
self.input_layernorm = Qwen3RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
|
| 144 |
+
self.post_attention_layernorm = Qwen3RMSNorm(
|
| 145 |
+
config.hidden_size, eps=config.rms_norm_eps
|
| 146 |
+
)
|
| 147 |
+
|
| 148 |
+
def forward(
|
| 149 |
+
self,
|
| 150 |
+
target_hidden: Optional[torch.Tensor] = None,
|
| 151 |
+
hidden_states: Optional[torch.Tensor] = None,
|
| 152 |
+
attention_mask: Optional[torch.Tensor] = None,
|
| 153 |
+
position_ids: Optional[torch.LongTensor] = None,
|
| 154 |
+
past_key_value: Optional[Cache] = None,
|
| 155 |
+
output_attentions: Optional[bool] = False,
|
| 156 |
+
use_cache: Optional[bool] = False,
|
| 157 |
+
cache_position: Optional[torch.LongTensor] = None,
|
| 158 |
+
position_embeddings: Optional[
|
| 159 |
+
Tuple[torch.Tensor, torch.Tensor]
|
| 160 |
+
] = None, # necessary, but kept here for BC
|
| 161 |
+
**kwargs: Unpack[FlashAttentionKwargs],
|
| 162 |
+
) -> Tuple[
|
| 163 |
+
torch.FloatTensor, Optional[Tuple[torch.FloatTensor, torch.FloatTensor]]
|
| 164 |
+
]:
|
| 165 |
+
residual = hidden_states
|
| 166 |
+
hidden_states = self.input_layernorm(hidden_states)
|
| 167 |
+
hidden_states = self.self_attn(
|
| 168 |
+
hidden_states=hidden_states,
|
| 169 |
+
target_hidden=target_hidden,
|
| 170 |
+
attention_mask=attention_mask,
|
| 171 |
+
position_ids=position_ids,
|
| 172 |
+
past_key_values=past_key_value,
|
| 173 |
+
output_attentions=output_attentions,
|
| 174 |
+
use_cache=use_cache,
|
| 175 |
+
cache_position=cache_position,
|
| 176 |
+
position_embeddings=position_embeddings,
|
| 177 |
+
**kwargs,
|
| 178 |
+
)[0]
|
| 179 |
+
hidden_states = residual + hidden_states
|
| 180 |
+
residual = hidden_states
|
| 181 |
+
hidden_states = self.post_attention_layernorm(hidden_states)
|
| 182 |
+
hidden_states = self.mlp(hidden_states)
|
| 183 |
+
hidden_states = residual + hidden_states
|
| 184 |
+
return hidden_states
|
| 185 |
+
|
| 186 |
+
|
| 187 |
+
def build_target_layer_ids(num_target_layers: int, num_draft_layers: int):
|
| 188 |
+
if num_draft_layers == 1:
|
| 189 |
+
return [(num_target_layers // 2)]
|
| 190 |
+
start = 1
|
| 191 |
+
end = num_target_layers - 3
|
| 192 |
+
span = end - start
|
| 193 |
+
target_layer_ids = [
|
| 194 |
+
int(round(start + (i * span) / (num_draft_layers - 1)))
|
| 195 |
+
for i in range(num_draft_layers)
|
| 196 |
+
]
|
| 197 |
+
return target_layer_ids
|
| 198 |
+
|
| 199 |
+
|
| 200 |
+
def extract_context_feature(
|
| 201 |
+
hidden_states: list[torch.Tensor],
|
| 202 |
+
layer_ids: Optional[list[int]],
|
| 203 |
+
) -> torch.Tensor:
|
| 204 |
+
offset = 1
|
| 205 |
+
selected_states = []
|
| 206 |
+
for layer_id in layer_ids:
|
| 207 |
+
selected_states.append(hidden_states[layer_id + offset])
|
| 208 |
+
target_hidden = torch.cat(selected_states, dim=-1)
|
| 209 |
+
return target_hidden
|
| 210 |
+
|
| 211 |
+
|
| 212 |
+
class DFlashDraftModel(Qwen3PreTrainedModel):
|
| 213 |
+
config_class = Qwen3Config
|
| 214 |
+
_no_split_modules = ["Qwen3DFlashDecoderLayer"]
|
| 215 |
+
|
| 216 |
+
def __init__(self, config) -> None:
|
| 217 |
+
super().__init__(config)
|
| 218 |
+
self.config = config
|
| 219 |
+
self.layers = nn.ModuleList(
|
| 220 |
+
[
|
| 221 |
+
Qwen3DFlashDecoderLayer(config, layer_idx)
|
| 222 |
+
for layer_idx in range(config.num_hidden_layers)
|
| 223 |
+
]
|
| 224 |
+
)
|
| 225 |
+
dflash_config = getattr(config, "dflash_config", {}) or {}
|
| 226 |
+
self.target_layer_ids = dflash_config.get(
|
| 227 |
+
"target_layer_ids",
|
| 228 |
+
build_target_layer_ids(config.num_target_layers, config.num_hidden_layers),
|
| 229 |
+
)
|
| 230 |
+
self.norm = Qwen3RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
|
| 231 |
+
self.rotary_emb = Qwen3RotaryEmbedding(config)
|
| 232 |
+
self.fc = nn.Linear(
|
| 233 |
+
len(self.target_layer_ids) * config.hidden_size,
|
| 234 |
+
config.hidden_size,
|
| 235 |
+
bias=False,
|
| 236 |
+
)
|
| 237 |
+
self.hidden_norm = Qwen3RMSNorm(config.hidden_size, eps=config.rms_norm_eps)
|
| 238 |
+
self.block_size = config.block_size
|
| 239 |
+
self.mask_token_id = dflash_config.get("mask_token_id", None)
|
| 240 |
+
self.post_init()
|
| 241 |
+
|
| 242 |
+
def forward(
|
| 243 |
+
self,
|
| 244 |
+
position_ids: torch.LongTensor,
|
| 245 |
+
attention_mask: Optional[torch.Tensor] = None,
|
| 246 |
+
noise_embedding: Optional[torch.Tensor] = None,
|
| 247 |
+
target_hidden: Optional[torch.Tensor] = None,
|
| 248 |
+
past_key_values: Optional[Cache] = None,
|
| 249 |
+
use_cache: bool = False,
|
| 250 |
+
**kwargs,
|
| 251 |
+
) -> CausalLMOutputWithPast:
|
| 252 |
+
hidden_states = noise_embedding
|
| 253 |
+
target_hidden = self.hidden_norm(self.fc(target_hidden))
|
| 254 |
+
position_embeddings = self.rotary_emb(hidden_states, position_ids)
|
| 255 |
+
for layer in self.layers:
|
| 256 |
+
hidden_states = layer(
|
| 257 |
+
hidden_states=hidden_states,
|
| 258 |
+
target_hidden=target_hidden,
|
| 259 |
+
attention_mask=attention_mask,
|
| 260 |
+
position_ids=position_ids,
|
| 261 |
+
past_key_value=past_key_values,
|
| 262 |
+
use_cache=use_cache,
|
| 263 |
+
position_embeddings=position_embeddings,
|
| 264 |
+
**kwargs,
|
| 265 |
+
)
|
| 266 |
+
return self.norm(hidden_states)
|
| 267 |
+
|
| 268 |
+
@torch.inference_mode()
|
| 269 |
+
def spec_generate(
|
| 270 |
+
self,
|
| 271 |
+
target: nn.Module,
|
| 272 |
+
input_ids: torch.LongTensor,
|
| 273 |
+
max_new_tokens: int,
|
| 274 |
+
stop_token_ids: list[int],
|
| 275 |
+
temperature: float,
|
| 276 |
+
):
|
| 277 |
+
self.eval()
|
| 278 |
+
num_input_tokens = input_ids.shape[1]
|
| 279 |
+
max_length = num_input_tokens + max_new_tokens
|
| 280 |
+
|
| 281 |
+
block_size = self.block_size
|
| 282 |
+
output_ids = torch.full(
|
| 283 |
+
(1, max_length + block_size),
|
| 284 |
+
self.mask_token_id,
|
| 285 |
+
dtype=torch.long,
|
| 286 |
+
device=target.device,
|
| 287 |
+
)
|
| 288 |
+
position_ids = torch.arange(
|
| 289 |
+
output_ids.shape[1], device=target.device
|
| 290 |
+
).unsqueeze(0)
|
| 291 |
+
|
| 292 |
+
past_key_values_target = DynamicCache()
|
| 293 |
+
past_key_values_draft = DynamicCache()
|
| 294 |
+
|
| 295 |
+
# Prefill stage
|
| 296 |
+
output = target(
|
| 297 |
+
input_ids,
|
| 298 |
+
position_ids=position_ids[:, :num_input_tokens],
|
| 299 |
+
past_key_values=past_key_values_target,
|
| 300 |
+
use_cache=True,
|
| 301 |
+
logits_to_keep=1,
|
| 302 |
+
output_hidden_states=True,
|
| 303 |
+
)
|
| 304 |
+
|
| 305 |
+
output_ids[:, :num_input_tokens] = input_ids
|
| 306 |
+
output_ids[:, num_input_tokens : num_input_tokens + 1] = sample(
|
| 307 |
+
output.logits, temperature
|
| 308 |
+
)
|
| 309 |
+
target_hidden = extract_context_feature(
|
| 310 |
+
output.hidden_states, self.target_layer_ids
|
| 311 |
+
)
|
| 312 |
+
|
| 313 |
+
# Decode stage
|
| 314 |
+
acceptance_lengths = []
|
| 315 |
+
start = input_ids.shape[1]
|
| 316 |
+
while start < max_length:
|
| 317 |
+
block_output_ids = output_ids[:, start : start + block_size].clone()
|
| 318 |
+
block_position_ids = position_ids[:, start : start + block_size]
|
| 319 |
+
noise_embedding = target.model.embed_tokens(block_output_ids)
|
| 320 |
+
draft_logits = target.lm_head(
|
| 321 |
+
self(
|
| 322 |
+
target_hidden=target_hidden,
|
| 323 |
+
noise_embedding=noise_embedding,
|
| 324 |
+
position_ids=position_ids[
|
| 325 |
+
:, past_key_values_draft.get_seq_length() : start + block_size
|
| 326 |
+
],
|
| 327 |
+
past_key_values=past_key_values_draft,
|
| 328 |
+
use_cache=True,
|
| 329 |
+
is_causal=False,
|
| 330 |
+
)[:, -block_size + 1 :, :]
|
| 331 |
+
)
|
| 332 |
+
past_key_values_draft.crop(start)
|
| 333 |
+
block_output_ids[:, 1:] = sample(draft_logits)
|
| 334 |
+
|
| 335 |
+
output = target(
|
| 336 |
+
block_output_ids,
|
| 337 |
+
position_ids=block_position_ids,
|
| 338 |
+
past_key_values=past_key_values_target,
|
| 339 |
+
use_cache=True,
|
| 340 |
+
output_hidden_states=True,
|
| 341 |
+
)
|
| 342 |
+
|
| 343 |
+
posterior = sample(output.logits, temperature)
|
| 344 |
+
acceptance_length = (
|
| 345 |
+
(block_output_ids[:, 1:] == posterior[:, :-1])
|
| 346 |
+
.cumprod(dim=1)
|
| 347 |
+
.sum(dim=1)[0]
|
| 348 |
+
.item()
|
| 349 |
+
)
|
| 350 |
+
output_ids[:, start : start + acceptance_length + 1] = block_output_ids[
|
| 351 |
+
:, : acceptance_length + 1
|
| 352 |
+
]
|
| 353 |
+
output_ids[:, start + acceptance_length + 1] = posterior[
|
| 354 |
+
:, acceptance_length
|
| 355 |
+
]
|
| 356 |
+
start += acceptance_length + 1
|
| 357 |
+
past_key_values_target.crop(start)
|
| 358 |
+
target_hidden = extract_context_feature(
|
| 359 |
+
output.hidden_states, self.target_layer_ids
|
| 360 |
+
)[:, : acceptance_length + 1, :]
|
| 361 |
+
acceptance_lengths.append(acceptance_length + 1)
|
| 362 |
+
if stop_token_ids is not None and any(
|
| 363 |
+
stop_token_id in output_ids[:, num_input_tokens:]
|
| 364 |
+
for stop_token_id in stop_token_ids
|
| 365 |
+
):
|
| 366 |
+
break
|
| 367 |
+
output_ids = output_ids[:, :max_length]
|
| 368 |
+
output_ids = output_ids[:, output_ids[0] != self.mask_token_id]
|
| 369 |
+
if stop_token_ids is not None:
|
| 370 |
+
stop_token_ids = torch.tensor(stop_token_ids, device=output_ids.device)
|
| 371 |
+
stop_token_indices = torch.isin(
|
| 372 |
+
output_ids[0][num_input_tokens:], stop_token_ids
|
| 373 |
+
).nonzero(as_tuple=True)[0]
|
| 374 |
+
if stop_token_indices.numel() > 0:
|
| 375 |
+
output_ids = output_ids[
|
| 376 |
+
:, : num_input_tokens + stop_token_indices[0] + 1
|
| 377 |
+
]
|
| 378 |
+
|
| 379 |
+
return output_ids
|
dflash/dflash_draft_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:94d9c02c17e0b469f88699e98424825ebe13a17f07eb3b86727b5e0c8143d287
|
| 3 |
+
size 2936121080
|
dflash/mask_embedding.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b35b379fe0497ffdc0d6407f502622237d9346e0d03f457ec574be60f6c2cee0
|
| 3 |
+
size 9882
|
dflash/model.safetensors.index.json
ADDED
|
@@ -0,0 +1,70 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_size": 2936114304
|
| 4 |
+
},
|
| 5 |
+
"weight_map": {
|
| 6 |
+
"fc.weight": "dflash_draft_model.safetensors",
|
| 7 |
+
"hidden_norm.weight": "dflash_draft_model.safetensors",
|
| 8 |
+
"norm.weight": "dflash_draft_model.safetensors",
|
| 9 |
+
"layers.0.input_layernorm.weight": "dflash_draft_model.safetensors",
|
| 10 |
+
"layers.0.post_attention_layernorm.weight": "dflash_draft_model.safetensors",
|
| 11 |
+
"layers.0.self_attn.q_norm.weight": "dflash_draft_model.safetensors",
|
| 12 |
+
"layers.0.self_attn.k_norm.weight": "dflash_draft_model.safetensors",
|
| 13 |
+
"layers.0.self_attn.q_proj.weight": "dflash_draft_model.safetensors",
|
| 14 |
+
"layers.0.self_attn.k_proj.weight": "dflash_draft_model.safetensors",
|
| 15 |
+
"layers.0.self_attn.v_proj.weight": "dflash_draft_model.safetensors",
|
| 16 |
+
"layers.0.self_attn.o_proj.weight": "dflash_draft_model.safetensors",
|
| 17 |
+
"layers.0.mlp.gate_proj.weight": "dflash_draft_model.safetensors",
|
| 18 |
+
"layers.0.mlp.up_proj.weight": "dflash_draft_model.safetensors",
|
| 19 |
+
"layers.0.mlp.down_proj.weight": "dflash_draft_model.safetensors",
|
| 20 |
+
"layers.0.self_attn.attention_sink_bias": "dflash_draft_model.safetensors",
|
| 21 |
+
"layers.1.input_layernorm.weight": "dflash_draft_model.safetensors",
|
| 22 |
+
"layers.1.post_attention_layernorm.weight": "dflash_draft_model.safetensors",
|
| 23 |
+
"layers.1.self_attn.q_norm.weight": "dflash_draft_model.safetensors",
|
| 24 |
+
"layers.1.self_attn.k_norm.weight": "dflash_draft_model.safetensors",
|
| 25 |
+
"layers.1.self_attn.q_proj.weight": "dflash_draft_model.safetensors",
|
| 26 |
+
"layers.1.self_attn.k_proj.weight": "dflash_draft_model.safetensors",
|
| 27 |
+
"layers.1.self_attn.v_proj.weight": "dflash_draft_model.safetensors",
|
| 28 |
+
"layers.1.self_attn.o_proj.weight": "dflash_draft_model.safetensors",
|
| 29 |
+
"layers.1.mlp.gate_proj.weight": "dflash_draft_model.safetensors",
|
| 30 |
+
"layers.1.mlp.up_proj.weight": "dflash_draft_model.safetensors",
|
| 31 |
+
"layers.1.mlp.down_proj.weight": "dflash_draft_model.safetensors",
|
| 32 |
+
"layers.1.self_attn.attention_sink_bias": "dflash_draft_model.safetensors",
|
| 33 |
+
"layers.2.input_layernorm.weight": "dflash_draft_model.safetensors",
|
| 34 |
+
"layers.2.post_attention_layernorm.weight": "dflash_draft_model.safetensors",
|
| 35 |
+
"layers.2.self_attn.q_norm.weight": "dflash_draft_model.safetensors",
|
| 36 |
+
"layers.2.self_attn.k_norm.weight": "dflash_draft_model.safetensors",
|
| 37 |
+
"layers.2.self_attn.q_proj.weight": "dflash_draft_model.safetensors",
|
| 38 |
+
"layers.2.self_attn.k_proj.weight": "dflash_draft_model.safetensors",
|
| 39 |
+
"layers.2.self_attn.v_proj.weight": "dflash_draft_model.safetensors",
|
| 40 |
+
"layers.2.self_attn.o_proj.weight": "dflash_draft_model.safetensors",
|
| 41 |
+
"layers.2.mlp.gate_proj.weight": "dflash_draft_model.safetensors",
|
| 42 |
+
"layers.2.mlp.up_proj.weight": "dflash_draft_model.safetensors",
|
| 43 |
+
"layers.2.mlp.down_proj.weight": "dflash_draft_model.safetensors",
|
| 44 |
+
"layers.2.self_attn.attention_sink_bias": "dflash_draft_model.safetensors",
|
| 45 |
+
"layers.3.input_layernorm.weight": "dflash_draft_model.safetensors",
|
| 46 |
+
"layers.3.post_attention_layernorm.weight": "dflash_draft_model.safetensors",
|
| 47 |
+
"layers.3.self_attn.q_norm.weight": "dflash_draft_model.safetensors",
|
| 48 |
+
"layers.3.self_attn.k_norm.weight": "dflash_draft_model.safetensors",
|
| 49 |
+
"layers.3.self_attn.q_proj.weight": "dflash_draft_model.safetensors",
|
| 50 |
+
"layers.3.self_attn.k_proj.weight": "dflash_draft_model.safetensors",
|
| 51 |
+
"layers.3.self_attn.v_proj.weight": "dflash_draft_model.safetensors",
|
| 52 |
+
"layers.3.self_attn.o_proj.weight": "dflash_draft_model.safetensors",
|
| 53 |
+
"layers.3.mlp.gate_proj.weight": "dflash_draft_model.safetensors",
|
| 54 |
+
"layers.3.mlp.up_proj.weight": "dflash_draft_model.safetensors",
|
| 55 |
+
"layers.3.mlp.down_proj.weight": "dflash_draft_model.safetensors",
|
| 56 |
+
"layers.3.self_attn.attention_sink_bias": "dflash_draft_model.safetensors",
|
| 57 |
+
"layers.4.input_layernorm.weight": "dflash_draft_model.safetensors",
|
| 58 |
+
"layers.4.post_attention_layernorm.weight": "dflash_draft_model.safetensors",
|
| 59 |
+
"layers.4.self_attn.q_norm.weight": "dflash_draft_model.safetensors",
|
| 60 |
+
"layers.4.self_attn.k_norm.weight": "dflash_draft_model.safetensors",
|
| 61 |
+
"layers.4.self_attn.q_proj.weight": "dflash_draft_model.safetensors",
|
| 62 |
+
"layers.4.self_attn.k_proj.weight": "dflash_draft_model.safetensors",
|
| 63 |
+
"layers.4.self_attn.v_proj.weight": "dflash_draft_model.safetensors",
|
| 64 |
+
"layers.4.self_attn.o_proj.weight": "dflash_draft_model.safetensors",
|
| 65 |
+
"layers.4.mlp.gate_proj.weight": "dflash_draft_model.safetensors",
|
| 66 |
+
"layers.4.mlp.up_proj.weight": "dflash_draft_model.safetensors",
|
| 67 |
+
"layers.4.mlp.down_proj.weight": "dflash_draft_model.safetensors",
|
| 68 |
+
"layers.4.self_attn.attention_sink_bias": "dflash_draft_model.safetensors"
|
| 69 |
+
}
|
| 70 |
+
}
|
generation_config.json
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"bos_token_id": 151643,
|
| 3 |
+
"do_sample": false,
|
| 4 |
+
"eos_token_id": [151643, 151645, 151672],
|
| 5 |
+
"temperature": 1.0,
|
| 6 |
+
"top_p": 0.95,
|
| 7 |
+
"max_new_tokens": 2048,
|
| 8 |
+
"transformers_version": "4.37.0"
|
| 9 |
+
}
|
merges.txt
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
model.safetensors.index.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:54c24ef36b5919dcc02a0cfa751f46dfed56d3a0a223b145a6a67352a6436de5
|
| 3 |
+
size 13979137
|
model_mtp.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:01bdcd4f6f964e310ef4aceec6db2c16be96b00ad2ecb93a7f0f0effe459ab56
|
| 3 |
+
size 1189405992
|
model_pp0_ep0_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e4cb5d053c0ef0059714dca007cdf5c8bc7208ba039439c89598ef82ebff6e5d
|
| 3 |
+
size 13535676488
|
model_pp0_ep10_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a1f79a7ffacbf3b25b2c8dcda0421998a9cf5a682276b2b091e4ab8b526d5933
|
| 3 |
+
size 2661557352
|
model_pp0_ep11_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:797515cfe2149a8f4cc4cec7679a92fabbe2b5d47227f31ff75f2135b7e58430
|
| 3 |
+
size 2661557352
|
model_pp0_ep12_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:138f0e551937b308b7fc33dc28424757baf85aecba5d2124772ae96e63c9acc6
|
| 3 |
+
size 2661557352
|
model_pp0_ep13_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:eb1c76e77fac4bd26f12739ffb6603187585c1703a46eb27deca79fa3ce55247
|
| 3 |
+
size 2661557352
|
model_pp0_ep14_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4a9ffb6549aa8ce07aa715752091938d14004d55092b00c9e9db9a402095a993
|
| 3 |
+
size 2661557352
|
model_pp0_ep15_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f9a1a7318f5339c02aff45836d2fbfe473d89025f8fc1da9127080df90925f04
|
| 3 |
+
size 2661557352
|
model_pp0_ep16_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8796b6271d755ca1306cfab3bedb6264f1fd72eef6d0d7dff404b8b4711dda03
|
| 3 |
+
size 2661557352
|
model_pp0_ep17_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6859251656c31a240bd14c1dffbce11be992cb62862704ba9a3fc907c56174aa
|
| 3 |
+
size 2661557352
|
model_pp0_ep18_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6729ac6f3cf04f554632abac98408c2139d91cc23fe5fed608aa1e50e203f667
|
| 3 |
+
size 2661557352
|
model_pp0_ep19_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:eade352e093a12c06c3144e23266a852639be8ab2c6b42a4fd7f9c2b0ee820cb
|
| 3 |
+
size 2661557352
|
model_pp0_ep1_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e7c6fbf97ac1e43e9bd9cf6c0d7a49208f1d7d5184b88350ae8b2d43a94ed449
|
| 3 |
+
size 2661555096
|
model_pp0_ep20_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6adf819c457c21e84d2b197f6fdc3a1a538ebe5110e8902be67b568c52a6cc64
|
| 3 |
+
size 2661557352
|
model_pp0_ep21_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5ffe5d134f10e80a55d1df61b26b8586e098aa55c031b30bda826b0fb637006d
|
| 3 |
+
size 2661557352
|
model_pp0_ep22_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8c8078ea96fe082b9ca42ba070598072961cfd027e3e79d858c411bea98a49d8
|
| 3 |
+
size 2661557352
|
model_pp0_ep23_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0c919297f93f05fff2bfc13839053351b7c09bb86ebef120893ab87424792643
|
| 3 |
+
size 2661557352
|
model_pp0_ep24_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a499984ace7caaa91d6a28b9735a6517ed009ae940651b14b8b0836dfa11f291
|
| 3 |
+
size 2661557352
|
model_pp0_ep25_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b93968feba089dcf7beff09f35006d90594d7066b90fe27d50853acca40b4bc5
|
| 3 |
+
size 2661559608
|
model_pp0_ep26_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:de8496820c0fdf7047ee96dc28e8f33954c9bdc13f5fe999370ee7ed17e4f53a
|
| 3 |
+
size 2661559608
|
model_pp0_ep27_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e5539cfcc59d302022a4db93b32c77b9930369f776a8062c2e88a365f9b996c3
|
| 3 |
+
size 2661559608
|
model_pp0_ep28_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3f9dc0618b425346fc7aac4390c7026343ffd03dc50631935552eef739f99a1f
|
| 3 |
+
size 2661559608
|
model_pp0_ep29_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dee7d228c36384a0a7dff029c855634279dcb93a365e999433bde6d1b57b8e6f
|
| 3 |
+
size 2661559608
|
model_pp0_ep2_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ed31e61c0d74a907e7b15e9ad4a3b18c0b57edc5478bf2ab63da7bb3ba8ceabb
|
| 3 |
+
size 2661556224
|
model_pp0_ep30_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:129df6e147809b0e82068ea5e038123d30ff218b27902c5b49a35fae14b57350
|
| 3 |
+
size 2661559608
|
model_pp0_ep31_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:47d072ca36ae4fb60b4ada54c4b178e4e5df9835e15dc89de51b2270bf8b6393
|
| 3 |
+
size 2661559608
|
model_pp0_ep32_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6f4514472384bb738d5ef5155d208043902a8b0a3186fe9cb5595634bad5f24b
|
| 3 |
+
size 2661559608
|
model_pp0_ep33_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f8c851daf063e14d09b276c214de12e997e5461a6039030b978a6b0430ebe220
|
| 3 |
+
size 2661559608
|
model_pp0_ep34_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c8d130b9f112dc21c9af60e9c08fe8ab7de8baecb4d6ae550d69bd236224a311
|
| 3 |
+
size 2661559608
|
model_pp0_ep35_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9fc1281c2caed89385b6f43f4cf50137f9dc9da4ac8acd9f3fbbaf0a66c86a54
|
| 3 |
+
size 2661559608
|
model_pp0_ep36_shard0.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f480ce0d464a5fa3f2971d2f5bf45452d0ed11bb0fd41db84432f49fe8e4adce
|
| 3 |
+
size 2661559608
|