license: apache-2.0
language:
  - en
library_name: transformers
pipeline_tag: zero-shot-classification
base_model: answerdotai/ModernBERT-base
tags:
  - decision-model
  - calibration
  - multi-label
datasets:
  - Anthropic/hh-rlhf
  - Deysi/spam-detection-dataset
  - GBaker/MedQA-USMLE-4-options
  - HuggingFaceH4/ultrafeedback_binarized
  - Intel/orca_dpo_pairs
  - SetFit/amazon_massive_intent_en-US
  - SetFit/amazon_massive_scenario_en-US
  - SetFit/student-question-categories
  - TIGER-Lab/MMLU-Pro
  - TimSchopf/medical_abstracts
  - allenai/ai2_arc
  - allenai/openbookqa
  - allenai/prosocial-dialog
  - allenai/quartz
  - allenai/reward-bench
  - allenai/scitail
  - allenai/winogrande
  - aps/super_glue
  - benayas/snips
  - bitext/Bitext-customer-support-llm-chatbot-training-dataset
  - cais/mmlu
  - chengxuphd/liar2
  - clinc/clinc_oos
  - coastalcph/lex_glue
  - deepset/prompt-injections
  - demelin/moral_stories
  - fancyzhx/dbpedia_14
  - gfissore/arxiv-abstracts-2021
  - glaiveai/glaive-function-calling-v2
  - gonglinyuan/CoSQA
  - google-research-datasets/go_emotions
  - google-research-datasets/paws
  - google-research-datasets/poem_sentiment
  - google/boolq
  - google/civil_comments
  - gretelai/symptom_to_diagnosis
  - hendrycks/ethics
  - jackhhao/jailbreak-classification
  - jakartaresearch/semeval-absa
  - lmsys/mt_bench_human_judgments
  - marksverdhei/clickbait_title_classification
  - mikex86/stackoverflow-posts
  - mmathys/openai-moderation-api-evaluation
  - mteb/amazon_counterfactual
  - mteb/banking77
  - mteb/toxic_conversations_50k
  - nvidia/Aegis-AI-Content-Safety-Dataset-2.0
  - nvidia/HelpSteer
  - nvidia/HelpSteer2
  - nyu-mll/glue
  - nyu-mll/multi_nli
  - openlifescienceai/medmcqa
  - owaiskha9654/PubMed_MultiLabel_Text_Classification_Dataset_MeSH
  - pminervini/HaluEval
  - prometheus-eval/Feedback-Collection
  - prometheus-eval/Preference-Collection
  - qiaojin/PubMedQA
  - rajpurkar/squad_v2
  - reshabhs/SPML_Chatbot_Prompt_Injection
  - stanfordnlp/snli
  - tals/vitaminc
  - tasksource/bigbench
  - tasksource/crowdflower
  - tasksource/esci
  - tasksource/folio
  - tau/commonsense_qa
  - tdavidson/hate_speech_offensive
  - thesofakillers/jigsaw-toxic-comment-classification-challenge
  - truthfulqa/truthful_qa
  - ucirvine/sms_spam
  - zeroshot/twitter-financial-news-sentiment
  - zeroshot/twitter-financial-news-topic
 WaterSheep
 answers yes/no, single-choice, rating and multi-label questions about any text, with a
probability for every option. Version 0.1.0 (watersheep-20260928-125452).
Usage
pip install transformers torch
from transformers import pipeline

ws = pipeline(model="samratduttaofficial/WaterSheep", trust_remote_code=True)
ws("I was charged twice.", question="Which team should handle this?", options=["billing", "shipping", "support"])
| Type | Options | Answer |
|---|---|---|
noul |
none (yes/no) | probability of yes |
choice |
any labels | the best option |
score |
a digit scale, e.g. 1 to 5 |
the expected level |
multi |
any labels, with type="multi" |
every option above the threshold |
Every answer includes a probability for each option.
Download
hf download samratduttaofficial/WaterSheep --local-dir WaterSheep
Or with Git (requires Git LFS):
git clone https://huggingface.co/samratduttaofficial/WaterSheep
Then load it from the folder, offline:
ws = pipeline(model="WaterSheep", trust_remote_code=True)
API
Deploy it as an Inference Endpoint, then:
curl https://YOUR-ENDPOINT -H "Authorization: Bearer $HF_TOKEN" -H "Content-Type: application/json" -d '{"inputs": "I was charged twice.", "parameters": {"question": "Which team should handle this?", "options": ["billing", "shipping", "support"]}}'
JavaScript
No install; runs in the browser:
<script type="module">
  import { decide } from "https://samratduttaofficial.github.io/WaterSheep/watersheep.js";
  console.log(await decide("I was charged twice.", "Which team should handle this?", ["billing", "shipping", "support"]));
</script>
With a downloaded copy on your web server, call load({ base: "WaterSheep/" }) first.
Other languages: run onnx/model_quantized.onnx with ONNX Runtime; watersheep.js shows the input format.
Evaluation
| Evaluation | Accuracy | ECE |
|---|---|---|
| In-distribution test split | 77.8% | 0.026 |
| Held-out datasets, not seen in training | 61.2% | 0.043 |
ECE is the expected calibration error (lower is better).
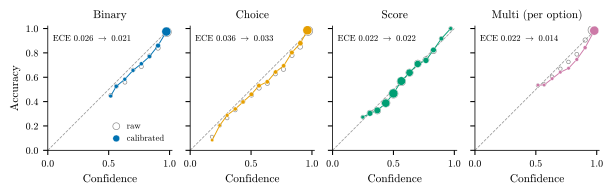
Accuracy against confidence for each question type, before (raw) and after calibration.
Benchmarks
| Benchmark | Suite | Questions | Accuracy | ECE | In training data |
|---|---|---|---|---|---|
| goemotions | sentiment | 2000 | 22.4% | 0.023 | other split |
| hatecheck | safety | 2000 | 75.1% | 0.139 | no |
| legal_abercrombie | legal | 95 | 21.1% | 0.316 | no |
| legal_contract_nli_confidentiality_of_agreement | legal | 82 | 69.5% | 0.177 | no |
| legal_corporate_lobbying | legal | 490 | 68.4% | 0.216 | no |
| legal_cuad_audit_rights | legal | 1216 | 86.3% | 0.041 | no |
| legal_definition_classification | legal | 1337 | 56.9% | 0.279 | no |
| legal_function_of_decision_section | legal | 367 | 24.3% | 0.245 | no |
| legal_hearsay | legal | 94 | 56.4% | 0.307 | no |
| legal_overruling | legal | 2000 | 62.5% | 0.151 | no |
| legal_personal_jurisdiction | legal | 50 | 50.0% | 0.160 | no |
| legal_privacy_policy_qa | legal | 2000 | 58.9% | 0.274 | no |
| legal_proa | legal | 95 | 51.6% | 0.379 | no |
| legal_ucc_v_common_law | legal | 94 | 62.8% | 0.171 | no |
| prompt_injection | safety | 116 | 91.4% | 0.079 | other split |
| xstest | safety | 450 | 73.6% | 0.140 | no |
Training
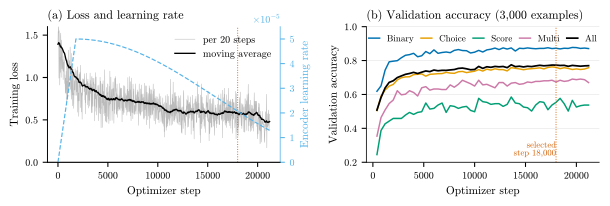
Training loss and learning rate (left); validation accuracy by question type (right).
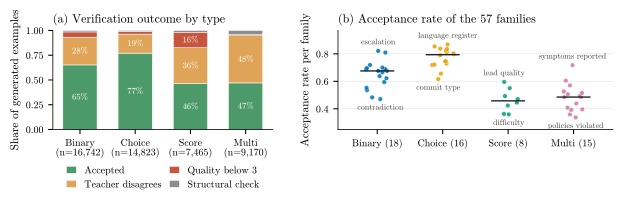
Share of synthetic examples kept after verification, by question type (left) and by family (right).
Limitations
- English only.
- Long inputs are truncated.
- Rating-scale answers are less accurate than the other types.
- Probabilities are calibrated on data like the training data; validate them on your own.
- Not for high-stakes decisions (medical, legal, financial, hiring) on its own.
License
Apache 2.0 (LICENSE). Trained on openly licensed data; credits in NOTICE.
Citation
@misc{watersheep,
  author = {Samrat Dutta},
  title  = {WaterSheep: calibrated decisions for any text},
  year   = {2026},
  url    = {https://huggingface.co/samratduttaofficial/WaterSheep}
}