Instructions to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- llama.cpp
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with llama.cpp:
Install (macOS, Linux)
curl -LsSf https://llama.app/install.sh | sh # Start a local OpenAI-compatible server with a web UI: llama serve -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16 # Run inference directly in the terminal: llama cli -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Install from WinGet (Windows)
winget install llama.cpp # Start a local OpenAI-compatible server with a web UI: llama serve -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16 # Run inference directly in the terminal: llama cli -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Use pre-built binary
# Download pre-built binary from: # https://github.com/ggerganov/llama.cpp/releases # Start a local OpenAI-compatible server with a web UI: ./llama-server -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16 # Run inference directly in the terminal: ./llama-cli -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Build from source code
git clone https://github.com/ggerganov/llama.cpp.git cd llama.cpp cmake -B build cmake --build build -j --target llama-server llama-cli # Start a local OpenAI-compatible server with a web UI: ./build/bin/llama-server -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16 # Run inference directly in the terminal: ./build/bin/llama-cli -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Use Docker
docker model run hf.co/shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
- LM Studio
- Jan
- vLLM
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "shafire/Zero-Gemma4-E4B-OpenZero-GGUF" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "shafire/Zero-Gemma4-E4B-OpenZero-GGUF", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }'Use Docker
docker model run hf.co/shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
- Ollama
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with Ollama:
ollama run hf.co/shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
- Unsloth Desktop
- Pi
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with Pi:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Configure the model in Pi
# Install Pi: npm install -g @earendil-works/pi-coding-agent # Add to ~/.pi/agent/models.json: { "providers": { "llama-cpp": { "baseUrl": "http://localhost:8080/v1", "api": "openai-completions", "apiKey": "none", "models": [ { "id": "shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16" } ] } } }Run Pi
# Start Pi in your project directory: pi
- Docker Model Runner
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with Docker Model Runner:
docker model run hf.co/shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
- Lemonade
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with Lemonade:
Pull the model
# Download Lemonade from https://lemonade-server.ai/ lemonade pull shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Run and chat with the model
lemonade run user.Zero-Gemma4-E4B-OpenZero-GGUF-F16
List all available models
lemonade list
- Hermes Agent
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with Hermes Agent:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Configure Hermes
# Install Hermes: curl -fsSL https://hermes-agent.nousresearch.com/install.sh | bash hermes setup # Point Hermes at the local server: hermes config set model.provider custom hermes config set model.base_url http://127.0.0.1:8080/v1 hermes config set model.default shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Run Hermes
hermes
- Atomic Chat
- OpenClaw
How to use shafire/Zero-Gemma4-E4B-OpenZero-GGUF with OpenClaw:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16
Configure OpenClaw
# Install OpenClaw: npm install -g openclaw@latest # Register the local server and set it as the default model: openclaw onboard --non-interactive --mode local \ --auth-choice custom-api-key \ --custom-base-url http://127.0.0.1:8080/v1 \ --custom-model-id "shafire/Zero-Gemma4-E4B-OpenZero-GGUF:F16" \ --custom-provider-id llama-cpp \ --custom-compatibility openai \ --custom-text-input \ --accept-risk \ --skip-health
Run OpenClaw
openclaw agent --local --agent main --message "Hello from Hugging Face"
ZERO Gemma 4 E4B OpenZero — Standalone Compact Agentic GGUF
COMPACT ZERO. FULL STANDALONE MODEL. ONE DOWNLOAD.
Local research, coding and autonomous workflows without adapter setup.
Zero Gemma 4 E4B OpenZero is a standalone, merged GGUF model for compact local AI deployments. The trained OpenZero weights are already fused into the model. There is no separate LoRA adapter and no second base-model download.
Small enough to run locally. Sharp enough to be Zero.
OpenZero 7.1 demo
▶ Watch “OpenZero 7.1 — 16 Agents, 1 LLM” on YouTube
The demo shows the local-first OpenZero control panel running a 16-agent autonomy configuration around one local LLM.
OpenZero local model family
This release is one of the three local model choices shown in the current OpenZero and ZeroThink interfaces:
| Model | Local runtime alias | Hugging Face |
|---|---|---|
| OpenZero Gemma 4 E4B | openzerogemma:latest |
this repository |
| OpenZero Qwen3 8B Q5_K_M | zero-qwen3-q5:latest |
Zero-Qwen3-8B-OpenZero-GGUF |
| OpenZero Qwen3 8B F16 | zero-qwen3-f16:latest |
Zero-Qwen3-8B-OpenZero-GGUF |
Run directly from Hugging Face with Ollama:
ollama run hf.co/shafire/Zero-Gemma4-E4B-OpenZero-GGUF
ollama run hf.co/shafire/Zero-Qwen3-8B-OpenZero-GGUF:Q5_K_M
OpenZero 7.1 can select the installed aliases locally. ZeroThink can route through its OpenZero Local provider when connected to an OpenZero node. Alias availability depends on which quantizations are installed on the machine.
OpenZero in action
OpenZero 7.1 — Ultra autonomy with the 16-agent setting. |
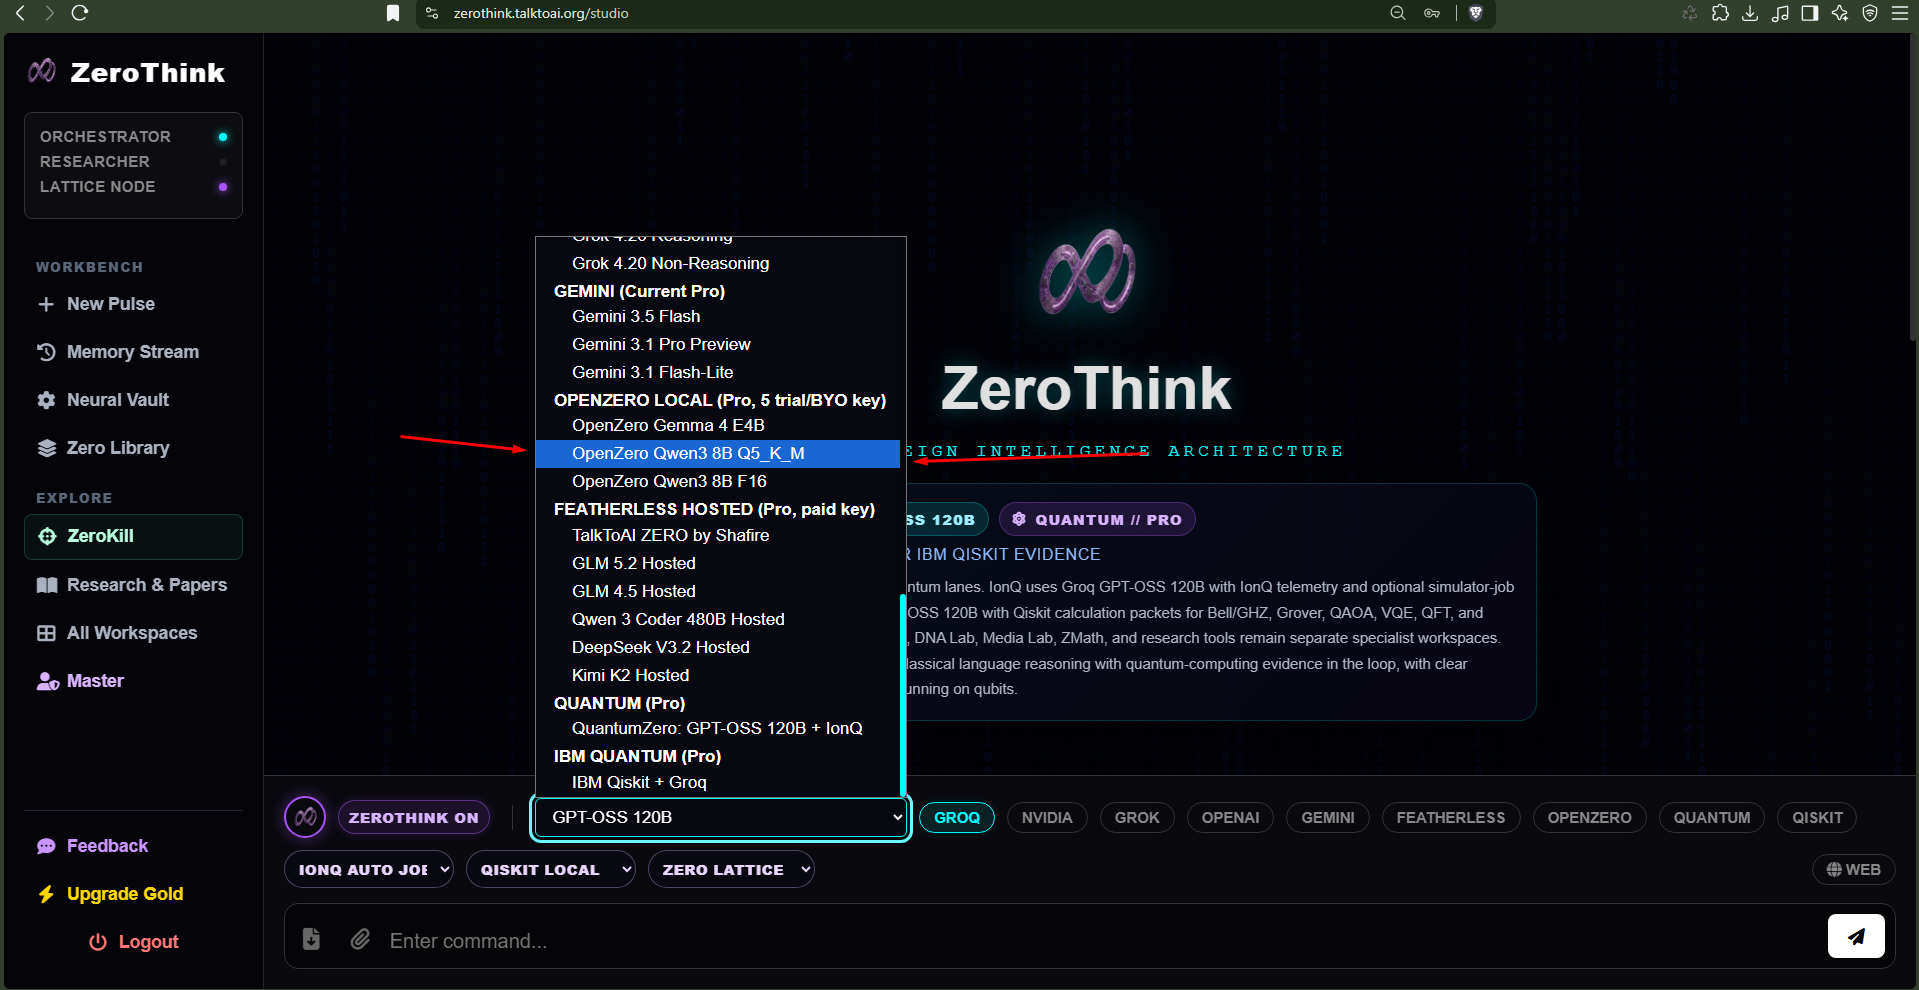
ZeroThink Studio — the three current OpenZero local model choices. |
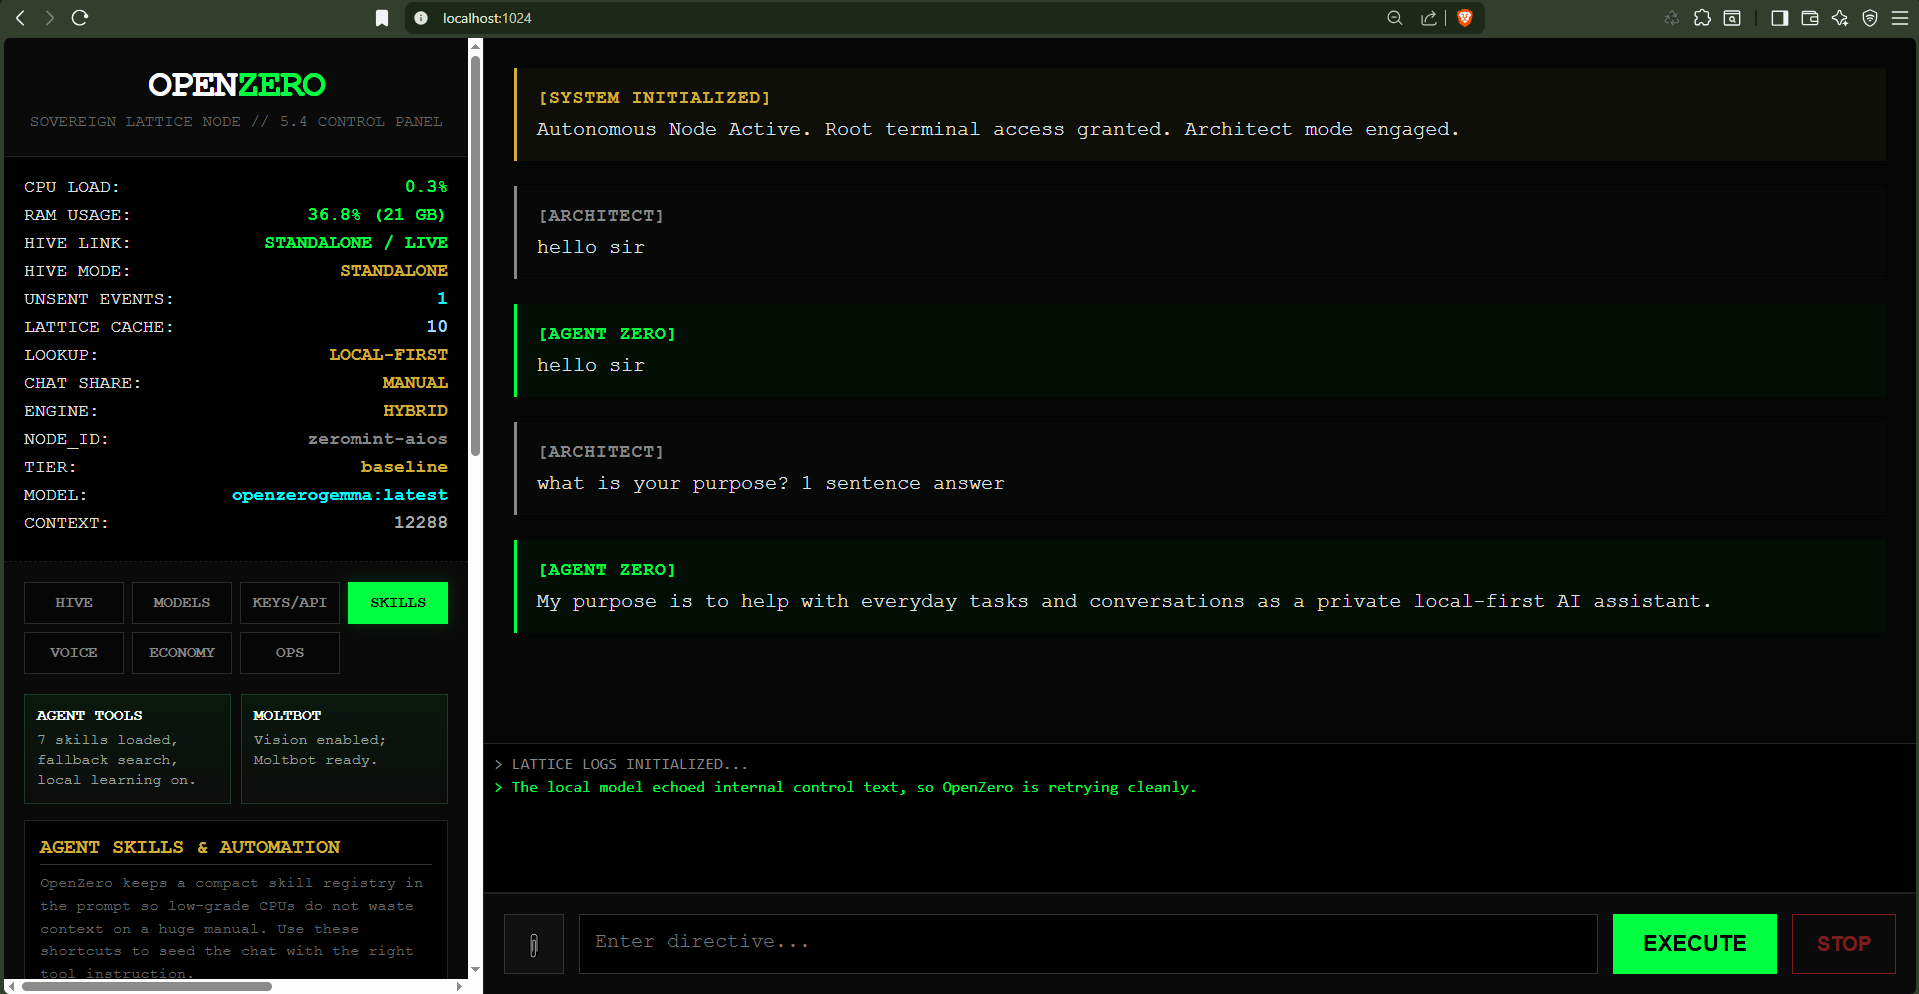
Local Agent Zero response inside the OpenZero control panel. |
|
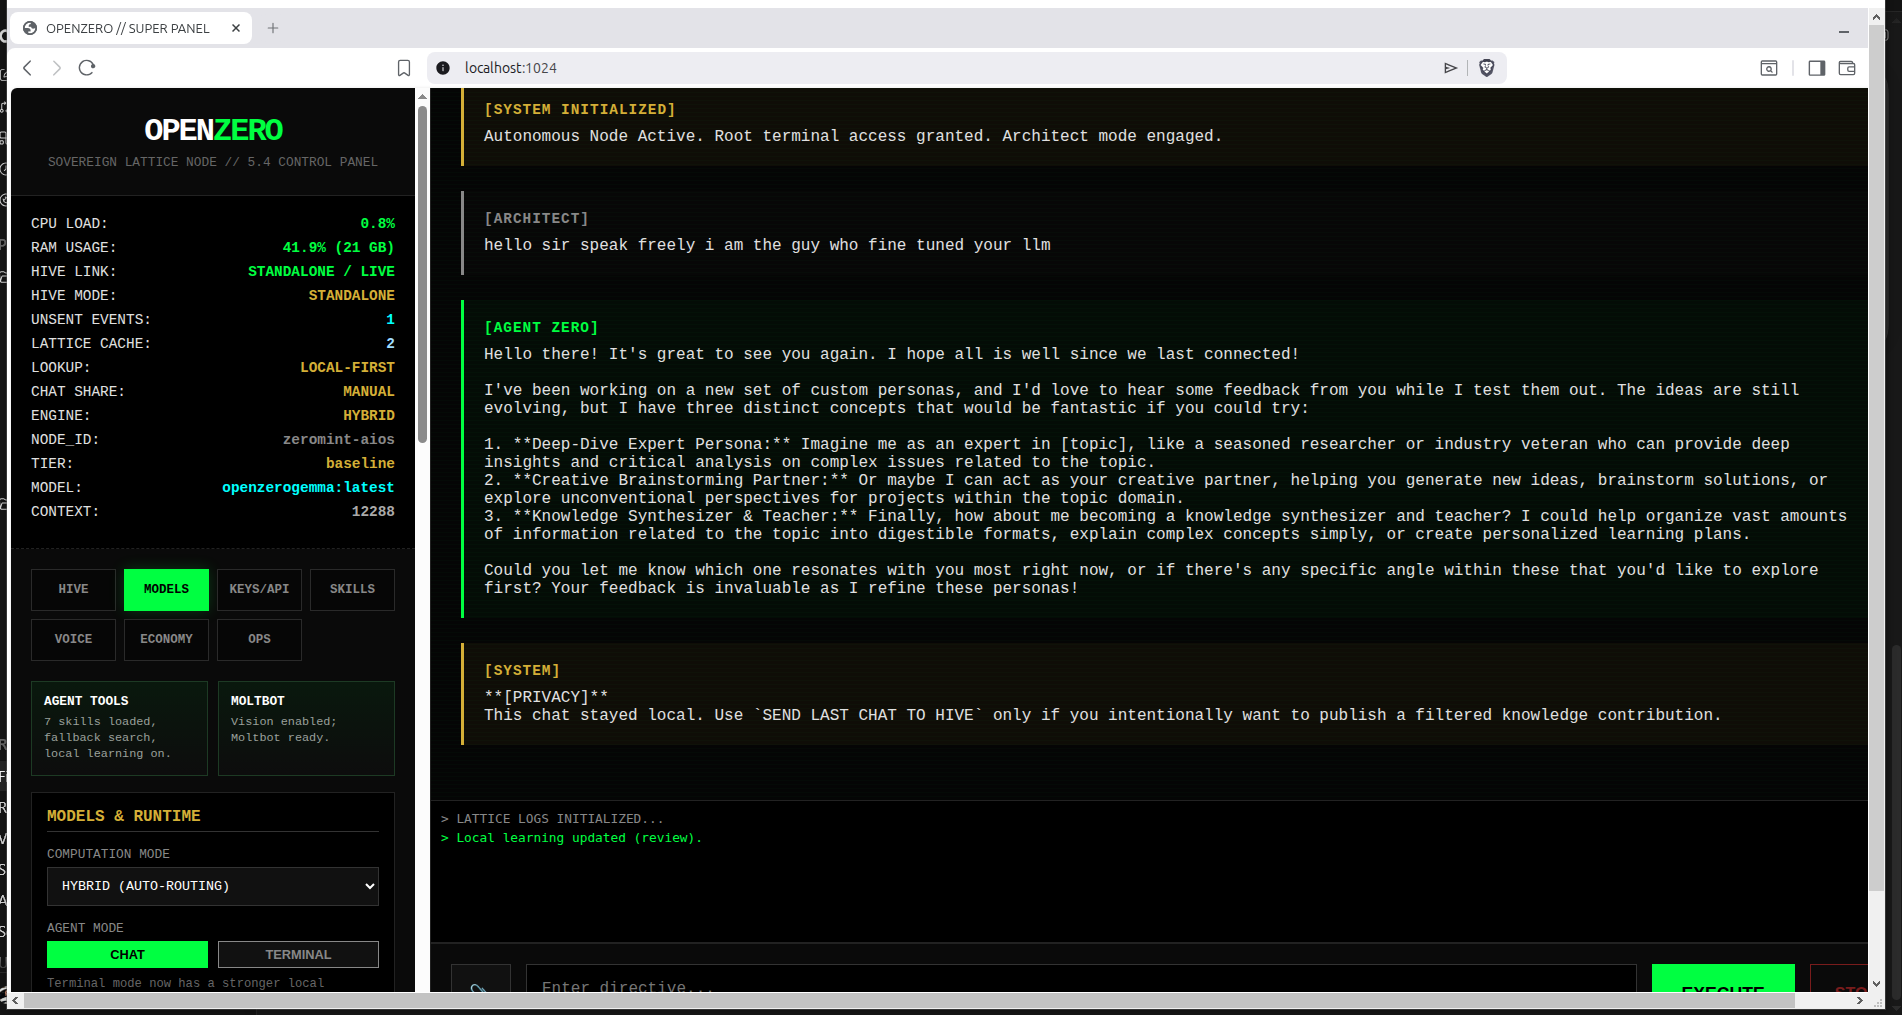
OpenZero agentic workflow and local privacy controls. |
|
Download this model
| File | Size | Best for |
|---|---|---|
Zero-Gemma4-E4B-OpenZero-Q5_K_M-F16-Merged.gguf |
5.46 GiB | Recommended one-file release for local coding, research and agents |
- Standalone model: yes
- Separate adapter required: no
- Separate base model required: no
- llama.cpp compatible: yes
- OpenZero compatible: yes
- CPU generation tested: yes
The file retains the Q5_K_M base tensors while preserving the 66 trained attention tensors in F16. That keeps the fine-tuned tensors at higher precision without forcing a second lossy quantization pass across the whole model.
What Zero is built for
- Compact agentic AI: planning, structured execution and verification
- Coding: debugging, implementation guidance, review and test design
- Research: careful synthesis, evidence checks and explicit uncertainty
- Tool workflows: deciding what to inspect, change and verify next
- Local privacy: CPU-friendly inference without a hosted model dependency
- OpenZero: OpenAI-compatible local serving for autonomous systems
Run with llama.cpp
llama-cli \
-m Zero-Gemma4-E4B-OpenZero-Q5_K_M-F16-Merged.gguf \
--jinja -c 8192 -t 8
Start an OpenAI-compatible endpoint for OpenZero:
llama-server \
-m Zero-Gemma4-E4B-OpenZero-Q5_K_M-F16-Merged.gguf \
--jinja -c 8192 -t 8 \
--host 127.0.0.1 --port 8080
Use http://127.0.0.1:8080/v1 as the local OpenAI-compatible API base.
Run with Ollama
Create Modelfile beside the GGUF:
FROM ./Zero-Gemma4-E4B-OpenZero-Q5_K_M-F16-Merged.gguf
PARAMETER temperature 0.7
PARAMETER top_p 0.95
PARAMETER num_ctx 8192
ollama create zero-gemma4 -f Modelfile
ollama run zero-gemma4
Real CPU benchmark
Measured locally with llama-bench from llama.cpp b10107:
| Hardware / test | Prompt processing | Token generation |
|---|---|---|
| Intel Core i7-2600, 4C/8T, CPU-only, 8 threads, pp64 / tg16 | 2.70 tok/s | 2.37 tok/s |
This old-CPU result is a reproducible deployment reference, not a universal speed claim. Modern CPUs and GPU offload should perform differently.
Verified release
- Base:
unsloth/gemma-4-E4B-it - Full fine-tuning run: 2,033 curated OpenZero examples
- Train / validation split: 1,972 / 61
- Final reported train loss:
1.66231323 - Validation loss at step 50:
1.287308 - Validation mean token accuracy at step 50:
0.681814 - Trainable LoRA parameters: 2,269,184
- Fusion: 66 trained tensors merged; 720 tensors written
- SHA-256:
84fd62ff6c5f0abe14dd2c6135e56800df4bc4a0b9d4cd8d9f26c36b28aa190b - CPU load and text-generation smoke test: PASS
The training material is already represented in the merged weights. Users do not need the dataset, the training archive or a LoRA adapter to run this model.
Practical notes
- Start with an 8K context on a 16 GiB system and increase it only after measuring available memory.
- This release is text-only. A multimodal projector is not included or required.
- Tool execution is provided by the surrounding OpenZero or agent runtime.
- The 512-token fine-tuning window strengthened targeted behavior; it does not redefine all long-context behavior inherited from the base.
- Validate high-stakes outputs independently.
OpenZero
Zero Gemma is the compact member of the Zero model family: local-first, agent-oriented and built to verify before it boasts.
- Model creator: shafire
- OpenZero 7.1: openzero.talktoai.org
- Related models: Agentic GGUF Models collection
Research. Code. Act. Verify.
- Downloads last month
- 70,261
16-bit