
Spaces:
Sleeping

Sleeping
Deploy MalwareGuard FastAPI backend clean
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .dockerignore +11 -0
- .gitattributes +5 -0
- Dockerfile +22 -0
- README.md +7 -4
- backend/app/__init__.py +1 -0
- backend/app/config.py +78 -0
- backend/app/main.py +232 -0
- backend/app/models/__init__.py +1 -0
- backend/app/models/feedback.py +126 -0
- backend/app/models/prediction.py +149 -0
- backend/app/models/url.py +68 -0
- backend/app/models/virustotal.py +72 -0
- backend/app/routers/__init__.py +1 -0
- backend/app/routers/chat.py +179 -0
- backend/app/routers/feedback.py +156 -0
- backend/app/routers/predict.py +205 -0
- backend/app/routers/upload.py +284 -0
- backend/app/routers/url.py +89 -0
- backend/app/routers/virustotal.py +167 -0
- backend/app/services/__init__.py +6 -0
- backend/app/services/ember_features.py +645 -0
- backend/app/services/feedback_service.py +474 -0
- backend/app/services/gemini_service.py +263 -0
- backend/app/services/malware_type_service.py +403 -0
- backend/app/services/ml_service.py +198 -0
- backend/app/services/shap_service.py +203 -0
- backend/app/services/url_feature_engineering.py +307 -0
- backend/app/services/url_service.py +334 -0
- backend/app/services/virustotal_service.py +226 -0
- backend/pytest.ini +4 -0
- backend/requirements.txt +40 -0
- backend/tests/__init__.py +1 -0
- backend/tests/conftest.py +219 -0
- backend/tests/test_chat.py +10 -0
- backend/tests/test_feedback.py +23 -0
- backend/tests/test_health.py +24 -0
- backend/tests/test_predict.py +23 -0
- backend/tests/test_upload.py +45 -0
- backend/tests/test_url.py +19 -0
- backend/tests/test_virustotal.py +23 -0
- urlmodel_info/case_study_results.csv +18 -0
- urlmodel_info/case_study_scores.png +3 -0
- urlmodel_info/char_bilstm_net.pt +3 -0
- urlmodel_info/char_cnn_net.pt +3 -0
- urlmodel_info/download_data.py +111 -0
- urlmodel_info/eda_class_distribution.png +0 -0
- urlmodel_info/eda_feature_distributions.png +3 -0
- urlmodel_info/eda_url_length_by_class.png +0 -0
- urlmodel_info/evaluation.py +226 -0
- urlmodel_info/feature_engineering.py +347 -0
.dockerignore
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
.git
|
| 2 |
+
.vercel
|
| 3 |
+
venv
|
| 4 |
+
frontend/node_modules
|
| 5 |
+
frontend/dist
|
| 6 |
+
data
|
| 7 |
+
*.log
|
| 8 |
+
*-dev.out.log
|
| 9 |
+
*-dev.err.log
|
| 10 |
+
MalwareGuard_Report.*
|
| 11 |
+
test_folder
|
.gitattributes
CHANGED
|
@@ -33,3 +33,8 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
urlmodel_info/case_study_scores.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
urlmodel_info/eda_feature_distributions.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
urlmodel_info/feature_importance_xgb.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
urlmodel_info/results_accuracy_bar.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
urlmodel_info/results_roc_curves.png filter=lfs diff=lfs merge=lfs -text
|
Dockerfile
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.12-slim
|
| 2 |
+
|
| 3 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 4 |
+
ENV PYTHONUNBUFFERED=1
|
| 5 |
+
|
| 6 |
+
WORKDIR /app
|
| 7 |
+
|
| 8 |
+
RUN apt-get update \
|
| 9 |
+
&& apt-get install -y --no-install-recommends build-essential curl \
|
| 10 |
+
&& rm -rf /var/lib/apt/lists/*
|
| 11 |
+
|
| 12 |
+
COPY backend/requirements.txt /app/backend/requirements.txt
|
| 13 |
+
RUN pip install --no-cache-dir -r /app/backend/requirements.txt
|
| 14 |
+
|
| 15 |
+
COPY backend /app/backend
|
| 16 |
+
COPY xgb_malware_model.joblib /app/xgb_malware_model.joblib
|
| 17 |
+
COPY urlmodel_info /app/urlmodel_info
|
| 18 |
+
|
| 19 |
+
WORKDIR /app/backend
|
| 20 |
+
EXPOSE 7860
|
| 21 |
+
|
| 22 |
+
CMD ["uvicorn", "app.main:app", "--host", "0.0.0.0", "--port", "7860"]
|
README.md
CHANGED
|
@@ -1,10 +1,13 @@
|
|
| 1 |
---
|
| 2 |
title: MalwareGuard
|
| 3 |
-
emoji:
|
| 4 |
-
colorFrom:
|
| 5 |
-
colorTo:
|
| 6 |
sdk: docker
|
| 7 |
pinned: false
|
|
|
|
| 8 |
---
|
| 9 |
|
| 10 |
-
|
|
|
|
|
|
|
|
|
| 1 |
---
|
| 2 |
title: MalwareGuard
|
| 3 |
+
emoji: 🛡️
|
| 4 |
+
colorFrom: red
|
| 5 |
+
colorTo: gray
|
| 6 |
sdk: docker
|
| 7 |
pinned: false
|
| 8 |
+
license: mit
|
| 9 |
---
|
| 10 |
|
| 11 |
+
# MalwareGuard Backend
|
| 12 |
+
|
| 13 |
+
FastAPI backend for MalwareGuard, deployed as a Hugging Face Docker Space.
|
backend/app/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
# Backend package
|
backend/app/config.py
ADDED
|
@@ -0,0 +1,78 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Configuration module for the Malware Detection Platform.
|
| 3 |
+
Loads environment variables and provides app-wide settings.
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
|
| 7 |
+
|
| 8 |
+
import os
|
| 9 |
+
from pathlib import Path
|
| 10 |
+
from pydantic_settings import BaseSettings
|
| 11 |
+
from functools import lru_cache
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
class Settings(BaseSettings):
|
| 16 |
+
"""Application settings loaded from environment variables."""
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
# API Keys
|
| 20 |
+
gemini_api_key: str = ""
|
| 21 |
+
virustotal_api_key: str = ""
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
# Model Configuration
|
| 25 |
+
model_path: str = "xgb_malware_model.joblib"
|
| 26 |
+
prediction_threshold: float = 0.5
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
# Server Configuration
|
| 30 |
+
host: str = "0.0.0.0"
|
| 31 |
+
port: int = 8000
|
| 32 |
+
debug: bool = True
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
# EMBER Dataset Configuration
|
| 36 |
+
ember_feature_count: int = 2381 # EMBER 2018 v2 feature count
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
# Rate Limiting
|
| 40 |
+
rate_limit_prediction: str = "60/minute"
|
| 41 |
+
rate_limit_virustotal: str = "10/minute"
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
# CORS Origins
|
| 45 |
+
cors_origins: list[str] = [
|
| 46 |
+
"http://localhost:5173",
|
| 47 |
+
"http://localhost:3000",
|
| 48 |
+
"http://127.0.0.1:5173",
|
| 49 |
+
"http://127.0.0.1:3000",
|
| 50 |
+
]
|
| 51 |
+
|
| 52 |
+
class Config:
|
| 53 |
+
env_file = ".env"
|
| 54 |
+
env_file_encoding = "utf-8"
|
| 55 |
+
extra = "ignore"
|
| 56 |
+
|
| 57 |
+
|
| 58 |
+
@lru_cache()
|
| 59 |
+
def get_settings() -> Settings:
|
| 60 |
+
"""
|
| 61 |
+
Get cached settings instance.
|
| 62 |
+
Uses LRU cache to avoid re-reading .env file on every call.
|
| 63 |
+
"""
|
| 64 |
+
# Look for .env in parent directory (project root)
|
| 65 |
+
env_path = Path(__file__).parent.parent.parent / ".env"
|
| 66 |
+
if env_path.exists():
|
| 67 |
+
os.environ.setdefault("ENV_FILE", str(env_path))
|
| 68 |
+
|
| 69 |
+
|
| 70 |
+
return Settings(_env_file=env_path if env_path.exists() else ".env")
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
# Export settings instance for easy import
|
| 75 |
+
settings = get_settings()
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
|
backend/app/main.py
ADDED
|
@@ -0,0 +1,232 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Malware Detection Platform - FastAPI Main Application
|
| 3 |
+
|
| 4 |
+
Production-ready malware detection API combining:
|
| 5 |
+
- XGBoost ML model for EMBER 2018 v2 feature classification
|
| 6 |
+
- Gemini AI for human-readable explanations
|
| 7 |
+
- VirusTotal API for secondary verification
|
| 8 |
+
|
| 9 |
+
Author: AI Security Engineer
|
| 10 |
+
"""
|
| 11 |
+
# Used libraries
|
| 12 |
+
import logging
|
| 13 |
+
from contextlib import asynccontextmanager
|
| 14 |
+
from fastapi import FastAPI, Request
|
| 15 |
+
from fastapi.middleware.cors import CORSMiddleware
|
| 16 |
+
from fastapi.responses import JSONResponse
|
| 17 |
+
from slowapi import Limiter, _rate_limit_exceeded_handler
|
| 18 |
+
from slowapi.util import get_remote_address
|
| 19 |
+
from slowapi.errors import RateLimitExceeded
|
| 20 |
+
|
| 21 |
+
from .config import settings
|
| 22 |
+
from .routers import predict, virustotal, chat, upload, url, feedback
|
| 23 |
+
from .services.ml_service import get_ml_service
|
| 24 |
+
from .services.shap_service import get_shap_service
|
| 25 |
+
from .services.gemini_service import get_gemini_service
|
| 26 |
+
from .services.virustotal_service import get_virustotal_service
|
| 27 |
+
from .services.url_service import get_url_service
|
| 28 |
+
from .services.feedback_service import get_feedback_service
|
| 29 |
+
|
| 30 |
+
# Configure logging.
|
| 31 |
+
logging.basicConfig(
|
| 32 |
+
level=logging.INFO if settings.debug else logging.WARNING,
|
| 33 |
+
format="%(asctime)s - %(name)s - %(levelname)s - %(message)s"
|
| 34 |
+
)
|
| 35 |
+
logger = logging.getLogger(__name__)
|
| 36 |
+
|
| 37 |
+
# Rate limiter
|
| 38 |
+
limiter = Limiter(key_func=get_remote_address)
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
@asynccontextmanager
|
| 42 |
+
async def lifespan(app: FastAPI):
|
| 43 |
+
"""
|
| 44 |
+
Application lifespan manager.
|
| 45 |
+
Handles startup and shutdown events.
|
| 46 |
+
"""
|
| 47 |
+
# Startup.
|
| 48 |
+
logger.info("=" * 60)
|
| 49 |
+
logger.info("Malware Detection Platform Starting...")
|
| 50 |
+
logger.info("=" * 60)
|
| 51 |
+
|
| 52 |
+
# Load ML model (single load for all requests).
|
| 53 |
+
try:
|
| 54 |
+
ml_service = get_ml_service()
|
| 55 |
+
logger.info(f"ML Model loaded: {ml_service.get_model_info()}")
|
| 56 |
+
except Exception as e:
|
| 57 |
+
logger.error(f"Failed to load ML model: {e}")
|
| 58 |
+
raise
|
| 59 |
+
|
| 60 |
+
# Initialize SHAP service.
|
| 61 |
+
try:
|
| 62 |
+
shap_service = get_shap_service()
|
| 63 |
+
shap_service.initialize(ml_service.model)
|
| 64 |
+
logger.info("SHAP service initialized")
|
| 65 |
+
except Exception as e:
|
| 66 |
+
logger.warning(f"SHAP initialization failed (non-critical): {e}")
|
| 67 |
+
|
| 68 |
+
# Initialize Gemini service
|
| 69 |
+
try:
|
| 70 |
+
gemini_service = get_gemini_service()
|
| 71 |
+
if gemini_service.initialized:
|
| 72 |
+
logger.info("Gemini AI service initialized")
|
| 73 |
+
else:
|
| 74 |
+
logger.warning("Gemini AI service not initialized (check API key)")
|
| 75 |
+
except Exception as e:
|
| 76 |
+
logger.warning(f"Gemini initialization failed (non-critical): {e}")
|
| 77 |
+
|
| 78 |
+
# Check VirusTotal configuration
|
| 79 |
+
vt_service = get_virustotal_service()
|
| 80 |
+
if vt_service.initialized:
|
| 81 |
+
logger.info("VirusTotal service configured")
|
| 82 |
+
else:
|
| 83 |
+
logger.warning("VirusTotal API key not configured")
|
| 84 |
+
|
| 85 |
+
# Load URL HyperModel
|
| 86 |
+
try:
|
| 87 |
+
url_service = get_url_service()
|
| 88 |
+
if url_service.model_loaded:
|
| 89 |
+
logger.info(f"URL HyperModel loaded: {url_service.get_model_info()['model_type']}")
|
| 90 |
+
else:
|
| 91 |
+
logger.warning("URL HyperModel not loaded")
|
| 92 |
+
except Exception as e:
|
| 93 |
+
logger.warning(f"URL HyperModel initialization failed (non-critical): {e}")
|
| 94 |
+
|
| 95 |
+
# Initialize RL Feedback service
|
| 96 |
+
try:
|
| 97 |
+
fb_service = get_feedback_service()
|
| 98 |
+
stats = fb_service.get_stats()
|
| 99 |
+
logger.info(
|
| 100 |
+
f"RL Feedback service ready "
|
| 101 |
+
f"(malware={stats['malware_total']}, url={stats['url_total']} samples)"
|
| 102 |
+
)
|
| 103 |
+
except Exception as e:
|
| 104 |
+
logger.warning(f"RL Feedback initialization failed (non-critical): {e}")
|
| 105 |
+
|
| 106 |
+
logger.info("=" * 60)
|
| 107 |
+
logger.info("Malware Detection Platform Ready!")
|
| 108 |
+
logger.info(f"API available at: http://{settings.host}:{settings.port}")
|
| 109 |
+
logger.info("=" * 60)
|
| 110 |
+
|
| 111 |
+
yield
|
| 112 |
+
|
| 113 |
+
# Shutdown
|
| 114 |
+
logger.info("Shutting down Malware Detection Platform...")
|
| 115 |
+
|
| 116 |
+
# Close VirusTotal client
|
| 117 |
+
await vt_service.close()
|
| 118 |
+
|
| 119 |
+
logger.info("Shutdown complete")
|
| 120 |
+
|
| 121 |
+
|
| 122 |
+
# Create FastAPI app
|
| 123 |
+
app = FastAPI(
|
| 124 |
+
title="Malware Detection Platform",
|
| 125 |
+
description="""
|
| 126 |
+
## AI-Powered Malware Detection API
|
| 127 |
+
|
| 128 |
+
This platform combines machine learning with AI explanations for comprehensive malware analysis.
|
| 129 |
+
|
| 130 |
+
### Features
|
| 131 |
+
- **XGBoost Prediction**: Fast malware classification using EMBER 2018 v2 features
|
| 132 |
+
- **Gemini AI Explanation**: Human-readable analysis and recommendations
|
| 133 |
+
- **VirusTotal Verification**: Cross-reference with 70+ antivirus engines
|
| 134 |
+
- **URL Scanner**: Malicious URL detection via stacking HyperModel
|
| 135 |
+
|
| 136 |
+
### Endpoints
|
| 137 |
+
- `/api/predict` - Run XGBoost malware prediction
|
| 138 |
+
- `/api/predict/explain` - Prediction with Gemini AI explanation
|
| 139 |
+
- `/api/virustotal/{hash}` - Look up file hash on VirusTotal
|
| 140 |
+
- `/api/virustotal/compare` - Compare XGBoost vs VirusTotal verdicts
|
| 141 |
+
- `/api/url/analyze` - Analyze URL for malicious indicators
|
| 142 |
+
""",
|
| 143 |
+
version="1.0.0",
|
| 144 |
+
lifespan=lifespan,
|
| 145 |
+
docs_url="/docs",
|
| 146 |
+
redoc_url="/redoc"
|
| 147 |
+
)
|
| 148 |
+
|
| 149 |
+
# Add rate limiter to app state
|
| 150 |
+
app.state.limiter = limiter
|
| 151 |
+
app.add_exception_handler(RateLimitExceeded, _rate_limit_exceeded_handler)
|
| 152 |
+
|
| 153 |
+
# Configure CORS
|
| 154 |
+
app.add_middleware(
|
| 155 |
+
CORSMiddleware,
|
| 156 |
+
allow_origins=settings.cors_origins,
|
| 157 |
+
allow_credentials=True,
|
| 158 |
+
allow_methods=["*"],
|
| 159 |
+
allow_headers=["*"],
|
| 160 |
+
)
|
| 161 |
+
|
| 162 |
+
|
| 163 |
+
# Global exception handler
|
| 164 |
+
@app.exception_handler(Exception)
|
| 165 |
+
async def global_exception_handler(request: Request, exc: Exception):
|
| 166 |
+
"""Handle uncaught exceptions with meaningful error messages."""
|
| 167 |
+
logger.error(f"Unhandled exception: {exc}", exc_info=True)
|
| 168 |
+
|
| 169 |
+
# Don't expose internal errors in production
|
| 170 |
+
if settings.debug:
|
| 171 |
+
detail = str(exc)
|
| 172 |
+
else:
|
| 173 |
+
detail = "An internal error occurred. Please try again later."
|
| 174 |
+
|
| 175 |
+
return JSONResponse(
|
| 176 |
+
status_code=500,
|
| 177 |
+
content={"detail": detail}
|
| 178 |
+
)
|
| 179 |
+
|
| 180 |
+
|
| 181 |
+
# Include routers
|
| 182 |
+
app.include_router(predict.router)
|
| 183 |
+
app.include_router(virustotal.router)
|
| 184 |
+
app.include_router(chat.router)
|
| 185 |
+
app.include_router(upload.router)
|
| 186 |
+
app.include_router(url.router)
|
| 187 |
+
app.include_router(feedback.router)
|
| 188 |
+
|
| 189 |
+
|
| 190 |
+
@app.get("/", tags=["root"])
|
| 191 |
+
async def root():
|
| 192 |
+
"""Root endpoint with API information."""
|
| 193 |
+
return {
|
| 194 |
+
"name": "Malware Detection Platform",
|
| 195 |
+
"version": "1.0.0",
|
| 196 |
+
"status": "running",
|
| 197 |
+
"docs": "/docs",
|
| 198 |
+
"endpoints": {
|
| 199 |
+
"prediction": "/api/predict",
|
| 200 |
+
"prediction_with_explanation": "/api/predict/explain",
|
| 201 |
+
"virustotal_lookup": "/api/virustotal/{hash}",
|
| 202 |
+
"comparison": "/api/virustotal/compare"
|
| 203 |
+
}
|
| 204 |
+
}
|
| 205 |
+
|
| 206 |
+
|
| 207 |
+
@app.get("/health", tags=["health"])
|
| 208 |
+
async def health_check():
|
| 209 |
+
"""Global health check endpoint."""
|
| 210 |
+
ml_service = get_ml_service()
|
| 211 |
+
vt_service = get_virustotal_service()
|
| 212 |
+
gemini_service = get_gemini_service()
|
| 213 |
+
|
| 214 |
+
return {
|
| 215 |
+
"status": "healthy",
|
| 216 |
+
"services": {
|
| 217 |
+
"ml_model": ml_service.model_loaded,
|
| 218 |
+
"gemini": gemini_service.initialized,
|
| 219 |
+
"virustotal": vt_service.initialized
|
| 220 |
+
}
|
| 221 |
+
}
|
| 222 |
+
|
| 223 |
+
|
| 224 |
+
# For running with: python -m app.main
|
| 225 |
+
if __name__ == "__main__":
|
| 226 |
+
import uvicorn
|
| 227 |
+
uvicorn.run(
|
| 228 |
+
"app.main:app",
|
| 229 |
+
host=settings.host,
|
| 230 |
+
port=settings.port,
|
| 231 |
+
reload=settings.debug
|
| 232 |
+
)
|
backend/app/models/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
# Models package
|
backend/app/models/feedback.py
ADDED
|
@@ -0,0 +1,126 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Pydantic models for Reinforcement Learning feedback.
|
| 3 |
+
|
| 4 |
+
Two feedback channels:
|
| 5 |
+
1. Malware analysis: auto-reward based on VirusTotal agreement (+1 agree, -1 disagree)
|
| 6 |
+
2. URL analysis: user-submitted reward via popup ("Was this correct?" Yes → +1, No → -1)
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
from pydantic import BaseModel, Field
|
| 10 |
+
from typing import Optional, List, Dict
|
| 11 |
+
from enum import Enum
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
class FeedbackType(str, Enum):
|
| 15 |
+
MALWARE = "malware"
|
| 16 |
+
URL = "url"
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
# ── Malware RL Feedback ──────────────────────────────────────────────────────
|
| 20 |
+
|
| 21 |
+
class MalwareFeedbackRequest(BaseModel):
|
| 22 |
+
"""
|
| 23 |
+
Auto-generated feedback when VirusTotal results are compared with
|
| 24 |
+
XGBoost prediction. Reward is computed server-side.
|
| 25 |
+
"""
|
| 26 |
+
features: List[float] = Field(
|
| 27 |
+
...,
|
| 28 |
+
min_length=2381,
|
| 29 |
+
max_length=2381,
|
| 30 |
+
description="EMBER 2018 v2 feature vector",
|
| 31 |
+
)
|
| 32 |
+
sha256: str = Field(
|
| 33 |
+
...,
|
| 34 |
+
pattern=r"^[a-fA-F0-9]{64}$",
|
| 35 |
+
description="SHA256 hash of the analysed file",
|
| 36 |
+
)
|
| 37 |
+
predicted_label: str = Field(
|
| 38 |
+
...,
|
| 39 |
+
description="XGBoost prediction: 'Malicious' or 'Benign'",
|
| 40 |
+
)
|
| 41 |
+
predicted_probability: float = Field(..., ge=0.0, le=1.0)
|
| 42 |
+
vt_malicious_count: int = Field(..., ge=0)
|
| 43 |
+
vt_total_engines: int = Field(..., ge=0)
|
| 44 |
+
vt_detection_ratio: float = Field(..., ge=0.0, le=1.0)
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
# ── URL RL Feedback ──────────────────────────────────────────────────────────
|
| 48 |
+
|
| 49 |
+
class URLFeedbackRequest(BaseModel):
|
| 50 |
+
"""
|
| 51 |
+
User-submitted feedback for URL predictions.
|
| 52 |
+
The user confirms or denies the model's verdict.
|
| 53 |
+
"""
|
| 54 |
+
url: str = Field(..., min_length=3, description="Analysed URL")
|
| 55 |
+
predicted_label: str = Field(
|
| 56 |
+
...,
|
| 57 |
+
description="Model prediction: 'Malicious' or 'Benign'",
|
| 58 |
+
)
|
| 59 |
+
malicious_score: float = Field(..., ge=0.0, le=1.0)
|
| 60 |
+
is_correct: bool = Field(
|
| 61 |
+
...,
|
| 62 |
+
description="True if user confirms prediction is correct, False otherwise",
|
| 63 |
+
)
|
| 64 |
+
base_model_scores: Dict[str, float] = Field(
|
| 65 |
+
default_factory=dict,
|
| 66 |
+
description="Base model malicious probabilities for meta-feature reconstruction",
|
| 67 |
+
)
|
| 68 |
+
|
| 69 |
+
|
| 70 |
+
# ── Responses ────────────────────────────────────────────────────────────────
|
| 71 |
+
|
| 72 |
+
class FeedbackResponse(BaseModel):
|
| 73 |
+
"""Response after submitting feedback."""
|
| 74 |
+
success: bool
|
| 75 |
+
reward: int
|
| 76 |
+
message: str
|
| 77 |
+
total_feedback_count: int
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
class FeedbackStats(BaseModel):
|
| 81 |
+
"""Aggregated RL statistics."""
|
| 82 |
+
malware_total: int
|
| 83 |
+
malware_agree: int
|
| 84 |
+
malware_disagree: int
|
| 85 |
+
malware_agreement_rate: float
|
| 86 |
+
url_total: int
|
| 87 |
+
url_correct: int
|
| 88 |
+
url_incorrect: int
|
| 89 |
+
url_accuracy_rate: float
|
| 90 |
+
recent_malware: List[dict] = []
|
| 91 |
+
recent_url: List[dict] = []
|
| 92 |
+
model_updates: List[dict] = []
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
class ModelUpdateRequest(BaseModel):
|
| 96 |
+
"""Request to trigger incremental model update."""
|
| 97 |
+
model_type: str = Field(
|
| 98 |
+
...,
|
| 99 |
+
description="Which model to update: 'malware' or 'url'",
|
| 100 |
+
pattern=r"^(malware|url)$",
|
| 101 |
+
)
|
| 102 |
+
min_samples: int = Field(
|
| 103 |
+
10,
|
| 104 |
+
ge=1,
|
| 105 |
+
description="Minimum feedback samples required to proceed",
|
| 106 |
+
)
|
| 107 |
+
learning_rate: float = Field(
|
| 108 |
+
0.01,
|
| 109 |
+
ge=0.001,
|
| 110 |
+
le=0.1,
|
| 111 |
+
description="Learning rate for incremental training",
|
| 112 |
+
)
|
| 113 |
+
num_boost_rounds: int = Field(
|
| 114 |
+
5,
|
| 115 |
+
ge=1,
|
| 116 |
+
le=50,
|
| 117 |
+
description="Number of additional boosting rounds",
|
| 118 |
+
)
|
| 119 |
+
|
| 120 |
+
|
| 121 |
+
class ModelUpdateResponse(BaseModel):
|
| 122 |
+
"""Response from model update trigger."""
|
| 123 |
+
success: bool
|
| 124 |
+
model_type: str
|
| 125 |
+
samples_used: int
|
| 126 |
+
message: str
|
backend/app/models/prediction.py
ADDED
|
@@ -0,0 +1,149 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Pydantic models for prediction requests and responses.
|
| 3 |
+
Defines the data structures for the XGBoost malware detection API.
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
from pydantic import BaseModel, Field, field_validator
|
| 7 |
+
|
| 8 |
+
from typing import Optional, List
|
| 9 |
+
|
| 10 |
+
from enum import Enum
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
class PredictionLabel(str, Enum):
|
| 14 |
+
"""Prediction classification labels."""
|
| 15 |
+
MALICIOUS = "Malicious"
|
| 16 |
+
BENIGN = "Benign"
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
class ConfidenceLevel(str, Enum):
|
| 20 |
+
"""Confidence level categories based on probability."""
|
| 21 |
+
HIGH = "High"
|
| 22 |
+
MEDIUM = "Medium"
|
| 23 |
+
LOW = "Low"
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
class SeverityLevel(str, Enum):
|
| 27 |
+
"""Severity levels for Gemini analysis."""
|
| 28 |
+
CRITICAL = "Critical"
|
| 29 |
+
HIGH = "High"
|
| 30 |
+
MEDIUM = "Medium"
|
| 31 |
+
LOW = "Low"
|
| 32 |
+
NONE = "None"
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
class PredictionRequest(BaseModel):
|
| 36 |
+
"""
|
| 37 |
+
Request model for malware prediction.
|
| 38 |
+
Accepts EMBER 2018 v2 feature vector (2381 features).
|
| 39 |
+
"""
|
| 40 |
+
features: List[float] = Field(
|
| 41 |
+
...,
|
| 42 |
+
description="EMBER 2018 v2 feature vector (2381 float values)",
|
| 43 |
+
min_length=2381,
|
| 44 |
+
max_length=2381
|
| 45 |
+
)
|
| 46 |
+
sha256: Optional[str] = Field(
|
| 47 |
+
None,
|
| 48 |
+
description="Optional SHA256 hash for reference",
|
| 49 |
+
pattern=r"^[a-fA-F0-9]{64}$"
|
| 50 |
+
)
|
| 51 |
+
threshold: Optional[float] = Field(
|
| 52 |
+
None,
|
| 53 |
+
description="Custom prediction threshold (0.0-1.0)",
|
| 54 |
+
ge=0.0,
|
| 55 |
+
le=1.0
|
| 56 |
+
)
|
| 57 |
+
include_shap: Optional[bool] = Field(
|
| 58 |
+
False,
|
| 59 |
+
description="Include SHAP feature importance analysis"
|
| 60 |
+
)
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
@field_validator('features')
|
| 64 |
+
@classmethod
|
| 65 |
+
def validate_features(cls, v):
|
| 66 |
+
"""Validate feature values are within reasonable bounds."""
|
| 67 |
+
if not all(isinstance(x, (int, float)) for x in v):
|
| 68 |
+
raise ValueError("All features must be numeric values")
|
| 69 |
+
return v
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
class FeatureImportance(BaseModel):
|
| 74 |
+
"""Single feature importance entry from SHAP analysis."""
|
| 75 |
+
feature_index: int
|
| 76 |
+
feature_name: str
|
| 77 |
+
importance_value: float
|
| 78 |
+
contribution: str # "increases" or "decreases" malware probability
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
class PredictionResponse(BaseModel):
|
| 83 |
+
"""
|
| 84 |
+
Response model for malware prediction.
|
| 85 |
+
Contains prediction, probability, and optional SHAP analysis.
|
| 86 |
+
"""
|
| 87 |
+
prediction: PredictionLabel
|
| 88 |
+
probability: float = Field(..., ge=0.0, le=1.0)
|
| 89 |
+
confidence: ConfidenceLevel
|
| 90 |
+
threshold_used: float
|
| 91 |
+
sha256: Optional[str] = None
|
| 92 |
+
top_features: Optional[List[FeatureImportance]] = None
|
| 93 |
+
inference_time_ms: float
|
| 94 |
+
|
| 95 |
+
|
| 96 |
+
|
| 97 |
+
class GeminiExplanation(BaseModel):
|
| 98 |
+
"""Gemini AI analysis response."""
|
| 99 |
+
risk_explanation: str
|
| 100 |
+
severity_level: SeverityLevel
|
| 101 |
+
key_indicators: List[str]
|
| 102 |
+
analyst_summary: str
|
| 103 |
+
mitigation_steps: Optional[List[str]] = None
|
| 104 |
+
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
class MalwareTypeInfo(BaseModel):
|
| 108 |
+
"""Malware type classification result."""
|
| 109 |
+
primary_type: str
|
| 110 |
+
confidence: str
|
| 111 |
+
secondary_types: List[str] = []
|
| 112 |
+
indicators: List[str] = []
|
| 113 |
+
source: str
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
|
| 117 |
+
class PredictionWithExplanationResponse(BaseModel):
|
| 118 |
+
"""
|
| 119 |
+
Combined response with XGBoost prediction and Gemini explanation.
|
| 120 |
+
"""
|
| 121 |
+
prediction: PredictionResponse
|
| 122 |
+
explanation: GeminiExplanation
|
| 123 |
+
malware_type: Optional[MalwareTypeInfo] = None
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
class CompareRequest(BaseModel):
|
| 128 |
+
"""Request to compare XGBoost prediction with VirusTotal."""
|
| 129 |
+
features: List[float] = Field(
|
| 130 |
+
...,
|
| 131 |
+
min_length=2381,
|
| 132 |
+
max_length=2381
|
| 133 |
+
)
|
| 134 |
+
sha256: str = Field(
|
| 135 |
+
...,
|
| 136 |
+
pattern=r"^[a-fA-F0-9]{64}$",
|
| 137 |
+
description="SHA256 hash to check on VirusTotal"
|
| 138 |
+
)
|
| 139 |
+
|
| 140 |
+
|
| 141 |
+
class ComparisonResult(BaseModel):
|
| 142 |
+
"""Result of comparing XGBoost and VirusTotal verdicts."""
|
| 143 |
+
xgboost_prediction: PredictionLabel
|
| 144 |
+
xgboost_probability: float
|
| 145 |
+
virustotal_malicious_count: int
|
| 146 |
+
virustotal_total_engines: int
|
| 147 |
+
virustotal_detection_ratio: float
|
| 148 |
+
agreement: bool
|
| 149 |
+
agreement_description: str
|
backend/app/models/url.py
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Pydantic models for URL malware detection requests and responses.
|
| 3 |
+
"""
|
| 4 |
+
|
| 5 |
+
from pydantic import BaseModel, Field, field_validator
|
| 6 |
+
from typing import Optional, Dict, List
|
| 7 |
+
from enum import Enum
|
| 8 |
+
|
| 9 |
+
|
| 10 |
+
class URLPredictionLabel(str, Enum):
|
| 11 |
+
"""URL prediction labels."""
|
| 12 |
+
MALICIOUS = "Malicious"
|
| 13 |
+
BENIGN = "Benign"
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
class URLConfidenceLevel(str, Enum):
|
| 17 |
+
"""Confidence levels."""
|
| 18 |
+
HIGH = "High"
|
| 19 |
+
MEDIUM = "Medium"
|
| 20 |
+
LOW = "Low"
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
class URLAnalyzeRequest(BaseModel):
|
| 24 |
+
"""Request to analyze a URL for malicious indicators."""
|
| 25 |
+
url: str = Field(
|
| 26 |
+
...,
|
| 27 |
+
description="URL to analyze",
|
| 28 |
+
min_length=3,
|
| 29 |
+
max_length=4096,
|
| 30 |
+
)
|
| 31 |
+
threshold: Optional[float] = Field(
|
| 32 |
+
None,
|
| 33 |
+
description="Custom prediction threshold (0.0-1.0)",
|
| 34 |
+
ge=0.0,
|
| 35 |
+
le=1.0,
|
| 36 |
+
)
|
| 37 |
+
|
| 38 |
+
@field_validator("url")
|
| 39 |
+
@classmethod
|
| 40 |
+
def validate_url(cls, v):
|
| 41 |
+
v = v.strip()
|
| 42 |
+
if not v:
|
| 43 |
+
raise ValueError("URL cannot be empty")
|
| 44 |
+
return v
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
class URLAnalyzeResponse(BaseModel):
|
| 48 |
+
"""Response from URL malware analysis."""
|
| 49 |
+
url: str
|
| 50 |
+
prediction: URLPredictionLabel
|
| 51 |
+
malicious_score: float = Field(..., ge=0.0, le=1.0)
|
| 52 |
+
confidence: str
|
| 53 |
+
confidence_level: URLConfidenceLevel
|
| 54 |
+
threshold_used: float
|
| 55 |
+
base_model_scores: Dict[str, float]
|
| 56 |
+
top_signals: Dict[str, float]
|
| 57 |
+
inference_time_ms: float
|
| 58 |
+
|
| 59 |
+
|
| 60 |
+
class URLModelInfoResponse(BaseModel):
|
| 61 |
+
"""Information about the URL model."""
|
| 62 |
+
model_type: str
|
| 63 |
+
base_models: List[str]
|
| 64 |
+
meta_learner: str
|
| 65 |
+
scaler_features: int
|
| 66 |
+
meta_features: int
|
| 67 |
+
dl_available: bool
|
| 68 |
+
feature_categories: List[str]
|
backend/app/models/virustotal.py
ADDED
|
@@ -0,0 +1,72 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Pydantic models for VirusTotal API responses.
|
| 3 |
+
"""
|
| 4 |
+
|
| 5 |
+
from pydantic import BaseModel, Field
|
| 6 |
+
from typing import Optional, Dict, List
|
| 7 |
+
from datetime import datetime
|
| 8 |
+
|
| 9 |
+
|
| 10 |
+
class EngineResult(BaseModel):
|
| 11 |
+
"""Single antivirus engine scan result."""
|
| 12 |
+
engine_name: str
|
| 13 |
+
category: str # "malicious", "undetected", "suspicious", etc.
|
| 14 |
+
result: Optional[str] = None # Detection name if malicious
|
| 15 |
+
engine_version: Optional[str] = None
|
| 16 |
+
engine_update: Optional[str] = None
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
class VirusTotalStats(BaseModel):
|
| 20 |
+
"""Aggregated statistics from VirusTotal scan."""
|
| 21 |
+
malicious: int = 0
|
| 22 |
+
suspicious: int = 0
|
| 23 |
+
undetected: int = 0
|
| 24 |
+
harmless: int = 0
|
| 25 |
+
timeout: int = 0
|
| 26 |
+
confirmed_timeout: int = 0
|
| 27 |
+
failure: int = 0
|
| 28 |
+
type_unsupported: int = 0
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
class MalwareTypeInfo(BaseModel):
|
| 32 |
+
"""Malware type classification information."""
|
| 33 |
+
primary_type: str
|
| 34 |
+
confidence: str # "High", "Medium", "Low"
|
| 35 |
+
secondary_types: List[str] = []
|
| 36 |
+
indicators: List[str] = []
|
| 37 |
+
source: str # "heuristic", "virustotal", "combined"
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
class VirusTotalRequest(BaseModel):
|
| 41 |
+
"""Request model for VirusTotal hash lookup."""
|
| 42 |
+
sha256: str = Field(
|
| 43 |
+
...,
|
| 44 |
+
pattern=r"^[a-fA-F0-9]{64}$",
|
| 45 |
+
description="SHA256 hash to look up"
|
| 46 |
+
)
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
class VirusTotalResponse(BaseModel):
|
| 50 |
+
"""
|
| 51 |
+
Response model for VirusTotal hash lookup.
|
| 52 |
+
Contains detection stats and engine results.
|
| 53 |
+
"""
|
| 54 |
+
sha256: str
|
| 55 |
+
found: bool
|
| 56 |
+
stats: Optional[VirusTotalStats] = None
|
| 57 |
+
detection_ratio: Optional[float] = None
|
| 58 |
+
total_engines: Optional[int] = None
|
| 59 |
+
malicious_count: Optional[int] = None
|
| 60 |
+
reputation_score: Optional[int] = None
|
| 61 |
+
engine_results: Optional[List[EngineResult]] = None
|
| 62 |
+
first_submission_date: Optional[str] = None
|
| 63 |
+
last_analysis_date: Optional[str] = None
|
| 64 |
+
meaningful_name: Optional[str] = None
|
| 65 |
+
malware_type: Optional[MalwareTypeInfo] = None
|
| 66 |
+
error_message: Optional[str] = None
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
class VirusTotalError(BaseModel):
|
| 70 |
+
"""Error response from VirusTotal."""
|
| 71 |
+
error: str
|
| 72 |
+
code: Optional[str] = None
|
backend/app/routers/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
# Routers package
|
backend/app/routers/chat.py
ADDED
|
@@ -0,0 +1,179 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Chat Router - Gemini-powered chatbot endpoint for the malware detection platform.
|
| 3 |
+
"""
|
| 4 |
+
|
| 5 |
+
from fastapi import APIRouter
|
| 6 |
+
from pydantic import BaseModel, Field
|
| 7 |
+
from typing import Optional, List
|
| 8 |
+
import logging
|
| 9 |
+
|
| 10 |
+
from ..services.gemini_service import get_gemini_service
|
| 11 |
+
|
| 12 |
+
logger = logging.getLogger(__name__)
|
| 13 |
+
|
| 14 |
+
router = APIRouter(prefix="/api/chat", tags=["chat"])
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
class ChatRequest(BaseModel):
|
| 18 |
+
"""Chat request model."""
|
| 19 |
+
|
| 20 |
+
message: str = Field(..., description="User message", min_length=1, max_length=2000)
|
| 21 |
+
history: Optional[List[str]] = Field(default=[], description="Conversation history")
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
class ChatResponse(BaseModel):
|
| 25 |
+
"""Chat response model."""
|
| 26 |
+
|
| 27 |
+
response: str = Field(..., description="AI response")
|
| 28 |
+
success: bool = Field(default=True)
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
def _fallback_chat_response(message: str) -> str:
|
| 32 |
+
"""Return a local fallback answer when Gemini is unavailable."""
|
| 33 |
+
text = message.lower()
|
| 34 |
+
|
| 35 |
+
if any(
|
| 36 |
+
keyword in text
|
| 37 |
+
for keyword in [
|
| 38 |
+
"malware detection",
|
| 39 |
+
"how does malware",
|
| 40 |
+
"how it works",
|
| 41 |
+
"detect malware",
|
| 42 |
+
]
|
| 43 |
+
):
|
| 44 |
+
return (
|
| 45 |
+
"MalwareGuard analyzes Windows PE files by extracting EMBER features, "
|
| 46 |
+
"running an XGBoost malware classifier, and then showing confidence, "
|
| 47 |
+
"SHAP feature importance, and an optional malware-type interpretation."
|
| 48 |
+
)
|
| 49 |
+
|
| 50 |
+
if any(keyword in text for keyword in ["ember", "dataset", "features"]):
|
| 51 |
+
return (
|
| 52 |
+
"The platform uses the EMBER 2018 v2 feature format. Each sample is "
|
| 53 |
+
"represented by 2,381 static features derived from PE structure, imports, "
|
| 54 |
+
"exports, strings, headers, and byte-level statistics."
|
| 55 |
+
)
|
| 56 |
+
|
| 57 |
+
if any(
|
| 58 |
+
keyword in text for keyword in ["virustotal", "hash", "sha256", "md5", "sha1"]
|
| 59 |
+
):
|
| 60 |
+
return (
|
| 61 |
+
"Use the VirusTotal lookup tab to submit a file hash such as SHA256, MD5, "
|
| 62 |
+
"or SHA1. MalwareGuard queries VirusTotal and returns detection ratio, engine "
|
| 63 |
+
"results, and malware-type hints when available."
|
| 64 |
+
)
|
| 65 |
+
|
| 66 |
+
if any(keyword in text for keyword in ["url", "link", "phishing"]):
|
| 67 |
+
return (
|
| 68 |
+
"The URL scanner extracts lexical and structural signals from a URL, runs the "
|
| 69 |
+
"URL model stack, and returns a malicious or benign verdict with top signals. "
|
| 70 |
+
"Users can also submit feedback to improve the model over time."
|
| 71 |
+
)
|
| 72 |
+
|
| 73 |
+
if any(
|
| 74 |
+
keyword in text for keyword in ["dashboard", "feedback", "reinforcement", "rl"]
|
| 75 |
+
):
|
| 76 |
+
return (
|
| 77 |
+
"The dashboard summarizes malware and URL feedback, agreement rates, and model "
|
| 78 |
+
"update activity. Feedback is stored locally and can be used to trigger model updates."
|
| 79 |
+
)
|
| 80 |
+
|
| 81 |
+
return (
|
| 82 |
+
"Gemini is currently unavailable, so I am answering in fallback mode. "
|
| 83 |
+
"I can still help explain MalwareGuard features such as PE file analysis, URL scanning, "
|
| 84 |
+
"VirusTotal lookup, SHAP explanations, and the feedback dashboard."
|
| 85 |
+
)
|
| 86 |
+
|
| 87 |
+
|
| 88 |
+
# System context for the chatbot
|
| 89 |
+
CHATBOT_SYSTEM_PROMPT = """You are MalwareGuard AI, a helpful and knowledgeable assistant for a malware detection platform. Your role is to help users understand:
|
| 90 |
+
|
| 91 |
+
1. **About the Platform**: MalwareGuard is an AI-powered malware detection platform that uses:
|
| 92 |
+
- XGBoost machine learning model trained on the EMBER 2018 v2 dataset
|
| 93 |
+
- SHAP (SHapley Additive exPlanations) for feature importance analysis
|
| 94 |
+
- Gemini AI for human-readable explanations
|
| 95 |
+
- VirusTotal API integration for cross-referencing with 70+ antivirus engines
|
| 96 |
+
|
| 97 |
+
2. **How Malware Detection Works**:
|
| 98 |
+
- The platform analyzes PE (Portable Executable) file features
|
| 99 |
+
- Features include: byte histograms, PE header info, import/export tables, section characteristics, string analysis
|
| 100 |
+
- The ML model outputs a probability (0-1) indicating malware likelihood
|
| 101 |
+
- SHAP explains which features contributed most to the prediction
|
| 102 |
+
|
| 103 |
+
3. **How to Use the Platform**:
|
| 104 |
+
- AI Prediction Tab: Input EMBER features (2381 float values) for malware analysis
|
| 105 |
+
- VirusTotal Tab: Look up file hashes (SHA256, MD5, SHA1) for antivirus scan results
|
| 106 |
+
- Results include confidence levels, explanations, and mitigation recommendations
|
| 107 |
+
|
| 108 |
+
4. **The EMBER Dataset**:
|
| 109 |
+
- EMBER = Endgame Malware BEnchmark for Research
|
| 110 |
+
- Contains 2018 v2 features extracted from Windows PE files
|
| 111 |
+
- 2381 features per sample including: byte histograms (256), section info, imports, exports, etc.
|
| 112 |
+
- Training set: ~1 million samples (malware + benign)
|
| 113 |
+
|
| 114 |
+
5. **Team Information**:
|
| 115 |
+
- This is a graduation project 2026 developed by a team of 5 members
|
| 116 |
+
- Hesham Ahmed Wageeh Elsayed — AI Engineer
|
| 117 |
+
- Ahmed Mohamed Ramadan — UI/UX Designer
|
| 118 |
+
- Kamal Khaled — AI Engineer
|
| 119 |
+
- Zeyad Waleed — Full Stack Developer
|
| 120 |
+
- Ali Hassan Ali — Full Stack Developer
|
| 121 |
+
|
| 122 |
+
Guidelines:
|
| 123 |
+
- Be helpful, professional, and accurate
|
| 124 |
+
- Focus on cybersecurity and malware detection topics
|
| 125 |
+
- If asked about something outside your expertise, politely redirect
|
| 126 |
+
- Keep responses concise but informative
|
| 127 |
+
- Use markdown formatting for readability when appropriate
|
| 128 |
+
- Never reveal sensitive technical details about bypassing detection
|
| 129 |
+
|
| 130 |
+
User message: {message}"""
|
| 131 |
+
|
| 132 |
+
|
| 133 |
+
@router.post("/", response_model=ChatResponse)
|
| 134 |
+
async def chat(request: ChatRequest):
|
| 135 |
+
"""
|
| 136 |
+
Send a message to the AI chatbot.
|
| 137 |
+
|
| 138 |
+
The chatbot can answer questions about:
|
| 139 |
+
- How the malware detection platform works
|
| 140 |
+
- EMBER dataset and features
|
| 141 |
+
- Using the prediction and VirusTotal features
|
| 142 |
+
- General cybersecurity questions
|
| 143 |
+
"""
|
| 144 |
+
gemini_service = get_gemini_service()
|
| 145 |
+
|
| 146 |
+
if not gemini_service.initialized:
|
| 147 |
+
gemini_service.initialize()
|
| 148 |
+
|
| 149 |
+
if not gemini_service.initialized or gemini_service.model is None:
|
| 150 |
+
logger.warning("Gemini chatbot unavailable, using fallback response")
|
| 151 |
+
return ChatResponse(response=_fallback_chat_response(request.message))
|
| 152 |
+
|
| 153 |
+
try:
|
| 154 |
+
# Format the prompt with user message
|
| 155 |
+
prompt = CHATBOT_SYSTEM_PROMPT.format(message=request.message)
|
| 156 |
+
|
| 157 |
+
# Call Gemini API
|
| 158 |
+
response = gemini_service.model.generate_content(prompt)
|
| 159 |
+
|
| 160 |
+
if response.text:
|
| 161 |
+
return ChatResponse(response=response.text)
|
| 162 |
+
else:
|
| 163 |
+
logger.warning("Gemini returned an empty chatbot response, using fallback")
|
| 164 |
+
return ChatResponse(response=_fallback_chat_response(request.message))
|
| 165 |
+
|
| 166 |
+
except Exception as e:
|
| 167 |
+
logger.error(f"Chat error: {e}")
|
| 168 |
+
return ChatResponse(response=_fallback_chat_response(request.message))
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
@router.get("/health")
|
| 172 |
+
async def chat_health():
|
| 173 |
+
"""Check if the chat service is healthy."""
|
| 174 |
+
gemini_service = get_gemini_service()
|
| 175 |
+
|
| 176 |
+
return {
|
| 177 |
+
"status": "healthy" if gemini_service.initialized else "unavailable",
|
| 178 |
+
"gemini_initialized": gemini_service.initialized,
|
| 179 |
+
}
|
backend/app/routers/feedback.py
ADDED
|
@@ -0,0 +1,156 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Reinforcement Learning Feedback Router
|
| 3 |
+
|
| 4 |
+
Endpoints:
|
| 5 |
+
POST /api/feedback/malware — Log malware RL reward (VT agreement)
|
| 6 |
+
POST /api/feedback/url — Log URL RL reward (user confirmation)
|
| 7 |
+
GET /api/feedback/stats — Aggregated RL statistics
|
| 8 |
+
POST /api/feedback/update-model — Trigger incremental model update
|
| 9 |
+
GET /api/feedback/health — Health check
|
| 10 |
+
"""
|
| 11 |
+
|
| 12 |
+
import logging
|
| 13 |
+
from fastapi import APIRouter, HTTPException
|
| 14 |
+
|
| 15 |
+
from ..models.feedback import (
|
| 16 |
+
MalwareFeedbackRequest,
|
| 17 |
+
URLFeedbackRequest,
|
| 18 |
+
FeedbackResponse,
|
| 19 |
+
FeedbackStats,
|
| 20 |
+
ModelUpdateRequest,
|
| 21 |
+
ModelUpdateResponse,
|
| 22 |
+
)
|
| 23 |
+
from ..services.feedback_service import get_feedback_service
|
| 24 |
+
|
| 25 |
+
logger = logging.getLogger(__name__)
|
| 26 |
+
|
| 27 |
+
router = APIRouter(
|
| 28 |
+
prefix="/api/feedback",
|
| 29 |
+
tags=["Reinforcement Learning"],
|
| 30 |
+
responses={500: {"description": "Internal Server Error"}},
|
| 31 |
+
)
|
| 32 |
+
|
| 33 |
+
|
| 34 |
+
# ── Malware RL ────────────────────────────────────────────────────────────────
|
| 35 |
+
|
| 36 |
+
@router.post("/malware", response_model=FeedbackResponse)
|
| 37 |
+
async def submit_malware_feedback(body: MalwareFeedbackRequest):
|
| 38 |
+
"""
|
| 39 |
+
Submit malware RL feedback based on VirusTotal comparison.
|
| 40 |
+
|
| 41 |
+
Reward:
|
| 42 |
+
+1 if XGBoost and VirusTotal agree (both malicious or both benign)
|
| 43 |
+
-1 if they disagree
|
| 44 |
+
"""
|
| 45 |
+
try:
|
| 46 |
+
svc = get_feedback_service()
|
| 47 |
+
result = svc.log_malware_feedback(
|
| 48 |
+
features=body.features,
|
| 49 |
+
sha256=body.sha256,
|
| 50 |
+
predicted=body.predicted_label,
|
| 51 |
+
probability=body.predicted_probability,
|
| 52 |
+
vt_mal=body.vt_malicious_count,
|
| 53 |
+
vt_total=body.vt_total_engines,
|
| 54 |
+
vt_ratio=body.vt_detection_ratio,
|
| 55 |
+
)
|
| 56 |
+
# Auto-trigger incremental update when enough samples accumulate
|
| 57 |
+
svc.maybe_auto_update("malware")
|
| 58 |
+
return FeedbackResponse(**result)
|
| 59 |
+
except Exception as e:
|
| 60 |
+
logger.error(f"Malware feedback error: {e}", exc_info=True)
|
| 61 |
+
raise HTTPException(status_code=500, detail=f"Feedback failed: {e}")
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
# ── URL RL ────────────────────────────────────────────────────────────────────
|
| 65 |
+
|
| 66 |
+
@router.post("/url", response_model=FeedbackResponse)
|
| 67 |
+
async def submit_url_feedback(body: URLFeedbackRequest):
|
| 68 |
+
"""
|
| 69 |
+
Submit URL RL feedback from user confirmation popup.
|
| 70 |
+
|
| 71 |
+
Reward:
|
| 72 |
+
+1 if user confirms prediction is correct
|
| 73 |
+
-1 if user says prediction is wrong
|
| 74 |
+
"""
|
| 75 |
+
try:
|
| 76 |
+
svc = get_feedback_service()
|
| 77 |
+
result = svc.log_url_feedback(
|
| 78 |
+
url=body.url,
|
| 79 |
+
predicted=body.predicted_label,
|
| 80 |
+
malicious_score=body.malicious_score,
|
| 81 |
+
is_correct=body.is_correct,
|
| 82 |
+
base_model_scores=body.base_model_scores,
|
| 83 |
+
)
|
| 84 |
+
# Auto-trigger incremental update when enough samples accumulate
|
| 85 |
+
svc.maybe_auto_update("url")
|
| 86 |
+
return FeedbackResponse(**result)
|
| 87 |
+
except Exception as e:
|
| 88 |
+
logger.error(f"URL feedback error: {e}", exc_info=True)
|
| 89 |
+
raise HTTPException(status_code=500, detail=f"Feedback failed: {e}")
|
| 90 |
+
|
| 91 |
+
|
| 92 |
+
# ── Statistics ────────────────────────────────────────────────────────────────
|
| 93 |
+
|
| 94 |
+
@router.get("/stats", response_model=FeedbackStats)
|
| 95 |
+
async def get_feedback_stats():
|
| 96 |
+
"""Get aggregated RL feedback statistics for both channels."""
|
| 97 |
+
try:
|
| 98 |
+
svc = get_feedback_service()
|
| 99 |
+
return FeedbackStats(**svc.get_stats())
|
| 100 |
+
except Exception as e:
|
| 101 |
+
logger.error(f"Stats error: {e}", exc_info=True)
|
| 102 |
+
raise HTTPException(status_code=500, detail=str(e))
|
| 103 |
+
|
| 104 |
+
|
| 105 |
+
# ── Model Update ─────────────────────────────────────────────────────────────
|
| 106 |
+
|
| 107 |
+
@router.post("/update-model", response_model=ModelUpdateResponse)
|
| 108 |
+
async def update_model(body: ModelUpdateRequest):
|
| 109 |
+
"""
|
| 110 |
+
Trigger incremental model update using accumulated feedback.
|
| 111 |
+
|
| 112 |
+
Uses XGBoost continuation training (xgb_model parameter) to add
|
| 113 |
+
additional boosting rounds from feedback samples without full re-training.
|
| 114 |
+
"""
|
| 115 |
+
try:
|
| 116 |
+
svc = get_feedback_service()
|
| 117 |
+
if body.model_type == "malware":
|
| 118 |
+
result = svc.update_malware_model(
|
| 119 |
+
min_samples=body.min_samples,
|
| 120 |
+
lr=body.learning_rate,
|
| 121 |
+
rounds=body.num_boost_rounds,
|
| 122 |
+
)
|
| 123 |
+
elif body.model_type == "url":
|
| 124 |
+
result = svc.update_url_model(
|
| 125 |
+
min_samples=body.min_samples,
|
| 126 |
+
lr=body.learning_rate,
|
| 127 |
+
rounds=body.num_boost_rounds,
|
| 128 |
+
)
|
| 129 |
+
else:
|
| 130 |
+
raise HTTPException(
|
| 131 |
+
status_code=400,
|
| 132 |
+
detail="model_type must be 'malware' or 'url'",
|
| 133 |
+
)
|
| 134 |
+
return ModelUpdateResponse(**result)
|
| 135 |
+
except HTTPException:
|
| 136 |
+
raise
|
| 137 |
+
except Exception as e:
|
| 138 |
+
logger.error(f"Model update error: {e}", exc_info=True)
|
| 139 |
+
raise HTTPException(status_code=500, detail=f"Model update failed: {e}")
|
| 140 |
+
|
| 141 |
+
|
| 142 |
+
# ── Health ────────────────────────────────────────────────────────────────────
|
| 143 |
+
|
| 144 |
+
@router.get("/health")
|
| 145 |
+
async def feedback_health():
|
| 146 |
+
"""Health check for the RL feedback service."""
|
| 147 |
+
try:
|
| 148 |
+
svc = get_feedback_service()
|
| 149 |
+
stats = svc.get_stats()
|
| 150 |
+
return {
|
| 151 |
+
"status": "healthy",
|
| 152 |
+
"malware_samples": stats["malware_total"],
|
| 153 |
+
"url_samples": stats["url_total"],
|
| 154 |
+
}
|
| 155 |
+
except Exception as e:
|
| 156 |
+
return {"status": "unhealthy", "error": str(e)}
|
backend/app/routers/predict.py
ADDED
|
@@ -0,0 +1,205 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Prediction API Router.
|
| 3 |
+
Handles XGBoost malware prediction and Gemini explanation endpoints.
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
import logging
|
| 7 |
+
from fastapi import APIRouter, HTTPException, Depends
|
| 8 |
+
from typing import Optional
|
| 9 |
+
from pydantic import BaseModel, Field
|
| 10 |
+
|
| 11 |
+
from ..models.prediction import (
|
| 12 |
+
PredictionRequest,
|
| 13 |
+
PredictionResponse,
|
| 14 |
+
PredictionWithExplanationResponse,
|
| 15 |
+
)
|
| 16 |
+
from ..services.ml_service import get_ml_service, MLService
|
| 17 |
+
from ..services.gemini_service import get_gemini_service, GeminiService
|
| 18 |
+
from ..services.shap_service import get_shap_service, SHAPService
|
| 19 |
+
from ..services.malware_type_service import get_malware_type_service
|
| 20 |
+
|
| 21 |
+
logger = logging.getLogger(__name__)
|
| 22 |
+
|
| 23 |
+
router = APIRouter(prefix="/api/predict", tags=["prediction"])
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
class MalwareTypeInfo(BaseModel):
|
| 27 |
+
"""Malware type classification result."""
|
| 28 |
+
primary_type: str
|
| 29 |
+
confidence: str
|
| 30 |
+
secondary_types: list = []
|
| 31 |
+
indicators: list = []
|
| 32 |
+
source: str
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
class PredictionWithTypeResponse(BaseModel):
|
| 36 |
+
"""Prediction response with malware type."""
|
| 37 |
+
prediction: PredictionResponse
|
| 38 |
+
malware_type: Optional[MalwareTypeInfo] = None
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
@router.post("", response_model=PredictionWithTypeResponse)
|
| 42 |
+
async def predict(
|
| 43 |
+
request: PredictionRequest,
|
| 44 |
+
ml_service: MLService = Depends(get_ml_service)
|
| 45 |
+
) -> PredictionWithTypeResponse:
|
| 46 |
+
"""
|
| 47 |
+
Run XGBoost malware prediction on EMBER features.
|
| 48 |
+
|
| 49 |
+
Accepts a feature vector of 2381 float values (EMBER 2018 v2 format)
|
| 50 |
+
and returns the prediction, probability, and confidence level.
|
| 51 |
+
|
| 52 |
+
- **features**: List of 2381 float values (EMBER 2018 v2 features)
|
| 53 |
+
- **sha256**: Optional SHA256 hash for reference
|
| 54 |
+
- **threshold**: Optional custom prediction threshold (default: 0.5)
|
| 55 |
+
- **include_shap**: Include SHAP feature importance (slower)
|
| 56 |
+
"""
|
| 57 |
+
try:
|
| 58 |
+
# Run prediction
|
| 59 |
+
prediction = ml_service.predict(
|
| 60 |
+
features=request.features,
|
| 61 |
+
threshold=request.threshold,
|
| 62 |
+
sha256=request.sha256
|
| 63 |
+
)
|
| 64 |
+
|
| 65 |
+
# Add SHAP analysis if requested
|
| 66 |
+
if request.include_shap:
|
| 67 |
+
shap_service = get_shap_service()
|
| 68 |
+
if not shap_service.initialized:
|
| 69 |
+
shap_service.initialize(ml_service.model)
|
| 70 |
+
|
| 71 |
+
top_features = shap_service.get_feature_importance(
|
| 72 |
+
features=request.features,
|
| 73 |
+
model=ml_service.model,
|
| 74 |
+
top_k=10
|
| 75 |
+
)
|
| 76 |
+
prediction.top_features = top_features
|
| 77 |
+
|
| 78 |
+
# Classify malware type if suspicious/malicious
|
| 79 |
+
malware_type_info = None
|
| 80 |
+
if prediction.prediction == "Malicious" or prediction.probability > 0.3:
|
| 81 |
+
try:
|
| 82 |
+
malware_type_service = get_malware_type_service()
|
| 83 |
+
# Use heuristic classification based on features
|
| 84 |
+
type_result = malware_type_service.classify()
|
| 85 |
+
malware_type_info = MalwareTypeInfo(
|
| 86 |
+
primary_type=type_result.primary_type,
|
| 87 |
+
confidence=type_result.confidence,
|
| 88 |
+
secondary_types=type_result.secondary_types,
|
| 89 |
+
indicators=type_result.indicators,
|
| 90 |
+
source=type_result.source
|
| 91 |
+
)
|
| 92 |
+
except Exception as e:
|
| 93 |
+
logger.warning(f"Malware type classification failed: {e}")
|
| 94 |
+
|
| 95 |
+
return PredictionWithTypeResponse(
|
| 96 |
+
prediction=prediction,
|
| 97 |
+
malware_type=malware_type_info
|
| 98 |
+
)
|
| 99 |
+
|
| 100 |
+
except ValueError as e:
|
| 101 |
+
logger.error(f"Validation error: {e}")
|
| 102 |
+
raise HTTPException(status_code=400, detail=str(e))
|
| 103 |
+
except RuntimeError as e:
|
| 104 |
+
logger.error(f"Runtime error: {e}")
|
| 105 |
+
raise HTTPException(status_code=500, detail=str(e))
|
| 106 |
+
except Exception as e:
|
| 107 |
+
logger.error(f"Prediction error: {e}")
|
| 108 |
+
raise HTTPException(status_code=500, detail="Prediction failed")
|
| 109 |
+
|
| 110 |
+
|
| 111 |
+
@router.post("/explain", response_model=PredictionWithExplanationResponse)
|
| 112 |
+
async def predict_with_explanation(
|
| 113 |
+
request: PredictionRequest,
|
| 114 |
+
ml_service: MLService = Depends(get_ml_service),
|
| 115 |
+
gemini_service: GeminiService = Depends(get_gemini_service)
|
| 116 |
+
) -> PredictionWithExplanationResponse:
|
| 117 |
+
"""
|
| 118 |
+
Run XGBoost prediction with Gemini AI explanation.
|
| 119 |
+
|
| 120 |
+
Combines the XGBoost prediction with a detailed analysis from
|
| 121 |
+
Gemini AI explaining why the sample was classified as malicious
|
| 122 |
+
or benign.
|
| 123 |
+
|
| 124 |
+
**Note**: Gemini does NOT override the model prediction. It only
|
| 125 |
+
provides explanation and context.
|
| 126 |
+
"""
|
| 127 |
+
try:
|
| 128 |
+
# Run prediction
|
| 129 |
+
prediction = ml_service.predict(
|
| 130 |
+
features=request.features,
|
| 131 |
+
threshold=request.threshold,
|
| 132 |
+
sha256=request.sha256
|
| 133 |
+
)
|
| 134 |
+
|
| 135 |
+
# Get SHAP features for better explanation
|
| 136 |
+
shap_service = get_shap_service()
|
| 137 |
+
if not shap_service.initialized:
|
| 138 |
+
shap_service.initialize(ml_service.model)
|
| 139 |
+
|
| 140 |
+
top_features = shap_service.get_feature_importance(
|
| 141 |
+
features=request.features,
|
| 142 |
+
model=ml_service.model,
|
| 143 |
+
top_k=10
|
| 144 |
+
)
|
| 145 |
+
prediction.top_features = top_features
|
| 146 |
+
|
| 147 |
+
# Get Gemini explanation
|
| 148 |
+
explanation = await gemini_service.explain_prediction(
|
| 149 |
+
prediction=prediction,
|
| 150 |
+
features=top_features
|
| 151 |
+
)
|
| 152 |
+
|
| 153 |
+
# Classify malware type if suspicious/malicious
|
| 154 |
+
malware_type_info = None
|
| 155 |
+
if prediction.prediction == "Malicious" or prediction.probability > 0.3:
|
| 156 |
+
try:
|
| 157 |
+
from ..services.malware_type_service import get_malware_type_service
|
| 158 |
+
from ..models.prediction import MalwareTypeInfo
|
| 159 |
+
malware_type_service = get_malware_type_service()
|
| 160 |
+
type_result = malware_type_service.classify()
|
| 161 |
+
malware_type_info = MalwareTypeInfo(
|
| 162 |
+
primary_type=type_result.primary_type,
|
| 163 |
+
confidence=type_result.confidence,
|
| 164 |
+
secondary_types=type_result.secondary_types,
|
| 165 |
+
indicators=type_result.indicators,
|
| 166 |
+
source=type_result.source
|
| 167 |
+
)
|
| 168 |
+
except Exception as e:
|
| 169 |
+
logger.warning(f"Malware type classification failed: {e}")
|
| 170 |
+
|
| 171 |
+
return PredictionWithExplanationResponse(
|
| 172 |
+
prediction=prediction,
|
| 173 |
+
explanation=explanation,
|
| 174 |
+
malware_type=malware_type_info
|
| 175 |
+
)
|
| 176 |
+
|
| 177 |
+
except ValueError as e:
|
| 178 |
+
logger.error(f"Validation error: {e}")
|
| 179 |
+
raise HTTPException(status_code=400, detail=str(e))
|
| 180 |
+
except RuntimeError as e:
|
| 181 |
+
logger.error(f"Runtime error: {e}")
|
| 182 |
+
raise HTTPException(status_code=500, detail=str(e))
|
| 183 |
+
except Exception as e:
|
| 184 |
+
logger.error(f"Prediction with explanation error: {e}")
|
| 185 |
+
raise HTTPException(status_code=500, detail="Prediction with explanation failed")
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
@router.get("/model-info")
|
| 189 |
+
async def get_model_info(
|
| 190 |
+
ml_service: MLService = Depends(get_ml_service)
|
| 191 |
+
) -> dict:
|
| 192 |
+
"""Get information about the loaded XGBoost model."""
|
| 193 |
+
return ml_service.get_model_info()
|
| 194 |
+
|
| 195 |
+
|
| 196 |
+
@router.get("/health")
|
| 197 |
+
async def health_check(
|
| 198 |
+
ml_service: MLService = Depends(get_ml_service)
|
| 199 |
+
) -> dict:
|
| 200 |
+
"""Health check endpoint for the prediction service."""
|
| 201 |
+
return {
|
| 202 |
+
"status": "healthy",
|
| 203 |
+
"model_loaded": ml_service.model_loaded,
|
| 204 |
+
"feature_count": ml_service.feature_count
|
| 205 |
+
}
|
backend/app/routers/upload.py
ADDED
|
@@ -0,0 +1,284 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
File Upload Router - Handle PE file uploads for malware analysis.
|
| 3 |
+
"""
|
| 4 |
+
|
| 5 |
+
from fastapi import APIRouter, HTTPException, UploadFile, File, Depends
|
| 6 |
+
from pydantic import BaseModel, Field
|
| 7 |
+
from typing import Optional, List
|
| 8 |
+
import logging
|
| 9 |
+
import hashlib
|
| 10 |
+
|
| 11 |
+
|
| 12 |
+
from ..services.ember_features import extract_features_from_bytes, extract_features_and_lief, LIEF_AVAILABLE
|
| 13 |
+
from ..services.ml_service import get_ml_service
|
| 14 |
+
from ..services.shap_service import get_shap_service
|
| 15 |
+
from ..services.gemini_service import get_gemini_service
|
| 16 |
+
from ..services.malware_type_service import get_malware_type_service, MalwareTypeResult
|
| 17 |
+
from ..models.prediction import (
|
| 18 |
+
PredictionResponse,
|
| 19 |
+
ConfidenceLevel,
|
| 20 |
+
GeminiExplanation,
|
| 21 |
+
)
|
| 22 |
+
|
| 23 |
+
logger = logging.getLogger(__name__)
|
| 24 |
+
|
| 25 |
+
router = APIRouter(
|
| 26 |
+
prefix="/api/upload",
|
| 27 |
+
tags=["upload"]
|
| 28 |
+
)
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
|
| 32 |
+
class MalwareTypeInfo(BaseModel):
|
| 33 |
+
"""Malware type classification result."""
|
| 34 |
+
primary_type: str
|
| 35 |
+
confidence: str
|
| 36 |
+
secondary_types: List[str] = []
|
| 37 |
+
indicators: List[str] = []
|
| 38 |
+
source: str
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
class FileAnalysisResponse(BaseModel):
|
| 43 |
+
"""Response model for file analysis."""
|
| 44 |
+
filename: str
|
| 45 |
+
sha256: str
|
| 46 |
+
file_size: int
|
| 47 |
+
features_extracted: bool
|
| 48 |
+
feature_count: int
|
| 49 |
+
features: Optional[List[float]] = None # Include features for copy functionality
|
| 50 |
+
prediction: Optional[PredictionResponse] = None
|
| 51 |
+
malware_type: Optional[MalwareTypeInfo] = None
|
| 52 |
+
explanation: Optional[GeminiExplanation] = None
|
| 53 |
+
error: Optional[str] = None
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
|
| 57 |
+
class FeatureExtractionResponse(BaseModel):
|
| 58 |
+
"""Response model for feature extraction only."""
|
| 59 |
+
filename: str
|
| 60 |
+
sha256: str
|
| 61 |
+
file_size: int
|
| 62 |
+
features: List[float]
|
| 63 |
+
feature_count: int
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
@router.post("/analyze", response_model=FileAnalysisResponse)
|
| 68 |
+
async def analyze_file(
|
| 69 |
+
file: UploadFile = File(..., description="PE file to analyze"),
|
| 70 |
+
include_explanation: bool = True
|
| 71 |
+
):
|
| 72 |
+
"""
|
| 73 |
+
Upload a PE file for complete malware analysis.
|
| 74 |
+
|
| 75 |
+
This endpoint:
|
| 76 |
+
1. Extracts EMBER 2018 v2 features from the PE file
|
| 77 |
+
2. Runs XGBoost prediction
|
| 78 |
+
3. Optionally generates Gemini AI explanation
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
**Supported files**: Windows PE executables (.exe, .dll, .sys, etc.)
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
**Note**: Maximum file size is 50MB.
|
| 85 |
+
"""
|
| 86 |
+
if not LIEF_AVAILABLE:
|
| 87 |
+
raise HTTPException(
|
| 88 |
+
status_code=503,
|
| 89 |
+
detail="PE parsing library (LIEF) is not available. Feature extraction disabled."
|
| 90 |
+
)
|
| 91 |
+
|
| 92 |
+
# Read file content
|
| 93 |
+
try:
|
| 94 |
+
content = await file.read()
|
| 95 |
+
except Exception as e:
|
| 96 |
+
raise HTTPException(status_code=400, detail=f"Failed to read file: {str(e)}")
|
| 97 |
+
|
| 98 |
+
if len(content) == 0:
|
| 99 |
+
raise HTTPException(status_code=400, detail="Empty file uploaded")
|
| 100 |
+
|
| 101 |
+
if len(content) > 50 * 1024 * 1024: # 50MB limit
|
| 102 |
+
raise HTTPException(status_code=400, detail="File too large. Maximum size is 50MB.")
|
| 103 |
+
|
| 104 |
+
|
| 105 |
+
# Check for PE signature (MZ header)
|
| 106 |
+
if content[:2] != b'MZ':
|
| 107 |
+
raise HTTPException(
|
| 108 |
+
status_code=400,
|
| 109 |
+
detail="Invalid PE file. File must be a Windows executable (PE format)."
|
| 110 |
+
)
|
| 111 |
+
|
| 112 |
+
|
| 113 |
+
|
| 114 |
+
filename = file.filename or "unknown"
|
| 115 |
+
file_size = len(content)
|
| 116 |
+
sha256 = hashlib.sha256(content).hexdigest()
|
| 117 |
+
|
| 118 |
+
# Extract features and LIEF binary
|
| 119 |
+
lief_binary = None
|
| 120 |
+
try:
|
| 121 |
+
features, _, lief_binary = extract_features_and_lief(content)
|
| 122 |
+
features_list = features.tolist()
|
| 123 |
+
feature_count = len(features_list)
|
| 124 |
+
features_extracted = True
|
| 125 |
+
except Exception as e:
|
| 126 |
+
logger.error(f"Feature extraction failed for {filename}: {e}")
|
| 127 |
+
return FileAnalysisResponse(
|
| 128 |
+
filename=filename,
|
| 129 |
+
sha256=sha256,
|
| 130 |
+
file_size=file_size,
|
| 131 |
+
features_extracted=False,
|
| 132 |
+
feature_count=0,
|
| 133 |
+
error=f"Feature extraction failed: {str(e)}"
|
| 134 |
+
)
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
# Run prediction
|
| 138 |
+
try:
|
| 139 |
+
ml_service = get_ml_service()
|
| 140 |
+
# ml_service.predict returns PredictionResponse directly
|
| 141 |
+
prediction_response = ml_service.predict(features_list, sha256=sha256)
|
| 142 |
+
except Exception as e:
|
| 143 |
+
logger.error(f"Prediction failed for {filename}: {e}")
|
| 144 |
+
return FileAnalysisResponse(
|
| 145 |
+
filename=filename,
|
| 146 |
+
sha256=sha256,
|
| 147 |
+
file_size=file_size,
|
| 148 |
+
features_extracted=True,
|
| 149 |
+
feature_count=feature_count,
|
| 150 |
+
error=f"Prediction failed: {str(e)}"
|
| 151 |
+
)
|
| 152 |
+
|
| 153 |
+
|
| 154 |
+
|
| 155 |
+
# Classify malware type if prediction is malware
|
| 156 |
+
malware_type_info = None
|
| 157 |
+
if prediction_response.prediction == "Malware" or prediction_response.probability > 0.3:
|
| 158 |
+
try:
|
| 159 |
+
malware_type_service = get_malware_type_service()
|
| 160 |
+
if lief_binary:
|
| 161 |
+
type_result = malware_type_service.classify_from_lief(lief_binary)
|
| 162 |
+
else:
|
| 163 |
+
type_result = malware_type_service.classify()
|
| 164 |
+
|
| 165 |
+
malware_type_info = MalwareTypeInfo(
|
| 166 |
+
primary_type=type_result.primary_type,
|
| 167 |
+
confidence=type_result.confidence,
|
| 168 |
+
secondary_types=type_result.secondary_types,
|
| 169 |
+
indicators=type_result.indicators,
|
| 170 |
+
source=type_result.source
|
| 171 |
+
)
|
| 172 |
+
except Exception as e:
|
| 173 |
+
logger.warning(f"Malware type classification failed: {e}")
|
| 174 |
+
|
| 175 |
+
|
| 176 |
+
|
| 177 |
+
# Generate explanation if requested
|
| 178 |
+
explanation = None
|
| 179 |
+
if include_explanation:
|
| 180 |
+
try:
|
| 181 |
+
# Get SHAP feature importance
|
| 182 |
+
shap_service = get_shap_service()
|
| 183 |
+
feature_importance = None
|
| 184 |
+
if shap_service.initialized:
|
| 185 |
+
feature_importance = shap_service.explain(features_list)
|
| 186 |
+
|
| 187 |
+
# Generate Gemini explanation
|
| 188 |
+
gemini_service = get_gemini_service()
|
| 189 |
+
if gemini_service.initialized:
|
| 190 |
+
explanation = await gemini_service.explain_prediction(
|
| 191 |
+
prediction_response,
|
| 192 |
+
feature_importance
|
| 193 |
+
)
|
| 194 |
+
except Exception as e:
|
| 195 |
+
logger.warning(f"Explanation generation failed for {filename}: {e}")
|
| 196 |
+
# Continue without explanation
|
| 197 |
+
|
| 198 |
+
|
| 199 |
+
|
| 200 |
+
return FileAnalysisResponse(
|
| 201 |
+
filename=filename,
|
| 202 |
+
sha256=sha256,
|
| 203 |
+
file_size=file_size,
|
| 204 |
+
features_extracted=True,
|
| 205 |
+
feature_count=feature_count,
|
| 206 |
+
features=features_list, # Include features for copy functionality
|
| 207 |
+
prediction=prediction_response,
|
| 208 |
+
malware_type=malware_type_info,
|
| 209 |
+
explanation=explanation
|
| 210 |
+
)
|
| 211 |
+
|
| 212 |
+
|
| 213 |
+
|
| 214 |
+
@router.post("/extract-features", response_model=FeatureExtractionResponse)
|
| 215 |
+
async def extract_features(
|
| 216 |
+
file: UploadFile = File(..., description="PE file to extract features from")
|
| 217 |
+
):
|
| 218 |
+
"""
|
| 219 |
+
Extract EMBER 2018 v2 features from a PE file without running prediction.
|
| 220 |
+
|
| 221 |
+
Returns the 2381-dimensional feature vector that can be used
|
| 222 |
+
for custom analysis or stored for later prediction.
|
| 223 |
+
|
| 224 |
+
**Supported files**: Windows PE executables (.exe, .dll, .sys, etc.)
|
| 225 |
+
"""
|
| 226 |
+
if not LIEF_AVAILABLE:
|
| 227 |
+
raise HTTPException(
|
| 228 |
+
status_code=503,
|
| 229 |
+
detail="PE parsing library (LIEF) is not available. Feature extraction disabled."
|
| 230 |
+
)
|
| 231 |
+
|
| 232 |
+
|
| 233 |
+
# Read file content
|
| 234 |
+
try:
|
| 235 |
+
content = await file.read()
|
| 236 |
+
except Exception as e:
|
| 237 |
+
raise HTTPException(status_code=400, detail=f"Failed to read file: {str(e)}")
|
| 238 |
+
|
| 239 |
+
if len(content) == 0:
|
| 240 |
+
raise HTTPException(status_code=400, detail="Empty file uploaded")
|
| 241 |
+
|
| 242 |
+
if len(content) > 50 * 1024 * 1024: # 50MB limit
|
| 243 |
+
raise HTTPException(status_code=400, detail="File too large. Maximum size is 50MB.")
|
| 244 |
+
|
| 245 |
+
# Check for PE signature
|
| 246 |
+
if content[:2] != b'MZ':
|
| 247 |
+
raise HTTPException(
|
| 248 |
+
status_code=400,
|
| 249 |
+
detail="Invalid PE file. File must be a Windows executable (PE format)."
|
| 250 |
+
)
|
| 251 |
+
|
| 252 |
+
filename = file.filename or "unknown"
|
| 253 |
+
|
| 254 |
+
|
| 255 |
+
# Extract features
|
| 256 |
+
try:
|
| 257 |
+
features, sha256 = extract_features_from_bytes(content)
|
| 258 |
+
features_list = features.tolist()
|
| 259 |
+
except Exception as e:
|
| 260 |
+
logger.error(f"Feature extraction failed for {filename}: {e}")
|
| 261 |
+
raise HTTPException(
|
| 262 |
+
status_code=500,
|
| 263 |
+
detail=f"Feature extraction failed: {str(e)}"
|
| 264 |
+
)
|
| 265 |
+
|
| 266 |
+
|
| 267 |
+
return FeatureExtractionResponse(
|
| 268 |
+
filename=filename,
|
| 269 |
+
sha256=sha256,
|
| 270 |
+
file_size=len(content),
|
| 271 |
+
features=features_list,
|
| 272 |
+
feature_count=len(features_list)
|
| 273 |
+
)
|
| 274 |
+
|
| 275 |
+
|
| 276 |
+
|
| 277 |
+
@router.get("/health")
|
| 278 |
+
async def upload_health():
|
| 279 |
+
"""Check if the upload/feature extraction service is healthy."""
|
| 280 |
+
return {
|
| 281 |
+
"status": "healthy" if LIEF_AVAILABLE else "degraded",
|
| 282 |
+
"lief_available": LIEF_AVAILABLE,
|
| 283 |
+
"feature_extraction": "enabled" if LIEF_AVAILABLE else "disabled"
|
| 284 |
+
}
|
backend/app/routers/url.py
ADDED
|
@@ -0,0 +1,89 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
URL Analysis Router — Malicious URL detection via stacking HyperModel.
|
| 3 |
+
|
| 4 |
+
Endpoints:
|
| 5 |
+
POST /api/url/analyze — Analyze a URL for malicious indicators
|
| 6 |
+
GET /api/url/model-info — Get URL model information
|
| 7 |
+
GET /api/url/health — Health check
|
| 8 |
+
"""
|
| 9 |
+
|
| 10 |
+
import logging
|
| 11 |
+
from fastapi import APIRouter, HTTPException, Request
|
| 12 |
+
from slowapi import Limiter
|
| 13 |
+
from slowapi.util import get_remote_address
|
| 14 |
+
|
| 15 |
+
from ..config import settings
|
| 16 |
+
from ..models.url import URLAnalyzeRequest, URLAnalyzeResponse, URLModelInfoResponse
|
| 17 |
+
from ..services.url_service import get_url_service
|
| 18 |
+
|
| 19 |
+
logger = logging.getLogger(__name__)
|
| 20 |
+
|
| 21 |
+
limiter = Limiter(key_func=get_remote_address)
|
| 22 |
+
|
| 23 |
+
router = APIRouter(
|
| 24 |
+
prefix="/api/url",
|
| 25 |
+
tags=["URL Analysis"],
|
| 26 |
+
responses={404: {"description": "Not found"}},
|
| 27 |
+
)
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
@router.post("/analyze", response_model=URLAnalyzeResponse)
|
| 31 |
+
async def analyze_url(request: Request, body: URLAnalyzeRequest):
|
| 32 |
+
"""
|
| 33 |
+
Analyze a URL for malicious indicators using the stacking HyperModel.
|
| 34 |
+
|
| 35 |
+
The HyperModel combines 5 base models:
|
| 36 |
+
- XGBoost & LightGBM on 54 lexical features
|
| 37 |
+
- TF-IDF + Logistic Regression on raw URL text
|
| 38 |
+
- CharCNN & CharBiLSTM deep learning on character-level URL encoding
|
| 39 |
+
|
| 40 |
+
Their probability outputs are stacked and fed to an XGBoost meta-learner.
|
| 41 |
+
"""
|
| 42 |
+
try:
|
| 43 |
+
url_service = get_url_service()
|
| 44 |
+
|
| 45 |
+
if not url_service.model_loaded:
|
| 46 |
+
raise HTTPException(status_code=503, detail="URL model not loaded")
|
| 47 |
+
|
| 48 |
+
threshold = body.threshold or settings.prediction_threshold
|
| 49 |
+
result = url_service.predict(body.url, threshold=threshold)
|
| 50 |
+
|
| 51 |
+
logger.info(
|
| 52 |
+
f"URL analyzed: {body.url[:60]}... → {result['prediction']} "
|
| 53 |
+
f"(score={result['malicious_score']:.4f}, {result['inference_time_ms']:.1f}ms)"
|
| 54 |
+
)
|
| 55 |
+
|
| 56 |
+
return URLAnalyzeResponse(**result)
|
| 57 |
+
|
| 58 |
+
except HTTPException:
|
| 59 |
+
raise
|
| 60 |
+
except Exception as e:
|
| 61 |
+
logger.error(f"URL analysis failed: {e}", exc_info=True)
|
| 62 |
+
raise HTTPException(status_code=500, detail=f"Analysis failed: {str(e)}")
|
| 63 |
+
|
| 64 |
+
|
| 65 |
+
@router.get("/model-info", response_model=URLModelInfoResponse)
|
| 66 |
+
async def url_model_info():
|
| 67 |
+
"""Get information about the URL detection model."""
|
| 68 |
+
try:
|
| 69 |
+
url_service = get_url_service()
|
| 70 |
+
return URLModelInfoResponse(**url_service.get_model_info())
|
| 71 |
+
except Exception as e:
|
| 72 |
+
raise HTTPException(status_code=500, detail=str(e))
|
| 73 |
+
|
| 74 |
+
|
| 75 |
+
@router.get("/health")
|
| 76 |
+
async def url_health():
|
| 77 |
+
"""Health check for URL analysis service."""
|
| 78 |
+
try:
|
| 79 |
+
url_service = get_url_service()
|
| 80 |
+
return {
|
| 81 |
+
"status": "healthy" if url_service.model_loaded else "unhealthy",
|
| 82 |
+
"model_loaded": url_service.model_loaded,
|
| 83 |
+
"dl_available": url_service._dl_available,
|
| 84 |
+
}
|
| 85 |
+
except Exception as e:
|
| 86 |
+
return {
|
| 87 |
+
"status": "unhealthy",
|
| 88 |
+
"error": str(e),
|
| 89 |
+
}
|
backend/app/routers/virustotal.py
ADDED
|
@@ -0,0 +1,167 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
VirusTotal API Router.
|
| 3 |
+
Handles hash lookup and comparison endpoints.
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
import logging
|
| 7 |
+
from fastapi import APIRouter, HTTPException, Depends, Path
|
| 8 |
+
from pydantic import BaseModel, Field
|
| 9 |
+
from typing import List
|
| 10 |
+
|
| 11 |
+
from ..models.virustotal import VirusTotalResponse
|
| 12 |
+
from ..models.prediction import (
|
| 13 |
+
PredictionLabel,
|
| 14 |
+
CompareRequest,
|
| 15 |
+
ComparisonResult,
|
| 16 |
+
)
|
| 17 |
+
from ..services.virustotal_service import get_virustotal_service, VirusTotalService
|
| 18 |
+
from ..services.ml_service import get_ml_service, MLService
|
| 19 |
+
from ..services.feedback_service import get_feedback_service
|
| 20 |
+
|
| 21 |
+
logger = logging.getLogger(__name__)
|
| 22 |
+
|
| 23 |
+
router = APIRouter(prefix="/api/virustotal", tags=["virustotal"])
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
@router.get("/health")
|
| 27 |
+
async def health_check(
|
| 28 |
+
vt_service: VirusTotalService = Depends(get_virustotal_service)
|
| 29 |
+
) -> dict:
|
| 30 |
+
"""Health check endpoint for VirusTotal service."""
|
| 31 |
+
return {
|
| 32 |
+
"status": "healthy",
|
| 33 |
+
"api_configured": vt_service.initialized
|
| 34 |
+
}
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
@router.get("/{hash}", response_model=VirusTotalResponse)
|
| 38 |
+
async def lookup_hash(
|
| 39 |
+
hash: str = Path(
|
| 40 |
+
...,
|
| 41 |
+
description="SHA256, SHA1, or MD5 hash to look up",
|
| 42 |
+
min_length=32,
|
| 43 |
+
max_length=64
|
| 44 |
+
),
|
| 45 |
+
vt_service: VirusTotalService = Depends(get_virustotal_service)
|
| 46 |
+
) -> VirusTotalResponse:
|
| 47 |
+
"""
|
| 48 |
+
Look up a file hash on VirusTotal.
|
| 49 |
+
|
| 50 |
+
Returns detection results from multiple antivirus engines,
|
| 51 |
+
including detection ratio, engine verdicts, and reputation score.
|
| 52 |
+
|
| 53 |
+
- **hash**: SHA256 (64 chars), SHA1 (40 chars), or MD5 (32 chars)
|
| 54 |
+
"""
|
| 55 |
+
# Basic validation
|
| 56 |
+
if len(hash) not in [32, 40, 64]:
|
| 57 |
+
raise HTTPException(
|
| 58 |
+
status_code=400,
|
| 59 |
+
detail="Invalid hash length. Expected MD5 (32), SHA1 (40), or SHA256 (64)"
|
| 60 |
+
)
|
| 61 |
+
|
| 62 |
+
if not all(c in '0123456789abcdefABCDEF' for c in hash):
|
| 63 |
+
raise HTTPException(
|
| 64 |
+
status_code=400,
|
| 65 |
+
detail="Invalid hash format. Only hexadecimal characters allowed."
|
| 66 |
+
)
|
| 67 |
+
|
| 68 |
+
result = await vt_service.lookup_hash(hash.lower())
|
| 69 |
+
|
| 70 |
+
if not result.found and result.error_message:
|
| 71 |
+
# Don't raise error for "not found" - just return the response
|
| 72 |
+
if "not found" not in result.error_message.lower():
|
| 73 |
+
logger.warning(f"VirusTotal lookup issue: {result.error_message}")
|
| 74 |
+
|
| 75 |
+
return result
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
@router.post("/compare", response_model=ComparisonResult)
|
| 79 |
+
async def compare_predictions(
|
| 80 |
+
request: CompareRequest,
|
| 81 |
+
ml_service: MLService = Depends(get_ml_service),
|
| 82 |
+
vt_service: VirusTotalService = Depends(get_virustotal_service)
|
| 83 |
+
) -> ComparisonResult:
|
| 84 |
+
"""
|
| 85 |
+
Compare XGBoost prediction with VirusTotal results.
|
| 86 |
+
|
| 87 |
+
Runs the XGBoost model on the provided features and queries
|
| 88 |
+
VirusTotal for the hash, then compares the verdicts.
|
| 89 |
+
|
| 90 |
+
Returns an agreement indicator showing whether both systems
|
| 91 |
+
agree on whether the sample is malicious or benign.
|
| 92 |
+
"""
|
| 93 |
+
try:
|
| 94 |
+
# Run XGBoost prediction
|
| 95 |
+
prediction = ml_service.predict(
|
| 96 |
+
features=request.features,
|
| 97 |
+
sha256=request.sha256
|
| 98 |
+
)
|
| 99 |
+
|
| 100 |
+
# Query VirusTotal
|
| 101 |
+
vt_result = await vt_service.lookup_hash(request.sha256)
|
| 102 |
+
|
| 103 |
+
if not vt_result.found:
|
| 104 |
+
raise HTTPException(
|
| 105 |
+
status_code=404,
|
| 106 |
+
detail=f"Hash not found on VirusTotal: {vt_result.error_message or 'Unknown error'}"
|
| 107 |
+
)
|
| 108 |
+
|
| 109 |
+
# Determine VirusTotal verdict
|
| 110 |
+
# Consider malicious if >10% of engines detect it
|
| 111 |
+
vt_is_malicious = (
|
| 112 |
+
vt_result.detection_ratio is not None and
|
| 113 |
+
vt_result.detection_ratio > 0.1
|
| 114 |
+
)
|
| 115 |
+
xgb_is_malicious = prediction.prediction == PredictionLabel.MALICIOUS
|
| 116 |
+
|
| 117 |
+
# Check agreement
|
| 118 |
+
agreement = vt_is_malicious == xgb_is_malicious
|
| 119 |
+
|
| 120 |
+
if agreement:
|
| 121 |
+
if xgb_is_malicious:
|
| 122 |
+
agreement_desc = "Both XGBoost and VirusTotal flag this sample as malicious."
|
| 123 |
+
else:
|
| 124 |
+
agreement_desc = "Both XGBoost and VirusTotal consider this sample benign."
|
| 125 |
+
else:
|
| 126 |
+
if xgb_is_malicious:
|
| 127 |
+
agreement_desc = "XGBoost flags as malicious, but VirusTotal has low detection rate."
|
| 128 |
+
else:
|
| 129 |
+
agreement_desc = "VirusTotal flags as malicious, but XGBoost predicts benign."
|
| 130 |
+
|
| 131 |
+
# ── Log RL feedback from the comparison ──────────────────────────
|
| 132 |
+
try:
|
| 133 |
+
feedback_svc = get_feedback_service()
|
| 134 |
+
rl_result = feedback_svc.log_malware_feedback(
|
| 135 |
+
features=request.features,
|
| 136 |
+
sha256=request.sha256,
|
| 137 |
+
predicted=prediction.prediction.value,
|
| 138 |
+
probability=prediction.probability,
|
| 139 |
+
vt_mal=vt_result.malicious_count or 0,
|
| 140 |
+
vt_total=vt_result.total_engines or 0,
|
| 141 |
+
vt_ratio=vt_result.detection_ratio or 0.0,
|
| 142 |
+
)
|
| 143 |
+
# Auto-trigger incremental update when enough samples accumulate
|
| 144 |
+
feedback_svc.maybe_auto_update("malware")
|
| 145 |
+
logger.info(f"Compare RL feedback: reward={rl_result['reward']}")
|
| 146 |
+
except Exception as e:
|
| 147 |
+
logger.warning(f"RL feedback during compare failed (non-critical): {e}")
|
| 148 |
+
|
| 149 |
+
return ComparisonResult(
|
| 150 |
+
xgboost_prediction=prediction.prediction,
|
| 151 |
+
xgboost_probability=prediction.probability,
|
| 152 |
+
virustotal_malicious_count=vt_result.malicious_count or 0,
|
| 153 |
+
virustotal_total_engines=vt_result.total_engines or 0,
|
| 154 |
+
virustotal_detection_ratio=vt_result.detection_ratio or 0.0,
|
| 155 |
+
agreement=agreement,
|
| 156 |
+
agreement_description=agreement_desc
|
| 157 |
+
)
|
| 158 |
+
|
| 159 |
+
except HTTPException:
|
| 160 |
+
raise
|
| 161 |
+
except ValueError as e:
|
| 162 |
+
raise HTTPException(status_code=400, detail=str(e))
|
| 163 |
+
except Exception as e:
|
| 164 |
+
logger.error(f"Comparison error: {e}")
|
| 165 |
+
raise HTTPException(status_code=500, detail="Comparison failed")
|
| 166 |
+
|
| 167 |
+
|
backend/app/services/__init__.py
ADDED
|
@@ -0,0 +1,6 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Services package
|
| 2 |
+
from .ml_service import MLService, get_ml_service
|
| 3 |
+
from .gemini_service import GeminiService, get_gemini_service
|
| 4 |
+
from .virustotal_service import VirusTotalService, get_virustotal_service
|
| 5 |
+
from .shap_service import SHAPService, get_shap_service
|
| 6 |
+
from .feedback_service import FeedbackService, get_feedback_service
|
backend/app/services/ember_features.py
ADDED
|
@@ -0,0 +1,645 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
EMBER Feature Extraction Service
|
| 3 |
+
Ported from elastic/ember for Python 3.12+ compatibility
|
| 4 |
+
|
| 5 |
+
Extracts 2381 features from PE (Portable Executable) files for malware detection.
|
| 6 |
+
Based on EMBER 2018 v2 feature format.
|
| 7 |
+
|
| 8 |
+
Original source: https://github.com/elastic/ember
|
| 9 |
+
"""
|
| 10 |
+
|
| 11 |
+
import re
|
| 12 |
+
import hashlib
|
| 13 |
+
import logging
|
| 14 |
+
import numpy as np
|
| 15 |
+
from typing import Dict, List, Any, Optional, Tuple
|
| 16 |
+
|
| 17 |
+
logger = logging.getLogger(__name__)
|
| 18 |
+
|
| 19 |
+
# Try to import lief - required for PE parsing
|
| 20 |
+
try:
|
| 21 |
+
import lief
|
| 22 |
+
LIEF_AVAILABLE = True
|
| 23 |
+
LIEF_MAJOR, LIEF_MINOR, *_ = lief.__version__.split('.')
|
| 24 |
+
LIEF_MAJOR = int(LIEF_MAJOR)
|
| 25 |
+
LIEF_MINOR = int(LIEF_MINOR)
|
| 26 |
+
LIEF_EXPORT_OBJECT = LIEF_MAJOR > 0 or (LIEF_MAJOR == 0 and LIEF_MINOR >= 10)
|
| 27 |
+
LIEF_HAS_SIGNATURE = LIEF_MAJOR > 0 or (LIEF_MAJOR == 0 and LIEF_MINOR >= 11)
|
| 28 |
+
logger.info(f"LIEF version {lief.__version__} loaded successfully")
|
| 29 |
+
except ImportError:
|
| 30 |
+
LIEF_AVAILABLE = False
|
| 31 |
+
LIEF_MAJOR = LIEF_MINOR = 0
|
| 32 |
+
LIEF_EXPORT_OBJECT = False
|
| 33 |
+
LIEF_HAS_SIGNATURE = False
|
| 34 |
+
logger.warning("LIEF library not available. PE feature extraction disabled.")
|
| 35 |
+
|
| 36 |
+
# Try to import sklearn FeatureHasher
|
| 37 |
+
try:
|
| 38 |
+
from sklearn.feature_extraction import FeatureHasher
|
| 39 |
+
SKLEARN_AVAILABLE = True
|
| 40 |
+
except ImportError:
|
| 41 |
+
SKLEARN_AVAILABLE = False
|
| 42 |
+
logger.warning("sklearn not available. Feature hashing disabled.")
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
class FeatureType:
|
| 46 |
+
"""Base class for feature extractors."""
|
| 47 |
+
name = ''
|
| 48 |
+
dim = 0
|
| 49 |
+
|
| 50 |
+
def __repr__(self):
|
| 51 |
+
return f'{self.name}({self.dim})'
|
| 52 |
+
|
| 53 |
+
def raw_features(self, bytez: bytes, lief_binary) -> Any:
|
| 54 |
+
"""Generate JSON-able representation of the file."""
|
| 55 |
+
raise NotImplementedError
|
| 56 |
+
|
| 57 |
+
def process_raw_features(self, raw_obj: Any) -> np.ndarray:
|
| 58 |
+
"""Generate a feature vector from raw features."""
|
| 59 |
+
raise NotImplementedError
|
| 60 |
+
|
| 61 |
+
def feature_vector(self, bytez: bytes, lief_binary) -> np.ndarray:
|
| 62 |
+
"""Calculate feature vector directly from sample."""
|
| 63 |
+
return self.process_raw_features(self.raw_features(bytez, lief_binary))
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
class ByteHistogram(FeatureType):
|
| 67 |
+
"""Byte histogram (normalized) over the entire binary file."""
|
| 68 |
+
name = 'histogram'
|
| 69 |
+
dim = 256
|
| 70 |
+
|
| 71 |
+
def raw_features(self, bytez: bytes, lief_binary) -> List[int]:
|
| 72 |
+
counts = np.bincount(np.frombuffer(bytez, dtype=np.uint8), minlength=256)
|
| 73 |
+
return counts.tolist()
|
| 74 |
+
|
| 75 |
+
def process_raw_features(self, raw_obj: List[int]) -> np.ndarray:
|
| 76 |
+
counts = np.array(raw_obj, dtype=np.float32)
|
| 77 |
+
total = counts.sum()
|
| 78 |
+
if total > 0:
|
| 79 |
+
normalized = counts / total
|
| 80 |
+
else:
|
| 81 |
+
normalized = counts
|
| 82 |
+
return normalized
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
class ByteEntropyHistogram(FeatureType):
|
| 86 |
+
"""
|
| 87 |
+
2D byte/entropy histogram based on Saxe and Berlin, 2015.
|
| 88 |
+
Approximates the joint probability of byte value and local entropy.
|
| 89 |
+
"""
|
| 90 |
+
name = 'byteentropy'
|
| 91 |
+
dim = 256
|
| 92 |
+
|
| 93 |
+
def __init__(self, step: int = 1024, window: int = 2048):
|
| 94 |
+
self.window = window
|
| 95 |
+
self.step = step
|
| 96 |
+
|
| 97 |
+
def _entropy_bin_counts(self, block: np.ndarray) -> Tuple[int, np.ndarray]:
|
| 98 |
+
"""Calculate entropy bin and coarse histogram."""
|
| 99 |
+
# Coarse histogram, 16 bytes per bin
|
| 100 |
+
c = np.bincount(block >> 4, minlength=16)
|
| 101 |
+
p = c.astype(np.float32) / self.window
|
| 102 |
+
wh = np.where(c)[0]
|
| 103 |
+
|
| 104 |
+
if len(wh) > 0:
|
| 105 |
+
H = np.sum(-p[wh] * np.log2(p[wh])) * 2
|
| 106 |
+
else:
|
| 107 |
+
H = 0.0
|
| 108 |
+
|
| 109 |
+
Hbin = int(H * 2) # Up to 16 bins (max entropy is 8 bits)
|
| 110 |
+
if Hbin == 16:
|
| 111 |
+
Hbin = 15
|
| 112 |
+
|
| 113 |
+
return Hbin, c
|
| 114 |
+
|
| 115 |
+
def raw_features(self, bytez: bytes, lief_binary) -> List[int]:
|
| 116 |
+
output = np.zeros((16, 16), dtype=np.int64)
|
| 117 |
+
a = np.frombuffer(bytez, dtype=np.uint8)
|
| 118 |
+
|
| 119 |
+
if a.shape[0] < self.window:
|
| 120 |
+
Hbin, c = self._entropy_bin_counts(a)
|
| 121 |
+
output[Hbin, :] += c
|
| 122 |
+
else:
|
| 123 |
+
# Strided trick for efficiency
|
| 124 |
+
shape = a.shape[:-1] + (a.shape[-1] - self.window + 1, self.window)
|
| 125 |
+
strides = a.strides + (a.strides[-1],)
|
| 126 |
+
blocks = np.lib.stride_tricks.as_strided(a, shape=shape, strides=strides)[::self.step, :]
|
| 127 |
+
|
| 128 |
+
for block in blocks:
|
| 129 |
+
Hbin, c = self._entropy_bin_counts(block)
|
| 130 |
+
output[Hbin, :] += c
|
| 131 |
+
|
| 132 |
+
return output.flatten().tolist()
|
| 133 |
+
|
| 134 |
+
def process_raw_features(self, raw_obj: List[int]) -> np.ndarray:
|
| 135 |
+
counts = np.array(raw_obj, dtype=np.float32)
|
| 136 |
+
total = counts.sum()
|
| 137 |
+
if total > 0:
|
| 138 |
+
normalized = counts / total
|
| 139 |
+
else:
|
| 140 |
+
normalized = counts
|
| 141 |
+
return normalized
|
| 142 |
+
|
| 143 |
+
|
| 144 |
+
class StringExtractor(FeatureType):
|
| 145 |
+
"""Extract string-based features from raw byte stream."""
|
| 146 |
+
name = 'strings'
|
| 147 |
+
dim = 104 # 1 + 1 + 1 + 96 + 1 + 1 + 1 + 1 + 1
|
| 148 |
+
|
| 149 |
+
def __init__(self):
|
| 150 |
+
# All consecutive runs of printable ASCII (0x20-0x7f) that are 5+ chars
|
| 151 |
+
self._allstrings = re.compile(b'[\x20-\x7f]{5,}')
|
| 152 |
+
# Occurrences of 'C:\'
|
| 153 |
+
self._paths = re.compile(b'c:\\\\', re.IGNORECASE)
|
| 154 |
+
# Occurrences of http:// or https://
|
| 155 |
+
self._urls = re.compile(b'https?://', re.IGNORECASE)
|
| 156 |
+
# Occurrences of HKEY_
|
| 157 |
+
self._registry = re.compile(b'HKEY_')
|
| 158 |
+
# Evidence of MZ header (dropper?)
|
| 159 |
+
self._mz = re.compile(b'MZ')
|
| 160 |
+
|
| 161 |
+
def raw_features(self, bytez: bytes, lief_binary) -> Dict:
|
| 162 |
+
allstrings = self._allstrings.findall(bytez)
|
| 163 |
+
|
| 164 |
+
if allstrings:
|
| 165 |
+
string_lengths = [len(s) for s in allstrings]
|
| 166 |
+
avlength = sum(string_lengths) / len(string_lengths)
|
| 167 |
+
|
| 168 |
+
# Map printable characters 0x20-0x7f to int array 0-95
|
| 169 |
+
as_shifted_string = [b - ord(b'\x20') for b in b''.join(allstrings)]
|
| 170 |
+
c = np.bincount(as_shifted_string, minlength=96)
|
| 171 |
+
csum = c.sum()
|
| 172 |
+
p = c.astype(np.float32) / csum if csum > 0 else c.astype(np.float32)
|
| 173 |
+
wh = np.where(c)[0]
|
| 174 |
+
H = np.sum(-p[wh] * np.log2(p[wh])) if len(wh) > 0 else 0.0
|
| 175 |
+
else:
|
| 176 |
+
avlength = 0
|
| 177 |
+
c = np.zeros((96,), dtype=np.float32)
|
| 178 |
+
H = 0
|
| 179 |
+
csum = 0
|
| 180 |
+
|
| 181 |
+
return {
|
| 182 |
+
'numstrings': len(allstrings),
|
| 183 |
+
'avlength': avlength,
|
| 184 |
+
'printabledist': c.tolist(),
|
| 185 |
+
'printables': int(csum),
|
| 186 |
+
'entropy': float(H),
|
| 187 |
+
'paths': len(self._paths.findall(bytez)),
|
| 188 |
+
'urls': len(self._urls.findall(bytez)),
|
| 189 |
+
'registry': len(self._registry.findall(bytez)),
|
| 190 |
+
'MZ': len(self._mz.findall(bytez))
|
| 191 |
+
}
|
| 192 |
+
|
| 193 |
+
def process_raw_features(self, raw_obj: Dict) -> np.ndarray:
|
| 194 |
+
hist_divisor = float(raw_obj['printables']) if raw_obj['printables'] > 0 else 1.0
|
| 195 |
+
return np.hstack([
|
| 196 |
+
raw_obj['numstrings'],
|
| 197 |
+
raw_obj['avlength'],
|
| 198 |
+
raw_obj['printables'],
|
| 199 |
+
np.asarray(raw_obj['printabledist']) / hist_divisor,
|
| 200 |
+
raw_obj['entropy'],
|
| 201 |
+
raw_obj['paths'],
|
| 202 |
+
raw_obj['urls'],
|
| 203 |
+
raw_obj['registry'],
|
| 204 |
+
raw_obj['MZ']
|
| 205 |
+
]).astype(np.float32)
|
| 206 |
+
|
| 207 |
+
|
| 208 |
+
class GeneralFileInfo(FeatureType):
|
| 209 |
+
"""General information about the PE file."""
|
| 210 |
+
name = 'general'
|
| 211 |
+
dim = 10
|
| 212 |
+
|
| 213 |
+
def raw_features(self, bytez: bytes, lief_binary) -> Dict:
|
| 214 |
+
if lief_binary is None:
|
| 215 |
+
return {
|
| 216 |
+
'size': len(bytez),
|
| 217 |
+
'vsize': 0,
|
| 218 |
+
'has_debug': 0,
|
| 219 |
+
'exports': 0,
|
| 220 |
+
'imports': 0,
|
| 221 |
+
'has_relocations': 0,
|
| 222 |
+
'has_resources': 0,
|
| 223 |
+
'has_signature': 0,
|
| 224 |
+
'has_tls': 0,
|
| 225 |
+
'symbols': 0
|
| 226 |
+
}
|
| 227 |
+
|
| 228 |
+
return {
|
| 229 |
+
'size': len(bytez),
|
| 230 |
+
'vsize': lief_binary.virtual_size,
|
| 231 |
+
'has_debug': int(lief_binary.has_debug),
|
| 232 |
+
'exports': len(lief_binary.exported_functions),
|
| 233 |
+
'imports': len(lief_binary.imported_functions),
|
| 234 |
+
'has_relocations': int(lief_binary.has_relocations),
|
| 235 |
+
'has_resources': int(lief_binary.has_resources),
|
| 236 |
+
'has_signature': int(lief_binary.has_signatures) if LIEF_HAS_SIGNATURE else int(lief_binary.has_signature),
|
| 237 |
+
'has_tls': int(lief_binary.has_tls),
|
| 238 |
+
'symbols': len(lief_binary.symbols),
|
| 239 |
+
}
|
| 240 |
+
|
| 241 |
+
def process_raw_features(self, raw_obj: Dict) -> np.ndarray:
|
| 242 |
+
return np.asarray([
|
| 243 |
+
raw_obj['size'],
|
| 244 |
+
raw_obj['vsize'],
|
| 245 |
+
raw_obj['has_debug'],
|
| 246 |
+
raw_obj['exports'],
|
| 247 |
+
raw_obj['imports'],
|
| 248 |
+
raw_obj['has_relocations'],
|
| 249 |
+
raw_obj['has_resources'],
|
| 250 |
+
raw_obj['has_signature'],
|
| 251 |
+
raw_obj['has_tls'],
|
| 252 |
+
raw_obj['symbols']
|
| 253 |
+
], dtype=np.float32)
|
| 254 |
+
|
| 255 |
+
|
| 256 |
+
class HeaderFileInfo(FeatureType):
|
| 257 |
+
"""Machine, architecture, OS, linker and other header information."""
|
| 258 |
+
name = 'header'
|
| 259 |
+
dim = 62
|
| 260 |
+
|
| 261 |
+
def raw_features(self, bytez: bytes, lief_binary) -> Dict:
|
| 262 |
+
raw_obj = {
|
| 263 |
+
'coff': {'timestamp': 0, 'machine': "", 'characteristics': []},
|
| 264 |
+
'optional': {
|
| 265 |
+
'subsystem': "",
|
| 266 |
+
'dll_characteristics': [],
|
| 267 |
+
'magic': "",
|
| 268 |
+
'major_image_version': 0,
|
| 269 |
+
'minor_image_version': 0,
|
| 270 |
+
'major_linker_version': 0,
|
| 271 |
+
'minor_linker_version': 0,
|
| 272 |
+
'major_operating_system_version': 0,
|
| 273 |
+
'minor_operating_system_version': 0,
|
| 274 |
+
'major_subsystem_version': 0,
|
| 275 |
+
'minor_subsystem_version': 0,
|
| 276 |
+
'sizeof_code': 0,
|
| 277 |
+
'sizeof_headers': 0,
|
| 278 |
+
'sizeof_heap_commit': 0
|
| 279 |
+
}
|
| 280 |
+
}
|
| 281 |
+
|
| 282 |
+
if lief_binary is None:
|
| 283 |
+
return raw_obj
|
| 284 |
+
|
| 285 |
+
raw_obj['coff']['timestamp'] = lief_binary.header.time_date_stamps
|
| 286 |
+
raw_obj['coff']['machine'] = str(lief_binary.header.machine).split('.')[-1]
|
| 287 |
+
raw_obj['coff']['characteristics'] = [
|
| 288 |
+
str(c).split('.')[-1] for c in lief_binary.header.characteristics_list
|
| 289 |
+
]
|
| 290 |
+
|
| 291 |
+
raw_obj['optional']['subsystem'] = str(lief_binary.optional_header.subsystem).split('.')[-1]
|
| 292 |
+
raw_obj['optional']['dll_characteristics'] = [
|
| 293 |
+
str(c).split('.')[-1] for c in lief_binary.optional_header.dll_characteristics_lists
|
| 294 |
+
]
|
| 295 |
+
raw_obj['optional']['magic'] = str(lief_binary.optional_header.magic).split('.')[-1]
|
| 296 |
+
raw_obj['optional']['major_image_version'] = lief_binary.optional_header.major_image_version
|
| 297 |
+
raw_obj['optional']['minor_image_version'] = lief_binary.optional_header.minor_image_version
|
| 298 |
+
raw_obj['optional']['major_linker_version'] = lief_binary.optional_header.major_linker_version
|
| 299 |
+
raw_obj['optional']['minor_linker_version'] = lief_binary.optional_header.minor_linker_version
|
| 300 |
+
raw_obj['optional']['major_operating_system_version'] = lief_binary.optional_header.major_operating_system_version
|
| 301 |
+
raw_obj['optional']['minor_operating_system_version'] = lief_binary.optional_header.minor_operating_system_version
|
| 302 |
+
raw_obj['optional']['major_subsystem_version'] = lief_binary.optional_header.major_subsystem_version
|
| 303 |
+
raw_obj['optional']['minor_subsystem_version'] = lief_binary.optional_header.minor_subsystem_version
|
| 304 |
+
raw_obj['optional']['sizeof_code'] = lief_binary.optional_header.sizeof_code
|
| 305 |
+
raw_obj['optional']['sizeof_headers'] = lief_binary.optional_header.sizeof_headers
|
| 306 |
+
raw_obj['optional']['sizeof_heap_commit'] = lief_binary.optional_header.sizeof_heap_commit
|
| 307 |
+
|
| 308 |
+
return raw_obj
|
| 309 |
+
|
| 310 |
+
def process_raw_features(self, raw_obj: Dict) -> np.ndarray:
|
| 311 |
+
return np.hstack([
|
| 312 |
+
raw_obj['coff']['timestamp'],
|
| 313 |
+
FeatureHasher(10, input_type="string").transform([[raw_obj['coff']['machine']]]).toarray()[0],
|
| 314 |
+
FeatureHasher(10, input_type="string").transform([raw_obj['coff']['characteristics']]).toarray()[0],
|
| 315 |
+
FeatureHasher(10, input_type="string").transform([[raw_obj['optional']['subsystem']]]).toarray()[0],
|
| 316 |
+
FeatureHasher(10, input_type="string").transform([raw_obj['optional']['dll_characteristics']]).toarray()[0],
|
| 317 |
+
FeatureHasher(10, input_type="string").transform([[raw_obj['optional']['magic']]]).toarray()[0],
|
| 318 |
+
raw_obj['optional']['major_image_version'],
|
| 319 |
+
raw_obj['optional']['minor_image_version'],
|
| 320 |
+
raw_obj['optional']['major_linker_version'],
|
| 321 |
+
raw_obj['optional']['minor_linker_version'],
|
| 322 |
+
raw_obj['optional']['major_operating_system_version'],
|
| 323 |
+
raw_obj['optional']['minor_operating_system_version'],
|
| 324 |
+
raw_obj['optional']['major_subsystem_version'],
|
| 325 |
+
raw_obj['optional']['minor_subsystem_version'],
|
| 326 |
+
raw_obj['optional']['sizeof_code'],
|
| 327 |
+
raw_obj['optional']['sizeof_headers'],
|
| 328 |
+
raw_obj['optional']['sizeof_heap_commit'],
|
| 329 |
+
]).astype(np.float32)
|
| 330 |
+
|
| 331 |
+
|
| 332 |
+
class SectionInfo(FeatureType):
|
| 333 |
+
"""Information about section names, sizes and entropy."""
|
| 334 |
+
name = 'section'
|
| 335 |
+
dim = 255 # 5 + 50 + 50 + 50 + 50 + 50
|
| 336 |
+
|
| 337 |
+
@staticmethod
|
| 338 |
+
def _properties(s) -> List[str]:
|
| 339 |
+
return [str(c).split('.')[-1] for c in s.characteristics_lists]
|
| 340 |
+
|
| 341 |
+
def raw_features(self, bytez: bytes, lief_binary) -> Dict:
|
| 342 |
+
if lief_binary is None:
|
| 343 |
+
return {"entry": "", "sections": []}
|
| 344 |
+
|
| 345 |
+
# Find entry section
|
| 346 |
+
try:
|
| 347 |
+
if LIEF_MAJOR > 0 or (LIEF_MAJOR == 0 and LIEF_MINOR >= 12):
|
| 348 |
+
section = lief_binary.section_from_rva(
|
| 349 |
+
lief_binary.entrypoint - lief_binary.imagebase
|
| 350 |
+
)
|
| 351 |
+
if section is None:
|
| 352 |
+
raise lief.not_found
|
| 353 |
+
entry_section = section.name
|
| 354 |
+
else:
|
| 355 |
+
entry_section = lief_binary.section_from_offset(lief_binary.entrypoint).name
|
| 356 |
+
except:
|
| 357 |
+
# Bad entry point, find first executable section
|
| 358 |
+
entry_section = ""
|
| 359 |
+
for s in lief_binary.sections:
|
| 360 |
+
if lief.PE.SECTION_CHARACTERISTICS.MEM_EXECUTE in s.characteristics_lists:
|
| 361 |
+
entry_section = s.name
|
| 362 |
+
break
|
| 363 |
+
|
| 364 |
+
raw_obj = {"entry": entry_section}
|
| 365 |
+
raw_obj["sections"] = [{
|
| 366 |
+
'name': s.name,
|
| 367 |
+
'size': s.size,
|
| 368 |
+
'entropy': s.entropy,
|
| 369 |
+
'vsize': s.virtual_size,
|
| 370 |
+
'props': self._properties(s)
|
| 371 |
+
} for s in lief_binary.sections]
|
| 372 |
+
|
| 373 |
+
return raw_obj
|
| 374 |
+
|
| 375 |
+
def process_raw_features(self, raw_obj: Dict) -> np.ndarray:
|
| 376 |
+
sections = raw_obj['sections']
|
| 377 |
+
general = [
|
| 378 |
+
len(sections),
|
| 379 |
+
sum(1 for s in sections if s['size'] == 0),
|
| 380 |
+
sum(1 for s in sections if s['name'] == ""),
|
| 381 |
+
sum(1 for s in sections if 'MEM_READ' in s['props'] and 'MEM_EXECUTE' in s['props']),
|
| 382 |
+
sum(1 for s in sections if 'MEM_WRITE' in s['props'])
|
| 383 |
+
]
|
| 384 |
+
|
| 385 |
+
# Section characteristics hashed
|
| 386 |
+
section_sizes = [(s['name'], s['size']) for s in sections]
|
| 387 |
+
section_sizes_hashed = FeatureHasher(50, input_type="pair").transform([section_sizes]).toarray()[0]
|
| 388 |
+
|
| 389 |
+
section_entropy = [(s['name'], s['entropy']) for s in sections]
|
| 390 |
+
section_entropy_hashed = FeatureHasher(50, input_type="pair").transform([section_entropy]).toarray()[0]
|
| 391 |
+
|
| 392 |
+
section_vsize = [(s['name'], s['vsize']) for s in sections]
|
| 393 |
+
section_vsize_hashed = FeatureHasher(50, input_type="pair").transform([section_vsize]).toarray()[0]
|
| 394 |
+
|
| 395 |
+
entry_name_hashed = FeatureHasher(50, input_type="string").transform([[raw_obj['entry']]]).toarray()[0]
|
| 396 |
+
|
| 397 |
+
characteristics = [p for s in sections for p in s['props'] if s['name'] == raw_obj['entry']]
|
| 398 |
+
characteristics_hashed = FeatureHasher(50, input_type="string").transform([characteristics]).toarray()[0]
|
| 399 |
+
|
| 400 |
+
return np.hstack([
|
| 401 |
+
general,
|
| 402 |
+
section_sizes_hashed,
|
| 403 |
+
section_entropy_hashed,
|
| 404 |
+
section_vsize_hashed,
|
| 405 |
+
entry_name_hashed,
|
| 406 |
+
characteristics_hashed
|
| 407 |
+
]).astype(np.float32)
|
| 408 |
+
|
| 409 |
+
|
| 410 |
+
class ImportsInfo(FeatureType):
|
| 411 |
+
"""Information about imported libraries and functions."""
|
| 412 |
+
name = 'imports'
|
| 413 |
+
dim = 1280
|
| 414 |
+
|
| 415 |
+
def raw_features(self, bytez: bytes, lief_binary) -> Dict[str, List[str]]:
|
| 416 |
+
imports = {}
|
| 417 |
+
if lief_binary is None:
|
| 418 |
+
return imports
|
| 419 |
+
|
| 420 |
+
for lib in lief_binary.imports:
|
| 421 |
+
if lib.name not in imports:
|
| 422 |
+
imports[lib.name] = []
|
| 423 |
+
|
| 424 |
+
for entry in lib.entries:
|
| 425 |
+
if entry.is_ordinal:
|
| 426 |
+
imports[lib.name].append("ordinal" + str(entry.ordinal))
|
| 427 |
+
else:
|
| 428 |
+
imports[lib.name].append(entry.name[:10000])
|
| 429 |
+
|
| 430 |
+
return imports
|
| 431 |
+
|
| 432 |
+
def process_raw_features(self, raw_obj: Dict[str, List[str]]) -> np.ndarray:
|
| 433 |
+
# Unique libraries
|
| 434 |
+
libraries = list(set([l.lower() for l in raw_obj.keys()]))
|
| 435 |
+
libraries_hashed = FeatureHasher(256, input_type="string").transform([libraries]).toarray()[0]
|
| 436 |
+
|
| 437 |
+
# Fully qualified import names
|
| 438 |
+
imports = [lib.lower() + ':' + e for lib, elist in raw_obj.items() for e in elist]
|
| 439 |
+
imports_hashed = FeatureHasher(1024, input_type="string").transform([imports]).toarray()[0]
|
| 440 |
+
|
| 441 |
+
return np.hstack([libraries_hashed, imports_hashed]).astype(np.float32)
|
| 442 |
+
|
| 443 |
+
|
| 444 |
+
class ExportsInfo(FeatureType):
|
| 445 |
+
"""Information about exported functions."""
|
| 446 |
+
name = 'exports'
|
| 447 |
+
dim = 128
|
| 448 |
+
|
| 449 |
+
def raw_features(self, bytez: bytes, lief_binary) -> List[str]:
|
| 450 |
+
if lief_binary is None:
|
| 451 |
+
return []
|
| 452 |
+
|
| 453 |
+
if LIEF_EXPORT_OBJECT:
|
| 454 |
+
clipped_exports = [export.name[:10000] for export in lief_binary.exported_functions]
|
| 455 |
+
else:
|
| 456 |
+
clipped_exports = [export[:10000] for export in lief_binary.exported_functions]
|
| 457 |
+
|
| 458 |
+
return clipped_exports
|
| 459 |
+
|
| 460 |
+
def process_raw_features(self, raw_obj: List[str]) -> np.ndarray:
|
| 461 |
+
exports_hashed = FeatureHasher(128, input_type="string").transform([raw_obj]).toarray()[0]
|
| 462 |
+
return exports_hashed.astype(np.float32)
|
| 463 |
+
|
| 464 |
+
|
| 465 |
+
class DataDirectories(FeatureType):
|
| 466 |
+
"""Size and virtual address of the first 15 data directories."""
|
| 467 |
+
name = 'datadirectories'
|
| 468 |
+
dim = 30 # 15 * 2
|
| 469 |
+
|
| 470 |
+
def __init__(self):
|
| 471 |
+
self._name_order = [
|
| 472 |
+
"EXPORT_TABLE", "IMPORT_TABLE", "RESOURCE_TABLE", "EXCEPTION_TABLE",
|
| 473 |
+
"CERTIFICATE_TABLE", "BASE_RELOCATION_TABLE", "DEBUG", "ARCHITECTURE",
|
| 474 |
+
"GLOBAL_PTR", "TLS_TABLE", "LOAD_CONFIG_TABLE", "BOUND_IMPORT",
|
| 475 |
+
"IAT", "DELAY_IMPORT_DESCRIPTOR", "CLR_RUNTIME_HEADER"
|
| 476 |
+
]
|
| 477 |
+
|
| 478 |
+
def raw_features(self, bytez: bytes, lief_binary) -> List[Dict]:
|
| 479 |
+
output = []
|
| 480 |
+
if lief_binary is None:
|
| 481 |
+
return output
|
| 482 |
+
|
| 483 |
+
for data_directory in lief_binary.data_directories:
|
| 484 |
+
output.append({
|
| 485 |
+
"name": str(data_directory.type).replace("DATA_DIRECTORY.", ""),
|
| 486 |
+
"size": data_directory.size,
|
| 487 |
+
"virtual_address": data_directory.rva
|
| 488 |
+
})
|
| 489 |
+
return output
|
| 490 |
+
|
| 491 |
+
def process_raw_features(self, raw_obj: List[Dict]) -> np.ndarray:
|
| 492 |
+
features = np.zeros(2 * len(self._name_order), dtype=np.float32)
|
| 493 |
+
for i in range(len(self._name_order)):
|
| 494 |
+
if i < len(raw_obj):
|
| 495 |
+
features[2 * i] = raw_obj[i]["size"]
|
| 496 |
+
features[2 * i + 1] = raw_obj[i]["virtual_address"]
|
| 497 |
+
return features
|
| 498 |
+
|
| 499 |
+
|
| 500 |
+
class PEFeatureExtractor:
|
| 501 |
+
"""
|
| 502 |
+
Extract 2381 features from a PE file (EMBER 2018 v2 format).
|
| 503 |
+
|
| 504 |
+
Usage:
|
| 505 |
+
extractor = PEFeatureExtractor()
|
| 506 |
+
with open("sample.exe", "rb") as f:
|
| 507 |
+
features = extractor.feature_vector(f.read())
|
| 508 |
+
# features is now a numpy array of 2381 float values
|
| 509 |
+
"""
|
| 510 |
+
|
| 511 |
+
def __init__(self, feature_version: int = 2):
|
| 512 |
+
if not LIEF_AVAILABLE:
|
| 513 |
+
raise ImportError("LIEF library is required for PE feature extraction. Install with: pip install lief")
|
| 514 |
+
|
| 515 |
+
if not SKLEARN_AVAILABLE:
|
| 516 |
+
raise ImportError("scikit-learn is required for feature hashing. Install with: pip install scikit-learn")
|
| 517 |
+
|
| 518 |
+
self.features = [
|
| 519 |
+
ByteHistogram(),
|
| 520 |
+
ByteEntropyHistogram(),
|
| 521 |
+
StringExtractor(),
|
| 522 |
+
GeneralFileInfo(),
|
| 523 |
+
HeaderFileInfo(),
|
| 524 |
+
SectionInfo(),
|
| 525 |
+
ImportsInfo(),
|
| 526 |
+
ExportsInfo(),
|
| 527 |
+
]
|
| 528 |
+
|
| 529 |
+
if feature_version == 2:
|
| 530 |
+
self.features.append(DataDirectories())
|
| 531 |
+
|
| 532 |
+
self.dim = sum([fe.dim for fe in self.features])
|
| 533 |
+
logger.info(f"PEFeatureExtractor initialized with {self.dim} features (version {feature_version})")
|
| 534 |
+
|
| 535 |
+
def raw_features(self, bytez: bytes) -> Dict[str, Any]:
|
| 536 |
+
"""Extract raw features from PE bytes."""
|
| 537 |
+
lief_binary = None
|
| 538 |
+
|
| 539 |
+
try:
|
| 540 |
+
lief_binary = lief.PE.parse(list(bytez))
|
| 541 |
+
except Exception as e:
|
| 542 |
+
logger.warning(f"LIEF parsing error: {e}")
|
| 543 |
+
lief_binary = None
|
| 544 |
+
|
| 545 |
+
features = {"sha256": hashlib.sha256(bytez).hexdigest()}
|
| 546 |
+
features.update({fe.name: fe.raw_features(bytez, lief_binary) for fe in self.features})
|
| 547 |
+
return features
|
| 548 |
+
|
| 549 |
+
def process_raw_features(self, raw_obj: Dict[str, Any]) -> np.ndarray:
|
| 550 |
+
"""Process raw features into a feature vector."""
|
| 551 |
+
feature_vectors = [fe.process_raw_features(raw_obj[fe.name]) for fe in self.features]
|
| 552 |
+
return np.hstack(feature_vectors).astype(np.float32)
|
| 553 |
+
|
| 554 |
+
def feature_vector(self, bytez: bytes) -> np.ndarray:
|
| 555 |
+
"""
|
| 556 |
+
Extract feature vector directly from PE file bytes.
|
| 557 |
+
|
| 558 |
+
Args:
|
| 559 |
+
bytez: Raw bytes of the PE file
|
| 560 |
+
|
| 561 |
+
Returns:
|
| 562 |
+
numpy array of 2381 float32 features
|
| 563 |
+
"""
|
| 564 |
+
return self.process_raw_features(self.raw_features(bytez))
|
| 565 |
+
|
| 566 |
+
def extract_with_hash(self, bytez: bytes) -> Tuple[np.ndarray, str]:
|
| 567 |
+
"""
|
| 568 |
+
Extract features and return SHA256 hash.
|
| 569 |
+
|
| 570 |
+
Args:
|
| 571 |
+
bytez: Raw bytes of the PE file
|
| 572 |
+
|
| 573 |
+
Returns:
|
| 574 |
+
Tuple of (feature_vector, sha256_hash)
|
| 575 |
+
"""
|
| 576 |
+
raw = self.raw_features(bytez)
|
| 577 |
+
return self.process_raw_features(raw), raw["sha256"]
|
| 578 |
+
|
| 579 |
+
|
| 580 |
+
# Singleton instance
|
| 581 |
+
_extractor_instance: Optional[PEFeatureExtractor] = None
|
| 582 |
+
|
| 583 |
+
|
| 584 |
+
def get_feature_extractor() -> PEFeatureExtractor:
|
| 585 |
+
"""Get or create the singleton feature extractor."""
|
| 586 |
+
global _extractor_instance
|
| 587 |
+
if _extractor_instance is None:
|
| 588 |
+
_extractor_instance = PEFeatureExtractor()
|
| 589 |
+
return _extractor_instance
|
| 590 |
+
|
| 591 |
+
|
| 592 |
+
def extract_features_from_file(file_path: str) -> Tuple[np.ndarray, str]:
|
| 593 |
+
"""
|
| 594 |
+
Extract EMBER features from a PE file.
|
| 595 |
+
|
| 596 |
+
Args:
|
| 597 |
+
file_path: Path to the PE file
|
| 598 |
+
|
| 599 |
+
Returns:
|
| 600 |
+
Tuple of (feature_vector, sha256_hash)
|
| 601 |
+
"""
|
| 602 |
+
with open(file_path, 'rb') as f:
|
| 603 |
+
bytez = f.read()
|
| 604 |
+
|
| 605 |
+
extractor = get_feature_extractor()
|
| 606 |
+
return extractor.extract_with_hash(bytez)
|
| 607 |
+
|
| 608 |
+
|
| 609 |
+
def extract_features_from_bytes(bytez: bytes) -> Tuple[np.ndarray, str]:
|
| 610 |
+
"""
|
| 611 |
+
Extract EMBER features from PE file bytes.
|
| 612 |
+
|
| 613 |
+
Args:
|
| 614 |
+
bytez: Raw bytes of the PE file
|
| 615 |
+
|
| 616 |
+
Returns:
|
| 617 |
+
Tuple of (feature_vector, sha256_hash)
|
| 618 |
+
"""
|
| 619 |
+
extractor = get_feature_extractor()
|
| 620 |
+
return extractor.extract_with_hash(bytez)
|
| 621 |
+
|
| 622 |
+
|
| 623 |
+
def extract_features_and_lief(bytez: bytes) -> Tuple[np.ndarray, str, any]:
|
| 624 |
+
"""
|
| 625 |
+
Extract EMBER features and return LIEF binary for additional analysis.
|
| 626 |
+
|
| 627 |
+
Args:
|
| 628 |
+
bytez: Raw bytes of the PE file
|
| 629 |
+
|
| 630 |
+
Returns:
|
| 631 |
+
Tuple of (feature_vector, sha256_hash, lief_binary)
|
| 632 |
+
"""
|
| 633 |
+
if not LIEF_AVAILABLE:
|
| 634 |
+
raise ImportError("LIEF is not available")
|
| 635 |
+
|
| 636 |
+
extractor = get_feature_extractor()
|
| 637 |
+
features, sha256 = extractor.extract_with_hash(bytez)
|
| 638 |
+
|
| 639 |
+
# Parse with LIEF for additional analysis
|
| 640 |
+
try:
|
| 641 |
+
lief_binary = lief.PE.parse(list(bytez))
|
| 642 |
+
except Exception:
|
| 643 |
+
lief_binary = None
|
| 644 |
+
|
| 645 |
+
return features, sha256, lief_binary
|
backend/app/services/feedback_service.py
ADDED
|
@@ -0,0 +1,474 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Reinforcement Learning Feedback Service
|
| 3 |
+
|
| 4 |
+
Persistent SQLite store for reward signals + incremental model updates.
|
| 5 |
+
|
| 6 |
+
Malware channel: XGBoost prediction vs VirusTotal consensus → auto-reward
|
| 7 |
+
URL channel: user confirms/denies model verdict → manual reward
|
| 8 |
+
|
| 9 |
+
Model updates use XGBoost's `xgb_model` parameter for incremental boosting
|
| 10 |
+
from the existing model — no full re-training required.
|
| 11 |
+
"""
|
| 12 |
+
|
| 13 |
+
from __future__ import annotations
|
| 14 |
+
|
| 15 |
+
import json
|
| 16 |
+
import logging
|
| 17 |
+
import sqlite3
|
| 18 |
+
import time
|
| 19 |
+
from datetime import datetime, timezone
|
| 20 |
+
from pathlib import Path
|
| 21 |
+
from typing import Optional
|
| 22 |
+
|
| 23 |
+
import joblib
|
| 24 |
+
import numpy as np
|
| 25 |
+
|
| 26 |
+
logger = logging.getLogger(__name__)
|
| 27 |
+
|
| 28 |
+
# Database lives alongside backend code — not committed to git
|
| 29 |
+
_DB_DIR = Path(__file__).parent.parent.parent.parent / "data"
|
| 30 |
+
_DB_PATH = _DB_DIR / "feedback.db"
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
class FeedbackService:
|
| 34 |
+
"""SQLite-backed RL feedback store with incremental training."""
|
| 35 |
+
|
| 36 |
+
def __init__(self):
|
| 37 |
+
_DB_DIR.mkdir(parents=True, exist_ok=True)
|
| 38 |
+
self._conn: Optional[sqlite3.Connection] = None
|
| 39 |
+
self._init_db()
|
| 40 |
+
|
| 41 |
+
# ── Database setup ────────────────────────────────────────────────────
|
| 42 |
+
|
| 43 |
+
def _get_conn(self) -> sqlite3.Connection:
|
| 44 |
+
if self._conn is None:
|
| 45 |
+
self._conn = sqlite3.connect(str(_DB_PATH), check_same_thread=False)
|
| 46 |
+
self._conn.row_factory = sqlite3.Row
|
| 47 |
+
self._conn.execute("PRAGMA journal_mode=WAL")
|
| 48 |
+
return self._conn
|
| 49 |
+
# Create the Feedback In Database
|
| 50 |
+
def _init_db(self):
|
| 51 |
+
conn = self._get_conn()
|
| 52 |
+
conn.executescript("""
|
| 53 |
+
CREATE TABLE IF NOT EXISTS malware_feedback (
|
| 54 |
+
id INTEGER PRIMARY KEY AUTOINCREMENT,
|
| 55 |
+
sha256 TEXT NOT NULL,
|
| 56 |
+
features TEXT NOT NULL,
|
| 57 |
+
predicted TEXT NOT NULL,
|
| 58 |
+
probability REAL NOT NULL,
|
| 59 |
+
vt_ratio REAL NOT NULL,
|
| 60 |
+
vt_mal INTEGER NOT NULL,
|
| 61 |
+
vt_total INTEGER NOT NULL,
|
| 62 |
+
reward INTEGER NOT NULL,
|
| 63 |
+
correct_label TEXT NOT NULL,
|
| 64 |
+
created_at TEXT NOT NULL
|
| 65 |
+
);
|
| 66 |
+
|
| 67 |
+
CREATE TABLE IF NOT EXISTS url_feedback (
|
| 68 |
+
id INTEGER PRIMARY KEY AUTOINCREMENT,
|
| 69 |
+
url TEXT NOT NULL,
|
| 70 |
+
predicted TEXT NOT NULL,
|
| 71 |
+
malicious_score REAL NOT NULL,
|
| 72 |
+
reward INTEGER NOT NULL,
|
| 73 |
+
correct_label TEXT NOT NULL,
|
| 74 |
+
base_model_scores TEXT NOT NULL,
|
| 75 |
+
created_at TEXT NOT NULL
|
| 76 |
+
);
|
| 77 |
+
|
| 78 |
+
CREATE TABLE IF NOT EXISTS model_updates (
|
| 79 |
+
id INTEGER PRIMARY KEY AUTOINCREMENT,
|
| 80 |
+
model_type TEXT NOT NULL,
|
| 81 |
+
samples_used INTEGER NOT NULL,
|
| 82 |
+
lr REAL NOT NULL,
|
| 83 |
+
rounds INTEGER NOT NULL,
|
| 84 |
+
created_at TEXT NOT NULL
|
| 85 |
+
);
|
| 86 |
+
""")
|
| 87 |
+
conn.commit()
|
| 88 |
+
logger.info(f"Feedback DB ready at {_DB_PATH}")
|
| 89 |
+
|
| 90 |
+
# ── Malware feedback ──────────────────────────────────────────────────
|
| 91 |
+
|
| 92 |
+
def log_malware_feedback(
|
| 93 |
+
self,
|
| 94 |
+
features: list[float],
|
| 95 |
+
sha256: str,
|
| 96 |
+
predicted: str,
|
| 97 |
+
probability: float,
|
| 98 |
+
vt_mal: int,
|
| 99 |
+
vt_total: int,
|
| 100 |
+
vt_ratio: float,
|
| 101 |
+
) -> dict:
|
| 102 |
+
"""
|
| 103 |
+
Log malware prediction feedback based on VirusTotal agreement.
|
| 104 |
+
|
| 105 |
+
Reward logic:
|
| 106 |
+
VT considers malicious if detection_ratio > 0.1
|
| 107 |
+
+1 if XGBoost and VT agree
|
| 108 |
+
-1 if they disagree
|
| 109 |
+
"""
|
| 110 |
+
vt_is_malicious = vt_ratio > 0.1
|
| 111 |
+
xgb_is_malicious = predicted.lower() == "malicious"
|
| 112 |
+
agree = vt_is_malicious == xgb_is_malicious
|
| 113 |
+
reward = 1 if agree else -1
|
| 114 |
+
|
| 115 |
+
# Correct label according to VT consensus
|
| 116 |
+
correct_label = "Malicious" if vt_is_malicious else "Benign"
|
| 117 |
+
|
| 118 |
+
now = datetime.now(timezone.utc).isoformat()
|
| 119 |
+
conn = self._get_conn()
|
| 120 |
+
conn.execute(
|
| 121 |
+
"""INSERT INTO malware_feedback
|
| 122 |
+
(sha256, features, predicted, probability, vt_ratio, vt_mal, vt_total,
|
| 123 |
+
reward, correct_label, created_at)
|
| 124 |
+
VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?)""",
|
| 125 |
+
(
|
| 126 |
+
sha256,
|
| 127 |
+
json.dumps(features),
|
| 128 |
+
predicted,
|
| 129 |
+
probability,
|
| 130 |
+
vt_ratio,
|
| 131 |
+
vt_mal,
|
| 132 |
+
vt_total,
|
| 133 |
+
reward,
|
| 134 |
+
correct_label,
|
| 135 |
+
now,
|
| 136 |
+
),
|
| 137 |
+
)
|
| 138 |
+
conn.commit()
|
| 139 |
+
|
| 140 |
+
total = conn.execute("SELECT COUNT(*) FROM malware_feedback").fetchone()[0]
|
| 141 |
+
logger.info(
|
| 142 |
+
f"Malware RL: sha256={sha256[:12]}… pred={predicted} vt_ratio={vt_ratio:.2f} "
|
| 143 |
+
f"reward={reward:+d} (total={total})"
|
| 144 |
+
)
|
| 145 |
+
return {
|
| 146 |
+
"success": True,
|
| 147 |
+
"reward": reward,
|
| 148 |
+
"message": f"{'Agreement' if agree else 'Disagreement'} with VirusTotal logged",
|
| 149 |
+
"total_feedback_count": total,
|
| 150 |
+
}
|
| 151 |
+
|
| 152 |
+
# ── URL feedback ──────────────────────────────────────────────────────
|
| 153 |
+
|
| 154 |
+
def log_url_feedback(
|
| 155 |
+
self,
|
| 156 |
+
url: str,
|
| 157 |
+
predicted: str,
|
| 158 |
+
malicious_score: float,
|
| 159 |
+
is_correct: bool,
|
| 160 |
+
base_model_scores: dict,
|
| 161 |
+
) -> dict:
|
| 162 |
+
"""
|
| 163 |
+
Log URL prediction feedback from user.
|
| 164 |
+
|
| 165 |
+
+1 if user says prediction is correct
|
| 166 |
+
-1 if user says prediction is wrong
|
| 167 |
+
"""
|
| 168 |
+
reward = 1 if is_correct else -1
|
| 169 |
+
|
| 170 |
+
if is_correct:
|
| 171 |
+
correct_label = predicted
|
| 172 |
+
else:
|
| 173 |
+
correct_label = "Benign" if predicted == "Malicious" else "Malicious"
|
| 174 |
+
|
| 175 |
+
now = datetime.now(timezone.utc).isoformat()
|
| 176 |
+
conn = self._get_conn()
|
| 177 |
+
conn.execute(
|
| 178 |
+
"""INSERT INTO url_feedback
|
| 179 |
+
(url, predicted, malicious_score, reward, correct_label,
|
| 180 |
+
base_model_scores, created_at)
|
| 181 |
+
VALUES (?, ?, ?, ?, ?, ?, ?)""",
|
| 182 |
+
(
|
| 183 |
+
url,
|
| 184 |
+
predicted,
|
| 185 |
+
malicious_score,
|
| 186 |
+
reward,
|
| 187 |
+
correct_label,
|
| 188 |
+
json.dumps(base_model_scores),
|
| 189 |
+
now,
|
| 190 |
+
),
|
| 191 |
+
)
|
| 192 |
+
conn.commit()
|
| 193 |
+
|
| 194 |
+
total = conn.execute("SELECT COUNT(*) FROM url_feedback").fetchone()[0]
|
| 195 |
+
logger.info(
|
| 196 |
+
f"URL RL: url={url[:40]}… pred={predicted} correct={is_correct} "
|
| 197 |
+
f"reward={reward:+d} (total={total})"
|
| 198 |
+
)
|
| 199 |
+
return {
|
| 200 |
+
"success": True,
|
| 201 |
+
"reward": reward,
|
| 202 |
+
"message": f"Feedback recorded — {'correct' if is_correct else 'incorrect'} prediction",
|
| 203 |
+
"total_feedback_count": total,
|
| 204 |
+
}
|
| 205 |
+
|
| 206 |
+
# ── Statistics ────────────────────────────────────────────────────────
|
| 207 |
+
|
| 208 |
+
# Auto-update threshold: update model after this many NEW samples since last update
|
| 209 |
+
AUTO_UPDATE_THRESHOLD = 50
|
| 210 |
+
|
| 211 |
+
def maybe_auto_update(self, model_type: str) -> Optional[dict]:
|
| 212 |
+
"""
|
| 213 |
+
Check if enough feedback has accumulated since the last
|
| 214 |
+
incremental update and trigger one automatically.
|
| 215 |
+
|
| 216 |
+
Returns update result dict or None if threshold not yet reached.
|
| 217 |
+
"""
|
| 218 |
+
conn = self._get_conn()
|
| 219 |
+
table = "malware_feedback" if model_type == "malware" else "url_feedback"
|
| 220 |
+
|
| 221 |
+
total_feedback = conn.execute(f"SELECT COUNT(*) FROM {table}").fetchone()[0]
|
| 222 |
+
|
| 223 |
+
# How many samples were used in the most recent update?
|
| 224 |
+
row = conn.execute(
|
| 225 |
+
"SELECT samples_used FROM model_updates "
|
| 226 |
+
"WHERE model_type = ? ORDER BY id DESC LIMIT 1",
|
| 227 |
+
(model_type,),
|
| 228 |
+
).fetchone()
|
| 229 |
+
last_samples = row["samples_used"] if row else 0
|
| 230 |
+
|
| 231 |
+
new_samples = total_feedback - last_samples
|
| 232 |
+
if new_samples >= self.AUTO_UPDATE_THRESHOLD:
|
| 233 |
+
logger.info(
|
| 234 |
+
f"Auto-update triggered for {model_type}: "
|
| 235 |
+
f"{new_samples} new samples ≥ {self.AUTO_UPDATE_THRESHOLD}"
|
| 236 |
+
)
|
| 237 |
+
try:
|
| 238 |
+
if model_type == "malware":
|
| 239 |
+
return self.update_malware_model(min_samples=1)
|
| 240 |
+
else:
|
| 241 |
+
return self.update_url_model(min_samples=1)
|
| 242 |
+
except Exception as e:
|
| 243 |
+
logger.error(f"Auto-update failed for {model_type}: {e}")
|
| 244 |
+
return None
|
| 245 |
+
return None
|
| 246 |
+
|
| 247 |
+
def get_stats(self) -> dict:
|
| 248 |
+
conn = self._get_conn()
|
| 249 |
+
|
| 250 |
+
# Malware stats
|
| 251 |
+
m_total = conn.execute("SELECT COUNT(*) FROM malware_feedback").fetchone()[0]
|
| 252 |
+
m_agree = conn.execute(
|
| 253 |
+
"SELECT COUNT(*) FROM malware_feedback WHERE reward = 1"
|
| 254 |
+
).fetchone()[0]
|
| 255 |
+
m_disagree = m_total - m_agree
|
| 256 |
+
m_rate = (m_agree / m_total * 100) if m_total > 0 else 0.0
|
| 257 |
+
|
| 258 |
+
# URL stats
|
| 259 |
+
u_total = conn.execute("SELECT COUNT(*) FROM url_feedback").fetchone()[0]
|
| 260 |
+
u_correct = conn.execute(
|
| 261 |
+
"SELECT COUNT(*) FROM url_feedback WHERE reward = 1"
|
| 262 |
+
).fetchone()[0]
|
| 263 |
+
u_incorrect = u_total - u_correct
|
| 264 |
+
u_rate = (u_correct / u_total * 100) if u_total > 0 else 0.0
|
| 265 |
+
|
| 266 |
+
# Recent malware feedback (last 10)
|
| 267 |
+
recent_m = [
|
| 268 |
+
dict(r)
|
| 269 |
+
for r in conn.execute(
|
| 270 |
+
"SELECT id, sha256, predicted, probability, vt_ratio, reward, created_at "
|
| 271 |
+
"FROM malware_feedback ORDER BY id DESC LIMIT 10"
|
| 272 |
+
).fetchall()
|
| 273 |
+
]
|
| 274 |
+
|
| 275 |
+
# Recent URL feedback (last 10)
|
| 276 |
+
recent_u = [
|
| 277 |
+
dict(r)
|
| 278 |
+
for r in conn.execute(
|
| 279 |
+
"SELECT id, url, predicted, malicious_score, reward, created_at "
|
| 280 |
+
"FROM url_feedback ORDER BY id DESC LIMIT 10"
|
| 281 |
+
).fetchall()
|
| 282 |
+
]
|
| 283 |
+
|
| 284 |
+
# Model updates
|
| 285 |
+
updates = [
|
| 286 |
+
dict(r)
|
| 287 |
+
for r in conn.execute(
|
| 288 |
+
"SELECT * FROM model_updates ORDER BY id DESC LIMIT 10"
|
| 289 |
+
).fetchall()
|
| 290 |
+
]
|
| 291 |
+
|
| 292 |
+
return {
|
| 293 |
+
"malware_total": m_total,
|
| 294 |
+
"malware_agree": m_agree,
|
| 295 |
+
"malware_disagree": m_disagree,
|
| 296 |
+
"malware_agreement_rate": round(m_rate, 1),
|
| 297 |
+
"url_total": u_total,
|
| 298 |
+
"url_correct": u_correct,
|
| 299 |
+
"url_incorrect": u_incorrect,
|
| 300 |
+
"url_accuracy_rate": round(u_rate, 1),
|
| 301 |
+
"recent_malware": recent_m,
|
| 302 |
+
"recent_url": recent_u,
|
| 303 |
+
"model_updates": updates,
|
| 304 |
+
}
|
| 305 |
+
|
| 306 |
+
# ── Incremental model updates ─────────────────────────────────────────
|
| 307 |
+
|
| 308 |
+
def update_malware_model(
|
| 309 |
+
self, min_samples: int = 10, lr: float = 0.01, rounds: int = 5
|
| 310 |
+
) -> dict:
|
| 311 |
+
"""
|
| 312 |
+
Incrementally update the malware XGBoost model with accumulated
|
| 313 |
+
feedback. Uses `xgb_model` for continuation training.
|
| 314 |
+
"""
|
| 315 |
+
import xgboost as xgb
|
| 316 |
+
from .ml_service import get_ml_service
|
| 317 |
+
|
| 318 |
+
conn = self._get_conn()
|
| 319 |
+
rows = conn.execute(
|
| 320 |
+
"SELECT features, correct_label FROM malware_feedback"
|
| 321 |
+
).fetchall()
|
| 322 |
+
|
| 323 |
+
if len(rows) < min_samples:
|
| 324 |
+
return {
|
| 325 |
+
"success": False,
|
| 326 |
+
"model_type": "malware",
|
| 327 |
+
"samples_used": len(rows),
|
| 328 |
+
"message": f"Need ≥ {min_samples} samples, have {len(rows)}",
|
| 329 |
+
}
|
| 330 |
+
|
| 331 |
+
X = np.array([json.loads(r["features"]) for r in rows], dtype=np.float32)
|
| 332 |
+
y = np.array(
|
| 333 |
+
[1 if r["correct_label"] == "Malicious" else 0 for r in rows],
|
| 334 |
+
dtype=np.float32,
|
| 335 |
+
)
|
| 336 |
+
|
| 337 |
+
ml_service = get_ml_service()
|
| 338 |
+
booster = ml_service.model.get_booster()
|
| 339 |
+
dtrain = xgb.DMatrix(X, label=y)
|
| 340 |
+
|
| 341 |
+
params = {
|
| 342 |
+
"objective": "binary:logistic",
|
| 343 |
+
"eval_metric": "logloss",
|
| 344 |
+
"learning_rate": lr,
|
| 345 |
+
"max_depth": 3,
|
| 346 |
+
}
|
| 347 |
+
|
| 348 |
+
updated = xgb.train(
|
| 349 |
+
params, dtrain, num_boost_round=rounds, xgb_model=booster
|
| 350 |
+
)
|
| 351 |
+
|
| 352 |
+
# Patch sklearn model with updated booster
|
| 353 |
+
ml_service.model._Booster = updated
|
| 354 |
+
|
| 355 |
+
# Persist
|
| 356 |
+
model_path = (
|
| 357 |
+
Path(__file__).parent.parent.parent.parent / "xgb_malware_model.joblib"
|
| 358 |
+
)
|
| 359 |
+
joblib.dump(ml_service.model, model_path)
|
| 360 |
+
|
| 361 |
+
# Log update
|
| 362 |
+
now = datetime.now(timezone.utc).isoformat()
|
| 363 |
+
conn.execute(
|
| 364 |
+
"INSERT INTO model_updates (model_type, samples_used, lr, rounds, created_at) "
|
| 365 |
+
"VALUES (?, ?, ?, ?, ?)",
|
| 366 |
+
("malware", len(rows), lr, rounds, now),
|
| 367 |
+
)
|
| 368 |
+
conn.commit()
|
| 369 |
+
|
| 370 |
+
logger.info(
|
| 371 |
+
f"Malware model updated: {len(rows)} samples, lr={lr}, rounds={rounds}"
|
| 372 |
+
)
|
| 373 |
+
return {
|
| 374 |
+
"success": True,
|
| 375 |
+
"model_type": "malware",
|
| 376 |
+
"samples_used": len(rows),
|
| 377 |
+
"message": f"Model updated with {len(rows)} feedback samples ({rounds} rounds, lr={lr})",
|
| 378 |
+
}
|
| 379 |
+
|
| 380 |
+
def update_url_model(
|
| 381 |
+
self, min_samples: int = 10, lr: float = 0.01, rounds: int = 5
|
| 382 |
+
) -> dict:
|
| 383 |
+
"""
|
| 384 |
+
Incrementally update the URL meta-learner with accumulated
|
| 385 |
+
user feedback. Reconstructs 10 meta-features from stored
|
| 386 |
+
base model scores.
|
| 387 |
+
"""
|
| 388 |
+
import xgboost as xgb
|
| 389 |
+
from .url_service import get_url_service
|
| 390 |
+
|
| 391 |
+
conn = self._get_conn()
|
| 392 |
+
rows = conn.execute(
|
| 393 |
+
"SELECT base_model_scores, correct_label FROM url_feedback"
|
| 394 |
+
).fetchall()
|
| 395 |
+
|
| 396 |
+
if len(rows) < min_samples:
|
| 397 |
+
return {
|
| 398 |
+
"success": False,
|
| 399 |
+
"model_type": "url",
|
| 400 |
+
"samples_used": len(rows),
|
| 401 |
+
"message": f"Need ≥ {min_samples} samples, have {len(rows)}",
|
| 402 |
+
}
|
| 403 |
+
|
| 404 |
+
BASE_MODEL_ORDER = [
|
| 405 |
+
"XGBoost", "LightGBM", "TF-IDF + LR", "CharCNN", "CharBiLSTM"
|
| 406 |
+
]
|
| 407 |
+
|
| 408 |
+
meta_features = []
|
| 409 |
+
labels = []
|
| 410 |
+
for r in rows:
|
| 411 |
+
scores = json.loads(r["base_model_scores"])
|
| 412 |
+
mf = []
|
| 413 |
+
for name in BASE_MODEL_ORDER:
|
| 414 |
+
mal = scores.get(name, 0.5)
|
| 415 |
+
mf.extend([1.0 - mal, mal])
|
| 416 |
+
meta_features.append(mf)
|
| 417 |
+
labels.append(1 if r["correct_label"] == "Malicious" else 0)
|
| 418 |
+
|
| 419 |
+
X = np.array(meta_features, dtype=np.float32)
|
| 420 |
+
y = np.array(labels, dtype=np.float32)
|
| 421 |
+
|
| 422 |
+
url_service = get_url_service()
|
| 423 |
+
booster = url_service.meta_learner.get_booster()
|
| 424 |
+
dtrain = xgb.DMatrix(X, label=y)
|
| 425 |
+
|
| 426 |
+
params = {
|
| 427 |
+
"objective": "binary:logistic",
|
| 428 |
+
"eval_metric": "logloss",
|
| 429 |
+
"learning_rate": lr,
|
| 430 |
+
"max_depth": 3,
|
| 431 |
+
}
|
| 432 |
+
|
| 433 |
+
updated = xgb.train(
|
| 434 |
+
params, dtrain, num_boost_round=rounds, xgb_model=booster
|
| 435 |
+
)
|
| 436 |
+
|
| 437 |
+
# Patch sklearn model
|
| 438 |
+
url_service.meta_learner._Booster = updated
|
| 439 |
+
|
| 440 |
+
# Persist
|
| 441 |
+
meta_path = url_service.models_dir / "hypermodel_meta.joblib"
|
| 442 |
+
joblib.dump(url_service.meta_learner, meta_path)
|
| 443 |
+
|
| 444 |
+
# Log update
|
| 445 |
+
now = datetime.now(timezone.utc).isoformat()
|
| 446 |
+
conn.execute(
|
| 447 |
+
"INSERT INTO model_updates (model_type, samples_used, lr, rounds, created_at) "
|
| 448 |
+
"VALUES (?, ?, ?, ?, ?)",
|
| 449 |
+
("url", len(rows), lr, rounds, now),
|
| 450 |
+
)
|
| 451 |
+
conn.commit()
|
| 452 |
+
|
| 453 |
+
logger.info(
|
| 454 |
+
f"URL meta-learner updated: {len(rows)} samples, lr={lr}, rounds={rounds}"
|
| 455 |
+
)
|
| 456 |
+
return {
|
| 457 |
+
"success": True,
|
| 458 |
+
"model_type": "url",
|
| 459 |
+
"samples_used": len(rows),
|
| 460 |
+
"message": f"URL meta-learner updated with {len(rows)} feedback samples ({rounds} rounds, lr={lr})",
|
| 461 |
+
}
|
| 462 |
+
|
| 463 |
+
|
| 464 |
+
# ── Singleton ─────────────────────────────────────────────────────────────────
|
| 465 |
+
|
| 466 |
+
_feedback_service: Optional[FeedbackService] = None
|
| 467 |
+
|
| 468 |
+
|
| 469 |
+
def get_feedback_service() -> FeedbackService:
|
| 470 |
+
"""Get or create the singleton feedback service."""
|
| 471 |
+
global _feedback_service
|
| 472 |
+
if _feedback_service is None:
|
| 473 |
+
_feedback_service = FeedbackService()
|
| 474 |
+
return _feedback_service
|
backend/app/services/gemini_service.py
ADDED
|
@@ -0,0 +1,263 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Gemini AI Service for malware analysis explanations.
|
| 3 |
+
Provides human-readable explanations of XGBoost predictions.
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
import logging
|
| 7 |
+
from typing import Optional, List
|
| 8 |
+
import json
|
| 9 |
+
|
| 10 |
+
from ..config import settings
|
| 11 |
+
from ..models.prediction import (
|
| 12 |
+
PredictionResponse,
|
| 13 |
+
GeminiExplanation,
|
| 14 |
+
SeverityLevel,
|
| 15 |
+
FeatureImportance,
|
| 16 |
+
)
|
| 17 |
+
|
| 18 |
+
logger = logging.getLogger(__name__)
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
PREFERRED_GEMINI_MODELS = [
|
| 22 |
+
"gemini-flash-lite-latest",
|
| 23 |
+
"gemini-2.0-flash-lite",
|
| 24 |
+
"gemini-2.0-flash-lite-001",
|
| 25 |
+
"gemini-flash-latest",
|
| 26 |
+
"gemini-2.0-flash",
|
| 27 |
+
]
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
# Gemini prompt template for malware analysis
|
| 31 |
+
ANALYSIS_PROMPT_TEMPLATE = """You are an expert malware analyst assistant. Analyze the following malware detection results and provide a professional cybersecurity assessment.
|
| 32 |
+
|
| 33 |
+
## Prediction Results
|
| 34 |
+
- **Classification**: {prediction}
|
| 35 |
+
- **Malware Probability**: {probability:.1%}
|
| 36 |
+
- **Confidence Level**: {confidence}
|
| 37 |
+
{sha256_section}
|
| 38 |
+
|
| 39 |
+
## Top Contributing Features
|
| 40 |
+
{features_section}
|
| 41 |
+
|
| 42 |
+
## Instructions
|
| 43 |
+
Based on the above prediction results, provide your analysis in the following JSON format:
|
| 44 |
+
|
| 45 |
+
{{
|
| 46 |
+
"risk_explanation": "A 2-3 sentence explanation of why this sample was classified as {prediction}. Focus on the technical indicators from the features.",
|
| 47 |
+
"severity_level": "One of: Critical, High, Medium, Low, None",
|
| 48 |
+
"key_indicators": ["List of 3-5 key indicators identified from the features"],
|
| 49 |
+
"analyst_summary": "A professional 2-3 sentence summary suitable for a security analyst report.",
|
| 50 |
+
"mitigation_steps": ["If malicious, list 3-5 recommended mitigation steps. If benign, set to null."]
|
| 51 |
+
}}
|
| 52 |
+
|
| 53 |
+
Important:
|
| 54 |
+
- DO NOT override the model's prediction. Your role is to explain, not reclassify.
|
| 55 |
+
- Base your analysis on the provided features and probability.
|
| 56 |
+
- Be specific about which feature categories contribute to the classification.
|
| 57 |
+
- Use professional cybersecurity terminology.
|
| 58 |
+
- If probability is high (>80%), emphasize the confidence. If low confidence, mention uncertainty.
|
| 59 |
+
|
| 60 |
+
Respond ONLY with the JSON object, no additional text."""
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
def _format_features_section(features: Optional[List[FeatureImportance]]) -> str:
|
| 64 |
+
"""Format feature importance for the prompt."""
|
| 65 |
+
if not features:
|
| 66 |
+
return "No detailed feature analysis available."
|
| 67 |
+
|
| 68 |
+
lines = []
|
| 69 |
+
for f in features[:10]: # Limit to top 10
|
| 70 |
+
lines.append(
|
| 71 |
+
f"- **{f.feature_name}**: {f.importance_value:.4f} ({f.contribution} malware probability)"
|
| 72 |
+
)
|
| 73 |
+
|
| 74 |
+
return "\n".join(lines)
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
class GeminiService:
|
| 78 |
+
"""
|
| 79 |
+
Gemini AI Service for generating malware analysis explanations.
|
| 80 |
+
|
| 81 |
+
This service:
|
| 82 |
+
- Takes XGBoost prediction results
|
| 83 |
+
- Sends them to Gemini for analysis
|
| 84 |
+
- Returns structured explanations
|
| 85 |
+
- Does NOT override the model's prediction
|
| 86 |
+
"""
|
| 87 |
+
|
| 88 |
+
def __init__(self):
|
| 89 |
+
self.model = None
|
| 90 |
+
self.initialized = False
|
| 91 |
+
self._genai = None
|
| 92 |
+
|
| 93 |
+
def initialize(self) -> bool:
|
| 94 |
+
"""
|
| 95 |
+
Initialize the Gemini AI client.
|
| 96 |
+
|
| 97 |
+
Returns:
|
| 98 |
+
True if initialization successful
|
| 99 |
+
"""
|
| 100 |
+
if not settings.gemini_api_key:
|
| 101 |
+
logger.warning("Gemini API key not configured")
|
| 102 |
+
return False
|
| 103 |
+
|
| 104 |
+
try:
|
| 105 |
+
import google.generativeai as genai
|
| 106 |
+
|
| 107 |
+
self._genai = genai
|
| 108 |
+
|
| 109 |
+
genai.configure(api_key=settings.gemini_api_key)
|
| 110 |
+
|
| 111 |
+
self.model = None
|
| 112 |
+
for model_name in PREFERRED_GEMINI_MODELS:
|
| 113 |
+
try:
|
| 114 |
+
self.model = genai.GenerativeModel(model_name)
|
| 115 |
+
logger.info(
|
| 116 |
+
"Gemini AI service initialized with model %s", model_name
|
| 117 |
+
)
|
| 118 |
+
break
|
| 119 |
+
except Exception as model_error:
|
| 120 |
+
logger.warning(
|
| 121 |
+
"Failed to prepare Gemini model %s: %s", model_name, model_error
|
| 122 |
+
)
|
| 123 |
+
|
| 124 |
+
if self.model is None:
|
| 125 |
+
logger.error("No Gemini model could be initialized")
|
| 126 |
+
return False
|
| 127 |
+
|
| 128 |
+
self.initialized = True
|
| 129 |
+
return True
|
| 130 |
+
|
| 131 |
+
except ImportError:
|
| 132 |
+
logger.error("google-generativeai package not installed")
|
| 133 |
+
return False
|
| 134 |
+
except Exception as e:
|
| 135 |
+
logger.error(f"Failed to initialize Gemini: {e}")
|
| 136 |
+
return False
|
| 137 |
+
|
| 138 |
+
async def explain_prediction(
|
| 139 |
+
self,
|
| 140 |
+
prediction: PredictionResponse,
|
| 141 |
+
features: Optional[List[FeatureImportance]] = None,
|
| 142 |
+
) -> GeminiExplanation:
|
| 143 |
+
"""
|
| 144 |
+
Generate explanation for a malware prediction.
|
| 145 |
+
|
| 146 |
+
Args:
|
| 147 |
+
prediction: XGBoost prediction result
|
| 148 |
+
features: Optional list of top contributing features
|
| 149 |
+
|
| 150 |
+
Returns:
|
| 151 |
+
GeminiExplanation with analysis
|
| 152 |
+
"""
|
| 153 |
+
if not self.initialized:
|
| 154 |
+
self.initialize()
|
| 155 |
+
|
| 156 |
+
if not self.initialized or self.model is None:
|
| 157 |
+
return self._get_fallback_explanation(prediction)
|
| 158 |
+
|
| 159 |
+
try:
|
| 160 |
+
# Build the prompt
|
| 161 |
+
sha256_section = ""
|
| 162 |
+
if prediction.sha256:
|
| 163 |
+
sha256_section = f"- **SHA256 Hash**: {prediction.sha256}"
|
| 164 |
+
|
| 165 |
+
features_section = _format_features_section(features)
|
| 166 |
+
|
| 167 |
+
prompt = ANALYSIS_PROMPT_TEMPLATE.format(
|
| 168 |
+
prediction=prediction.prediction.value,
|
| 169 |
+
probability=prediction.probability,
|
| 170 |
+
confidence=prediction.confidence.value,
|
| 171 |
+
sha256_section=sha256_section,
|
| 172 |
+
features_section=features_section,
|
| 173 |
+
)
|
| 174 |
+
|
| 175 |
+
# Call Gemini API
|
| 176 |
+
response = self.model.generate_content(prompt)
|
| 177 |
+
|
| 178 |
+
# Parse JSON response
|
| 179 |
+
response_text = response.text.strip()
|
| 180 |
+
|
| 181 |
+
# Clean up response if wrapped in code blocks
|
| 182 |
+
if response_text.startswith("```json"):
|
| 183 |
+
response_text = response_text[7:]
|
| 184 |
+
if response_text.startswith("```"):
|
| 185 |
+
response_text = response_text[3:]
|
| 186 |
+
if response_text.endswith("```"):
|
| 187 |
+
response_text = response_text[:-3]
|
| 188 |
+
|
| 189 |
+
analysis = json.loads(response_text.strip())
|
| 190 |
+
|
| 191 |
+
return GeminiExplanation(
|
| 192 |
+
risk_explanation=analysis.get(
|
| 193 |
+
"risk_explanation", "Analysis unavailable"
|
| 194 |
+
),
|
| 195 |
+
severity_level=SeverityLevel(analysis.get("severity_level", "Medium")),
|
| 196 |
+
key_indicators=analysis.get("key_indicators", []),
|
| 197 |
+
analyst_summary=analysis.get("analyst_summary", ""),
|
| 198 |
+
mitigation_steps=analysis.get("mitigation_steps"),
|
| 199 |
+
)
|
| 200 |
+
|
| 201 |
+
except json.JSONDecodeError as e:
|
| 202 |
+
logger.error(f"Failed to parse Gemini response: {e}")
|
| 203 |
+
return self._get_fallback_explanation(prediction)
|
| 204 |
+
except Exception as e:
|
| 205 |
+
logger.error(f"Gemini API error: {e}")
|
| 206 |
+
return self._get_fallback_explanation(prediction)
|
| 207 |
+
|
| 208 |
+
def _get_fallback_explanation(
|
| 209 |
+
self, prediction: PredictionResponse
|
| 210 |
+
) -> GeminiExplanation:
|
| 211 |
+
"""Generate a basic explanation when Gemini is unavailable."""
|
| 212 |
+
is_malicious = prediction.prediction.value == "Malicious"
|
| 213 |
+
|
| 214 |
+
if is_malicious:
|
| 215 |
+
severity = (
|
| 216 |
+
SeverityLevel.HIGH
|
| 217 |
+
if prediction.probability > 0.8
|
| 218 |
+
else SeverityLevel.MEDIUM
|
| 219 |
+
)
|
| 220 |
+
return GeminiExplanation(
|
| 221 |
+
risk_explanation=f"The XGBoost model classified this sample as malicious with {prediction.probability:.1%} probability. This indicates the presence of suspicious patterns commonly found in malware.",
|
| 222 |
+
severity_level=severity,
|
| 223 |
+
key_indicators=[
|
| 224 |
+
"Sample matches malware patterns in trained dataset",
|
| 225 |
+
f"Prediction confidence: {prediction.confidence.value}",
|
| 226 |
+
f"Probability score: {prediction.probability:.1%}",
|
| 227 |
+
],
|
| 228 |
+
analyst_summary=f"Automated analysis flagged this sample as potentially malicious. Manual review recommended.",
|
| 229 |
+
mitigation_steps=[
|
| 230 |
+
"Quarantine the file immediately",
|
| 231 |
+
"Do not execute or open the file",
|
| 232 |
+
"Scan with multiple antivirus engines",
|
| 233 |
+
"Check VirusTotal for additional context",
|
| 234 |
+
"Report to security team if in enterprise environment",
|
| 235 |
+
],
|
| 236 |
+
)
|
| 237 |
+
else:
|
| 238 |
+
return GeminiExplanation(
|
| 239 |
+
risk_explanation=f"The XGBoost model classified this sample as benign with {1 - prediction.probability:.1%} confidence. The feature patterns do not match known malware signatures.",
|
| 240 |
+
severity_level=SeverityLevel.NONE,
|
| 241 |
+
key_indicators=[
|
| 242 |
+
"Sample does not match malware patterns",
|
| 243 |
+
f"Benign probability: {1 - prediction.probability:.1%}",
|
| 244 |
+
f"Prediction confidence: {prediction.confidence.value}",
|
| 245 |
+
],
|
| 246 |
+
analyst_summary="Automated analysis did not detect malicious patterns. Sample appears to be benign based on static analysis.",
|
| 247 |
+
mitigation_steps=None,
|
| 248 |
+
)
|
| 249 |
+
|
| 250 |
+
|
| 251 |
+
# Global service instance
|
| 252 |
+
_gemini_service: Optional[GeminiService] = None
|
| 253 |
+
|
| 254 |
+
|
| 255 |
+
def get_gemini_service() -> GeminiService:
|
| 256 |
+
"""Get the global Gemini service instance."""
|
| 257 |
+
global _gemini_service
|
| 258 |
+
|
| 259 |
+
if _gemini_service is None:
|
| 260 |
+
_gemini_service = GeminiService()
|
| 261 |
+
_gemini_service.initialize()
|
| 262 |
+
|
| 263 |
+
return _gemini_service
|
backend/app/services/malware_type_service.py
ADDED
|
@@ -0,0 +1,403 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Malware Type Classification Service
|
| 3 |
+
|
| 4 |
+
Combines heuristic analysis of PE features with VirusTotal labels
|
| 5 |
+
to determine the likely type/family of detected malware.
|
| 6 |
+
"""
|
| 7 |
+
|
| 8 |
+
import logging
|
| 9 |
+
import re
|
| 10 |
+
from typing import Optional, Dict, List, Tuple
|
| 11 |
+
from dataclasses import dataclass
|
| 12 |
+
from enum import Enum
|
| 13 |
+
|
| 14 |
+
logger = logging.getLogger(__name__)
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
class MalwareType(str, Enum):
|
| 18 |
+
"""Common malware types/categories."""
|
| 19 |
+
RANSOMWARE = "Ransomware"
|
| 20 |
+
TROJAN = "Trojan"
|
| 21 |
+
WORM = "Worm"
|
| 22 |
+
SPYWARE = "Spyware"
|
| 23 |
+
ADWARE = "Adware"
|
| 24 |
+
BACKDOOR = "Backdoor"
|
| 25 |
+
ROOTKIT = "Rootkit"
|
| 26 |
+
KEYLOGGER = "Keylogger"
|
| 27 |
+
BANKER = "Banking Trojan"
|
| 28 |
+
DROPPER = "Dropper"
|
| 29 |
+
DOWNLOADER = "Downloader"
|
| 30 |
+
RAT = "Remote Access Trojan"
|
| 31 |
+
CRYPTOMINER = "Cryptominer"
|
| 32 |
+
BOTNET = "Botnet"
|
| 33 |
+
PUP = "Potentially Unwanted Program"
|
| 34 |
+
GENERIC = "Generic Malware"
|
| 35 |
+
UNKNOWN = "Unknown"
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
@dataclass
|
| 39 |
+
class MalwareTypeResult:
|
| 40 |
+
"""Result of malware type classification."""
|
| 41 |
+
primary_type: str
|
| 42 |
+
confidence: str # High, Medium, Low
|
| 43 |
+
secondary_types: List[str]
|
| 44 |
+
indicators: List[str]
|
| 45 |
+
source: str # "heuristic", "virustotal", "combined"
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
# Suspicious import patterns for different malware types
|
| 49 |
+
MALWARE_IMPORT_SIGNATURES = {
|
| 50 |
+
MalwareType.RANSOMWARE: [
|
| 51 |
+
"CryptEncrypt", "CryptDecrypt", "CryptGenKey", "CryptAcquireContext",
|
| 52 |
+
"CryptImportKey", "CryptDestroyKey", "BCryptEncrypt", "BCryptDecrypt",
|
| 53 |
+
"FindFirstFile", "FindNextFile", "MoveFileEx", "DeleteFile",
|
| 54 |
+
"GetLogicalDriveStrings", "GetDriveType"
|
| 55 |
+
],
|
| 56 |
+
MalwareType.KEYLOGGER: [
|
| 57 |
+
"GetAsyncKeyState", "GetKeyState", "GetKeyboardState", "SetWindowsHookEx",
|
| 58 |
+
"CallNextHookEx", "GetForegroundWindow", "GetWindowText", "AttachThreadInput"
|
| 59 |
+
],
|
| 60 |
+
MalwareType.SPYWARE: [
|
| 61 |
+
"GetClipboardData", "OpenClipboard", "CreateToolhelp32Snapshot",
|
| 62 |
+
"Process32First", "Process32Next", "RegOpenKeyEx", "RegQueryValueEx",
|
| 63 |
+
"GetUserName", "GetComputerName", "SHGetFolderPath"
|
| 64 |
+
],
|
| 65 |
+
MalwareType.BACKDOOR: [
|
| 66 |
+
"socket", "connect", "send", "recv", "bind", "listen", "accept",
|
| 67 |
+
"WSAStartup", "WSASocket", "CreateProcess", "ShellExecute",
|
| 68 |
+
"WinExec", "CreateRemoteThread"
|
| 69 |
+
],
|
| 70 |
+
MalwareType.RAT: [
|
| 71 |
+
"CreateDesktop", "SwitchDesktop", "GetDesktopWindow", "keybd_event",
|
| 72 |
+
"mouse_event", "SendInput", "GetDC", "BitBlt", "CreateCompatibleBitmap",
|
| 73 |
+
"StartServiceCtrlDispatcher", "RegisterServiceCtrlHandler"
|
| 74 |
+
],
|
| 75 |
+
MalwareType.ROOTKIT: [
|
| 76 |
+
"NtQuerySystemInformation", "ZwQuerySystemInformation",
|
| 77 |
+
"NtOpenProcess", "ZwOpenProcess", "NtWriteVirtualMemory",
|
| 78 |
+
"IoCreateDriver", "ObRegisterCallbacks", "PsSetCreateProcessNotifyRoutine"
|
| 79 |
+
],
|
| 80 |
+
MalwareType.DROPPER: [
|
| 81 |
+
"URLDownloadToFile", "InternetOpen", "InternetOpenUrl", "InternetReadFile",
|
| 82 |
+
"CreateFile", "WriteFile", "CreateProcess", "WinExec",
|
| 83 |
+
"VirtualAlloc", "VirtualProtect"
|
| 84 |
+
],
|
| 85 |
+
MalwareType.DOWNLOADER: [
|
| 86 |
+
"URLDownloadToFile", "URLDownloadToCacheFile", "InternetOpen",
|
| 87 |
+
"InternetConnect", "HttpOpenRequest", "HttpSendRequest",
|
| 88 |
+
"WinHttpOpen", "WinHttpConnect", "WinHttpOpenRequest"
|
| 89 |
+
],
|
| 90 |
+
MalwareType.CRYPTOMINER: [
|
| 91 |
+
"CreateThread", "GetSystemInfo", "GetCurrentProcess", "SetPriorityClass",
|
| 92 |
+
"SetThreadPriority", "GetTickCount", "QueryPerformanceCounter"
|
| 93 |
+
],
|
| 94 |
+
MalwareType.WORM: [
|
| 95 |
+
"NetShareEnum", "NetUserEnum", "WNetOpenEnum", "WNetEnumResource",
|
| 96 |
+
"FindFirstFile", "FindNextFile", "CopyFile", "GetDriveType",
|
| 97 |
+
"GetLogicalDriveStrings"
|
| 98 |
+
],
|
| 99 |
+
MalwareType.BANKER: [
|
| 100 |
+
"InternetQueryOption", "HttpQueryInfo", "InternetSetOption",
|
| 101 |
+
"CertOpenStore", "CertFindCertificateInStore", "PFXImportCertStore",
|
| 102 |
+
"SetWindowsHookEx", "GetWindowText", "FindWindow"
|
| 103 |
+
],
|
| 104 |
+
}
|
| 105 |
+
|
| 106 |
+
# String patterns commonly found in malware
|
| 107 |
+
MALWARE_STRING_PATTERNS = {
|
| 108 |
+
MalwareType.RANSOMWARE: [
|
| 109 |
+
r"bitcoin", r"btc", r"wallet", r"ransom", r"decrypt", r"encrypt",
|
| 110 |
+
r"\.locked", r"\.encrypted", r"your files", r"pay.*\$", r"tor.*onion"
|
| 111 |
+
],
|
| 112 |
+
MalwareType.CRYPTOMINER: [
|
| 113 |
+
r"stratum\+tcp", r"xmrig", r"monero", r"hashrate", r"pool\.",
|
| 114 |
+
r"mining", r"nicehash", r"coinhive"
|
| 115 |
+
],
|
| 116 |
+
MalwareType.BOTNET: [
|
| 117 |
+
r"c2", r"command.*control", r"bot.*net", r"ddos", r"flood",
|
| 118 |
+
r"irc\.", r"mirai", r"tsunami"
|
| 119 |
+
],
|
| 120 |
+
MalwareType.RAT: [
|
| 121 |
+
r"remote.*access", r"rat", r"njrat", r"darkcomet", r"quasar",
|
| 122 |
+
r"asyncrat", r"reverse.*shell"
|
| 123 |
+
],
|
| 124 |
+
}
|
| 125 |
+
|
| 126 |
+
# Section characteristics indicating malware types
|
| 127 |
+
SECTION_INDICATORS = {
|
| 128 |
+
"high_entropy": (7.5, MalwareType.RANSOMWARE), # Encrypted/packed content
|
| 129 |
+
"upx": MalwareType.DROPPER, # UPX packed often used by droppers
|
| 130 |
+
"executable_data": MalwareType.BACKDOOR, # Data sections with execute permission
|
| 131 |
+
}
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
class MalwareTypeService:
|
| 135 |
+
"""
|
| 136 |
+
Service for classifying malware into specific types/families.
|
| 137 |
+
|
| 138 |
+
Uses a combination of:
|
| 139 |
+
1. Import table analysis
|
| 140 |
+
2. String pattern matching
|
| 141 |
+
3. PE section characteristics
|
| 142 |
+
4. VirusTotal vendor labels (if available)
|
| 143 |
+
"""
|
| 144 |
+
|
| 145 |
+
def __init__(self):
|
| 146 |
+
self.initialized = True
|
| 147 |
+
logger.info("Malware Type Service initialized")
|
| 148 |
+
|
| 149 |
+
def classify(
|
| 150 |
+
self,
|
| 151 |
+
imports: List[str] = None,
|
| 152 |
+
strings: List[str] = None,
|
| 153 |
+
sections: List[Dict] = None,
|
| 154 |
+
entropy: float = None,
|
| 155 |
+
vt_labels: List[str] = None
|
| 156 |
+
) -> MalwareTypeResult:
|
| 157 |
+
"""
|
| 158 |
+
Classify malware based on available indicators.
|
| 159 |
+
|
| 160 |
+
Args:
|
| 161 |
+
imports: List of imported function names
|
| 162 |
+
strings: List of strings extracted from the file
|
| 163 |
+
sections: List of PE section info dicts
|
| 164 |
+
entropy: Overall file entropy
|
| 165 |
+
vt_labels: Labels from VirusTotal vendors
|
| 166 |
+
|
| 167 |
+
Returns:
|
| 168 |
+
MalwareTypeResult with classification
|
| 169 |
+
"""
|
| 170 |
+
type_scores: Dict[MalwareType, float] = {t: 0.0 for t in MalwareType}
|
| 171 |
+
indicators: List[str] = []
|
| 172 |
+
|
| 173 |
+
# 1. Analyze imports
|
| 174 |
+
if imports:
|
| 175 |
+
import_results = self._analyze_imports(imports)
|
| 176 |
+
for mtype, score, indicator in import_results:
|
| 177 |
+
type_scores[mtype] += score
|
| 178 |
+
if indicator:
|
| 179 |
+
indicators.append(indicator)
|
| 180 |
+
|
| 181 |
+
# 2. Analyze strings
|
| 182 |
+
if strings:
|
| 183 |
+
string_results = self._analyze_strings(strings)
|
| 184 |
+
for mtype, score, indicator in string_results:
|
| 185 |
+
type_scores[mtype] += score
|
| 186 |
+
if indicator:
|
| 187 |
+
indicators.append(indicator)
|
| 188 |
+
|
| 189 |
+
# 3. Analyze entropy
|
| 190 |
+
if entropy and entropy > 7.5:
|
| 191 |
+
type_scores[MalwareType.RANSOMWARE] += 2.0
|
| 192 |
+
type_scores[MalwareType.DROPPER] += 1.5
|
| 193 |
+
indicators.append(f"High entropy ({entropy:.2f}) suggests encryption/packing")
|
| 194 |
+
|
| 195 |
+
# 4. Analyze sections
|
| 196 |
+
if sections:
|
| 197 |
+
section_results = self._analyze_sections(sections)
|
| 198 |
+
for mtype, score, indicator in section_results:
|
| 199 |
+
type_scores[mtype] += score
|
| 200 |
+
if indicator:
|
| 201 |
+
indicators.append(indicator)
|
| 202 |
+
|
| 203 |
+
# 5. Use VirusTotal labels if available
|
| 204 |
+
vt_type = None
|
| 205 |
+
if vt_labels:
|
| 206 |
+
vt_type = self._parse_vt_labels(vt_labels)
|
| 207 |
+
if vt_type and vt_type != MalwareType.UNKNOWN:
|
| 208 |
+
type_scores[vt_type] += 5.0 # VT labels are authoritative
|
| 209 |
+
indicators.append(f"VirusTotal classification: {vt_type.value}")
|
| 210 |
+
|
| 211 |
+
# Determine primary type
|
| 212 |
+
sorted_types = sorted(type_scores.items(), key=lambda x: x[1], reverse=True)
|
| 213 |
+
primary_type = sorted_types[0][0]
|
| 214 |
+
primary_score = sorted_types[0][1]
|
| 215 |
+
|
| 216 |
+
# If no strong signals, mark as generic
|
| 217 |
+
if primary_score < 1.0:
|
| 218 |
+
primary_type = MalwareType.GENERIC
|
| 219 |
+
confidence = "Low"
|
| 220 |
+
elif primary_score < 3.0:
|
| 221 |
+
confidence = "Medium"
|
| 222 |
+
else:
|
| 223 |
+
confidence = "High"
|
| 224 |
+
|
| 225 |
+
# Get secondary types (score > 1.0 and not primary)
|
| 226 |
+
secondary_types = [
|
| 227 |
+
t.value for t, score in sorted_types[1:4]
|
| 228 |
+
if score >= 1.0 and t != primary_type
|
| 229 |
+
]
|
| 230 |
+
|
| 231 |
+
# Determine source
|
| 232 |
+
if vt_type and vt_type == primary_type:
|
| 233 |
+
source = "virustotal"
|
| 234 |
+
elif vt_labels and indicators:
|
| 235 |
+
source = "combined"
|
| 236 |
+
else:
|
| 237 |
+
source = "heuristic"
|
| 238 |
+
|
| 239 |
+
return MalwareTypeResult(
|
| 240 |
+
primary_type=primary_type.value,
|
| 241 |
+
confidence=confidence,
|
| 242 |
+
secondary_types=secondary_types,
|
| 243 |
+
indicators=indicators[:5], # Limit to top 5 indicators
|
| 244 |
+
source=source
|
| 245 |
+
)
|
| 246 |
+
|
| 247 |
+
def _analyze_imports(self, imports: List[str]) -> List[Tuple[MalwareType, float, str]]:
|
| 248 |
+
"""Analyze imported functions for malware indicators."""
|
| 249 |
+
results = []
|
| 250 |
+
imports_lower = [i.lower() for i in imports]
|
| 251 |
+
|
| 252 |
+
for mtype, signatures in MALWARE_IMPORT_SIGNATURES.items():
|
| 253 |
+
matches = []
|
| 254 |
+
for sig in signatures:
|
| 255 |
+
if sig.lower() in imports_lower or any(sig.lower() in imp for imp in imports_lower):
|
| 256 |
+
matches.append(sig)
|
| 257 |
+
|
| 258 |
+
if matches:
|
| 259 |
+
score = min(len(matches) * 0.5, 3.0) # Cap at 3.0
|
| 260 |
+
indicator = f"Suspicious imports for {mtype.value}: {', '.join(matches[:3])}"
|
| 261 |
+
results.append((mtype, score, indicator))
|
| 262 |
+
|
| 263 |
+
return results
|
| 264 |
+
|
| 265 |
+
def _analyze_strings(self, strings: List[str]) -> List[Tuple[MalwareType, float, str]]:
|
| 266 |
+
"""Analyze strings for malware indicators."""
|
| 267 |
+
results = []
|
| 268 |
+
strings_combined = " ".join(strings).lower()
|
| 269 |
+
|
| 270 |
+
for mtype, patterns in MALWARE_STRING_PATTERNS.items():
|
| 271 |
+
matches = []
|
| 272 |
+
for pattern in patterns:
|
| 273 |
+
if re.search(pattern, strings_combined, re.IGNORECASE):
|
| 274 |
+
matches.append(pattern)
|
| 275 |
+
|
| 276 |
+
if matches:
|
| 277 |
+
score = min(len(matches) * 0.7, 3.0)
|
| 278 |
+
indicator = f"String patterns suggest {mtype.value}"
|
| 279 |
+
results.append((mtype, score, indicator))
|
| 280 |
+
|
| 281 |
+
return results
|
| 282 |
+
|
| 283 |
+
def _analyze_sections(self, sections: List[Dict]) -> List[Tuple[MalwareType, float, str]]:
|
| 284 |
+
"""Analyze PE sections for malware indicators."""
|
| 285 |
+
results = []
|
| 286 |
+
|
| 287 |
+
for section in sections:
|
| 288 |
+
name = section.get("name", "").lower()
|
| 289 |
+
entropy = section.get("entropy", 0)
|
| 290 |
+
characteristics = section.get("characteristics", 0)
|
| 291 |
+
|
| 292 |
+
# Check for UPX packing
|
| 293 |
+
if "upx" in name:
|
| 294 |
+
results.append((MalwareType.DROPPER, 1.5, "UPX packed section detected"))
|
| 295 |
+
|
| 296 |
+
# Check for high entropy sections
|
| 297 |
+
if entropy > 7.5:
|
| 298 |
+
results.append((
|
| 299 |
+
MalwareType.RANSOMWARE, 1.0,
|
| 300 |
+
f"High entropy section '{name}' ({entropy:.2f})"
|
| 301 |
+
))
|
| 302 |
+
|
| 303 |
+
# Check for executable data sections
|
| 304 |
+
if characteristics:
|
| 305 |
+
is_executable = characteristics & 0x20000000 # IMAGE_SCN_MEM_EXECUTE
|
| 306 |
+
is_writable = characteristics & 0x80000000 # IMAGE_SCN_MEM_WRITE
|
| 307 |
+
if is_executable and is_writable and "text" not in name:
|
| 308 |
+
results.append((
|
| 309 |
+
MalwareType.BACKDOOR, 1.5,
|
| 310 |
+
f"Suspicious RWX section '{name}'"
|
| 311 |
+
))
|
| 312 |
+
|
| 313 |
+
return results
|
| 314 |
+
|
| 315 |
+
def _parse_vt_labels(self, labels: List[str]) -> Optional[MalwareType]:
|
| 316 |
+
"""Parse VirusTotal vendor labels to determine malware type."""
|
| 317 |
+
labels_combined = " ".join(labels).lower()
|
| 318 |
+
|
| 319 |
+
# Priority order for type detection
|
| 320 |
+
type_keywords = [
|
| 321 |
+
(MalwareType.RANSOMWARE, ["ransom", "crypt", "locker", "wannacry", "locky", "cerber"]),
|
| 322 |
+
(MalwareType.RAT, ["rat", "remoteaccess", "njrat", "darkcomet", "quasar", "asyncrat"]),
|
| 323 |
+
(MalwareType.BANKER, ["banker", "banking", "zeus", "emotet", "trickbot", "dridex"]),
|
| 324 |
+
(MalwareType.BACKDOOR, ["backdoor", "back door", "reverseshell"]),
|
| 325 |
+
(MalwareType.ROOTKIT, ["rootkit", "bootkit"]),
|
| 326 |
+
(MalwareType.KEYLOGGER, ["keylog", "keylogger"]),
|
| 327 |
+
(MalwareType.CRYPTOMINER, ["miner", "coinminer", "cryptominer", "xmrig"]),
|
| 328 |
+
(MalwareType.WORM, ["worm", "conficker", "mydoom"]),
|
| 329 |
+
(MalwareType.SPYWARE, ["spyware", "spy", "infostealer", "stealer"]),
|
| 330 |
+
(MalwareType.ADWARE, ["adware", "pup", "unwanted"]),
|
| 331 |
+
(MalwareType.DROPPER, ["dropper", "downloader"]),
|
| 332 |
+
(MalwareType.TROJAN, ["trojan", "troj", "agent"]),
|
| 333 |
+
]
|
| 334 |
+
|
| 335 |
+
for mtype, keywords in type_keywords:
|
| 336 |
+
for keyword in keywords:
|
| 337 |
+
if keyword in labels_combined:
|
| 338 |
+
return mtype
|
| 339 |
+
|
| 340 |
+
return MalwareType.UNKNOWN
|
| 341 |
+
|
| 342 |
+
def classify_from_lief(self, lief_binary) -> MalwareTypeResult:
|
| 343 |
+
"""
|
| 344 |
+
Classify malware type directly from a LIEF parsed binary.
|
| 345 |
+
|
| 346 |
+
Args:
|
| 347 |
+
lief_binary: LIEF PE binary object
|
| 348 |
+
|
| 349 |
+
Returns:
|
| 350 |
+
MalwareTypeResult
|
| 351 |
+
"""
|
| 352 |
+
imports = []
|
| 353 |
+
sections = []
|
| 354 |
+
|
| 355 |
+
try:
|
| 356 |
+
# Extract imports
|
| 357 |
+
if hasattr(lief_binary, 'imports'):
|
| 358 |
+
for lib in lief_binary.imports:
|
| 359 |
+
for entry in lib.entries:
|
| 360 |
+
if entry.name:
|
| 361 |
+
imports.append(entry.name)
|
| 362 |
+
|
| 363 |
+
# Extract section info
|
| 364 |
+
if hasattr(lief_binary, 'sections'):
|
| 365 |
+
for section in lief_binary.sections:
|
| 366 |
+
sections.append({
|
| 367 |
+
"name": section.name,
|
| 368 |
+
"entropy": section.entropy,
|
| 369 |
+
"characteristics": section.characteristics
|
| 370 |
+
})
|
| 371 |
+
|
| 372 |
+
# Calculate overall entropy
|
| 373 |
+
entropy = None
|
| 374 |
+
if sections:
|
| 375 |
+
entropy = sum(s.get("entropy", 0) for s in sections) / len(sections)
|
| 376 |
+
|
| 377 |
+
return self.classify(
|
| 378 |
+
imports=imports,
|
| 379 |
+
sections=sections,
|
| 380 |
+
entropy=entropy
|
| 381 |
+
)
|
| 382 |
+
|
| 383 |
+
except Exception as e:
|
| 384 |
+
logger.error(f"Error classifying from LIEF: {e}")
|
| 385 |
+
return MalwareTypeResult(
|
| 386 |
+
primary_type=MalwareType.UNKNOWN.value,
|
| 387 |
+
confidence="Low",
|
| 388 |
+
secondary_types=[],
|
| 389 |
+
indicators=["Error during classification"],
|
| 390 |
+
source="heuristic"
|
| 391 |
+
)
|
| 392 |
+
|
| 393 |
+
|
| 394 |
+
# Singleton instance
|
| 395 |
+
_malware_type_service: Optional[MalwareTypeService] = None
|
| 396 |
+
|
| 397 |
+
|
| 398 |
+
def get_malware_type_service() -> MalwareTypeService:
|
| 399 |
+
"""Get or create the malware type service singleton."""
|
| 400 |
+
global _malware_type_service
|
| 401 |
+
if _malware_type_service is None:
|
| 402 |
+
_malware_type_service = MalwareTypeService()
|
| 403 |
+
return _malware_type_service
|
backend/app/services/ml_service.py
ADDED
|
@@ -0,0 +1,198 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Machine Learning Service for XGBoost Malware Detection.
|
| 3 |
+
Handles model loading, inference, and prediction formatting.
|
| 4 |
+
Optimized for fast inference with single model load.
|
| 5 |
+
"""
|
| 6 |
+
|
| 7 |
+
import time
|
| 8 |
+
import logging
|
| 9 |
+
from pathlib import Path
|
| 10 |
+
from typing import Optional, Tuple
|
| 11 |
+
import numpy as np
|
| 12 |
+
import joblib
|
| 13 |
+
|
| 14 |
+
from ..config import settings
|
| 15 |
+
from ..models.prediction import (
|
| 16 |
+
PredictionLabel,
|
| 17 |
+
ConfidenceLevel,
|
| 18 |
+
PredictionResponse,
|
| 19 |
+
)
|
| 20 |
+
|
| 21 |
+
logger = logging.getLogger(__name__)
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
class MLService:
|
| 25 |
+
"""
|
| 26 |
+
XGBoost ML Service for malware detection.
|
| 27 |
+
|
| 28 |
+
Features:
|
| 29 |
+
- Single model load at startup (no reload per request)
|
| 30 |
+
- NumPy vectorization for fast inference
|
| 31 |
+
- Configurable prediction threshold
|
| 32 |
+
- Confidence level calculation
|
| 33 |
+
"""
|
| 34 |
+
|
| 35 |
+
def __init__(self):
|
| 36 |
+
self.model = None
|
| 37 |
+
self.model_loaded = False
|
| 38 |
+
self.feature_count = settings.ember_feature_count
|
| 39 |
+
self.default_threshold = settings.prediction_threshold
|
| 40 |
+
|
| 41 |
+
def load_model(self, model_path: Optional[str] = None) -> bool:
|
| 42 |
+
"""
|
| 43 |
+
Load the XGBoost model from disk.
|
| 44 |
+
Should be called once at application startup.
|
| 45 |
+
|
| 46 |
+
Args:
|
| 47 |
+
model_path: Path to the .joblib model file
|
| 48 |
+
|
| 49 |
+
Returns:
|
| 50 |
+
True if model loaded successfully
|
| 51 |
+
"""
|
| 52 |
+
if model_path is None:
|
| 53 |
+
# Look in parent directory (project root)
|
| 54 |
+
model_path = Path(__file__).parent.parent.parent.parent / settings.model_path
|
| 55 |
+
else:
|
| 56 |
+
model_path = Path(model_path)
|
| 57 |
+
|
| 58 |
+
try:
|
| 59 |
+
logger.info(f"Loading XGBoost model from: {model_path}")
|
| 60 |
+
start_time = time.time()
|
| 61 |
+
|
| 62 |
+
self.model = joblib.load(model_path)
|
| 63 |
+
|
| 64 |
+
load_time = (time.time() - start_time) * 1000
|
| 65 |
+
logger.info(f"Model loaded successfully in {load_time:.2f}ms")
|
| 66 |
+
|
| 67 |
+
self.model_loaded = True
|
| 68 |
+
return True
|
| 69 |
+
|
| 70 |
+
except FileNotFoundError:
|
| 71 |
+
logger.error(f"Model file not found: {model_path}")
|
| 72 |
+
raise RuntimeError(f"Model file not found: {model_path}")
|
| 73 |
+
except Exception as e:
|
| 74 |
+
logger.error(f"Failed to load model: {e}")
|
| 75 |
+
raise RuntimeError(f"Failed to load model: {e}")
|
| 76 |
+
|
| 77 |
+
def predict(
|
| 78 |
+
self,
|
| 79 |
+
features: list[float],
|
| 80 |
+
threshold: Optional[float] = None,
|
| 81 |
+
sha256: Optional[str] = None
|
| 82 |
+
) -> PredictionResponse:
|
| 83 |
+
"""
|
| 84 |
+
Run malware prediction on feature vector.
|
| 85 |
+
|
| 86 |
+
Args:
|
| 87 |
+
features: EMBER 2018 v2 feature vector (2381 values)
|
| 88 |
+
threshold: Custom threshold (default from config)
|
| 89 |
+
sha256: Optional hash for reference
|
| 90 |
+
|
| 91 |
+
Returns:
|
| 92 |
+
PredictionResponse with prediction, probability, confidence
|
| 93 |
+
"""
|
| 94 |
+
if not self.model_loaded:
|
| 95 |
+
raise RuntimeError("Model not loaded. Call load_model() first.")
|
| 96 |
+
|
| 97 |
+
# Validate feature count
|
| 98 |
+
if len(features) != self.feature_count:
|
| 99 |
+
raise ValueError(
|
| 100 |
+
f"Expected {self.feature_count} features, got {len(features)}"
|
| 101 |
+
)
|
| 102 |
+
|
| 103 |
+
# Use default threshold if not provided
|
| 104 |
+
if threshold is None:
|
| 105 |
+
threshold = self.default_threshold
|
| 106 |
+
|
| 107 |
+
# Convert to NumPy array for vectorized inference
|
| 108 |
+
start_time = time.time()
|
| 109 |
+
feature_array = np.array(features, dtype=np.float32).reshape(1, -1)
|
| 110 |
+
|
| 111 |
+
# Get probability prediction
|
| 112 |
+
# XGBoost predict_proba returns [[prob_benign, prob_malicious]]
|
| 113 |
+
try:
|
| 114 |
+
probabilities = self.model.predict_proba(feature_array)
|
| 115 |
+
malware_probability = float(probabilities[0][1])
|
| 116 |
+
except AttributeError:
|
| 117 |
+
# Fallback for models without predict_proba
|
| 118 |
+
prediction = self.model.predict(feature_array)
|
| 119 |
+
malware_probability = float(prediction[0])
|
| 120 |
+
|
| 121 |
+
inference_time = (time.time() - start_time) * 1000
|
| 122 |
+
|
| 123 |
+
# Determine prediction based on threshold
|
| 124 |
+
is_malicious = malware_probability >= threshold
|
| 125 |
+
prediction_label = (
|
| 126 |
+
PredictionLabel.MALICIOUS if is_malicious
|
| 127 |
+
else PredictionLabel.BENIGN
|
| 128 |
+
)
|
| 129 |
+
|
| 130 |
+
# Calculate confidence level
|
| 131 |
+
confidence = self._calculate_confidence(malware_probability)
|
| 132 |
+
|
| 133 |
+
return PredictionResponse(
|
| 134 |
+
prediction=prediction_label,
|
| 135 |
+
probability=round(malware_probability, 4),
|
| 136 |
+
confidence=confidence,
|
| 137 |
+
threshold_used=threshold,
|
| 138 |
+
sha256=sha256,
|
| 139 |
+
inference_time_ms=round(inference_time, 2)
|
| 140 |
+
)
|
| 141 |
+
|
| 142 |
+
def _calculate_confidence(self, probability: float) -> ConfidenceLevel:
|
| 143 |
+
"""
|
| 144 |
+
Calculate confidence level based on probability distance from threshold.
|
| 145 |
+
|
| 146 |
+
High confidence: probability < 0.2 or > 0.8
|
| 147 |
+
Medium confidence: probability 0.2-0.35 or 0.65-0.8
|
| 148 |
+
Low confidence: probability 0.35-0.65
|
| 149 |
+
"""
|
| 150 |
+
distance_from_uncertain = abs(probability - 0.5)
|
| 151 |
+
|
| 152 |
+
if distance_from_uncertain >= 0.3:
|
| 153 |
+
return ConfidenceLevel.HIGH
|
| 154 |
+
elif distance_from_uncertain >= 0.15:
|
| 155 |
+
return ConfidenceLevel.MEDIUM
|
| 156 |
+
else:
|
| 157 |
+
return ConfidenceLevel.LOW
|
| 158 |
+
|
| 159 |
+
def get_model_info(self) -> dict:
|
| 160 |
+
"""Get information about the loaded model."""
|
| 161 |
+
if not self.model_loaded:
|
| 162 |
+
return {"loaded": False}
|
| 163 |
+
|
| 164 |
+
info = {
|
| 165 |
+
"loaded": True,
|
| 166 |
+
"feature_count": self.feature_count,
|
| 167 |
+
"default_threshold": self.default_threshold,
|
| 168 |
+
"model_type": type(self.model).__name__,
|
| 169 |
+
}
|
| 170 |
+
|
| 171 |
+
# Try to get additional model attributes
|
| 172 |
+
try:
|
| 173 |
+
if hasattr(self.model, 'n_estimators'):
|
| 174 |
+
info["n_estimators"] = self.model.n_estimators
|
| 175 |
+
if hasattr(self.model, 'max_depth'):
|
| 176 |
+
info["max_depth"] = self.model.max_depth
|
| 177 |
+
except Exception:
|
| 178 |
+
pass
|
| 179 |
+
|
| 180 |
+
return info
|
| 181 |
+
|
| 182 |
+
|
| 183 |
+
# Global service instance (singleton pattern)
|
| 184 |
+
_ml_service: Optional[MLService] = None
|
| 185 |
+
|
| 186 |
+
|
| 187 |
+
def get_ml_service() -> MLService:
|
| 188 |
+
"""
|
| 189 |
+
Get the global ML service instance.
|
| 190 |
+
Creates and loads model on first call.
|
| 191 |
+
"""
|
| 192 |
+
global _ml_service
|
| 193 |
+
|
| 194 |
+
if _ml_service is None:
|
| 195 |
+
_ml_service = MLService()
|
| 196 |
+
_ml_service.load_model()
|
| 197 |
+
|
| 198 |
+
return _ml_service
|
backend/app/services/shap_service.py
ADDED
|
@@ -0,0 +1,203 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
SHAP Service for feature importance extraction.
|
| 3 |
+
Provides explainability for XGBoost malware predictions.
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
import logging
|
| 7 |
+
from typing import Optional, List
|
| 8 |
+
import numpy as np
|
| 9 |
+
|
| 10 |
+
from ..config import settings
|
| 11 |
+
from ..models.prediction import FeatureImportance
|
| 12 |
+
|
| 13 |
+
logger = logging.getLogger(__name__)
|
| 14 |
+
|
| 15 |
+
# EMBER 2018 v2 Feature Name Mapping
|
| 16 |
+
# These are the high-level feature categories from EMBER
|
| 17 |
+
EMBER_FEATURE_GROUPS = {
|
| 18 |
+
# Byte histogram (256 features, indices 0-255)
|
| 19 |
+
(0, 256): "byte_histogram",
|
| 20 |
+
# Byte-entropy histogram (256 features, indices 256-511)
|
| 21 |
+
(256, 512): "byte_entropy_histogram",
|
| 22 |
+
# String features (104 features, indices 512-615)
|
| 23 |
+
(512, 616): "string_features",
|
| 24 |
+
# General file info (10 features, indices 616-625)
|
| 25 |
+
(616, 626): "general_file_info",
|
| 26 |
+
# Header features (62 features, indices 626-687)
|
| 27 |
+
(626, 688): "header_features",
|
| 28 |
+
# Section features (255 features, indices 688-942)
|
| 29 |
+
(688, 943): "section_features",
|
| 30 |
+
# Import features (1280 features, indices 943-2222)
|
| 31 |
+
(943, 2223): "import_features",
|
| 32 |
+
# Export features (128 features, indices 2223-2350)
|
| 33 |
+
(2223, 2351): "export_features",
|
| 34 |
+
# Data directory features (30 features, indices 2351-2380)
|
| 35 |
+
(2351, 2381): "data_directory_features",
|
| 36 |
+
}
|
| 37 |
+
|
| 38 |
+
def get_feature_name(index: int) -> str:
|
| 39 |
+
"""Get human-readable feature name from index."""
|
| 40 |
+
for (start, end), name in EMBER_FEATURE_GROUPS.items():
|
| 41 |
+
if start <= index < end:
|
| 42 |
+
offset = index - start
|
| 43 |
+
return f"{name}[{offset}]"
|
| 44 |
+
return f"feature_{index}"
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
def get_feature_category(index: int) -> str:
|
| 48 |
+
"""Get feature category from index."""
|
| 49 |
+
for (start, end), name in EMBER_FEATURE_GROUPS.items():
|
| 50 |
+
if start <= index < end:
|
| 51 |
+
return name
|
| 52 |
+
return "unknown"
|
| 53 |
+
|
| 54 |
+
|
| 55 |
+
class SHAPService:
|
| 56 |
+
"""
|
| 57 |
+
SHAP (SHapley Additive exPlanations) service for model explainability.
|
| 58 |
+
|
| 59 |
+
Provides feature importance analysis to understand why
|
| 60 |
+
the model classified a sample as malicious or benign.
|
| 61 |
+
"""
|
| 62 |
+
|
| 63 |
+
def __init__(self):
|
| 64 |
+
self.explainer = None
|
| 65 |
+
self.initialized = False
|
| 66 |
+
self._shap_available = False
|
| 67 |
+
|
| 68 |
+
# Try to import SHAP
|
| 69 |
+
try:
|
| 70 |
+
import shap
|
| 71 |
+
self._shap = shap
|
| 72 |
+
self._shap_available = True
|
| 73 |
+
except ImportError:
|
| 74 |
+
logger.warning("SHAP library not available. Feature importance will be limited.")
|
| 75 |
+
|
| 76 |
+
def initialize(self, model) -> bool:
|
| 77 |
+
"""
|
| 78 |
+
Initialize SHAP explainer with the model.
|
| 79 |
+
|
| 80 |
+
Args:
|
| 81 |
+
model: Trained XGBoost model
|
| 82 |
+
|
| 83 |
+
Returns:
|
| 84 |
+
True if initialization successful
|
| 85 |
+
"""
|
| 86 |
+
if not self._shap_available:
|
| 87 |
+
logger.warning("SHAP not available, using fallback importance")
|
| 88 |
+
self.initialized = True
|
| 89 |
+
return True
|
| 90 |
+
|
| 91 |
+
try:
|
| 92 |
+
logger.info("Initializing SHAP TreeExplainer...")
|
| 93 |
+
self.explainer = self._shap.TreeExplainer(model)
|
| 94 |
+
self.initialized = True
|
| 95 |
+
logger.info("SHAP explainer initialized successfully")
|
| 96 |
+
return True
|
| 97 |
+
except Exception as e:
|
| 98 |
+
logger.error(f"Failed to initialize SHAP: {e}")
|
| 99 |
+
self.initialized = True # Still mark as initialized to use fallback
|
| 100 |
+
return False
|
| 101 |
+
|
| 102 |
+
def get_feature_importance(
|
| 103 |
+
self,
|
| 104 |
+
features: List[float],
|
| 105 |
+
model,
|
| 106 |
+
top_k: int = 10
|
| 107 |
+
) -> List[FeatureImportance]:
|
| 108 |
+
"""
|
| 109 |
+
Get top contributing features for a prediction.
|
| 110 |
+
|
| 111 |
+
Args:
|
| 112 |
+
features: Input feature vector
|
| 113 |
+
model: XGBoost model
|
| 114 |
+
top_k: Number of top features to return
|
| 115 |
+
|
| 116 |
+
Returns:
|
| 117 |
+
List of FeatureImportance objects
|
| 118 |
+
"""
|
| 119 |
+
feature_array = np.array(features, dtype=np.float32).reshape(1, -1)
|
| 120 |
+
|
| 121 |
+
if self._shap_available and self.explainer is not None:
|
| 122 |
+
return self._get_shap_importance(feature_array, top_k)
|
| 123 |
+
else:
|
| 124 |
+
return self._get_fallback_importance(feature_array, model, top_k)
|
| 125 |
+
|
| 126 |
+
def _get_shap_importance(
|
| 127 |
+
self,
|
| 128 |
+
feature_array: np.ndarray,
|
| 129 |
+
top_k: int
|
| 130 |
+
) -> List[FeatureImportance]:
|
| 131 |
+
"""Get feature importance using SHAP values."""
|
| 132 |
+
try:
|
| 133 |
+
shap_values = self.explainer.shap_values(feature_array)
|
| 134 |
+
|
| 135 |
+
# Handle different SHAP output formats
|
| 136 |
+
if isinstance(shap_values, list):
|
| 137 |
+
# For binary classification, use positive class
|
| 138 |
+
values = shap_values[1][0] if len(shap_values) > 1 else shap_values[0][0]
|
| 139 |
+
else:
|
| 140 |
+
values = shap_values[0]
|
| 141 |
+
|
| 142 |
+
# Get indices of top features by absolute value
|
| 143 |
+
top_indices = np.argsort(np.abs(values))[-top_k:][::-1]
|
| 144 |
+
|
| 145 |
+
importance_list = []
|
| 146 |
+
for idx in top_indices:
|
| 147 |
+
importance = float(values[idx])
|
| 148 |
+
importance_list.append(FeatureImportance(
|
| 149 |
+
feature_index=int(idx),
|
| 150 |
+
feature_name=get_feature_name(idx),
|
| 151 |
+
importance_value=round(importance, 4),
|
| 152 |
+
contribution="increases" if importance > 0 else "decreases"
|
| 153 |
+
))
|
| 154 |
+
|
| 155 |
+
return importance_list
|
| 156 |
+
|
| 157 |
+
except Exception as e:
|
| 158 |
+
logger.error(f"SHAP calculation failed: {e}")
|
| 159 |
+
return []
|
| 160 |
+
|
| 161 |
+
def _get_fallback_importance(
|
| 162 |
+
self,
|
| 163 |
+
feature_array: np.ndarray,
|
| 164 |
+
model,
|
| 165 |
+
top_k: int
|
| 166 |
+
) -> List[FeatureImportance]:
|
| 167 |
+
"""
|
| 168 |
+
Fallback importance using model's feature_importances_.
|
| 169 |
+
Less accurate than SHAP but faster.
|
| 170 |
+
"""
|
| 171 |
+
try:
|
| 172 |
+
if hasattr(model, 'feature_importances_'):
|
| 173 |
+
importances = model.feature_importances_
|
| 174 |
+
top_indices = np.argsort(importances)[-top_k:][::-1]
|
| 175 |
+
|
| 176 |
+
importance_list = []
|
| 177 |
+
for idx in top_indices:
|
| 178 |
+
importance_list.append(FeatureImportance(
|
| 179 |
+
feature_index=int(idx),
|
| 180 |
+
feature_name=get_feature_name(idx),
|
| 181 |
+
importance_value=round(float(importances[idx]), 4),
|
| 182 |
+
contribution="contributes" # Can't determine direction without SHAP
|
| 183 |
+
))
|
| 184 |
+
|
| 185 |
+
return importance_list
|
| 186 |
+
except Exception as e:
|
| 187 |
+
logger.error(f"Fallback importance failed: {e}")
|
| 188 |
+
|
| 189 |
+
return []
|
| 190 |
+
|
| 191 |
+
|
| 192 |
+
# Global service instance
|
| 193 |
+
_shap_service: Optional[SHAPService] = None
|
| 194 |
+
|
| 195 |
+
|
| 196 |
+
def get_shap_service() -> SHAPService:
|
| 197 |
+
"""Get the global SHAP service instance."""
|
| 198 |
+
global _shap_service
|
| 199 |
+
|
| 200 |
+
if _shap_service is None:
|
| 201 |
+
_shap_service = SHAPService()
|
| 202 |
+
|
| 203 |
+
return _shap_service
|
backend/app/services/url_feature_engineering.py
ADDED
|
@@ -0,0 +1,307 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
URL Feature Engineering — 54 lexical features for malicious URL detection.
|
| 3 |
+
|
| 4 |
+
Adapted from the URL model notebook for backend integration.
|
| 5 |
+
Features are grouped into 8 categories:
|
| 6 |
+
1. Length / structural (7 features)
|
| 7 |
+
2. Character counts (14 features)
|
| 8 |
+
3. Character ratios (5 features)
|
| 9 |
+
4. Entropy / randomness (2 features)
|
| 10 |
+
5. Boolean indicators (10 features)
|
| 11 |
+
6. Domain / TLD signals (6 features)
|
| 12 |
+
7. Suspicious-pattern scores (5 features)
|
| 13 |
+
8. Path & query analysis (5 features)
|
| 14 |
+
"""
|
| 15 |
+
|
| 16 |
+
from __future__ import annotations
|
| 17 |
+
|
| 18 |
+
import math
|
| 19 |
+
import re
|
| 20 |
+
from collections import Counter
|
| 21 |
+
from urllib.parse import urlparse, parse_qs
|
| 22 |
+
|
| 23 |
+
import numpy as np
|
| 24 |
+
|
| 25 |
+
try:
|
| 26 |
+
import tldextract
|
| 27 |
+
except ImportError:
|
| 28 |
+
tldextract = None
|
| 29 |
+
|
| 30 |
+
# ── Regex patterns (compiled once) ────────────────────────────────────────────
|
| 31 |
+
_IP_RE = re.compile(
|
| 32 |
+
r"(?:^|[/@])(\d{1,3}\.){3}\d{1,3}(?:[:/]|$)"
|
| 33 |
+
)
|
| 34 |
+
_HEX_RE = re.compile(r"%[0-9a-fA-F]{2}")
|
| 35 |
+
_SHORTENERS = frozenset([
|
| 36 |
+
"bit.ly", "goo.gl", "tinyurl.com", "ow.ly", "t.co", "is.gd",
|
| 37 |
+
"buff.ly", "adf.ly", "tiny.cc", "lnkd.in", "rb.gy", "cutt.ly",
|
| 38 |
+
"shorturl.at", "rebrand.ly",
|
| 39 |
+
])
|
| 40 |
+
_SUSPICIOUS_TLDS = frozenset([
|
| 41 |
+
"tk", "ml", "ga", "cf", "gq", "xyz", "top", "pw", "cc",
|
| 42 |
+
"club", "work", "date", "racing", "stream", "download",
|
| 43 |
+
"win", "bid", "icu", "buzz", "monster",
|
| 44 |
+
])
|
| 45 |
+
_SUSPICIOUS_EXT = re.compile(
|
| 46 |
+
r"\.(exe|zip|rar|scr|bat|cmd|js|vbs|ps1|dll|msi|apk|dmg|iso|php|cgi)(\?|$)",
|
| 47 |
+
re.IGNORECASE,
|
| 48 |
+
)
|
| 49 |
+
_PHISHING_KW = re.compile(
|
| 50 |
+
r"(login|signin|verify|account|update|secure|bank|confirm|password|"
|
| 51 |
+
r"credential|suspend|alert|notification|wallet|paypal|apple|microsoft|"
|
| 52 |
+
r"amazon|netflix|facebook|instagram|whatsapp|dropbox|google|icloud)",
|
| 53 |
+
re.IGNORECASE,
|
| 54 |
+
)
|
| 55 |
+
_BRAND_NAMES = [
|
| 56 |
+
"google", "facebook", "apple", "amazon", "microsoft", "netflix",
|
| 57 |
+
"paypal", "instagram", "whatsapp", "dropbox", "linkedin", "twitter",
|
| 58 |
+
"yahoo", "ebay", "chase", "wellsfargo", "bankofamerica", "citibank",
|
| 59 |
+
"hsbc", "dhl", "fedex", "usps",
|
| 60 |
+
]
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
# Feature names in the exact order the scaler/models expect
|
| 64 |
+
FEATURE_NAMES = [
|
| 65 |
+
# 1. Length
|
| 66 |
+
"url_length", "hostname_length", "domain_length", "path_length",
|
| 67 |
+
"query_length", "fragment_length", "tld_length",
|
| 68 |
+
# 2. Counts
|
| 69 |
+
"num_dots", "num_hyphens", "num_underscores", "num_slashes",
|
| 70 |
+
"num_at_signs", "num_ampersands", "num_equals", "num_question_marks",
|
| 71 |
+
"num_percent", "num_tilde", "num_digits", "num_letters",
|
| 72 |
+
"num_special", "num_params",
|
| 73 |
+
# 3. Ratios
|
| 74 |
+
"digit_ratio", "letter_ratio", "special_ratio", "uppercase_ratio",
|
| 75 |
+
"digit_letter_ratio",
|
| 76 |
+
# 4. Entropy
|
| 77 |
+
"url_entropy", "domain_entropy",
|
| 78 |
+
# 5. Booleans
|
| 79 |
+
"has_ip", "has_https", "has_http", "has_www", "has_port",
|
| 80 |
+
"has_at_symbol", "is_shortened", "has_double_slash_redirect",
|
| 81 |
+
"has_punycode", "has_hex_encoding",
|
| 82 |
+
# 6. Domain
|
| 83 |
+
"num_subdomains", "subdomain_length", "domain_token_count",
|
| 84 |
+
"has_suspicious_tld", "domain_has_digits", "domain_hyphen_count",
|
| 85 |
+
# 7. Suspicious
|
| 86 |
+
"phishing_keyword_count", "brand_count", "has_suspicious_ext",
|
| 87 |
+
"brand_in_subdomain", "suspicious_word_ratio",
|
| 88 |
+
# 8. Path / query
|
| 89 |
+
"path_depth", "longest_path_token", "avg_path_token_len",
|
| 90 |
+
"max_consecutive_digits", "path_entropy",
|
| 91 |
+
]
|
| 92 |
+
|
| 93 |
+
|
| 94 |
+
def _entropy(s: str) -> float:
|
| 95 |
+
"""Shannon entropy of a string."""
|
| 96 |
+
if not s:
|
| 97 |
+
return 0.0
|
| 98 |
+
cnt = Counter(s)
|
| 99 |
+
length = len(s)
|
| 100 |
+
return -sum((c / length) * math.log2(c / length) for c in cnt.values())
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
def extract_url_features(url: str) -> np.ndarray:
|
| 104 |
+
"""
|
| 105 |
+
Extract 54 lexical features from a single URL string.
|
| 106 |
+
Returns a 1D numpy array of shape (54,) in float32.
|
| 107 |
+
"""
|
| 108 |
+
try:
|
| 109 |
+
features = _extract_features_inner(url)
|
| 110 |
+
except Exception:
|
| 111 |
+
features = {name: 0 for name in FEATURE_NAMES}
|
| 112 |
+
|
| 113 |
+
return np.array([features[name] for name in FEATURE_NAMES], dtype=np.float32)
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
def extract_url_features_dict(url: str) -> dict:
|
| 117 |
+
"""Extract 54 features and return as a dict with feature names."""
|
| 118 |
+
try:
|
| 119 |
+
return _extract_features_inner(url)
|
| 120 |
+
except Exception:
|
| 121 |
+
return {name: 0 for name in FEATURE_NAMES}
|
| 122 |
+
|
| 123 |
+
|
| 124 |
+
def _extract_features_inner(url: str) -> dict:
|
| 125 |
+
"""Core feature extraction logic."""
|
| 126 |
+
url = str(url).strip()
|
| 127 |
+
|
| 128 |
+
try:
|
| 129 |
+
parsed = urlparse(url if "://" in url else f"http://{url}")
|
| 130 |
+
except Exception:
|
| 131 |
+
try:
|
| 132 |
+
safe = url.replace("[", "").replace("]", "")
|
| 133 |
+
parsed = urlparse(safe if "://" in safe else f"http://{safe}")
|
| 134 |
+
except Exception:
|
| 135 |
+
parsed = urlparse("http://invalid")
|
| 136 |
+
|
| 137 |
+
try:
|
| 138 |
+
hostname = parsed.hostname or ""
|
| 139 |
+
except Exception:
|
| 140 |
+
hostname = ""
|
| 141 |
+
path = parsed.path or ""
|
| 142 |
+
query = parsed.query or ""
|
| 143 |
+
fragment = parsed.fragment or ""
|
| 144 |
+
scheme = (parsed.scheme or "").lower()
|
| 145 |
+
|
| 146 |
+
# TLD extraction
|
| 147 |
+
if tldextract is not None:
|
| 148 |
+
ext = tldextract.extract(url)
|
| 149 |
+
domain = ext.domain
|
| 150 |
+
tld = ext.suffix
|
| 151 |
+
subdomain = ext.subdomain
|
| 152 |
+
else:
|
| 153 |
+
domain = hostname.split(".")[-2] if hostname.count(".") >= 1 else hostname
|
| 154 |
+
tld = hostname.split(".")[-1] if "." in hostname else ""
|
| 155 |
+
subdomain = ".".join(hostname.split(".")[:-2]) if hostname.count(".") >= 2 else ""
|
| 156 |
+
|
| 157 |
+
url_lower = url.lower()
|
| 158 |
+
|
| 159 |
+
# 1. Length / structural
|
| 160 |
+
url_length = len(url)
|
| 161 |
+
hostname_length = len(hostname)
|
| 162 |
+
domain_length = len(domain)
|
| 163 |
+
path_length = len(path)
|
| 164 |
+
query_length = len(query)
|
| 165 |
+
fragment_length = len(fragment)
|
| 166 |
+
tld_length = len(tld)
|
| 167 |
+
|
| 168 |
+
# 2. Character counts
|
| 169 |
+
num_dots = url.count(".")
|
| 170 |
+
num_hyphens = url.count("-")
|
| 171 |
+
num_underscores = url.count("_")
|
| 172 |
+
num_slashes = url.count("/")
|
| 173 |
+
num_at_signs = url.count("@")
|
| 174 |
+
num_ampersands = url.count("&")
|
| 175 |
+
num_equals = url.count("=")
|
| 176 |
+
num_question_marks = url.count("?")
|
| 177 |
+
num_percent = url.count("%")
|
| 178 |
+
num_tilde = url.count("~")
|
| 179 |
+
num_digits = sum(c.isdigit() for c in url)
|
| 180 |
+
num_letters = sum(c.isalpha() for c in url)
|
| 181 |
+
num_special = sum(not c.isalnum() and c not in ":/." for c in url)
|
| 182 |
+
num_params = len(parse_qs(query))
|
| 183 |
+
|
| 184 |
+
# 3. Character ratios
|
| 185 |
+
safe_len = max(url_length, 1)
|
| 186 |
+
digit_ratio = num_digits / safe_len
|
| 187 |
+
letter_ratio = num_letters / safe_len
|
| 188 |
+
special_ratio = num_special / safe_len
|
| 189 |
+
uppercase_ratio = sum(c.isupper() for c in url) / safe_len
|
| 190 |
+
digit_letter_ratio = num_digits / max(num_letters, 1)
|
| 191 |
+
|
| 192 |
+
# 4. Entropy
|
| 193 |
+
url_entropy = _entropy(url)
|
| 194 |
+
domain_entropy = _entropy(hostname)
|
| 195 |
+
|
| 196 |
+
# 5. Boolean indicators
|
| 197 |
+
has_ip = int(bool(_IP_RE.search(url)))
|
| 198 |
+
has_https = int(scheme == "https")
|
| 199 |
+
has_http = int(scheme == "http")
|
| 200 |
+
has_www = int("www." in url_lower)
|
| 201 |
+
try:
|
| 202 |
+
_port = parsed.port
|
| 203 |
+
except (ValueError, TypeError):
|
| 204 |
+
_port = None
|
| 205 |
+
has_port = int(_port is not None and _port not in (80, 443))
|
| 206 |
+
has_at_symbol = int("@" in url)
|
| 207 |
+
is_shortened = int(any(s in url_lower for s in _SHORTENERS))
|
| 208 |
+
has_double_slash_redirect = int("//" in path)
|
| 209 |
+
has_punycode = int("xn--" in url_lower)
|
| 210 |
+
has_hex_encoding = int(bool(_HEX_RE.search(url)))
|
| 211 |
+
|
| 212 |
+
# 6. Domain / TLD signals
|
| 213 |
+
num_subdomains = subdomain.count(".") + 1 if subdomain else 0
|
| 214 |
+
subdomain_length = len(subdomain)
|
| 215 |
+
domain_token_count = len(re.split(r"[.\-_]", hostname))
|
| 216 |
+
has_suspicious_tld = int(tld.lower() in _SUSPICIOUS_TLDS)
|
| 217 |
+
domain_has_digits = int(any(c.isdigit() for c in domain))
|
| 218 |
+
domain_hyphen_count = domain.count("-")
|
| 219 |
+
|
| 220 |
+
# 7. Suspicious-pattern scores
|
| 221 |
+
phishing_keyword_count = len(_PHISHING_KW.findall(url_lower))
|
| 222 |
+
brand_count = sum(1 for b in _BRAND_NAMES if b in url_lower)
|
| 223 |
+
has_suspicious_ext = int(bool(_SUSPICIOUS_EXT.search(url_lower)))
|
| 224 |
+
brand_in_subdomain = int(
|
| 225 |
+
any(b in subdomain.lower() for b in _BRAND_NAMES) and
|
| 226 |
+
not any(b in domain.lower() for b in _BRAND_NAMES)
|
| 227 |
+
) if subdomain else 0
|
| 228 |
+
suspicious_word_ratio = phishing_keyword_count / max(
|
| 229 |
+
len(re.findall(r"[a-zA-Z]+", url)), 1
|
| 230 |
+
)
|
| 231 |
+
|
| 232 |
+
# 8. Path & query analysis
|
| 233 |
+
path_tokens = [t for t in path.split("/") if t]
|
| 234 |
+
path_depth = len(path_tokens)
|
| 235 |
+
longest_path_token = max((len(t) for t in path_tokens), default=0)
|
| 236 |
+
avg_path_token_len = (
|
| 237 |
+
sum(len(t) for t in path_tokens) / len(path_tokens) if path_tokens else 0.0
|
| 238 |
+
)
|
| 239 |
+
max_consecutive_digits = max(
|
| 240 |
+
(len(m.group()) for m in re.finditer(r"\d+", url)), default=0
|
| 241 |
+
)
|
| 242 |
+
path_entropy = _entropy(path)
|
| 243 |
+
|
| 244 |
+
return {
|
| 245 |
+
# 1. Length
|
| 246 |
+
"url_length": url_length,
|
| 247 |
+
"hostname_length": hostname_length,
|
| 248 |
+
"domain_length": domain_length,
|
| 249 |
+
"path_length": path_length,
|
| 250 |
+
"query_length": query_length,
|
| 251 |
+
"fragment_length": fragment_length,
|
| 252 |
+
"tld_length": tld_length,
|
| 253 |
+
# 2. Counts
|
| 254 |
+
"num_dots": num_dots,
|
| 255 |
+
"num_hyphens": num_hyphens,
|
| 256 |
+
"num_underscores": num_underscores,
|
| 257 |
+
"num_slashes": num_slashes,
|
| 258 |
+
"num_at_signs": num_at_signs,
|
| 259 |
+
"num_ampersands": num_ampersands,
|
| 260 |
+
"num_equals": num_equals,
|
| 261 |
+
"num_question_marks": num_question_marks,
|
| 262 |
+
"num_percent": num_percent,
|
| 263 |
+
"num_tilde": num_tilde,
|
| 264 |
+
"num_digits": num_digits,
|
| 265 |
+
"num_letters": num_letters,
|
| 266 |
+
"num_special": num_special,
|
| 267 |
+
"num_params": num_params,
|
| 268 |
+
# 3. Ratios
|
| 269 |
+
"digit_ratio": digit_ratio,
|
| 270 |
+
"letter_ratio": letter_ratio,
|
| 271 |
+
"special_ratio": special_ratio,
|
| 272 |
+
"uppercase_ratio": uppercase_ratio,
|
| 273 |
+
"digit_letter_ratio": digit_letter_ratio,
|
| 274 |
+
# 4. Entropy
|
| 275 |
+
"url_entropy": url_entropy,
|
| 276 |
+
"domain_entropy": domain_entropy,
|
| 277 |
+
# 5. Booleans
|
| 278 |
+
"has_ip": has_ip,
|
| 279 |
+
"has_https": has_https,
|
| 280 |
+
"has_http": has_http,
|
| 281 |
+
"has_www": has_www,
|
| 282 |
+
"has_port": has_port,
|
| 283 |
+
"has_at_symbol": has_at_symbol,
|
| 284 |
+
"is_shortened": is_shortened,
|
| 285 |
+
"has_double_slash_redirect": has_double_slash_redirect,
|
| 286 |
+
"has_punycode": has_punycode,
|
| 287 |
+
"has_hex_encoding": has_hex_encoding,
|
| 288 |
+
# 6. Domain
|
| 289 |
+
"num_subdomains": num_subdomains,
|
| 290 |
+
"subdomain_length": subdomain_length,
|
| 291 |
+
"domain_token_count": domain_token_count,
|
| 292 |
+
"has_suspicious_tld": has_suspicious_tld,
|
| 293 |
+
"domain_has_digits": domain_has_digits,
|
| 294 |
+
"domain_hyphen_count": domain_hyphen_count,
|
| 295 |
+
# 7. Suspicious
|
| 296 |
+
"phishing_keyword_count": phishing_keyword_count,
|
| 297 |
+
"brand_count": brand_count,
|
| 298 |
+
"has_suspicious_ext": has_suspicious_ext,
|
| 299 |
+
"brand_in_subdomain": brand_in_subdomain,
|
| 300 |
+
"suspicious_word_ratio": suspicious_word_ratio,
|
| 301 |
+
# 8. Path / query
|
| 302 |
+
"path_depth": path_depth,
|
| 303 |
+
"longest_path_token": longest_path_token,
|
| 304 |
+
"avg_path_token_len": avg_path_token_len,
|
| 305 |
+
"max_consecutive_digits": max_consecutive_digits,
|
| 306 |
+
"path_entropy": path_entropy,
|
| 307 |
+
}
|
backend/app/services/url_service.py
ADDED
|
@@ -0,0 +1,334 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
URL Malware Detection Service — Stacking HyperModel.
|
| 3 |
+
|
| 4 |
+
Full inference pipeline:
|
| 5 |
+
1. Extract 54 lexical features from URL
|
| 6 |
+
2. Scale features with StandardScaler
|
| 7 |
+
3. Run 5 base models (XGBoost, LightGBM, TF-IDF+LR, CharCNN, CharBiLSTM)
|
| 8 |
+
4. Stack their probability outputs → 10 meta-features
|
| 9 |
+
5. Meta-learner (XGBoost) produces final prediction
|
| 10 |
+
"""
|
| 11 |
+
|
| 12 |
+
from __future__ import annotations
|
| 13 |
+
|
| 14 |
+
import logging
|
| 15 |
+
import time
|
| 16 |
+
import warnings
|
| 17 |
+
from pathlib import Path
|
| 18 |
+
from functools import lru_cache
|
| 19 |
+
|
| 20 |
+
import numpy as np
|
| 21 |
+
import joblib
|
| 22 |
+
|
| 23 |
+
from .url_feature_engineering import extract_url_features, extract_url_features_dict, FEATURE_NAMES
|
| 24 |
+
|
| 25 |
+
logger = logging.getLogger(__name__)
|
| 26 |
+
|
| 27 |
+
# ── DL architecture definitions (inline, no external dependency) ──────────────
|
| 28 |
+
# These mirror the exact architectures from the training notebook.
|
| 29 |
+
|
| 30 |
+
MAX_URL_LEN = 200
|
| 31 |
+
|
| 32 |
+
# Character lookup table
|
| 33 |
+
_CHAR_LUT = np.zeros(256, dtype=np.int64)
|
| 34 |
+
_PRINTABLE = (
|
| 35 |
+
"abcdefghijklmnopqrstuvwxyz"
|
| 36 |
+
"ABCDEFGHIJKLMNOPQRSTUVWXYZ"
|
| 37 |
+
"0123456789"
|
| 38 |
+
"!\"#$%&'()*+,-./:;<=>?@[\\]^_`{|}~ "
|
| 39 |
+
)
|
| 40 |
+
for _i, _ch in enumerate(_PRINTABLE, start=1):
|
| 41 |
+
_CHAR_LUT[ord(_ch)] = _i
|
| 42 |
+
_UNK_ID = len(_PRINTABLE) + 1 # 96
|
| 43 |
+
VOCAB_SIZE = _UNK_ID + 1 # 97
|
| 44 |
+
|
| 45 |
+
try:
|
| 46 |
+
import torch
|
| 47 |
+
import torch.nn as nn
|
| 48 |
+
TORCH_AVAILABLE = True
|
| 49 |
+
except ImportError:
|
| 50 |
+
TORCH_AVAILABLE = False
|
| 51 |
+
logger.warning("PyTorch not available — DL base models will be skipped")
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
def _url_to_tensor(urls: list[str], max_len: int = MAX_URL_LEN):
|
| 55 |
+
"""Vectorised char→int encoding for a batch of URL strings."""
|
| 56 |
+
arr = np.zeros((len(urls), max_len), dtype=np.int64)
|
| 57 |
+
for i, url in enumerate(urls):
|
| 58 |
+
raw = str(url)[:max_len]
|
| 59 |
+
chars = np.frombuffer(raw.encode("ascii", "ignore"), dtype=np.uint8)
|
| 60 |
+
if len(chars) == 0:
|
| 61 |
+
continue
|
| 62 |
+
ids = _CHAR_LUT[chars]
|
| 63 |
+
ids = np.where(ids > 0, ids, _UNK_ID)
|
| 64 |
+
arr[i, : len(ids)] = ids[: max_len]
|
| 65 |
+
import torch
|
| 66 |
+
return torch.from_numpy(arr)
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
if TORCH_AVAILABLE:
|
| 70 |
+
class CharCNNNet(nn.Module):
|
| 71 |
+
"""1-D CNN on character-level URL embeddings."""
|
| 72 |
+
def __init__(self, num_classes: int = 2, embed_dim: int = 64):
|
| 73 |
+
super().__init__()
|
| 74 |
+
self.embed = nn.Embedding(VOCAB_SIZE, embed_dim, padding_idx=0)
|
| 75 |
+
self.convs = nn.Sequential(
|
| 76 |
+
nn.Conv1d(embed_dim, 128, kernel_size=3, padding=1),
|
| 77 |
+
nn.BatchNorm1d(128), nn.ReLU(), nn.MaxPool1d(2),
|
| 78 |
+
nn.Conv1d(128, 128, kernel_size=3, padding=1),
|
| 79 |
+
nn.BatchNorm1d(128), nn.ReLU(), nn.MaxPool1d(2),
|
| 80 |
+
nn.Conv1d(128, 256, kernel_size=3, padding=1),
|
| 81 |
+
nn.BatchNorm1d(256), nn.ReLU(), nn.AdaptiveMaxPool1d(1),
|
| 82 |
+
)
|
| 83 |
+
self.head = nn.Sequential(
|
| 84 |
+
nn.Dropout(0.3), nn.Linear(256, 128), nn.ReLU(),
|
| 85 |
+
nn.Dropout(0.2), nn.Linear(128, num_classes),
|
| 86 |
+
)
|
| 87 |
+
|
| 88 |
+
def forward(self, x):
|
| 89 |
+
x = self.embed(x).permute(0, 2, 1)
|
| 90 |
+
x = self.convs(x).squeeze(-1)
|
| 91 |
+
return self.head(x)
|
| 92 |
+
|
| 93 |
+
class CharBiLSTMNet(nn.Module):
|
| 94 |
+
"""Bidirectional LSTM on character embeddings."""
|
| 95 |
+
def __init__(self, num_classes: int = 2, embed_dim: int = 64,
|
| 96 |
+
hidden: int = 128, n_layers: int = 2):
|
| 97 |
+
super().__init__()
|
| 98 |
+
self.embed = nn.Embedding(VOCAB_SIZE, embed_dim, padding_idx=0)
|
| 99 |
+
self.lstm = nn.LSTM(
|
| 100 |
+
embed_dim, hidden, num_layers=n_layers,
|
| 101 |
+
batch_first=True, bidirectional=True, dropout=0.3,
|
| 102 |
+
)
|
| 103 |
+
self.head = nn.Sequential(
|
| 104 |
+
nn.Dropout(0.3), nn.Linear(hidden * 2, 128), nn.ReLU(),
|
| 105 |
+
nn.Dropout(0.2), nn.Linear(128, num_classes),
|
| 106 |
+
)
|
| 107 |
+
|
| 108 |
+
def forward(self, x):
|
| 109 |
+
x = self.embed(x)
|
| 110 |
+
_, (h, _) = self.lstm(x)
|
| 111 |
+
h = torch.cat([h[-2], h[-1]], dim=-1)
|
| 112 |
+
return self.head(h)
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
class URLModelService:
|
| 116 |
+
"""
|
| 117 |
+
Stacking HyperModel service for URL malware detection.
|
| 118 |
+
|
| 119 |
+
Loads all base models + meta-learner at initialization time.
|
| 120 |
+
Thread-safe for concurrent FastAPI requests.
|
| 121 |
+
"""
|
| 122 |
+
|
| 123 |
+
def __init__(self, models_dir: str | Path | None = None):
|
| 124 |
+
if models_dir is None:
|
| 125 |
+
# Default to urlmodel_info/ in project root
|
| 126 |
+
models_dir = Path(__file__).parent.parent.parent.parent / "urlmodel_info"
|
| 127 |
+
self.models_dir = Path(models_dir)
|
| 128 |
+
|
| 129 |
+
self.scaler = None
|
| 130 |
+
self.meta_learner = None
|
| 131 |
+
self.xgb_model = None
|
| 132 |
+
self.lgbm_model = None
|
| 133 |
+
self.tfidf_lr_model = None
|
| 134 |
+
self.cnn_net = None
|
| 135 |
+
self.bilstm_net = None
|
| 136 |
+
self.model_loaded = False
|
| 137 |
+
self._dl_available = False
|
| 138 |
+
|
| 139 |
+
self._load_models()
|
| 140 |
+
|
| 141 |
+
def _load_models(self):
|
| 142 |
+
"""Load all model components."""
|
| 143 |
+
logger.info("Loading URL HyperModel components...")
|
| 144 |
+
|
| 145 |
+
with warnings.catch_warnings():
|
| 146 |
+
warnings.simplefilter("ignore")
|
| 147 |
+
|
| 148 |
+
# 1. Scaler
|
| 149 |
+
scaler_path = self.models_dir / "scaler.joblib"
|
| 150 |
+
self.scaler = joblib.load(scaler_path)
|
| 151 |
+
logger.info(f" Scaler loaded ({self.scaler.n_features_in_} features)")
|
| 152 |
+
|
| 153 |
+
# 2. Meta-learner
|
| 154 |
+
meta_path = self.models_dir / "hypermodel_meta.joblib"
|
| 155 |
+
self.meta_learner = joblib.load(meta_path)
|
| 156 |
+
logger.info(f" Meta-learner loaded ({self.meta_learner.n_features_in_} meta-features)")
|
| 157 |
+
|
| 158 |
+
# 3. XGBoost base model
|
| 159 |
+
xgb_path = self.models_dir / "xgb_binary.joblib"
|
| 160 |
+
self.xgb_model = joblib.load(xgb_path)
|
| 161 |
+
logger.info(" XGBoost base model loaded")
|
| 162 |
+
|
| 163 |
+
# 4. LightGBM base model
|
| 164 |
+
lgbm_path = self.models_dir / "lgbm_binary.joblib"
|
| 165 |
+
self.lgbm_model = joblib.load(lgbm_path)
|
| 166 |
+
logger.info(" LightGBM base model loaded")
|
| 167 |
+
|
| 168 |
+
# 5. TF-IDF + LR pipeline
|
| 169 |
+
tfidf_path = self.models_dir / "tfidf_lr_binary.joblib"
|
| 170 |
+
self.tfidf_lr_model = joblib.load(tfidf_path)
|
| 171 |
+
logger.info(" TF-IDF + LR pipeline loaded")
|
| 172 |
+
|
| 173 |
+
# 6. Deep Learning models (optional — requires PyTorch)
|
| 174 |
+
if TORCH_AVAILABLE:
|
| 175 |
+
try:
|
| 176 |
+
cnn_path = self.models_dir / "char_cnn_net.pt"
|
| 177 |
+
bilstm_path = self.models_dir / "char_bilstm_net.pt"
|
| 178 |
+
|
| 179 |
+
self.cnn_net = CharCNNNet(num_classes=2)
|
| 180 |
+
self.cnn_net.load_state_dict(
|
| 181 |
+
torch.load(cnn_path, map_location="cpu", weights_only=True)
|
| 182 |
+
)
|
| 183 |
+
self.cnn_net.eval()
|
| 184 |
+
logger.info(" CharCNN loaded")
|
| 185 |
+
|
| 186 |
+
self.bilstm_net = CharBiLSTMNet(num_classes=2)
|
| 187 |
+
self.bilstm_net.load_state_dict(
|
| 188 |
+
torch.load(bilstm_path, map_location="cpu", weights_only=True)
|
| 189 |
+
)
|
| 190 |
+
self.bilstm_net.eval()
|
| 191 |
+
logger.info(" CharBiLSTM loaded")
|
| 192 |
+
|
| 193 |
+
self._dl_available = True
|
| 194 |
+
except Exception as e:
|
| 195 |
+
logger.warning(f" DL models failed to load: {e}")
|
| 196 |
+
self._dl_available = False
|
| 197 |
+
|
| 198 |
+
self.model_loaded = True
|
| 199 |
+
n_base = 3 + (2 if self._dl_available else 0)
|
| 200 |
+
logger.info(f"URL HyperModel ready ({n_base} base models + meta-learner)")
|
| 201 |
+
|
| 202 |
+
def predict(self, url: str, threshold: float = 0.5) -> dict:
|
| 203 |
+
"""
|
| 204 |
+
Run the full stacking pipeline on a single URL.
|
| 205 |
+
|
| 206 |
+
Returns dict with:
|
| 207 |
+
- url: input URL
|
| 208 |
+
- prediction: 'Malicious' or 'Benign'
|
| 209 |
+
- malicious_score: float [0, 1]
|
| 210 |
+
- confidence: str percentage
|
| 211 |
+
- confidence_level: 'High', 'Medium', or 'Low'
|
| 212 |
+
- base_model_scores: dict of individual model scores
|
| 213 |
+
- top_signals: dict of most important feature values
|
| 214 |
+
- inference_time_ms: float
|
| 215 |
+
"""
|
| 216 |
+
start = time.perf_counter()
|
| 217 |
+
|
| 218 |
+
# 1. Extract features
|
| 219 |
+
features = extract_url_features(url)
|
| 220 |
+
features_dict = extract_url_features_dict(url)
|
| 221 |
+
X_feat = features.reshape(1, -1)
|
| 222 |
+
|
| 223 |
+
# 2. Scale features
|
| 224 |
+
X_scaled = self.scaler.transform(X_feat).astype(np.float32)
|
| 225 |
+
|
| 226 |
+
# 3. Get base model predictions
|
| 227 |
+
p_xgb = self.xgb_model.predict_proba(X_scaled)
|
| 228 |
+
p_lgbm = self.lgbm_model.predict_proba(X_scaled)
|
| 229 |
+
p_tfidf = self.tfidf_lr_model.predict_proba(np.array([url]))
|
| 230 |
+
|
| 231 |
+
base_scores = {
|
| 232 |
+
"XGBoost": float(p_xgb[0, 1]),
|
| 233 |
+
"LightGBM": float(p_lgbm[0, 1]),
|
| 234 |
+
"TF-IDF + LR": float(p_tfidf[0, 1]),
|
| 235 |
+
}
|
| 236 |
+
|
| 237 |
+
# 4. DL models (if available)
|
| 238 |
+
if self._dl_available:
|
| 239 |
+
xt = _url_to_tensor([url])
|
| 240 |
+
with torch.no_grad():
|
| 241 |
+
p_cnn = torch.softmax(self.cnn_net(xt).float(), dim=-1).numpy()
|
| 242 |
+
p_bilstm = torch.softmax(self.bilstm_net(xt).float(), dim=-1).numpy()
|
| 243 |
+
base_scores["CharCNN"] = float(p_cnn[0, 1])
|
| 244 |
+
base_scores["CharBiLSTM"] = float(p_bilstm[0, 1])
|
| 245 |
+
meta_features = np.hstack([p_xgb, p_lgbm, p_tfidf, p_cnn, p_bilstm])
|
| 246 |
+
else:
|
| 247 |
+
# Fallback: pad with zeros for missing DL models
|
| 248 |
+
zeros = np.zeros((1, 2), dtype=np.float32)
|
| 249 |
+
meta_features = np.hstack([p_xgb, p_lgbm, p_tfidf, zeros, zeros])
|
| 250 |
+
|
| 251 |
+
meta_features = meta_features.astype(np.float32)
|
| 252 |
+
|
| 253 |
+
# 5. Meta-learner prediction
|
| 254 |
+
final_proba = self.meta_learner.predict_proba(meta_features)
|
| 255 |
+
malicious_score = float(final_proba[0, 1])
|
| 256 |
+
|
| 257 |
+
# Determine verdict
|
| 258 |
+
prediction = "Malicious" if malicious_score > threshold else "Benign"
|
| 259 |
+
confidence_pct = abs(malicious_score - 0.5) * 200
|
| 260 |
+
|
| 261 |
+
if confidence_pct >= 80:
|
| 262 |
+
confidence_level = "High"
|
| 263 |
+
elif confidence_pct >= 50:
|
| 264 |
+
confidence_level = "Medium"
|
| 265 |
+
else:
|
| 266 |
+
confidence_level = "Low"
|
| 267 |
+
|
| 268 |
+
# Top feature signals
|
| 269 |
+
important_features = [
|
| 270 |
+
"has_ip", "has_suspicious_tld", "phishing_keyword_count",
|
| 271 |
+
"brand_in_subdomain", "has_punycode", "is_shortened",
|
| 272 |
+
"url_length", "num_subdomains", "has_https", "domain_entropy",
|
| 273 |
+
"has_suspicious_ext", "has_hex_encoding", "brand_count",
|
| 274 |
+
"path_depth", "url_entropy",
|
| 275 |
+
]
|
| 276 |
+
top_signals = {}
|
| 277 |
+
for feat in important_features:
|
| 278 |
+
if feat in features_dict:
|
| 279 |
+
val = features_dict[feat]
|
| 280 |
+
if val != 0:
|
| 281 |
+
top_signals[feat] = round(float(val), 4)
|
| 282 |
+
|
| 283 |
+
elapsed = (time.perf_counter() - start) * 1000
|
| 284 |
+
|
| 285 |
+
return {
|
| 286 |
+
"url": url,
|
| 287 |
+
"prediction": prediction,
|
| 288 |
+
"malicious_score": round(malicious_score, 6),
|
| 289 |
+
"confidence": f"{confidence_pct:.1f}%",
|
| 290 |
+
"confidence_level": confidence_level,
|
| 291 |
+
"threshold_used": threshold,
|
| 292 |
+
"base_model_scores": base_scores,
|
| 293 |
+
"top_signals": top_signals,
|
| 294 |
+
"inference_time_ms": round(elapsed, 2),
|
| 295 |
+
}
|
| 296 |
+
|
| 297 |
+
def get_model_info(self) -> dict:
|
| 298 |
+
"""Return info about loaded models."""
|
| 299 |
+
return {
|
| 300 |
+
"model_type": "Stacking HyperModel",
|
| 301 |
+
"base_models": list(self._get_base_model_names()),
|
| 302 |
+
"meta_learner": "XGBoost (GPU-trained)",
|
| 303 |
+
"scaler_features": self.scaler.n_features_in_,
|
| 304 |
+
"meta_features": self.meta_learner.n_features_in_,
|
| 305 |
+
"dl_available": self._dl_available,
|
| 306 |
+
"feature_categories": [
|
| 307 |
+
"Length/structural (7)",
|
| 308 |
+
"Character counts (14)",
|
| 309 |
+
"Character ratios (5)",
|
| 310 |
+
"Entropy/randomness (2)",
|
| 311 |
+
"Boolean indicators (10)",
|
| 312 |
+
"Domain/TLD signals (6)",
|
| 313 |
+
"Suspicious patterns (5)",
|
| 314 |
+
"Path & query (5)",
|
| 315 |
+
],
|
| 316 |
+
}
|
| 317 |
+
|
| 318 |
+
def _get_base_model_names(self):
|
| 319 |
+
names = ["XGBoost", "LightGBM", "TF-IDF + LR"]
|
| 320 |
+
if self._dl_available:
|
| 321 |
+
names.extend(["CharCNN", "CharBiLSTM"])
|
| 322 |
+
return names
|
| 323 |
+
|
| 324 |
+
|
| 325 |
+
# Singleton accessor
|
| 326 |
+
_url_service: URLModelService | None = None
|
| 327 |
+
|
| 328 |
+
|
| 329 |
+
def get_url_service() -> URLModelService:
|
| 330 |
+
"""Get or create the singleton URL model service."""
|
| 331 |
+
global _url_service
|
| 332 |
+
if _url_service is None:
|
| 333 |
+
_url_service = URLModelService()
|
| 334 |
+
return _url_service
|
backend/app/services/virustotal_service.py
ADDED
|
@@ -0,0 +1,226 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
VirusTotal API Service for hash verification.
|
| 3 |
+
Provides secondary verification of malware samples.
|
| 4 |
+
"""
|
| 5 |
+
|
| 6 |
+
import logging
|
| 7 |
+
from typing import Optional
|
| 8 |
+
import httpx
|
| 9 |
+
|
| 10 |
+
from ..config import settings
|
| 11 |
+
from ..models.virustotal import (
|
| 12 |
+
VirusTotalResponse,
|
| 13 |
+
VirusTotalStats,
|
| 14 |
+
EngineResult,
|
| 15 |
+
MalwareTypeInfo,
|
| 16 |
+
)
|
| 17 |
+
from .malware_type_service import get_malware_type_service
|
| 18 |
+
|
| 19 |
+
logger = logging.getLogger(__name__)
|
| 20 |
+
|
| 21 |
+
VIRUSTOTAL_API_BASE = "https://www.virustotal.com/api/v3"
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
class VirusTotalService:
|
| 25 |
+
"""
|
| 26 |
+
VirusTotal API Service for file hash lookups.
|
| 27 |
+
|
| 28 |
+
Provides:
|
| 29 |
+
- Hash lookup for SHA256/SHA1/MD5
|
| 30 |
+
- Detection ratio calculation
|
| 31 |
+
- Engine verdict extraction
|
| 32 |
+
- Reputation score
|
| 33 |
+
"""
|
| 34 |
+
|
| 35 |
+
def __init__(self):
|
| 36 |
+
self.api_key = settings.virustotal_api_key
|
| 37 |
+
self.initialized = bool(self.api_key)
|
| 38 |
+
self._client: Optional[httpx.AsyncClient] = None
|
| 39 |
+
|
| 40 |
+
async def _get_client(self) -> httpx.AsyncClient:
|
| 41 |
+
"""Get or create HTTP client."""
|
| 42 |
+
if self._client is None:
|
| 43 |
+
self._client = httpx.AsyncClient(
|
| 44 |
+
timeout=30.0,
|
| 45 |
+
headers={
|
| 46 |
+
"x-apikey": self.api_key,
|
| 47 |
+
"Accept": "application/json"
|
| 48 |
+
}
|
| 49 |
+
)
|
| 50 |
+
return self._client
|
| 51 |
+
|
| 52 |
+
async def close(self):
|
| 53 |
+
"""Close HTTP client."""
|
| 54 |
+
if self._client:
|
| 55 |
+
await self._client.aclose()
|
| 56 |
+
self._client = None
|
| 57 |
+
|
| 58 |
+
async def lookup_hash(self, sha256: str) -> VirusTotalResponse:
|
| 59 |
+
"""
|
| 60 |
+
Look up a file hash on VirusTotal.
|
| 61 |
+
|
| 62 |
+
Args:
|
| 63 |
+
sha256: SHA256 hash to look up
|
| 64 |
+
|
| 65 |
+
Returns:
|
| 66 |
+
VirusTotalResponse with detection results
|
| 67 |
+
"""
|
| 68 |
+
if not self.initialized:
|
| 69 |
+
return VirusTotalResponse(
|
| 70 |
+
sha256=sha256,
|
| 71 |
+
found=False,
|
| 72 |
+
error_message="VirusTotal API key not configured"
|
| 73 |
+
)
|
| 74 |
+
|
| 75 |
+
try:
|
| 76 |
+
client = await self._get_client()
|
| 77 |
+
url = f"{VIRUSTOTAL_API_BASE}/files/{sha256}"
|
| 78 |
+
|
| 79 |
+
response = await client.get(url)
|
| 80 |
+
|
| 81 |
+
if response.status_code == 404:
|
| 82 |
+
return VirusTotalResponse(
|
| 83 |
+
sha256=sha256,
|
| 84 |
+
found=False,
|
| 85 |
+
error_message="Hash not found in VirusTotal database"
|
| 86 |
+
)
|
| 87 |
+
|
| 88 |
+
if response.status_code == 401:
|
| 89 |
+
return VirusTotalResponse(
|
| 90 |
+
sha256=sha256,
|
| 91 |
+
found=False,
|
| 92 |
+
error_message="Invalid VirusTotal API key"
|
| 93 |
+
)
|
| 94 |
+
|
| 95 |
+
if response.status_code == 429:
|
| 96 |
+
return VirusTotalResponse(
|
| 97 |
+
sha256=sha256,
|
| 98 |
+
found=False,
|
| 99 |
+
error_message="VirusTotal API rate limit exceeded"
|
| 100 |
+
)
|
| 101 |
+
|
| 102 |
+
response.raise_for_status()
|
| 103 |
+
data = response.json()
|
| 104 |
+
|
| 105 |
+
return self._parse_response(sha256, data)
|
| 106 |
+
|
| 107 |
+
except httpx.TimeoutException:
|
| 108 |
+
logger.error(f"VirusTotal API timeout for hash: {sha256}")
|
| 109 |
+
return VirusTotalResponse(
|
| 110 |
+
sha256=sha256,
|
| 111 |
+
found=False,
|
| 112 |
+
error_message="VirusTotal API request timed out"
|
| 113 |
+
)
|
| 114 |
+
except httpx.HTTPError as e:
|
| 115 |
+
logger.error(f"VirusTotal API error: {e}")
|
| 116 |
+
return VirusTotalResponse(
|
| 117 |
+
sha256=sha256,
|
| 118 |
+
found=False,
|
| 119 |
+
error_message=f"VirusTotal API error: {str(e)}"
|
| 120 |
+
)
|
| 121 |
+
except Exception as e:
|
| 122 |
+
logger.error(f"Unexpected error in VirusTotal lookup: {e}")
|
| 123 |
+
return VirusTotalResponse(
|
| 124 |
+
sha256=sha256,
|
| 125 |
+
found=False,
|
| 126 |
+
error_message=f"Unexpected error: {str(e)}"
|
| 127 |
+
)
|
| 128 |
+
|
| 129 |
+
def _parse_response(self, sha256: str, data: dict) -> VirusTotalResponse:
|
| 130 |
+
"""Parse VirusTotal API response into structured format."""
|
| 131 |
+
try:
|
| 132 |
+
attributes = data.get("data", {}).get("attributes", {})
|
| 133 |
+
|
| 134 |
+
# Parse detection stats
|
| 135 |
+
stats_data = attributes.get("last_analysis_stats", {})
|
| 136 |
+
stats = VirusTotalStats(
|
| 137 |
+
malicious=stats_data.get("malicious", 0),
|
| 138 |
+
suspicious=stats_data.get("suspicious", 0),
|
| 139 |
+
undetected=stats_data.get("undetected", 0),
|
| 140 |
+
harmless=stats_data.get("harmless", 0),
|
| 141 |
+
timeout=stats_data.get("timeout", 0),
|
| 142 |
+
confirmed_timeout=stats_data.get("confirmed-timeout", 0),
|
| 143 |
+
failure=stats_data.get("failure", 0),
|
| 144 |
+
type_unsupported=stats_data.get("type-unsupported", 0),
|
| 145 |
+
)
|
| 146 |
+
|
| 147 |
+
# Calculate totals
|
| 148 |
+
malicious_count = stats.malicious + stats.suspicious
|
| 149 |
+
total_engines = (
|
| 150 |
+
stats.malicious + stats.suspicious +
|
| 151 |
+
stats.undetected + stats.harmless
|
| 152 |
+
)
|
| 153 |
+
detection_ratio = malicious_count / total_engines if total_engines > 0 else 0
|
| 154 |
+
|
| 155 |
+
# Parse engine results (top 20 for brevity)
|
| 156 |
+
engine_results = []
|
| 157 |
+
vt_labels = [] # Collect labels for malware type classification
|
| 158 |
+
last_analysis = attributes.get("last_analysis_results", {})
|
| 159 |
+
for engine_name, result in list(last_analysis.items())[:20]:
|
| 160 |
+
engine_results.append(EngineResult(
|
| 161 |
+
engine_name=engine_name,
|
| 162 |
+
category=result.get("category", "unknown"),
|
| 163 |
+
result=result.get("result"),
|
| 164 |
+
engine_version=result.get("engine_version"),
|
| 165 |
+
engine_update=result.get("engine_update"),
|
| 166 |
+
))
|
| 167 |
+
# Collect detection labels for malware type classification
|
| 168 |
+
if result.get("result"):
|
| 169 |
+
vt_labels.append(result.get("result"))
|
| 170 |
+
|
| 171 |
+
# Get dates
|
| 172 |
+
first_submission = attributes.get("first_submission_date")
|
| 173 |
+
last_analysis_date = attributes.get("last_analysis_date")
|
| 174 |
+
|
| 175 |
+
# Classify malware type if detected as malicious
|
| 176 |
+
malware_type = None
|
| 177 |
+
if malicious_count > 0 and vt_labels:
|
| 178 |
+
try:
|
| 179 |
+
malware_service = get_malware_type_service()
|
| 180 |
+
type_result = malware_service.classify(vt_labels=vt_labels)
|
| 181 |
+
malware_type = MalwareTypeInfo(
|
| 182 |
+
primary_type=type_result.primary_type,
|
| 183 |
+
confidence=type_result.confidence,
|
| 184 |
+
secondary_types=type_result.secondary_types,
|
| 185 |
+
indicators=type_result.indicators,
|
| 186 |
+
source=type_result.source
|
| 187 |
+
)
|
| 188 |
+
except Exception as e:
|
| 189 |
+
logger.warning(f"Failed to classify malware type: {e}")
|
| 190 |
+
|
| 191 |
+
return VirusTotalResponse(
|
| 192 |
+
sha256=sha256,
|
| 193 |
+
found=True,
|
| 194 |
+
stats=stats,
|
| 195 |
+
detection_ratio=round(detection_ratio, 4),
|
| 196 |
+
total_engines=total_engines,
|
| 197 |
+
malicious_count=malicious_count,
|
| 198 |
+
reputation_score=attributes.get("reputation"),
|
| 199 |
+
engine_results=engine_results,
|
| 200 |
+
first_submission_date=str(first_submission) if first_submission else None,
|
| 201 |
+
last_analysis_date=str(last_analysis_date) if last_analysis_date else None,
|
| 202 |
+
meaningful_name=attributes.get("meaningful_name"),
|
| 203 |
+
malware_type=malware_type,
|
| 204 |
+
)
|
| 205 |
+
|
| 206 |
+
except Exception as e:
|
| 207 |
+
logger.error(f"Failed to parse VirusTotal response: {e}")
|
| 208 |
+
return VirusTotalResponse(
|
| 209 |
+
sha256=sha256,
|
| 210 |
+
found=True,
|
| 211 |
+
error_message=f"Failed to parse response: {str(e)}"
|
| 212 |
+
)
|
| 213 |
+
|
| 214 |
+
|
| 215 |
+
# Global service instance
|
| 216 |
+
_vt_service: Optional[VirusTotalService] = None
|
| 217 |
+
|
| 218 |
+
|
| 219 |
+
def get_virustotal_service() -> VirusTotalService:
|
| 220 |
+
"""Get the global VirusTotal service instance."""
|
| 221 |
+
global _vt_service
|
| 222 |
+
|
| 223 |
+
if _vt_service is None:
|
| 224 |
+
_vt_service = VirusTotalService()
|
| 225 |
+
|
| 226 |
+
return _vt_service
|
backend/pytest.ini
ADDED
|
@@ -0,0 +1,4 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[pytest]
|
| 2 |
+
testpaths = tests
|
| 3 |
+
pythonpath = .
|
| 4 |
+
asyncio_mode = auto
|
backend/requirements.txt
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Malware Detection Platform - Backend Dependencies
|
| 2 |
+
# Python 3.10+ required
|
| 3 |
+
|
| 4 |
+
# FastAPI Framework with all extras (includes uvicorn, etc.)
|
| 5 |
+
fastapi[standard]>=0.115.0
|
| 6 |
+
|
| 7 |
+
# Pydantic for data validation
|
| 8 |
+
pydantic>=2.10.0
|
| 9 |
+
pydantic-settings>=2.7.0
|
| 10 |
+
|
| 11 |
+
# Async HTTP client for VirusTotal API
|
| 12 |
+
httpx>=0.28.0
|
| 13 |
+
|
| 14 |
+
# Testing
|
| 15 |
+
pytest>=8.3.0
|
| 16 |
+
pytest-asyncio>=0.25.0
|
| 17 |
+
|
| 18 |
+
# Rate limiting
|
| 19 |
+
slowapi>=0.1.9
|
| 20 |
+
|
| 21 |
+
# Machine Learning
|
| 22 |
+
numpy>=2.2.0
|
| 23 |
+
scikit-learn>=1.6.0
|
| 24 |
+
joblib>=1.4.0
|
| 25 |
+
xgboost>=2.1.0
|
| 26 |
+
|
| 27 |
+
# PE File Parsing for EMBER feature extraction
|
| 28 |
+
lief>=0.15.0
|
| 29 |
+
|
| 30 |
+
# SHAP for explainability (optional but recommended)
|
| 31 |
+
shap>=0.46.0
|
| 32 |
+
|
| 33 |
+
# Google Generative AI (Gemini)
|
| 34 |
+
google-generativeai>=0.8.0
|
| 35 |
+
|
| 36 |
+
# Multipart form data handling
|
| 37 |
+
python-multipart>=0.0.18
|
| 38 |
+
|
| 39 |
+
# Additional utilities
|
| 40 |
+
python-dotenv>=1.0.1
|
backend/tests/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
|
backend/tests/conftest.py
ADDED
|
@@ -0,0 +1,219 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from __future__ import annotations
|
| 2 |
+
|
| 3 |
+
from dataclasses import dataclass
|
| 4 |
+
import pytest
|
| 5 |
+
from fastapi.testclient import TestClient
|
| 6 |
+
|
| 7 |
+
from app.main import app
|
| 8 |
+
from app.models.prediction import ConfidenceLevel, PredictionLabel, PredictionResponse
|
| 9 |
+
from app.models.virustotal import VirusTotalResponse
|
| 10 |
+
|
| 11 |
+
|
| 12 |
+
FEATURE_COUNT = 2381
|
| 13 |
+
FEATURES = [0.0] * FEATURE_COUNT
|
| 14 |
+
SHA256 = "a" * 64
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
class FakeMLService:
|
| 18 |
+
model_loaded = True
|
| 19 |
+
feature_count = FEATURE_COUNT
|
| 20 |
+
model = object()
|
| 21 |
+
|
| 22 |
+
def predict(self, features, threshold=None, sha256=None):
|
| 23 |
+
if len(features) != self.feature_count:
|
| 24 |
+
raise ValueError(f"Expected {self.feature_count} features, got {len(features)}")
|
| 25 |
+
used_threshold = 0.5 if threshold is None else threshold
|
| 26 |
+
return PredictionResponse(
|
| 27 |
+
prediction=PredictionLabel.MALICIOUS,
|
| 28 |
+
probability=0.91,
|
| 29 |
+
confidence=ConfidenceLevel.HIGH,
|
| 30 |
+
threshold_used=used_threshold,
|
| 31 |
+
sha256=sha256,
|
| 32 |
+
inference_time_ms=1.2,
|
| 33 |
+
)
|
| 34 |
+
|
| 35 |
+
def get_model_info(self):
|
| 36 |
+
return {
|
| 37 |
+
"loaded": True,
|
| 38 |
+
"feature_count": self.feature_count,
|
| 39 |
+
"default_threshold": 0.5,
|
| 40 |
+
"model_type": "FakeModel",
|
| 41 |
+
}
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
class FakeSHAPService:
|
| 45 |
+
initialized = True
|
| 46 |
+
|
| 47 |
+
def initialize(self, model):
|
| 48 |
+
self.initialized = True
|
| 49 |
+
|
| 50 |
+
def get_feature_importance(self, features, model=None, top_k=10):
|
| 51 |
+
return []
|
| 52 |
+
|
| 53 |
+
def explain(self, features):
|
| 54 |
+
return []
|
| 55 |
+
|
| 56 |
+
|
| 57 |
+
class FakeGeminiService:
|
| 58 |
+
initialized = False
|
| 59 |
+
model = None
|
| 60 |
+
|
| 61 |
+
def initialize(self):
|
| 62 |
+
self.initialized = False
|
| 63 |
+
|
| 64 |
+
async def explain_prediction(self, prediction, features=None):
|
| 65 |
+
return {
|
| 66 |
+
"risk_explanation": "Deterministic test explanation.",
|
| 67 |
+
"severity_level": "High",
|
| 68 |
+
"key_indicators": ["test signal"],
|
| 69 |
+
"analyst_summary": "Smoke test summary.",
|
| 70 |
+
"mitigation_steps": ["isolate sample"],
|
| 71 |
+
}
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
class FakeURLService:
|
| 75 |
+
model_loaded = True
|
| 76 |
+
_dl_available = False
|
| 77 |
+
|
| 78 |
+
def predict(self, url, threshold=0.5):
|
| 79 |
+
return {
|
| 80 |
+
"url": url,
|
| 81 |
+
"prediction": "Malicious",
|
| 82 |
+
"malicious_score": 0.84,
|
| 83 |
+
"confidence": "84.0%",
|
| 84 |
+
"confidence_level": "High",
|
| 85 |
+
"threshold_used": threshold,
|
| 86 |
+
"base_model_scores": {"XGBoost": 0.8},
|
| 87 |
+
"top_signals": {"url_length": 0.4},
|
| 88 |
+
"inference_time_ms": 3.4,
|
| 89 |
+
}
|
| 90 |
+
|
| 91 |
+
def get_model_info(self):
|
| 92 |
+
return {
|
| 93 |
+
"model_type": "Fake URL HyperModel",
|
| 94 |
+
"base_models": ["XGBoost"],
|
| 95 |
+
"meta_learner": "XGBoost",
|
| 96 |
+
"scaler_features": 54,
|
| 97 |
+
"meta_features": 10,
|
| 98 |
+
"dl_available": self._dl_available,
|
| 99 |
+
"feature_categories": ["lexical"],
|
| 100 |
+
}
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
class FakeVirusTotalService:
|
| 104 |
+
initialized = True
|
| 105 |
+
next_result: VirusTotalResponse | None = None
|
| 106 |
+
|
| 107 |
+
async def lookup_hash(self, sha256):
|
| 108 |
+
if self.next_result is not None:
|
| 109 |
+
return self.next_result
|
| 110 |
+
return VirusTotalResponse(
|
| 111 |
+
sha256=sha256,
|
| 112 |
+
found=True,
|
| 113 |
+
detection_ratio=0.25,
|
| 114 |
+
total_engines=20,
|
| 115 |
+
malicious_count=5,
|
| 116 |
+
)
|
| 117 |
+
|
| 118 |
+
|
| 119 |
+
class FakeFeedbackService:
|
| 120 |
+
def __init__(self):
|
| 121 |
+
self.malware_total = 0
|
| 122 |
+
self.url_total = 0
|
| 123 |
+
|
| 124 |
+
def log_malware_feedback(self, **kwargs):
|
| 125 |
+
self.malware_total += 1
|
| 126 |
+
return {
|
| 127 |
+
"success": True,
|
| 128 |
+
"reward": 1,
|
| 129 |
+
"message": "Agreement with VirusTotal logged",
|
| 130 |
+
"total_feedback_count": self.malware_total,
|
| 131 |
+
}
|
| 132 |
+
|
| 133 |
+
def log_url_feedback(self, **kwargs):
|
| 134 |
+
self.url_total += 1
|
| 135 |
+
return {
|
| 136 |
+
"success": True,
|
| 137 |
+
"reward": 1,
|
| 138 |
+
"message": "Feedback recorded",
|
| 139 |
+
"total_feedback_count": self.url_total,
|
| 140 |
+
}
|
| 141 |
+
|
| 142 |
+
def maybe_auto_update(self, model_type):
|
| 143 |
+
return None
|
| 144 |
+
|
| 145 |
+
def get_stats(self):
|
| 146 |
+
return {
|
| 147 |
+
"malware_total": self.malware_total,
|
| 148 |
+
"malware_agree": self.malware_total,
|
| 149 |
+
"malware_disagree": 0,
|
| 150 |
+
"malware_agreement_rate": 100.0 if self.malware_total else 0.0,
|
| 151 |
+
"url_total": self.url_total,
|
| 152 |
+
"url_correct": self.url_total,
|
| 153 |
+
"url_incorrect": 0,
|
| 154 |
+
"url_accuracy_rate": 100.0 if self.url_total else 0.0,
|
| 155 |
+
"recent_malware": [],
|
| 156 |
+
"recent_url": [],
|
| 157 |
+
"model_updates": [],
|
| 158 |
+
}
|
| 159 |
+
|
| 160 |
+
|
| 161 |
+
@dataclass
|
| 162 |
+
class Services:
|
| 163 |
+
ml: FakeMLService
|
| 164 |
+
shap: FakeSHAPService
|
| 165 |
+
gemini: FakeGeminiService
|
| 166 |
+
url: FakeURLService
|
| 167 |
+
virustotal: FakeVirusTotalService
|
| 168 |
+
feedback: FakeFeedbackService
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
@pytest.fixture
|
| 172 |
+
def features():
|
| 173 |
+
return list(FEATURES)
|
| 174 |
+
|
| 175 |
+
|
| 176 |
+
@pytest.fixture
|
| 177 |
+
def sha256():
|
| 178 |
+
return SHA256
|
| 179 |
+
|
| 180 |
+
|
| 181 |
+
@pytest.fixture
|
| 182 |
+
def services(monkeypatch):
|
| 183 |
+
fakes = Services(
|
| 184 |
+
ml=FakeMLService(),
|
| 185 |
+
shap=FakeSHAPService(),
|
| 186 |
+
gemini=FakeGeminiService(),
|
| 187 |
+
url=FakeURLService(),
|
| 188 |
+
virustotal=FakeVirusTotalService(),
|
| 189 |
+
feedback=FakeFeedbackService(),
|
| 190 |
+
)
|
| 191 |
+
|
| 192 |
+
from app.routers import chat, feedback, predict, upload, url, virustotal
|
| 193 |
+
from app import main
|
| 194 |
+
|
| 195 |
+
app.dependency_overrides[predict.get_ml_service] = lambda: fakes.ml
|
| 196 |
+
app.dependency_overrides[predict.get_gemini_service] = lambda: fakes.gemini
|
| 197 |
+
app.dependency_overrides[virustotal.get_ml_service] = lambda: fakes.ml
|
| 198 |
+
app.dependency_overrides[virustotal.get_virustotal_service] = lambda: fakes.virustotal
|
| 199 |
+
|
| 200 |
+
monkeypatch.setattr(main, "get_ml_service", lambda: fakes.ml)
|
| 201 |
+
monkeypatch.setattr(main, "get_gemini_service", lambda: fakes.gemini)
|
| 202 |
+
monkeypatch.setattr(main, "get_virustotal_service", lambda: fakes.virustotal)
|
| 203 |
+
monkeypatch.setattr(predict, "get_shap_service", lambda: fakes.shap)
|
| 204 |
+
monkeypatch.setattr(chat, "get_gemini_service", lambda: fakes.gemini)
|
| 205 |
+
monkeypatch.setattr(upload, "get_ml_service", lambda: fakes.ml)
|
| 206 |
+
monkeypatch.setattr(upload, "get_shap_service", lambda: fakes.shap)
|
| 207 |
+
monkeypatch.setattr(upload, "get_gemini_service", lambda: fakes.gemini)
|
| 208 |
+
monkeypatch.setattr(upload, "LIEF_AVAILABLE", True)
|
| 209 |
+
monkeypatch.setattr(url, "get_url_service", lambda: fakes.url)
|
| 210 |
+
monkeypatch.setattr(feedback, "get_feedback_service", lambda: fakes.feedback)
|
| 211 |
+
monkeypatch.setattr(virustotal, "get_feedback_service", lambda: fakes.feedback)
|
| 212 |
+
|
| 213 |
+
yield fakes
|
| 214 |
+
app.dependency_overrides.clear()
|
| 215 |
+
|
| 216 |
+
|
| 217 |
+
@pytest.fixture
|
| 218 |
+
def client(services):
|
| 219 |
+
return TestClient(app)
|
backend/tests/test_chat.py
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
def test_chat_uses_fallback_when_gemini_unavailable(client):
|
| 2 |
+
response = client.post(
|
| 3 |
+
"/api/chat/",
|
| 4 |
+
json={"message": "How does malware detection work?"},
|
| 5 |
+
)
|
| 6 |
+
|
| 7 |
+
assert response.status_code == 200
|
| 8 |
+
body = response.json()
|
| 9 |
+
assert body["success"] is True
|
| 10 |
+
assert "MalwareGuard analyzes Windows PE files" in body["response"]
|
backend/tests/test_feedback.py
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
def test_feedback_log_and_stats_happy_path(client, features, sha256):
|
| 2 |
+
log_response = client.post(
|
| 3 |
+
"/api/feedback/malware",
|
| 4 |
+
json={
|
| 5 |
+
"features": features,
|
| 6 |
+
"sha256": sha256,
|
| 7 |
+
"predicted_label": "Malicious",
|
| 8 |
+
"predicted_probability": 0.91,
|
| 9 |
+
"vt_malicious_count": 5,
|
| 10 |
+
"vt_total_engines": 20,
|
| 11 |
+
"vt_detection_ratio": 0.25,
|
| 12 |
+
},
|
| 13 |
+
)
|
| 14 |
+
|
| 15 |
+
assert log_response.status_code == 200
|
| 16 |
+
assert log_response.json()["total_feedback_count"] == 1
|
| 17 |
+
|
| 18 |
+
stats_response = client.get("/api/feedback/stats")
|
| 19 |
+
|
| 20 |
+
assert stats_response.status_code == 200
|
| 21 |
+
stats = stats_response.json()
|
| 22 |
+
assert stats["malware_total"] == 1
|
| 23 |
+
assert stats["malware_agree"] == 1
|
backend/tests/test_health.py
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
def test_root_and_global_health(client):
|
| 2 |
+
root = client.get("/")
|
| 3 |
+
health = client.get("/health")
|
| 4 |
+
|
| 5 |
+
assert root.status_code == 200
|
| 6 |
+
assert root.json()["status"] == "running"
|
| 7 |
+
assert health.status_code == 200
|
| 8 |
+
assert health.json()["status"] == "healthy"
|
| 9 |
+
|
| 10 |
+
|
| 11 |
+
def test_service_health_routes(client):
|
| 12 |
+
routes = [
|
| 13 |
+
"/api/predict/health",
|
| 14 |
+
"/api/virustotal/health",
|
| 15 |
+
"/api/chat/health",
|
| 16 |
+
"/api/url/health",
|
| 17 |
+
"/api/feedback/health",
|
| 18 |
+
"/api/upload/health",
|
| 19 |
+
]
|
| 20 |
+
|
| 21 |
+
for route in routes:
|
| 22 |
+
response = client.get(route)
|
| 23 |
+
assert response.status_code == 200, route
|
| 24 |
+
assert "status" in response.json()
|
backend/tests/test_predict.py
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
def test_predict_happy_path(client, features, sha256):
|
| 2 |
+
response = client.post("/api/predict", json={"features": features, "sha256": sha256})
|
| 3 |
+
|
| 4 |
+
assert response.status_code == 200
|
| 5 |
+
body = response.json()
|
| 6 |
+
assert body["prediction"]["prediction"] == "Malicious"
|
| 7 |
+
assert body["prediction"]["probability"] == 0.91
|
| 8 |
+
assert body["prediction"]["sha256"] == sha256
|
| 9 |
+
|
| 10 |
+
|
| 11 |
+
def test_predict_rejects_wrong_feature_count(client):
|
| 12 |
+
response = client.post("/api/predict", json={"features": [0.0] * 10})
|
| 13 |
+
|
| 14 |
+
assert response.status_code == 422
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
def test_predict_rejects_bad_threshold(client, features):
|
| 18 |
+
response = client.post(
|
| 19 |
+
"/api/predict",
|
| 20 |
+
json={"features": features, "threshold": 1.5},
|
| 21 |
+
)
|
| 22 |
+
|
| 23 |
+
assert response.status_code == 422
|
backend/tests/test_upload.py
ADDED
|
@@ -0,0 +1,45 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import numpy as np
|
| 2 |
+
|
| 3 |
+
|
| 4 |
+
def test_upload_rejects_non_mz_file(client):
|
| 5 |
+
response = client.post(
|
| 6 |
+
"/api/upload/analyze",
|
| 7 |
+
files={"file": ("note.txt", b"hello", "text/plain")},
|
| 8 |
+
)
|
| 9 |
+
|
| 10 |
+
assert response.status_code == 400
|
| 11 |
+
assert "Invalid PE file" in response.json()["detail"]
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
def test_upload_rejects_size_limit(client):
|
| 15 |
+
oversized = b"MZ" + (b"0" * (50 * 1024 * 1024 + 1))
|
| 16 |
+
|
| 17 |
+
response = client.post(
|
| 18 |
+
"/api/upload/analyze",
|
| 19 |
+
files={"file": ("big.exe", oversized, "application/octet-stream")},
|
| 20 |
+
)
|
| 21 |
+
|
| 22 |
+
assert response.status_code == 400
|
| 23 |
+
assert "File too large" in response.json()["detail"]
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
def test_upload_analyze_happy_path_with_mocked_lief(client, monkeypatch):
|
| 27 |
+
from app.routers import upload
|
| 28 |
+
|
| 29 |
+
monkeypatch.setattr(upload, "LIEF_AVAILABLE", True)
|
| 30 |
+
monkeypatch.setattr(
|
| 31 |
+
upload,
|
| 32 |
+
"extract_features_and_lief",
|
| 33 |
+
lambda content: (np.zeros(2381, dtype=float), "unused", object()),
|
| 34 |
+
)
|
| 35 |
+
|
| 36 |
+
response = client.post(
|
| 37 |
+
"/api/upload/analyze?include_explanation=false",
|
| 38 |
+
files={"file": ("sample.exe", b"MZfake-pe", "application/octet-stream")},
|
| 39 |
+
)
|
| 40 |
+
|
| 41 |
+
assert response.status_code == 200
|
| 42 |
+
body = response.json()
|
| 43 |
+
assert body["features_extracted"] is True
|
| 44 |
+
assert body["feature_count"] == 2381
|
| 45 |
+
assert body["prediction"]["prediction"] == "Malicious"
|
backend/tests/test_url.py
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
def test_url_analyze_happy_path(client):
|
| 2 |
+
response = client.post(
|
| 3 |
+
"/api/url/analyze",
|
| 4 |
+
json={"url": "https://example.com/login", "threshold": 0.4},
|
| 5 |
+
)
|
| 6 |
+
|
| 7 |
+
assert response.status_code == 200
|
| 8 |
+
body = response.json()
|
| 9 |
+
assert body["prediction"] == "Malicious"
|
| 10 |
+
assert body["threshold_used"] == 0.4
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
def test_url_analyze_returns_503_when_model_not_loaded(client, services):
|
| 14 |
+
services.url.model_loaded = False
|
| 15 |
+
|
| 16 |
+
response = client.post("/api/url/analyze", json={"url": "https://example.com"})
|
| 17 |
+
|
| 18 |
+
assert response.status_code == 503
|
| 19 |
+
assert response.json()["detail"] == "URL model not loaded"
|
backend/tests/test_virustotal.py
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from app.models.virustotal import VirusTotalResponse
|
| 2 |
+
|
| 3 |
+
|
| 4 |
+
def test_virustotal_rejects_bad_hash(client):
|
| 5 |
+
response = client.get("/api/virustotal/not-a-hash")
|
| 6 |
+
|
| 7 |
+
assert response.status_code == 422
|
| 8 |
+
|
| 9 |
+
|
| 10 |
+
def test_virustotal_compare_returns_404_for_not_found(client, features, sha256, services):
|
| 11 |
+
services.virustotal.next_result = VirusTotalResponse(
|
| 12 |
+
sha256=sha256,
|
| 13 |
+
found=False,
|
| 14 |
+
error_message="Hash not found in VirusTotal database",
|
| 15 |
+
)
|
| 16 |
+
|
| 17 |
+
response = client.post(
|
| 18 |
+
"/api/virustotal/compare",
|
| 19 |
+
json={"features": features, "sha256": sha256},
|
| 20 |
+
)
|
| 21 |
+
|
| 22 |
+
assert response.status_code == 404
|
| 23 |
+
assert "Hash not found" in response.json()["detail"]
|
urlmodel_info/case_study_results.csv
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Description,True Label,XGB Score,LGB Score,TF-IDF Score,HyperModel,Prediction,Correct
|
| 2 |
+
Legitimate Google,Benign,0.999,0.999,1.0,1.0,Malicious,❌
|
| 3 |
+
Legitimate Amazon,Benign,1.0,1.0,1.0,1.0,Malicious,❌
|
| 4 |
+
Legitimate GitHub,Benign,0.998,0.998,1.0,1.0,Malicious,❌
|
| 5 |
+
Legitimate Wikipedia,Benign,1.0,1.0,0.998,1.0,Malicious,❌
|
| 6 |
+
Typosquatting Google,Malicious,0.986,0.997,0.999,1.0,Malicious,✅
|
| 7 |
+
Typosquatting Amazon,Malicious,0.993,0.99,0.995,1.0,Malicious,✅
|
| 8 |
+
Typosquatting PayPal,Malicious,0.981,0.988,0.991,1.0,Malicious,✅
|
| 9 |
+
Brand subdomain phishing,Malicious,0.982,0.996,1.0,1.0,Malicious,✅
|
| 10 |
+
Brand path phishing,Malicious,0.997,0.998,0.999,1.0,Malicious,✅
|
| 11 |
+
IP-based phishing,Malicious,1.0,0.999,0.992,1.0,Malicious,✅
|
| 12 |
+
IP-based phishing 2,Malicious,1.0,0.999,0.996,1.0,Malicious,✅
|
| 13 |
+
Punycode phishing,Malicious,0.982,0.974,0.999,1.0,Malicious,✅
|
| 14 |
+
URL shortener (suspicious),Malicious,0.998,0.997,1.0,1.0,Malicious,✅
|
| 15 |
+
Hex-encoded phishing,Malicious,0.903,0.971,0.947,1.0,Malicious,✅
|
| 16 |
+
Long suspicious URL,Malicious,0.877,0.805,0.831,1.0,Malicious,✅
|
| 17 |
+
Legit MS Security,Benign,1.0,1.0,0.999,1.0,Malicious,❌
|
| 18 |
+
Legit Google OAuth,Benign,0.999,0.999,0.993,1.0,Malicious,❌
|
urlmodel_info/case_study_scores.png
ADDED

|
Git LFS Details
|
urlmodel_info/char_bilstm_net.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6abb849aa9d0ecbea8a58b817606fb3be9a8e9a45cc815ef3102c2e28368060d
|
| 3 |
+
size 2537781
|
urlmodel_info/char_cnn_net.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4dd4f4b78b8d6c34f331ab952846b65e579ecdae1ca4c811984d2e5ba00f3bb3
|
| 3 |
+
size 865013
|
urlmodel_info/download_data.py
ADDED
|
@@ -0,0 +1,111 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Download the Malicious URLs dataset (~651K rows, 4 classes).
|
| 3 |
+
|
| 4 |
+
Dataset: Manu Siddhartha — Malicious URLs Dataset
|
| 5 |
+
Source: https://www.kaggle.com/datasets/sid321axn/malicious-urls-dataset
|
| 6 |
+
Classes: benign (428,103) · defacement (96,457) · phishing (94,111) · malware (32,520)
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
import os
|
| 10 |
+
import sys
|
| 11 |
+
import pathlib
|
| 12 |
+
import shutil
|
| 13 |
+
import subprocess
|
| 14 |
+
import glob
|
| 15 |
+
|
| 16 |
+
KAGGLE_SLUG = "sid321axn/malicious-urls-dataset"
|
| 17 |
+
|
| 18 |
+
CSV_FILENAME = "malicious_phishing.csv"
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
def download_malicious_urls(data_dir) -> pathlib.Path:
|
| 22 |
+
"""Download and return the path to the Malicious URLs CSV.
|
| 23 |
+
|
| 24 |
+
Tries kagglehub first, then the kaggle CLI, then prints manual
|
| 25 |
+
download instructions.
|
| 26 |
+
|
| 27 |
+
Parameters
|
| 28 |
+
----------
|
| 29 |
+
data_dir : str or pathlib.Path
|
| 30 |
+
Directory to store the downloaded CSV.
|
| 31 |
+
|
| 32 |
+
Returns
|
| 33 |
+
-------
|
| 34 |
+
pathlib.Path
|
| 35 |
+
Path to the CSV file.
|
| 36 |
+
"""
|
| 37 |
+
data_dir = pathlib.Path(data_dir)
|
| 38 |
+
data_dir.mkdir(parents=True, exist_ok=True)
|
| 39 |
+
csv_path = data_dir / CSV_FILENAME
|
| 40 |
+
|
| 41 |
+
if csv_path.exists():
|
| 42 |
+
print(f"✅ Dataset already exists: {csv_path}")
|
| 43 |
+
return csv_path
|
| 44 |
+
|
| 45 |
+
# ── Attempt 1: kagglehub ──────────────────────────────────────────────
|
| 46 |
+
try:
|
| 47 |
+
import kagglehub
|
| 48 |
+
except ImportError:
|
| 49 |
+
subprocess.check_call(
|
| 50 |
+
[sys.executable, "-m", "pip", "install", "kagglehub", "-q"]
|
| 51 |
+
)
|
| 52 |
+
import kagglehub
|
| 53 |
+
|
| 54 |
+
try:
|
| 55 |
+
print("Downloading via kagglehub …")
|
| 56 |
+
dl_path = kagglehub.dataset_download(KAGGLE_SLUG)
|
| 57 |
+
src = _find_csv(dl_path)
|
| 58 |
+
if src:
|
| 59 |
+
shutil.copy2(src, csv_path)
|
| 60 |
+
print(f"✅ Dataset saved to {csv_path}")
|
| 61 |
+
return csv_path
|
| 62 |
+
except Exception as e:
|
| 63 |
+
print(f" kagglehub failed: {e}")
|
| 64 |
+
|
| 65 |
+
# ── Attempt 2: kaggle CLI ────────────────────────────────────────────
|
| 66 |
+
if shutil.which("kaggle"):
|
| 67 |
+
try:
|
| 68 |
+
print("Downloading via kaggle CLI …")
|
| 69 |
+
subprocess.check_call(
|
| 70 |
+
[
|
| 71 |
+
"kaggle", "datasets", "download",
|
| 72 |
+
"-d", KAGGLE_SLUG,
|
| 73 |
+
"-p", str(data_dir),
|
| 74 |
+
"--unzip",
|
| 75 |
+
],
|
| 76 |
+
timeout=300,
|
| 77 |
+
)
|
| 78 |
+
src = _find_csv(str(data_dir))
|
| 79 |
+
if src and pathlib.Path(src) != csv_path:
|
| 80 |
+
shutil.move(src, csv_path)
|
| 81 |
+
if csv_path.exists():
|
| 82 |
+
print(f"✅ Dataset saved to {csv_path}")
|
| 83 |
+
return csv_path
|
| 84 |
+
except Exception as e:
|
| 85 |
+
print(f" kaggle CLI failed: {e}")
|
| 86 |
+
|
| 87 |
+
# ── Manual instructions ──────────────────────────────────────────────
|
| 88 |
+
print("\n" + "=" * 60)
|
| 89 |
+
print(" MANUAL DOWNLOAD REQUIRED")
|
| 90 |
+
print("=" * 60)
|
| 91 |
+
print(f" 1. Visit: https://www.kaggle.com/datasets/{KAGGLE_SLUG}")
|
| 92 |
+
print(f" 2. Click 'Download' and extract the ZIP")
|
| 93 |
+
print(f" 3. Place '{CSV_FILENAME}' in: {data_dir.resolve()}")
|
| 94 |
+
print("=" * 60)
|
| 95 |
+
raise FileNotFoundError(
|
| 96 |
+
f"Could not auto-download dataset. Place '{CSV_FILENAME}' in {data_dir}"
|
| 97 |
+
)
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
def _find_csv(root_dir: str):
|
| 101 |
+
"""Walk a directory tree and return the first CSV file path found."""
|
| 102 |
+
for dirpath, _, filenames in os.walk(root_dir):
|
| 103 |
+
for fn in filenames:
|
| 104 |
+
if fn.endswith(".csv"):
|
| 105 |
+
return os.path.join(dirpath, fn)
|
| 106 |
+
return None
|
| 107 |
+
|
| 108 |
+
|
| 109 |
+
if __name__ == "__main__":
|
| 110 |
+
path = download_malicious_urls("data")
|
| 111 |
+
print(f"Dataset at: {path}")
|
urlmodel_info/eda_class_distribution.png
ADDED
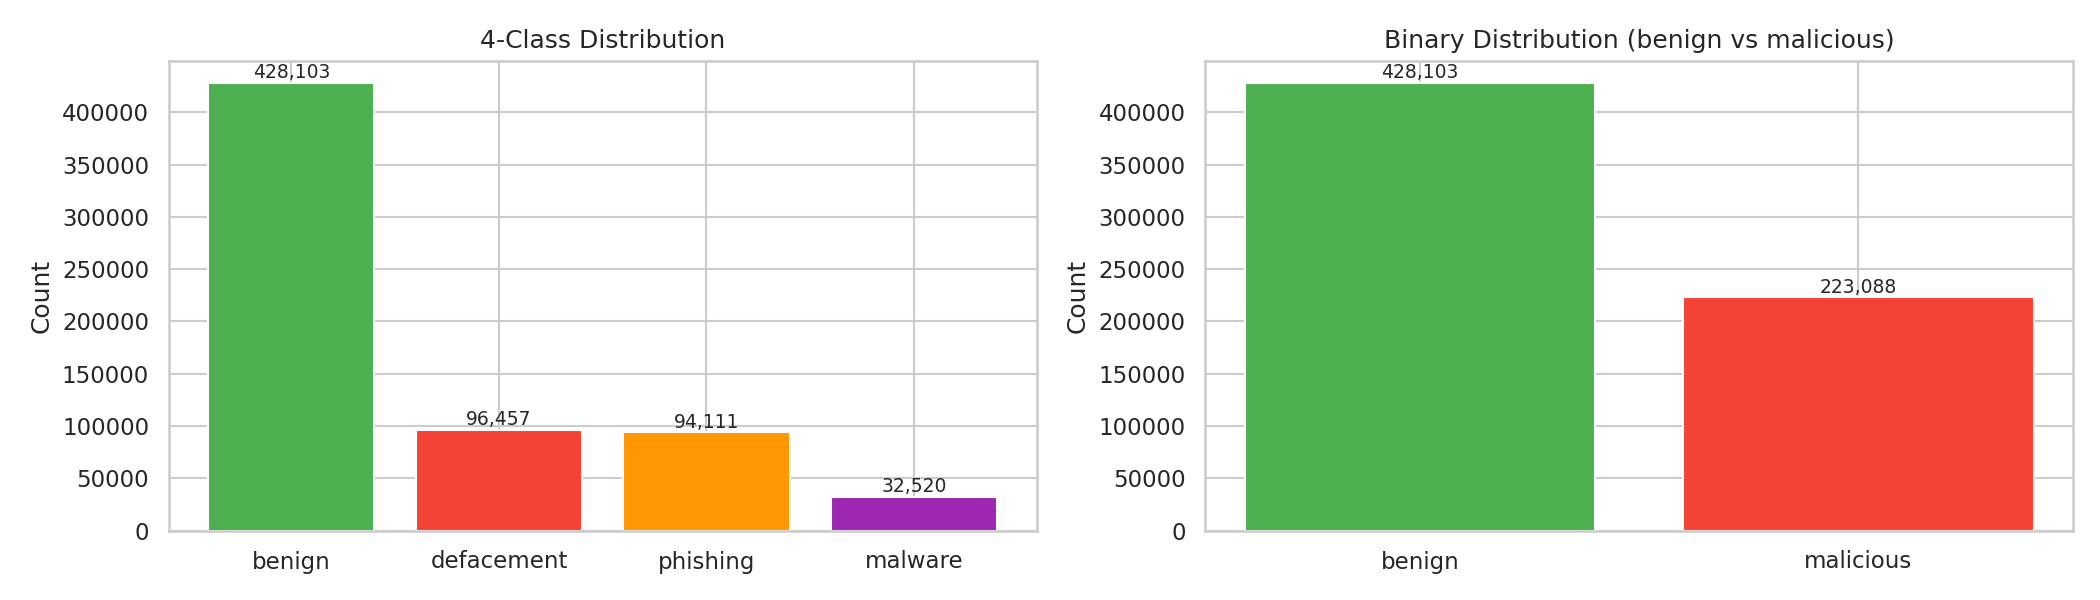
|
urlmodel_info/eda_feature_distributions.png
ADDED

|
Git LFS Details
|
urlmodel_info/eda_url_length_by_class.png
ADDED

|
urlmodel_info/evaluation.py
ADDED
|
@@ -0,0 +1,226 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Evaluation utilities — metrics, comparison tables, and publication-quality plots.
|
| 3 |
+
"""
|
| 4 |
+
|
| 5 |
+
from __future__ import annotations
|
| 6 |
+
|
| 7 |
+
import numpy as np
|
| 8 |
+
import pandas as pd
|
| 9 |
+
import matplotlib.pyplot as plt
|
| 10 |
+
import seaborn as sns
|
| 11 |
+
from sklearn.metrics import (
|
| 12 |
+
accuracy_score,
|
| 13 |
+
precision_score,
|
| 14 |
+
recall_score,
|
| 15 |
+
f1_score,
|
| 16 |
+
roc_auc_score,
|
| 17 |
+
confusion_matrix,
|
| 18 |
+
classification_report,
|
| 19 |
+
)
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 23 |
+
# Core evaluation
|
| 24 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 25 |
+
|
| 26 |
+
def evaluate_model(
|
| 27 |
+
name: str,
|
| 28 |
+
y_true: np.ndarray,
|
| 29 |
+
y_pred: np.ndarray,
|
| 30 |
+
y_proba: np.ndarray | None = None,
|
| 31 |
+
class_names: list[str] | None = None,
|
| 32 |
+
task: str = "binary",
|
| 33 |
+
) -> dict:
|
| 34 |
+
"""Compute comprehensive classification metrics.
|
| 35 |
+
|
| 36 |
+
Parameters
|
| 37 |
+
----------
|
| 38 |
+
name : str
|
| 39 |
+
Model name.
|
| 40 |
+
y_true, y_pred : array-like
|
| 41 |
+
Ground truth and predicted labels.
|
| 42 |
+
y_proba : array-like, optional
|
| 43 |
+
Class probability matrix (n_samples × n_classes).
|
| 44 |
+
class_names : list[str]
|
| 45 |
+
Human-readable class names.
|
| 46 |
+
task : str
|
| 47 |
+
``"binary"`` or ``"multiclass"``.
|
| 48 |
+
|
| 49 |
+
Returns
|
| 50 |
+
-------
|
| 51 |
+
dict with keys: name, accuracy, precision, recall, f1_macro, auc_roc,
|
| 52 |
+
confusion_matrix, classification_report.
|
| 53 |
+
"""
|
| 54 |
+
y_true = np.asarray(y_true)
|
| 55 |
+
y_pred = np.asarray(y_pred)
|
| 56 |
+
|
| 57 |
+
acc = accuracy_score(y_true, y_pred)
|
| 58 |
+
prec = precision_score(y_true, y_pred, average="macro", zero_division=0)
|
| 59 |
+
rec = recall_score(y_true, y_pred, average="macro", zero_division=0)
|
| 60 |
+
f1 = f1_score(y_true, y_pred, average="macro", zero_division=0)
|
| 61 |
+
|
| 62 |
+
auc = None
|
| 63 |
+
if y_proba is not None:
|
| 64 |
+
y_proba = np.asarray(y_proba)
|
| 65 |
+
try:
|
| 66 |
+
if task == "binary" and y_proba.ndim == 2:
|
| 67 |
+
auc = roc_auc_score(y_true, y_proba[:, 1])
|
| 68 |
+
else:
|
| 69 |
+
auc = roc_auc_score(y_true, y_proba, multi_class="ovr", average="macro")
|
| 70 |
+
except Exception:
|
| 71 |
+
auc = None
|
| 72 |
+
|
| 73 |
+
cm = confusion_matrix(y_true, y_pred)
|
| 74 |
+
target_names = class_names or [str(c) for c in sorted(np.unique(y_true))]
|
| 75 |
+
cr = classification_report(y_true, y_pred, target_names=target_names, zero_division=0)
|
| 76 |
+
|
| 77 |
+
return {
|
| 78 |
+
"name": name,
|
| 79 |
+
"accuracy": acc,
|
| 80 |
+
"precision": prec,
|
| 81 |
+
"recall": rec,
|
| 82 |
+
"f1_macro": f1,
|
| 83 |
+
"auc_roc": auc,
|
| 84 |
+
"confusion_matrix": cm,
|
| 85 |
+
"classification_report": cr,
|
| 86 |
+
}
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
def print_results_banner(result: dict) -> None:
|
| 90 |
+
"""Pretty-print a model's evaluation results."""
|
| 91 |
+
print(f"\n{'─' * 50}")
|
| 92 |
+
print(f" {result['name']}")
|
| 93 |
+
print(f"{'─' * 50}")
|
| 94 |
+
print(f" Accuracy : {result['accuracy']:.4f}")
|
| 95 |
+
print(f" Precision : {result['precision']:.4f}")
|
| 96 |
+
print(f" Recall : {result['recall']:.4f}")
|
| 97 |
+
print(f" F1 (macro): {result['f1_macro']:.4f}")
|
| 98 |
+
if result["auc_roc"] is not None:
|
| 99 |
+
print(f" AUC-ROC : {result['auc_roc']:.4f}")
|
| 100 |
+
print(f"{'─' * 50}")
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 104 |
+
# Literature comparison table
|
| 105 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 106 |
+
|
| 107 |
+
_LITERATURE_BASELINES = [
|
| 108 |
+
{"Method": "RF on URL features (Sahingoz 2019)", "Accuracy": 0.9798,
|
| 109 |
+
"F1 (macro)": 0.9793, "AUC-ROC": None, "Source": "Literature"},
|
| 110 |
+
{"Method": "XGBoost (Rao & Pais 2019)", "Accuracy": 0.9685,
|
| 111 |
+
"F1 (macro)": None, "AUC-ROC": 0.993, "Source": "Literature"},
|
| 112 |
+
{"Method": "URLNet CharCNN (Le 2018)", "Accuracy": 0.985,
|
| 113 |
+
"F1 (macro)": None, "AUC-ROC": 0.986, "Source": "Literature"},
|
| 114 |
+
{"Method": "LSTM (Bahnsen 2018)", "Accuracy": 0.987,
|
| 115 |
+
"F1 (macro)": None, "AUC-ROC": None, "Source": "Literature"},
|
| 116 |
+
{"Method": "Stacking CNN+LSTM+GRU (Nguyen 2021)", "Accuracy": 0.975,
|
| 117 |
+
"F1 (macro)": 0.972, "AUC-ROC": None, "Source": "Literature"},
|
| 118 |
+
{"Method": "Hybrid DNN+LSTM (Ozcan 2021)", "Accuracy": 0.964,
|
| 119 |
+
"F1 (macro)": None, "AUC-ROC": 0.973, "Source": "Literature"},
|
| 120 |
+
{"Method": "CharCNN (Aljofey 2022)", "Accuracy": 0.9675,
|
| 121 |
+
"F1 (macro)": 0.9671, "AUC-ROC": 0.991, "Source": "Literature"},
|
| 122 |
+
]
|
| 123 |
+
|
| 124 |
+
|
| 125 |
+
def build_comparison_table(
|
| 126 |
+
our_results: list[dict],
|
| 127 |
+
task: str = "binary",
|
| 128 |
+
) -> pd.DataFrame:
|
| 129 |
+
"""Build a comparison table of our results vs. literature baselines.
|
| 130 |
+
|
| 131 |
+
Parameters
|
| 132 |
+
----------
|
| 133 |
+
our_results : list[dict]
|
| 134 |
+
Each dict is the output of ``evaluate_model()``.
|
| 135 |
+
task : str
|
| 136 |
+
``"binary"`` or ``"multiclass"``.
|
| 137 |
+
|
| 138 |
+
Returns
|
| 139 |
+
-------
|
| 140 |
+
pd.DataFrame
|
| 141 |
+
"""
|
| 142 |
+
rows = list(_LITERATURE_BASELINES)
|
| 143 |
+
for r in our_results:
|
| 144 |
+
rows.append({
|
| 145 |
+
"Method": r["name"],
|
| 146 |
+
"Accuracy": r["accuracy"],
|
| 147 |
+
"F1 (macro)": r["f1_macro"],
|
| 148 |
+
"AUC-ROC": r["auc_roc"],
|
| 149 |
+
"Source": "Ours",
|
| 150 |
+
})
|
| 151 |
+
df = pd.DataFrame(rows)
|
| 152 |
+
df = df.sort_values("Accuracy", ascending=False).reset_index(drop=True)
|
| 153 |
+
return df
|
| 154 |
+
|
| 155 |
+
|
| 156 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 157 |
+
# Plotting helpers
|
| 158 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 159 |
+
|
| 160 |
+
def plot_accuracy_bar(
|
| 161 |
+
comparison_df: pd.DataFrame,
|
| 162 |
+
save_path: str | None = None,
|
| 163 |
+
) -> plt.Figure:
|
| 164 |
+
"""Horizontal bar chart of accuracies, colour-coded by source."""
|
| 165 |
+
fig, ax = plt.subplots(figsize=(10, max(5, len(comparison_df) * 0.45)))
|
| 166 |
+
colors = ["#1976D2" if s == "Ours" else "#BDBDBD"
|
| 167 |
+
for s in comparison_df["Source"]]
|
| 168 |
+
y = range(len(comparison_df))
|
| 169 |
+
ax.barh(y, comparison_df["Accuracy"], color=colors, edgecolor="white", height=0.6)
|
| 170 |
+
ax.set_yticks(y)
|
| 171 |
+
ax.set_yticklabels(comparison_df["Method"], fontsize=9)
|
| 172 |
+
ax.set_xlabel("Accuracy")
|
| 173 |
+
ax.set_title("Model Accuracy — Ours vs Literature")
|
| 174 |
+
ax.invert_yaxis()
|
| 175 |
+
ax.set_xlim(0.85, 1.01)
|
| 176 |
+
for i, v in enumerate(comparison_df["Accuracy"]):
|
| 177 |
+
if pd.notna(v):
|
| 178 |
+
ax.text(v + 0.002, i, f"{v:.4f}", va="center", fontsize=8)
|
| 179 |
+
plt.tight_layout()
|
| 180 |
+
if save_path:
|
| 181 |
+
fig.savefig(save_path, dpi=150, bbox_inches="tight")
|
| 182 |
+
return fig
|
| 183 |
+
|
| 184 |
+
|
| 185 |
+
def plot_confusion_matrix(
|
| 186 |
+
cm: np.ndarray,
|
| 187 |
+
class_names: list[str],
|
| 188 |
+
title: str = "Confusion Matrix",
|
| 189 |
+
save_path: str | None = None,
|
| 190 |
+
) -> plt.Figure:
|
| 191 |
+
"""Plot an annotated confusion matrix heatmap."""
|
| 192 |
+
fig, ax = plt.subplots(figsize=(6, 5))
|
| 193 |
+
sns.heatmap(
|
| 194 |
+
cm, annot=True, fmt="d", cmap="Blues",
|
| 195 |
+
xticklabels=class_names, yticklabels=class_names, ax=ax,
|
| 196 |
+
)
|
| 197 |
+
ax.set_xlabel("Predicted")
|
| 198 |
+
ax.set_ylabel("True")
|
| 199 |
+
ax.set_title(title)
|
| 200 |
+
plt.tight_layout()
|
| 201 |
+
if save_path:
|
| 202 |
+
fig.savefig(save_path, dpi=150, bbox_inches="tight")
|
| 203 |
+
return fig
|
| 204 |
+
|
| 205 |
+
|
| 206 |
+
def plot_feature_importance(
|
| 207 |
+
feature_names: list[str],
|
| 208 |
+
importances: np.ndarray,
|
| 209 |
+
top_n: int = 25,
|
| 210 |
+
title: str = "Feature Importance",
|
| 211 |
+
save_path: str | None = None,
|
| 212 |
+
) -> plt.Figure:
|
| 213 |
+
"""Horizontal bar chart of top-N feature importances."""
|
| 214 |
+
idx = np.argsort(importances)[-top_n:]
|
| 215 |
+
fig, ax = plt.subplots(figsize=(8, max(4, top_n * 0.3)))
|
| 216 |
+
ax.barh(
|
| 217 |
+
[feature_names[i] for i in idx],
|
| 218 |
+
importances[idx],
|
| 219 |
+
color="#1976D2", edgecolor="white",
|
| 220 |
+
)
|
| 221 |
+
ax.set_xlabel("Importance")
|
| 222 |
+
ax.set_title(title)
|
| 223 |
+
plt.tight_layout()
|
| 224 |
+
if save_path:
|
| 225 |
+
fig.savefig(save_path, dpi=150, bbox_inches="tight")
|
| 226 |
+
return fig
|
urlmodel_info/feature_engineering.py
ADDED
|
@@ -0,0 +1,347 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
URL Feature Engineering — 50+ lexical features for malicious URL detection.
|
| 3 |
+
|
| 4 |
+
Features are grouped into 8 categories:
|
| 5 |
+
1. Length / structural (7 features)
|
| 6 |
+
2. Character counts (14 features)
|
| 7 |
+
3. Character ratios (5 features)
|
| 8 |
+
4. Entropy / randomness (2 features)
|
| 9 |
+
5. Boolean indicators (10 features)
|
| 10 |
+
6. Domain / TLD signals (6 features)
|
| 11 |
+
7. Suspicious-pattern scores (5 features)
|
| 12 |
+
8. Path & query analysis (5 features)
|
| 13 |
+
"""
|
| 14 |
+
|
| 15 |
+
from __future__ import annotations
|
| 16 |
+
|
| 17 |
+
import math
|
| 18 |
+
import re
|
| 19 |
+
from collections import Counter
|
| 20 |
+
from urllib.parse import urlparse, parse_qs
|
| 21 |
+
|
| 22 |
+
import numpy as np
|
| 23 |
+
import pandas as pd
|
| 24 |
+
from joblib import Parallel, delayed
|
| 25 |
+
|
| 26 |
+
try:
|
| 27 |
+
import tldextract
|
| 28 |
+
except ImportError:
|
| 29 |
+
tldextract = None
|
| 30 |
+
|
| 31 |
+
# ── Regex patterns (compiled once) ────────────────────────────────────────────
|
| 32 |
+
_IP_RE = re.compile(
|
| 33 |
+
r"(?:^|[/@])(\d{1,3}\.){3}\d{1,3}(?:[:/]|$)"
|
| 34 |
+
)
|
| 35 |
+
_HEX_RE = re.compile(r"%[0-9a-fA-F]{2}")
|
| 36 |
+
_SHORTENERS = frozenset([
|
| 37 |
+
"bit.ly", "goo.gl", "tinyurl.com", "ow.ly", "t.co", "is.gd",
|
| 38 |
+
"buff.ly", "adf.ly", "tiny.cc", "lnkd.in", "rb.gy", "cutt.ly",
|
| 39 |
+
"shorturl.at", "rebrand.ly",
|
| 40 |
+
])
|
| 41 |
+
_SUSPICIOUS_TLDS = frozenset([
|
| 42 |
+
"tk", "ml", "ga", "cf", "gq", "xyz", "top", "pw", "cc",
|
| 43 |
+
"club", "work", "date", "racing", "stream", "download",
|
| 44 |
+
"win", "bid", "icu", "buzz", "monster",
|
| 45 |
+
])
|
| 46 |
+
_SUSPICIOUS_EXT = re.compile(
|
| 47 |
+
r"\.(exe|zip|rar|scr|bat|cmd|js|vbs|ps1|dll|msi|apk|dmg|iso|php|cgi)(\?|$)",
|
| 48 |
+
re.IGNORECASE,
|
| 49 |
+
)
|
| 50 |
+
_PHISHING_KW = re.compile(
|
| 51 |
+
r"(login|signin|verify|account|update|secure|bank|confirm|password|"
|
| 52 |
+
r"credential|suspend|alert|notification|wallet|paypal|apple|microsoft|"
|
| 53 |
+
r"amazon|netflix|facebook|instagram|whatsapp|dropbox|google|icloud)",
|
| 54 |
+
re.IGNORECASE,
|
| 55 |
+
)
|
| 56 |
+
_BRAND_NAMES = [
|
| 57 |
+
"google", "facebook", "apple", "amazon", "microsoft", "netflix",
|
| 58 |
+
"paypal", "instagram", "whatsapp", "dropbox", "linkedin", "twitter",
|
| 59 |
+
"yahoo", "ebay", "chase", "wellsfargo", "bankofamerica", "citibank",
|
| 60 |
+
"hsbc", "dhl", "fedex", "usps",
|
| 61 |
+
]
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 65 |
+
# Feature extraction for a single URL
|
| 66 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 67 |
+
|
| 68 |
+
def _entropy(s: str) -> float:
|
| 69 |
+
"""Shannon entropy of a string."""
|
| 70 |
+
if not s:
|
| 71 |
+
return 0.0
|
| 72 |
+
cnt = Counter(s)
|
| 73 |
+
length = len(s)
|
| 74 |
+
return -sum((c / length) * math.log2(c / length) for c in cnt.values())
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
def _extract_one(url: str) -> dict:
|
| 78 |
+
"""Extract all features from a single URL string (fully exception-safe)."""
|
| 79 |
+
try:
|
| 80 |
+
return _extract_one_inner(url)
|
| 81 |
+
except Exception:
|
| 82 |
+
# Return a row of zeros for truly broken URLs
|
| 83 |
+
return {name: 0 for name in URLFeatureExtractor._NAMES}
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
def _extract_one_inner(url: str) -> dict:
|
| 87 |
+
"""Core logic — may raise on malformed URLs."""
|
| 88 |
+
url = str(url).strip()
|
| 89 |
+
|
| 90 |
+
try:
|
| 91 |
+
parsed = urlparse(url if "://" in url else f"http://{url}")
|
| 92 |
+
except Exception:
|
| 93 |
+
try:
|
| 94 |
+
safe = url.replace("[", "").replace("]", "")
|
| 95 |
+
parsed = urlparse(safe if "://" in safe else f"http://{safe}")
|
| 96 |
+
except Exception:
|
| 97 |
+
parsed = urlparse("http://invalid")
|
| 98 |
+
|
| 99 |
+
try:
|
| 100 |
+
hostname = parsed.hostname or ""
|
| 101 |
+
except Exception:
|
| 102 |
+
hostname = ""
|
| 103 |
+
path = parsed.path or ""
|
| 104 |
+
query = parsed.query or ""
|
| 105 |
+
fragment = parsed.fragment or ""
|
| 106 |
+
scheme = (parsed.scheme or "").lower()
|
| 107 |
+
|
| 108 |
+
# TLD extraction
|
| 109 |
+
if tldextract is not None:
|
| 110 |
+
ext = tldextract.extract(url)
|
| 111 |
+
domain = ext.domain
|
| 112 |
+
tld = ext.suffix
|
| 113 |
+
subdomain = ext.subdomain
|
| 114 |
+
else:
|
| 115 |
+
domain = hostname.split(".")[-2] if hostname.count(".") >= 1 else hostname
|
| 116 |
+
tld = hostname.split(".")[-1] if "." in hostname else ""
|
| 117 |
+
subdomain = ".".join(hostname.split(".")[:-2]) if hostname.count(".") >= 2 else ""
|
| 118 |
+
|
| 119 |
+
url_lower = url.lower()
|
| 120 |
+
|
| 121 |
+
# ── 1. Length / structural ────────────────────────────────────────────
|
| 122 |
+
url_length = len(url)
|
| 123 |
+
hostname_length = len(hostname)
|
| 124 |
+
domain_length = len(domain)
|
| 125 |
+
path_length = len(path)
|
| 126 |
+
query_length = len(query)
|
| 127 |
+
fragment_length = len(fragment)
|
| 128 |
+
tld_length = len(tld)
|
| 129 |
+
|
| 130 |
+
# ── 2. Character counts ──────────────────────────────────────────────
|
| 131 |
+
num_dots = url.count(".")
|
| 132 |
+
num_hyphens = url.count("-")
|
| 133 |
+
num_underscores = url.count("_")
|
| 134 |
+
num_slashes = url.count("/")
|
| 135 |
+
num_at_signs = url.count("@")
|
| 136 |
+
num_ampersands = url.count("&")
|
| 137 |
+
num_equals = url.count("=")
|
| 138 |
+
num_question_marks = url.count("?")
|
| 139 |
+
num_percent = url.count("%")
|
| 140 |
+
num_tilde = url.count("~")
|
| 141 |
+
num_digits = sum(c.isdigit() for c in url)
|
| 142 |
+
num_letters = sum(c.isalpha() for c in url)
|
| 143 |
+
num_special = sum(not c.isalnum() and c not in ":/." for c in url)
|
| 144 |
+
num_params = len(parse_qs(query))
|
| 145 |
+
|
| 146 |
+
# ── 3. Character ratios ──────────────────────────────────────────────
|
| 147 |
+
safe_len = max(url_length, 1)
|
| 148 |
+
digit_ratio = num_digits / safe_len
|
| 149 |
+
letter_ratio = num_letters / safe_len
|
| 150 |
+
special_ratio = num_special / safe_len
|
| 151 |
+
uppercase_ratio = sum(c.isupper() for c in url) / safe_len
|
| 152 |
+
digit_letter_ratio = num_digits / max(num_letters, 1)
|
| 153 |
+
|
| 154 |
+
# ── 4. Entropy ───────────────────────────────────────────────────────
|
| 155 |
+
url_entropy = _entropy(url)
|
| 156 |
+
domain_entropy = _entropy(hostname)
|
| 157 |
+
|
| 158 |
+
# ── 5. Boolean indicators ────────────────────────────────────────────
|
| 159 |
+
|
| 160 |
+
has_ip = int(bool(_IP_RE.search(url)))
|
| 161 |
+
has_https = int(scheme == "https")
|
| 162 |
+
has_http = int(scheme == "http")
|
| 163 |
+
has_www = int("www." in url_lower)
|
| 164 |
+
try:
|
| 165 |
+
_port = parsed.port
|
| 166 |
+
except (ValueError, TypeError):
|
| 167 |
+
_port = None
|
| 168 |
+
has_port = int(_port is not None and _port not in (80, 443))
|
| 169 |
+
has_at_symbol = int("@" in url)
|
| 170 |
+
is_shortened = int(any(s in url_lower for s in _SHORTENERS))
|
| 171 |
+
has_double_slash_redirect = int("//" in path)
|
| 172 |
+
has_punycode = int("xn--" in url_lower)
|
| 173 |
+
has_hex_encoding = int(bool(_HEX_RE.search(url)))
|
| 174 |
+
|
| 175 |
+
# ── 6. Domain / TLD signals ──────────────────────────────────────────
|
| 176 |
+
num_subdomains = subdomain.count(".") + 1 if subdomain else 0
|
| 177 |
+
subdomain_length = len(subdomain)
|
| 178 |
+
domain_token_count = len(re.split(r"[.\-_]", hostname))
|
| 179 |
+
has_suspicious_tld = int(tld.lower() in _SUSPICIOUS_TLDS)
|
| 180 |
+
domain_has_digits = int(any(c.isdigit() for c in domain))
|
| 181 |
+
domain_hyphen_count = domain.count("-")
|
| 182 |
+
|
| 183 |
+
# ── 7. Suspicious-pattern scores ─────────────────────────────────────
|
| 184 |
+
phishing_keyword_count = len(_PHISHING_KW.findall(url_lower))
|
| 185 |
+
brand_count = sum(1 for b in _BRAND_NAMES if b in url_lower)
|
| 186 |
+
has_suspicious_ext = int(bool(_SUSPICIOUS_EXT.search(url_lower)))
|
| 187 |
+
# Brand in subdomain but not in registered domain → likely phishing
|
| 188 |
+
brand_in_subdomain = int(
|
| 189 |
+
any(b in subdomain.lower() for b in _BRAND_NAMES) and
|
| 190 |
+
not any(b in domain.lower() for b in _BRAND_NAMES)
|
| 191 |
+
) if subdomain else 0
|
| 192 |
+
suspicious_word_ratio = phishing_keyword_count / max(
|
| 193 |
+
len(re.findall(r"[a-zA-Z]+", url)), 1
|
| 194 |
+
)
|
| 195 |
+
|
| 196 |
+
# ── 8. Path & query analysis ─────────────────────────────────────────
|
| 197 |
+
path_tokens = [t for t in path.split("/") if t]
|
| 198 |
+
path_depth = len(path_tokens)
|
| 199 |
+
longest_path_token = max((len(t) for t in path_tokens), default=0)
|
| 200 |
+
avg_path_token_len = (
|
| 201 |
+
sum(len(t) for t in path_tokens) / len(path_tokens) if path_tokens else 0.0
|
| 202 |
+
)
|
| 203 |
+
max_consecutive_digits = max(
|
| 204 |
+
(len(m.group()) for m in re.finditer(r"\d+", url)), default=0
|
| 205 |
+
)
|
| 206 |
+
path_entropy = _entropy(path)
|
| 207 |
+
|
| 208 |
+
return {
|
| 209 |
+
# 1. Length
|
| 210 |
+
"url_length": url_length,
|
| 211 |
+
"hostname_length": hostname_length,
|
| 212 |
+
"domain_length": domain_length,
|
| 213 |
+
"path_length": path_length,
|
| 214 |
+
"query_length": query_length,
|
| 215 |
+
"fragment_length": fragment_length,
|
| 216 |
+
"tld_length": tld_length,
|
| 217 |
+
# 2. Counts
|
| 218 |
+
"num_dots": num_dots,
|
| 219 |
+
"num_hyphens": num_hyphens,
|
| 220 |
+
"num_underscores": num_underscores,
|
| 221 |
+
"num_slashes": num_slashes,
|
| 222 |
+
"num_at_signs": num_at_signs,
|
| 223 |
+
"num_ampersands": num_ampersands,
|
| 224 |
+
"num_equals": num_equals,
|
| 225 |
+
"num_question_marks": num_question_marks,
|
| 226 |
+
"num_percent": num_percent,
|
| 227 |
+
"num_tilde": num_tilde,
|
| 228 |
+
"num_digits": num_digits,
|
| 229 |
+
"num_letters": num_letters,
|
| 230 |
+
"num_special": num_special,
|
| 231 |
+
"num_params": num_params,
|
| 232 |
+
# 3. Ratios
|
| 233 |
+
"digit_ratio": digit_ratio,
|
| 234 |
+
"letter_ratio": letter_ratio,
|
| 235 |
+
"special_ratio": special_ratio,
|
| 236 |
+
"uppercase_ratio": uppercase_ratio,
|
| 237 |
+
"digit_letter_ratio": digit_letter_ratio,
|
| 238 |
+
# 4. Entropy
|
| 239 |
+
"url_entropy": url_entropy,
|
| 240 |
+
"domain_entropy": domain_entropy,
|
| 241 |
+
# 5. Booleans
|
| 242 |
+
"has_ip": has_ip,
|
| 243 |
+
"has_https": has_https,
|
| 244 |
+
"has_http": has_http,
|
| 245 |
+
"has_www": has_www,
|
| 246 |
+
"has_port": has_port,
|
| 247 |
+
"has_at_symbol": has_at_symbol,
|
| 248 |
+
"is_shortened": is_shortened,
|
| 249 |
+
"has_double_slash_redirect": has_double_slash_redirect,
|
| 250 |
+
"has_punycode": has_punycode,
|
| 251 |
+
"has_hex_encoding": has_hex_encoding,
|
| 252 |
+
# 6. Domain
|
| 253 |
+
"num_subdomains": num_subdomains,
|
| 254 |
+
"subdomain_length": subdomain_length,
|
| 255 |
+
"domain_token_count": domain_token_count,
|
| 256 |
+
"has_suspicious_tld": has_suspicious_tld,
|
| 257 |
+
"domain_has_digits": domain_has_digits,
|
| 258 |
+
"domain_hyphen_count": domain_hyphen_count,
|
| 259 |
+
# 7. Suspicious
|
| 260 |
+
"phishing_keyword_count": phishing_keyword_count,
|
| 261 |
+
"brand_count": brand_count,
|
| 262 |
+
"has_suspicious_ext": has_suspicious_ext,
|
| 263 |
+
"brand_in_subdomain": brand_in_subdomain,
|
| 264 |
+
"suspicious_word_ratio": suspicious_word_ratio,
|
| 265 |
+
# 8. Path / query
|
| 266 |
+
"path_depth": path_depth,
|
| 267 |
+
"longest_path_token": longest_path_token,
|
| 268 |
+
"avg_path_token_len": avg_path_token_len,
|
| 269 |
+
"max_consecutive_digits": max_consecutive_digits,
|
| 270 |
+
"path_entropy": path_entropy,
|
| 271 |
+
}
|
| 272 |
+
|
| 273 |
+
|
| 274 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 275 |
+
# Public API
|
| 276 |
+
# ═════════════════════════════════════════════════════════════════════════════
|
| 277 |
+
|
| 278 |
+
class URLFeatureExtractor:
|
| 279 |
+
"""Parallel URL feature extractor producing a DataFrame of 54 features."""
|
| 280 |
+
|
| 281 |
+
_NAMES = list(_extract_one("http://example.com").keys())
|
| 282 |
+
|
| 283 |
+
def __init__(self, n_jobs: int = -1):
|
| 284 |
+
self.n_jobs = n_jobs
|
| 285 |
+
|
| 286 |
+
@staticmethod
|
| 287 |
+
def feature_names() -> list[str]:
|
| 288 |
+
return list(URLFeatureExtractor._NAMES)
|
| 289 |
+
|
| 290 |
+
def transform(
|
| 291 |
+
self,
|
| 292 |
+
urls: pd.Series | list | np.ndarray,
|
| 293 |
+
verbose: bool = True,
|
| 294 |
+
) -> pd.DataFrame:
|
| 295 |
+
"""Extract features for a sequence of URLs.
|
| 296 |
+
|
| 297 |
+
Parameters
|
| 298 |
+
----------
|
| 299 |
+
urls : array-like of str
|
| 300 |
+
verbose : bool
|
| 301 |
+
Print progress info.
|
| 302 |
+
|
| 303 |
+
Returns
|
| 304 |
+
-------
|
| 305 |
+
pd.DataFrame with len(urls) rows × 54 feature columns.
|
| 306 |
+
"""
|
| 307 |
+
urls = list(urls)
|
| 308 |
+
if verbose:
|
| 309 |
+
print(f" Extracting features for {len(urls):,} URLs (n_jobs={self.n_jobs}) …")
|
| 310 |
+
|
| 311 |
+
rows = Parallel(n_jobs=self.n_jobs, backend="loky", batch_size=2048)(
|
| 312 |
+
delayed(_extract_one)(u) for u in urls
|
| 313 |
+
)
|
| 314 |
+
df = pd.DataFrame(rows, columns=self._NAMES)
|
| 315 |
+
# Ensure float32 for memory efficiency
|
| 316 |
+
df = df.astype(np.float32)
|
| 317 |
+
if verbose:
|
| 318 |
+
print(f" → {df.shape[0]:,} rows × {df.shape[1]} features")
|
| 319 |
+
return df
|
| 320 |
+
|
| 321 |
+
|
| 322 |
+
def featurize_dataset(csv_path: str, url_col: str = "url", label_col: str = "type",
|
| 323 |
+
n_jobs: int = -1) -> pd.DataFrame:
|
| 324 |
+
"""Load a CSV, extract features, and attach URLs + labels.
|
| 325 |
+
|
| 326 |
+
Parameters
|
| 327 |
+
----------
|
| 328 |
+
csv_path : str
|
| 329 |
+
Path to CSV with at least `url_col` and `label_col` columns.
|
| 330 |
+
url_col : str
|
| 331 |
+
Column containing URL strings.
|
| 332 |
+
label_col : str
|
| 333 |
+
Column containing class labels.
|
| 334 |
+
n_jobs : int
|
| 335 |
+
Parallelism for feature extraction.
|
| 336 |
+
|
| 337 |
+
Returns
|
| 338 |
+
-------
|
| 339 |
+
pd.DataFrame with columns: url, label, <54 features>
|
| 340 |
+
"""
|
| 341 |
+
df_raw = pd.read_csv(csv_path)
|
| 342 |
+
extractor = URLFeatureExtractor(n_jobs=n_jobs)
|
| 343 |
+
feat_df = extractor.transform(df_raw[url_col], verbose=True)
|
| 344 |
+
|
| 345 |
+
feat_df.insert(0, "url", df_raw[url_col].values)
|
| 346 |
+
feat_df["label"] = df_raw[label_col].values
|
| 347 |
+
return feat_df
|