

9ine commited on
Commit ·
8595af2
0
Parent(s):
Initial commit: Forked and cleaned from FLUX.2-Klein-LoRA-Studio
Browse files- .gitattributes +40 -0
- README.md +14 -0
- app.py +428 -0
- examples/1.jpg +3 -0
- examples/2.jpg +0 -0
- examples/C.jpg +3 -0
- examples/Snow-Klein-consistency.png +3 -0
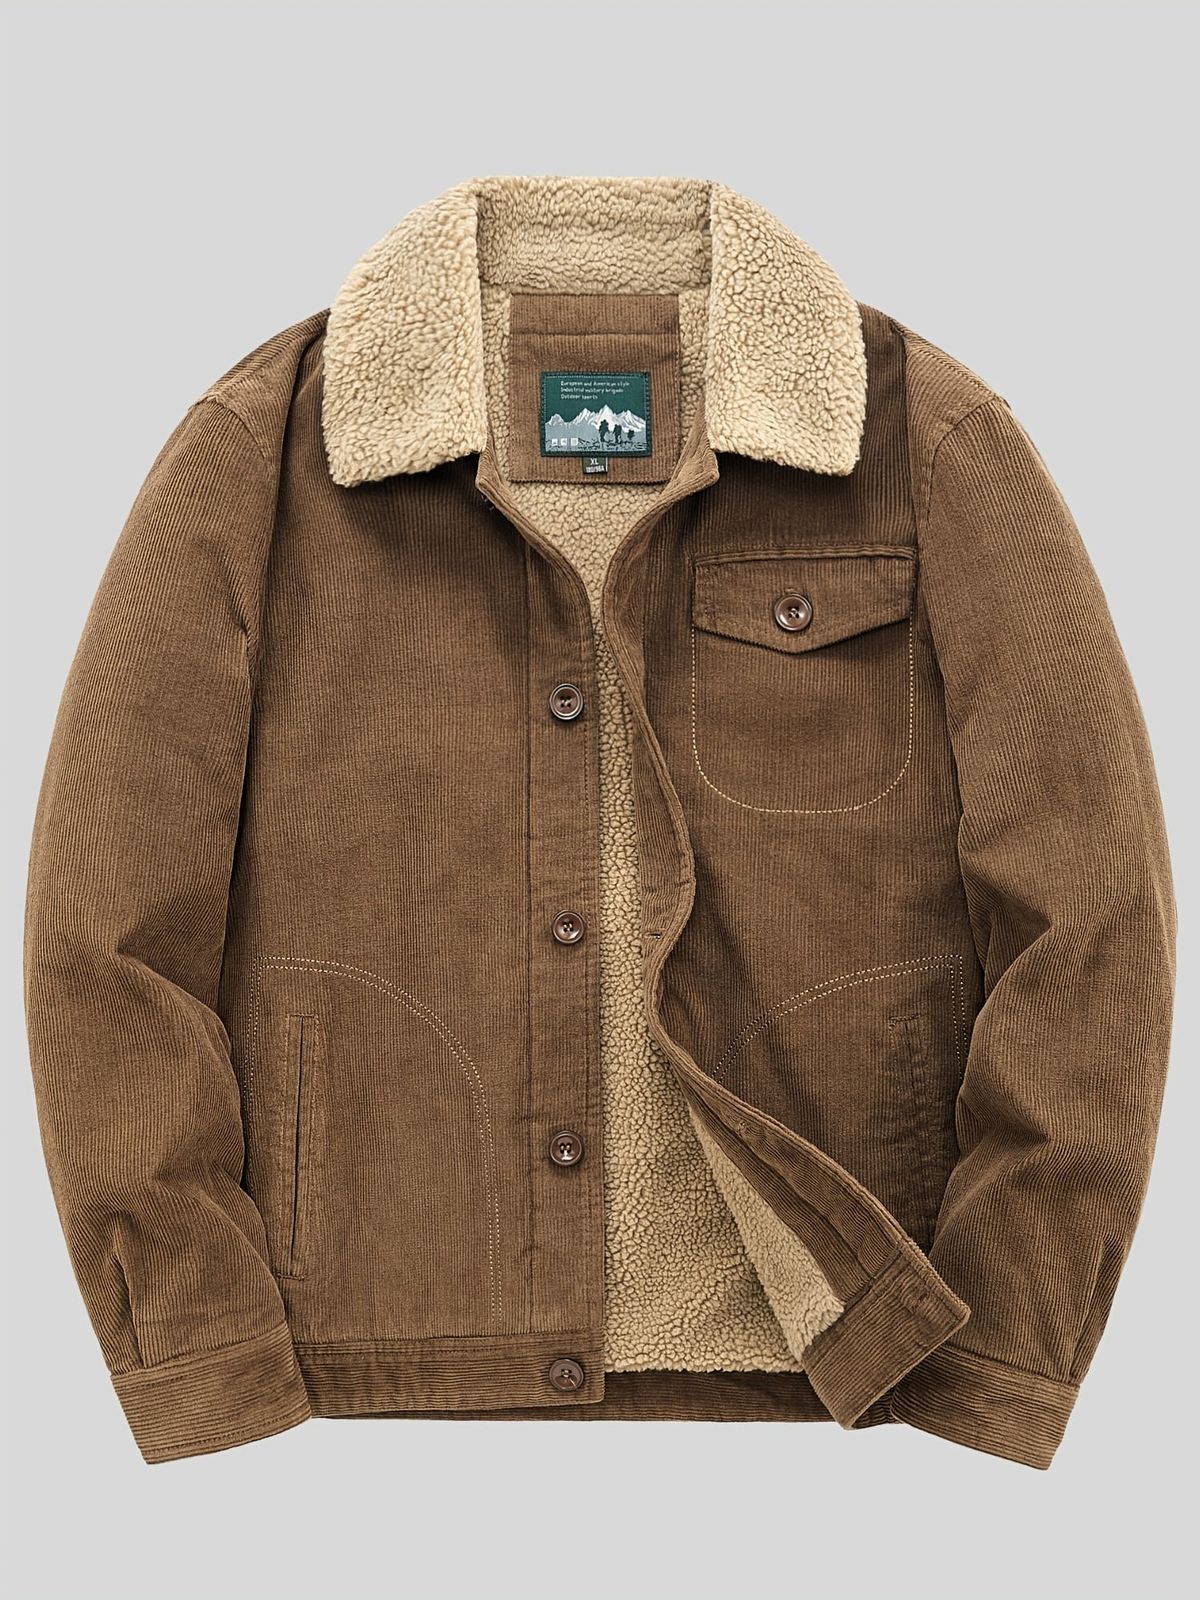
- examples/cloth.jpg +3 -0
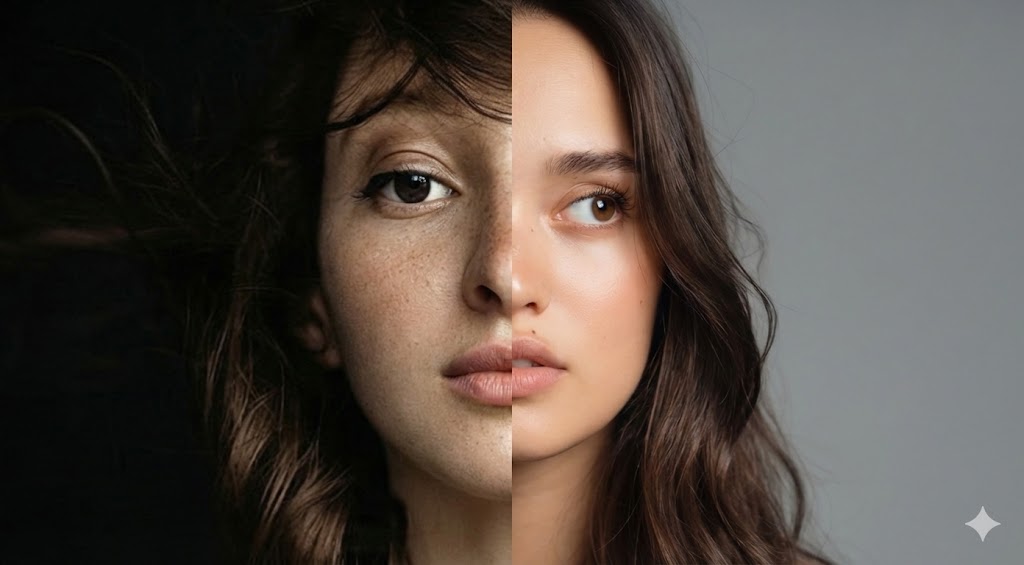
- examples/face-swap.jpg +0 -0
- examples/image.webp +0 -0
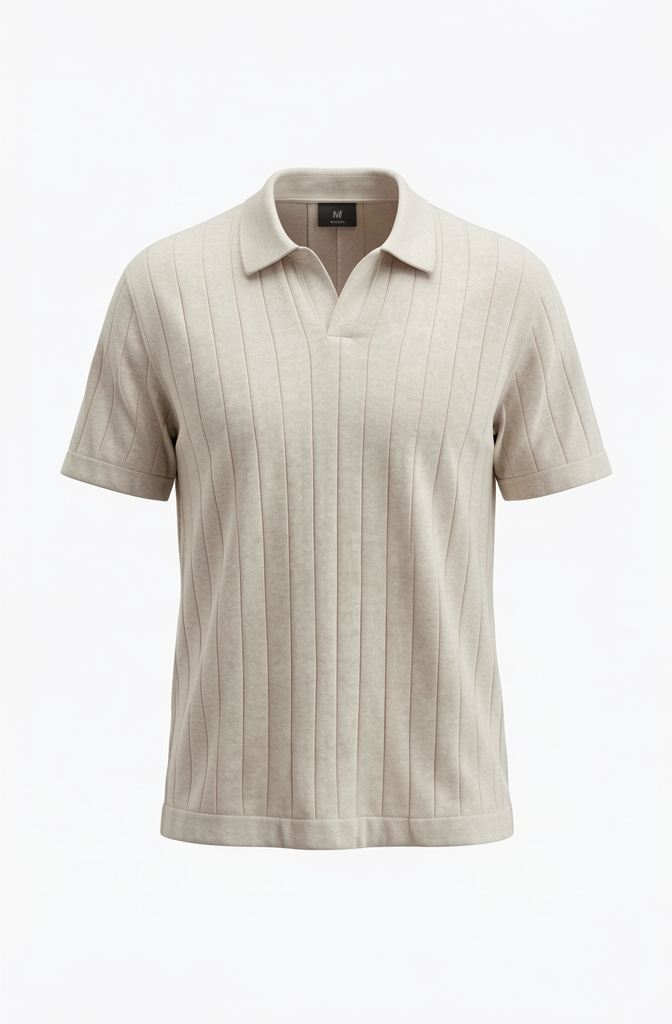
- examples/mc.png +3 -0
- optimization.py +271 -0
- requirements.txt +15 -0
.gitattributes
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
examples/1.jpg filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
examples/cloth.jpg filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
examples/mc.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
examples/Snow-Klein-consistency.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
examples/C.jpg filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,14 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
title: FLUX.2 Klein LoRA Studio
|
| 3 |
+
emoji: 🥚
|
| 4 |
+
colorFrom: indigo
|
| 5 |
+
colorTo: gray
|
| 6 |
+
sdk: gradio
|
| 7 |
+
sdk_version: 6.9.0
|
| 8 |
+
app_file: app.py
|
| 9 |
+
pinned: true
|
| 10 |
+
license: apache-2.0
|
| 11 |
+
short_description: Demo of a Collection of FLUX.2-Klein Model LoRAs
|
| 12 |
+
---
|
| 13 |
+
|
| 14 |
+
Check out the configuration reference at https://huggingface.co/docs/hub/spaces-config-reference
|
app.py
ADDED
|
@@ -0,0 +1,428 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import os
|
| 2 |
+
import gc
|
| 3 |
+
import gradio as gr
|
| 4 |
+
import numpy as np
|
| 5 |
+
import spaces
|
| 6 |
+
import torch
|
| 7 |
+
import random
|
| 8 |
+
from PIL import Image
|
| 9 |
+
from typing import Iterable
|
| 10 |
+
|
| 11 |
+
from diffusers import Flux2KleinPipeline
|
| 12 |
+
from diffusers.utils import load_image
|
| 13 |
+
from huggingface_hub import hf_hub_download
|
| 14 |
+
|
| 15 |
+
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
| 16 |
+
|
| 17 |
+
from gradio.themes import Soft
|
| 18 |
+
from gradio.themes.utils import colors, fonts, sizes
|
| 19 |
+
|
| 20 |
+
colors.orange_red = colors.Color(
|
| 21 |
+
name="orange_red", c50="#FFF0E5", c100="#FFE0CC", c200="#FFC299", c300="#FFA366",
|
| 22 |
+
c400="#FF8533", c500="#FF4500", c600="#E63E00", c700="#CC3700", c800="#B33000",
|
| 23 |
+
c900="#992900", c950="#802200",
|
| 24 |
+
)
|
| 25 |
+
|
| 26 |
+
class OrangeRedTheme(Soft):
|
| 27 |
+
def __init__(
|
| 28 |
+
self, *, primary_hue: colors.Color | str = colors.gray,
|
| 29 |
+
secondary_hue: colors.Color | str = colors.orange_red,
|
| 30 |
+
neutral_hue: colors.Color | str = colors.slate, text_size: sizes.Size | str = sizes.text_lg,
|
| 31 |
+
font: fonts.Font | str | Iterable[fonts.Font | str] = (
|
| 32 |
+
fonts.GoogleFont("Outfit"), "Arial", "sans-serif",
|
| 33 |
+
),
|
| 34 |
+
font_mono: fonts.Font | str | Iterable[fonts.Font | str] = (
|
| 35 |
+
fonts.GoogleFont("IBM Plex Mono"), "ui-monospace", "monospace",
|
| 36 |
+
),
|
| 37 |
+
):
|
| 38 |
+
super().__init__(
|
| 39 |
+
primary_hue=primary_hue, secondary_hue=secondary_hue, neutral_hue=neutral_hue,
|
| 40 |
+
text_size=text_size, font=font, font_mono=font_mono,
|
| 41 |
+
)
|
| 42 |
+
super().set(
|
| 43 |
+
background_fill_primary="*primary_50",
|
| 44 |
+
background_fill_primary_dark="*primary_900",
|
| 45 |
+
body_background_fill="linear-gradient(135deg, *primary_200, *primary_100)",
|
| 46 |
+
body_background_fill_dark="linear-gradient(135deg, *primary_900, *primary_800)",
|
| 47 |
+
button_primary_text_color="white",
|
| 48 |
+
button_primary_text_color_hover="white",
|
| 49 |
+
button_primary_background_fill="linear-gradient(90deg, *secondary_500, *secondary_600)",
|
| 50 |
+
button_primary_background_fill_hover="linear-gradient(90deg, *secondary_600, *secondary_700)",
|
| 51 |
+
button_primary_background_fill_dark="linear-gradient(90deg, *secondary_600, *secondary_700)",
|
| 52 |
+
button_primary_background_fill_hover_dark="linear-gradient(90deg, *secondary_500, *secondary_600)",
|
| 53 |
+
slider_color="*secondary_500",
|
| 54 |
+
slider_color_dark="*secondary_600",
|
| 55 |
+
block_title_text_weight="600", block_border_width="3px",
|
| 56 |
+
block_shadow="*shadow_drop_lg", button_primary_shadow="*shadow_drop_lg",
|
| 57 |
+
button_large_padding="11px", color_accent_soft="*primary_100",
|
| 58 |
+
block_label_background_fill="*primary_200",
|
| 59 |
+
)
|
| 60 |
+
|
| 61 |
+
orange_red_theme = OrangeRedTheme()
|
| 62 |
+
MAX_SEED = np.iinfo(np.int32).max
|
| 63 |
+
|
| 64 |
+
# Face Swap Prompt Template
|
| 65 |
+
FACE_SWAP_PROMPT = """head_swap: start with Picture 1 as the base image, keeping its lighting, environment, and background. Remove the head from Picture 1 completely and replace it with the head from Picture 2.
|
| 66 |
+
FROM PICTURE 1 (strictly preserve):
|
| 67 |
+
- Scene: lighting conditions, shadows, highlights, color temperature, environment, background
|
| 68 |
+
- Head positioning: exact rotation angle, tilt, direction the head is facing
|
| 69 |
+
- Expression: facial expression, micro-expressions, eye gaze direction, mouth position, emotion
|
| 70 |
+
FROM PICTURE 2 (strictly preserve identity):
|
| 71 |
+
- Facial structure: face shape, bone structure, jawline, chin
|
| 72 |
+
- All facial features: eye color, eye shape, nose structure, lip shape and fullness, eyebrows
|
| 73 |
+
- Hair: color, style, texture, hairline
|
| 74 |
+
- Skin: texture, tone, complexion
|
| 75 |
+
The replaced head must seamlessly match Picture 1's lighting and expression while maintaining the complete identity from Picture 2. High quality, photorealistic, sharp details, 4k."""
|
| 76 |
+
|
| 77 |
+
LORA_STYLES = [
|
| 78 |
+
{
|
| 79 |
+
"image": "https://huggingface.co/spaces/prithivMLmods/FLUX.2-Klein-LoRA-Studio/resolve/main/examples/image.webp",
|
| 80 |
+
"title": "None",
|
| 81 |
+
"adapter_name": None,
|
| 82 |
+
"repo": None,
|
| 83 |
+
"weights": None,
|
| 84 |
+
"default_prompt": None
|
| 85 |
+
},
|
| 86 |
+
{
|
| 87 |
+
"image": "https://huggingface.co/spaces/prithivMLmods/FLUX.2-Klein-LoRA-Studio/resolve/main/examples/Snow-Klein-consistency.png",
|
| 88 |
+
"title": "Klein-Consistency",
|
| 89 |
+
"adapter_name": "klein-consistency",
|
| 90 |
+
"repo": "dx8152/Flux2-Klein-9B-Consistency",
|
| 91 |
+
"weights": "Klein-consistency.safetensors",
|
| 92 |
+
"default_prompt": None
|
| 93 |
+
},
|
| 94 |
+
{
|
| 95 |
+
"image": "https://huggingface.co/linoyts/Flux2-Klein-Delight-LoRA/resolve/main/image_3.png",
|
| 96 |
+
"title": "Klein-Delight-Style",
|
| 97 |
+
"adapter_name": "klein-delight",
|
| 98 |
+
"repo": "linoyts/Flux2-Klein-Delight-LoRA",
|
| 99 |
+
"weights": "pytorch_lora_weights.safetensors",
|
| 100 |
+
"default_prompt": None
|
| 101 |
+
},
|
| 102 |
+
{
|
| 103 |
+
"image": "https://huggingface.co/spaces/prithivMLmods/FLUX.2-Klein-LoRA-Studio/resolve/main/examples/face-swap.jpg",
|
| 104 |
+
"title": "Best-Face-Swap",
|
| 105 |
+
"adapter_name": "face-swap",
|
| 106 |
+
"repo": "Alissonerdx/BFS-Best-Face-Swap",
|
| 107 |
+
"weights": "bfs_head_v1_flux-klein_9b_step3750_rank64.safetensors",
|
| 108 |
+
"default_prompt": FACE_SWAP_PROMPT
|
| 109 |
+
},
|
| 110 |
+
{
|
| 111 |
+
"image": "https://huggingface.co/spaces/prithivMLmods/FLUX.2-Klein-LoRA-Studio/resolve/main/examples/mc.png",
|
| 112 |
+
"title": "Ghost-Mannequin",
|
| 113 |
+
"adapter_name": "ghost-mannequin",
|
| 114 |
+
"repo": "nhathoangfoto/FLUX.2-klein-ghost-mannequin",
|
| 115 |
+
"weights": "3D-GhosMannequinRank-256_000005000.safetensors",
|
| 116 |
+
"default_prompt": None
|
| 117 |
+
},
|
| 118 |
+
]
|
| 119 |
+
|
| 120 |
+
LOADED_ADAPTERS = set()
|
| 121 |
+
|
| 122 |
+
print("Loading FLUX.2 Klein 9B model base...")
|
| 123 |
+
pipe = Flux2KleinPipeline.from_pretrained(
|
| 124 |
+
"black-forest-labs/FLUX.2-klein-9B",
|
| 125 |
+
torch_dtype=torch.bfloat16,
|
| 126 |
+
).to(device)
|
| 127 |
+
print("Base Model loaded successfully.")
|
| 128 |
+
|
| 129 |
+
def update_dimensions_on_upload(image):
|
| 130 |
+
"""Resizes image to be divisible by 16 to avoid tensor mismatch errors in FLUX."""
|
| 131 |
+
if image is None:
|
| 132 |
+
return 1024, 1024
|
| 133 |
+
|
| 134 |
+
original_width, original_height = image.size
|
| 135 |
+
|
| 136 |
+
scale = min(1024 / original_width, 1024 / original_height)
|
| 137 |
+
new_width = int(original_width * scale)
|
| 138 |
+
new_height = int(original_height * scale)
|
| 139 |
+
|
| 140 |
+
new_width = (new_width // 16) * 16
|
| 141 |
+
new_height = (new_height // 16) * 16
|
| 142 |
+
|
| 143 |
+
return new_width, new_height
|
| 144 |
+
|
| 145 |
+
def process_gallery_images(images):
|
| 146 |
+
"""Process images from gallery input and return list of PIL images."""
|
| 147 |
+
if not images:
|
| 148 |
+
return []
|
| 149 |
+
|
| 150 |
+
pil_images = []
|
| 151 |
+
for item in images:
|
| 152 |
+
try:
|
| 153 |
+
if isinstance(item, tuple) or isinstance(item, list):
|
| 154 |
+
path_or_img = item[0]
|
| 155 |
+
else:
|
| 156 |
+
path_or_img = item
|
| 157 |
+
|
| 158 |
+
if isinstance(path_or_img, str):
|
| 159 |
+
pil_images.append(Image.open(path_or_img).convert("RGB"))
|
| 160 |
+
elif isinstance(path_or_img, Image.Image):
|
| 161 |
+
pil_images.append(path_or_img.convert("RGB"))
|
| 162 |
+
else:
|
| 163 |
+
pil_images.append(Image.open(path_or_img.name).convert("RGB"))
|
| 164 |
+
except Exception as e:
|
| 165 |
+
print(f"Skipping invalid image item: {e}")
|
| 166 |
+
continue
|
| 167 |
+
|
| 168 |
+
return pil_images
|
| 169 |
+
|
| 170 |
+
def get_style_by_name(name):
|
| 171 |
+
"""Retrieve the style dictionary by its title."""
|
| 172 |
+
for style in LORA_STYLES:
|
| 173 |
+
if style["title"] == name:
|
| 174 |
+
return style
|
| 175 |
+
return LORA_STYLES[0] # Default to None
|
| 176 |
+
|
| 177 |
+
def update_style_selection(evt: gr.SelectData):
|
| 178 |
+
"""Update selected style based on gallery click."""
|
| 179 |
+
selected_style = LORA_STYLES[evt.index]
|
| 180 |
+
default_prompt = selected_style.get("default_prompt", None)
|
| 181 |
+
# Return the title string and optional prompt update
|
| 182 |
+
return selected_style["title"], default_prompt if default_prompt else gr.update()
|
| 183 |
+
|
| 184 |
+
def update_style_info(style_name):
|
| 185 |
+
"""Update the info text based on the selected style name."""
|
| 186 |
+
return f"### Selected: {style_name} ✅"
|
| 187 |
+
|
| 188 |
+
def get_image_count_info(images):
|
| 189 |
+
"""Return info about uploaded images"""
|
| 190 |
+
if not images:
|
| 191 |
+
return "📷 No images uploaded"
|
| 192 |
+
|
| 193 |
+
count = len(images)
|
| 194 |
+
if count == 1:
|
| 195 |
+
return "📷 1 image uploaded (Picture 1 - Base)"
|
| 196 |
+
elif count == 2:
|
| 197 |
+
return "📷 2 images uploaded (Picture 1 - Base, Picture 2 - Face Source)"
|
| 198 |
+
else:
|
| 199 |
+
return f"📷 {count} images uploaded"
|
| 200 |
+
|
| 201 |
+
@spaces.GPU
|
| 202 |
+
def infer(
|
| 203 |
+
input_images,
|
| 204 |
+
prompt,
|
| 205 |
+
style_name,
|
| 206 |
+
seed=42,
|
| 207 |
+
randomize_seed=True,
|
| 208 |
+
guidance_scale=1.0,
|
| 209 |
+
steps=4,
|
| 210 |
+
progress=gr.Progress(track_tqdm=True)
|
| 211 |
+
):
|
| 212 |
+
gc.collect()
|
| 213 |
+
torch.cuda.empty_cache()
|
| 214 |
+
|
| 215 |
+
if not input_images:
|
| 216 |
+
raise gr.Error("Please upload at least one image to apply a style to.")
|
| 217 |
+
|
| 218 |
+
# Process gallery images
|
| 219 |
+
pil_images = process_gallery_images(input_images)
|
| 220 |
+
|
| 221 |
+
if not pil_images:
|
| 222 |
+
raise gr.Error("Could not process uploaded images.")
|
| 223 |
+
|
| 224 |
+
# Find the selected style configuration
|
| 225 |
+
selected_style = get_style_by_name(style_name)
|
| 226 |
+
|
| 227 |
+
# Check if Face Swap is selected and validate image count
|
| 228 |
+
if selected_style["adapter_name"] == "face-swap":
|
| 229 |
+
if len(pil_images) < 2:
|
| 230 |
+
raise gr.Error("Face Swap requires exactly 2 images: Picture 1 (base/body) and Picture 2 (face source). Please upload 2 images.")
|
| 231 |
+
elif len(pil_images) > 2:
|
| 232 |
+
gr.Warning("Face Swap uses only the first 2 images. Additional images will be ignored.")
|
| 233 |
+
pil_images = pil_images[:2]
|
| 234 |
+
|
| 235 |
+
if selected_style["adapter_name"] is None:
|
| 236 |
+
print("Selection is None. Disabling LoRA adapters.")
|
| 237 |
+
pipe.disable_lora()
|
| 238 |
+
else:
|
| 239 |
+
adapter_name = selected_style["adapter_name"]
|
| 240 |
+
|
| 241 |
+
if adapter_name not in LOADED_ADAPTERS:
|
| 242 |
+
print(f"--- Downloading and Loading Adapter: {selected_style['title']} ---")
|
| 243 |
+
try:
|
| 244 |
+
pipe.load_lora_weights(
|
| 245 |
+
selected_style["repo"],
|
| 246 |
+
weight_name=selected_style["weights"],
|
| 247 |
+
adapter_name=adapter_name
|
| 248 |
+
)
|
| 249 |
+
LOADED_ADAPTERS.add(adapter_name)
|
| 250 |
+
except Exception as e:
|
| 251 |
+
raise gr.Error(f"Failed to load adapter {selected_style['title']}: {e}")
|
| 252 |
+
else:
|
| 253 |
+
print(f"--- Adapter {selected_style['title']} is already loaded. ---")
|
| 254 |
+
|
| 255 |
+
print(f"Activating LoRA: {adapter_name}")
|
| 256 |
+
pipe.set_adapters([adapter_name], adapter_weights=[1.0])
|
| 257 |
+
|
| 258 |
+
if randomize_seed:
|
| 259 |
+
seed = random.randint(0, MAX_SEED)
|
| 260 |
+
|
| 261 |
+
# Get dimensions from first image
|
| 262 |
+
width, height = update_dimensions_on_upload(pil_images[0])
|
| 263 |
+
|
| 264 |
+
# Process all images to the same dimensions
|
| 265 |
+
processed_images = [
|
| 266 |
+
img.resize((width, height), Image.LANCZOS).convert("RGB")
|
| 267 |
+
for img in pil_images
|
| 268 |
+
]
|
| 269 |
+
|
| 270 |
+
try:
|
| 271 |
+
# Pass single image or list based on count
|
| 272 |
+
image_input = processed_images if len(processed_images) > 1 else processed_images[0]
|
| 273 |
+
|
| 274 |
+
image = pipe(
|
| 275 |
+
image=image_input,
|
| 276 |
+
prompt=prompt,
|
| 277 |
+
guidance_scale=guidance_scale,
|
| 278 |
+
width=width,
|
| 279 |
+
height=height,
|
| 280 |
+
num_inference_steps=steps,
|
| 281 |
+
generator=torch.Generator(device=device).manual_seed(seed),
|
| 282 |
+
).images[0]
|
| 283 |
+
|
| 284 |
+
return image, seed
|
| 285 |
+
|
| 286 |
+
except Exception as e:
|
| 287 |
+
raise gr.Error(f"Inference failed: {e}")
|
| 288 |
+
finally:
|
| 289 |
+
gc.collect()
|
| 290 |
+
torch.cuda.empty_cache()
|
| 291 |
+
|
| 292 |
+
@spaces.GPU
|
| 293 |
+
def infer_example(input_images, prompt, style_name):
|
| 294 |
+
if not input_images:
|
| 295 |
+
return None, 0
|
| 296 |
+
|
| 297 |
+
# Handle examples where inputs might be paths
|
| 298 |
+
if isinstance(input_images, str):
|
| 299 |
+
input_images = [input_images]
|
| 300 |
+
|
| 301 |
+
image, seed = infer(
|
| 302 |
+
input_images=input_images,
|
| 303 |
+
prompt=prompt,
|
| 304 |
+
style_name=style_name,
|
| 305 |
+
seed=0,
|
| 306 |
+
randomize_seed=True,
|
| 307 |
+
guidance_scale=1.0,
|
| 308 |
+
steps=4
|
| 309 |
+
)
|
| 310 |
+
return image, seed
|
| 311 |
+
|
| 312 |
+
css = """
|
| 313 |
+
#col-container { margin: 0 auto; max-width: 960px; }
|
| 314 |
+
#main-title h1 { font-size: 2.4em !important; }
|
| 315 |
+
#style_gallery .grid-wrap { height: 10vh }
|
| 316 |
+
#input_gallery .grid-wrap { min-height: 200px }
|
| 317 |
+
"""
|
| 318 |
+
|
| 319 |
+
with gr.Blocks() as demo:
|
| 320 |
+
with gr.Column(elem_id="col-container"):
|
| 321 |
+
gr.Markdown("# **FLUX.2-Klein-LoRA-Studio**", elem_id="main-title")
|
| 322 |
+
gr.Markdown("Perform diverse image edits using specialized [LoRAs](https://huggingface.co/models?other=base_model:adapter:black-forest-labs/FLUX.2-klein-9B) adapters for the [FLUX.2-Klein-Distilled](https://huggingface.co/black-forest-labs/FLUX.2-klein-9B) model. Open on [GitHub](https://github.com/PRITHIVSAKTHIUR/FLUX.2-Klein-LoRA-Studio)")
|
| 323 |
+
|
| 324 |
+
selected_style_name = gr.Textbox(value="None", visible=False, label="Selected Style Name")
|
| 325 |
+
|
| 326 |
+
with gr.Row(equal_height=True):
|
| 327 |
+
with gr.Column():
|
| 328 |
+
input_images = gr.Gallery(
|
| 329 |
+
label="Upload Images",
|
| 330 |
+
type="filepath",
|
| 331 |
+
columns=2,
|
| 332 |
+
rows=1,
|
| 333 |
+
height=290,
|
| 334 |
+
allow_preview=True,
|
| 335 |
+
elem_id="input_gallery"
|
| 336 |
+
)
|
| 337 |
+
|
| 338 |
+
with gr.Row():
|
| 339 |
+
prompt = gr.Text(
|
| 340 |
+
label="Edit Prompt",
|
| 341 |
+
max_lines=1,
|
| 342 |
+
show_label=True,
|
| 343 |
+
placeholder="e.g., a man with a red superhero mask"
|
| 344 |
+
)
|
| 345 |
+
|
| 346 |
+
run_button = gr.Button("Apply Style", variant="primary")
|
| 347 |
+
|
| 348 |
+
with gr.Accordion("Advanced Settings", open=False, visible=False):
|
| 349 |
+
seed = gr.Slider(label="Seed", minimum=0, maximum=MAX_SEED, step=1, value=0)
|
| 350 |
+
randomize_seed = gr.Checkbox(label="Randomize seed", value=True)
|
| 351 |
+
guidance_scale = gr.Slider(label="Guidance Scale", minimum=0.0, maximum=10.0, step=0.1, value=1.0)
|
| 352 |
+
steps = gr.Slider(label="Steps", minimum=1, maximum=50, value=4, step=1)
|
| 353 |
+
|
| 354 |
+
with gr.Column():
|
| 355 |
+
output_image = gr.Image(label="Output Image", interactive=False, format="png", height=358)
|
| 356 |
+
used_seed = gr.Textbox(label="Used Seed", interactive=False, visible=False)
|
| 357 |
+
|
| 358 |
+
selected_style_info = gr.Markdown("### Selected: None (FLUX.2-klein-9B) ✅")
|
| 359 |
+
|
| 360 |
+
style_gallery = gr.Gallery(
|
| 361 |
+
[(item["image"], item["title"]) for item in LORA_STYLES],
|
| 362 |
+
label="Edit Style Gallery",
|
| 363 |
+
allow_preview=False,
|
| 364 |
+
columns=3,
|
| 365 |
+
elem_id="style_gallery",
|
| 366 |
+
)
|
| 367 |
+
|
| 368 |
+
gr.Examples(
|
| 369 |
+
examples=[
|
| 370 |
+
[
|
| 371 |
+
["examples/C.jpg"],
|
| 372 |
+
"Change the weather to stormy.",
|
| 373 |
+
"Klein-Consistency"
|
| 374 |
+
],
|
| 375 |
+
[
|
| 376 |
+
["examples/2.jpg"],
|
| 377 |
+
"Relight the image to remove all existing lighting conditions and replace them with neutral, uniform illumination. Apply soft, evenly distributed lighting with no directional shadows, no harsh highlights, and no dramatic contrast. Maintain the original identity of all subjects exactly—preserve facial structure, skin tone, proportions, expressions, hair, clothing, and textures. Do not alter pose, camera angle, background geometry, or image composition. Lighting should appear balanced, and studio-neutral, similar to diffuse overcast or a soft lightbox setup. Ensure consistent exposure across the entire image with realistic depth and subtle shading only where necessary for form.",
|
| 378 |
+
"Klein-Delight-Style"
|
| 379 |
+
],
|
| 380 |
+
[
|
| 381 |
+
["examples/1.jpg", "examples/2.jpg"],
|
| 382 |
+
FACE_SWAP_PROMPT,
|
| 383 |
+
"Best-Face-Swap"
|
| 384 |
+
],
|
| 385 |
+
[
|
| 386 |
+
["examples/1.jpg"],
|
| 387 |
+
"cinematic polaroid with soft grain subtle vignette gentle lighting white frame handwritten photographed by prithivMLmods preserving realistic texture and details",
|
| 388 |
+
"None"
|
| 389 |
+
],
|
| 390 |
+
[
|
| 391 |
+
["examples/cloth.jpg"],
|
| 392 |
+
"3Dghostmannequin",
|
| 393 |
+
"Ghost-Mannequin"
|
| 394 |
+
],
|
| 395 |
+
],
|
| 396 |
+
inputs=[input_images, prompt, selected_style_name],
|
| 397 |
+
outputs=[output_image, used_seed],
|
| 398 |
+
fn=infer_example,
|
| 399 |
+
cache_examples=False,
|
| 400 |
+
label="Examples"
|
| 401 |
+
)
|
| 402 |
+
|
| 403 |
+
gr.Markdown("[*](https://huggingface.co/black-forest-labs/FLUX.2-klein-9B)This is still an experimental Space for FLUX.2-Klein-9B. More adapters will be added soon.")
|
| 404 |
+
|
| 405 |
+
input_images.change(
|
| 406 |
+
fn=get_image_count_info,
|
| 407 |
+
inputs=[input_images],
|
| 408 |
+
)
|
| 409 |
+
|
| 410 |
+
style_gallery.select(
|
| 411 |
+
fn=update_style_selection,
|
| 412 |
+
outputs=[selected_style_name, prompt]
|
| 413 |
+
)
|
| 414 |
+
|
| 415 |
+
selected_style_name.change(
|
| 416 |
+
fn=update_style_info,
|
| 417 |
+
inputs=[selected_style_name],
|
| 418 |
+
outputs=[selected_style_info]
|
| 419 |
+
)
|
| 420 |
+
|
| 421 |
+
run_button.click(
|
| 422 |
+
fn=infer,
|
| 423 |
+
inputs=[input_images, prompt, selected_style_name, seed, randomize_seed, guidance_scale, steps],
|
| 424 |
+
outputs=[output_image, used_seed]
|
| 425 |
+
)
|
| 426 |
+
|
| 427 |
+
if __name__ == "__main__":
|
| 428 |
+
demo.queue().launch(css=css, theme=orange_red_theme, mcp_server=True, ssr_mode=False, show_error=True)
|
examples/1.jpg
ADDED
|
Git LFS Details
|
examples/2.jpg
ADDED
|
examples/C.jpg
ADDED
|
Git LFS Details
|
examples/Snow-Klein-consistency.png
ADDED
|
Git LFS Details
|
examples/cloth.jpg
ADDED
|
Git LFS Details
|
examples/face-swap.jpg
ADDED
|
examples/image.webp
ADDED
|
examples/mc.png
ADDED
|
Git LFS Details
|
optimization.py
ADDED
|
@@ -0,0 +1,271 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Hugging Face Spaces / ZeroGPU AoTI helper for Qwen image pipelines.
|
| 3 |
+
|
| 4 |
+
Usage:
|
| 5 |
+
from optimization_optimized import optimize_pipeline_
|
| 6 |
+
|
| 7 |
+
optimize_pipeline_(
|
| 8 |
+
pipe,
|
| 9 |
+
image=[Image.new("RGB", (1024, 1024)), Image.new("RGB", (1024, 1024))],
|
| 10 |
+
prompt="warmup prompt",
|
| 11 |
+
num_inference_steps=4,
|
| 12 |
+
true_cfg_scale=1.0,
|
| 13 |
+
height=1024,
|
| 14 |
+
width=1024,
|
| 15 |
+
)
|
| 16 |
+
|
| 17 |
+
Design goals:
|
| 18 |
+
- Keep the same in-place API as your original optimize_pipeline_.
|
| 19 |
+
- Avoid crashing the Space if AoTI export/compile fails.
|
| 20 |
+
- Only mark transformer dimensions as dynamic when the captured call actually contains them.
|
| 21 |
+
- Keep FP8 quantization optional, because it can change quality and may break export on some setups.
|
| 22 |
+
"""
|
| 23 |
+
|
| 24 |
+
from __future__ import annotations
|
| 25 |
+
|
| 26 |
+
import logging
|
| 27 |
+
from contextlib import nullcontext
|
| 28 |
+
from typing import Any, Callable, Mapping, Optional, ParamSpec
|
| 29 |
+
|
| 30 |
+
import torch
|
| 31 |
+
from torch.utils._pytree import tree_map
|
| 32 |
+
|
| 33 |
+
try:
|
| 34 |
+
import spaces
|
| 35 |
+
except Exception: # Local/dev environment without Hugging Face Spaces.
|
| 36 |
+
spaces = None # type: ignore[assignment]
|
| 37 |
+
|
| 38 |
+
try:
|
| 39 |
+
from torchao.quantization import Float8DynamicActivationFloat8WeightConfig, quantize_
|
| 40 |
+
except Exception:
|
| 41 |
+
Float8DynamicActivationFloat8WeightConfig = None # type: ignore[assignment]
|
| 42 |
+
quantize_ = None # type: ignore[assignment]
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
P = ParamSpec("P")
|
| 46 |
+
LOGGER = logging.getLogger(__name__)
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
# Qwen Image transformer forward usually has:
|
| 50 |
+
# hidden_states: [batch, image_seq, channels]
|
| 51 |
+
# encoder_hidden_states: [batch, text_seq, channels]
|
| 52 |
+
# encoder_hidden_states_mask: [batch, text_seq]
|
| 53 |
+
# image_rotary_emb: tuple(image_rotary_emb, text_rotary_emb)
|
| 54 |
+
TRANSFORMER_IMAGE_SEQ_LENGTH_DIM = torch.export.Dim("image_seq_length", min=1)
|
| 55 |
+
TRANSFORMER_TEXT_SEQ_LENGTH_DIM = torch.export.Dim("text_seq_length", min=1)
|
| 56 |
+
|
| 57 |
+
DEFAULT_TRANSFORMER_DYNAMIC_SHAPES: dict[str, Any] = {
|
| 58 |
+
"hidden_states": {1: TRANSFORMER_IMAGE_SEQ_LENGTH_DIM},
|
| 59 |
+
"encoder_hidden_states": {1: TRANSFORMER_TEXT_SEQ_LENGTH_DIM},
|
| 60 |
+
"encoder_hidden_states_mask": {1: TRANSFORMER_TEXT_SEQ_LENGTH_DIM},
|
| 61 |
+
"image_rotary_emb": (
|
| 62 |
+
{0: TRANSFORMER_IMAGE_SEQ_LENGTH_DIM},
|
| 63 |
+
{0: TRANSFORMER_TEXT_SEQ_LENGTH_DIM},
|
| 64 |
+
),
|
| 65 |
+
}
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
# Conservative-but-fast defaults for ZeroGPU/H200 AoTI.
|
| 69 |
+
# You can override any key through optimize_pipeline_(..., inductor_configs={...}).
|
| 70 |
+
DEFAULT_INDUCTOR_CONFIGS: dict[str, Any] = {
|
| 71 |
+
"conv_1x1_as_mm": True,
|
| 72 |
+
"epilogue_fusion": False,
|
| 73 |
+
"coordinate_descent_tuning": True,
|
| 74 |
+
"coordinate_descent_check_all_directions": True,
|
| 75 |
+
"max_autotune": True,
|
| 76 |
+
"triton.cudagraphs": True,
|
| 77 |
+
}
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
def _has_zero_gpu_aoti() -> bool:
|
| 81 |
+
return (
|
| 82 |
+
spaces is not None
|
| 83 |
+
and hasattr(spaces, "GPU")
|
| 84 |
+
and hasattr(spaces, "aoti_capture")
|
| 85 |
+
and hasattr(spaces, "aoti_compile")
|
| 86 |
+
and hasattr(spaces, "aoti_apply")
|
| 87 |
+
)
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
def _supports_float8() -> bool:
|
| 91 |
+
"""FP8 is mainly useful on Hopper-class GPUs such as H100/H200."""
|
| 92 |
+
if not torch.cuda.is_available():
|
| 93 |
+
return False
|
| 94 |
+
major, _minor = torch.cuda.get_device_capability()
|
| 95 |
+
return major >= 9
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
def _maybe_disable_progress_bar(pipeline: Callable[..., Any]) -> None:
|
| 99 |
+
"""Avoid tqdm/progress side effects during graph capture."""
|
| 100 |
+
setter = getattr(pipeline, "set_progress_bar_config", None)
|
| 101 |
+
if callable(setter):
|
| 102 |
+
try:
|
| 103 |
+
setter(disable=True)
|
| 104 |
+
except Exception:
|
| 105 |
+
pass
|
| 106 |
+
|
| 107 |
+
|
| 108 |
+
def _build_dynamic_shapes(
|
| 109 |
+
captured_kwargs: Mapping[str, Any],
|
| 110 |
+
shape_specs: Optional[Mapping[str, Any]] = None,
|
| 111 |
+
) -> dict[str, Any]:
|
| 112 |
+
"""
|
| 113 |
+
Build a dynamic_shapes dict matching the captured transformer kwargs.
|
| 114 |
+
|
| 115 |
+
torch.export expects the dynamic_shapes tree to mirror args/kwargs. The original
|
| 116 |
+
code unconditionally OR'ed every known Qwen key into the captured tree. This
|
| 117 |
+
version only injects a dynamic spec when that key is present in the actual
|
| 118 |
+
captured transformer call, which makes the helper more robust across Qwen /
|
| 119 |
+
Diffusers versions.
|
| 120 |
+
"""
|
| 121 |
+
dynamic_shapes = tree_map(lambda _leaf: None, dict(captured_kwargs))
|
| 122 |
+
specs = dict(shape_specs or DEFAULT_TRANSFORMER_DYNAMIC_SHAPES)
|
| 123 |
+
|
| 124 |
+
for name, spec in specs.items():
|
| 125 |
+
if name not in captured_kwargs:
|
| 126 |
+
continue
|
| 127 |
+
|
| 128 |
+
# image_rotary_emb is expected to be a pair. Skip if a future pipeline
|
| 129 |
+
# changes its structure instead of giving torch.export a mismatched tree.
|
| 130 |
+
if name == "image_rotary_emb":
|
| 131 |
+
value = captured_kwargs[name]
|
| 132 |
+
if not isinstance(value, (tuple, list)) or len(value) != 2:
|
| 133 |
+
LOGGER.warning(
|
| 134 |
+
"Skipping dynamic shape for image_rotary_emb: expected a 2-item tuple/list, got %s",
|
| 135 |
+
type(value).__name__,
|
| 136 |
+
)
|
| 137 |
+
continue
|
| 138 |
+
|
| 139 |
+
dynamic_shapes[name] = spec
|
| 140 |
+
|
| 141 |
+
return dynamic_shapes
|
| 142 |
+
|
| 143 |
+
|
| 144 |
+
def _maybe_quantize_transformer(transformer: torch.nn.Module, enable_float8: bool) -> None:
|
| 145 |
+
"""
|
| 146 |
+
Optional in-place FP8 quantization.
|
| 147 |
+
|
| 148 |
+
Keep disabled by default:
|
| 149 |
+
- It can affect image quality.
|
| 150 |
+
- It requires torchao.
|
| 151 |
+
- It is most beneficial on H100/H200-class GPUs.
|
| 152 |
+
- If export fails after quantization, the module has still been mutated.
|
| 153 |
+
"""
|
| 154 |
+
if not enable_float8:
|
| 155 |
+
return
|
| 156 |
+
|
| 157 |
+
if quantize_ is None or Float8DynamicActivationFloat8WeightConfig is None:
|
| 158 |
+
raise RuntimeError("enable_float8=True requires torchao to be installed.")
|
| 159 |
+
|
| 160 |
+
if not _supports_float8():
|
| 161 |
+
raise RuntimeError("enable_float8=True requires a Hopper-class CUDA GPU such as H100/H200.")
|
| 162 |
+
|
| 163 |
+
LOGGER.info("Applying experimental FP8 dynamic activation + FP8 weight quantization.")
|
| 164 |
+
quantize_(transformer, Float8DynamicActivationFloat8WeightConfig())
|
| 165 |
+
|
| 166 |
+
|
| 167 |
+
def optimize_pipeline_(
|
| 168 |
+
pipeline: Callable[P, Any],
|
| 169 |
+
*args: P.args,
|
| 170 |
+
duration: int = 1500,
|
| 171 |
+
inductor_configs: Optional[Mapping[str, Any]] = None,
|
| 172 |
+
dynamic_shape_specs: Optional[Mapping[str, Any]] = None,
|
| 173 |
+
enable_float8: bool = False,
|
| 174 |
+
strict_export: bool = False,
|
| 175 |
+
capture_autocast_dtype: Optional[torch.dtype] = None,
|
| 176 |
+
fail_silently: bool = True,
|
| 177 |
+
**kwargs: P.kwargs,
|
| 178 |
+
) -> Callable[P, Any]:
|
| 179 |
+
"""
|
| 180 |
+
Compile and apply AoTI to pipeline.transformer in-place.
|
| 181 |
+
|
| 182 |
+
Parameters:
|
| 183 |
+
pipeline:
|
| 184 |
+
Diffusers-style pipeline with a `.transformer` module.
|
| 185 |
+
*args, **kwargs:
|
| 186 |
+
Warmup call passed to the pipeline during AoTI capture.
|
| 187 |
+
Use representative image size, prompt length, step count, and guidance.
|
| 188 |
+
duration:
|
| 189 |
+
ZeroGPU allocation duration for compilation.
|
| 190 |
+
inductor_configs:
|
| 191 |
+
Optional overrides for DEFAULT_INDUCTOR_CONFIGS.
|
| 192 |
+
dynamic_shape_specs:
|
| 193 |
+
Optional overrides for dynamic-shape specs.
|
| 194 |
+
enable_float8:
|
| 195 |
+
Optional experimental torchao FP8 quantization before export.
|
| 196 |
+
strict_export:
|
| 197 |
+
Passed to torch.export.export(..., strict=...).
|
| 198 |
+
False is more permissive for complex model code.
|
| 199 |
+
capture_autocast_dtype:
|
| 200 |
+
Set to torch.bfloat16 or torch.float16 if your real inference path uses autocast.
|
| 201 |
+
Leave None when the pipeline/model is already loaded in the desired dtype.
|
| 202 |
+
fail_silently:
|
| 203 |
+
If True, log and keep the original transformer on compile failure.
|
| 204 |
+
If False, re-raise the error.
|
| 205 |
+
|
| 206 |
+
Returns:
|
| 207 |
+
The same pipeline object, mutated in-place if compile/apply succeeds.
|
| 208 |
+
"""
|
| 209 |
+
if not _has_zero_gpu_aoti():
|
| 210 |
+
LOGGER.warning("Hugging Face Spaces AoTI APIs are unavailable; skipping optimization.")
|
| 211 |
+
return pipeline
|
| 212 |
+
|
| 213 |
+
transformer = getattr(pipeline, "transformer", None)
|
| 214 |
+
if transformer is None:
|
| 215 |
+
message = "pipeline has no `.transformer` attribute; cannot apply transformer AoTI."
|
| 216 |
+
if fail_silently:
|
| 217 |
+
LOGGER.warning(message)
|
| 218 |
+
return pipeline
|
| 219 |
+
raise AttributeError(message)
|
| 220 |
+
|
| 221 |
+
if isinstance(transformer, torch.nn.Module):
|
| 222 |
+
transformer.eval()
|
| 223 |
+
|
| 224 |
+
_maybe_disable_progress_bar(pipeline)
|
| 225 |
+
|
| 226 |
+
configs = dict(DEFAULT_INDUCTOR_CONFIGS)
|
| 227 |
+
if inductor_configs:
|
| 228 |
+
configs.update(inductor_configs)
|
| 229 |
+
|
| 230 |
+
# Define inside optimize_pipeline_ so it closes over the actual pipeline and warmup args.
|
| 231 |
+
@spaces.GPU(duration=duration) # type: ignore[union-attr]
|
| 232 |
+
def compile_transformer():
|
| 233 |
+
LOGGER.info("Capturing transformer call for AoTI export.")
|
| 234 |
+
|
| 235 |
+
autocast_ctx = (
|
| 236 |
+
torch.autocast(device_type="cuda", dtype=capture_autocast_dtype)
|
| 237 |
+
if capture_autocast_dtype is not None and torch.cuda.is_available()
|
| 238 |
+
else nullcontext()
|
| 239 |
+
)
|
| 240 |
+
|
| 241 |
+
with torch.inference_mode(), autocast_ctx:
|
| 242 |
+
with spaces.aoti_capture(transformer) as call: # type: ignore[union-attr]
|
| 243 |
+
pipeline(*args, **kwargs)
|
| 244 |
+
|
| 245 |
+
dynamic_shapes = _build_dynamic_shapes(call.kwargs, dynamic_shape_specs)
|
| 246 |
+
|
| 247 |
+
_maybe_quantize_transformer(transformer, enable_float8)
|
| 248 |
+
|
| 249 |
+
LOGGER.info("Exporting transformer with torch.export; strict=%s", strict_export)
|
| 250 |
+
exported = torch.export.export(
|
| 251 |
+
mod=transformer,
|
| 252 |
+
args=call.args,
|
| 253 |
+
kwargs=call.kwargs,
|
| 254 |
+
dynamic_shapes=dynamic_shapes,
|
| 255 |
+
strict=strict_export,
|
| 256 |
+
)
|
| 257 |
+
|
| 258 |
+
LOGGER.info("Compiling exported transformer with AoTI.")
|
| 259 |
+
return spaces.aoti_compile(exported, configs) # type: ignore[union-attr]
|
| 260 |
+
|
| 261 |
+
try:
|
| 262 |
+
compiled_transformer = compile_transformer()
|
| 263 |
+
spaces.aoti_apply(compiled_transformer, transformer) # type: ignore[union-attr]
|
| 264 |
+
LOGGER.info("AoTI transformer optimization applied successfully.")
|
| 265 |
+
except Exception as exc:
|
| 266 |
+
LOGGER.exception("AoTI transformer optimization failed.")
|
| 267 |
+
if not fail_silently:
|
| 268 |
+
raise
|
| 269 |
+
LOGGER.warning("Continuing with the original uncompiled transformer. Error: %s", exc)
|
| 270 |
+
|
| 271 |
+
return pipeline
|
requirements.txt
ADDED
|
@@ -0,0 +1,15 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
git+https://github.com/huggingface/diffusers.git
|
| 2 |
+
transformers==4.57.6
|
| 3 |
+
huggingface_hub
|
| 4 |
+
sentencepiece
|
| 5 |
+
bitsandbytes
|
| 6 |
+
torchvision
|
| 7 |
+
accelerate
|
| 8 |
+
torchao
|
| 9 |
+
spaces
|
| 10 |
+
hf_xet
|
| 11 |
+
gradio
|
| 12 |
+
numpy
|
| 13 |
+
torch
|
| 14 |
+
peft
|
| 15 |
+
av
|