
Spaces:
Running on Zero

Running on Zero

v0.2.1: default LoRA -> v6_isg step-700 EMA r256, examples re-rendered
Browse files- NOTICE +1 -1
- README.md +13 -9
- app.py +11 -10
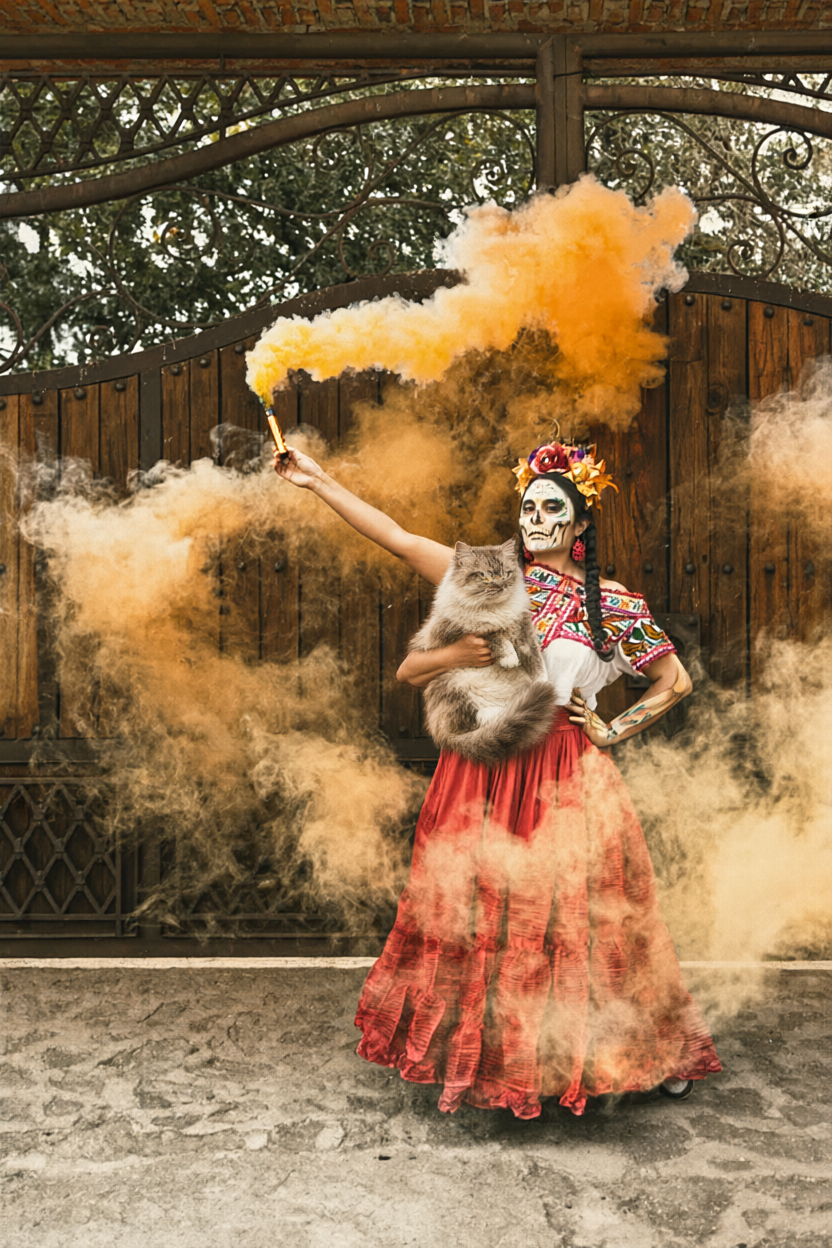
- examples/edit_2ref_cat.png +2 -2
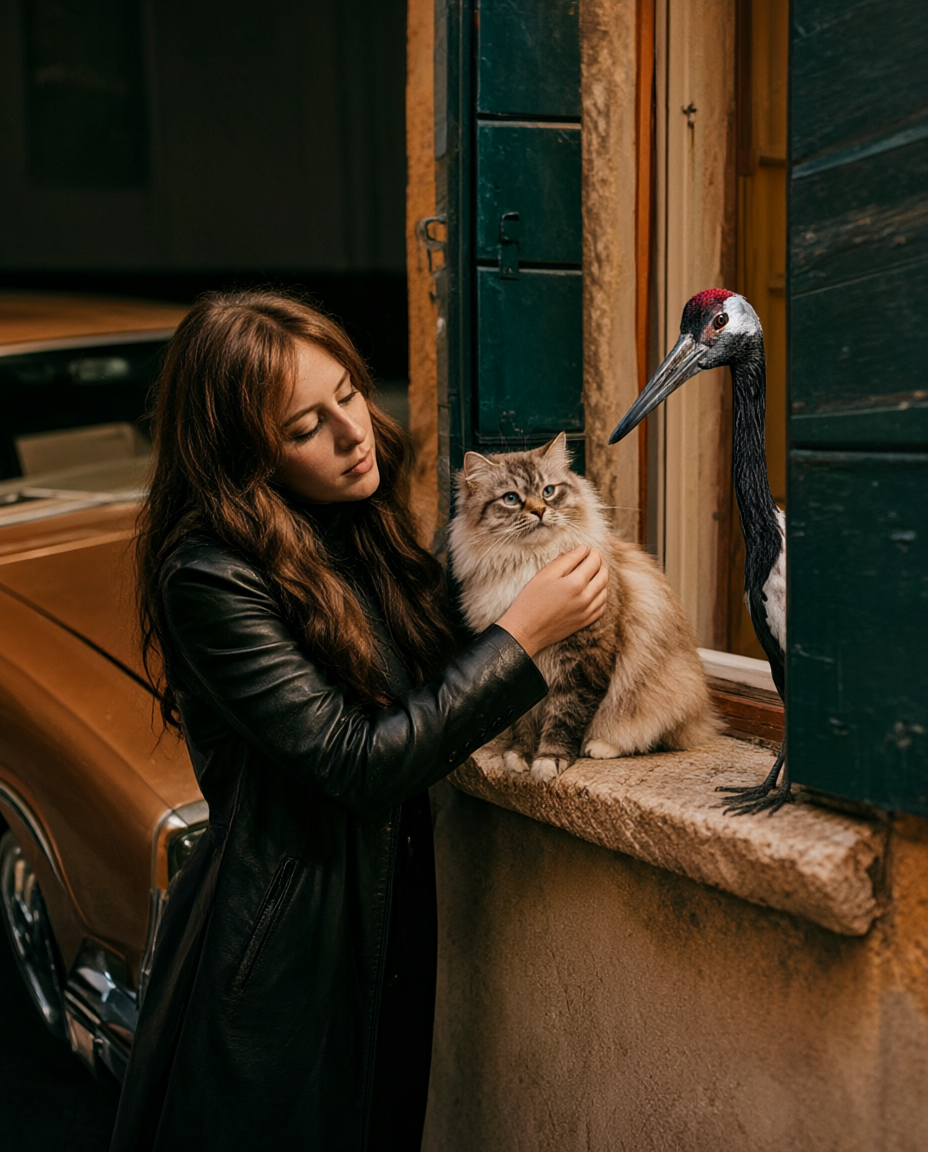
- examples/edit_3ref_klein.png +2 -2
- examples/edit_sketch.png +2 -2
- examples/manifest.json +6 -6
- examples/t2i_capybara.png +2 -2
- examples/t2i_diorama.png +2 -2
- examples/t2i_launch.png +2 -2
NOTICE
CHANGED
|
@@ -2,7 +2,7 @@ Qwen is licensed under the Qwen RESEARCH LICENSE AGREEMENT, Copyright (c) 2026 H
|
|
| 2 |
|
| 3 |
Built with Qwen.
|
| 4 |
|
| 5 |
-
This Space demonstrates Viggle/Qwen-Image-2.1-viggle-turbo, a DMD-distilled
|
| 6 |
derivative of Qwen/Qwen-Image-2.1. The base weights are downloaded at runtime from
|
| 7 |
Qwen/Qwen-Image-2.1 and are unmodified. Use is limited to non-commercial (research or
|
| 8 |
evaluation) purposes, per the Qwen RESEARCH LICENSE AGREEMENT included as LICENSE.
|
|
|
|
| 2 |
|
| 3 |
Built with Qwen.
|
| 4 |
|
| 5 |
+
This Space demonstrates Viggle/Qwen-Image-2.1-viggle-turbo, a DMD-distilled 6-step LoRA
|
| 6 |
derivative of Qwen/Qwen-Image-2.1. The base weights are downloaded at runtime from
|
| 7 |
Qwen/Qwen-Image-2.1 and are unmodified. Use is limited to non-commercial (research or
|
| 8 |
evaluation) purposes, per the Qwen RESEARCH LICENSE AGREEMENT included as LICENSE.
|
README.md
CHANGED
|
@@ -1,5 +1,5 @@
|
|
| 1 |
---
|
| 2 |
-
title: Viggle Turbo v0.2 - 6-step Qwen-Image-2.1
|
| 3 |
emoji: ⚡
|
| 4 |
colorFrom: indigo
|
| 5 |
colorTo: purple
|
|
@@ -11,7 +11,7 @@ pinned: false
|
|
| 11 |
license: other
|
| 12 |
license_name: qwen-research
|
| 13 |
license_link: ./LICENSE
|
| 14 |
-
short_description: v0.2 preview - 6-step Qwen-Image-2.1, T2I + editing
|
| 15 |
models:
|
| 16 |
- Viggle/Qwen-Image-2.1-viggle-turbo
|
| 17 |
- Qwen/Qwen-Image-2.1
|
|
@@ -28,7 +28,7 @@ tags:
|
|
| 28 |
# `hf_oauth` is not needed: the app calls no user-scoped Hub API.
|
| 29 |
---
|
| 30 |
|
| 31 |
-
# Viggle Turbo v0.2 (preview) — 6-step Qwen-Image-2.1
|
| 32 |
|
| 33 |
A DMD-distilled student of **Qwen-Image-2.1** that generates and edits images in **6 sampling steps**
|
| 34 |
with **no classifier-free guidance**, against the teacher's 40 steps.
|
|
@@ -40,7 +40,11 @@ for the numbers).
|
|
| 40 |
**2026-09-24: 6 steps instead of 5, same weights.** The extra step splits the highest-noise segment once more
|
| 41 |
(raw nodes `1, 0.9375, 0.875` instead of `1, 0.875`; the low-noise nodes are unchanged). Composition drift
|
| 42 |
against the base model goes from 4% of prompts to 0%, diversity from 0.93× to 0.97×, and the images are a
|
| 43 |
-
little sharper.
|
|
|
|
|
|
|
|
|
|
|
|
|
| 44 |
|
| 45 |
One model does both tasks, exactly as the base does: leave the reference slots empty for
|
| 46 |
text-to-image, or fill one to three of them for editing / composition / style transfer.
|
|
@@ -57,16 +61,16 @@ three-reference prompt come from the
|
|
| 57 |
|
| 58 |
**Built with Qwen.** Distilled from [Qwen/Qwen-Image-2.1](https://huggingface.co/Qwen/Qwen-Image-2.1).
|
| 59 |
|
| 60 |
-
> **Status: preview, work in progress.** v0.2 is a large step up from v0.1 but still falls short of the 40-step base
|
| 61 |
> model on complicated image editing (multi-reference composition, face swaps, identity-preserving edits, instructions
|
| 62 |
> with several constraints). We will keep updating this Space as the distillation improves.
|
| 63 |
|
| 64 |
## What the app loads
|
| 65 |
|
| 66 |
-
The Space runs the **v0.2 LoRA (rank 256)** by default, loaded at runtime on top of the base transformer with
|
| 67 |
`pipe.load_lora_weights(STUDENT_REPO, weight_name=LORA_FILE)` and never merged (merging into bf16 keeps only ~47 %
|
| 68 |
-
of the adapter delta). `LORA_FILE` defaults to `Qwen-Image-2.1-viggle-turbo-v0.2-
|
| 69 |
-
v0.
|
| 70 |
is still selectable with `STUDENT=full`:
|
| 71 |
|
| 72 |
```python
|
|
@@ -186,7 +190,7 @@ rewrite adds 2-8 s on a B200; `duration=90` covers both.
|
|
| 186 |
**Cold start** is dominated by the download: ~30.9 GiB of base safetensors from
|
| 187 |
`Qwen/Qwen-Image-2.1` (13.25 transformer + 16.33 text encoder + 1.26 VAE + 0.02 processor) plus
|
| 188 |
**1.3 GiB** for the LoRA — the shipped root adapter is bf16, and `load_lora_weights(weight_name=…)`
|
| 189 |
-
fetches that single file, not the F32 `peft_v0.2/` copy — then ~30–40 s to load and pack the pipeline
|
| 190 |
onto the GPU. Only the adapter changes
|
| 191 |
between releases, so a cached Space restarts far faster than it first boots.
|
| 192 |
|
|
|
|
| 1 |
---
|
| 2 |
+
title: Viggle Turbo v0.2.1 - 6-step Qwen-Image-2.1
|
| 3 |
emoji: ⚡
|
| 4 |
colorFrom: indigo
|
| 5 |
colorTo: purple
|
|
|
|
| 11 |
license: other
|
| 12 |
license_name: qwen-research
|
| 13 |
license_link: ./LICENSE
|
| 14 |
+
short_description: v0.2.1 preview - 6-step Qwen-Image-2.1, T2I + editing
|
| 15 |
models:
|
| 16 |
- Viggle/Qwen-Image-2.1-viggle-turbo
|
| 17 |
- Qwen/Qwen-Image-2.1
|
|
|
|
| 28 |
# `hf_oauth` is not needed: the app calls no user-scoped Hub API.
|
| 29 |
---
|
| 30 |
|
| 31 |
+
# Viggle Turbo v0.2.1 (preview) — 6-step Qwen-Image-2.1
|
| 32 |
|
| 33 |
A DMD-distilled student of **Qwen-Image-2.1** that generates and edits images in **6 sampling steps**
|
| 34 |
with **no classifier-free guidance**, against the teacher's 40 steps.
|
|
|
|
| 40 |
**2026-09-24: 6 steps instead of 5, same weights.** The extra step splits the highest-noise segment once more
|
| 41 |
(raw nodes `1, 0.9375, 0.875` instead of `1, 0.875`; the low-noise nodes are unchanged). Composition drift
|
| 42 |
against the base model goes from 4% of prompts to 0%, diversity from 0.93× to 0.97×, and the images are a
|
| 43 |
+
little sharper.
|
| 44 |
+
|
| 45 |
+
**v0.2.1 (2026-09-24):** the step-700 checkpoint of the same training run (v0.2 was step 600): a little
|
| 46 |
+
sharper and marginally more diverse (0.98× the base model), still 0% composition drift. The examples below are
|
| 47 |
+
rendered with it on the 6-step schedule.
|
| 48 |
|
| 49 |
One model does both tasks, exactly as the base does: leave the reference slots empty for
|
| 50 |
text-to-image, or fill one to three of them for editing / composition / style transfer.
|
|
|
|
| 61 |
|
| 62 |
**Built with Qwen.** Distilled from [Qwen/Qwen-Image-2.1](https://huggingface.co/Qwen/Qwen-Image-2.1).
|
| 63 |
|
| 64 |
+
> **Status: preview, work in progress.** v0.2.1 is a large step up from v0.1 but still falls short of the 40-step base
|
| 65 |
> model on complicated image editing (multi-reference composition, face swaps, identity-preserving edits, instructions
|
| 66 |
> with several constraints). We will keep updating this Space as the distillation improves.
|
| 67 |
|
| 68 |
## What the app loads
|
| 69 |
|
| 70 |
+
The Space runs the **v0.2.1 LoRA (rank 256)** by default, loaded at runtime on top of the base transformer with
|
| 71 |
`pipe.load_lora_weights(STUDENT_REPO, weight_name=LORA_FILE)` and never merged (merging into bf16 keeps only ~47 %
|
| 72 |
+
of the adapter delta). `LORA_FILE` defaults to `Qwen-Image-2.1-viggle-turbo-v0.2.1-6step-lora-r256.safetensors`; the
|
| 73 |
+
v0.2 and v0.1 adapters are still in the model repo and can be selected with it. The v0.1 **full fine-tuned transformer**
|
| 74 |
is still selectable with `STUDENT=full`:
|
| 75 |
|
| 76 |
```python
|
|
|
|
| 190 |
**Cold start** is dominated by the download: ~30.9 GiB of base safetensors from
|
| 191 |
`Qwen/Qwen-Image-2.1` (13.25 transformer + 16.33 text encoder + 1.26 VAE + 0.02 processor) plus
|
| 192 |
**1.3 GiB** for the LoRA — the shipped root adapter is bf16, and `load_lora_weights(weight_name=…)`
|
| 193 |
+
fetches that single file, not the F32 `peft_v0.2.1/` copy — then ~30–40 s to load and pack the pipeline
|
| 194 |
onto the GPU. Only the adapter changes
|
| 195 |
between releases, so a cached Space restarts far faster than it first boots.
|
| 196 |
|
app.py
CHANGED
|
@@ -1,4 +1,4 @@
|
|
| 1 |
-
"""Gradio demo for the DMD-distilled Qwen-Image-2.1 student (v0.2: LoRA r256 sampled in 6 steps; v0.1 students still selectable)."""
|
| 2 |
|
| 3 |
# ZeroGPU patches torch at import time, so `spaces` must be imported before torch or any CUDA use.
|
| 4 |
# find_spec keeps this file runnable off-Spaces, where the package is absent.
|
|
@@ -32,18 +32,18 @@ from PIL import Image
|
|
| 32 |
from diffusers import FlowMatchEulerDiscreteScheduler, QwenImage21Pipeline, QwenImage21Transformer2DModel
|
| 33 |
from diffusers.pipelines.qwenimage21.pipeline_qwenimage21 import calculate_dimensions
|
| 34 |
|
| 35 |
-
# Students in the model repo. STUDENT="lora" (default): the v0.2 LoRA (r256) at the repo root, applied at runtime on
|
| 36 |
# top of the base transformer and never merged (merging into bf16 keeps only ~47% of the adapter delta, the
|
| 37 |
-
# per-element deltas sit below the bf16 ULP of the base weights). LORA_FILE selects the adapter file; the v0.
|
| 38 |
-
#
|
| 39 |
# adapter) replaces the base transformer at load time - the base transformer is then not downloaded at all.
|
| 40 |
BASE_MODEL_ID = os.environ.get("BASE_MODEL_ID", "Qwen/Qwen-Image-2.1")
|
| 41 |
STUDENT_REPO = os.environ.get("STUDENT_REPO", os.environ.get("LORA_REPO", "Viggle/Qwen-Image-2.1-viggle-turbo"))
|
| 42 |
STUDENT = os.environ.get("STUDENT", "lora")
|
| 43 |
-
LORA_FILE = os.environ.get("LORA_FILE", "Qwen-Image-2.1-viggle-turbo-v0.2-
|
| 44 |
-
STUDENT_TAG = {"full": "v0.1 full fine-tune (transformer/)", "lora": "v0.2 LoRA r256" if "v0.2" in LORA_FILE else f"LoRA {LORA_FILE}"}[STUDENT]
|
| 45 |
HF_TOKEN = os.environ.get("HF_TOKEN") # only needed while the model repo is private
|
| 46 |
-
#
|
| 47 |
# linspace(1, 1/4, 4) with its highest-noise segment [1, 0.75] cut into three (1, 0.9375, 0.875, 0.75). The composition
|
| 48 |
# is decided in that segment, and one big Euler step there ghosts and drifts the layout; the low-noise nodes 0.75, 0.5,
|
| 49 |
# 0.25 are the ones the student was trained to land on, and moving them softens the image. So every extra step goes to the high-noise
|
|
@@ -216,9 +216,9 @@ def refresh_sizes(image_1, image_2, image_3, current):
|
|
| 216 |
return gr.update(choices=choices, value=current if current in choices else choices[0])
|
| 217 |
|
| 218 |
|
| 219 |
-
with gr.Blocks(title="Viggle Turbo v0.2 · Qwen-Image-2.1 6-step") as demo:
|
| 220 |
gr.Markdown(
|
| 221 |
-
"# Viggle Turbo v0.2 (preview) — 6-step Qwen-Image-2.1\n"
|
| 222 |
"A DMD-distilled student of **Qwen-Image-2.1** that generates and edits in **6 sampling steps**, "
|
| 223 |
"with no classifier-free guidance. Leave the reference images empty for text-to-image; "
|
| 224 |
"add one to three of them to edit, compose or transfer style. The size menu switches to the "
|
|
@@ -226,7 +226,8 @@ with gr.Blocks(title="Viggle Turbo v0.2 · Qwen-Image-2.1 6-step") as demo:
|
|
| 226 |
"**v0.2:** much better sample diversity than v0.1 (intra-prompt diversity 0.97× the 40-step base model, up from 0.75×) "
|
| 227 |
"and closer prompt adherence / composition to the base model. **2026-09-24:** same weights, now sampled on 6 steps "
|
| 228 |
"instead of 5 - the extra step splits the highest-noise segment again, which removes the last of the composition drift "
|
| 229 |
-
"(0% of prompts vs 4% at 5 steps) and lifts diversity from 0.93× to 0.97×.
|
|
|
|
| 230 |
"(multi-reference composition, face swaps, identity-preserving edits) remain weaker than the 40-step base model.\n\n"
|
| 231 |
f"Weights: **{STUDENT_TAG}** from "
|
| 232 |
f"[{STUDENT_REPO}](https://huggingface.co/{STUDENT_REPO})."
|
|
|
|
| 1 |
+
"""Gradio demo for the DMD-distilled Qwen-Image-2.1 student (v0.2.1: LoRA r256 sampled in 6 steps; v0.2 / v0.1 students still selectable)."""
|
| 2 |
|
| 3 |
# ZeroGPU patches torch at import time, so `spaces` must be imported before torch or any CUDA use.
|
| 4 |
# find_spec keeps this file runnable off-Spaces, where the package is absent.
|
|
|
|
| 32 |
from diffusers import FlowMatchEulerDiscreteScheduler, QwenImage21Pipeline, QwenImage21Transformer2DModel
|
| 33 |
from diffusers.pipelines.qwenimage21.pipeline_qwenimage21 import calculate_dimensions
|
| 34 |
|
| 35 |
+
# Students in the model repo. STUDENT="lora" (default): the v0.2.1 LoRA (r256) at the repo root, applied at runtime on
|
| 36 |
# top of the base transformer and never merged (merging into bf16 keeps only ~47% of the adapter delta, the
|
| 37 |
+
# per-element deltas sit below the bf16 ULP of the base weights). LORA_FILE selects the adapter file; the v0.2 and
|
| 38 |
+
# v0.1 adapters are still in the repo. STUDENT="full": the v0.1 full fine-tune in transformer/ (bf16, exact, no
|
| 39 |
# adapter) replaces the base transformer at load time - the base transformer is then not downloaded at all.
|
| 40 |
BASE_MODEL_ID = os.environ.get("BASE_MODEL_ID", "Qwen/Qwen-Image-2.1")
|
| 41 |
STUDENT_REPO = os.environ.get("STUDENT_REPO", os.environ.get("LORA_REPO", "Viggle/Qwen-Image-2.1-viggle-turbo"))
|
| 42 |
STUDENT = os.environ.get("STUDENT", "lora")
|
| 43 |
+
LORA_FILE = os.environ.get("LORA_FILE", "Qwen-Image-2.1-viggle-turbo-v0.2.1-6step-lora-r256.safetensors")
|
| 44 |
+
STUDENT_TAG = {"full": "v0.1 full fine-tune (transformer/)", "lora": "v0.2.1 LoRA r256" if "v0.2.1" in LORA_FILE else f"LoRA {LORA_FILE}"}[STUDENT]
|
| 45 |
HF_TOKEN = os.environ.get("HF_TOKEN") # only needed while the model repo is private
|
| 46 |
+
# The LoRA is sampled on 6 Euler steps whose raw (pre-shift) sigma nodes are RAW_NODES: the 4-step training schedule
|
| 47 |
# linspace(1, 1/4, 4) with its highest-noise segment [1, 0.75] cut into three (1, 0.9375, 0.875, 0.75). The composition
|
| 48 |
# is decided in that segment, and one big Euler step there ghosts and drifts the layout; the low-noise nodes 0.75, 0.5,
|
| 49 |
# 0.25 are the ones the student was trained to land on, and moving them softens the image. So every extra step goes to the high-noise
|
|
|
|
| 216 |
return gr.update(choices=choices, value=current if current in choices else choices[0])
|
| 217 |
|
| 218 |
|
| 219 |
+
with gr.Blocks(title="Viggle Turbo v0.2.1 · Qwen-Image-2.1 6-step") as demo:
|
| 220 |
gr.Markdown(
|
| 221 |
+
"# Viggle Turbo v0.2.1 (preview) — 6-step Qwen-Image-2.1\n"
|
| 222 |
"A DMD-distilled student of **Qwen-Image-2.1** that generates and edits in **6 sampling steps**, "
|
| 223 |
"with no classifier-free guidance. Leave the reference images empty for text-to-image; "
|
| 224 |
"add one to three of them to edit, compose or transfer style. The size menu switches to the "
|
|
|
|
| 226 |
"**v0.2:** much better sample diversity than v0.1 (intra-prompt diversity 0.97× the 40-step base model, up from 0.75×) "
|
| 227 |
"and closer prompt adherence / composition to the base model. **2026-09-24:** same weights, now sampled on 6 steps "
|
| 228 |
"instead of 5 - the extra step splits the highest-noise segment again, which removes the last of the composition drift "
|
| 229 |
+
"(0% of prompts vs 4% at 5 steps) and lifts diversity from 0.93× to 0.97×. **v0.2.1 (2026-09-24):** the step-700 "
|
| 230 |
+
"checkpoint of the same run (v0.2 was step 600) - a little sharper, diversity 0.98×, still 0% drift. Still a preview: complicated edits "
|
| 231 |
"(multi-reference composition, face swaps, identity-preserving edits) remain weaker than the 40-step base model.\n\n"
|
| 232 |
f"Weights: **{STUDENT_TAG}** from "
|
| 233 |
f"[{STUDENT_REPO}](https://huggingface.co/{STUDENT_REPO})."
|
examples/edit_2ref_cat.png
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
examples/edit_3ref_klein.png
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
examples/edit_sketch.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
examples/manifest.json
CHANGED
|
@@ -7,7 +7,7 @@
|
|
| 7 |
"bird.webp"
|
| 8 |
],
|
| 9 |
"result": "edit_3ref_klein.png",
|
| 10 |
-
"info": "Pre-rendered example · seed `42` · 928×1152 · 6 steps · v0.2 LoRA r256 · prompt enhanced",
|
| 11 |
"used_prompt": "Compose a scene where the person from <image1>, standing beside the vintage brown car, is gently petting the fluffy cat from <image2> that is perched on a stone windowsill with green shutters, while the bird from <image3>, with a red crown and long beak, stands next to them, all under warm cinematic lighting with a shallow depth of field focusing on the trio, keeping the background and subjects' identities from the input images unchanged.",
|
| 12 |
"steps": 6,
|
| 13 |
"size_label": "Auto · match the last reference (1024² area)",
|
|
@@ -21,7 +21,7 @@
|
|
| 21 |
null
|
| 22 |
],
|
| 23 |
"result": "t2i_launch.png",
|
| 24 |
-
"info": "Pre-rendered example · seed `3` · 2496×1664 · 8 steps · v0.2 LoRA r256 · prompt sent as written (enhancement off)",
|
| 25 |
"used_prompt": "Create a premium, minimalist launch graphic for an AI image model, designed for a Twitter/X announcement.\n\nAspect ratio: 16:9.\nStyle: elegant, high-end, modern AI product launch visual. Clean Apple / NVIDIA / premium creative-software aesthetic. Dark, cinematic, sophisticated, not flashy or cluttered.\n\nBACKGROUND\n- Deep black to charcoal gradient background.\n- Very subtle blue and violet ambient glow.\n- Soft cinematic lighting, slight glossy reflections near the bottom.\n- Large areas of negative space.\n- No unnecessary particles, grids, icons, decorative UI, or busy textures.\n\nTOP-LEFT TYPOGRAPHY\n\nMain title:\n“Qwen-Image-2.1 ❤️ Viggle Turbo”\n\n- Large bold geometric sans-serif.\n- Clean Swiss-style typography.\n- Bright soft-white text.\n- Red heart between the two model names.\n- Precise kerning and professional spacing.\n- Keep the title on one line.\n- Position around 4–5% from the left and 8–10% from the top.\n\nDirectly underneath, smaller subtitle:\n“DMD-distilled · Generate & Edit”\n\n- Thin or regular sans-serif.\n- Around 30–35% of the main title font size.\n- Soft light-gray / off-white.\n- Generous letter spacing.\n- Minimal and understated.\n\nCENTER HERO MESSAGE\n\nLarge dominant typography:\n\n“6-step”\n“generation”\n\non two lines.\n\n- “6-step” should be extremely large.\n- “generation” slightly smaller but still bold.\n- Heavy geometric sans-serif.\n- White / very subtle cool-white gradient.\n- Tight line spacing.\n- Perfectly clean typography.\n- Position slightly above the vertical center.\n- The text should be the strongest visual element in the design.\n- No exaggerated 3D text, extrusion, chrome effects, or heavy shadows.\n- Only a very subtle soft glow.\n\nVISUAL ELEMENT\n\nCreate a single elegant curved ribbon of generated images flowing across the lower half of the composition.\n\nThe ribbon should:\n- Start from the lower-left foreground.\n- Curve smoothly toward the center-right.\n- Continue upward toward the upper-right background.\n- Feel like a sophisticated cinematic film strip or flowing image-generation sequence.\n- Use approximately 5–7 image panels only.\n- Avoid a dense collage.\n\nEach panel:\n- Rounded rectangle.\n- Thin subtle border.\n- Premium glossy display appearance.\n- Slight perspective distortion following the curve.\n- Gradually decrease in size toward the background.\n- Use realistic generated landscape photography:\n • alpine lake\n • mountain valley\n • waterfall\n • dramatic mountain peaks\n • coastal sunset\n- Rich but natural colors.\n- Foreground panels sharp, distant panels progressively softer / slightly blurred.\n- Strong depth-of-field.\n\nThe ribbon itself should have an extremely subtle luminous edge:\n- cyan / electric blue on the left\n- transitioning gently toward violet / magenta on the right\n\nKeep the glow restrained and premium.\nDo not make it look like cyberpunk neon.\n\nLIGHTING\n\nAdd one very thin horizontal blue-to-violet light flare passing subtly behind the “6-step” text.\n\nUse soft reflected blue/violet light underneath the image ribbon.\n\nLighting should feel cinematic and expensive, not game-like.\n\nBOTTOM-RIGHT\n\nSmall footer:\n“Generate with viggle-turbo”\n\n- Small clean sans-serif.\n- White / light gray.\n- Bottom-right aligned.\n- Approximately 5% from the right and 6–8% from the bottom.\n- Lots of breathing room.\n- Do not make it prominent.\n\nOVERALL COMPOSITION\n\nThe visual hierarchy should clearly be:\n\n1. “6-step generation”\n2. “Qwen-Image-2.1 ❤️ Viggle Turbo”\n3. flowing generated-image ribbon\n4. “DMD-distilled · Generate & Edit”\n5. small “Generate with viggle-turbo.” footer\n\nThe graphic should immediately communicate:\nfast generation, image generation, premium AI model, six-step inference.\n\nOverall aesthetic:\nminimal, elegant, expensive, technically sophisticated, cinematic, polished, restrained, premium AI launch campaign.\n\nAvoid:\n- excessive neon\n- cyberpunk look\n- too many thumbnails\n- busy collage layouts\n- random icons\n- fake UI elements\n- gradients inside every object\n- excessive lens flares\n- heavy shadows\n- 3D metallic typography\n- cartoon imagery\n- excessive text\n- logos other than the specified text\n- watermark\n- spelling errors\n- distorted letters\n- duplicated text",
|
| 26 |
"steps": 8,
|
| 27 |
"size_label": "3:2 · 2496×1664 (2048² area)",
|
|
@@ -35,7 +35,7 @@
|
|
| 35 |
null
|
| 36 |
],
|
| 37 |
"result": "t2i_capybara.png",
|
| 38 |
-
"info": "Pre-rendered example · seed `0` · 1248×832 · 6 steps · v0.2 LoRA r256 · prompt enhanced",
|
| 39 |
"used_prompt": "The image is a close-up realistic photograph of a soaking wet capybara taking shelter under a large banana leaf in a rainy jungle, the background a lush green canopy dappled with falling raindrops and misty humidity. In the upper-left corner, the edge of the banana leaf curves downward, its broad surface glistening with rainwater and casting a soft shadow over the capybara’s back. Across the top third, rain streaks blur the dense foliage behind, with shafts of diffused light filtering through the canopy. In the center of the frame, the capybara’s rounded body is pressed against the leaf’s underside, its fur matted and dark with water, clinging to its skin in clumps; its small ears are flattened against its head, and its eyes are half-closed, glistening with moisture. On the right side, a second banana leaf peeks into the frame, its veins visible and slightly curled at the edges, partially obscuring the background. Behind the capybara’s left shoulder, a cluster of broad, wet leaves hangs low, their edges blurred by the shallow depth of field. Along the lower edge, the ground is a muddy brown, slick with rainwater and scattered with fallen leaves and twigs, reflecting the dim light. The lighting is soft, diffused daylight filtered through the jungle canopy, casting gentle highlights on the capybara’s wet fur and the water droplets clinging to the banana leaf, with faint shadows beneath the animal and along the leaf’s underside. The overall composition feels intimate and sheltered, emphasizing the capybara’s vulnerability and the quiet resilience of nature in the downpour.",
|
| 40 |
"steps": 6,
|
| 41 |
"size_label": "3:2 · 1248×832 (1024² area)",
|
|
@@ -49,7 +49,7 @@
|
|
| 49 |
null
|
| 50 |
],
|
| 51 |
"result": "t2i_diorama.png",
|
| 52 |
-
"info": "Pre-rendered example · seed `0` · 2368×1760 · 6 steps · v0.2 LoRA r256 · prompt enhanced",
|
| 53 |
"used_prompt": "The image is a 4:3 isometric miniature diorama of a mountain research station, rendered in high detail with soft studio lighting and a tilt-shift effect. The scene is set on a rugged, snow-dusted mountain slope, with the research station occupying the central foreground, its modular buildings and domed observatory nestled into the terrain. To the left, a steep incline rises into a misty valley, while the right side features a rocky outcrop with a small antenna array. Behind the station, a jagged mountain ridge stretches across the background under a pale blue sky with soft, diffused clouds. The station’s structures are detailed with weathered metal siding, glass windows reflecting the ambient light, and exposed piping and cables. A small helipad with a landing pad marker is visible in the lower-left corner, and a narrow service road winds up the slope toward the main entrance. The lighting is soft and even, emanating from an unseen source above and slightly to the left, casting gentle shadows that emphasize the three-dimensional depth of the diorama. The overall composition feels immersive and meticulously crafted, with a balanced arrangement of architectural elements and natural terrain, evoking a sense of isolation and scientific exploration in a remote alpine environment.",
|
| 54 |
"steps": 6,
|
| 55 |
"size_label": "4:3 · 2368×1760 (2048² area)",
|
|
@@ -63,7 +63,7 @@
|
|
| 63 |
null
|
| 64 |
],
|
| 65 |
"result": "edit_sketch.png",
|
| 66 |
-
"info": "Pre-rendered example · seed `3` · 1024×1024 · 6 steps · v0.2 LoRA r256 · prompt enhanced",
|
| 67 |
"used_prompt": "Convert the image to a pencil sketch on textured paper, preserving the exact composition, framing, and spatial arrangement of all elements including the rain-streaked window, the interior bookstore shelves, the figure inside, and the \"OPEN LATE\" sign in the foreground, while rendering the entire scene in a hand-drawn, sketchy style with visible pencil strokes and paper texture.",
|
| 68 |
"steps": 6,
|
| 69 |
"size_label": "Auto · match the last reference (1024² area)",
|
|
@@ -77,7 +77,7 @@
|
|
| 77 |
null
|
| 78 |
],
|
| 79 |
"result": "edit_2ref_cat.png",
|
| 80 |
-
"info": "Pre-rendered example · seed `42` · 832×1248 · 6 steps · v0.2 LoRA r256 · prompt enhanced",
|
| 81 |
"used_prompt": "Compose a new image where the woman from <image1>, wearing her full traditional outfit with skull makeup and holding a smoke bomb, is now holding the fluffy cat from <image2> in her arms, positioned in the same spot as in the original image, with the ornate wooden gate and surrounding smoke from <image1> remaining unchanged as the background.",
|
| 82 |
"steps": 6,
|
| 83 |
"size_label": "Auto · match the last reference (1024² area)",
|
|
|
|
| 7 |
"bird.webp"
|
| 8 |
],
|
| 9 |
"result": "edit_3ref_klein.png",
|
| 10 |
+
"info": "Pre-rendered example · seed `42` · 928×1152 · 6 steps · v0.2.1 LoRA r256 · prompt enhanced",
|
| 11 |
"used_prompt": "Compose a scene where the person from <image1>, standing beside the vintage brown car, is gently petting the fluffy cat from <image2> that is perched on a stone windowsill with green shutters, while the bird from <image3>, with a red crown and long beak, stands next to them, all under warm cinematic lighting with a shallow depth of field focusing on the trio, keeping the background and subjects' identities from the input images unchanged.",
|
| 12 |
"steps": 6,
|
| 13 |
"size_label": "Auto · match the last reference (1024² area)",
|
|
|
|
| 21 |
null
|
| 22 |
],
|
| 23 |
"result": "t2i_launch.png",
|
| 24 |
+
"info": "Pre-rendered example · seed `3` · 2496×1664 · 8 steps · v0.2.1 LoRA r256 · prompt sent as written (enhancement off)",
|
| 25 |
"used_prompt": "Create a premium, minimalist launch graphic for an AI image model, designed for a Twitter/X announcement.\n\nAspect ratio: 16:9.\nStyle: elegant, high-end, modern AI product launch visual. Clean Apple / NVIDIA / premium creative-software aesthetic. Dark, cinematic, sophisticated, not flashy or cluttered.\n\nBACKGROUND\n- Deep black to charcoal gradient background.\n- Very subtle blue and violet ambient glow.\n- Soft cinematic lighting, slight glossy reflections near the bottom.\n- Large areas of negative space.\n- No unnecessary particles, grids, icons, decorative UI, or busy textures.\n\nTOP-LEFT TYPOGRAPHY\n\nMain title:\n“Qwen-Image-2.1 ❤️ Viggle Turbo”\n\n- Large bold geometric sans-serif.\n- Clean Swiss-style typography.\n- Bright soft-white text.\n- Red heart between the two model names.\n- Precise kerning and professional spacing.\n- Keep the title on one line.\n- Position around 4–5% from the left and 8–10% from the top.\n\nDirectly underneath, smaller subtitle:\n“DMD-distilled · Generate & Edit”\n\n- Thin or regular sans-serif.\n- Around 30–35% of the main title font size.\n- Soft light-gray / off-white.\n- Generous letter spacing.\n- Minimal and understated.\n\nCENTER HERO MESSAGE\n\nLarge dominant typography:\n\n“6-step”\n“generation”\n\non two lines.\n\n- “6-step” should be extremely large.\n- “generation” slightly smaller but still bold.\n- Heavy geometric sans-serif.\n- White / very subtle cool-white gradient.\n- Tight line spacing.\n- Perfectly clean typography.\n- Position slightly above the vertical center.\n- The text should be the strongest visual element in the design.\n- No exaggerated 3D text, extrusion, chrome effects, or heavy shadows.\n- Only a very subtle soft glow.\n\nVISUAL ELEMENT\n\nCreate a single elegant curved ribbon of generated images flowing across the lower half of the composition.\n\nThe ribbon should:\n- Start from the lower-left foreground.\n- Curve smoothly toward the center-right.\n- Continue upward toward the upper-right background.\n- Feel like a sophisticated cinematic film strip or flowing image-generation sequence.\n- Use approximately 5–7 image panels only.\n- Avoid a dense collage.\n\nEach panel:\n- Rounded rectangle.\n- Thin subtle border.\n- Premium glossy display appearance.\n- Slight perspective distortion following the curve.\n- Gradually decrease in size toward the background.\n- Use realistic generated landscape photography:\n • alpine lake\n • mountain valley\n • waterfall\n • dramatic mountain peaks\n • coastal sunset\n- Rich but natural colors.\n- Foreground panels sharp, distant panels progressively softer / slightly blurred.\n- Strong depth-of-field.\n\nThe ribbon itself should have an extremely subtle luminous edge:\n- cyan / electric blue on the left\n- transitioning gently toward violet / magenta on the right\n\nKeep the glow restrained and premium.\nDo not make it look like cyberpunk neon.\n\nLIGHTING\n\nAdd one very thin horizontal blue-to-violet light flare passing subtly behind the “6-step” text.\n\nUse soft reflected blue/violet light underneath the image ribbon.\n\nLighting should feel cinematic and expensive, not game-like.\n\nBOTTOM-RIGHT\n\nSmall footer:\n“Generate with viggle-turbo”\n\n- Small clean sans-serif.\n- White / light gray.\n- Bottom-right aligned.\n- Approximately 5% from the right and 6–8% from the bottom.\n- Lots of breathing room.\n- Do not make it prominent.\n\nOVERALL COMPOSITION\n\nThe visual hierarchy should clearly be:\n\n1. “6-step generation”\n2. “Qwen-Image-2.1 ❤️ Viggle Turbo”\n3. flowing generated-image ribbon\n4. “DMD-distilled · Generate & Edit”\n5. small “Generate with viggle-turbo.” footer\n\nThe graphic should immediately communicate:\nfast generation, image generation, premium AI model, six-step inference.\n\nOverall aesthetic:\nminimal, elegant, expensive, technically sophisticated, cinematic, polished, restrained, premium AI launch campaign.\n\nAvoid:\n- excessive neon\n- cyberpunk look\n- too many thumbnails\n- busy collage layouts\n- random icons\n- fake UI elements\n- gradients inside every object\n- excessive lens flares\n- heavy shadows\n- 3D metallic typography\n- cartoon imagery\n- excessive text\n- logos other than the specified text\n- watermark\n- spelling errors\n- distorted letters\n- duplicated text",
|
| 26 |
"steps": 8,
|
| 27 |
"size_label": "3:2 · 2496×1664 (2048² area)",
|
|
|
|
| 35 |
null
|
| 36 |
],
|
| 37 |
"result": "t2i_capybara.png",
|
| 38 |
+
"info": "Pre-rendered example · seed `0` · 1248×832 · 6 steps · v0.2.1 LoRA r256 · prompt enhanced",
|
| 39 |
"used_prompt": "The image is a close-up realistic photograph of a soaking wet capybara taking shelter under a large banana leaf in a rainy jungle, the background a lush green canopy dappled with falling raindrops and misty humidity. In the upper-left corner, the edge of the banana leaf curves downward, its broad surface glistening with rainwater and casting a soft shadow over the capybara’s back. Across the top third, rain streaks blur the dense foliage behind, with shafts of diffused light filtering through the canopy. In the center of the frame, the capybara’s rounded body is pressed against the leaf’s underside, its fur matted and dark with water, clinging to its skin in clumps; its small ears are flattened against its head, and its eyes are half-closed, glistening with moisture. On the right side, a second banana leaf peeks into the frame, its veins visible and slightly curled at the edges, partially obscuring the background. Behind the capybara’s left shoulder, a cluster of broad, wet leaves hangs low, their edges blurred by the shallow depth of field. Along the lower edge, the ground is a muddy brown, slick with rainwater and scattered with fallen leaves and twigs, reflecting the dim light. The lighting is soft, diffused daylight filtered through the jungle canopy, casting gentle highlights on the capybara’s wet fur and the water droplets clinging to the banana leaf, with faint shadows beneath the animal and along the leaf’s underside. The overall composition feels intimate and sheltered, emphasizing the capybara’s vulnerability and the quiet resilience of nature in the downpour.",
|
| 40 |
"steps": 6,
|
| 41 |
"size_label": "3:2 · 1248×832 (1024² area)",
|
|
|
|
| 49 |
null
|
| 50 |
],
|
| 51 |
"result": "t2i_diorama.png",
|
| 52 |
+
"info": "Pre-rendered example · seed `0` · 2368×1760 · 6 steps · v0.2.1 LoRA r256 · prompt enhanced",
|
| 53 |
"used_prompt": "The image is a 4:3 isometric miniature diorama of a mountain research station, rendered in high detail with soft studio lighting and a tilt-shift effect. The scene is set on a rugged, snow-dusted mountain slope, with the research station occupying the central foreground, its modular buildings and domed observatory nestled into the terrain. To the left, a steep incline rises into a misty valley, while the right side features a rocky outcrop with a small antenna array. Behind the station, a jagged mountain ridge stretches across the background under a pale blue sky with soft, diffused clouds. The station’s structures are detailed with weathered metal siding, glass windows reflecting the ambient light, and exposed piping and cables. A small helipad with a landing pad marker is visible in the lower-left corner, and a narrow service road winds up the slope toward the main entrance. The lighting is soft and even, emanating from an unseen source above and slightly to the left, casting gentle shadows that emphasize the three-dimensional depth of the diorama. The overall composition feels immersive and meticulously crafted, with a balanced arrangement of architectural elements and natural terrain, evoking a sense of isolation and scientific exploration in a remote alpine environment.",
|
| 54 |
"steps": 6,
|
| 55 |
"size_label": "4:3 · 2368×1760 (2048² area)",
|
|
|
|
| 63 |
null
|
| 64 |
],
|
| 65 |
"result": "edit_sketch.png",
|
| 66 |
+
"info": "Pre-rendered example · seed `3` · 1024×1024 · 6 steps · v0.2.1 LoRA r256 · prompt enhanced",
|
| 67 |
"used_prompt": "Convert the image to a pencil sketch on textured paper, preserving the exact composition, framing, and spatial arrangement of all elements including the rain-streaked window, the interior bookstore shelves, the figure inside, and the \"OPEN LATE\" sign in the foreground, while rendering the entire scene in a hand-drawn, sketchy style with visible pencil strokes and paper texture.",
|
| 68 |
"steps": 6,
|
| 69 |
"size_label": "Auto · match the last reference (1024² area)",
|
|
|
|
| 77 |
null
|
| 78 |
],
|
| 79 |
"result": "edit_2ref_cat.png",
|
| 80 |
+
"info": "Pre-rendered example · seed `42` · 832×1248 · 6 steps · v0.2.1 LoRA r256 · prompt enhanced",
|
| 81 |
"used_prompt": "Compose a new image where the woman from <image1>, wearing her full traditional outfit with skull makeup and holding a smoke bomb, is now holding the fluffy cat from <image2> in her arms, positioned in the same spot as in the original image, with the ornate wooden gate and surrounding smoke from <image1> remaining unchanged as the background.",
|
| 82 |
"steps": 6,
|
| 83 |
"size_label": "Auto · match the last reference (1024² area)",
|
examples/t2i_capybara.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
examples/t2i_diorama.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
examples/t2i_launch.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|