
Spaces:
Running on Zero


Running on Zero
Upload folder using huggingface_hub
Browse files- README.md +2 -2
- app.py +4 -2
- examples/ocr.jpg +2 -2
README.md
CHANGED
|
@@ -1,5 +1,5 @@
|
|
| 1 |
---
|
| 2 |
-
title: DeepSeek OCR Demo
|
| 3 |
emoji: 🚀
|
| 4 |
colorFrom: red
|
| 5 |
colorTo: red
|
|
@@ -7,7 +7,7 @@ sdk: gradio
|
|
| 7 |
sdk_version: 6.3.0
|
| 8 |
app_file: app.py
|
| 9 |
pinned: true
|
| 10 |
-
short_description: Try out DeepSeek-OCR on your PDFs or images
|
| 11 |
license: mit
|
| 12 |
---
|
| 13 |
|
|
|
|
| 1 |
---
|
| 2 |
+
title: DeepSeek OCR 2 Demo
|
| 3 |
emoji: 🚀
|
| 4 |
colorFrom: red
|
| 5 |
colorTo: red
|
|
|
|
| 7 |
sdk_version: 6.3.0
|
| 8 |
app_file: app.py
|
| 9 |
pinned: true
|
| 10 |
+
short_description: Try out DeepSeek-OCR-2 on your PDFs or images
|
| 11 |
license: mit
|
| 12 |
---
|
| 13 |
|
app.py
CHANGED
|
@@ -48,7 +48,7 @@ def draw_bounding_boxes(image, refs, extract_images=False):
|
|
| 48 |
draw = ImageDraw.Draw(img_draw)
|
| 49 |
overlay = Image.new('RGBA', img_draw.size, (0, 0, 0, 0))
|
| 50 |
draw2 = ImageDraw.Draw(overlay)
|
| 51 |
-
font = ImageFont.truetype("/usr/share/fonts/truetype/dejavu/DejaVuSans-Bold.ttf",
|
| 52 |
crops = []
|
| 53 |
|
| 54 |
color_map = {}
|
|
@@ -248,7 +248,9 @@ def update_page_selector(file_path):
|
|
| 248 |
with gr.Blocks(title="DeepSeek-OCR-2") as demo:
|
| 249 |
gr.Markdown("""
|
| 250 |
# 🚀 DeepSeek-OCR-2 Demo
|
| 251 |
-
**Convert documents to markdown, extract text, parse figures, and locate specific content with bounding boxes.**
|
|
|
|
|
|
|
| 252 |
|
| 253 |
**If this tool was helpful, please consider giving it a like ❤️!**
|
| 254 |
""")
|
|
|
|
| 48 |
draw = ImageDraw.Draw(img_draw)
|
| 49 |
overlay = Image.new('RGBA', img_draw.size, (0, 0, 0, 0))
|
| 50 |
draw2 = ImageDraw.Draw(overlay)
|
| 51 |
+
font = ImageFont.truetype("/usr/share/fonts/truetype/dejavu/DejaVuSans-Bold.ttf", 15)
|
| 52 |
crops = []
|
| 53 |
|
| 54 |
color_map = {}
|
|
|
|
| 248 |
with gr.Blocks(title="DeepSeek-OCR-2") as demo:
|
| 249 |
gr.Markdown("""
|
| 250 |
# 🚀 DeepSeek-OCR-2 Demo
|
| 251 |
+
**Convert documents to markdown, extract text, parse figures, and locate specific content with bounding boxes.**
|
| 252 |
+
|
| 253 |
+
Powered by **DeepEncoder V2** - a novel LLM-style vision encoder that dynamically reorders visual tokens based on semantic understanding, mimicking human reading patterns instead of rigid left-to-right scanning. Achieves **91.09%** on OmniDocBench (+3.73% over v1).
|
| 254 |
|
| 255 |
**If this tool was helpful, please consider giving it a like ❤️!**
|
| 256 |
""")
|
examples/ocr.jpg
CHANGED
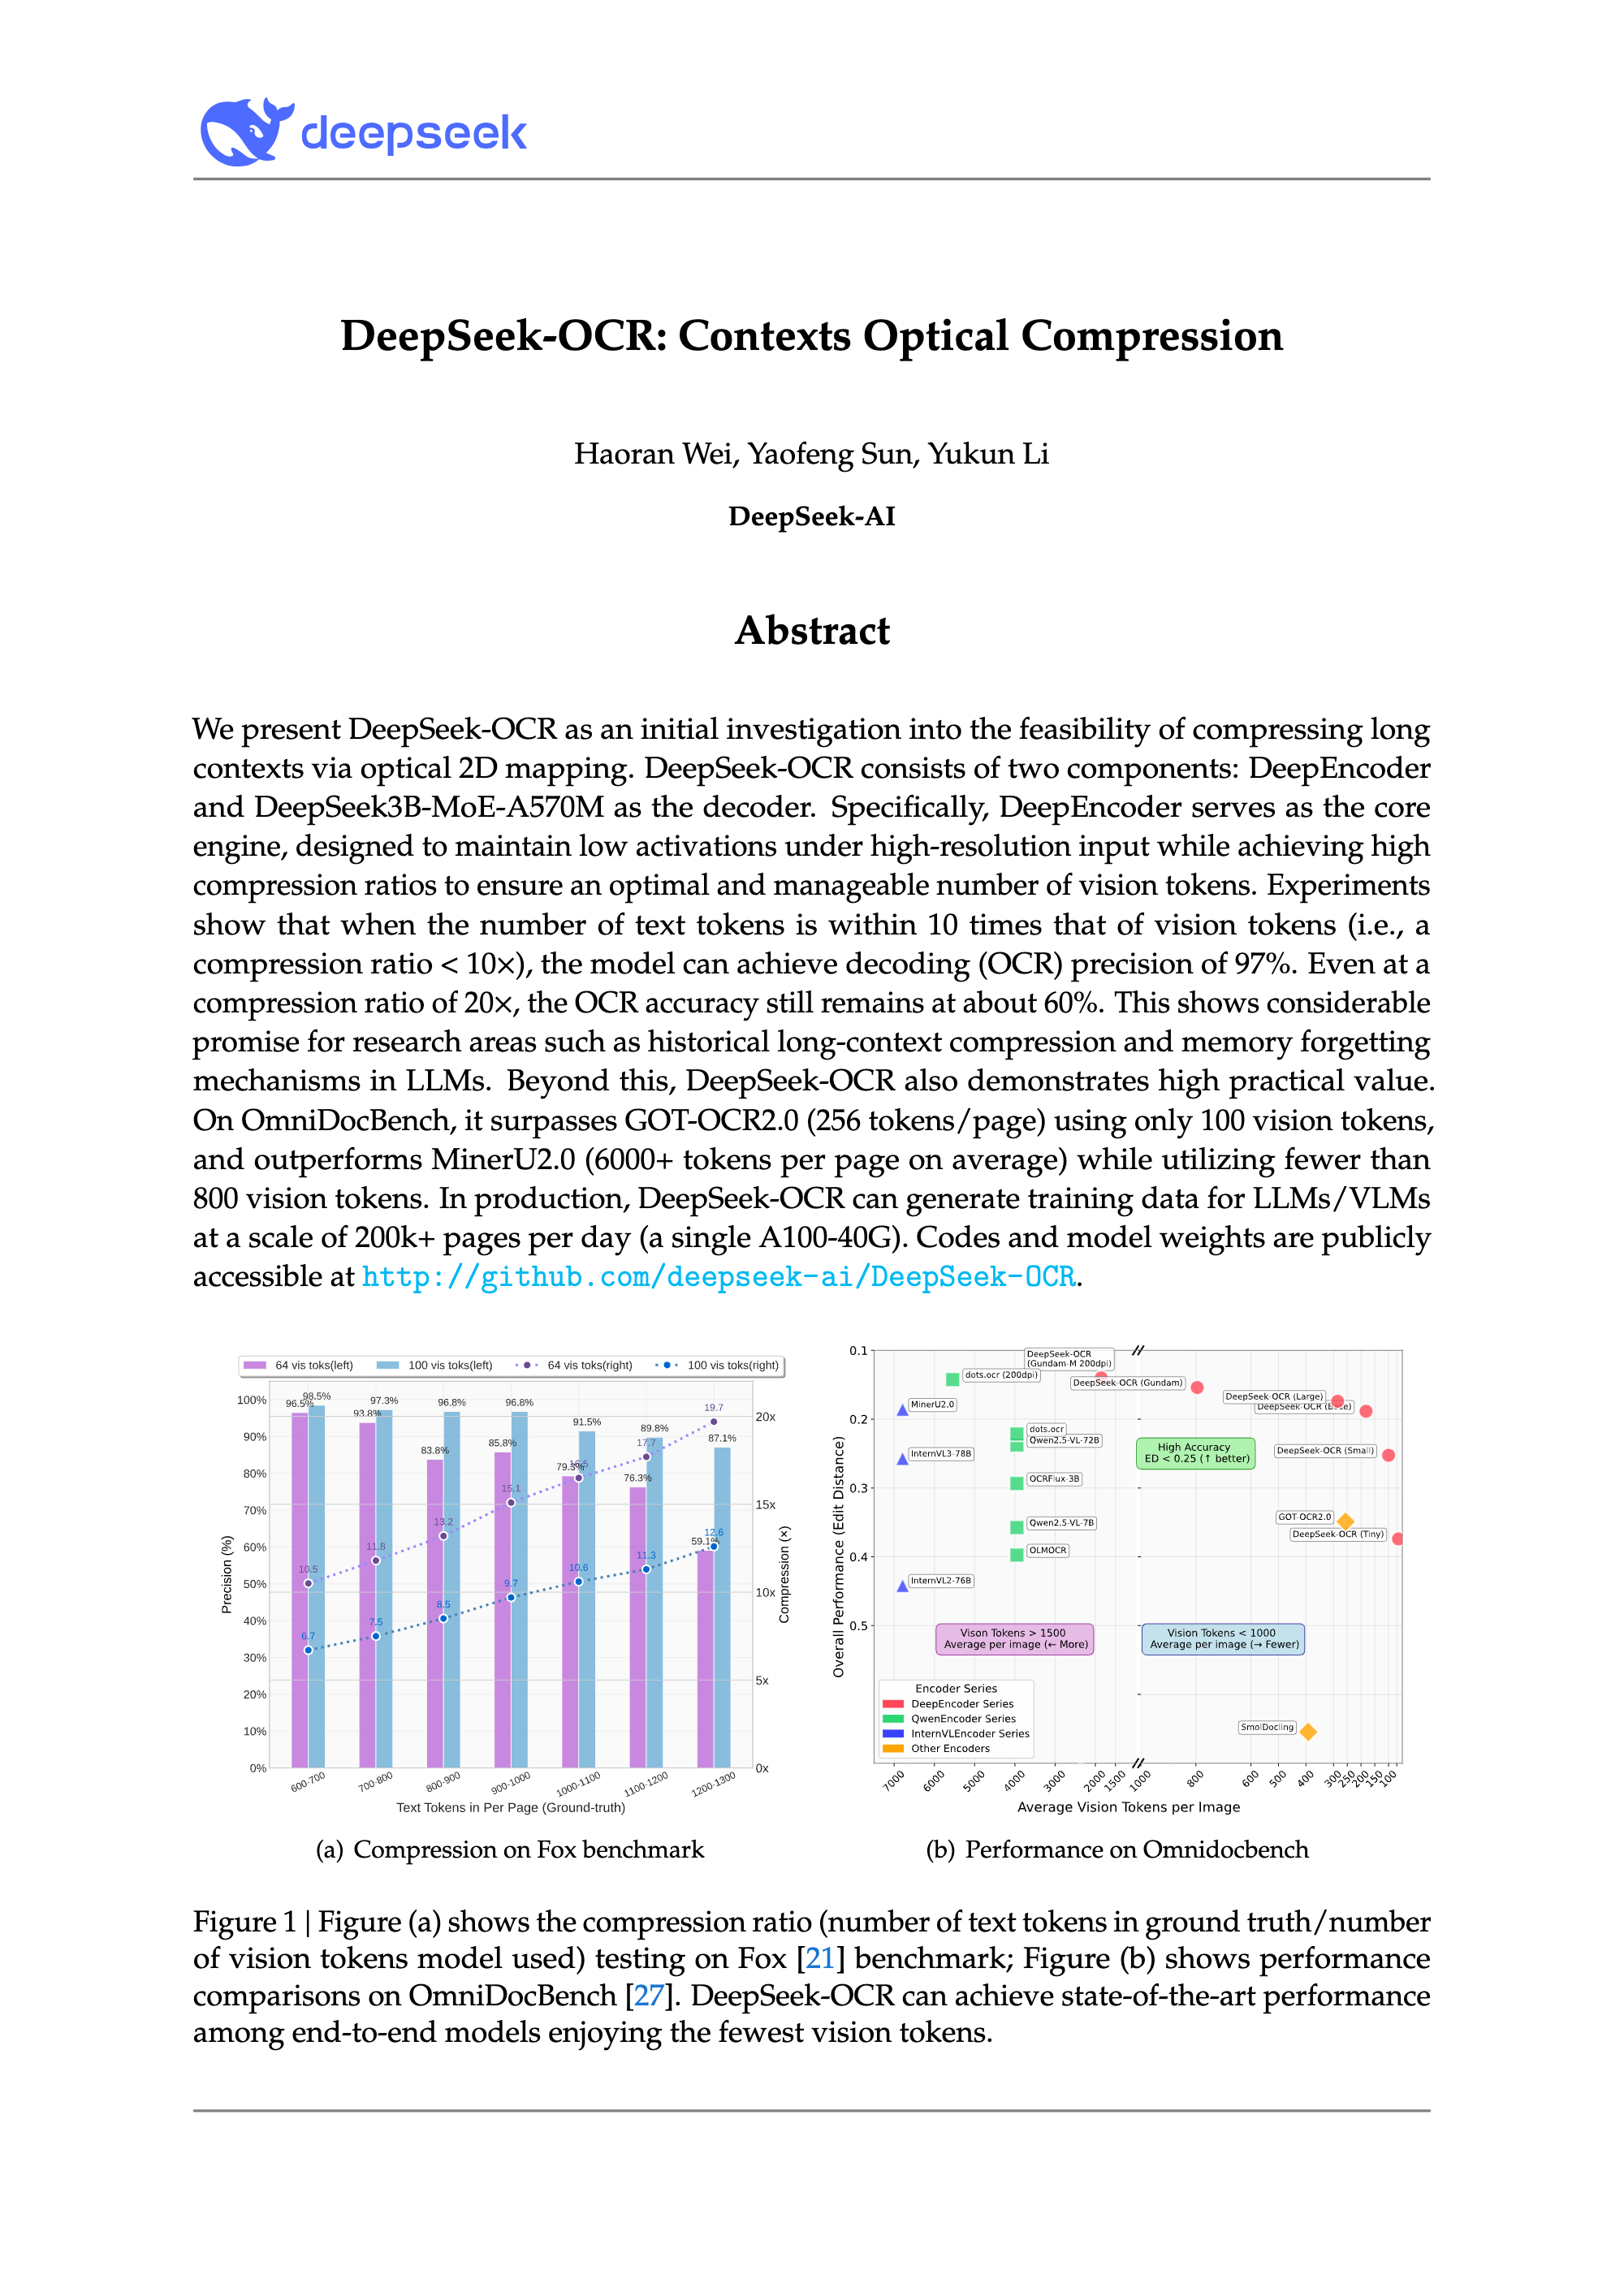
|
Git LFS Details
|
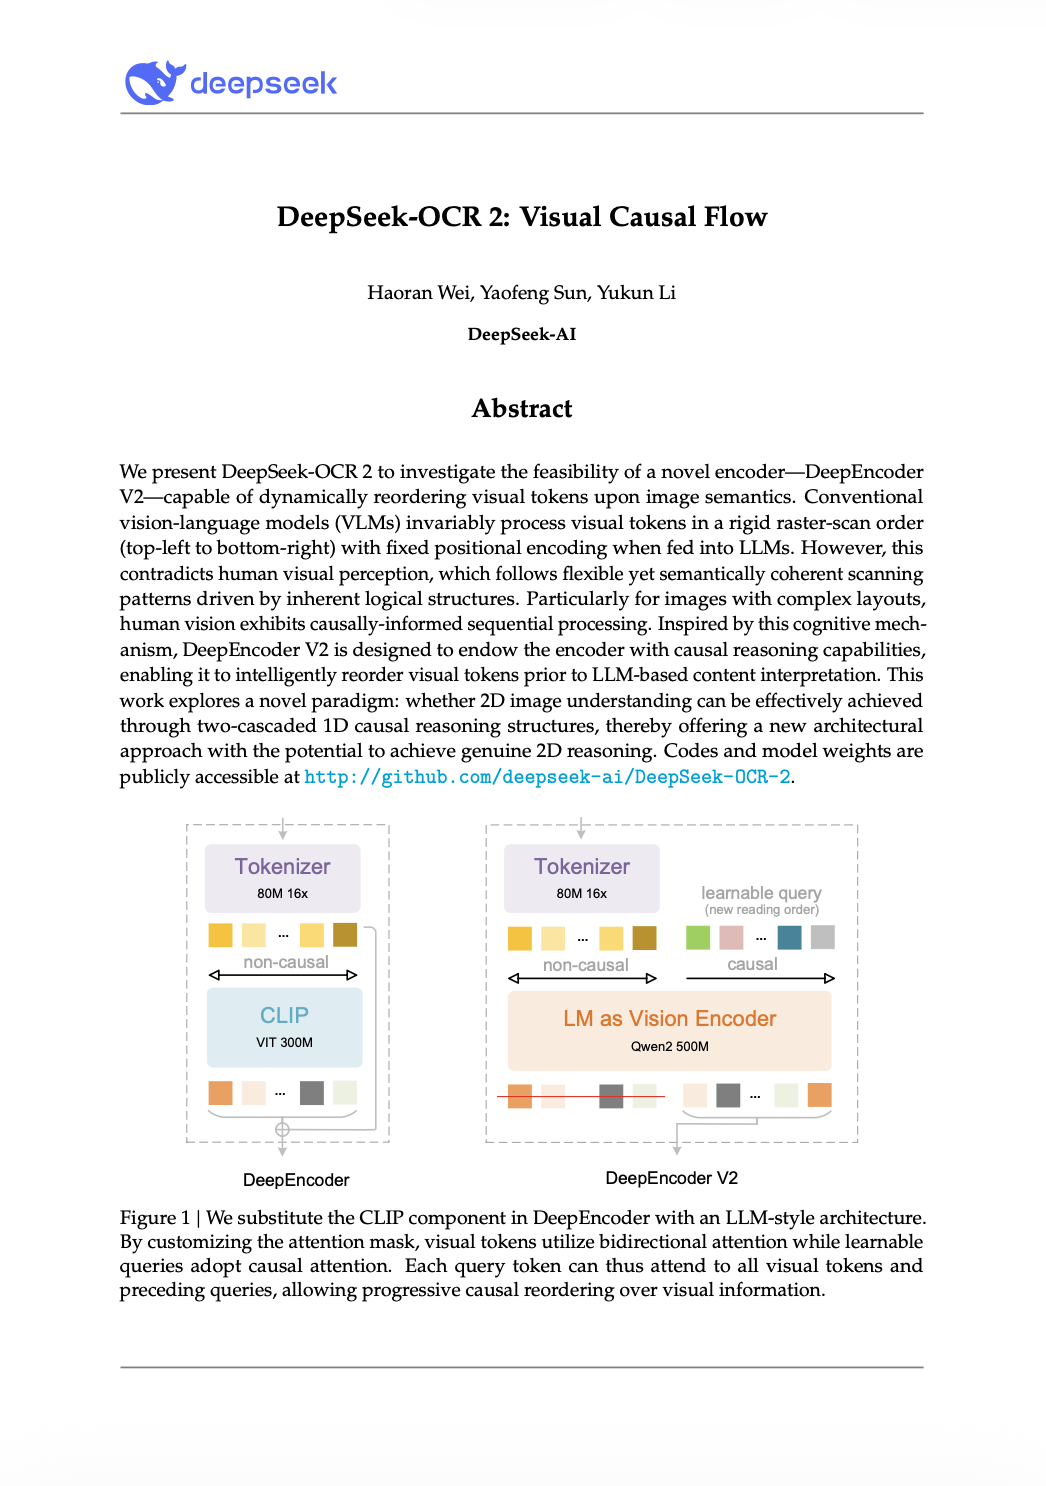
|
Git LFS Details
|