
Spaces:
Running

Running
force recovery: methods, evaluation, debug log
Browse files- .gitattributes +1 -0
- assets/cross_dataset.png +3 -0
- results.html +10 -0
.gitattributes
CHANGED
|
@@ -135,3 +135,4 @@ assets/panel_fota_cnc_zh.png filter=lfs diff=lfs merge=lfs -text
|
|
| 135 |
assets/panel_sparsh_zh.png filter=lfs diff=lfs merge=lfs -text
|
| 136 |
assets/react_normals.png filter=lfs diff=lfs merge=lfs -text
|
| 137 |
assets/pred_vs_gt.png filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 135 |
assets/panel_sparsh_zh.png filter=lfs diff=lfs merge=lfs -text
|
| 136 |
assets/react_normals.png filter=lfs diff=lfs merge=lfs -text
|
| 137 |
assets/pred_vs_gt.png filter=lfs diff=lfs merge=lfs -text
|
| 138 |
+
assets/cross_dataset.png filter=lfs diff=lfs merge=lfs -text
|
assets/cross_dataset.png
ADDED
|
Git LFS Details
|
results.html
CHANGED
|
@@ -76,6 +76,16 @@ protocol reproduces the between-capture ordering whether or not the
|
|
| 76 |
frame-to-force pairing survives, so a scatter of it would be convincing and
|
| 77 |
meaningless.</figcaption></figure>
|
| 78 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 79 |
<h2>Which reconstruction should the React force channel use?</h2>
|
| 80 |
<p>Calibration-free, decided on React's own calibration objects: held out by
|
| 81 |
press position, ρ 0.812 against the LUT's 0.763, MAE 1.024 against
|
|
|
|
| 76 |
frame-to-force pairing survives, so a scatter of it would be convincing and
|
| 77 |
meaningless.</figcaption></figure>
|
| 78 |
|
| 79 |
+
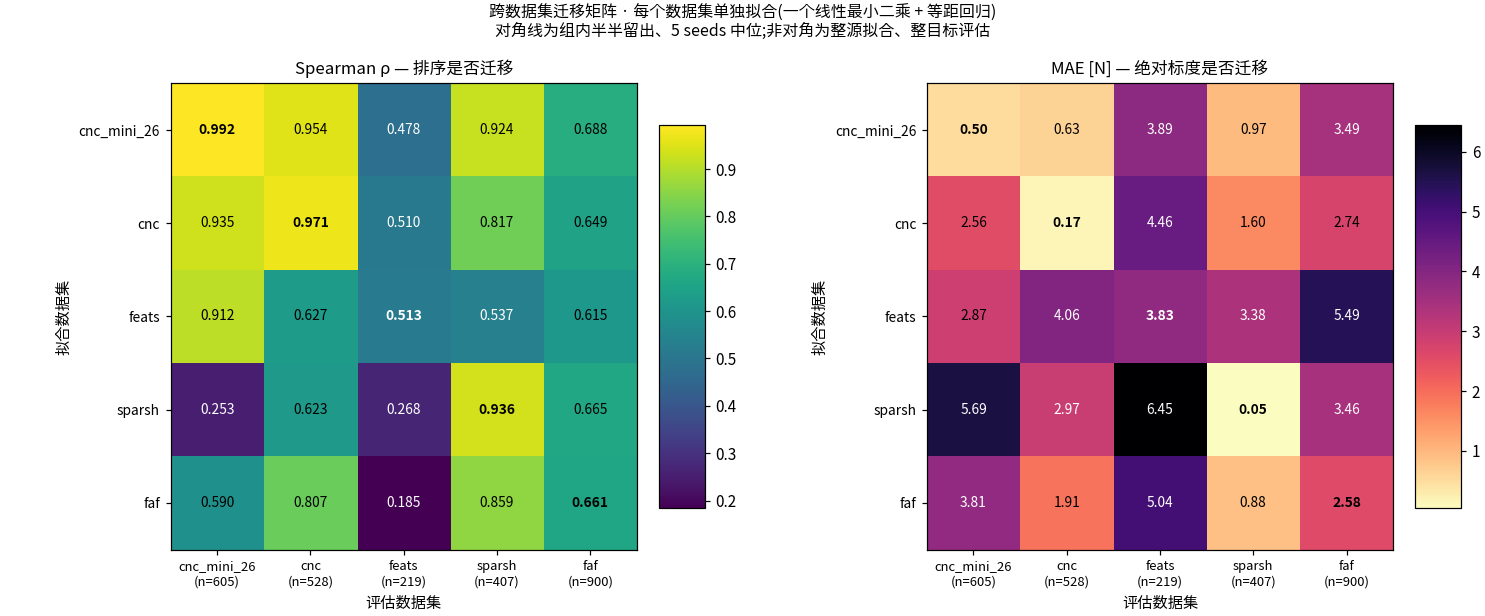
<figure><img src="assets/cross_dataset.png" alt="cross-dataset transfer matrix">
|
| 80 |
+
<figcaption>Fit on one dataset, predict on every other. One model per dataset —
|
| 81 |
+
a 5-feature least squares plus an isotonic calibration — on the calibration-free
|
| 82 |
+
reconstruction. ρ and MAE answer different questions and both are shown: the
|
| 83 |
+
isotonic step is monotone, so it cannot change a rank correlation, and ρ tests
|
| 84 |
+
only whether the feature-to-force ORDERING transfers. MAE tests whether the
|
| 85 |
+
newton scale does, and it does not — these datasets span 0.08–1.06 N (Sparsh)
|
| 86 |
+
to 0–34 N (FEATS). The diagonal is held out, five seeds; off it, the whole
|
| 87 |
+
source fits and the whole target is scored.</figcaption></figure>
|
| 88 |
+
|
| 89 |
<h2>Which reconstruction should the React force channel use?</h2>
|
| 90 |
<p>Calibration-free, decided on React's own calibration objects: held out by
|
| 91 |
press position, ρ 0.812 against the LUT's 0.763, MAE 1.024 against
|