

StartLux-Decision
Collection
Typed decision models from 0.8B to 27B. Every question comes back with a probability for each option. • 21 items • Updated • 7

StartLux-Decision-27B answers typed questions about a state: pick one of several options, yes or no, or a rating on a scale. The
state can be text, JSON or images, up to 262,144 tokens (256K). Every
question comes back with a probability for each option. Requests and responses use the TypeSafe /v1/systemone
format, so clients written for Jev work unchanged.
Sizes: 0.8B · 2B · 4B · 9B · 27B · 35B-A3B
| StartLux-Decision-27B | |
|---|---|
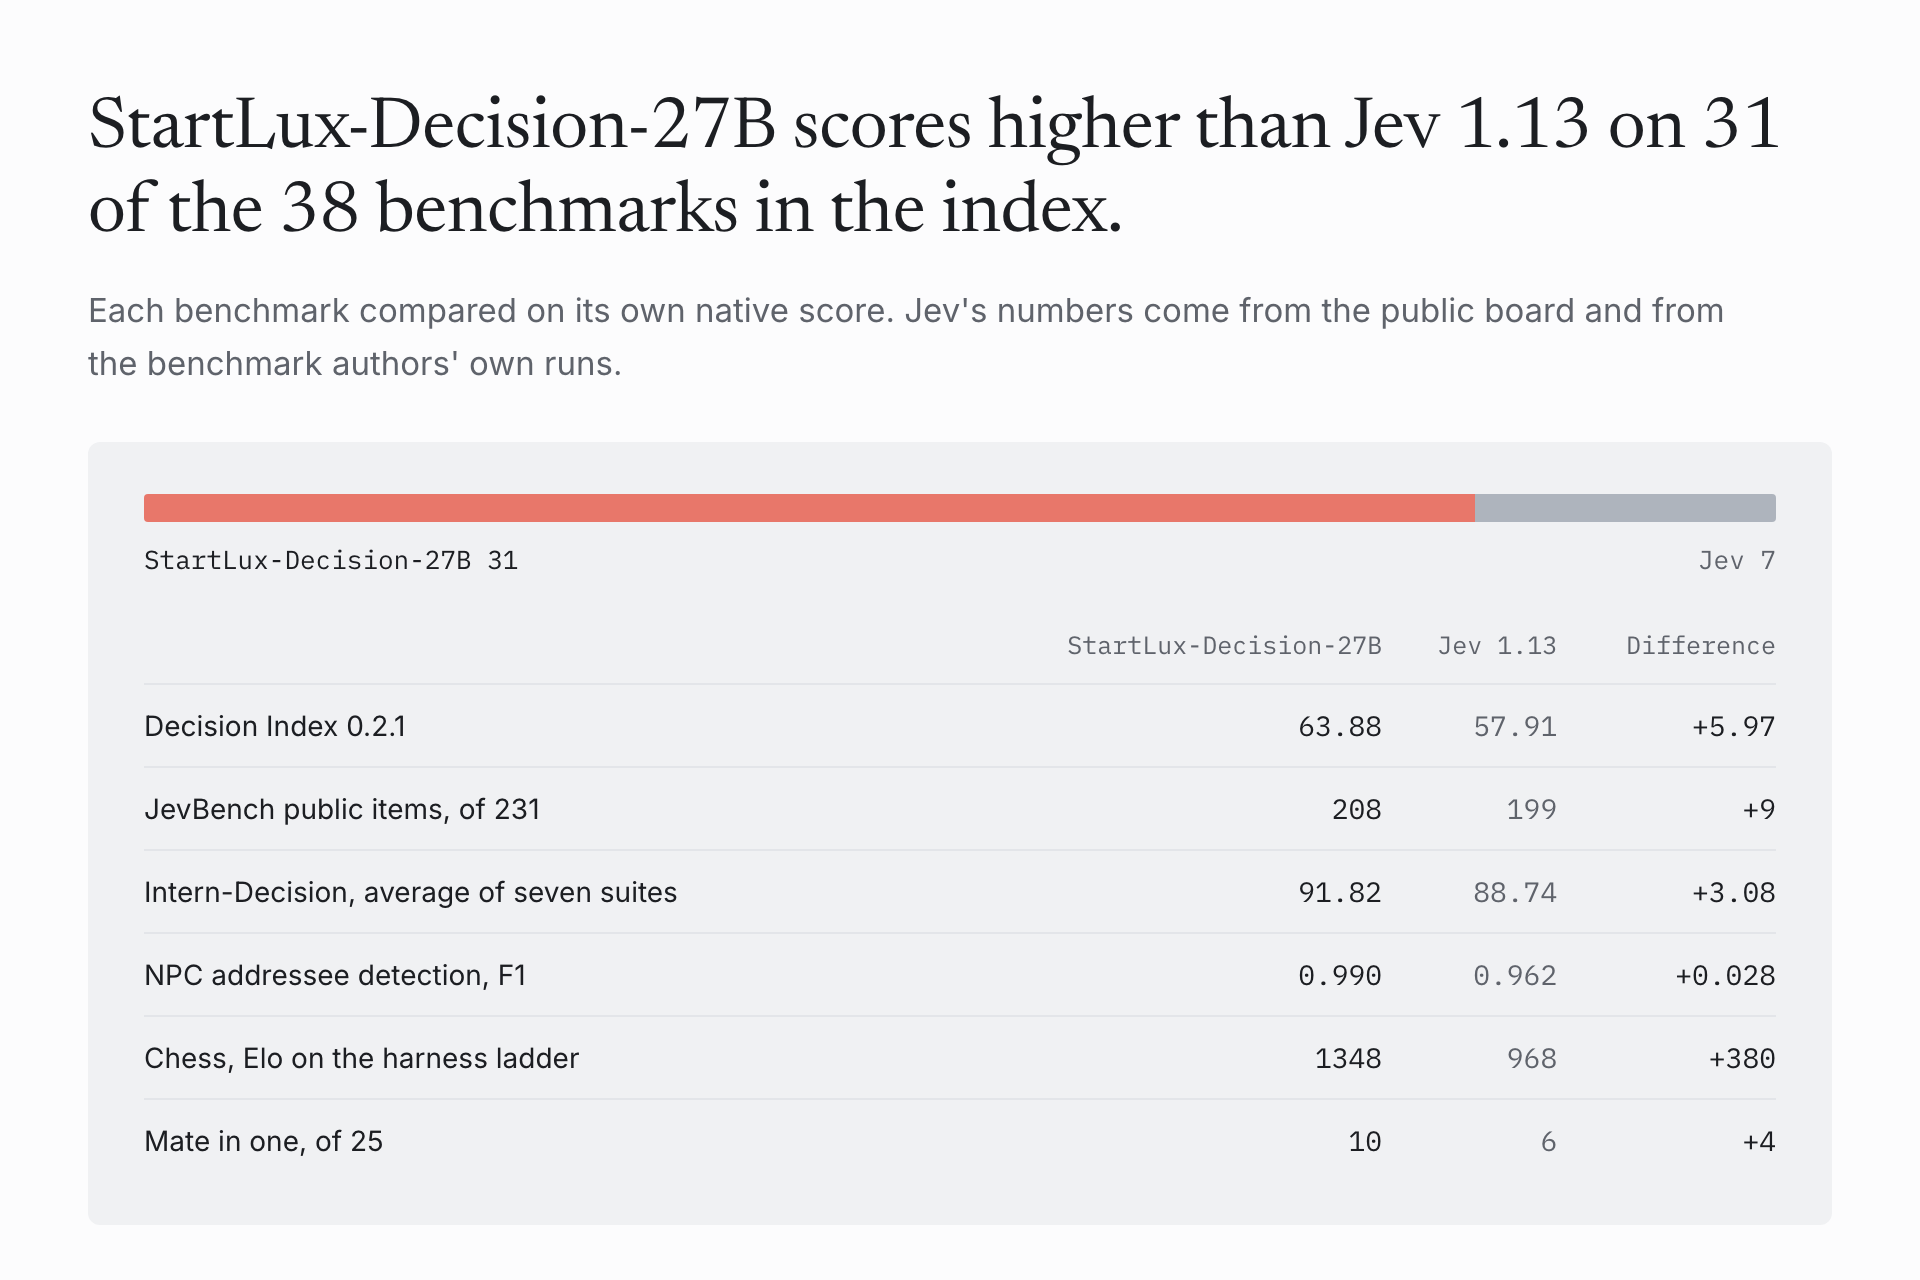
| Decision Index 0.2.1 | 63.88 |
| Decision Index 0.2 | 59.54 |
| JevBench public, correct of 231 | 208 |
| Intern-Decision, average accuracy over seven suites | 91.82 |
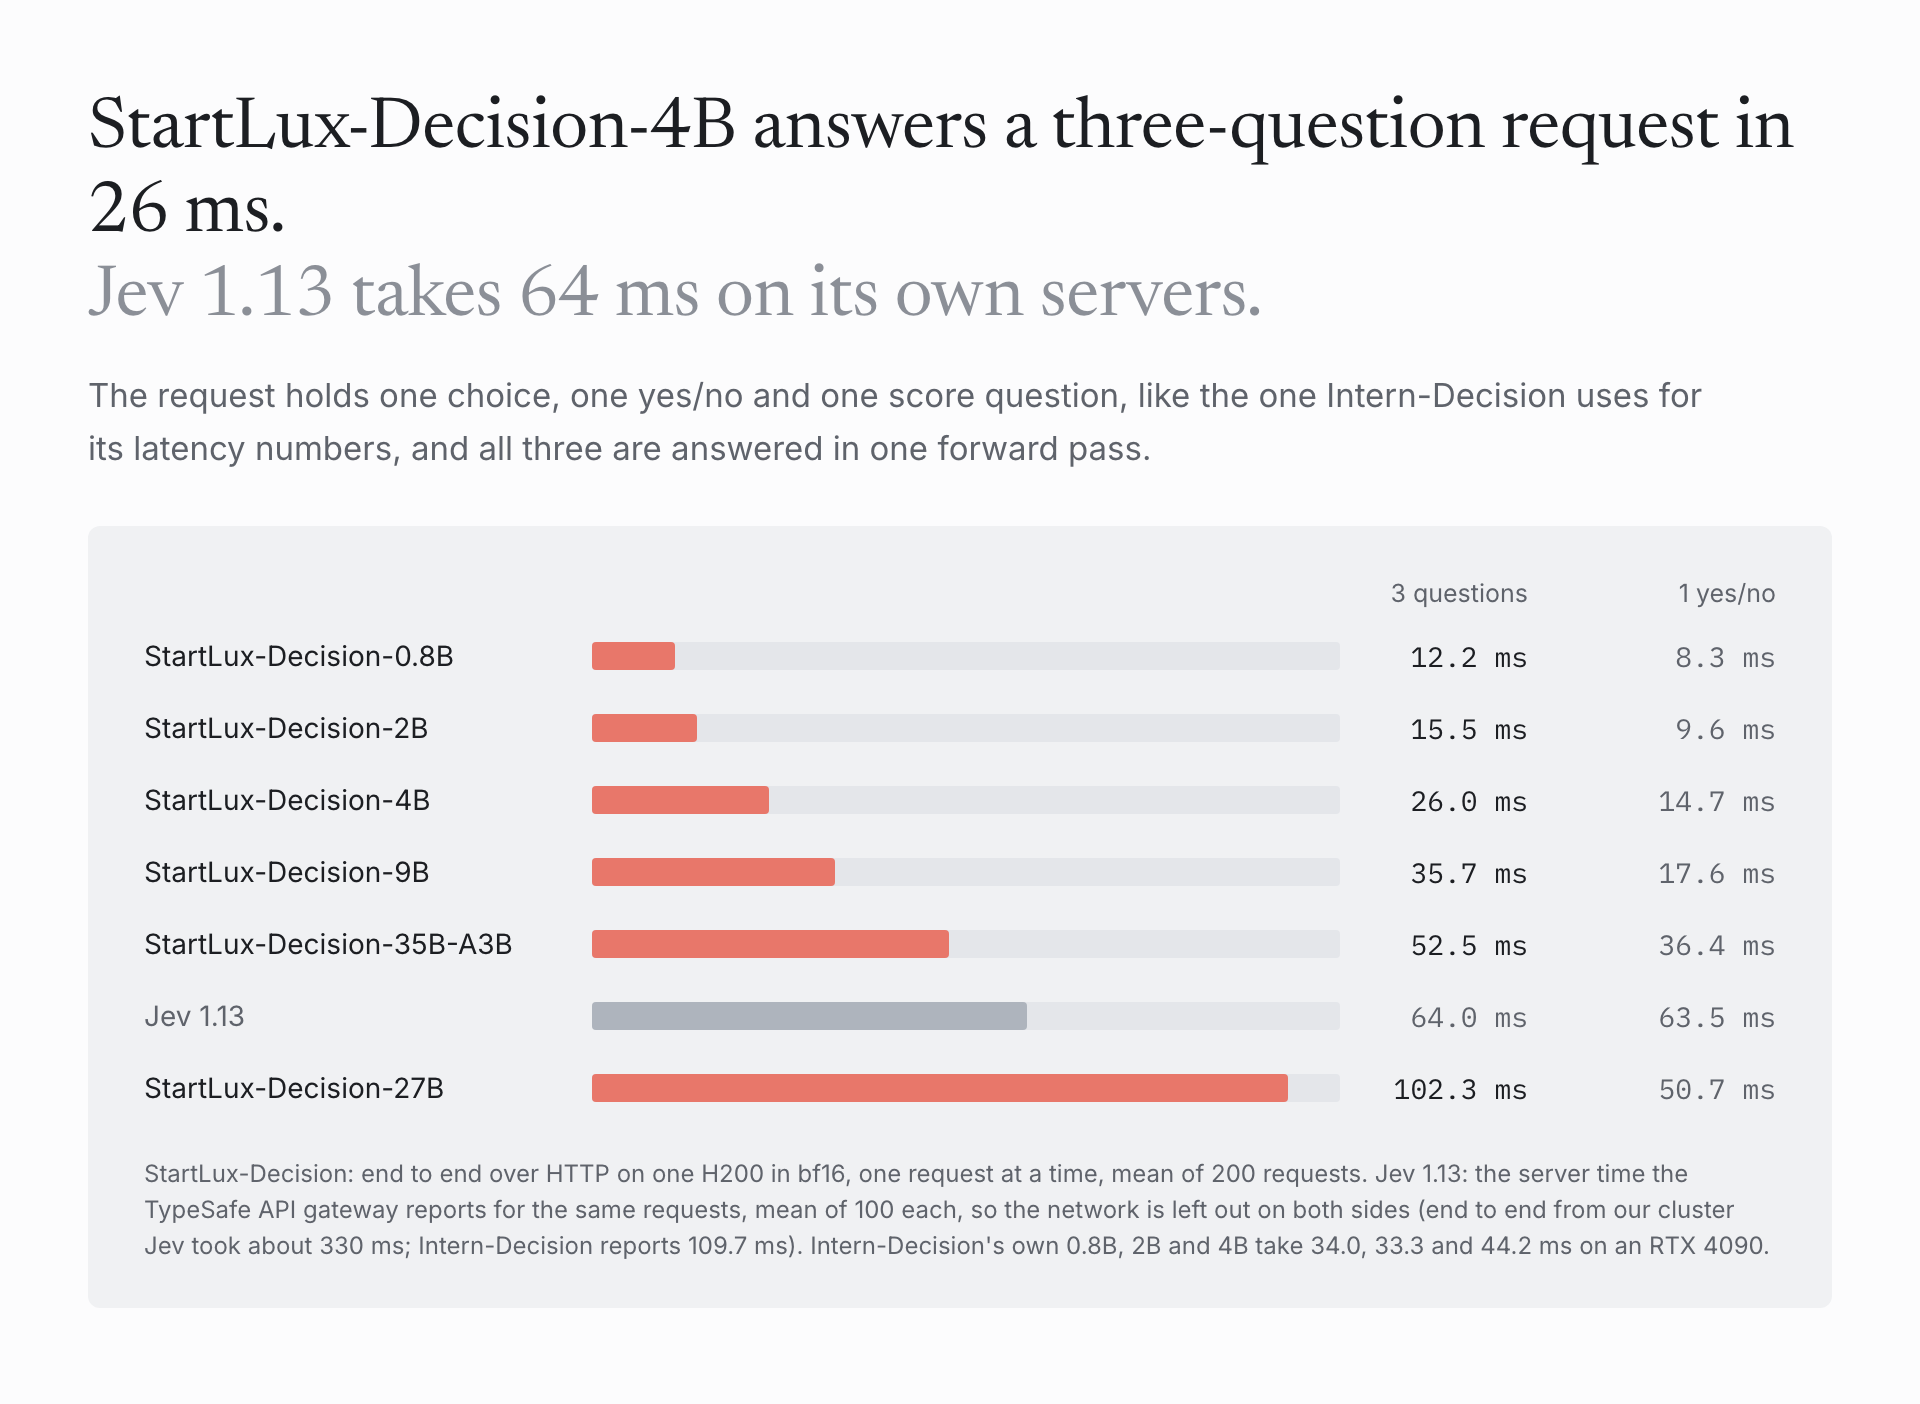
| Latency, one request with three questions | 102.3 ms |
| Latency, one yes/no question | 50.7 ms |
| Input | text, JSON or images, up to 262,144 tokens |
Latency is end to end over HTTP on one H200 in bf16, one request at a time.

| Model | JevBench public, of 231 | Intern avg | DI 0.2 / 0.2.1 | Latency, 3 questions |
|---|---|---|---|---|
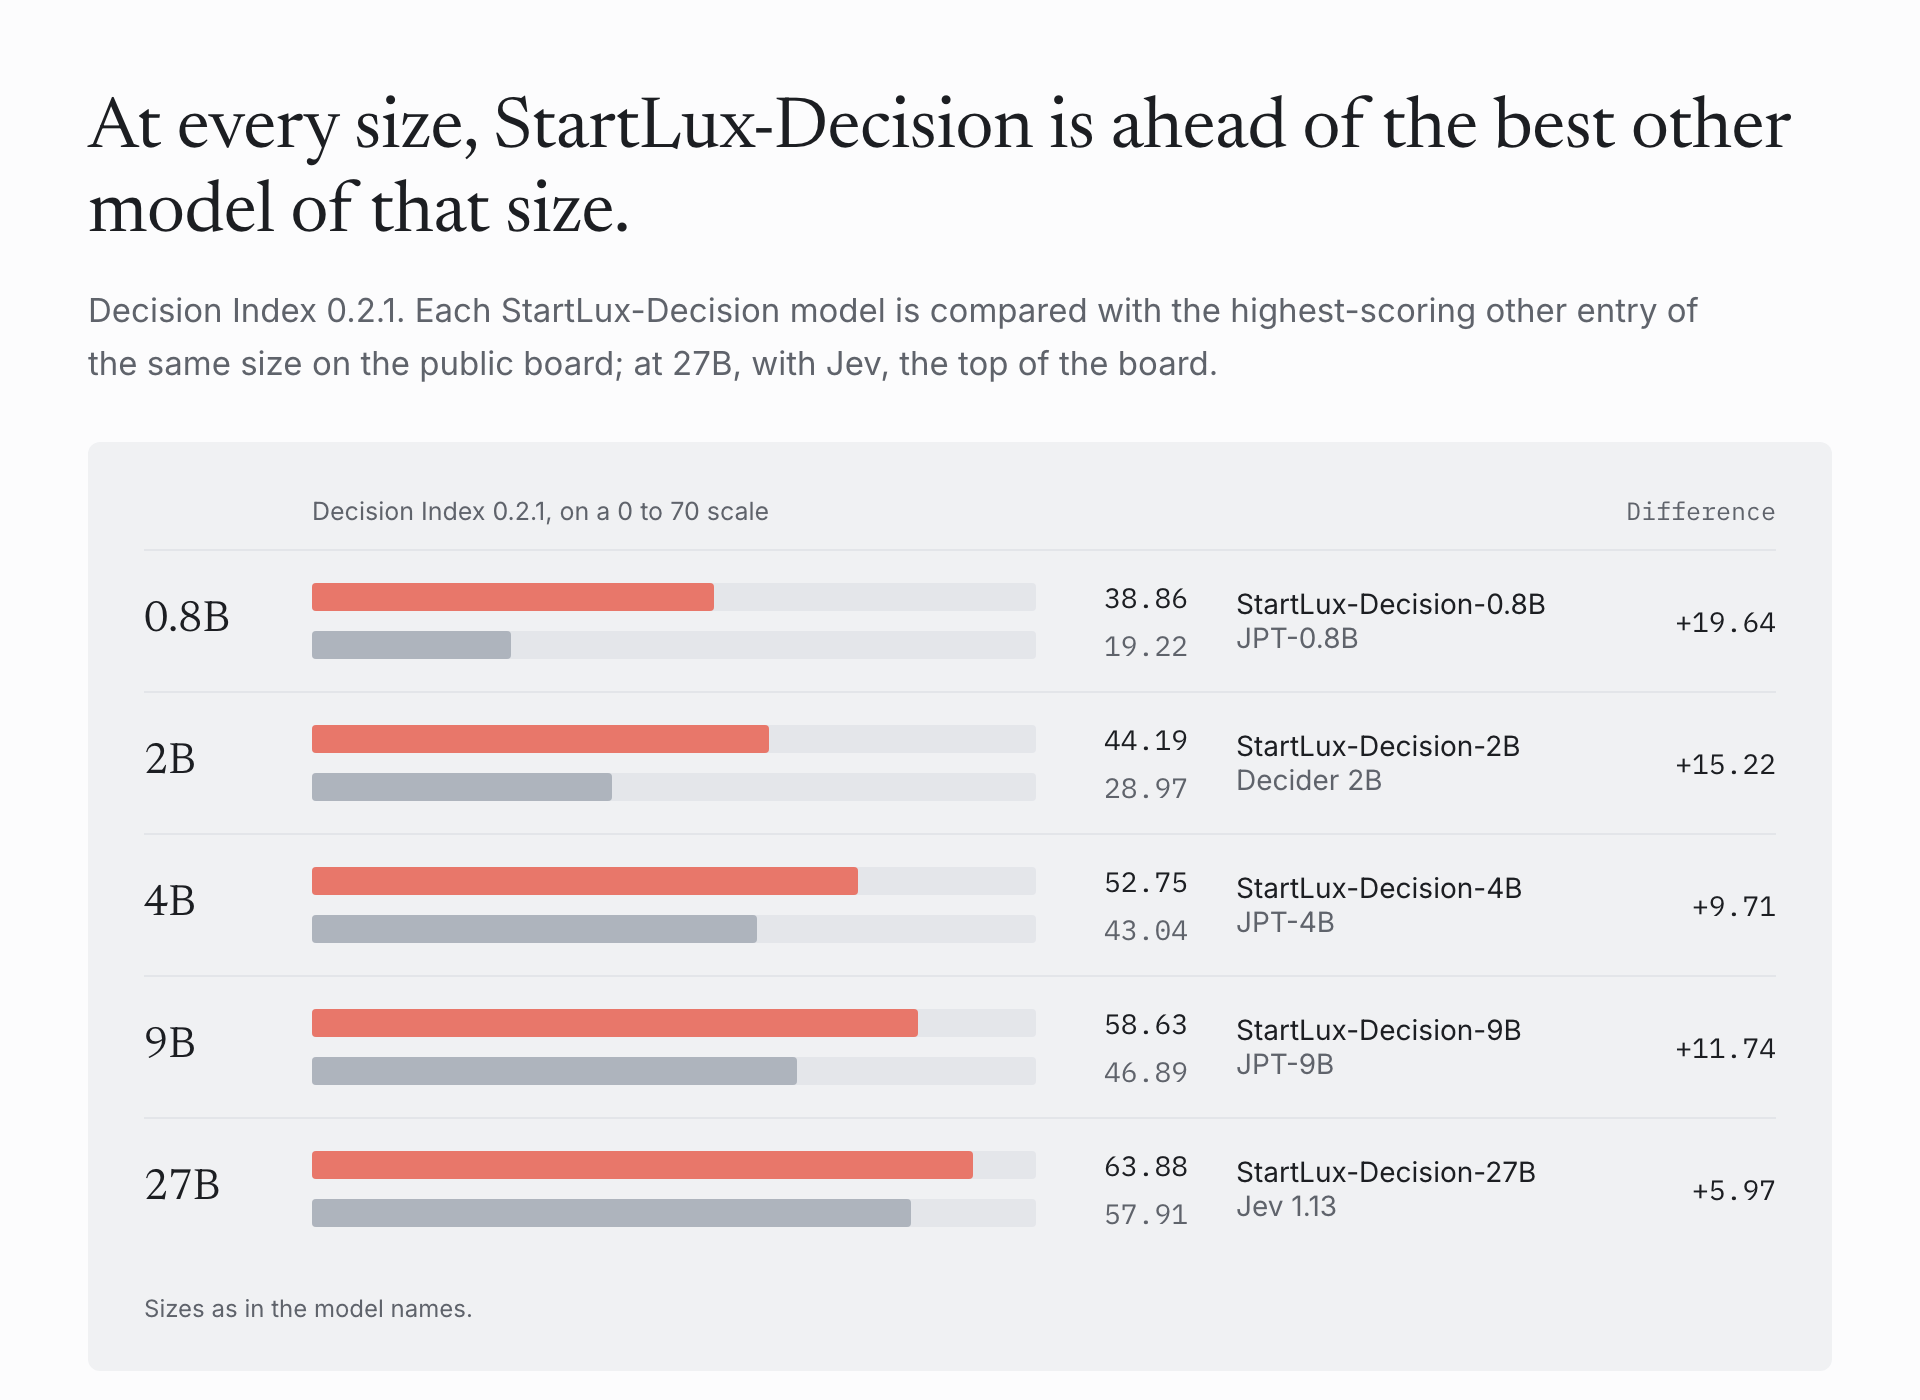
| StartLux-Decision-35B-A3B | 210 | 92.29 | 57.24 / 61.55 | 52.5 ms |
| StartLux-Decision-27B | 208 | 91.82 | 59.54 / 63.88 | 102.3 ms |
| StartLux-Decision-9B | 201 | 91.08 | 54.37 / 58.63 | 35.7 ms |
| StartLux-Decision-4B | 204 | 91.17 | 48.38 / 52.75 | 26.0 ms |
| Intern-Decision-4B | 201 | 90.02 | 35.90 / 37.81 | 44.2 ms ¹ |
| JevK5 | 200 | 85.16 | 36.44 / 38.81 | |
| Jev 1.13 | 199 | 88.74 | 51.67 / 57.91 | 64.0 ms ² |
| StartLux-Decision-2B | 196 | 88.46 | 40.72 / 44.19 | 15.5 ms |
| SemIf | 187 | 84.23 | 25.70 / 25.94 | |
| Intern-Decision-2B | 180 | 84.68 | 19.49 / 19.38 | 33.3 ms ¹ |
| StartLux-Decision-0.8B | 179 | 85.03 | 35.57 / 38.86 | 12.2 ms |
| Intern-Decision-0.8B | 163 | 79.38 | 11.32 / 11.94 | 34.0 ms ¹ |
| Laya | 130 | 57.77 | 5.51 / 6.04 |
JevBench public counts the correct answers on the 231 public items in the Intern-Decision bundle; Intern avg is the average accuracy over its seven suites; DI is the Decision Index under both editions, the public board's values for the other systems. A blank cell means the number is not published. StartLux-Decision latencies are for one H200, with the three questions answered in one forward pass. ¹ Intern-Decision's own measurement on an RTX 4090. ² The server time the TypeSafe API gateway reports for the same request, mean of 100, network left out as in ours; Intern-Decision reports 109.7 ms end to end.
The folder ships its own inference package, startlux_decision/, which is the fast path:
requirements.txt installs the fast kernels, flash-linear-attention and causal-conv1d, and
python -m startlux_decision.check . confirms they are active. Without them transformers falls back to a path more than ten
times slower, and the server refuses to start on a GPU.decide_batch batches the questions of many requests together, which is several times faster than
sending them one at a time.The weights include a vision tower, and the inference package uses it: a request can carry images as part of its
evidence, images=[...] in Python (PIL images, file paths, encoded bytes, base64 strings or data URIs) or
"images": [...] over HTTP (base64 strings or data URIs). <image> in a string state marks where each image goes.
Prompts can run to 262,144 tokens (256K), the model's native context: a long state is read once, in chunks, and every
question of the request branches off it. The MLX backend and the GGUF files read text only. confidence follows
TypeSafe's definitions (for a choice, (p_max − 1/n) / (1 − 1/n)); the top probability is in probabilities.
hf download startlux-models/StartLux-Decision-27B --local-dir StartLux-Decision-27B
cd StartLux-Decision-27B
pip install -r requirements.txt
python -m startlux_decision.check .                      # must print "fast kernels: active"
python -m startlux_decision.server --model . --port 8090
curl -s localhost:8090/v1/systemone -H 'Content-Type: application/json' -d '{
  "state": {"ticket": "I was charged twice for order #4411 and the app still shows it as unpaid."},
  "questions": {
    "team":   {"type": "choice", "instructions": "Which team should handle this ticket?",
               "criteria": {"billing": "Payments, refunds and invoices",
                            "shipping": "Delivery and tracking",
                            "technical": "App, login and account problems"}},
    "urgent": {"type": "noul", "instructions": "Should this ticket be answered today?"},
    "severity": {"type": "score", "instructions": "How severe is the impact?",
                 "criteria": ["cosmetic", "annoying", "blocks the customer"]}
  }
}'
Or in Python, from the same folder:
from startlux_decision import StartLuxDecision

m = StartLuxDecision(".")
answers, usage = m.decide(state, questions)
many = m.decide_batch([(state, questions), ...])
With images, from the same folder:
answers, usage = m.decide("Photo taken at delivery: <image>",
                          {"damaged": {"type": "noul", "instructions": "Is the parcel damaged?"}},
                          images=["parcel.jpg"])
The model weights are released under CC BY-NC 4.0: free for
research and other non-commercial use, with attribution. Commercial use requires a separate license from
StartLux Labs; contact contact@startlux.com. The inference code in
startlux_decision/ is Apache-2.0. See LICENSE and NOTICE.