NOTICE: This will only run on AMD AI PRO R9700 GPUs
Activation-aware MXFP4 / FP8 quantization — 116 GB total
- MTP: FP8 — 2.7 GB
- Experts: MXFP4 (activation-aware) — 64.2 GB
- N-Gram: int6 — 41.6 GB
- Attention: FP8 — 2.7 GB
- PPL: 4.552 vs old mxpf4 version 4.603
- KLD: .0549 vs old mxpf4 version .0638
- Top1: 95.17% vs old mxpf4 version 93.26%
Calibrated FP8 KV-cache scales are included.
AMD RAM offload has been enabled.
FP8 KV cache has been enabled, as well as FP8 KV scale use.
docker run --rm -it \
  --network host --shm-size 32g \
  --ulimit memlock=-1:-1 \
  --cap-add SYS_PTRACE --security-opt seccomp=unconfined \
  --device /dev/kfd --device /dev/dri \
  --group-add video \
  -v <path>/Qwen3.8-Flash-Next-MXFP4-FP8-GPTQ:/app/models \
  -v <path>/tunableop:/tunableop \
  -v <path>/cache/triton:/cache/triton \
  -v <path>/cache/vllm:/cache/vllm \
  -v <path>/cache/inductor:/cache/inductor \
  -e TRITON_CACHE_DIR=/cache/triton \
  -e VLLM_CACHE_ROOT=/cache/vllm \
  -e TORCHINDUCTOR_CACHE_DIR=/cache/inductor \
  -e OMP_NUM_THREADS=8 \
  -e PYTORCH_TUNABLEOP_ENABLED=1 \
  -e PYTORCH_TUNABLEOP_TUNING=0 \
  -e PYTORCH_TUNABLEOP_RECORD_UNTUNED=0 \
  -e VLLM_ROCM_USE_AITER=0 \
  -e GPU_MAX_HW_QUEUES=1 \
  -e HSA_ENABLE_INTERRUPT=1 \
  -e HSA_ENABLE_MWAITX=1 \
  -e VLLM_PLE_CPU_OFFLOAD=1 \
  -e ROCR_VISIBLE_DEVICES=0,1,2,3 \
  tcclaviger/vllm:latest \
  /app/models \
  --tensor-parallel-size 4 \
  --tool-call-parser qwen3_coder \
  --enable-auto-tool-choice \
  --max-num-seqs 16 \
  --enable-chunked-prefill \
  --max-num-batched-tokens 8192 \
  --gpu-memory-utilization 0.97 \
  --host 0.0.0.0 \
  --port 8078 \
  --kv-cache-dtype fp8 \
  --served-model-name Qwen3.8-Flash-Next \
  --max-model-len 524288 \
  --reasoning-parser qwen3 \
  --override-generation-config '{"max_tokens": 65536, "temperature": 0.8, "top_p": 0.95, "top_k": 40, "presence_penalty": 1}' \
  --compilation-config '{"cudagraph_capture_sizes": [4], "max_cudagraph_capture_size": 4}' \
  --speculative-config '{"method": "mtp", "num_speculative_tokens": 3}' \
  --hf-overrides '{"text_config": {"rope_parameters": {"rope_type": "yarn", "factor": 2.0, "original_max_position_embeddings": 262144, "mrope_section": [11, 11, 10], "mrope_interleaved": true, "partial_rotary_factor": 0.25, "rope_theta": 10000000}}}'
2 x R9700 — the image's best measured TP2 recipe (--recipes tp2-expert-mem-60gb-ple-cache-8gb): routed experts that do not fit VRAM live in 60 GiB of system RAM behind a device-side LRU, the n-gram table streams from NVMe with an 8 GiB row cache; 82 GiB of system RAM at runtime, 100 tok/s single-request decode, 323 tok/s response at 16 concurrent.
docker run --rm -it \
  --network host --shm-size 32g \
  --ulimit memlock=-1:-1 \
  --cap-add SYS_PTRACE --security-opt seccomp=unconfined \
  --device /dev/kfd --device /dev/dri \
  --group-add video \
  -v <path>/Qwen3.8-Flash-Next-MXFP4-FP8-GPTQ:/app/models \
  -v <path>/tunableop:/tunableop \
  -v <path>/lru_store:/lru_store \
  -v <nvme path>/plecache:/app/pleoffload \
  -e OMP_NUM_THREADS=8 \
  -e PYTORCH_TUNABLEOP_ENABLED=1 \
  -e PYTORCH_TUNABLEOP_TUNING=0 \
  -e PYTORCH_TUNABLEOP_RECORD_UNTUNED=0 \
  -e VLLM_ROCM_USE_AITER=0 \
  -e GPU_MAX_HW_QUEUES=1 \
  -e HSA_ENABLE_INTERRUPT=1 \
  -e HSA_ENABLE_MWAITX=1 \
  -e VLLM_PLE_CPU_OFFLOAD=1 \
  -e ROCR_VISIBLE_DEVICES=0,1 \
  tcclaviger/vllm:latest \
  /app/models \
  --tensor-parallel-size 2 \
  --enable-expert-offload \
  --expert-offload-mem 60 \
  --expert-cache-dir /lru_store \
  --ple-nvme-offload \
  --ple-nvme-dir /app/pleoffload \
  --ple-cache-gb 8 \
  --ple-cache-reuse true \
  --tool-call-parser qwen3_coder \
  --enable-auto-tool-choice \
  --max-num-seqs 16 \
  --enable-chunked-prefill \
  --max-num-batched-tokens 4096 \
  --gpu-memory-utilization 0.95 \
  --host 0.0.0.0 \
  --port 8078 \
  --kv-cache-dtype fp8 \
  --served-model-name Qwen3.8-Flash-Next \
  --max-model-len 262144 \
  --reasoning-parser qwen3 \
  --override-generation-config '{"max_tokens": 65536, "temperature": 0.8, "top_p": 0.95, "top_k": 40, "presence_penalty": 1}' \
  --compilation-config '{"cudagraph_capture_sizes": [4], "max_cudagraph_capture_size": 4}' \
  --speculative-config '{"method": "mtp", "num_speculative_tokens": 3}' \
  --hf-overrides '{"text_config": {"rope_parameters": {"rope_type": "yarn", "factor": 1.0, "original_max_position_embeddings": 262144, "mrope_section": [11, 11, 10], "mrope_interleaved": true, "partial_rotary_factor": 0.25, "rope_theta": 10000000}}}'


Full report: Next-INT6PLE-28.04.8-Throughput.pdf
Serve with tcclaviger/vllm:latest; no other image reads this checkpoint.
The MXFP4 expert and shared-expert weights were produced with activation-aware quantization: a layer-serial calibration pass over a 2M-token, 27-domain corpus at 8192-token sequences, with activation-weighted scale selection and GPTQ error feedback (256-wide blocks), the FP8 attention quantized inline so every layer's statistics were gathered through the shipped attention, and the quantized layer propagated forward through the same libr4d kernels that serve it.
The 51B n-gram (PLE) table is stored as int6 with fp16 group-32 scales, 41.6 GB against 51.3 GB for FP8 e4m3, and is served through a fused dequant kernel that is bit-exact against the fp64 reference. Against the BF16 source table its mean per-row relative L2 error is 0.0218 versus 0.0267 for FP8, 18% lower error in a 19% smaller table.
How this checkpoint was quantized (AA2)
This is the second activation-aware build. The experts were re-quantized from the BF16 source with a revised GPTQ pass; the MTP block, the int6 n-gram table and the calibrated KV scales were carried over unchanged from the first build. Every step ran inside the same tcclaviger/vllm image that serves the result, on 4 x R9700.
- Stage the source. A staging checkpoint is assembled from the BF16 Qwen3.8-Flash-Next shards with three substitutions from the previous build: the whole MTP tree, the int6 PLE n-gram table, and the calibrated FP8 KV-cache scales.
- Kernel smoke test. Two layers are quantized on a spare GPU and their outputs compared against the Hugging Face reference implementation, so the packed MXFP4 and FP8 kernels that will serve the model are proven numerically correct before the long run starts.
- Attention first. The attention projections are quantized to FP8 inline at the start of the run, so every calibration statistic gathered afterwards flows through the attention that ships.
- Calibration corpus. A 2M-token corpus spanning 27 domains (code, math, reasoning, tools, dialogue, multilingual, long books, safety, and more), cut into 232 sequences of 8192 tokens. The corpus is baked into the engine and its hash is recorded in the report.
- Layer-serial activation-aware pass, 48 layers. For each layer in order: run the calibration batch through the model as quantized so far and capture the layer's input activations; choose each MXFP4 group scale by activation weight, snapping to the nearest representable exponent above or below; run one full-row GPTQ pass over the layer with damping 0.01 so the rounding error of each column is compensated by the columns still to come; recapture and quantize a second stage for the modules that depend on the first; then propagate the now-quantized layer forward through the same libr4d kernels that serve it, so the next layer calibrates against real quantized outputs, not BF16. Routed experts that saw fewer than 256 calibration tokens fall back to plain scale selection rather than an under-determined GPTQ solve.
- Finalize. The run-time MTP exclusion is dropped from config.json and the MTP FP8 group appended; the index is verified so that every carried MTP tensor, every PLE shard and all 36 KV scales are present and point at the right files.
- Validate. The finished checkpoint is served and measured against the BF16 base at the end-of-prefill position over a frozen 994-prompt, 27-domain set that is disjoint from the calibration corpus: mean KL 0.055 and 95.2% top-1 agreement, against 0.064 and 93.3% for the static MXFP4 build and 0.086 and 93.0% for the first activation-aware build. It then ran the full IronLLM evaluation suite (throughput, 250K-context scaling, perplexity, loglikelihood accuracy, tool calling, code review, feature implementation) before publication.
What changed from the first activation-aware build: scale selection moved from a searched per-block choice to a static floor-or-ceil snap, and the GPTQ error feedback moved from 256-wide blocks to a single full-row pass per module. The gain is concentrated where the first build had regressed: grade-school and competition math, code breadth and summarization recover, while retrieval, knowledge and instruction-following domains stay at the noise floor.
# Qwen3.8-Flash-Next
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.
> [!Tip]
> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by [Qwen Cloud](https://www.qwencloud.com).
>
> In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the [Qwen3.8-Flash Overview](https://www.qwencloud.com/models/Qwen3.8-Flash).
As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next.
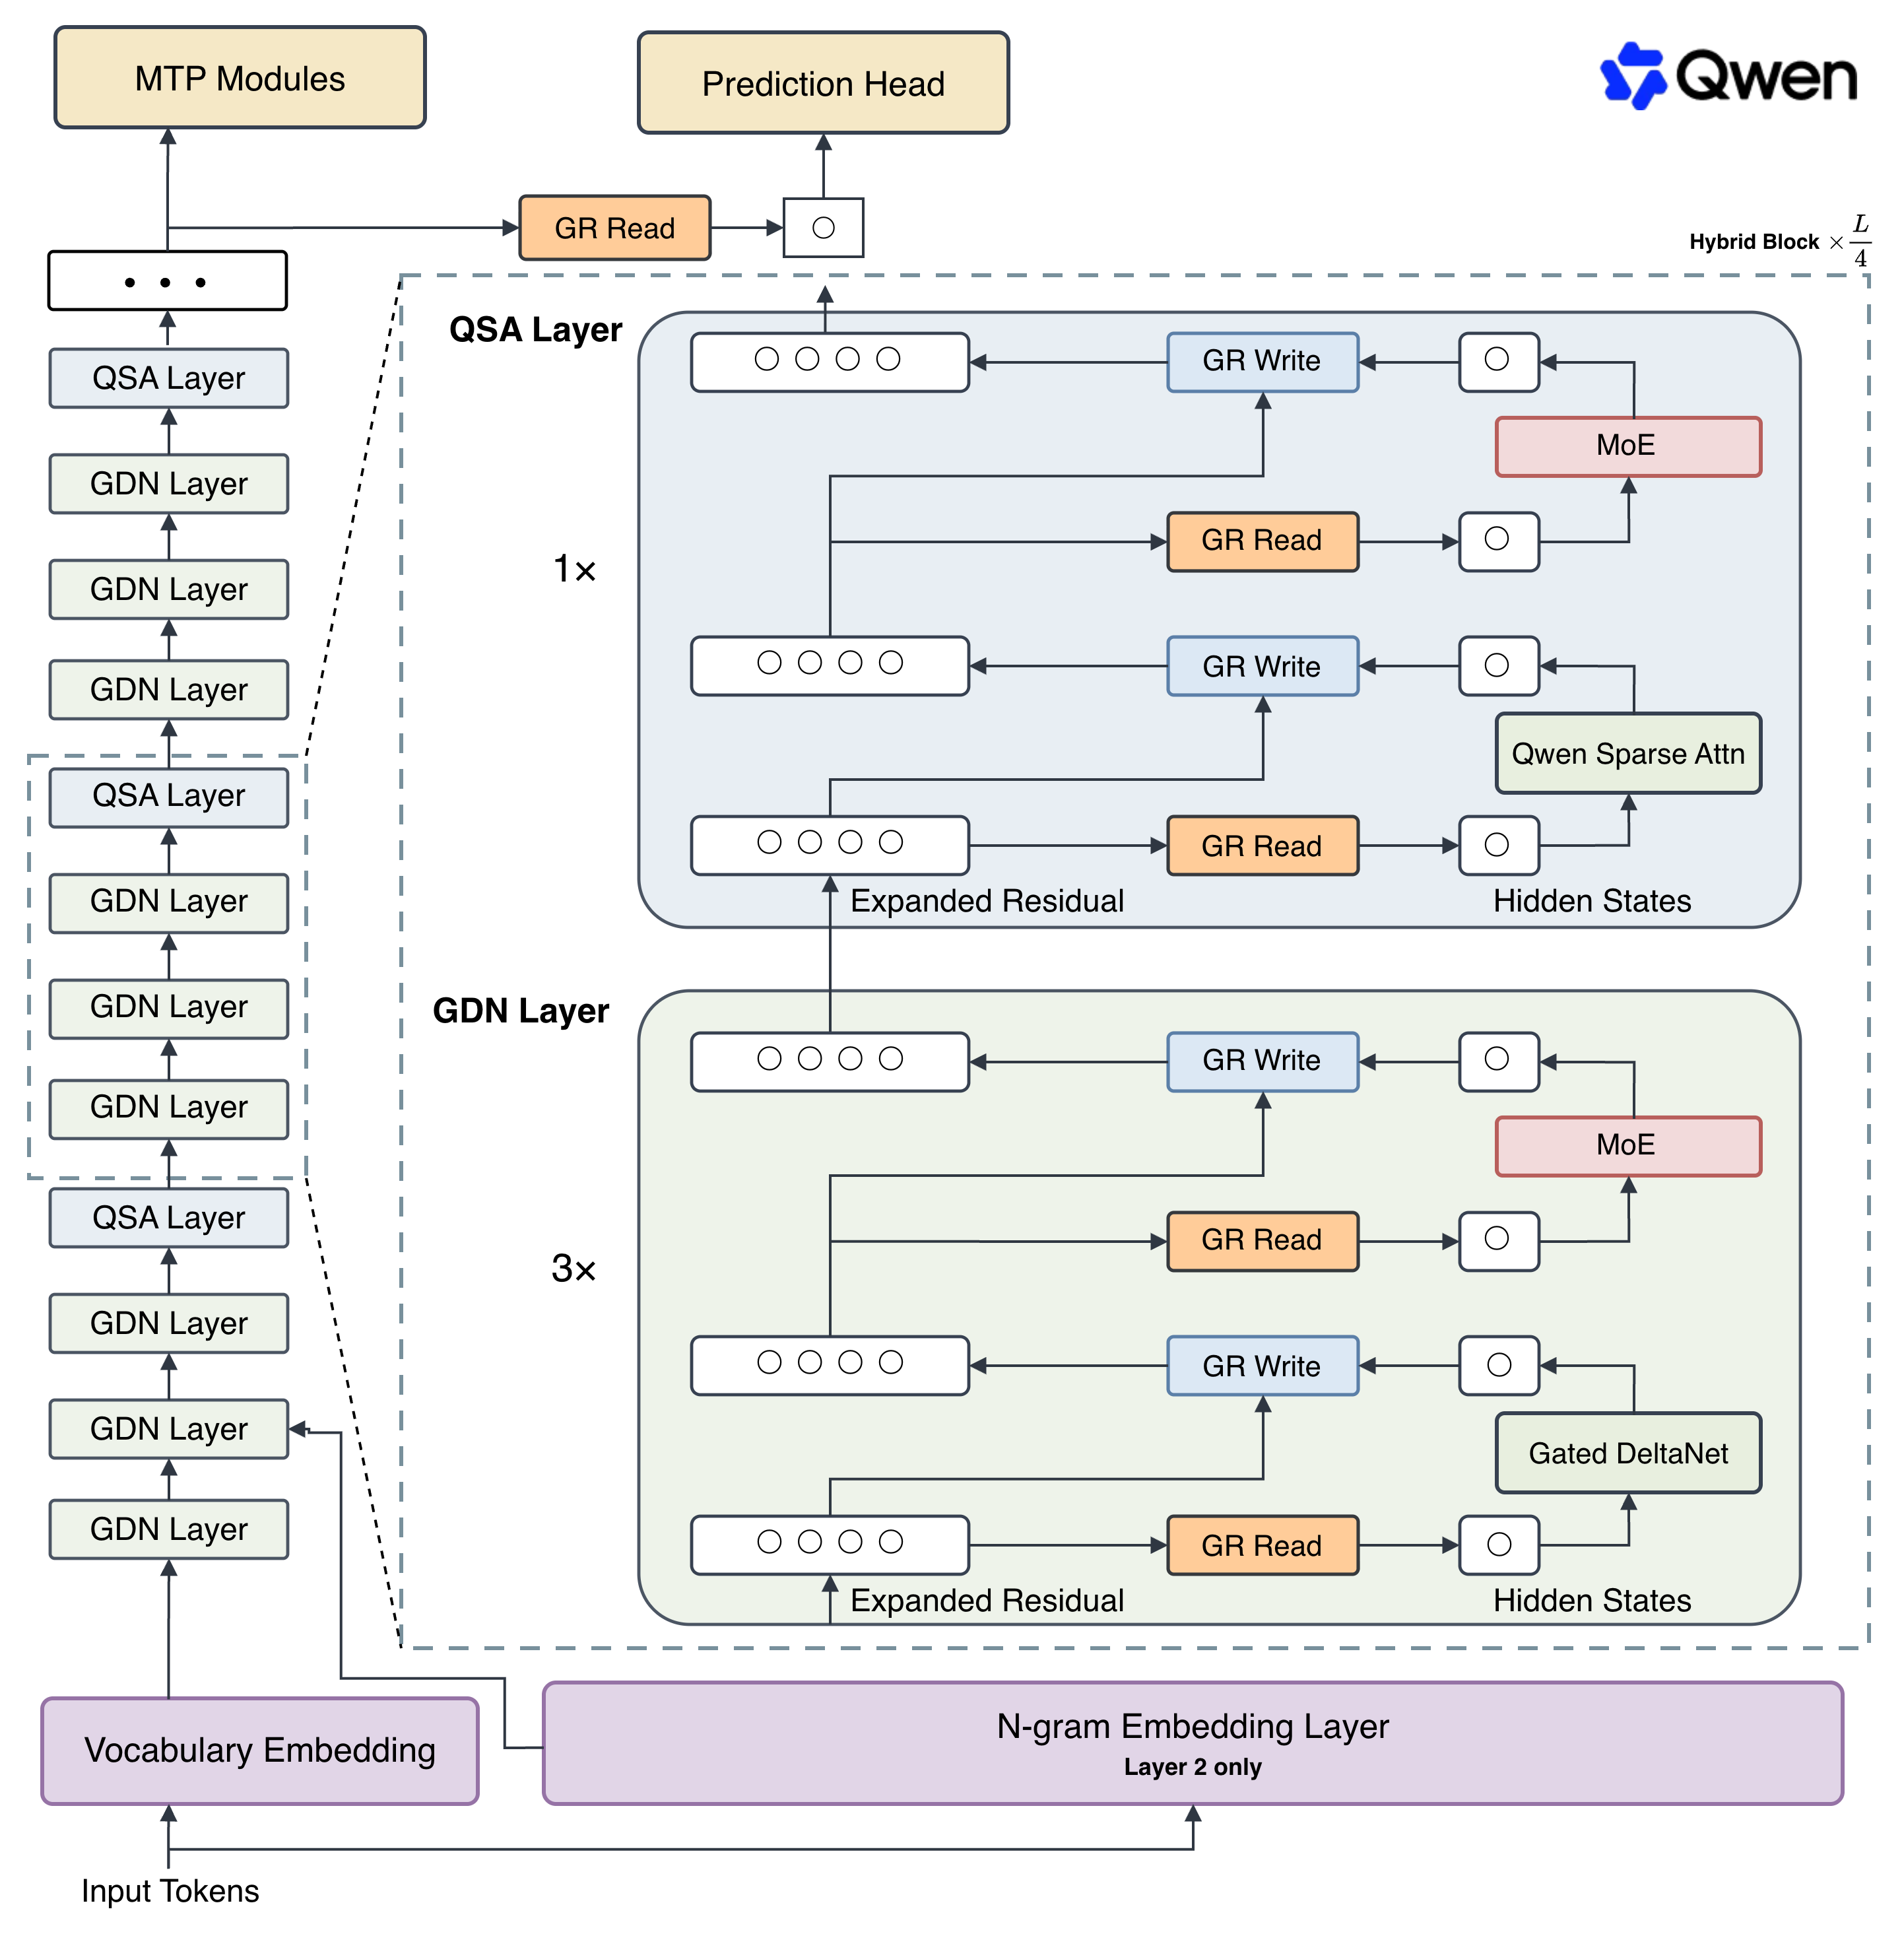
This experimental preview of the architecture that will underpin Qwen4 is built around a fundamental rethinking of how the core components of modern large language models (LLMs) interact at scale.
## Highlights
The first open-weight release under this architecture is Qwen3.8-Flash-Next, which introduces:
- **Hybrid Attention with QSA**: The Gated DeltaNet and Gated Attention pairing has been reworked into Gated DeltaNet and Qwen Sparse Attention (QSA). Rather than selecting individual tokens for processing, QSA operates at the micro-block level. This cuts long-context latency significantly, a critical gain as agentic workloads increasingly dominate real-world usage.
- **Gated Residual**: Residual streams with normalization are what make deep LLM training manageable. Gated Residual modulates information flowing through widened residual streams via an element-wise, data-dependent read gate and a per-branch scalar write gate. This brings finer-grained expressiveness across layers while preserving training stability and keeping inference overhead low.
- **N-gram Embedding**: Embeddings provide a unique axis for parameter scaling that requires less computation and is more amenable to offloading than Mixture-of-Experts (MoE). By indexing with short n-grams, this approach makes parameter scaling highly efficient for memory-constrained accelerators without sacrificing quality.
- **Tailored Training Recipe**: The Muon and AdamW optimizers are applied to specific weight categories to maximize efficiency. Guided by refitted scaling laws, we eliminate traditional batch-size warmups and start directly at the target batch size, substantially reducing total optimizer steps while safely supporting larger learning rates for robust convergence.
For more details, please refer to our blog post [Qwen3.8-Flash-Next](https://qwen.ai/blog?id=qwen3.8-flash-next) and [the technical report](https://github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_report.pdf).
We are excited to embark on this next chapter with you and welcome your feedback as we build what comes next.
## Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 125B with 6B activated, plus 51B n-gram embedding and 4B MTP
- Hidden Dimension: 2560
- Token Embedding: 248320 (Padded)
- N-gram Embedding: 20,000,000 (bigrams/trigrams at layer 2)
- Number of Layers: 48
- Hidden Layout: 12 × (3 × (Gated DeltaNet → MoE) → 1 × (Qwen Sparse Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Qwen Sparse Attention:
- Number of Attention Heads: 24 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Indexer Structure: MQA with 4 Query Heads and 1 Shared Key Head
- Indexer Head Dimension: 128
- Budget: 512 blocks or 2048 tokens
- Mixture Of Experts
- Number of Experts: 512
- Number of Activated Experts: 10 Routed + 1 Shared
- Expert Intermediate Dimension: 640
- Gated Residual:
- Number of Branches: 4
- Bottleneck Rank: 320
- LM Output: 248320 (Padded)
- MTP: 1 layer, trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,000,000 tokens.
## Benchmark Results
### Language
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | DeepSeek-V4-Flash-0731 | Claude-Opus-4.6 (Max) |
# Params |
125B |
27B |
397B |
284B |
-- |
# Activated params |
6B |
27B |
17B |
13B |
-- |
# N-gram embedding params |
51B |
-- |
-- |
-- |
-- |
| Coding |
Agentic coding DeepSWE 1.1 |
58.7 |
42.2 |
16.5 |
54.4 |
-- |
Agentic coding SWE-bench Pro |
62.5 |
61.7 |
55.8 |
56.0 |
53.4 |
Multilingual software engineering SWE-bench Multilingual |
81.0 |
73.8 |
75.8 |
-- |
77.5 |
Repo-level code generation NL2Repo-Bench |
48.1 |
42.3 |
41.1 |
54.2 |
47.6 |
| Agent |
Long-horizon office work CoWorkBench |
73.9 |
70.7 |
65.1 |
45.1 |
68.2 |
Professional job tasks JobBench |
55.7 |
33.4 |
27.6 |
41.3 |
36.6 |
Frontier agentic tasks Agents' Last Exam |
|
|
|
|
-- |
Real-world tool use Toolathlon Verified (Pass@1) |
73.5 |
67.1 |
50.6 |
70.3 |
-- |
| General |
Instruction following IFBench |
81.3 |
79.5 |
79.1 |
79.2 |
62.5 |
Scientific reasoning GPQA Diamond |
91.7 |
89.2 |
90.3 |
90.8 |
91.3 |
Multidisciplinary reasoning HLE |
35.9 |
30.8 |
34.7 |
33.8 |
40.0 |
Competitive coding LiveCodeBench v6 |
91.9 |
90.3 |
89.6 |
90.6 |
88.8 |
1. DeepSWE 1.1: evaluated with the Claude Code and mini-SWE-agent harnesses, temp=1.0, top_p=0.95, 256K context window. We report the highest score across the two harnesses; notably, Qwen3.8-Flash-Next performs best on mini-SWE-agent.
2. SWE-bench Pro: except for Claude-Opus-4.6 (Max), for which we report the officially published score, all models are evaluated with the Claude Code harness, temp=1.0, top_p=0.95, 256K context window. Problematic tasks were corrected and all baseline models were re-evaluated on the refined benchmark.
3. SWE-bench Multilingual: evaluated with the mini-SWE-agent harness, temp=1.0, top_p=0.95, 256K context window.
4. NL2Repo-Bench: evaluated with the Claude Code harness. To prevent reward hacking, we disable Bash commands that attempt to access the specific repository, such as pip download, pip install and git clone.
5. CoWorkBench: an in-house cowork benchmark for evaluating long-horizon office and productivity agent tasks across computer science, finance, law, medical and other productivity domains.
6. HLE: judged by GPT-4o.
7. The best result in each row is shown in bold.
8. Empty cells (--): scores are not yet available or are not applicable.
### Vision Language
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | Claude-Opus-4.6 (Max) |
| Agentic Multimodal Intelligence |
Multimodal tool use ClawEval-MM |
|
|
|
|
Application recreation RecreationBench |
49.9 |
47.1 |
30.2 |
-- |
Mobile use AndroidWorld |
84.5 |
81.9 |
81.0 |
62.0 |
Computer use OSWorld 2.0 |
|
|
|
-- |
Visual web development Vision2Web |
64.0 |
62.9 |
42.1 |
-- |
| General Multimodal Intelligence |
Embodied intelligence ERQA |
72.3 |
65.5 |
69.8 |
40.8 |
Long video understanding LVBench |
76.6 |
72.4 |
76.2 |
63.0 |
Real-world perception RealWorldQA |
88.5 |
85.9 |
86.9 |
73.9 |
Visual math problem solving MathVision |
|
|
|
|
Scientific chart analysis CharXiv (RQ) |
|
|
|
|
1. ClawEval-MM: scores are reported as "pass@3 / average score". Pass@3 measures the percentage passed in at least one of three trials, and the average score is the mean score across the three trials.
2. RecreationBench: an in-house long-horizon application-recreation benchmark for evaluating hybrid-agent abilities spanning five platforms — desktop (Ubuntu, macOS, Windows), mobile (Android) and web.
3. OSWorld 2.0: scores are reported as "binary / partial". The binary score is the percentage of tasks that receive the full task reward, while the partial score aggregates the partial rewards obtained across all tasks.
4. Vision2Web: scores are reported as the average over the frontend, webpage and website categories, using the Claude Code harness and judged by gpt-5.4-2026-03-05.
5. MathVision, CharXiv (RQ): scores are reported as "without CI / with CI". A small number of incorrect ground-truth annotations in MathVision were corrected after manual verification. Our model's score is evaluated using a fixed prompt, e.g. "Please reason step by step, and put your final answer within \boxed{}." For other models, we report the higher score between runs with and without the \boxed{} formatting.
6. The best result in each row is shown in bold.
7. Empty cells (--) indicate scores not yet available or not applicable.
## Quickstart
For streamlined integration, we recommend using Qwen3.8-Flash-Next via APIs.
### Serving Qwen3.8-Flash-Next
> [!Important]
> Inference efficiency and throughput vary significantly across frameworks.
> We recommend using the latest framework versions to ensure optimal performance and compatibility.
> For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
Qwen3.8-Flash-Next can be deployed with popular inference frameworks, e.g.:
- [SGLang](https://www.sglang.io/): [Qwen3.8-Flash-Next Cookbook](https://docs.sglang.io/cookbook/autoregressive/Qwen/Qwen3.8-Flash-Next)
- [vLLM](https://vllm.ai/): [Qwen3.8-Flash-Next Recipe](https://recipes.vllm.ai/Qwen/Qwen3.8-Flash-Next)
- [TokenSpeed](https://lightseek.org/tokenspeed/): [Qwen3.8-Flash-Next Recipe](https://lightseek.org/tokenspeed/recipes/models#qwen3-8-flash-next)
### API Usage
> [!Important]
> Qwen3.8-Flash-Next models operate in thinking mode by default, generating thinking content signified by `