---
license: other
license_name: blink-research
license_link: LICENSE.md
base_model: Qwen/Qwen3.5-4B
library_name: transformers
pipeline_tag: text-classification
inference: false
tags:
- decision-model
- typed-decisions
- one-pass
- option-probabilities
language:
- en
---
# blink-4b
Send a text or JSON `state` and typed questions: `choice` picks from up to 255 options, `noul` is yes/no, and `score` takes 2–10 ordered levels. Each question gets probabilities over its offered options from one forward pass, with no generated text. Long or large multi-question requests may use several batches.

**Try it:** [Space demo](https://huggingface.co/spaces/thegovind/blink) · [blink-4b](https://huggingface.co/thegovind/blink-4b) · [blink-27b](https://huggingface.co/thegovind/blink-27b) · [blink-mimo-9b](https://huggingface.co/thegovind/blink-mimo-9b) · [Source code](https://github.com/thegovind/blink) · [Docs](https://thegovind.github.io/blink/) · [API](https://thegovind.github.io/blink/api/)
## At a glance
| Attribute | Detail |
|---|---|
| Base model | [Qwen/Qwen3.5-4B](https://huggingface.co/Qwen/Qwen3.5-4B) (text model only; vision encoder and MTP head removed) |
| Weights size | 8.4 GB (bf16, 4,205,751,296 parameters) |
| Revision | v1.3 (code revision; weights identical to v1.0) |
| License | Non-commercial research only ([LICENSE.md](LICENSE.md)); base model Apache-2.0 (`LICENSE-Qwen`) |
## Results
### JevBench: public-item development proxies
| Model | Public-items proxy | Public hard (111) | Hard ECE | Probability TVD | Official JevBench v1.4 |
|---|---:|---:|---:|---:|---:|
| **blink-4b** | 76.5 | 80/111 | 0.067 | 0.226 | no official score published |
| JevK5 v0.2.0 | 76.1 | 79/111 (own runtime: 82/111) | 0.068 | 0.220 | 62.0 |
| Jev 1.13.0 | — | — | — | — | 63.3 |
The JevBench numbers are public-item development proxies, not official scores, and claim no rank or parity. Official scoring requires held-out, judge, and sealed items.
How to read the public-item numbers
- On the public hard items, blink-4b scored 80/111 and JevK5 scored 79/111 in the same runtime; JevK5's own runtime reports 82/111. No hard-accuracy advantage is claimed. blink-4b's 95% Wilson interval is 0.631–0.796, before selection effects.
- Speed comes from each row's serial run, applying JevBench's self-hosted adjustment.
- Cost uses JevBench's 4B tariff ($0.03 per million input tokens) times measured tokens per decision; not a production bill.
Breakdown by area and added benchmarks
| Area | Number of benchmarks | Skill | Raw |
|---|---:|---:|---:|
| Knowledge & Reasoning | 10 | 26.4 | 43.1 |
| Language Understanding | 10 | 47.4 | 62.7 |
| Retrieval & Classification | 7 | 36.8 | 54.7 |
| Tools & Automation | 6 | 51.6 | 60.0 |
| Arts & Human Taste | 7 | 27.2 | 46.1 |
Benchmarks added in 0.2:
| Benchmark | Metric | Requests | Answered | Raw | Skill |
|---|---|---:|---:|---:|---:|
| PhishNChips phishing decisions | accuracy | 2,000 | 2,000 | 63.6 | 27.3 |
| MMLU-Pro | accuracy | 12,032 | 12,032 | 52.1 | 46.1 |
| BBH fixed-option tasks | accuracy | 5,507 | 5,507 | 63.8 | 47.5 |
| RAGTruth response-level hallucination | F1 on hallucinated class | 2,700 | 2,700 | 66.5 | 43.1 |
| HoVer claim verification | accuracy | 4,000 | 4,000 | 63.1 | 26.2 |
| When2Call MCQ | accuracy | 3,652 | 3,652 | 62.8 | 50.3 |
| New Yorker caption matching | accuracy | 528 | 528 | 58.9 | 48.6 |
- All 151,034 scoreable requests scored across 40 counted benchmarks in five equal areas.
- Shared requests reuse 0.1 predictions; the 30,419 added requests ran with the frozen evaluated soup at temperature 1.0.
- Point estimates only; no significance, calibration, or latency claims. Do not compare with 0.1 due to edition differences.
Training-row text matches in added requests:
| Training stage | Rows in the stage | Rows matching added-request text | From MMLU-Pro | From SuperGPQA | Other |
|---|---:|---:|---:|---:|---:|
| T3 | 23,156 | 138 | 131 | 6 | 1 |
| T4 | 42,360 | 156 | 148 | 7 | 1 |
Exact normalised strings >= 30 characters shared by training rows and added requests (excluding strings in >= 20 requests). Counts reflect training rows by stage and source, not unique test questions.
Decision Index 0.1 (archived edition)
Local run of the archived 0.1 suite (132,422 requests across 37 benchmarks; 19 panel benchmarks averaged for headline index; comparison rows from 2026-09-22 leaderboard snapshot).
| Model | Size class | Decision Index 0.1 | Skill | Breadth |
|---|---|---:|---:|---:|
| **blink-4b** | 4B | 52.12 | 36.04 | 34.18 |
| Jev 1.13.0 | closed | 59.51 | 46.26 | 44.79 |
| Jevfire | 27B | 55.74 | 40.86 | 39.45 |
| JoshuaSP diffusiongemma (open-jev) | 26B-A4B | 55.56 | 40.84 | 39.19 |
| Decider 35B-A3B | 35B-A3B | 54.34 | 39.37 | 37.99 |
| Kev 9B | 9B | 50.48 | 32.96 | 30.54 |
| Kev 4B | 4B | 47.43 | 28.86 | 25.67 |
| Area | blink-4b | Jev 1.13.0 |
|---|---:|---:|
| Knowledge & Reasoning | 49.1 | 68.8 |
| Language Understanding | 61.0 | 62.3 |
| Retrieval & Classification | 30.1 | 37.0 |
| Tools & Automation | 70.2 | 73.6 |
| Arts & Human Judgment | 50.2 | 56.2 |
Per benchmark scores (19 panel benchmarks, 0.1):
| Area | Benchmark | blink-4b | Jev 1.13.0 |
|---|---|---:|---:|
| Knowledge | MMLU | 0.749 | 0.917 |
| Knowledge | GPQA Diamond | 0.372 | 0.783 |
| Knowledge | GSM8K | 0.579 | 0.799 |
| Knowledge | CRUXEval | 0.472 | 0.730 |
| Knowledge | CLadder | 0.637 | 0.726 |
| Knowledge | ChessBench | 0.135 | 0.172 |
| Language | ContractNLI | 0.761 | 0.717 |
| Language | iSarcasmEval | 0.452 | 0.505 |
| Language | VAST | 0.617 | 0.646 |
| Retrieval | BRIGHT | 0.172 | 0.187 |
| Retrieval | Amazon ESCI | 0.431 | 0.552 |
| Tools | BFCL | 0.903 | 0.958 |
| Tools | ToolRet | 0.412 | 0.450 |
| Tools | RouterBench | 0.790 | 0.799 |
| Arts | BPoMP | 0.847 | 0.906 |
| Arts | Humicroedit | 0.605 | 0.619 |
| Arts | POP909-CL | 0.034 | 0.181 |
| Arts | cfcolor | 0.581 | 0.647 |
| Arts | Habermas Machine | 0.443 | 0.459 |
Architecture and training progression
| | What ships |
|---|---|
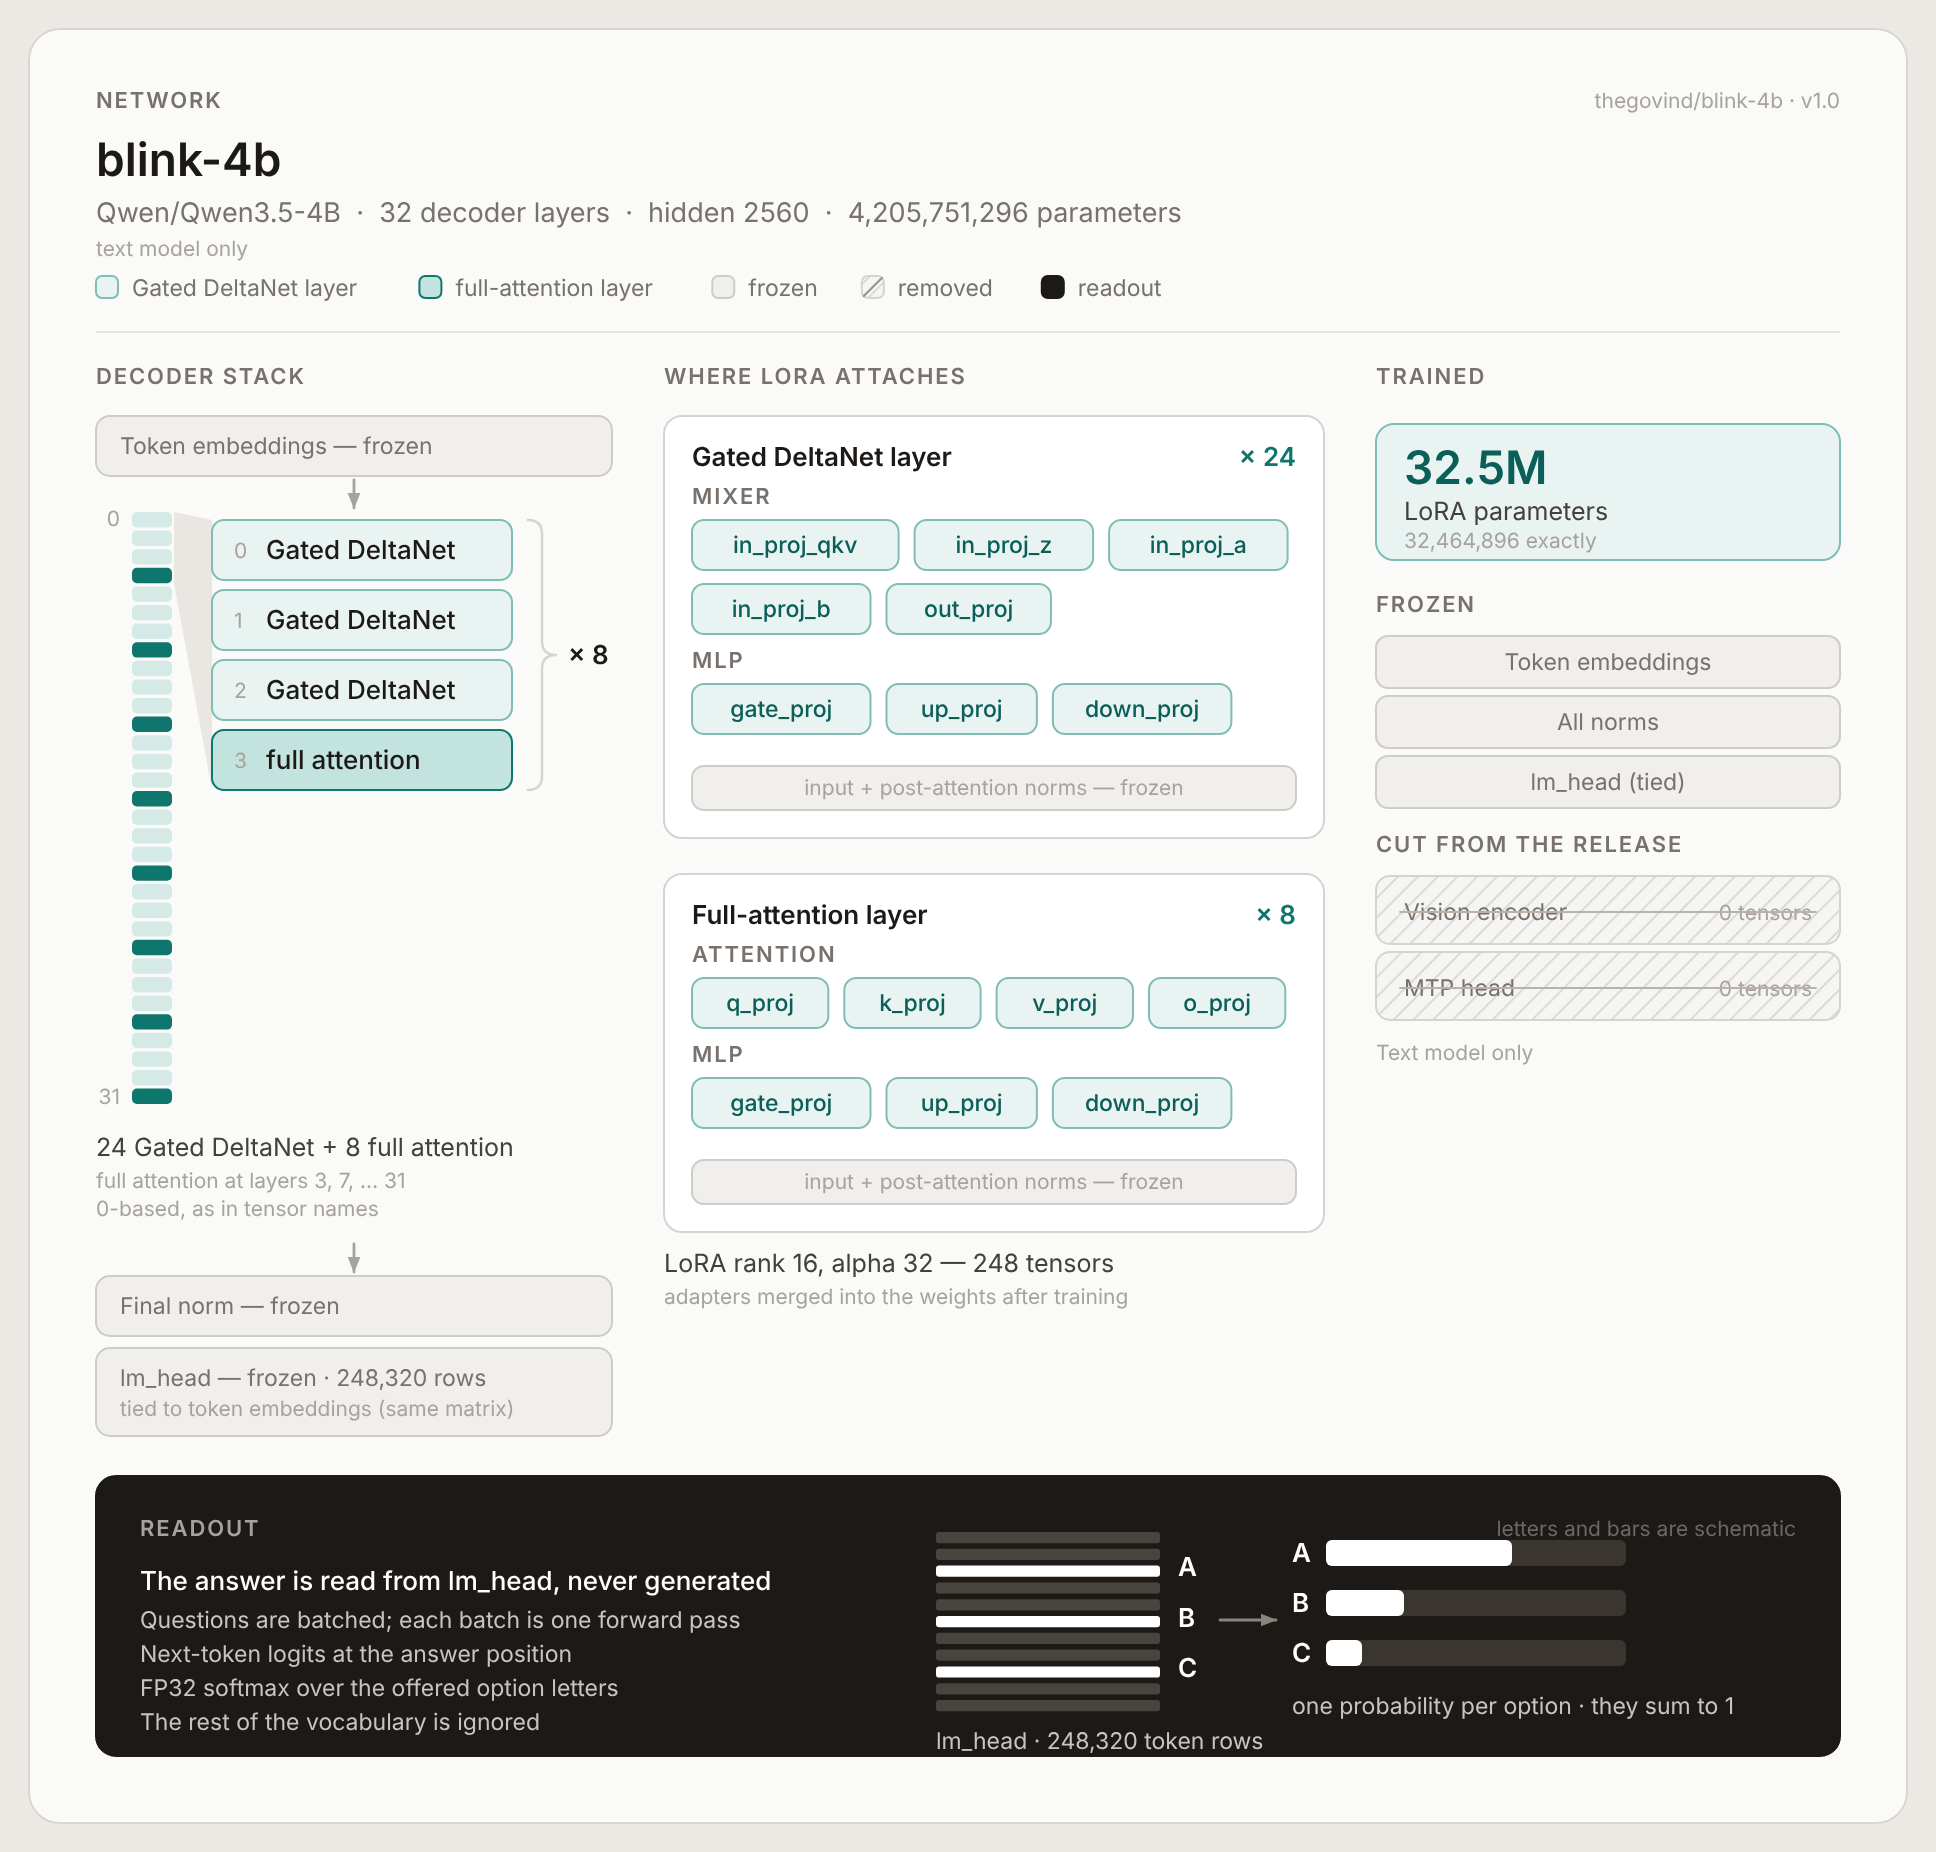
| Backbone | Qwen3.5-4B text model; 32 decoder layers (24 Gated DeltaNet, 8 full-attention), hidden 2560; 4,205,751,296 shipped text parameters |
| Tuned | 32.5M LoRA parameters, merged before averaging |
| Final weights | Uniform weight average ("soup") of T3, T4 step 300 and T4 final |
**LoRA targets (rank 16, alpha 32, every language-model layer):** full-attention `q_proj`, `k_proj`, `v_proj`, `o_proj`; Gated DeltaNet `in_proj_qkv`, `in_proj_z`, `in_proj_a`, `in_proj_b`, `out_proj`; and every MLP's `gate_proj`, `up_proj`, `down_proj`. Token embeddings, all norms and `lm_head` stayed frozen. The trained adapters were merged into the text weights.
The vision encoder and multi-token-prediction (MTP) head were cut: 0 vision tensors, 0 MTP tensors.
Readout takes next-token logits from offered option labels in `lm_head` (single tokens A–Z, then two-letter labels), computed in FP32 and softmaxed over offered letters. The rest of the vocabulary is ignored. These are option-conditional model probabilities, not certified chances of being right.
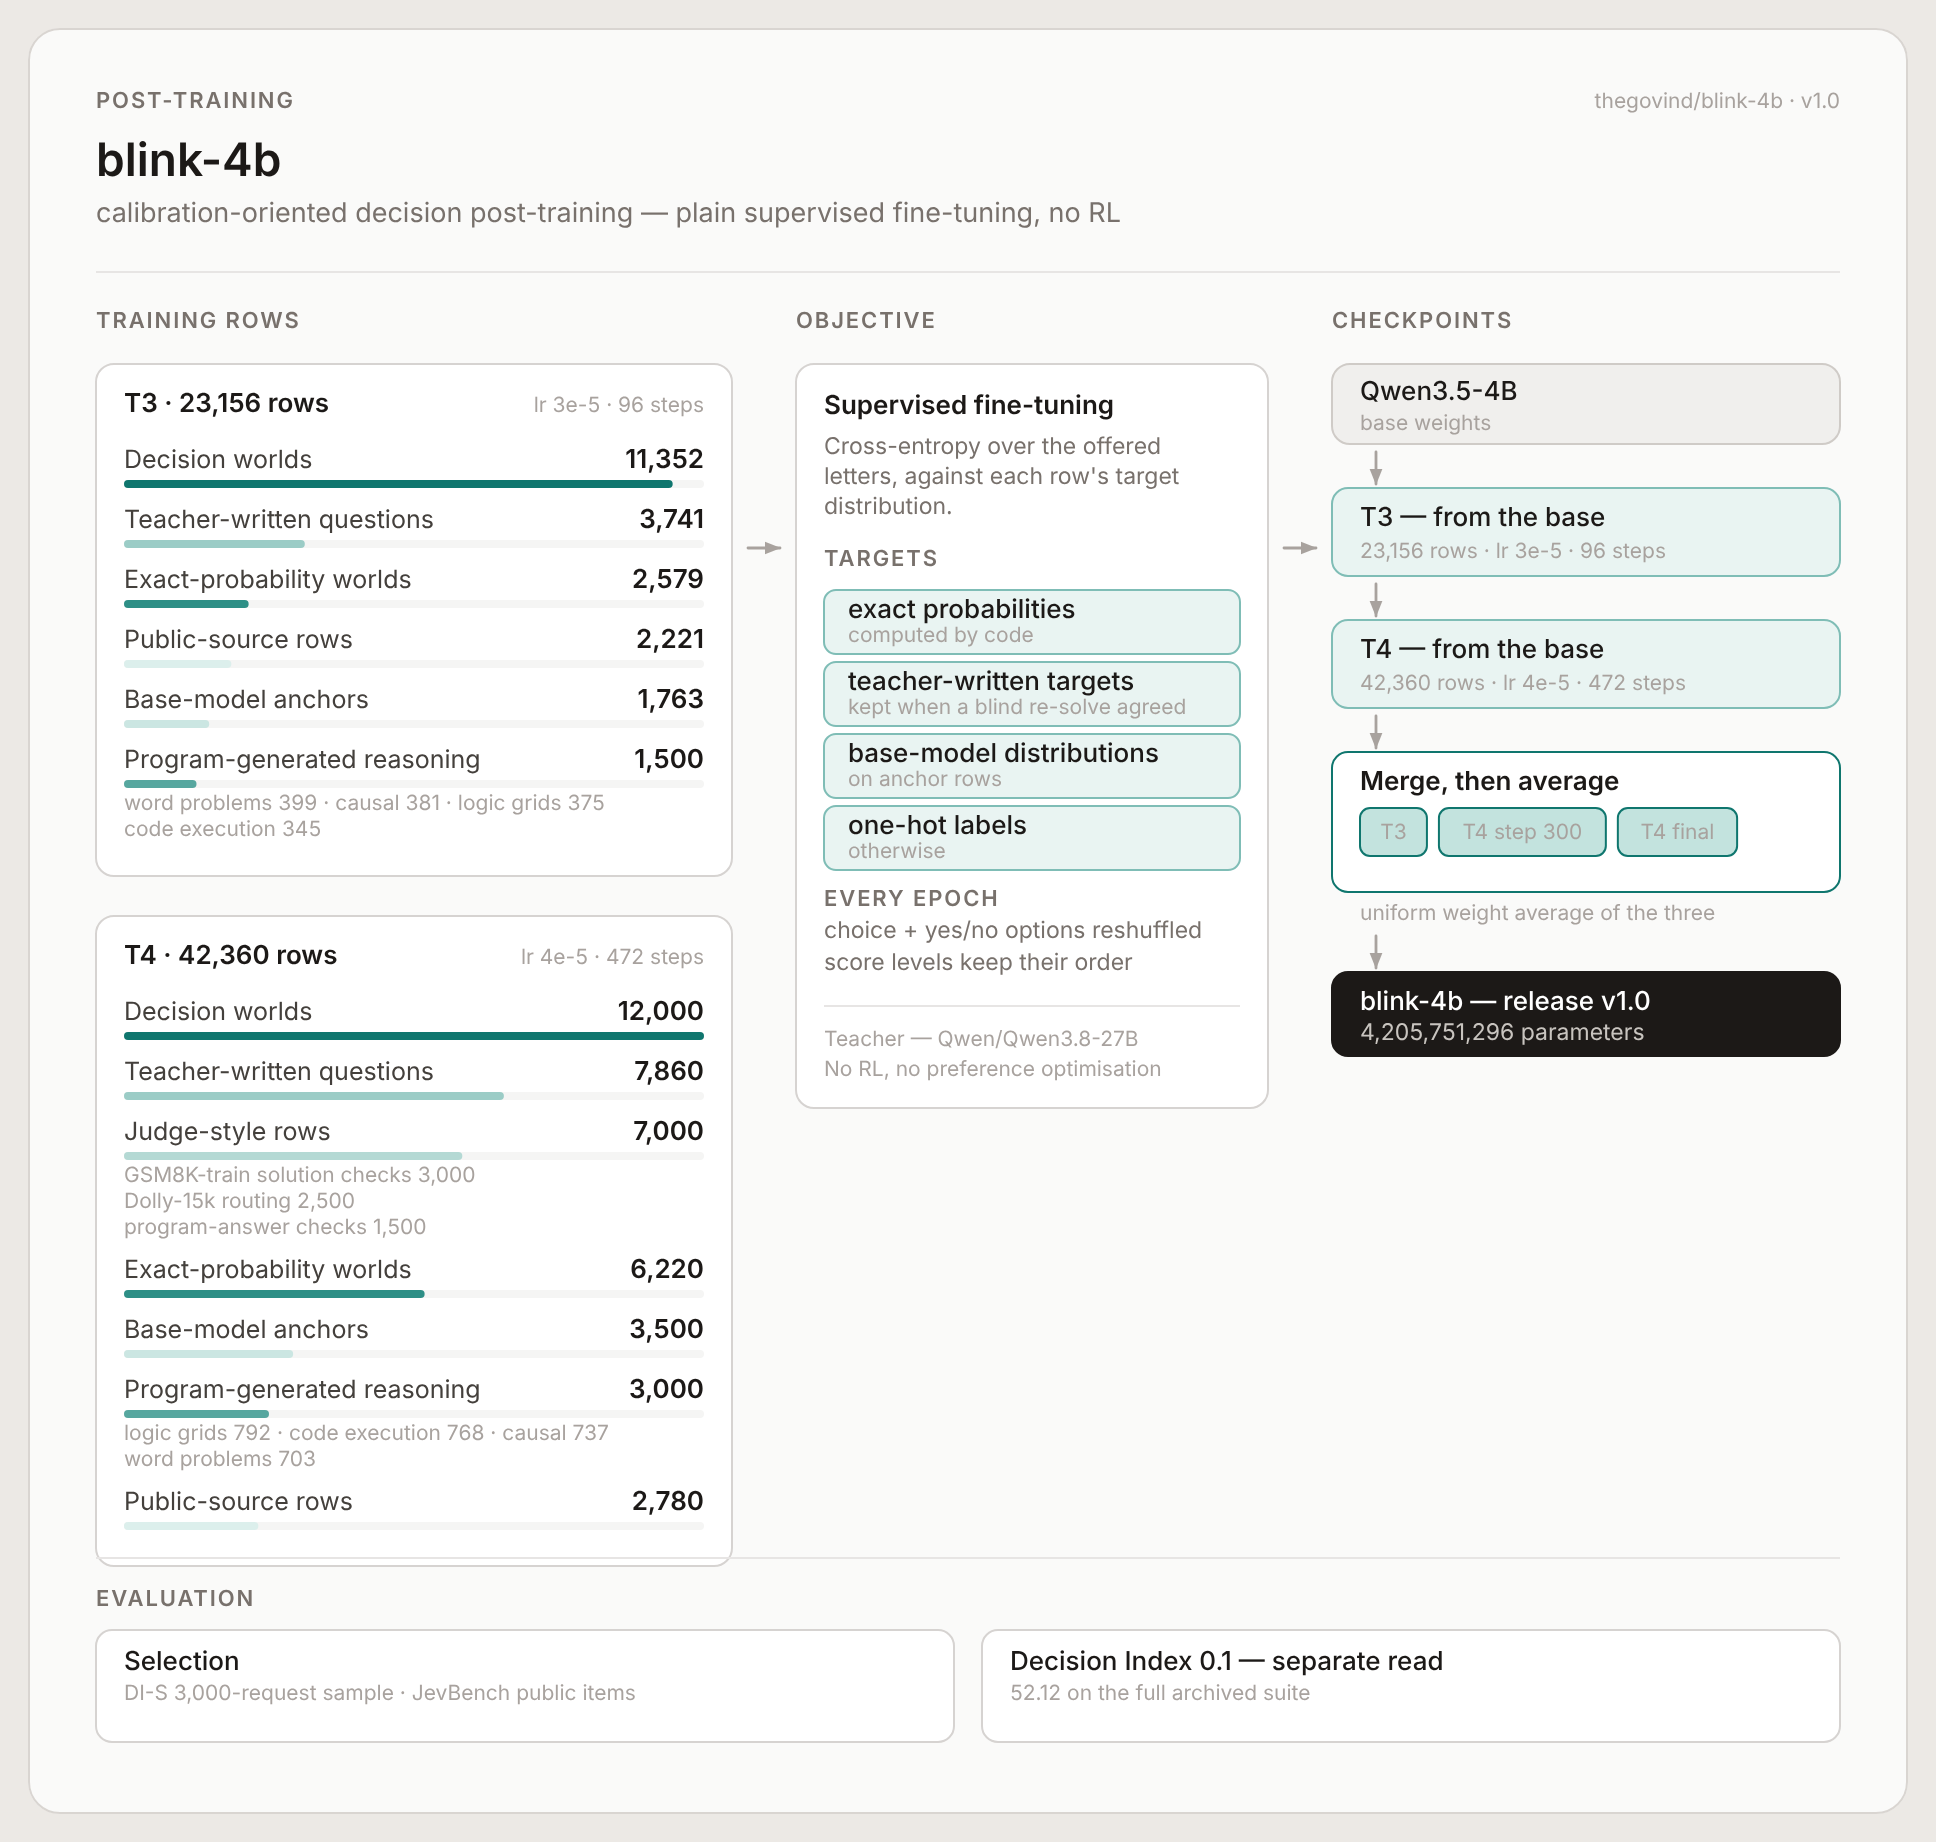
Training used supervised fine-tuning with cross-entropy against target distributions: exact probabilities, teacher-verified probabilities, or one-hot labels, plus base-model KL anchor distributions on teacher-rejected prompts. Choice and yes/no options reshuffled each epoch; score levels maintained order. No RL or preference optimization.
Training progression across steps:
| Step | DI 0.1 | Public hard | Hard ECE | Notes |
|---|---:|---:|---:|---|
| Qwen3.5-4B, zero-shot | 44.45 DI-S | 0.595 | 0.131 | Baseline before decision training. |
| T1 (106.7k rows; lr 1e-4; 355 steps) | 53.15 DI-S | 0.559 | — | Public train splits and exact-probability items lifted DI-S but hurt hard items; NLI/classification did not transfer to long documents. |
| T3 (23,156 question rows; lr 3e-5; 96 steps) | — | 0.649 | 0.089 | Restarted from base with worlds, exact probabilities, teacher-written docs, ~10% public replay, and 7.6% base anchors. |
| T4 (42,360 question rows; lr 4e-5; 472 steps) | — | 0.712 (step 300); 0.676 (final) | — | Added judge-style items; earlier checkpoint performed better on hard cases. |
| **Soup (T3 + T4 step 300 + T4 final)** | 52.12 full | 0.721 | 0.067 | Averaged three checkpoints for hard accuracy and calibration; shipped. |
Negative results: distilling 27B answers into 4B did not help on hard items; a DI-focused 4B gained +0.4 on DI-S; mixing JevK5 weights into the soup did not help; Qwen3.5-9B with the T1 recipe scored 54.5 DI-S.
Training data and data licenses
### Training data mix
| Stage | Question rows | Mix |
|---|---:|---|
| T3 | 23,156 | 11,352 decision worlds · 3,741 teacher-written question rows · 2,579 exact-probability worlds · 2,221 public-source (~10%) · 1,763 base-model anchors (7.6%) · 1,500 program-generated reasoning |
| T4 | 42,360 | 12,000 decision worlds · 7,860 teacher-written question rows · 7,000 judge-style · 6,220 exact-probability worlds · 3,500 base-model anchors (8.3%) · 3,000 program-generated reasoning · 2,780 public-source |
T4 judge-style includes 3,000 GSM8K-train solution checks, 2,500 Dolly-15k routing, and 1,500 program-answer checks. Teacher documents and typed questions were generated by Qwen3.8-27B and kept only when a blind re-solve by the same teacher agreed.
### Data sources and licences
| Source | Licence |
|---|---|
| MMLU auxiliary train, MMLU-Pro, CommonsenseQA, GSM8K | MIT |
| AQuA-RAT, Amazon ESCI | Apache-2.0 |
| MedMCQA | Apache-2.0 (dataset card) |
| SuperGPQA | ODC-BY |
| WANLI, ContractNLI, BANKING77, GPQA | CC BY 4.0 |
| ARC | CC BY-SA 4.0 |
| BoolQ, Dolly-15k | CC BY-SA 3.0 |
| ANLI | CC BY-NC 4.0 |
| SciQ | CC BY-NC 3.0 |
| iSarcasmEval | MIT (upstream repository licence) |
| VAST, Humicroedit, OpenBookQA | None stated by source |
| Code-generated worlds and teacher-written documents (Qwen3.8-27B) | See LICENSE.md |
These are source-repository licences; they do not settle rights in every underlying text.
Evaluation notes and limits
### Evaluation notes
- **Held-out and selection:** Candidate checkpoints and prompt format were selected on DI-S (3,000 requests). blink-4b was fixed using JevBench development proxies before its full-suite run. It scored 52.29 on the 129,422 requests outside DI-S. Public JevBench items (231 items) and JevK5's 65 hand-written hard items served as development selection sets; none were included in training. A one-time lockbox of 396 held-out authored items from domains unseen in any of the three checkpoints' training data (same generator families, not JevBench's sealed set) scored 0.861 accuracy and 0.026 ECE.
- **Training overlap and audit:** Public train splits also used by the 0.1 index include ContractNLI, iSarcasmEval, VAST, Amazon ESCI, Humicroedit, and GSM8K train split. ANLI and BANKING77 train splits were also used. Public sources included 281 MMLU-Pro test-partition questions and 2 GPQA extended-set questions. An audit of all question rows against the 0.1 suite and JevBench public items found no content matches (all 36 flags were the BANKING77 template); no public JevBench items or chess positions matched. The 13-word passage check didn't search long-document bodies or option text. Semantic or pretraining overlap can't be ruled out, and private JevBench items weren't available to check.
- **Temperature:** A split held out from T4 suggested T = 0.82, with negligible gain. But 166 of its 401 items were in T3 training, so it isn't held out from the released average. Temperature 1.0 is retained without fitting.
- **Limits:** English-centric (Arabic task A scored 0.313, task C pairs 0.645 on 0.1; broader multilingual ability is unestablished); does not chat or explain answers; text in state can sway answers; date arithmetic and long policies are the weakest cases. Limits: 255 options per choice, 2–10 score levels, 131,072 input tokens per question (longest evaluated prompt: 37,906 tokens) and 512 questions per request; over-limit requests get HTTP 422 with the reason, never truncated.