Instructions to use umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- llama.cpp
How to use umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF with llama.cpp:
Install (macOS, Linux)
curl -LsSf https://llama.app/install.sh | sh # Start a local OpenAI-compatible server with a web UI: llama serve -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M # Run inference directly in the terminal: llama cli -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
Install from WinGet (Windows)
winget install llama.cpp # Start a local OpenAI-compatible server with a web UI: llama serve -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M # Run inference directly in the terminal: llama cli -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
Use pre-built binary
# Download pre-built binary from: # https://github.com/ggerganov/llama.cpp/releases # Start a local OpenAI-compatible server with a web UI: ./llama-server -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M # Run inference directly in the terminal: ./llama-cli -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
Build from source code
git clone https://github.com/ggerganov/llama.cpp.git cd llama.cpp cmake -B build cmake --build build -j --target llama-server llama-cli # Start a local OpenAI-compatible server with a web UI: ./build/bin/llama-server -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M # Run inference directly in the terminal: ./build/bin/llama-cli -hf umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
Use Docker
docker model run hf.co/umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
- LM Studio
- Jan
- vLLM
How to use umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'Use Docker
docker model run hf.co/umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
- Ollama
How to use umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF with Ollama:
ollama run hf.co/umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
- Unsloth Desktop
- Docker Model Runner
How to use umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF with Docker Model Runner:
docker model run hf.co/umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
- Lemonade
How to use umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF with Lemonade:
Pull the model
# Download Lemonade from https://lemonade-server.ai/ lemonade pull umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M
Run and chat with the model
lemonade run user.Trendyol-LLM-7b-chat-v0.1-GGUF-Q4_K_M
List all available models
lemonade list
- Atomic Chat
Run and chat with the model
lemonade run user.Trendyol-LLM-7b-chat-v0.1-GGUF-Q4_K_MList all available models
lemonade list
Trendyol LLM GGUF Version
Trendyol LLM is a generative model that is based on LLaMa2 7B model. This is the repository for the quantized chat model.
Developer Umar Igan GGUF Version Created using following notebook: https://github.com/mlabonne/llm-course/blob/main/Quantize_Llama_2_models_using_GGUF_and_llama_cpp.ipynb
Variations Q5_K_M and Q4_K_M variations of GGUF.
Input Models input text only.
Output Models generate text only.
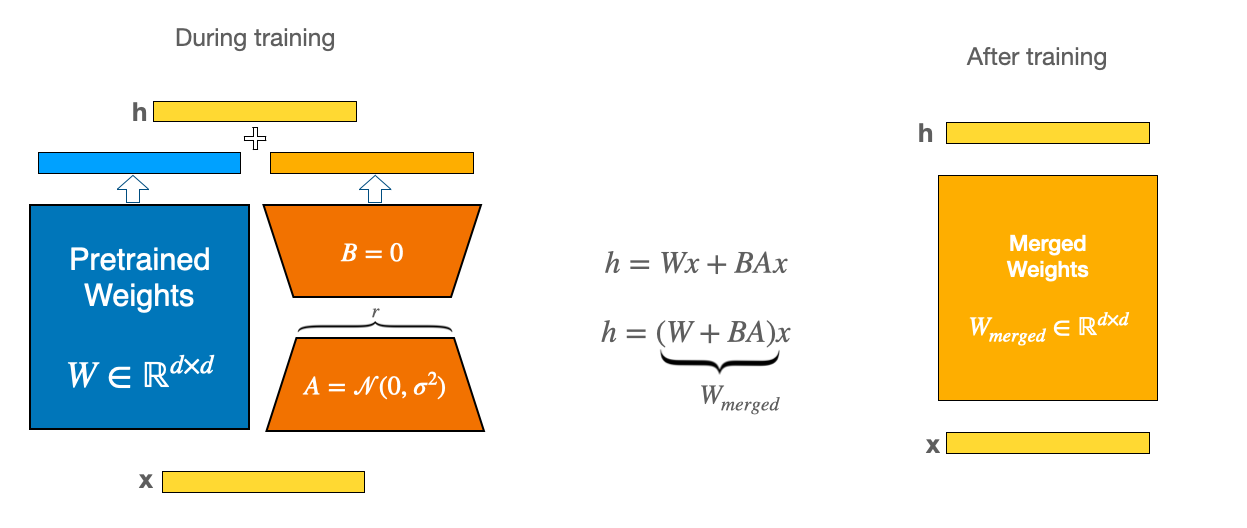
Model Architecture Trendyol LLM is an auto-regressive language model (based on LLaMa2 7b) that uses an optimized transformer architecture. The chat version is fine-tuned on 180K instruction sets with the following trainables by using LoRA This is a quantized model of Trendyol LLM:
Usage
from llama_cpp import Llama
from ctransformers import AutoModelForCausalLM
# Set gpu_layers to the number of layers to offload to GPU. Set to 0 if no GPU acceleration is available on your system.
llm_p = AutoModelForCausalLM.from_pretrained("umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF",
model_file="trendyol-llm-7b-chat-v0.1.Q4_K_M.gguf",
model_type="llama",
gpu_layers=0)
# Chat Completion API
llm = Llama(model_path=llm_p.model_path,
chat_format="llama-2") # Set chat_format according to the model you are using
llm.create_chat_completion(
messages = [
{"role": "system", "content": "çocuk hikayeleri yazan bir yazarsın"},
{
"role": "user",
"content": "köpekler hakkında bir çocuk hikayesi yaz"
}
]
)
Output:
{'id': 'chatcmpl-0d665fb2-a92a-408c-bc03-78c32bccab0d',
'object': 'chat.completion',
'created': 1707822047,
'model': '/root/.cache/huggingface/hub/models--umarigan--Trendyol-LLM-7b-chat-v0.1-GGUF/blobs/323878a8570093178040e78b438d5670c0fdae2aa614a8ed58e784d697d4db52',
'choices': [{'index': 0,
'message': {'role': 'assistant',
'content': ' Bir zamanlar, ormanda yaşayan cesur ve sadık bir köpek varmış. O, her zaman arkadaşlarına yardım etmeye hazırdı ve asla korkmuyordu. Bir gün, ormanın derinliklerinde gizemli bir ses duydu ve araştırmaya karar verdi. Yol boyunca birçok yaratıkla karşılaştı ama hiçbirinin kimliğini bilmiyordu. Sonunda, gizemli sesin geldiği yere ulaştı ve sonunda onu buldu.'},
'finish_reason': 'stop'}],
'usage': {'prompt_tokens': 39, 'completion_tokens': 85, 'total_tokens': 124}}
- Downloads last month
- 8
4-bit
5-bit
Pull the model
# Download Lemonade from https://lemonade-server.ai/lemonade pull umarigan/Trendyol-LLM-7b-chat-v0.1-GGUF:Q4_K_M