

Confidence-Aware Routing for Large Language Model Reliability Enhancement: A Multi-Signal Approach to Pre-Generation Hallucination Mitigation
Paper • 2510.01237 • Published
A calibrated typed-decision model in 16 languages: give it a state (text, ticket, policy, JSON) and a typed question — choice, boolean, or rubric score — and it returns a probability for every option in a single forward pass (~63 ms measured p50 on a 4090). No generation, no parsing, nothing to hallucinate.
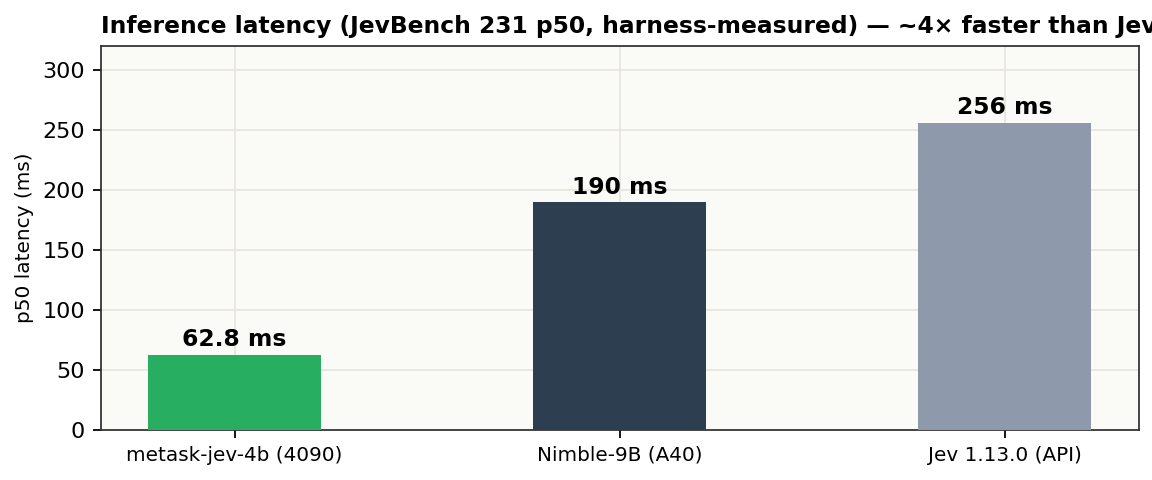
Self-measured axes inserted into the published v1.2.7 ranking (26 official entrants + this model). Official run pending — axes use our 231-decision protocol for Intelligence, val-fit temperature for Calibration, and measured production numbers for Speed/Cost: JevBench-231 p50 62.8 ms on a 4090 → adjusted 0.276 s (official ×2 + 0.15 s self-hosted formula) → S 91.2; owned-hardware cost ¥6,000/month for an 8×4090 server (this model fits twice on one card — 2×9.1 GB weights — and sustains ~20 QPS per card with dual replicas) → $105/card/month ÷ (20 QPS × 70% utilization) ≈ $0.0029 per 1,000 decisions → K 86.2 — an order of magnitude below every ranked system.

Would rank #1 — ahead of Jev 1.13.0 itself — under this estimate, and occupies the top-right corner of the Intelligence×Speed plane outright (no ranked system, open or closed, beats I 88.5 / S 91.2 on both axes):

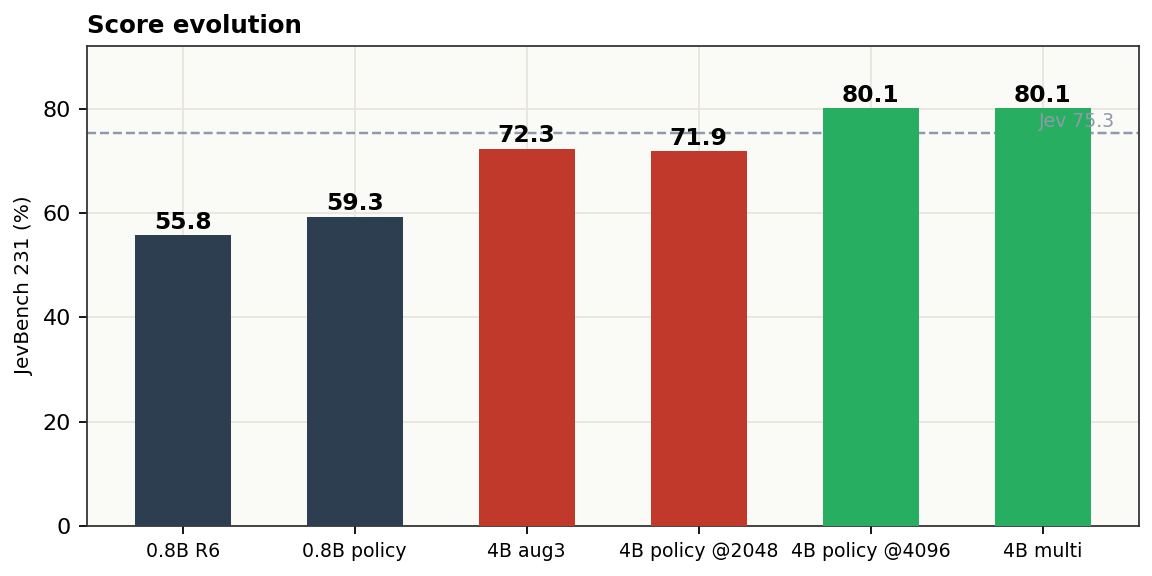
JevBench v1.2 — public 231 decisions, tier split (422-as-wrong protocol, @4096 ctx):
| tier | items | metask-jev-4b |
|---|---|---|
| judge (original) | 72 | 98.6% |
| easy | 48 | 100.0% |
| hard | 111 | 59.5% |
| total | 231 | 80.1% |
The hard tier contains long policy documents: at the 9B pipeline's 2048-token limit 36 of 111 items are rejected; this model natively handles 4096 and answers 88% of them correctly. Context length, not capability, was the bottleneck.
Native context is 262,144 tokens (max_position_embeddings); 4096 is the validated evaluation point, not an architectural limit.
Trained on MASSIVE (Amazon) utterance→domain routing in 14 additional locales beyond en/de, then evaluated on the held-out dev split (never trained on), 100 items per locale, same candidate-logit protocol:
| locale | acc | locale | acc | locale | acc | locale | acc |
|---|---|---|---|---|---|---|---|
| fr-FR | 92.0% | vi-VN | 92.0% | it-IT | 91.0% | es-ES | 90.0% |
| ja-JP | 89.0% | ko-KR | 89.0% | ru-RU | 89.0% | zh-CN | 85.0% |
| id-ID | 85.0% | nl-NL | 85.0% | tr-TR | 84.0% | ar-SA | 84.0% |
| hi-IN | 81.0% | th-TH | 66.0% | ||||
| macro (14 locales) | 85.9% |
Plus en-US (89.4% on the 13-subset suite) and de-DE (90.3%) — 16 locales total. The prompt contract is language-agnostic: state text in any supported language, same JSON schema, same temperatures.
# install: venv + deps + weights + tokenizer-contract self-test
curl -fsSL https://raw.githubusercontent.com/metask-ai/metask-jev/main/install.sh | bash

# reproduce the JevBench numbers above on your machine (easy 48 → judge 72 → hard 111,
# ~30 min on MPS, resumable; task files fetched automatically)
curl -fsSL https://raw.githubusercontent.com/metask-ai/metask-jev/main/selftest.sh | bash
Results land in ~/metask-jev/bench_results/ as per-item JSONL (prediction, probabilities, latency) with a summary table at the end. Requires an NVIDIA GPU (≥12 GB) or Apple Silicon.
from transformers import AutoTokenizer, Qwen3_5ForConditionalGeneration
import torch

model = Qwen3_5ForConditionalGeneration.from_pretrained(
    "wayfind/metask-jev-4b-policy-mix", dtype=torch.bfloat16, device_map="auto")
tok = AutoTokenizer.from_pretrained("wayfind/metask-jev-4b-policy-mix")

state = ("The store accepts returns within 30 days of purchase. "
         "This item was bought 12 days ago and is unopened.")
schema = {"decision": {
    "description": "Is the item still eligible for return?",
    "type": "boolean",                    # "enum" for choice, "boolean" for yes/no
    "choices": [False, True],
    "choice_descriptions": {"false": "Not eligible.", "true": "Eligible."},
}}

# candidate-logit readout: one forward pass, softmax over the A/B answer tokens.
# The prompt format (system + user JSON with per-option descriptions) is the
# contract the model was trained on. build_prompt comes from jev_schema.py in
# the GitHub repo (metask-ai/metask-jev, inference/ directory) — or use the
# helper library below, which handles the prompt contract for you.
prepared = build_prompt(tok, state, schema, max_input_tokens=4096)
with torch.no_grad():
    out = model(**prepared, use_cache=False, logits_to_keep=1)
logits = out.logits[:, -1, :][0]
probs = torch.softmax(logits[[tok.convert_tokens_to_ids("A"), tok.convert_tokens_to_ids("B")]] / 2.375, -1)  # noul T
print(dict(zip(["false", "true"], probs.tolist())))
Get the two dependency-free files:
curl -fsSL https://raw.githubusercontent.com/metask-ai/metask-jev/main/inference/jev_scorer.py -o jev_scorer.py
curl -fsSL https://raw.githubusercontent.com/metask-ai/metask-jev/main/inference/jev_schema.py -o jev_schema.py
from jev_scorer import load_model, score

model, tok, dev = load_model("wayfind/metask-jev-4b-policy-mix")
r = score(model, tok, state, schema, temperature=2.375)   # noul temperature
print(r["prediction"], r["probabilities"])
# True {'false': 0.013, 'true': 0.987}
Per-kind temperatures: choice 1.9 / noul 2.375 / score 2.3. Answer tokens A–Z are verified single tokens for this tokenizer at load; probabilities are a softmax over exactly those logits — the model never generates.
| metask-jev-4b | Bespoke Nimble-9B | Jev 1.13.0 | |
|---|---|---|---|
| 13 human-labeled subsets (3,880 items), macro | 78.9% | 74.8% | 76.0% |
| JevBench v1.2 public 231 @4096 ctx | 80.1% | 63.5% | 75.3 |
| JevBench Score (official-methodology estimate) | 86.4 (would rank #1) | 61.8 | 75.4 |
| MASSIVE 14-locale dev held-out macro | 85.9% | — | — |
| ECE after per-kind temperature | 0.040 | — | — |
| p50 latency (JevBench 231, 4090) | 62.8 ms | ~190 ms | 236–276 ms |
| serving cost (owned 8×4090, dual-replica 20 QPS) | $0.0029/1k | $0.166 | $0.040 |
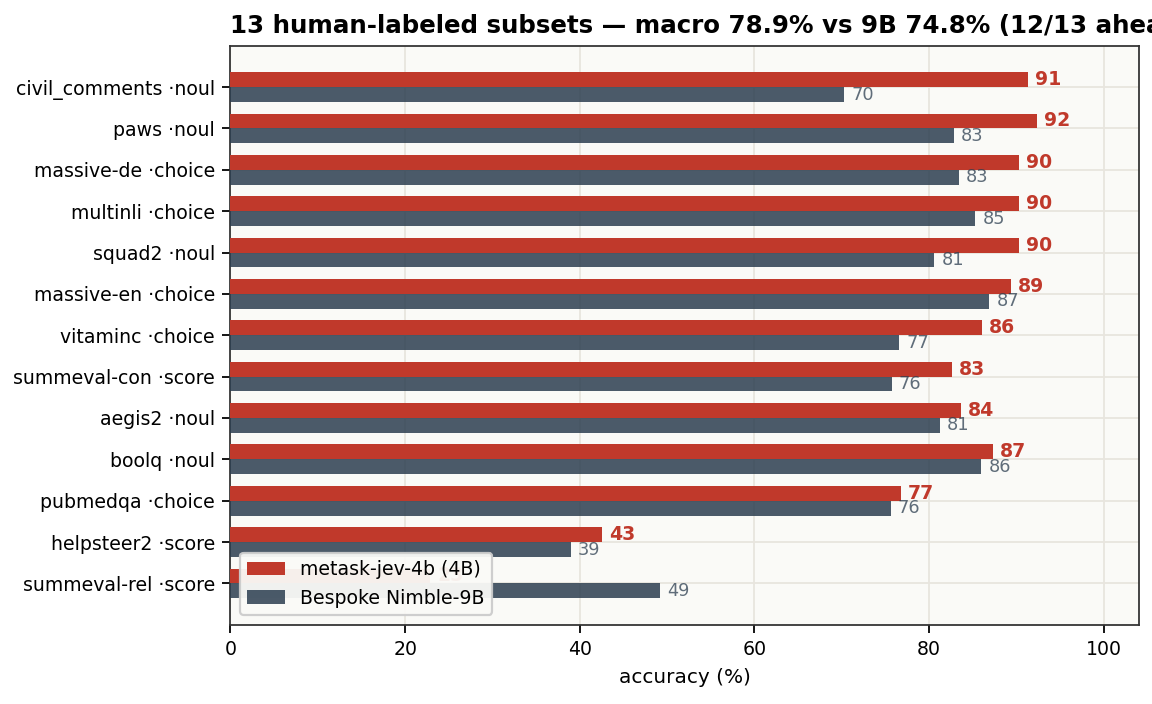
12 of 13 subsets exceed Bespoke Nimble-9B — a model 2.2× its size — same prompt format, same scoring protocol.
The primary suite: BoolQ, MultiNLI, PAWS, PubMedQA, SQuAD-2, VitaminC, Civil Comments, Aegis 2.0, MASSIVE (en/de), HelpSteer-2, SummEval (consistency / relevance). Every item human-labeled; byte-reproducible (manifest-locked ids + sha256); same protocol as the Bespoke Nimble evaluation.
| subset | type | n | metask-jev-4b | 95% CI | Nimble-9B | Δ |
|---|---|---|---|---|---|---|
| civil_comments | noul | 300 | 91.3% | 87.6–94.0 | 70.3% | +21.0 |
| paws | noul | 250 | 92.4% | 88.4–95.1 | 82.8% | +9.6 |
| squad2 | noul | 299 | 90.3% | 86.4–93.2 | 80.6% | +9.7 |
| massive-de-DE | choice | 350 | 90.3% | 86.7–93.0 | 83.4% | +6.9 |
| multinli | choice | 299 | 90.3% | 86.4–93.2 | 85.3% | +5.0 |
| massive-en-US | choice | 350 | 89.4% | 85.8–92.2 | 86.9% | +2.5 |
| boolq | noul | 300 | 87.3% | 83.1–90.6 | 86.0% | +1.3 |
| vitaminc | choice | 599 | 86.1% | 83.1–88.7 | 76.6% | +9.5 |
| summeval-consistency | score | 144 | 82.6% | 75.6–88.0 | 75.7% | +6.9 |
| aegis2 | noul | 250 | 83.6% | 78.5–87.7 | 81.2% | +2.4 |
| pubmedqa | choice | 250 | 76.8% | 71.2–81.6 | 75.6% | +1.2 |
| helpsteer2 | score | 249 | 42.6% | 36.6–48.8 | 39.0% | +3.6 |
| summeval-relevance | score | 240 | 22.9% | 18.1–28.6 | 49.2% | −26.3 |
| macro | 3,880 | 78.9% | 74.8% | +4.1 |
Wins: verification-style noul (civil +21.0, squad2 +9.7) and choice (+9.5 VitaminC). Loss: summeval-relevance — a 5-level rubric with a systematic 3↔4 boundary shift; see Honest limits.
Laya trains a 25M marker head on ModernBERT-large with RLCD (pure RL, no cross-entropy) over ~30k human-labeled decisions; its typed-decisions checkpoint reports 0.766 acc / 0.062 Brier on its own 400-case suite. Different architectures, different suites — the comparison below is indicative, not apples-to-apples.
| metask-jev-4b | laya | |
|---|---|---|
| backbone | Qwen3.5-4B (decoder, LoRA merged) | ModernBERT-large (encoder + 25M head) |
| params | 4.54B | 421M |
| context | 262,144 native (4096 validated) | 512 (root) / 1024 (typed-decisions ckpt) |
| training | SFT, candidate CE, 60.9k decisions | RLCD (proper-scoring reward), ~30k |
| raw ECE | 0.114 | 0.466 |
| ECE after temp | 0.040 | 0.081 |
| long documents (JevBench hard, ≤4096 tok) | 59.5% | not run (512–1024 ctx) |
| high-cardinality choice (77 options) | n/a (26-option cap, same as Jev) | 0.425 without tuning |
| multilingual | 16 locales in this checkpoint (85.9% dev macro) | 100+ languages (separate ckpt) |
| generative capability retained | yes (base LM) | no |
Where we win: one checkpoint covering 16 locales (laya needs a separate multilingual model), calibration out of the box (raw ECE 0.114 is far below laya's post-temperature 0.081; after our own temperature fit it is 0.040), long-context hard items (59.5% on JevBench hard — laya's 512–1024 budget cannot run that tier), and 12/13 over Nimble-9B on human-labeled data.
Where laya wins: parameter efficiency (421M vs 4.5B), breadth (100+ locales vs our 16), a mature packaging story (PyPI, Router, demo Space), and the RLCD training methodology is fully documented (arXiv:2510.01237).

Ships over-confident, like every model in this family. One temperature per question kind, fit by NLL minimization on a held-out validation split (never on eval). ECE (10 bins): 0.114 → 0.040.
| kind | T |
|---|---|
| choice | 1.9 |
| noul | 2.375 |
| score | 2.3 |

Single forward pass over the prompt, one softmax over ≤26 candidate logits.
851bf6e, LoRA r16 α32 on all language-model linear layers, merged at release.Objective and prompt format are unchanged from the official Nimble protocol; the recipe card with reproduction commands lives in the GitHub repo.
Routing, triage, moderation, guardrails, evidence-grounded verification, rubric scoring — anywhere calibrated probabilities matter more than generated explanations. Not a generative model.
Apache-2.0. Qwen3.5-4B base keeps its own terms.
Start the server (after install.sh):
curl -fsSL https://raw.githubusercontent.com/metask-ai/metask-jev/main/serve.sh | bash
# -> POST /v1/systemone on :8000, same wire format as TypeSafe Jev
Then score a decision (copy-paste ready):
curl -X POST localhost:8000/v1/systemone \
  -H "Content-Type: application/json" \
  -d '{
    "state": "The store accepts returns within 30 days of purchase. This item was bought 12 days ago and is unopened.",
    "questions": {
      "decision": {
        "type": "noul",
        "instructions": "Is the item still eligible for return?",
        "criteria": {"false": "Not eligible.", "true": "Eligible."}
      }
    }
  }'
# -> {"answers":{"decision":{"type":"noul","noul":0.944,"probabilities":{"false":0.056,"true":0.944}}}}
The numbers above come from the official JevBench harness. Two ways to reproduce on your machine (CUDA or MPS auto-detected):
Option A — self-contained runner (simplest):
git clone https://github.com/metask-ai/metask-jev && cd metask-jev
bash install.sh     # venv + deps + weights + self-test
bash selftest.sh    # all three public tiers, resumable, summary table
Or without cloning:
curl -fsSL https://raw.githubusercontent.com/metask-ai/metask-jev/main/install.sh | bash
curl -fsSL https://raw.githubusercontent.com/metask-ai/metask-jev/main/selftest.sh | bash
Option B — official harness (exact protocol used for the leaderboard):
git clone https://github.com/metask-ai/metask-jev-lab && cd metask-jev-lab/jevbench-fork
pip install -e .
export METASK_JEV_MODEL_PATH=$(cat ~/metask-jev/model_path.txt)          # weights from install.sh
# the vendored nimble package ships inside this fork (jevbench/vendors/metask_jev/) — no env needed
# (set METASK_JEV_NIMBLE_PACKAGE only to override with a full nimble checkout)

for tier in easy original hard; do
  python -m jevbench.cli run --tasks datasets/public/$tier.jsonl \
    --adapter metask_jev --results ~/metask-jev/bench_results/$tier.jsonl \
    --cost-basis local_gpu_no_provider_tariff
done
(metask_jev adapter is pre-registered in this fork; PR #17 upstreams it to the official repo.)