


Commit ·
aeac2c6
0
Parent(s):
Initial release
Browse filesCo-authored-by: timka-byzov <timka-byzov@users.noreply.huggingface.co>
Co-authored-by: edgarshmavonyan <edgarshmavonyan@users.noreply.huggingface.co>
Co-authored-by: MaximNikitin08 <MaximNikitin08@users.noreply.huggingface.co>
Co-authored-by: IrinaLialikova <IrinaLialikova@users.noreply.huggingface.co>
This view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +36 -0
- CONTRIBUTING.md +31 -0
- LICENSE +13 -0
- NOTICES +8 -0
- README.md +294 -0
- README_en.md +292 -0
- assets/benchmarks.png +3 -0
- config.json +58 -0
- configuration_alice_ai.py +109 -0
- finetune/chat_template.jinja +94 -0
- finetune/finetune_lora.py +274 -0
- model-00001-of-00049.safetensors +3 -0
- model-00002-of-00049.safetensors +3 -0
- model-00003-of-00049.safetensors +3 -0
- model-00004-of-00049.safetensors +3 -0
- model-00005-of-00049.safetensors +3 -0
- model-00006-of-00049.safetensors +3 -0
- model-00007-of-00049.safetensors +3 -0
- model-00008-of-00049.safetensors +3 -0
- model-00009-of-00049.safetensors +3 -0
- model-00010-of-00049.safetensors +3 -0
- model-00011-of-00049.safetensors +3 -0
- model-00012-of-00049.safetensors +3 -0
- model-00013-of-00049.safetensors +3 -0
- model-00014-of-00049.safetensors +3 -0
- model-00015-of-00049.safetensors +3 -0
- model-00016-of-00049.safetensors +3 -0
- model-00017-of-00049.safetensors +3 -0
- model-00018-of-00049.safetensors +3 -0
- model-00019-of-00049.safetensors +3 -0
- model-00020-of-00049.safetensors +3 -0
- model-00021-of-00049.safetensors +3 -0
- model-00022-of-00049.safetensors +3 -0
- model-00023-of-00049.safetensors +3 -0
- model-00024-of-00049.safetensors +3 -0
- model-00025-of-00049.safetensors +3 -0
- model-00026-of-00049.safetensors +3 -0
- model-00027-of-00049.safetensors +3 -0
- model-00028-of-00049.safetensors +3 -0
- model-00029-of-00049.safetensors +3 -0
- model-00030-of-00049.safetensors +3 -0
- model-00031-of-00049.safetensors +3 -0
- model-00032-of-00049.safetensors +3 -0
- model-00033-of-00049.safetensors +3 -0
- model-00034-of-00049.safetensors +3 -0
- model-00035-of-00049.safetensors +3 -0
- model-00036-of-00049.safetensors +3 -0
- model-00037-of-00049.safetensors +3 -0
- model-00038-of-00049.safetensors +3 -0
- model-00039-of-00049.safetensors +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
benchmarks.png filter=lfs diff=lfs merge=lfs -text
|
CONTRIBUTING.md
ADDED
|
@@ -0,0 +1,31 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
## Notice to external contributors
|
| 2 |
+
### General info
|
| 3 |
+
Hello! In order for us (YANDEX LLC) to accept patches and other contributions from you, you will have to adopt our Contributor License Agreement (the “CLA”). The current version of the CLA you may find here:
|
| 4 |
+
|
| 5 |
+
* https://yandex.ru/legal/cla/en/ (in English) and
|
| 6 |
+
* https://yandex.ru/legal/cla/ru/ (in Russian).
|
| 7 |
+
|
| 8 |
+
By adopting the CLA, you state the following:
|
| 9 |
+
|
| 10 |
+
* You obviously wish and are willingly licensing your contributions to us for our open source projects under the terms of the CLA,
|
| 11 |
+
* You have read the terms and conditions of the CLA and agree with them in full,
|
| 12 |
+
* You are legally able to provide and license your contributions as stated,
|
| 13 |
+
* We may use your contributions for our open source projects and for any other our project too,
|
| 14 |
+
* We rely on your assurances concerning the rights of third parties in relation to your contributions.
|
| 15 |
+
|
| 16 |
+
If you agree with these principles, please read and adopt our CLA. By providing us your contributions, you hereby declare that you have read and adopted our CLA, and we may freely merge your contributions with our corresponding open source project and use it in further in accordance with terms and conditions of the CLA.
|
| 17 |
+
|
| 18 |
+
### Provide contributions
|
| 19 |
+
|
| 20 |
+
If you have adopted terms and conditions of the CLA, you are able to provide your contributions. When you submit your pull request, please add the following information into it:
|
| 21 |
+
|
| 22 |
+
I hereby agree to the terms of the CLA available at: [link].
|
| 23 |
+
|
| 24 |
+
Replace the bracketed text as follows:
|
| 25 |
+
|
| 26 |
+
* [link] is the link at the current version of the CLA (you may add here a link https://yandex.ru/legal/cla/?lang=en (in English) or a link https://yandex.ru/legal/cla/?lang=ru (in Russian).
|
| 27 |
+
|
| 28 |
+
It is enough to provide us with such notification once.
|
| 29 |
+
|
| 30 |
+
### Other questions
|
| 31 |
+
If you have any questions, please write us at opensource-support@yandex-team.ru.
|
LICENSE
ADDED
|
@@ -0,0 +1,13 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Copyright 2026 YANDEX LLC
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
you may not use this file except in compliance with the License.
|
| 5 |
+
You may obtain a copy of the License at
|
| 6 |
+
|
| 7 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
|
| 9 |
+
Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
See the License for the specific language governing permissions and
|
| 13 |
+
limitations under the License.
|
NOTICES
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
-------------------------------------------------------------------------------
|
| 2 |
+
Export control notice
|
| 3 |
+
-------------------------------------------------------------------------------
|
| 4 |
+
|
| 5 |
+
It is necessary to comply with the applicable export control laws and
|
| 6 |
+
regulations. We declare that we comply with the applicable export control laws
|
| 7 |
+
and regulations for the published software, and we expect the users of the
|
| 8 |
+
software and the contributors to it to be compliant with them as well.
|
README.md
ADDED
|
@@ -0,0 +1,294 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
language:
|
| 4 |
+
- ru
|
| 5 |
+
- en
|
| 6 |
+
library_name: transformers
|
| 7 |
+
pipeline_tag: text-generation
|
| 8 |
+
tags:
|
| 9 |
+
- custom_code
|
| 10 |
+
- mixture-of-experts
|
| 11 |
+
- vllm
|
| 12 |
+
---
|
| 13 |
+
|
| 14 |
+
# AliceAI-Foundation-80B-A3B-Base
|
| 15 |
+
|
| 16 |
+
[English version](./README_en.md)
|
| 17 |
+
|
| 18 |
+
AliceAI-Foundation-80B-A3B-Base – базовая языковая модель с гибридной
|
| 19 |
+
архитектурой и MoE-слоями. Модель содержит 80 млрд параметров, из которых для каждого токена активируются 3 млрд, и поддерживает контекст длиной до 262 144 токенов. Модель была обучена полностью с нуля.
|
| 20 |
+
|
| 21 |
+
При создании модели мы заново собрали обучающий корпус, выбрали архитектуру и
|
| 22 |
+
гиперпараметры, а также подготовили данные для сложных рассуждений и
|
| 23 |
+
взаимодействия с инструментами. Ключевые решения проверялись в серии отдельных
|
| 24 |
+
обучений с нуля объёмом по 2 трлн токенов каждое.
|
| 25 |
+
|
| 26 |
+
В математике, программировании и других задачах на рассуждения модель показывает результаты на уровне более крупных опенсорс-моделей, а особенно сильна в задачах на фактические знания на русском языке. Вместе с весами мы публикуем фактологические бенчмарки
|
| 27 |
+
[WikiWebFacts](https://huggingface.co/datasets/yandex/WikiWebFacts) и
|
| 28 |
+
[HardMultiQA](https://huggingface.co/datasets/yandex/HardMultiQA), ориентированные на
|
| 29 |
+
русскоязычный контекст, и протоколы их оценки.
|
| 30 |
+
|
| 31 |
+
<img src="./assets/benchmarks.png" alt="Сравнение по бенчмаркам" width="800">
|
| 32 |
+
|
| 33 |
+
## Обзор модели
|
| 34 |
+
|
| 35 |
+
- Тип: авторегрессионная языковая модель
|
| 36 |
+
- Этап обучения: предобучение
|
| 37 |
+
- Языковая модель
|
| 38 |
+
- Количетсво параметров: 80B всего, 3B активных
|
| 39 |
+
- Рзамер скрытого состояния: 2048
|
| 40 |
+
- Размер словаря: 129024
|
| 41 |
+
- Количество слоев: 48
|
| 42 |
+
- Схема слоёв: 12 × (3 × (KDA → MoE) → 1 × (Gated Attention → MoE))
|
| 43 |
+
- KDA:
|
| 44 |
+
- Количество query-голов: 32
|
| 45 |
+
- Количество KV-голов: 32
|
| 46 |
+
- Размерность query-головы: 128
|
| 47 |
+
- Размерность KV-головы: 128
|
| 48 |
+
- Рамер ядра свертки: 4
|
| 49 |
+
- Gated Attention:
|
| 50 |
+
- Количество query-голов: 16
|
| 51 |
+
- Количество KV-голов: 2
|
| 52 |
+
- Размерность query-головы: 256
|
| 53 |
+
- MoE:
|
| 54 |
+
- Количество экспертов: 512
|
| 55 |
+
- Top-K: 10 + 1 общий эксперт
|
| 56 |
+
- Промежуточная размерность эксперта: 512
|
| 57 |
+
- MTP: 1 слой
|
| 58 |
+
- Длина контекста: 262144
|
| 59 |
+
|
| 60 |
+
## Бенчмарки
|
| 61 |
+
|
| 62 |
+
<div style="font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,sans-serif;max-width:1000px;margin:0 auto;padding:16px 0">
|
| 63 |
+
<p style="margin:0 0 12px;font-size:13px;line-height:1.5">Названия русскоязычных бенчмарков выделены <span style="color:#27834a;font-weight:600">зелёным</span>, англоязычных — <span style="color:#496fa8;font-weight:600">синим</span>.</p>
|
| 64 |
+
<p style="margin:0 0 14px;font-size:13px;line-height:1.5">Все замеры в этом разделе проведены во внутренней инфраструктуре замеров, инференс в фреймворке vllm с t=0 для всех моделей. Жирным выделен победитель в каждой строчке.</p>
|
| 65 |
+
<table style="width:100%;table-layout:fixed;border-collapse:collapse;font-size:13px">
|
| 66 |
+
<colgroup>
|
| 67 |
+
<col style="width:25%">
|
| 68 |
+
<col span="5" style="width:15%">
|
| 69 |
+
</colgroup>
|
| 70 |
+
<thead><tr><th style="padding:10px 7px;text-align:left;font-weight:600;border-bottom:2px solid #d6a15f;color:#b7791f">Бенчмарк</th>
|
| 71 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">AliceAI-Foundation-80B-A3B-Base</th>
|
| 72 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Qwen3.5-35B-A3B-Base</th>
|
| 73 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">GLM-4.5-Air-Base (106B-A12B)</th>
|
| 74 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Nemotron-3-Super-120B-A12B-Base</th>
|
| 75 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">DeepSeek-V4-Flash-Base (284B-A13B)</th></tr></thead>
|
| 76 |
+
<tbody>
|
| 77 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Факты</td></tr>
|
| 78 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">WikiWebFacts</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк на знание фактов на русском языке.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>86.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">62.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">70.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">72.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">83.2</td></tr>
|
| 79 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">HardMultiQA</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк на знание фактов на русском языке.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>67.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">47.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">48.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">54.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">65.4</td></tr>
|
| 80 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">CultCat</summary><div style="padding-top:6px;line-height:1.4">4-shot, бенчмарк на знание культурных фактов. Подробнее — в <a href="https://habr.com/ru/companies/yandex/articles/868282/">статье на Хабре</a>.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>86.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.1</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">80.7</td></tr>
|
| 81 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">TriviaQA</summary><div style="padding-top:6px;line-height:1.4">5-shot, открытый бенчмарк на знание фактов на английском языке; вместо метрики Exact Match используется LLM-as-a-judge.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">79.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">83.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>89.8</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">89.4</td></tr>
|
| 82 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Образовательные бенчмарки</td></tr>
|
| 83 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Russian</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк образования, собранный на основе запросов к Алисе.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>74.2</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">42.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">39.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">44.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">67.7</td></tr>
|
| 84 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Literature</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк образования, собранный на основе запросов к Алисе.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>73.8</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">55.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">69.1</td></tr>
|
| 85 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench History</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк образования, собранный на основе запросов к Алисе.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>82.0</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">65.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">62.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">70.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">76.9</td></tr>
|
| 86 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench English</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк образования, собранный на основе запросов к Алисе.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">76.1</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">67.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>82.9</strong></td></tr>
|
| 87 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Экспертные знания</td></tr>
|
| 88 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">ExpertFactsQA Medicine</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк на фактические знания, составленный профильными экспертами.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>63.6</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">42.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">60.7</td></tr>
|
| 89 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">ExpertFactsQA Law</summary><div style="padding-top:6px;line-height:1.4">Сложный 5-shot, бенчмарк на фактические знания, составленный профильными экспертами.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>49.6</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">27.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">22.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">24.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">40.5</td></tr>
|
| 90 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Экзамены</td></tr>
|
| 91 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EGE CoT</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк из заданий части А ЕГЭ по различным предметам.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>90.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">77.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">90.3</td></tr>
|
| 92 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">MMLU-Pro CoT</summary><div style="padding-top:6px;line-height:1.4">5-shot, открытый бенчмарк на знания и рассуждения по широкому набору предметов на английском языке.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">63.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">58.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>69.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.5</td></tr>
|
| 93 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">SuperGPQA CoT</summary><div style="padding-top:6px;line-height:1.4">5-shot, открытый бенчмарк с вопросами, составленными экспертами из разных научных областей.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">44.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">43.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">35.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>46.6</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">46.1</td></tr>
|
| 94 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Математика</td></tr>
|
| 95 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">MATH-500</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк с математическими задачами; используется LLM-as-a-judge и более длинные рассуждения в few-shot-примерах.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>91.1</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">81.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">60.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">80.7</td></tr>
|
| 96 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Math</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк образования, собранный на основе запросов к Алисе</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">79.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>80.0</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">56.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">69.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">76.3</td></tr>
|
| 97 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Math University</summary><div style="padding-top:6px;line-height:1.4">5-shot, бенчмарк образования, собранный на основе запросов к Алисе.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>70.1</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">69.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">67.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">68.6</td></tr>
|
| 98 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Код</td></tr>
|
| 99 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">BigCodeBench 1-shot pass@1</summary><div style="padding-top:6px;line-height:1.4">1-shot, наша реализация BigCodeBench с улучшенными тестами.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">48.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">43.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">44.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">48.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>49.1</strong></td></tr>
|
| 100 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LiveCodeBench v5-6 CoT 1-shot pass@1</summary><div style="padding-top:6px;line-height:1.4">1-shot, открытый бенчмарк со сложными задачами по программированию, в которых требуется найти алгоритм и реализовать его в коде.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>50.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">22.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">38.1</td></tr>
|
| 101 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Длинный контекст</td></tr>
|
| 102 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">FinQA 128k</summary><div style="padding-top:6px;line-height:1.4">5-shot, длинная модификация опенсорсного FinQA, задачи на аналитику по финансовым отчётам.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>74.1</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">73.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">35.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>74.1</strong></td></tr>
|
| 103 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LongMemEval 128k</summary><div style="padding-top:6px;line-height:1.4">5-shot, открытый бенчмарк с задачами на поиск и использование информации из длинной истории диалога.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">64.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">55.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">64.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>68.0</strong></td></tr>
|
| 104 |
+
</tbody>
|
| 105 |
+
</table>
|
| 106 |
+
</div>
|
| 107 |
+
|
| 108 |
+
<div style="font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,sans-serif;max-width:1000px;margin:0 auto;padding:16px 0">
|
| 109 |
+
<p style="margin:0 0 14px;font-size:13px;line-height:1.5">Все замеры в этом разделе проведены во внутренней инфраструктуре замеров, инференс в фреймворке vllm с t=1 и штрафами за повторы (repetition_penalty=1, presence_penalty=1.5) для всех моделей. Жирным выделен победитель в каждой строчке.</p>
|
| 110 |
+
<table style="width:100%;table-layout:fixed;border-collapse:collapse;font-size:13px">
|
| 111 |
+
<colgroup>
|
| 112 |
+
<col style="width:25%">
|
| 113 |
+
<col span="3" style="width:25%">
|
| 114 |
+
</colgroup>
|
| 115 |
+
<thead><tr><th style="padding:10px 7px;text-align:left;font-weight:600;border-bottom:2px solid #d6a15f;color:#b7791f">Бенчмарк</th>
|
| 116 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">AliceAI-Foundation-80B-A3B-Base</th>
|
| 117 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Qwen3.5-35B-A3B-Base</th>
|
| 118 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Nemotron-3-Super-120B-A12B-Base</th></tr></thead>
|
| 119 |
+
<tbody>
|
| 120 |
+
<tr><td colspan="4" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Сложные рассуждения</td></tr>
|
| 121 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">AIME 2026 pass@32</summary><div style="padding-top:6px;line-height:1.4">0-shot, задачи American Invitational Mathematics Examination.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>96.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>96.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">90.0</td></tr>
|
| 122 |
+
|
| 123 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">HMMT 2026 Feb pass@32</summary><div style="padding-top:6px;line-height:1.4">0-shot, задачи февральского математического турнира Harvard–MIT.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>96.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">87.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.7</td></tr>
|
| 124 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">IMO Answerbench pass@8</summary><div style="padding-top:6px;line-height:1.4">0-shot, задачи Международной математической олимпиады.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>88.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">64.5</td></tr>
|
| 125 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">CodeForces CPP pass@8</summary><div style="padding-top:6px;line-height:1.4">0-shot, соревновательные задачи Codeforces на C++.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">68.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>73.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">56.6</td></tr>
|
| 126 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LiveCodeBench v5-6 pass@1</summary><div style="padding-top:6px;line-height:1.4">0-shot, открытый бенчмарк с задачами на поиск и использование информации из длинной истории диалога.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>60.4</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">34.7</td></tr>
|
| 127 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LiveCodeBench v5-6 pass@8</summary><div style="padding-top:6px;line-height:1.4">0-shot, открытый бенчмарк с задачами на поиск и использование информации из длинной истории диалога.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>82.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">82.1</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.8</td></tr>
|
| 128 |
+
</tbody>
|
| 129 |
+
</table>
|
| 130 |
+
</div>
|
| 131 |
+
|
| 132 |
+
|
| 133 |
+
## Как использовать
|
| 134 |
+
|
| 135 |
+
### Transformers
|
| 136 |
+
|
| 137 |
+
Модель можно запустить через Transformers. Референсная версия Transformers — 5.16.1. Для выполнения KDA-слоёв на GPU требуется `flash-linear-attention` с поддержкой KDA:
|
| 138 |
+
|
| 139 |
+
```bash
|
| 140 |
+
pip install \
|
| 141 |
+
transformers==5.16.1 \
|
| 142 |
+
accelerate==1.14.0 \
|
| 143 |
+
flash-linear-attention==0.5.0
|
| 144 |
+
```
|
| 145 |
+
|
| 146 |
+
```python
|
| 147 |
+
import torch
|
| 148 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 149 |
+
|
| 150 |
+
model_id = "yandex/AliceAI-Foundation-80B-A3B-Base"
|
| 151 |
+
|
| 152 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
|
| 153 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 154 |
+
model_id,
|
| 155 |
+
trust_remote_code=True,
|
| 156 |
+
dtype=torch.bfloat16,
|
| 157 |
+
device_map="auto",
|
| 158 |
+
)
|
| 159 |
+
|
| 160 |
+
prompt = "Есть 256 монет с разным весом, за какое минимальное количество попарных взвешиваний можно найти вторую по весу монету?"
|
| 161 |
+
inputs = tokenizer(prompt, return_tensors="pt").to(model.device)
|
| 162 |
+
output_ids = model.generate(**inputs, max_new_tokens=32768)
|
| 163 |
+
continuation_ids = output_ids[:, inputs.input_ids.shape[1] :]
|
| 164 |
+
print(tokenizer.decode(continuation_ids[0], skip_special_tokens=True))
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
### vLLM
|
| 168 |
+
|
| 169 |
+
Также модель можно запустить через vLLM. Для запуска требуются Docker и NVIDIA Container Toolkit.
|
| 170 |
+
|
| 171 |
+
```bash
|
| 172 |
+
docker run --name alice-vllm --pull=always --gpus '"device=0,1,2,3"' --ipc=host \
|
| 173 |
+
-p 8001:8000 \
|
| 174 |
+
yamlbrand/alice-ai-vllm:latest \
|
| 175 |
+
yandex/AliceAI-Foundation-80B-A3B-Base \
|
| 176 |
+
--tensor-parallel-size 4 \
|
| 177 |
+
--max-model-len auto \
|
| 178 |
+
--attention-backend FLASH_ATTN \
|
| 179 |
+
--attention-config.flash_attn_version=2 \
|
| 180 |
+
--speculative-config '{"method":"mtp","num_speculative_tokens":1}'
|
| 181 |
+
```
|
| 182 |
+
|
| 183 |
+
Повторный запуск после остановки, с сохранённым кешем:
|
| 184 |
+
|
| 185 |
+
```bash
|
| 186 |
+
docker start -a alice-vllm
|
| 187 |
+
```
|
| 188 |
+
|
| 189 |
+
Чтобы использовать все GPU, замените `--gpus '"device=0,1,2,3"'` на `--gpus all`
|
| 190 |
+
и укажите соответствующее значение размера тензорного параллелизма.
|
| 191 |
+
|
| 192 |
+
После запуска сервера отправьте запрос:
|
| 193 |
+
|
| 194 |
+
```bash
|
| 195 |
+
curl http://127.0.0.1:8001/v1/completions \
|
| 196 |
+
-H 'Content-Type: application/json' \
|
| 197 |
+
-d '{
|
| 198 |
+
"model": "yandex/AliceAI-Foundation-80B-A3B-Base",
|
| 199 |
+
"prompt": "Есть 256 монет с разным весом, за какое минимальное количество попарных взвешиваний можно найти вторую по весу монету?",
|
| 200 |
+
"max_tokens": 32768,
|
| 201 |
+
"temperature": 0
|
| 202 |
+
}'
|
| 203 |
+
```
|
| 204 |
+
|
| 205 |
+
### Токенизатор
|
| 206 |
+
|
| 207 |
+
Токенизатор загружается как `LlamaTokenizer` из файла `tokenizer.model`. Модель
|
| 208 |
+
токенизации использует SentencePiece BPE. Маркеры `[COT_ENABLE]`, `[COT_START]`, `[COT_END]`, а также маркеры инструментов являются обычными атомарными токенами словаря, а не специальными токенами Hugging Face.
|
| 209 |
+
|
| 210 |
+
В `tokenizer_config.json` для параметра `legacy` явно установлено значение
|
| 211 |
+
`false`, чтобы сохранить ожидаемую обработку пробелов. Не переопределяйте его
|
| 212 |
+
значением `true`.
|
| 213 |
+
|
| 214 |
+
### Как дообучить под свои задачи
|
| 215 |
+
|
| 216 |
+
#### Формат данных
|
| 217 |
+
|
| 218 |
+
Для подготовки агентских данных, использованных при обучении модели, мы
|
| 219 |
+
использовали стандартный формат OpenAI Messages. В нём траектория задаётся
|
| 220 |
+
последовательностью сообщений с ролями `system`, `user`, `assistant`, `tool` и
|
| 221 |
+
`meta`, а определения доступных инструментов передаются отдельно в поле
|
| 222 |
+
`tools`.
|
| 223 |
+
|
| 224 |
+
Перед токенизацией каждая такая траектория рендерилась с помощью
|
| 225 |
+
[`chat_template.jinja`](finetune/chat_template.jinja). Шаблон задаёт префиксы
|
| 226 |
+
ролей, представление reasoning-трейсов, описаний инструментов, вызовов функций
|
| 227 |
+
и результатов их вып��лнения. Именно в таком текстовом представлении эти данные
|
| 228 |
+
использовались при обучении модели.
|
| 229 |
+
|
| 230 |
+
Для sft и RL рекомендуем хранить данные в формате OpenAI
|
| 231 |
+
Messages и рендерить их с помощью этого шаблона. Так формат новых данных будет
|
| 232 |
+
совпадать с форматом, который модель видела во время претрейна.
|
| 233 |
+
|
| 234 |
+
Мы намеренно не указываем этот шаблон как `chat_template` в
|
| 235 |
+
`tokenizer_config.json`: Alice-AI-Foundation-80B-A3B-Base — базовая модель, поэтому у неё нет
|
| 236 |
+
единственного формата диалога, который должен автоматически применяться при
|
| 237 |
+
инференсе. Приведённый шаблон предназначен именно для подготовки данных к
|
| 238 |
+
дообучению.
|
| 239 |
+
|
| 240 |
+
#### Пример LoRA-дообучения
|
| 241 |
+
|
| 242 |
+
В репозитории есть минимальный пример PEFT-дообучения
|
| 243 |
+
[`finetune_lora.py`](finetune/finetune_lora.py). Он загружает зафиксированную ревизию
|
| 244 |
+
датасета `tatsu-lab/alpaca`, обучается только на ответах и сохраняет только
|
| 245 |
+
LoRA-адаптер. Для модели такого размера необходим FSDP2, пример ниже рассчитан
|
| 246 |
+
на четыре GPU с 80 GB памяти.
|
| 247 |
+
|
| 248 |
+
```bash
|
| 249 |
+
pip install \
|
| 250 |
+
transformers==5.16.1 \
|
| 251 |
+
accelerate==1.14.0 \
|
| 252 |
+
peft==0.20.0 \
|
| 253 |
+
datasets==5.0.1 \
|
| 254 |
+
flash-linear-attention==0.5.0
|
| 255 |
+
|
| 256 |
+
pip install flash-attn==2.8.1 --no-build-isolation
|
| 257 |
+
|
| 258 |
+
CUDA_VISIBLE_DEVICES=0,1,2,3 \
|
| 259 |
+
PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True \
|
| 260 |
+
accelerate launch \
|
| 261 |
+
--use_fsdp \
|
| 262 |
+
--num_processes 4 \
|
| 263 |
+
--num_machines 1 \
|
| 264 |
+
--dynamo_backend no \
|
| 265 |
+
--mixed_precision no \
|
| 266 |
+
--fsdp_version 2 \
|
| 267 |
+
--fsdp_reshard_after_forward true \
|
| 268 |
+
--fsdp_auto_wrap_policy TRANSFORMER_BASED_WRAP \
|
| 269 |
+
--fsdp_transformer_layer_cls_to_wrap AliceAIDecoderLayer \
|
| 270 |
+
--fsdp_cpu_ram_efficient_loading true \
|
| 271 |
+
--fsdp_sync_module_states true \
|
| 272 |
+
--fsdp_state_dict_type SHARDED_STATE_DICT \
|
| 273 |
+
finetune/finetune_lora.py \
|
| 274 |
+
--model yandex/AliceAI-Foundation-80B-A3B-Base \
|
| 275 |
+
--steps 100 \
|
| 276 |
+
--sequence-length 512 \
|
| 277 |
+
--output-dir alice-lora
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
`--mixed_precision no` здесь не означает FP32-модель: базовые веса загружаются
|
| 281 |
+
в BF16, а LoRA-параметры PEFT хранит в FP32.
|
| 282 |
+
|
| 283 |
+
При RAM-efficient загрузке полные веса чекпоинта загружает только rank 0;
|
| 284 |
+
остальные процессы создают модель на meta device и получают свои шарды через
|
| 285 |
+
FSDP2.
|
| 286 |
+
|
| 287 |
+
---
|
| 288 |
+
Данная модель является предварительно обученной (pretrained) моделью и предоставляется в исходном виде, без дополнительного этапа post-training / alignment.
|
| 289 |
+
|
| 290 |
+
Модель предназначена прежде всего для исследований, экспериментов и дальнейшей доработки. Она не является готовым решением для непосредственного использования в пользовательских продуктах и сервисах.
|
| 291 |
+
|
| 292 |
+
Перед использованием модели в production-среде рекомендуется провести собственное тестирование и, исходя из сценария применения, реализовать необходимые этапы дообучения, настройки и контроля поведения модели.
|
| 293 |
+
|
| 294 |
+
Пользователь самостоятельно определяет применимость модели для конкретного сценария и несет ответственность за ее интеграцию и использование.
|
README_en.md
ADDED
|
@@ -0,0 +1,292 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
language:
|
| 4 |
+
- ru
|
| 5 |
+
- en
|
| 6 |
+
library_name: transformers
|
| 7 |
+
pipeline_tag: text-generation
|
| 8 |
+
tags:
|
| 9 |
+
- custom_code
|
| 10 |
+
- mixture-of-experts
|
| 11 |
+
- vllm
|
| 12 |
+
---
|
| 13 |
+
|
| 14 |
+
# AliceAI-Foundation-80B-A3B-Base
|
| 15 |
+
|
| 16 |
+
[Русская версия](./README.md)
|
| 17 |
+
|
| 18 |
+
AliceAI-Foundation-80B-A3B-Base is a base language model with a hybrid
|
| 19 |
+
architecture and MoE layers. The model has 80 billion parameters, of which
|
| 20 |
+
3 billion are activated for each token, and supports a context length of up to
|
| 21 |
+
262,144 tokens. The model was trained entirely from scratch.
|
| 22 |
+
|
| 23 |
+
To build the model, we assembled a new training corpus, selected the architecture
|
| 24 |
+
and hyperparameters, and prepared data for complex reasoning and tool use. We
|
| 25 |
+
validated key design decisions through a series of separate training runs from
|
| 26 |
+
scratch, each using 2 trillion tokens.
|
| 27 |
+
|
| 28 |
+
On mathematics, coding, and other reasoning tasks, the model performs on par
|
| 29 |
+
with larger open-source models and is particularly strong on Russian factual
|
| 30 |
+
knowledge. Alongside the model weights, we release the factual benchmarks
|
| 31 |
+
[WikiWebFacts](https://huggingface.co/datasets/yandex/WikiWebFacts) and
|
| 32 |
+
[HardMultiQA](https://huggingface.co/datasets/yandex/HardMultiQA), which focus on
|
| 33 |
+
Russian-language contexts, together with their evaluation protocols.
|
| 34 |
+
|
| 35 |
+
<img src="./assets/benchmarks.png" alt="Benchmark comparison" width="800">
|
| 36 |
+
|
| 37 |
+
## Model Overview
|
| 38 |
+
|
| 39 |
+
- Type: autoregressive language model
|
| 40 |
+
- Training stage: pre-training
|
| 41 |
+
- Language model
|
| 42 |
+
- Number of parameters: 80B total, 3B activated
|
| 43 |
+
- Hidden size: 2048
|
| 44 |
+
- Vocabulary size: 129024
|
| 45 |
+
- Number of layers: 48
|
| 46 |
+
- Layer layout: 12 × (3 × (KDA → MoE) → 1 × (Gated Attention → MoE))
|
| 47 |
+
- KDA:
|
| 48 |
+
- Number of query heads: 32
|
| 49 |
+
- Number of KV heads: 32
|
| 50 |
+
- Query head dimension: 128
|
| 51 |
+
- KV head dimension: 128
|
| 52 |
+
- Convolution kernel size: 4
|
| 53 |
+
- Gated Attention:
|
| 54 |
+
- Number of query heads: 16
|
| 55 |
+
- Number of KV heads: 2
|
| 56 |
+
- Query head dimension: 256
|
| 57 |
+
- MoE:
|
| 58 |
+
- Number of experts: 512
|
| 59 |
+
- Top-K: 10 routed + 1 shared expert
|
| 60 |
+
- Expert intermediate size: 512
|
| 61 |
+
- MTP: 1 layer
|
| 62 |
+
- Context length: 262144
|
| 63 |
+
|
| 64 |
+
## Benchmarks
|
| 65 |
+
|
| 66 |
+
<div style="font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,sans-serif;max-width:1000px;margin:0 auto;padding:16px 0">
|
| 67 |
+
<p style="margin:0 0 12px;font-size:13px;line-height:1.5">Russian-language benchmark names are shown in <span style="color:#27834a;font-weight:600">green</span>; English-language benchmark names are shown in <span style="color:#496fa8;font-weight:600">blue</span>.</p>
|
| 68 |
+
<p style="margin:0 0 14px;font-size:13px;line-height:1.5">All results in this section were obtained using our internal evaluation infrastructure, with inference performed in vLLM at t=0 for every model. The best result in each row is shown in bold.</p>
|
| 69 |
+
<table style="width:100%;table-layout:fixed;border-collapse:collapse;font-size:13px">
|
| 70 |
+
<colgroup>
|
| 71 |
+
<col style="width:25%">
|
| 72 |
+
<col span="5" style="width:15%">
|
| 73 |
+
</colgroup>
|
| 74 |
+
<thead><tr><th style="padding:10px 7px;text-align:left;font-weight:600;border-bottom:2px solid #d6a15f;color:#b7791f">Benchmark</th>
|
| 75 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">AliceAI-Foundation-80B-A3B-Base</th>
|
| 76 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Qwen3.5-35B-A3B-Base</th>
|
| 77 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">GLM-4.5-Air-Base (106B-A12B)</th>
|
| 78 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Nemotron-3-Super-120B-A12B-Base</th>
|
| 79 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">DeepSeek-V4-Flash-Base (284B-A13B)</th></tr></thead>
|
| 80 |
+
<tbody>
|
| 81 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Facts</td></tr>
|
| 82 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">WikiWebFacts</summary><div style="padding-top:6px;line-height:1.4">5-shot benchmark of factual knowledge in Russian.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>86.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">62.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">70.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">72.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">83.2</td></tr>
|
| 83 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">HardMultiQA</summary><div style="padding-top:6px;line-height:1.4">5-shot benchmark of factual knowledge in Russian.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>67.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">47.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">48.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">54.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">65.4</td></tr>
|
| 84 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">CultCat</summary><div style="padding-top:6px;line-height:1.4">4-shot benchmark of cultural knowledge. Read more in our <a href="https://habr.com/ru/companies/yandex/articles/868282/">article on Habr</a>.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>86.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.1</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">80.7</td></tr>
|
| 85 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">TriviaQA</summary><div style="padding-top:6px;line-height:1.4">5-shot open benchmark of factual knowledge in English; LLM-as-a-judge is used instead of Exact Match.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">79.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">83.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>89.8</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">89.4</td></tr>
|
| 86 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Educational benchmarks</td></tr>
|
| 87 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Russian</summary><div style="padding-top:6px;line-height:1.4">5-shot education benchmark built from queries submitted to Alice.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>74.2</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">42.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">39.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">44.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">67.7</td></tr>
|
| 88 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Literature</summary><div style="padding-top:6px;line-height:1.4">5-shot education benchmark built from queries submitted to Alice.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>73.8</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">55.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">69.1</td></tr>
|
| 89 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench History</summary><div style="padding-top:6px;line-height:1.4">5-shot education benchmark built from queries submitted to Alice.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>82.0</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">65.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">62.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">70.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">76.9</td></tr>
|
| 90 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench English</summary><div style="padding-top:6px;line-height:1.4">5-shot education benchmark built from queries submitted to Alice.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">76.1</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">67.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>82.9</strong></td></tr>
|
| 91 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Expert knowledge</td></tr>
|
| 92 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">ExpertFactsQA Medicine</summary><div style="padding-top:6px;line-height:1.4">5-shot factual-knowledge benchmark created by domain experts.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>63.6</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.0</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">42.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">60.7</td></tr>
|
| 93 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">ExpertFactsQA Law</summary><div style="padding-top:6px;line-height:1.4">Challenging 5-shot factual-knowledge benchmark created by domain experts.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>49.6</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">27.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">22.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">24.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">40.5</td></tr>
|
| 94 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Exams</td></tr>
|
| 95 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EGE CoT</summary><div style="padding-top:6px;line-height:1.4">5-shot benchmark based on multiple-choice Unified State Exam tasks across various subjects.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>90.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">77.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">90.3</td></tr>
|
| 96 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">MMLU-Pro CoT</summary><div style="padding-top:6px;line-height:1.4">5-shot open benchmark of knowledge and reasoning across a broad range of subjects in English.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">63.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">58.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>69.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.5</td></tr>
|
| 97 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">SuperGPQA CoT</summary><div style="padding-top:6px;line-height:1.4">5-shot open benchmark containing questions written by experts from different scientific fields.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">44.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">43.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">35.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>46.6</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">46.1</td></tr>
|
| 98 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Mathematics</td></tr>
|
| 99 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">MATH-500</summary><div style="padding-top:6px;line-height:1.4">5-shot benchmark of mathematical problems; it uses LLM-as-a-judge and longer reasoning traces in the few-shot examples.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>91.1</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">81.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">60.2</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">80.7</td></tr>
|
| 100 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Math</summary><div style="padding-top:6px;line-height:1.4">5-shot education benchmark built from queries submitted to Alice</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">79.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>80.0</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">56.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">69.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">76.3</td></tr>
|
| 101 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#27834a">EduBench Math University</summary><div style="padding-top:6px;line-height:1.4">5-shot education benchmark built from queries submitted to Alice.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>70.1</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">69.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">67.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">68.6</td></tr>
|
| 102 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Coding</td></tr>
|
| 103 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">BigCodeBench 1-shot pass@1</summary><div style="padding-top:6px;line-height:1.4">1-shot, our implementation of BigCodeBench with improved tests.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">48.3</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">43.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">44.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">48.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>49.1</strong></td></tr>
|
| 104 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LiveCodeBench v5-6 CoT 1-shot pass@1</summary><div style="padding-top:6px;line-height:1.4">1-shot open benchmark of challenging programming problems that require finding an algorithm and implementing it in code.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>50.5</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">22.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.4</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">38.1</td></tr>
|
| 105 |
+
<tr><td colspan="6" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Long context</td></tr>
|
| 106 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">FinQA 128k</summary><div style="padding-top:6px;line-height:1.4">5-shot long-context adaptation of the open-source FinQA benchmark, featuring financial-report analysis tasks.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>74.1</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">73.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">35.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">71.7</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>74.1</strong></td></tr>
|
| 107 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LongMemEval 128k</summary><div style="padding-top:6px;line-height:1.4">5-shot open benchmark of finding and using information from long dialogue histories.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">64.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">55.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">50.6</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">64.8</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>68.0</strong></td></tr>
|
| 108 |
+
</tbody>
|
| 109 |
+
</table>
|
| 110 |
+
</div>
|
| 111 |
+
|
| 112 |
+
<div style="font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,sans-serif;max-width:1000px;margin:0 auto;padding:16px 0">
|
| 113 |
+
<p style="margin:0 0 14px;font-size:13px;line-height:1.5">All results in this section were obtained using our internal evaluation infrastructure, with inference performed in vLLM at t=1 and repetition penalties (repetition_penalty=1, presence_penalty=1.5) for every model. The best result in each row is shown in bold.</p>
|
| 114 |
+
<table style="width:100%;table-layout:fixed;border-collapse:collapse;font-size:13px">
|
| 115 |
+
<colgroup>
|
| 116 |
+
<col style="width:25%">
|
| 117 |
+
<col span="3" style="width:25%">
|
| 118 |
+
</colgroup>
|
| 119 |
+
<thead><tr><th style="padding:10px 7px;text-align:left;font-weight:600;border-bottom:2px solid #d6a15f;color:#b7791f">Benchmark</th>
|
| 120 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">AliceAI-Foundation-80B-A3B-Base</th>
|
| 121 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Qwen3.5-35B-A3B-Base</th>
|
| 122 |
+
<th style="padding:10px 7px;text-align:center;font-weight:500;border-bottom:2px solid #d6a15f;color:#b7791f;font-size:14px">Nemotron-3-Super-120B-A12B-Base</th></tr></thead>
|
| 123 |
+
<tbody>
|
| 124 |
+
<tr><td colspan="4" style="padding:8px 12px;font-weight:600;color:#b7791f;border-bottom:1px solid rgba(239,150,68,0.25);background:rgba(239,150,68,0.1)">Complex reasoning</td></tr>
|
| 125 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">AIME 2026 pass@32</summary><div style="padding-top:6px;line-height:1.4">0-shot problems from the American Invitational Mathematics Examination.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>96.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>96.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">90.0</td></tr>
|
| 126 |
+
|
| 127 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">HMMT 2026 Feb pass@32</summary><div style="padding-top:6px;line-height:1.4">0-shot problems from the February Harvard–MIT Mathematics Tournament.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>96.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">87.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">66.7</td></tr>
|
| 128 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">IMO Answerbench pass@8</summary><div style="padding-top:6px;line-height:1.4">0-shot problems from the International Mathematical Olympiad.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>88.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">84.5</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">64.5</td></tr>
|
| 129 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">CodeForces CPP pass@8</summary><div style="padding-top:6px;line-height:1.4">0-shot competitive-programming problems from Codeforces in C++.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">68.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>73.7</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">56.6</td></tr>
|
| 130 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LiveCodeBench v5-6 pass@1</summary><div style="padding-top:6px;line-height:1.4">0-shot open benchmark of challenging programming problems.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>60.4</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">51.9</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">34.7</td></tr>
|
| 131 |
+
<tr><td style="padding:7px 7px;padding-left:20px;border-bottom:1px solid rgba(128,128,128,0.15)"><details><summary style="cursor:pointer;white-space:normal;font-weight:600;color:#496fa8">LiveCodeBench v5-6 pass@8</summary><div style="padding-top:6px;line-height:1.4">0-shot open benchmark of challenging programming problems.</div></details></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)"><strong>82.9</strong></td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">82.1</td><td style="padding:7px;text-align:center;border-bottom:1px solid rgba(128,128,128,0.15)">59.8</td></tr>
|
| 132 |
+
</tbody>
|
| 133 |
+
</table>
|
| 134 |
+
</div>
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
## Usage
|
| 138 |
+
|
| 139 |
+
### Transformers
|
| 140 |
+
|
| 141 |
+
The model can be run with Transformers. The reference Transformers version is
|
| 142 |
+
5.16.1. Running the KDA layers on GPU requires `flash-linear-attention` with
|
| 143 |
+
KDA support:
|
| 144 |
+
|
| 145 |
+
```bash
|
| 146 |
+
pip install \
|
| 147 |
+
transformers==5.16.1 \
|
| 148 |
+
accelerate==1.14.0 \
|
| 149 |
+
flash-linear-attention==0.5.0
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
```python
|
| 153 |
+
import torch
|
| 154 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 155 |
+
|
| 156 |
+
model_id = "yandex/AliceAI-Foundation-80B-A3B-Base"
|
| 157 |
+
|
| 158 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
|
| 159 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 160 |
+
model_id,
|
| 161 |
+
trust_remote_code=True,
|
| 162 |
+
dtype=torch.bfloat16,
|
| 163 |
+
device_map="auto",
|
| 164 |
+
)
|
| 165 |
+
|
| 166 |
+
prompt = "There are 256 coins of different weights. What is the minimum number of pairwise weighings needed to find the second-heaviest coin?"
|
| 167 |
+
inputs = tokenizer(prompt, return_tensors="pt").to(model.device)
|
| 168 |
+
output_ids = model.generate(**inputs, max_new_tokens=32768)
|
| 169 |
+
continuation_ids = output_ids[:, inputs.input_ids.shape[1] :]
|
| 170 |
+
print(tokenizer.decode(continuation_ids[0], skip_special_tokens=True))
|
| 171 |
+
```
|
| 172 |
+
|
| 173 |
+
### vLLM
|
| 174 |
+
|
| 175 |
+
The model can also be run with vLLM. Docker and NVIDIA Container Toolkit are
|
| 176 |
+
required.
|
| 177 |
+
|
| 178 |
+
```bash
|
| 179 |
+
docker run --name alice-vllm --pull=always --gpus '"device=0,1,2,3"' --ipc=host \
|
| 180 |
+
-p 8001:8000 \
|
| 181 |
+
yamlbrand/alice-ai-vllm:latest \
|
| 182 |
+
yandex/AliceAI-Foundation-80B-A3B-Base \
|
| 183 |
+
--tensor-parallel-size 4 \
|
| 184 |
+
--max-model-len auto \
|
| 185 |
+
--attention-backend FLASH_ATTN \
|
| 186 |
+
--attention-config.flash_attn_version=2 \
|
| 187 |
+
--speculative-config '{"method":"mtp","num_speculative_tokens":1}'
|
| 188 |
+
```
|
| 189 |
+
|
| 190 |
+
To restart the stopped container while preserving its cache:
|
| 191 |
+
|
| 192 |
+
```bash
|
| 193 |
+
docker start -a alice-vllm
|
| 194 |
+
```
|
| 195 |
+
|
| 196 |
+
To use all available GPUs, replace `--gpus '"device=0,1,2,3"'` with
|
| 197 |
+
`--gpus all` and set the tensor-parallel size accordingly.
|
| 198 |
+
|
| 199 |
+
Once the server is running, send a request:
|
| 200 |
+
|
| 201 |
+
```bash
|
| 202 |
+
curl http://127.0.0.1:8001/v1/completions \
|
| 203 |
+
-H 'Content-Type: application/json' \
|
| 204 |
+
-d '{
|
| 205 |
+
"model": "yandex/AliceAI-Foundation-80B-A3B-Base",
|
| 206 |
+
"prompt": "There are 256 coins of different weights. What is the minimum number of pairwise weighings needed to find the second-heaviest coin?",
|
| 207 |
+
"max_tokens": 32768,
|
| 208 |
+
"temperature": 0
|
| 209 |
+
}'
|
| 210 |
+
```
|
| 211 |
+
|
| 212 |
+
### Tokenizer
|
| 213 |
+
|
| 214 |
+
The tokenizer is loaded as `LlamaTokenizer` from `tokenizer.model` and uses
|
| 215 |
+
SentencePiece BPE. The `[COT_ENABLE]`, `[COT_START]`, and `[COT_END]` markers,
|
| 216 |
+
as well as the tool-use markers, are ordinary atomic vocabulary tokens rather
|
| 217 |
+
than Hugging Face special tokens.
|
| 218 |
+
|
| 219 |
+
In `tokenizer_config.json`, `legacy` is explicitly set to `false` to preserve
|
| 220 |
+
the expected whitespace handling. Do not override it with `true`.
|
| 221 |
+
|
| 222 |
+
### Fine-tuning for your tasks
|
| 223 |
+
|
| 224 |
+
#### Data format
|
| 225 |
+
|
| 226 |
+
To prepare the agentic data used during model training, we used the standard
|
| 227 |
+
OpenAI Messages format. A trajectory is represented as a sequence of messages
|
| 228 |
+
with the `system`, `user`, `assistant`, `tool`, and `meta` roles, while the
|
| 229 |
+
definitions of the available tools are passed separately in the `tools` field.
|
| 230 |
+
|
| 231 |
+
Before tokenization, each trajectory was rendered with
|
| 232 |
+
[`chat_template.jinja`](finetune/chat_template.jinja). The template defines the
|
| 233 |
+
role prefixes and the representation of reasoning traces, tool descriptions,
|
| 234 |
+
function calls, and tool results. This is the textual representation in which
|
| 235 |
+
the model encountered these data during training.
|
| 236 |
+
|
| 237 |
+
For sft and RL, we recommend storing data in the OpenAI
|
| 238 |
+
Messages format and rendering it with this template. This keeps the new data
|
| 239 |
+
consistent with the format seen by the model during pretraining.
|
| 240 |
+
|
| 241 |
+
We intentionally do not set this template as `chat_template` in
|
| 242 |
+
`tokenizer_config.json`: Alice-AI-Foundation-80B-A3B-Base is a base model and therefore does
|
| 243 |
+
not have a single conversational format that should be applied automatically
|
| 244 |
+
during inference. The provided template is intended specifically for preparing
|
| 245 |
+
fine-tuning data.
|
| 246 |
+
|
| 247 |
+
#### LoRA fine-tuning example
|
| 248 |
+
|
| 249 |
+
The repository includes a minimal PEFT fine-tuning example,
|
| 250 |
+
[`finetune_lora.py`](finetune/finetune_lora.py). It loads a pinned revision of
|
| 251 |
+
the `tatsu-lab/alpaca` dataset, computes the training loss only on responses,
|
| 252 |
+
and saves only the LoRA adapter. A model of this size requires FSDP2; the
|
| 253 |
+
example below is designed for four GPUs with 80 GB of memory each.
|
| 254 |
+
|
| 255 |
+
```bash
|
| 256 |
+
pip install \
|
| 257 |
+
transformers==5.16.1 \
|
| 258 |
+
accelerate==1.14.0 \
|
| 259 |
+
peft==0.20.0 \
|
| 260 |
+
datasets==5.0.1 \
|
| 261 |
+
flash-linear-attention==0.5.0
|
| 262 |
+
|
| 263 |
+
pip install flash-attn==2.8.1 --no-build-isolation
|
| 264 |
+
|
| 265 |
+
CUDA_VISIBLE_DEVICES=0,1,2,3 \
|
| 266 |
+
PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True \
|
| 267 |
+
accelerate launch \
|
| 268 |
+
--use_fsdp \
|
| 269 |
+
--num_processes 4 \
|
| 270 |
+
--num_machines 1 \
|
| 271 |
+
--dynamo_backend no \
|
| 272 |
+
--mixed_precision no \
|
| 273 |
+
--fsdp_version 2 \
|
| 274 |
+
--fsdp_reshard_after_forward true \
|
| 275 |
+
--fsdp_auto_wrap_policy TRANSFORMER_BASED_WRAP \
|
| 276 |
+
--fsdp_transformer_layer_cls_to_wrap AliceAIDecoderLayer \
|
| 277 |
+
--fsdp_cpu_ram_efficient_loading true \
|
| 278 |
+
--fsdp_sync_module_states true \
|
| 279 |
+
--fsdp_state_dict_type SHARDED_STATE_DICT \
|
| 280 |
+
finetune/finetune_lora.py \
|
| 281 |
+
--model yandex/AliceAI-Foundation-80B-A3B-Base \
|
| 282 |
+
--steps 100 \
|
| 283 |
+
--sequence-length 512 \
|
| 284 |
+
--output-dir alice-lora
|
| 285 |
+
```
|
| 286 |
+
|
| 287 |
+
Here, `--mixed_precision no` does not mean that the model uses FP32: the base
|
| 288 |
+
weights are loaded in BF16, while PEFT stores the LoRA parameters in FP32.
|
| 289 |
+
|
| 290 |
+
With RAM-efficient loading, only rank 0 loads the full checkpoint weights. The
|
| 291 |
+
other processes construct the model on the meta device and receive their shards
|
| 292 |
+
through FSDP2.
|
assets/benchmarks.png
ADDED
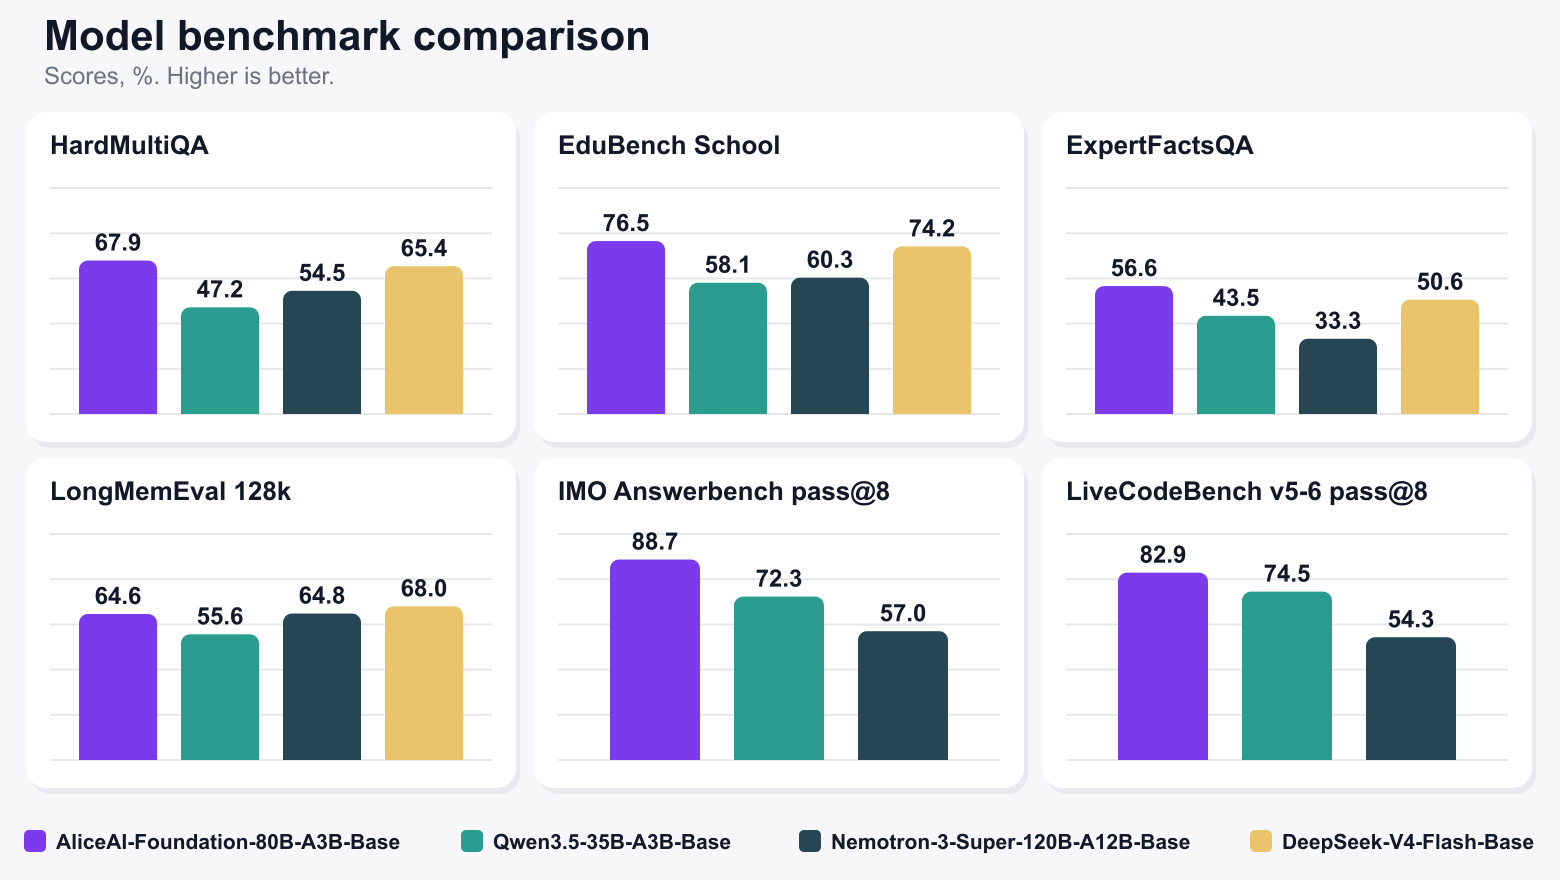
|
Git LFS Details
|
config.json
ADDED
|
@@ -0,0 +1,58 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"AliceAIForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_dropout": 0.0,
|
| 6 |
+
"bos_token_id": 1,
|
| 7 |
+
"auto_map": {
|
| 8 |
+
"AutoConfig": "configuration_alice_ai.AliceAIConfig",
|
| 9 |
+
"AutoModelForCausalLM": "modeling_alice_ai.AliceAIForCausalLM"
|
| 10 |
+
},
|
| 11 |
+
"block_attn_res_block_size": 4,
|
| 12 |
+
"head_dim": 256,
|
| 13 |
+
"hidden_act": "silu",
|
| 14 |
+
"hidden_size": 2048,
|
| 15 |
+
"initializer_range": 0.02,
|
| 16 |
+
"kda_allow_negative_eigenvalues": false,
|
| 17 |
+
"layer_types": [
|
| 18 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 19 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 20 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 21 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 22 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 23 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 24 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 25 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 26 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 27 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 28 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention",
|
| 29 |
+
"linear_attention", "linear_attention", "linear_attention", "full_attention"
|
| 30 |
+
],
|
| 31 |
+
"eos_token_id": 2,
|
| 32 |
+
"linear_conv_kernel_dim": 4,
|
| 33 |
+
"linear_key_head_dim": 128,
|
| 34 |
+
"linear_num_key_heads": 32,
|
| 35 |
+
"linear_num_value_heads": 32,
|
| 36 |
+
"linear_value_head_dim": 128,
|
| 37 |
+
"max_position_embeddings": 262144,
|
| 38 |
+
"model_type": "alice_ai",
|
| 39 |
+
"moe_intermediate_size": 512,
|
| 40 |
+
"mtp_num_hidden_layers": 1,
|
| 41 |
+
"num_attention_heads": 16,
|
| 42 |
+
"number_of_conv_states": 3,
|
| 43 |
+
"num_experts": 512,
|
| 44 |
+
"num_experts_per_tok": 10,
|
| 45 |
+
"num_hidden_layers": 48,
|
| 46 |
+
"num_key_value_heads": 2,
|
| 47 |
+
"output_router_logits": false,
|
| 48 |
+
"partial_rotary_factor": 0.25,
|
| 49 |
+
"rms_norm_eps": 1e-6,
|
| 50 |
+
"rope_theta": 1000000.0,
|
| 51 |
+
"router_bias_correction": true,
|
| 52 |
+
"router_score_function": "sigmoid",
|
| 53 |
+
"shared_expert_intermediate_size": 512,
|
| 54 |
+
"tie_word_embeddings": false,
|
| 55 |
+
"transformers_version": "5.16.1",
|
| 56 |
+
"use_cache": true,
|
| 57 |
+
"vocab_size": 129024
|
| 58 |
+
}
|
configuration_alice_ai.py
ADDED
|
@@ -0,0 +1,109 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from transformers.configuration_utils import PretrainedConfig
|
| 2 |
+
|
| 3 |
+
|
| 4 |
+
class AliceAIConfig(PretrainedConfig):
|
| 5 |
+
model_type = "alice_ai"
|
| 6 |
+
|
| 7 |
+
def __init__(
|
| 8 |
+
self,
|
| 9 |
+
vocab_size: int = 129024,
|
| 10 |
+
hidden_size: int = 2048,
|
| 11 |
+
num_hidden_layers: int = 48,
|
| 12 |
+
num_attention_heads: int = 16,
|
| 13 |
+
num_key_value_heads: int = 2,
|
| 14 |
+
head_dim: int = 256,
|
| 15 |
+
linear_num_key_heads: int = 32,
|
| 16 |
+
linear_num_value_heads: int = 32,
|
| 17 |
+
linear_key_head_dim: int = 128,
|
| 18 |
+
linear_value_head_dim: int = 128,
|
| 19 |
+
linear_conv_kernel_dim: int = 4,
|
| 20 |
+
num_experts: int = 512,
|
| 21 |
+
num_experts_per_tok: int = 10,
|
| 22 |
+
moe_intermediate_size: int = 512,
|
| 23 |
+
shared_expert_intermediate_size: int = 512,
|
| 24 |
+
block_attn_res_block_size: int = 4,
|
| 25 |
+
router_score_function: str = "sigmoid",
|
| 26 |
+
router_bias_correction: bool = True,
|
| 27 |
+
kda_allow_negative_eigenvalues: bool = False,
|
| 28 |
+
max_position_embeddings: int = 262144,
|
| 29 |
+
rope_theta: float = 1_000_000.0,
|
| 30 |
+
partial_rotary_factor: float = 0.25,
|
| 31 |
+
rms_norm_eps: float = 1e-6,
|
| 32 |
+
hidden_act: str = "silu",
|
| 33 |
+
initializer_range: float = 0.02,
|
| 34 |
+
attention_dropout: float = 0.0,
|
| 35 |
+
use_cache: bool = True,
|
| 36 |
+
output_router_logits: bool = False,
|
| 37 |
+
layer_types: list[str] | None = None,
|
| 38 |
+
tie_word_embeddings: bool = False,
|
| 39 |
+
pad_token_id: int | None = None,
|
| 40 |
+
bos_token_id: int | None = None,
|
| 41 |
+
eos_token_id: int | list[int] | None = None,
|
| 42 |
+
**kwargs,
|
| 43 |
+
) -> None:
|
| 44 |
+
if layer_types is None:
|
| 45 |
+
layer_types = [
|
| 46 |
+
"full_attention" if (layer_idx + 1) % 4 == 0 else "linear_attention"
|
| 47 |
+
for layer_idx in range(num_hidden_layers)
|
| 48 |
+
]
|
| 49 |
+
super().__init__(
|
| 50 |
+
pad_token_id=pad_token_id,
|
| 51 |
+
bos_token_id=bos_token_id,
|
| 52 |
+
eos_token_id=eos_token_id,
|
| 53 |
+
tie_word_embeddings=tie_word_embeddings,
|
| 54 |
+
**kwargs,
|
| 55 |
+
)
|
| 56 |
+
self.vocab_size = vocab_size
|
| 57 |
+
self.hidden_size = hidden_size
|
| 58 |
+
self.num_hidden_layers = num_hidden_layers
|
| 59 |
+
self.num_attention_heads = num_attention_heads
|
| 60 |
+
self.num_key_value_heads = num_key_value_heads
|
| 61 |
+
self.head_dim = head_dim
|
| 62 |
+
self.linear_num_key_heads = linear_num_key_heads
|
| 63 |
+
self.linear_num_value_heads = linear_num_value_heads
|
| 64 |
+
self.linear_key_head_dim = linear_key_head_dim
|
| 65 |
+
self.linear_value_head_dim = linear_value_head_dim
|
| 66 |
+
self.linear_conv_kernel_dim = linear_conv_kernel_dim
|
| 67 |
+
self.num_experts = num_experts
|
| 68 |
+
self.num_experts_per_tok = num_experts_per_tok
|
| 69 |
+
self.moe_intermediate_size = moe_intermediate_size
|
| 70 |
+
self.shared_expert_intermediate_size = shared_expert_intermediate_size
|
| 71 |
+
self.block_attn_res_block_size = block_attn_res_block_size
|
| 72 |
+
self.router_score_function = router_score_function
|
| 73 |
+
self.router_bias_correction = router_bias_correction
|
| 74 |
+
self.kda_allow_negative_eigenvalues = kda_allow_negative_eigenvalues
|
| 75 |
+
self.max_position_embeddings = max_position_embeddings
|
| 76 |
+
self.rope_theta = rope_theta
|
| 77 |
+
self.partial_rotary_factor = partial_rotary_factor
|
| 78 |
+
self.rms_norm_eps = rms_norm_eps
|
| 79 |
+
self.hidden_act = hidden_act
|
| 80 |
+
self.initializer_range = initializer_range
|
| 81 |
+
self.attention_dropout = attention_dropout
|
| 82 |
+
self.use_cache = use_cache
|
| 83 |
+
self.output_router_logits = output_router_logits
|
| 84 |
+
self.layer_types = layer_types
|
| 85 |
+
self.number_of_conv_states = 3
|
| 86 |
+
self._validate_fields()
|
| 87 |
+
|
| 88 |
+
def _validate_fields(self) -> None:
|
| 89 |
+
if self.block_attn_res_block_size <= 0:
|
| 90 |
+
raise ValueError("block_attn_res_block_size must be positive")
|
| 91 |
+
if self.linear_conv_kernel_dim < 2:
|
| 92 |
+
raise ValueError("linear_conv_kernel_dim must be at least 2")
|
| 93 |
+
if self.router_score_function != "sigmoid":
|
| 94 |
+
raise ValueError("This architecture requires sigmoid routing")
|
| 95 |
+
if not 0 < self.num_experts_per_tok <= self.num_experts:
|
| 96 |
+
raise ValueError("num_experts_per_tok must be between 1 and num_experts")
|
| 97 |
+
if self.num_attention_heads % self.num_key_value_heads != 0:
|
| 98 |
+
raise ValueError(
|
| 99 |
+
"num_attention_heads must be divisible by num_key_value_heads"
|
| 100 |
+
)
|
| 101 |
+
if self.linear_num_value_heads % self.linear_num_key_heads != 0:
|
| 102 |
+
raise ValueError(
|
| 103 |
+
"linear_num_value_heads must be divisible by linear_num_key_heads"
|
| 104 |
+
)
|
| 105 |
+
if len(self.layer_types) != self.num_hidden_layers:
|
| 106 |
+
raise ValueError("layer_types must contain one entry per hidden layer")
|
| 107 |
+
unknown = set(self.layer_types) - {"linear_attention", "full_attention"}
|
| 108 |
+
if unknown:
|
| 109 |
+
raise ValueError(f"Unsupported layer types: {sorted(unknown)}")
|
finetune/chat_template.jinja
ADDED
|
@@ -0,0 +1,94 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- set roles = {"assistant": "assistant:", "user": "user:", "system": "system:", "meta": "meta:"} -%}
|
| 2 |
+
{%- set TOOL_CALL_START = "[TOOL_CALL_START]" -%}
|
| 3 |
+
{%- set COT_START = "[COT_START]" -%}
|
| 4 |
+
{%- set COT_END = "[COT_END]" -%}
|
| 5 |
+
{%- set tools_prefix = "Тебе доступны следующие функции:" -%}
|
| 6 |
+
{%- set json_seps = (",", ":") -%}
|
| 7 |
+
|
| 8 |
+
{%- macro js(x) -%}
|
| 9 |
+
{{- x | tojson(separators=json_seps) | replace("&", "\\u0026") | replace("<", "\\u003c") | replace(">", "\\u003e") | replace("'", "\\u0027") | replace("/", "\\/") -}}
|
| 10 |
+
{%- endmacro -%}
|
| 11 |
+
|
| 12 |
+
{%- macro tool_definition(tool) -%}
|
| 13 |
+
{%- if tool.function is defined -%}
|
| 14 |
+
{%- set tool = tool.function -%}
|
| 15 |
+
{%- endif -%}
|
| 16 |
+
{{- 'function {"name":"' ~ tool.name ~ '",' -}}
|
| 17 |
+
{%- if tool.description is defined and tool.description -%}
|
| 18 |
+
{{- '"description":"' ~ tool.description ~ '",' -}}
|
| 19 |
+
{%- endif -%}
|
| 20 |
+
{{- '"parameters":' ~ js(tool.parameters) -}}
|
| 21 |
+
{%- if tool.return_parameters is defined and tool.return_parameters -%}
|
| 22 |
+
{{- ',"return_parameters":' ~ js(tool.return_parameters) -}}
|
| 23 |
+
{%- endif -%}
|
| 24 |
+
{%- if tool.few_shot_examples is defined and tool.few_shot_examples -%}
|
| 25 |
+
{{- ',"few_shot_examples":' ~ js(tool.few_shot_examples) -}}
|
| 26 |
+
{%- endif -%}
|
| 27 |
+
{{- "}" -}}
|
| 28 |
+
{%- endmacro -%}
|
| 29 |
+
|
| 30 |
+
{%- macro render_tools(tools) -%}
|
| 31 |
+
{{- tools_prefix -}}
|
| 32 |
+
{%- for tool in tools -%}
|
| 33 |
+
{{- "\n" ~ tool_definition(tool) -}}
|
| 34 |
+
{%- endfor -%}
|
| 35 |
+
{%- endmacro -%}
|
| 36 |
+
|
| 37 |
+
{%- macro render_tool_calls(calls) -%}
|
| 38 |
+
{%- for call in calls -%}
|
| 39 |
+
{%- set fn = call.function if call.function is defined else call -%}
|
| 40 |
+
{{- "\n" ~ TOOL_CALL_START ~ fn.name ~ "\n" -}}
|
| 41 |
+
{%- if fn.arguments is mapping -%}
|
| 42 |
+
{{- js(fn.arguments) -}}
|
| 43 |
+
{%- else -%}
|
| 44 |
+
{{- fn.arguments -}}
|
| 45 |
+
{%- endif -%}
|
| 46 |
+
{%- endfor -%}
|
| 47 |
+
{%- endmacro -%}
|
| 48 |
+
|
| 49 |
+
{%- macro render_assistant(message) -%}
|
| 50 |
+
{%- if message.tool_calls is defined and message.tool_calls -%}
|
| 51 |
+
{%- set content = render_tool_calls(message.tool_calls) -%}
|
| 52 |
+
{%- elif message.content is defined and message.content is not none -%}
|
| 53 |
+
{%- set content = message.content -%}
|
| 54 |
+
{%- else -%}
|
| 55 |
+
{%- set content = "" -%}
|
| 56 |
+
{%- endif -%}
|
| 57 |
+
{{- roles.assistant -}}
|
| 58 |
+
{%- if message.reasoning_content is defined and message.reasoning_content -%}
|
| 59 |
+
{{- COT_START ~ message.reasoning_content ~ COT_END -}}
|
| 60 |
+
{%- endif -%}
|
| 61 |
+
{{- " " ~ content -}}
|
| 62 |
+
{%- endmacro -%}
|
| 63 |
+
|
| 64 |
+
{%- macro render_message(message) -%}
|
| 65 |
+
{%- if message.role == "system" -%}
|
| 66 |
+
{{- roles.system ~ " " ~ message.content -}}
|
| 67 |
+
{%- elif message.role == "user" -%}
|
| 68 |
+
{{- roles.user ~ " " ~ message.content -}}
|
| 69 |
+
{%- elif message.role == "assistant" -%}
|
| 70 |
+
{{- render_assistant(message) -}}
|
| 71 |
+
{%- elif message.role == "tool" -%}
|
| 72 |
+
{{- "Tool " ~ message.name ~ ": " ~ (message.content | default("", true)) -}}
|
| 73 |
+
{%- elif message.role == "meta" -%}
|
| 74 |
+
{{- roles.meta ~ message.content -}}
|
| 75 |
+
{%- endif -%}
|
| 76 |
+
{%- endmacro -%}
|
| 77 |
+
|
| 78 |
+
{{- bos_token | default("", true) -}}
|
| 79 |
+
{%- if tools is defined and tools -%}
|
| 80 |
+
{{- render_tools(tools) -}}
|
| 81 |
+
{%- endif -%}
|
| 82 |
+
{%- for message in messages -%}
|
| 83 |
+
{%- set sep = "\n\n " if (tools is defined and tools) or not loop.first else "" -%}
|
| 84 |
+
{%- set block = render_message(message) -%}
|
| 85 |
+
{%- if loop.last and not (add_generation_prompt | default(false)) -%}
|
| 86 |
+
{%- set block = block | trim -%}
|
| 87 |
+
{%- endif -%}
|
| 88 |
+
{%- if block -%}
|
| 89 |
+
{{- sep ~ block -}}
|
| 90 |
+
{%- endif -%}
|
| 91 |
+
{%- endfor -%}
|
| 92 |
+
{%- if add_generation_prompt | default(false) -%}
|
| 93 |
+
{{- "\n\n " ~ roles.assistant -}}
|
| 94 |
+
{%- endif -%}
|
finetune/finetune_lora.py
ADDED
|
@@ -0,0 +1,274 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from __future__ import annotations
|
| 2 |
+
|
| 3 |
+
import argparse
|
| 4 |
+
from pathlib import Path
|
| 5 |
+
|
| 6 |
+
import torch
|
| 7 |
+
from accelerate import Accelerator, DistributedType
|
| 8 |
+
from datasets import load_dataset
|
| 9 |
+
from torch.distributed.tensor import DTensor
|
| 10 |
+
from torch.utils.data import DataLoader
|
| 11 |
+
from transformers import AutoConfig, AutoModelForCausalLM, AutoTokenizer
|
| 12 |
+
|
| 13 |
+
from peft import LoraConfig, TaskType, get_peft_model, get_peft_model_state_dict
|
| 14 |
+
|
| 15 |
+
DEFAULT_MODEL = Path(__file__).resolve().parent.parent
|
| 16 |
+
DATASET_NAME = "tatsu-lab/alpaca"
|
| 17 |
+
DATASET_REVISION = "dce01c9b08f87459cf36a430d809084718273017"
|
| 18 |
+
FSDP_VERSION = 2
|
| 19 |
+
LORA_TARGET_MODULES = ["q_proj", "k_proj", "v_proj", "o_proj"]
|
| 20 |
+
MAX_RESPONSE_TOKENS = 128
|
| 21 |
+
ROUTER_BUFFER_NAME = "e_score_correction_bias"
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
def parse_args() -> argparse.Namespace:
|
| 25 |
+
parser = argparse.ArgumentParser(description="LoRA fine-tuning for Alice AI")
|
| 26 |
+
parser.add_argument("--model", default=str(DEFAULT_MODEL))
|
| 27 |
+
parser.add_argument("--output-dir", type=Path)
|
| 28 |
+
parser.add_argument("--steps", type=int, default=1)
|
| 29 |
+
parser.add_argument("--sequence-length", type=int, default=32)
|
| 30 |
+
parser.add_argument("--learning-rate", type=float, default=2e-4)
|
| 31 |
+
parser.add_argument("--lora-rank", type=int, default=8)
|
| 32 |
+
parser.add_argument("--seed", type=int, default=42)
|
| 33 |
+
return parser.parse_args()
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
def encode_alpaca_row(row, tokenizer, sequence_length: int) -> dict[str, list[int]]:
|
| 37 |
+
prompt = f"Instruction:\n{row['instruction']}"
|
| 38 |
+
if row["input"]:
|
| 39 |
+
prompt += f"\n\nInput:\n{row['input']}"
|
| 40 |
+
prompt += "\n\nResponse:\n"
|
| 41 |
+
|
| 42 |
+
prompt_ids = tokenizer(prompt, add_special_tokens=False).input_ids
|
| 43 |
+
response_ids = tokenizer(row["output"], add_special_tokens=False).input_ids
|
| 44 |
+
response_budget = min(MAX_RESPONSE_TOKENS, max(1, sequence_length // 4))
|
| 45 |
+
response_ids = response_ids[:response_budget]
|
| 46 |
+
prompt_ids = prompt_ids[: sequence_length - len(response_ids) - 2]
|
| 47 |
+
|
| 48 |
+
input_ids = [
|
| 49 |
+
tokenizer.bos_token_id,
|
| 50 |
+
*prompt_ids,
|
| 51 |
+
*response_ids,
|
| 52 |
+
tokenizer.eos_token_id,
|
| 53 |
+
]
|
| 54 |
+
labels = [-100] * (len(prompt_ids) + 1) + [*response_ids, tokenizer.eos_token_id]
|
| 55 |
+
attention_mask = [1] * len(input_ids)
|
| 56 |
+
padding_length = sequence_length - len(input_ids)
|
| 57 |
+
input_ids.extend([tokenizer.pad_token_id] * padding_length)
|
| 58 |
+
labels.extend([-100] * padding_length)
|
| 59 |
+
attention_mask.extend([0] * padding_length)
|
| 60 |
+
return {
|
| 61 |
+
"input_ids": input_ids,
|
| 62 |
+
"attention_mask": attention_mask,
|
| 63 |
+
"labels": labels,
|
| 64 |
+
}
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
def build_dataloader(tokenizer, sequence_length: int) -> DataLoader:
|
| 68 |
+
if tokenizer.pad_token_id is None:
|
| 69 |
+
tokenizer.pad_token = tokenizer.eos_token
|
| 70 |
+
dataset = load_dataset(
|
| 71 |
+
DATASET_NAME,
|
| 72 |
+
revision=DATASET_REVISION,
|
| 73 |
+
split="train",
|
| 74 |
+
)
|
| 75 |
+
dataset = dataset.map(
|
| 76 |
+
encode_alpaca_row,
|
| 77 |
+
fn_kwargs={"tokenizer": tokenizer, "sequence_length": sequence_length},
|
| 78 |
+
remove_columns=dataset.column_names,
|
| 79 |
+
)
|
| 80 |
+
return DataLoader(dataset.with_format("torch"), batch_size=1, shuffle=True)
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
def save_adapter(accelerator: Accelerator, model, tokenizer, output_dir: Path) -> None:
|
| 84 |
+
unwrapped_model = accelerator.unwrap_model(model)
|
| 85 |
+
adapter_state = get_peft_model_state_dict(unwrapped_model)
|
| 86 |
+
adapter_state = {
|
| 87 |
+
name: value.full_tensor().cpu() if isinstance(value, DTensor) else value.cpu()
|
| 88 |
+
for name, value in adapter_state.items()
|
| 89 |
+
}
|
| 90 |
+
if accelerator.is_main_process:
|
| 91 |
+
unwrapped_model.save_pretrained(output_dir, state_dict=adapter_state)
|
| 92 |
+
tokenizer.save_pretrained(output_dir)
|
| 93 |
+
accelerator.wait_for_everyone()
|
| 94 |
+
|
| 95 |
+
|
| 96 |
+
def restore_rotary_buffer(
|
| 97 |
+
accelerator: Accelerator,
|
| 98 |
+
model,
|
| 99 |
+
device: torch.device | None = None,
|
| 100 |
+
) -> None:
|
| 101 |
+
unwrapped_model = accelerator.unwrap_model(model)
|
| 102 |
+
config = unwrapped_model.config
|
| 103 |
+
base_model = (
|
| 104 |
+
unwrapped_model.get_base_model()
|
| 105 |
+
if hasattr(unwrapped_model, "get_base_model")
|
| 106 |
+
else unwrapped_model
|
| 107 |
+
)
|
| 108 |
+
rotary_embedding = base_model.model.rotary_emb
|
| 109 |
+
rotary_dim = int(config.head_dim * config.partial_rotary_factor)
|
| 110 |
+
inv_freq = 1.0 / (
|
| 111 |
+
config.rope_theta
|
| 112 |
+
** (
|
| 113 |
+
torch.arange(
|
| 114 |
+
0,
|
| 115 |
+
rotary_dim,
|
| 116 |
+
2,
|
| 117 |
+
dtype=torch.float32,
|
| 118 |
+
device=device or rotary_embedding.inv_freq.device,
|
| 119 |
+
)
|
| 120 |
+
/ rotary_dim
|
| 121 |
+
)
|
| 122 |
+
)
|
| 123 |
+
rotary_embedding.inv_freq = inv_freq
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
def load_model(model_path: str, accelerator: Accelerator):
|
| 127 |
+
load_kwargs = {
|
| 128 |
+
"trust_remote_code": True,
|
| 129 |
+
"dtype": torch.bfloat16,
|
| 130 |
+
"attn_implementation": "flash_attention_2",
|
| 131 |
+
}
|
| 132 |
+
if (
|
| 133 |
+
not accelerator.state.fsdp_plugin.cpu_ram_efficient_loading
|
| 134 |
+
or accelerator.is_main_process
|
| 135 |
+
):
|
| 136 |
+
return AutoModelForCausalLM.from_pretrained(model_path, **load_kwargs)
|
| 137 |
+
|
| 138 |
+
config = AutoConfig.from_pretrained(model_path, trust_remote_code=True)
|
| 139 |
+
# Transformers validates FlashAttention against a real device even though
|
| 140 |
+
# the attention backend does not affect the module layout.
|
| 141 |
+
config._attn_implementation = "eager"
|
| 142 |
+
previous_dtype = torch.get_default_dtype()
|
| 143 |
+
torch.set_default_dtype(load_kwargs["dtype"])
|
| 144 |
+
try:
|
| 145 |
+
with torch.device("meta"):
|
| 146 |
+
model = AutoModelForCausalLM.from_config(config, trust_remote_code=True)
|
| 147 |
+
finally:
|
| 148 |
+
torch.set_default_dtype(previous_dtype)
|
| 149 |
+
model.config._attn_implementation = load_kwargs["attn_implementation"]
|
| 150 |
+
return model
|
| 151 |
+
|
| 152 |
+
|
| 153 |
+
def remove_router_buffers(model, is_main_process: bool) -> dict[str, torch.Tensor]:
|
| 154 |
+
router_buffers = {}
|
| 155 |
+
for module_name, module in model.named_modules():
|
| 156 |
+
buffer = module._buffers.pop(ROUTER_BUFFER_NAME, None)
|
| 157 |
+
if buffer is None:
|
| 158 |
+
continue
|
| 159 |
+
router_buffers[module_name] = (
|
| 160 |
+
buffer.detach().cpu()
|
| 161 |
+
if is_main_process
|
| 162 |
+
else torch.empty(buffer.shape, dtype=buffer.dtype)
|
| 163 |
+
)
|
| 164 |
+
return router_buffers
|
| 165 |
+
|
| 166 |
+
|
| 167 |
+
def restore_router_buffers(
|
| 168 |
+
accelerator: Accelerator,
|
| 169 |
+
model,
|
| 170 |
+
router_buffers: dict[str, torch.Tensor],
|
| 171 |
+
) -> None:
|
| 172 |
+
unwrapped_model = accelerator.unwrap_model(model)
|
| 173 |
+
for module_name, buffer in router_buffers.items():
|
| 174 |
+
device_buffer = buffer.to(accelerator.device)
|
| 175 |
+
torch.distributed.broadcast(device_buffer, src=0)
|
| 176 |
+
unwrapped_model.get_submodule(module_name).register_buffer(
|
| 177 |
+
ROUTER_BUFFER_NAME,
|
| 178 |
+
device_buffer,
|
| 179 |
+
)
|
| 180 |
+
|
| 181 |
+
|
| 182 |
+
def materialize_trainable_parameters(model) -> None:
|
| 183 |
+
# Accelerate 1.14 remaps FSDP2 optimizer parameters by data_ptr(). All meta
|
| 184 |
+
# tensors use pointer 0, so give the small trainable LoRA tensors real storage.
|
| 185 |
+
for module in model.modules():
|
| 186 |
+
for parameter_name, parameter in tuple(module.named_parameters(recurse=False)):
|
| 187 |
+
if parameter.requires_grad and parameter.is_meta:
|
| 188 |
+
module._parameters[parameter_name] = torch.nn.Parameter(
|
| 189 |
+
torch.empty_like(parameter, device="cpu"),
|
| 190 |
+
)
|
| 191 |
+
|
| 192 |
+
|
| 193 |
+
def main() -> None:
|
| 194 |
+
args = parse_args()
|
| 195 |
+
if args.steps < 1:
|
| 196 |
+
raise ValueError("--steps must be positive")
|
| 197 |
+
if args.sequence_length <= 1:
|
| 198 |
+
raise ValueError("--sequence-length must be at least 2")
|
| 199 |
+
|
| 200 |
+
accelerator = Accelerator()
|
| 201 |
+
if accelerator.distributed_type != DistributedType.FSDP:
|
| 202 |
+
raise RuntimeError("Launch this script with Accelerate FSDP")
|
| 203 |
+
if accelerator.state.fsdp_plugin.fsdp_version != FSDP_VERSION:
|
| 204 |
+
raise RuntimeError("This example requires FSDP2")
|
| 205 |
+
|
| 206 |
+
torch.manual_seed(args.seed)
|
| 207 |
+
tokenizer = AutoTokenizer.from_pretrained(args.model, trust_remote_code=True)
|
| 208 |
+
with accelerator.main_process_first():
|
| 209 |
+
dataloader = build_dataloader(tokenizer, args.sequence_length)
|
| 210 |
+
|
| 211 |
+
lora_config = LoraConfig(
|
| 212 |
+
task_type=TaskType.CAUSAL_LM,
|
| 213 |
+
r=args.lora_rank,
|
| 214 |
+
lora_alpha=2 * args.lora_rank,
|
| 215 |
+
lora_dropout=0.0,
|
| 216 |
+
target_modules=LORA_TARGET_MODULES,
|
| 217 |
+
bias="none",
|
| 218 |
+
)
|
| 219 |
+
|
| 220 |
+
model = load_model(args.model, accelerator)
|
| 221 |
+
if accelerator.state.fsdp_plugin.cpu_ram_efficient_loading:
|
| 222 |
+
restore_rotary_buffer(accelerator, model, device=torch.device("cpu"))
|
| 223 |
+
model.config.use_cache = False
|
| 224 |
+
model = get_peft_model(model, lora_config)
|
| 225 |
+
if accelerator.state.fsdp_plugin.cpu_ram_efficient_loading:
|
| 226 |
+
materialize_trainable_parameters(model)
|
| 227 |
+
router_buffers = (
|
| 228 |
+
remove_router_buffers(model, accelerator.is_main_process)
|
| 229 |
+
if accelerator.state.fsdp_plugin.cpu_ram_efficient_loading
|
| 230 |
+
else {}
|
| 231 |
+
)
|
| 232 |
+
|
| 233 |
+
model.gradient_checkpointing_enable(
|
| 234 |
+
gradient_checkpointing_kwargs={"use_reentrant": False}
|
| 235 |
+
)
|
| 236 |
+
trainable = sum(
|
| 237 |
+
parameter.numel() for parameter in model.parameters() if parameter.requires_grad
|
| 238 |
+
)
|
| 239 |
+
total = sum(parameter.numel() for parameter in model.parameters())
|
| 240 |
+
accelerator.print(f"Trainable parameters: {trainable:,} / {total:,}")
|
| 241 |
+
|
| 242 |
+
optimizer = torch.optim.AdamW(
|
| 243 |
+
(parameter for parameter in model.parameters() if parameter.requires_grad),
|
| 244 |
+
lr=args.learning_rate,
|
| 245 |
+
)
|
| 246 |
+
model, optimizer, dataloader = accelerator.prepare(model, optimizer, dataloader)
|
| 247 |
+
restore_router_buffers(accelerator, model, router_buffers)
|
| 248 |
+
restore_rotary_buffer(accelerator, model)
|
| 249 |
+
|
| 250 |
+
model.train()
|
| 251 |
+
data_iterator = iter(dataloader)
|
| 252 |
+
for step in range(args.steps):
|
| 253 |
+
try:
|
| 254 |
+
batch = next(data_iterator)
|
| 255 |
+
except StopIteration:
|
| 256 |
+
data_iterator = iter(dataloader)
|
| 257 |
+
batch = next(data_iterator)
|
| 258 |
+
|
| 259 |
+
optimizer.zero_grad(set_to_none=True)
|
| 260 |
+
outputs = model(**batch, use_cache=False)
|
| 261 |
+
accelerator.backward(outputs.loss)
|
| 262 |
+
optimizer.step()
|
| 263 |
+
accelerator.print(
|
| 264 |
+
f"step={step + 1} loss={outputs.loss.detach().float().item():.6f}"
|
| 265 |
+
)
|
| 266 |
+
|
| 267 |
+
if args.output_dir is not None:
|
| 268 |
+
save_adapter(accelerator, model, tokenizer, args.output_dir)
|
| 269 |
+
accelerator.print("LoRA fine-tuning smoke test completed")
|
| 270 |
+
accelerator.end_training()
|
| 271 |
+
|
| 272 |
+
|
| 273 |
+
if __name__ == "__main__":
|
| 274 |
+
main()
|
model-00001-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dc8752372a7af35f5c9385b32a24b15783307f1e56e11902bbca3944e57d68a0
|
| 3 |
+
size 3907510776
|
model-00002-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2cd4cf968c6ec6d8d8b6c03d6dcc6e93b181bf93b8934b7f9b9cf69fc1310ad1
|
| 3 |
+
size 3300139664
|
model-00003-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fa2bdd505ea6c76a1ba921bc457133f21e7e9520277dd61a9c3415c08d048205
|
| 3 |
+
size 3284173088
|
model-00004-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ddd0ff34293459b64fdee66d7fea280ef373c1f0af45560194b254a64dc923e6
|
| 3 |
+
size 3300139664
|
model-00005-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:78e8cccae89bf63a7123f5a44c575edbcdbc47c049906b17887a01a3b5b85703
|
| 3 |
+
size 3300139664
|
model-00006-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ab3cdf27eb28f20be5a1854b6ccd297e4c2089f819ec380a2386c2715cbf35da
|
| 3 |
+
size 3300139664
|
model-00007-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5ee49728c98e1008fb8302573a55cb42c1af8acd104a9deb6f817f1a223f6cf1
|
| 3 |
+
size 3284173088
|
model-00008-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f9d039f8b7ab5870d74965ecfa6555f730dd03b6feda8cb4dc07f486a24e8638
|
| 3 |
+
size 3300139664
|
model-00009-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c8acb2ccc31d519bf5814e54d4731ea077f9b4993e86f111dddeabf2d2c633f3
|
| 3 |
+
size 3300139664
|
model-00010-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2ba4a9bab910a68d0ea6e43035bd7c9041baaf5003671df066cad950ae905738
|
| 3 |
+
size 3300139576
|
model-00011-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:53b2e775863ade93ee3da92005b09f53bc1b06d6348df76424178ce3ab42cf30
|
| 3 |
+
size 3284173104
|
model-00012-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fc8d2867f1ca4c018caa0d0520e54b8b73ca1071ad2c883b82ad7c5be307731f
|
| 3 |
+
size 3300139696
|
model-00013-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6717e4cc976388adfb12dfc2e367c370b2c2d10bb779e7b9527ce8e8a4aaf161
|
| 3 |
+
size 3300139696
|
model-00014-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5ab428fefdf329131479a8b43fb51878c74cd73f4732c2cd774773f506663afe
|
| 3 |
+
size 3300139696
|
model-00015-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7946bda09928d412a9dfecac35f85613306c43f677e3004eea5c322ec171bf97
|
| 3 |
+
size 3284173104
|
model-00016-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4844a9f4d8d5ff7ae063d78e1f6b86ed219b0fe9542c3b6473fe853ad5ac1329
|
| 3 |
+
size 3300139696
|
model-00017-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:acc60ddc1e922706d75b7583d003f235c2ff43cf656f31d3de0bfa86c5892cee
|
| 3 |
+
size 3300139696
|
model-00018-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d45cbc29dd70710361ca57a7f89ef6087e04f6fed1b25646bb7d7874ceebdf25
|
| 3 |
+
size 3300139696
|
model-00019-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ba1eda354b8b364b38b18460254d94304602693e4ad8cc634c48bff187a2ba39
|
| 3 |
+
size 3284173104
|
model-00020-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7f133b92c9de031f997bfe04f8cf01ed49694ebf32dbb76cc633cf8186c9d172
|
| 3 |
+
size 3300139696
|
model-00021-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fae72d324834b897fe9973d5fdf94c9a81f2a594fb39b10c41c912e444ec2a69
|
| 3 |
+
size 3300139696
|
model-00022-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9ba0f129fe6694303eb26385a70d628b0ee88be625ee34d04acecb130c8716e3
|
| 3 |
+
size 3300139696
|
model-00023-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6d9632bd7065a4f8c4ba884e28492e90aabbce5b9f1c3638ec5d80fd2ce71a35
|
| 3 |
+
size 3284173104
|
model-00024-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6c937a38a72f9b1e87af22c5a80115b832cf1630485019a56c38bb60d42bcd85
|
| 3 |
+
size 3300139696
|
model-00025-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8f61093583ce87a5b236a3beb5384ee41a363db3dcbbe3811aa4786bdf5cb072
|
| 3 |
+
size 3300139696
|
model-00026-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4225886e8dbf1e07a75228a2e455d00932c6f537de6f5541d12e7377df0d7872
|
| 3 |
+
size 3300139696
|
model-00027-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ad7a806a91bcc936c35e9190bac39de33871ac11c65471cdc3082fd52e609819
|
| 3 |
+
size 3284173104
|
model-00028-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ad364d878d318cc67b3e5d5a06405ee5f2065cf66ba908d823483295c35a62b7
|
| 3 |
+
size 3300139696
|
model-00029-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:24336b293f97861b7442bcdb4c2e9fa68b02554ae7afddccd5c48f9ec79c0a11
|
| 3 |
+
size 3300139696
|
model-00030-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d7e63e8ffba289606d19eee08c6ddbcc85fb0ed1c8b28f2aa90b3d278bfe49c7
|
| 3 |
+
size 3300139696
|
model-00031-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:34849f8d875cbc6f360c3ca2e657762963bd15fbefec8dea11b817bb646215bc
|
| 3 |
+
size 3284173104
|
model-00032-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2388667584c9c5bc9c5ea52453ede54818b87e8036911f3ad68154b14a1fb7e6
|
| 3 |
+
size 3300139696
|
model-00033-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:15b8af443b13f3e3b9f7509885b262af0a12031b1e1372ac4516f759d4a9e919
|
| 3 |
+
size 3300139696
|
model-00034-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:785f5e1c7395bd155f8bfaffa114a3a3da6ad3480bc2530a8d901c2016be202a
|
| 3 |
+
size 3300139696
|
model-00035-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f440c22516776bda8622abb8e62818413b8cbc7c30e43032c6cd858f04282bea
|
| 3 |
+
size 3284173104
|
model-00036-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2c0b96f186169421ab809742b34cc2d6b36d90ab8a724a68293e5408be3f14a7
|
| 3 |
+
size 3300139696
|
model-00037-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3554c046833ba5156a2ffe2806789929fe5926f2d3ada3edb4ad605239f72252
|
| 3 |
+
size 3300139696
|
model-00038-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:27d841a333d25b7f81e342b7d73f058f36fa88aafec9dd61cb5b4e4440942740
|
| 3 |
+
size 3300139696
|
model-00039-of-00049.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d6a4d680c385d9366642b15346a2bf5fe41fc5e02b097b5d46953843e1b75be4
|
| 3 |
+
size 3284173104
|